# Portkey Features
Source: https://docs.portkey.ai/docs/introduction/feature-overview
Explore the powerful features of Portkey
## AI Gateway
Connect to 250+ AI models using a single consistent API. Set up load balancers, automated fallbacks, caching, conditional routing, and more, seamlessly.
> [card] [🌐 Universal API](/docs/product/ai-gateway/universal-api)
>
> Integrate with multiple AI models through a single API
> [card] [💾 Caching](/docs/product/ai-gateway/cache-simple-and-semantic)
>
> Implement simple and semantic caching for improved performance
> [card] [🔄 Fallbacks](/docs/product/ai-gateway/fallbacks)
>
> Set up automated fallbacks for enhanced reliability
> [card] [🔀 Multimodal Capabilities](/docs/product/ai-gateway/multimodal-capabilities)
>
> Handle various data types with multimodal AI capabilities
> [card] [🔁 Automatic Retries](/docs/product/ai-gateway/automatic-retries)
>
> Implement automatic retries for improved resilience
> [card] [🔌 Circuit Breaker](/docs/product/ai-gateway/circuit-breaker)
>
> Configure per-strategy circuit protection and failure handling
> [card] [⚖️ Load Balancing](/docs/product/ai-gateway/load-balancing)
>
> Distribute workload efficiently across multiple models
> [card] [🔑 Integrations](/docs/product/integrations)
>
> Manage access to LLMs
> [card] [⏱️ Request Timeouts](/docs/product/ai-gateway/request-timeouts)
>
> Set and manage request timeouts
> [card] [🐤 Canary Tests](/docs/product/ai-gateway/canary-testing)
>
> Implement canary testing for safe deployments
> [card] [🚦 Conditional Routing](/docs/product/ai-gateway/conditional-routing)
>
> Route requests based on specific conditions
> [card] [💳 Budget Limits](/docs/product/model-catalog/budget-limits)
>
> Set and manage budget limits
## Observability & Logs
Gain real-time insights, track key metrics, and streamline debugging with our OpenTelemetry-compliant system.
> [card] [📜 Logs](/docs/product/observability/logs)
>
> Access and analyze detailed logs
> [card] [🕵️ Tracing](/docs/product/observability/traces)
>
> Implement distributed tracing for request flows
> [card] [📊 Analytics](/docs/product/observability/analytics)
>
> Gain insights through comprehensive analytics
> [card] [🧪 Filters](/docs/product/observability/filters)
>
> Apply filters for targeted analysis
> [card] [🏷️ Metadata](/docs/product/observability/metadata)
>
> Manage and utilize metadata effectively
> [card] [💬 Feedback](/docs/product/observability/feedback)
>
> Collect and analyze user feedback
## Prompt Library
Collaborate with team members to create, templatize, and version prompt templates easily. Experiment across 250+ LLMs with a strong Publish/Release flow to deploy the prompts.
> [card] [🧩 Prompt Templates](/docs/product/prompt-library/prompt-templates)
>
> Create and manage reusable prompt templates
> [card] [✂️ Prompt Partials](/docs/product/prompt-library/prompt-partials)
>
> Utilize modular prompt components
> [card] [\{ } JSON Mode Prompting](/docs/product/prompt-library/advanced-prompting-with-json-mode)
>
> Advanced prompting with JSON mode
## Guardrails
Enforce Real-Time LLM Behavior with 50+ state-of-the-art AI guardrails, so that you can synchronously run Guardrails on your requests and route them with precision.
> [card] [🛡️ Deterministic Guardrails](/docs/product/guardrails/list-of-guardrail-checks)
>
> Implement rule-based safety checks
> [card] [🤖 LLM-based Guardrails](/docs/product/guardrails/list-of-guardrail-checks)
>
> Leverage AI for advanced content filtering
> [card] [🤝 Partner Guardrails](/docs/product/guardrails/list-of-guardrail-checks)
>
> Integrate third-party safety solutions
> [card] [🎒 Bring Your Own](/docs/integrations/guardrails/bring-your-own-guardrails)
>
> Customize guardrails to your needs
## Agents
Natively integrate Portkey's gateway, guardrails, and observability suite with leading agent frameworks and take them to production.
> [card] [🤖 Autogen](/docs/integrations/agents/autogen)
> [card] [👥 CrewAI](/docs/integrations/agents/crewai)
> [card] [🔗 Langchain Agents](/docs/integrations/agents/langchain-agents)
> [card] [🦙 Llama Agents](/docs/integrations/agents/llama-agents)
> [card] [φ PhiData](/docs/integrations/agents/phidata)
> [card] [🔀 ControlFlow](/docs/integrations/agents/control-flow)
> [card] [🕸️ LangGraph](/docs/integrations/agents/langgraph)
## More Resources
> [card] [📋 Portkey Plans](/docs/product/product-feature-comparison)
>
> Compare different Portkey subscription plans
> [card] [💬 Developer Forum](/docs/support/developer-forum)
>
> Join our community of developers
> [card] [📚 API Reference](/docs/api-reference)
>
> Explore our comprehensive API documentation
> [card] [🏢 Portkey Enterprise](/docs/product/enterprise-offering)
>
> Learn about our enterprise solutions
> [card] [🌐 Portkey Open Source](/docs/product/open-source)
>
> Contribute to our open-source projects
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Make Your First Request
Source: https://docs.portkey.ai/docs/introduction/make-your-first-request
Integrate Portkey and analyze your first LLM call in 2 minutes!
## 1. Get your Portkey API Key
[Create](https://app.portkey.ai/signup) or [log in](https://app.portkey.ai/login) to your Portkey account. Grab your account's API key from the "Settings" page.
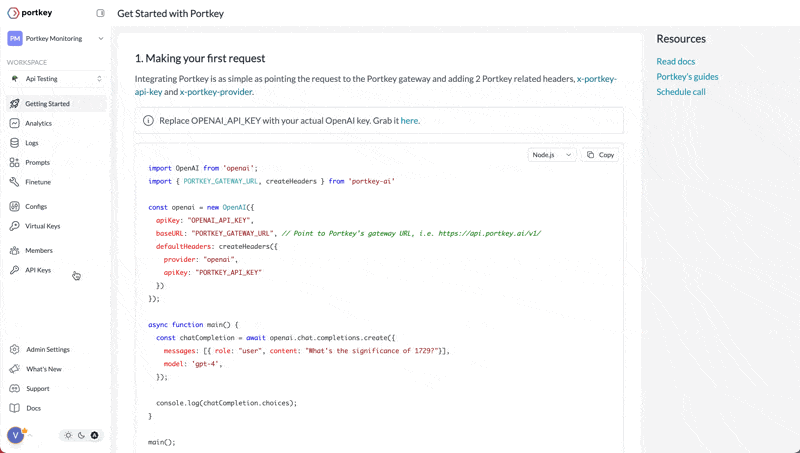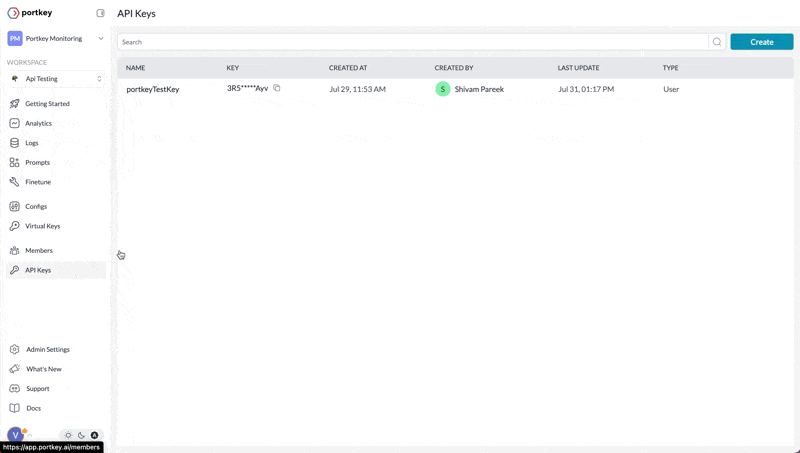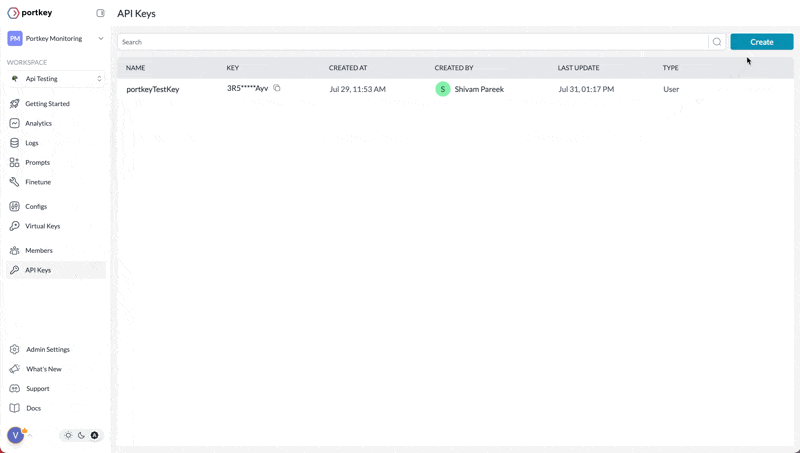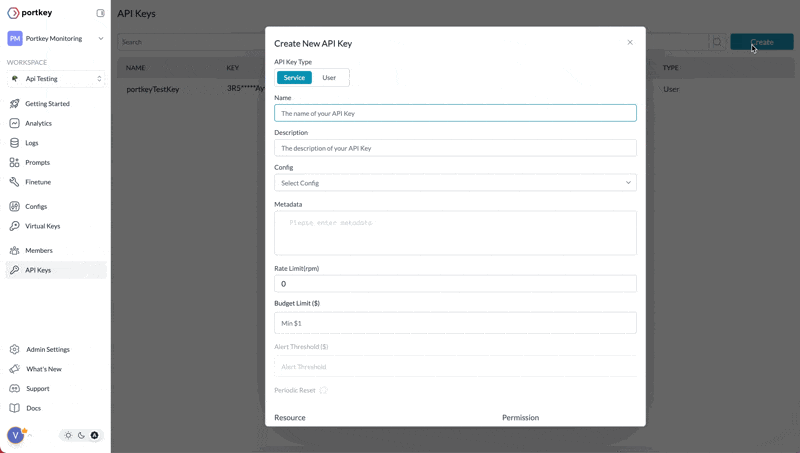
Copy your Portkey account API key
Based on your access level, you might see the relevant permissions on the API key modal - tick the ones you'd like, name your API key, and save it.
## 2. Integrate Portkey
Portkey offers a variety of integration options, including SDKs, REST APIs, and native connections with platforms like OpenAI, Langchain, and LlamaIndex, among others.
### Through the OpenAI SDK
If you're using the **OpenAI SDK**, import the Portkey SDK and configure it within your OpenAI client object:
> [card] [OpenAI](/docs/integrations/llms/openai)
### Portkey SDK
You can also use the **Portkey SDK / REST APIs** directly to make the chat completion calls. This is a more versatile way to make LLM calls across any provider:
> [card] [SDK](/docs/api-reference/sdk)
Once, the integration is ready, you can view the requests reflect on your Portkey dashboard.
### Other Integration Guides
> [card] [Azure OpenAI](/docs/integrations/llms/azure-openai)
> [card] [Anthropic](/docs/integrations/llms/anthropic)
> [card] [Langchain](/docs/integrations/libraries/langchain-python)
> [card] [LlamaIndex](/docs/integrations/libraries/llama-index-python)
> [card] [Ollama](/docs/integrations/llms/ollama)
> [card] [Others](/docs/integrations/llms)
## 3. Next Steps
Now that you're up and running with Portkey, you can dive into the various Portkey features to learn about all of the supported functionalities:
> [card] [Observability](/docs/product/observability/)
> [card] [AI Gateway](/docs/product/ai-gateway)
> [card] [Prompt Library](/docs/product/prompt-library)
> [card] [Autonomous Fine-Tuning](/docs/product/autonomous-fine-tuning)
> [card] [Guardrails](/docs/product/guardrails)
> [card] [Enterprise](/docs/product/enterprise-offering)
> [!TIP]
>
> While you're here, why not [give us a star](https://git.new/ai-gateway-docs)? It helps us a lot!
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# What is Portkey?
Source: https://docs.portkey.ai/docs/introduction/what-is-portkey
Portkey AI is a comprehensive platform designed to streamline and enhance AI integration for developers and organizations. It serves as a unified interface for interacting with over 250 AI models, offering advanced tools for control, visibility, and security in your Generative AI apps.
It takes 2 mins to integrate and with that, it starts monitoring all of your LLM requests and makes your app resilient, secure, performant, and more accurate at the same time.
Here's a product walkthrough (3 mins):
[YouTube video player](https://www.youtube.com/embed/DBGeYByV5zc)
### Integrate in 3 Lines of Code
```Python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="YOUR_PORTKEY_API_KEY",
provider="@YOUR_PROVIDER"
)
chat_complete = portkey.chat.completions.create(
model="gpt-3.5-turbo",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "Hello!"}
]
)
print(chat_complete.choices[0].message.content)
```
```js NodeJS theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "YOUR_PORTKEY_API_KEY",
provider:"@YOUR_PROVIDER"
});
async function createChatCompletion() {
const chat_complete = await portkey.chat.completions.create({
model: "gpt-3.5-turbo",
messages: [
{ role: "system", content: "You are a helpful assistant." },
{ role: "user", content: "Hello!" }
]
});
console.log(chat_complete.choices[0].message.content);
}
createChatCompletion();
```
```sh REST API theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: YOUR_PORTKEY_API_KEY" \
-H "x-portkey-provider: YOUR_PROVIDER" \
-d '{
"model": "gpt-3.5-turbo",
"messages": [
{
"role": "system",
"content": "You are a helpful assistant."
},
{
"role": "user",
"content": "Hello!"
}
]
}'
```
```py OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
client = OpenAI(
api_key="YOUR_OPENAI_API_KEY",
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="openai",
api_key="YOUR_PORTKEY_API_KEY"
)
)
chat_complete = client.chat.completions.create(
model="gpt-3.5-turbo",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "Hello!"}
]
)
print(chat_complete.choices[0].message.content)
```
```js OpenAI NodeJS SDK theme={"system"}
import OpenAI from 'openai';
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
const openai = new OpenAI({
apiKey: 'YOUR_OPENAI_API_KEY',
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "openai",
apiKey: "YOUR_PORTKEY_API_KEY"
})
});
async function createChatCompletion() {
const chat_complete = await openai.chat.completions.create({
model: "gpt-3.5-turbo",
messages: [
{ role: "system", content: "You are a helpful assistant." },
{ role: "user", content: "Hello!" }
]
});
console.log(chat_complete.choices[0].message.content);
}
createChatCompletion();
```
> [!TIP]
>
> While you're here, why not [give us a star](https://git.new/ai-gateway-docs)? It helps us a lot!
### FAQs
> [accordion] Will Portkey increase the latency of my API requests?
>
> Portkey is hosted on edge workers throughout the world, ensuring minimal latency. Our benchmarks estimate a total latency addition between 20-40ms compared to direct API calls. This slight increase is often offset by the benefits of our caching and routing optimizations.
>
> Our edge worker locations:
>
> 
> [accordion] Is my data secure?
>
> Portkey AI is ISO:27001 and SOC 2 certified, and GDPR & HIPAA compliant. We maintain best practices for service security, data storage, and retrieval. All data is encrypted in transit and at rest using industry-standard AES-256 encryption. For enhanced security, we offer:
>
> 1. On request, we can enable a feature that does NOT store any of your request and response body objects in Portkey datastores or our logs.
> 2. For enterprises, we offer managed hosting to deploy Portkey inside private clouds.
>
> For more information on these options, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
> [accordion] Will Portkey scale if my app explodes?
>
> Portkey is built on scalable infrastructure and can handle millions of requests per minute with very high concurrency. We currently serve over 25M requests daily with a 99.99% uptime. Our edge architecture & scaling capabilities ensure we can accommodate sudden spikes in traffic without performance degradation.
>
> [View our Status Page](https://status.portkey.ai)
> [accordion] Does Portkey impose timeouts on requests?
>
> We *DO NOT* impose any explicit timeout for our free OR paid plans currently. While we don't time out requests on our end, we recommend implementing client-side timeouts appropriate for your use case to handle potential network issues or upstream API delays.
> [accordion] Do you support SSO?
>
> Yes! We support SSO with any custom OIDC provider.
> [accordion] What are the pricing options? Is there a free trial?
>
> Portkey's Gateway is open source and free to use.
> On managed version, Portkey offers a free plan with 10k requests per month. We also offer paid plans with more requests and additional features.
> [accordion] Where can I reach you?
>
> We're available via our [support portal](https://support.portkey.ai/forms/customer-portal-ticket-form)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Agent Gateway
Source: https://docs.portkey.ai/docs/product/agent-gateway
Centralized authentication, access control, and observability for your agents
> [!NOTE]
>
> Supported agent frameworks: [A2A
> agents](https://a2a-protocol.org/latest/topics/what-is-a2a/#understanding-the-agent-stack-a2a-mcp-agent-frameworks-and-models)
> [card] [Quickstart](/docs/product/agent-gateway/quickstart)
>
> Skip to the quickstart
> [card] [Advanced code snippets and examples](/docs/product/agent-gateway/advanced-code-snippets-and-examples)
>
> Advanced code snippets and examples for the Agent Gateway
## Introduction
Feel free to consume the documentation in any order you prefer, the quickstart is a good place to start to get going.
The Agent Gateway consists of 2 components:
* [Agent Registry](/docs/product/agent-gateway/registry): A centralised registry of all agents in your organization with access control and observability.
* [Agent Servers](/docs/product/agent-gateway/servers): Agent servers that act as a client to the upstream agent server and as a server to the downstream agent clients.
The agent gateway acts as a centralised proxy for your agent servers. Sitting in between your agent clients and your agent servers.
Here is a broad architecture diagram:
```mermaid theme={"system"}
flowchart TD
subgraph client["Client Layer"]
A["Client (API Consumer)"]
end
subgraph gateway["Agent Gateway"]
B["Portkey Agent Gateway"]
end
subgraph agentServer["Agent Server"]
C["Agent Server"]
end
subgraph controlPlane["Control Plane"]
D["Authentication, access control (skills, capabilities)"]
end
subgraph observability["Logging / Observability"]
E[(Secure Logging)]
end
A -- "Portkey API key" --> B
B -- "Authorization" --> C
D -.-> B
B -.-> D
B --> E
style D fill:#f2f6fd,stroke:#346df1,color:#346df1
style E fill:#f8f9fa,stroke:#70a19f,color:#70a19f
```
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Advanced code snippets and examples
Source: https://docs.portkey.ai/docs/product/agent-gateway/advanced-code-snippets-and-examples
Advanced code snippets and examples for the Agent Gateway
> [!NOTE]
>
> Modify the API key permissions and turn on the **Agent Gateway** toggle for your API key. See the [Quickstart](/docs/product/agent-gateway/quickstart) for where to configure this in the app. Make sure the `agents.invoke` scope is enabled.
## Introduction
The [Quickstart](/docs/product/agent-gateway/quickstart) guide provides a basic example of how to use the Agent Gateway.
This guide provides more examples and code snippets to help you get started.
## Fetching the agent card
```shell cURL theme={"system"}
curl --location --request POST 'https://agents.portkey.ai/v1/agent/{agent-slug}/.well-known/agent.json' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: {PORTKEY_API_KEY}'
```
```python python theme={"system"}
import asyncio
import json
from a2a.client import A2ACardResolver
import httpx
BASE_URL = "https://agents.portkey.ai/v1/agent/{agent-slug}"
API_KEY = "{PORTKEY_API_KEY}"
async def log_httpx_request(request: httpx.Request) -> None:
try:
body = request.content.decode("utf-8") if request.content else ""
except Exception:
body = ""
print(f"[httpx] {request.method} {request.url}")
print(f"[httpx] body: {body}\n")
async def main() -> None:
print(f"Fetching agent card from {BASE_URL}...")
async with httpx.AsyncClient(
base_url=BASE_URL,
headers={"x-portkey-api-key": API_KEY},
event_hooks={"request": [log_httpx_request]},
) as client:
resolver = A2ACardResolver(httpx_client=client, base_url=BASE_URL)
agent_card = await resolver.get_agent_card()
print(json.dumps(agent_card.model_dump(mode="json", exclude_none=True), indent=2))
if __name__ == "__main__":
asyncio.run(main())
```
```javascript JavaScript theme={"system"}
import {
DefaultAgentCardResolver,
ClientFactory,
ClientFactoryOptions,
} from "@a2a-js/sdk/client";
const BASE_URL = "https://agents.portkey.ai/v1/agent/{agent-slug}";
const API_KEY = "{PORTKEY_API_KEY}";
class HeaderAuthInterceptor {
async before(args) {
args.options = {
...args.options,
serviceParameters: {
...(args.options?.serviceParameters || {}),
"x-portkey-api-key": API_KEY,
},
};
}
async after() {}
}
function createAuthenticatedFetch() {
return async (input, init = {}) => {
const headers = new Headers(init.headers || {});
headers.set("x-portkey-api-key", API_KEY);
return fetch(input, { ...init, headers });
};
}
async function main() {
console.log(`Fetching agent card from ${BASE_URL}...`);
const authFetch = createAuthenticatedFetch();
const resolverBaseUrl = BASE_URL.endsWith("/") ? BASE_URL : `${BASE_URL}/`;
const options = ClientFactoryOptions.createFrom(
ClientFactoryOptions.default,
{
cardResolver: new DefaultAgentCardResolver({
fetchImpl: authFetch,
}),
clientConfig: { interceptors: [new HeaderAuthInterceptor()] },
},
);
const factory = new ClientFactory(options);
const client = await factory.createFromUrl(resolverBaseUrl);
const card = client.agentCard;
if (!card) {
throw new Error("Unable to read agent card from SDK client instance.");
}
console.log(JSON.stringify(card, null, 2));
}
main().catch((error) => {
console.error(error);
process.exit(1);
});
```
## Invoking the agent
### JSON-RPC examples
```shell cURL theme={"system"}
curl --location 'https://agents.portkey.ai/v1/agent/{agent-slug}' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: {PORTKEY_API_KEY}' \
--data '{
"jsonrpc": "2.0",
"id": "req-1",
"method": "tasks/send",
"params": {
"id": "task-header-1",
"message": {
"role": "user",
"parts": [
{
"type": "text",
"text": "echo Hello from header auth"
}
]
}
}
}'
```
```python python theme={"system"}
import asyncio
import json
from uuid import uuid4
import httpx
BASE_URL = "https://agents.portkey.ai/v1/agent/header-based-authentication"
API_KEY = "+/gW5Oclr7Y9z01jEOVBaAfKZxfz"
async def log_httpx_request(request: httpx.Request) -> None:
try:
body = request.content.decode("utf-8") if request.content else ""
except Exception:
body = ""
print(f"[httpx] {request.method} {request.url}")
print(f"[httpx] body: {body}\n")
async def main() -> None:
print(f"Connecting to A2A agent at {BASE_URL}...")
message_text = "echo Hello from header auth"
task_id = f"task-{uuid4().hex[:12]}"
request_id = f"req-{uuid4().hex[:8]}"
payload = {
"jsonrpc": "2.0",
"id": request_id,
"method": "tasks/send",
"params": {
"id": task_id,
"message": {
"role": "user",
"parts": [
{
"type": "text",
"text": message_text,
}
],
},
},
}
async with httpx.AsyncClient(
base_url=BASE_URL,
headers={
"x-portkey-api-key": API_KEY,
"Content-Type": "application/json",
},
event_hooks={"request": [log_httpx_request]},
) as httpx_client:
print(f"Sending task with message: {message_text}")
response = await httpx_client.post("", json=payload)
response.raise_for_status()
print(json.dumps(response.json(), indent=2))
if __name__ == "__main__":
asyncio.run(main())
```
```javascript JavaScript theme={"system"}
const BASE_URL =
process.env.BASE_URL || "https://agents.portkey.ai/v1/agent/{agent-slug}";
const API_KEY = process.env.API_KEY || "{PORTKEY_API_KEY}";
const MESSAGE_TEXT = process.env.MESSAGE_TEXT || "echo Hello from header auth";
async function main() {
console.log(`Connecting to A2A agent at ${BASE_URL}...`);
console.log(`Sending task with message: ${MESSAGE_TEXT}`);
const payload = {
jsonrpc: "2.0",
id: `req-${crypto.randomUUID().slice(0, 8)}`,
method: "tasks/send",
params: {
id: `task-${crypto.randomUUID().slice(0, 12)}`,
message: {
role: "user",
parts: [{ type: "text", text: MESSAGE_TEXT }],
},
},
};
const response = await fetch(BASE_URL, {
method: "POST",
headers: {
"Content-Type": "application/json",
"x-portkey-api-key": API_KEY,
},
body: JSON.stringify(payload),
});
if (!response.ok) {
throw new Error(
`HTTP ${response.status}: ${response.statusText} while calling tasks/send`,
);
}
const result = await response.json();
console.log(JSON.stringify(result, null, 2));
}
main().catch((error) => {
console.error(error);
process.exit(1);
});
```
## Further reading
> [card] [Quickstart](/docs/product/agent-gateway/quickstart)
>
> Get started with the Agent Gateway by registering your first agent.
> [card] [Agent Registry](/docs/product/agent-gateway/registry)
>
> Manage your agent integrations and control access to agents and their skills.
> [card] [Agent Servers](/docs/product/agent-gateway/servers)
>
> Learn how virtual agent servers work and how to host your own.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Quickstart
Source: https://docs.portkey.ai/docs/product/agent-gateway/quickstart
Get started with Agent Gateway
> [!NOTE]
>
> Modify the API key permissions and turn on the toggle for **Agent Gateway** to enable Agent Gateway for your API key. Create or edit a key on the [API Keys](https://app.portkey.ai/api-keys) page, and enable the `agents.invoke` scope when you will invoke agents with that key. For how Portkey API keys and scopes work, see [API keys, authentication, and authorization](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz).
All you need to get started is an agent server.
For this quickstart, we will be using an [A2A agent](https://a2a-protocol.org/latest/topics/what-is-a2a/#understanding-the-agent-stack-a2a-mcp-agent-frameworks-and-models).
**1. Fetch your server URL**
Make use of one of the following agent servers and configure it as the
upstream agent server. This is used to fetch the agent card and authenticate
requests.
> [card] Hello world A2A Agent
>
> \[[https://hello.a2aregistry.org](https://hello.a2aregistry.org)]\([https://hello.a2aregistry.org](https://hello.a2aregistry.org))
> [card] Simple A2A Agent with tools and header based authentication
>
> \[[https://a2a-header-auth.ayush-0a3.workers.dev](https://a2a-header-auth.ayush-0a3.workers.dev)]\([https://a2a-header-auth.ayush-0a3.workers.dev](https://a2a-header-auth.ayush-0a3.workers.dev))
>
> headers: `Authorization: Bearer secret-key-1`
> [card] Host your own agent
>
> You can host your own A2A Agent server following the instructions in the
> [Agent Server
> SDK](https://a2a-protocol.org/latest/tutorials/python/1-introduction/)
> documentation.
**2. Add agent to registry**
**1. Configure the agent**
Access the [Agent
Registry](https://app.portkey.ai/agent-integrations/integrated) and
configure the agent server URL.

**2. Fetch agent card and validate**
Validate transport and authentication schemes by clicking the `Fetch
Agent Card` button. The upstream URL must be a public `http`/`https` endpoint (Backend `v1.16.1+` applies SSRF protections and rejects private IPs, metadata hosts, and URLs with `#` fragments).

**3. Provision workspaces**

**3. Verify your integration**
**1. Grab your Portkey API key**
Head over to the [API Keys](https://app.portkey.ai/api-keys) page and
create a new API key. Make sure the `agents.invoke` scope is enabled for
your API key.

**2. Fetch the agent server URL from the agents tab**
Open the [Agents](https://app.portkey.ai/agents) tab and fetch the
corresponding agent server URL. This is the URL you will use to connect
your agent to the Portkey Agent Gateway instead of the agent server URL.
It looks something like this (you can replace the agent slug with your
server's slug):
`https://agents.portkey.ai/v1/agent/header-based-authentication`

## Interface with your agent
You can simply replace your agent server URL with the one you fetched
from the agents tab and test out the integration.
Alternatively, make use of one of the code snippets below!
```shell cURL theme={"system"}
curl --location --request POST 'https://agents.portkey.ai/v1/agent/{agent-slug}/.well-known/agent.json' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: {PORTKEY_API_KEY}'
```
```python python theme={"system"}
import asyncio
import json
from a2a.client import A2ACardResolver
import httpx
BASE_URL = "https://agents.portkey.ai/v1/agent/{agent-slug}"
API_KEY = "{PORTKEY_API_KEY}"
async def log_httpx_request(request: httpx.Request) -> None:
try:
body = request.content.decode("utf-8") if request.content else ""
except Exception:
body = ""
print(f"[httpx] {request.method} {request.url}")
print(f"[httpx] body: {body}\n")
async def main() -> None:
print(f"Fetching agent card from {BASE_URL}...")
async with httpx.AsyncClient(
base_url=BASE_URL,
headers={"x-portkey-api-key": API_KEY},
event_hooks={"request": [log_httpx_request]},
) as client:
resolver = A2ACardResolver(httpx_client=client, base_url=BASE_URL)
agent_card = await resolver.get_agent_card()
print(json.dumps(agent_card.model_dump(mode="json", exclude_none=True), indent=2))
if __name__ == "__main__":
asyncio.run(main())
```
```javascript JavaScript theme={"system"}
import {
DefaultAgentCardResolver,
ClientFactory,
ClientFactoryOptions,
} from "@a2a-js/sdk/client";
const BASE_URL = "https://agents.portkey.ai/v1/agent/{agent-slug}";
const API_KEY = "{PORTKEY_API_KEY}";
class HeaderAuthInterceptor {
async before(args) {
args.options = {
...args.options,
serviceParameters: {
...(args.options?.serviceParameters || {}),
"x-portkey-api-key": API_KEY,
},
};
}
async after() {}
}
function createAuthenticatedFetch() {
return async (input, init = {}) => {
const headers = new Headers(init.headers || {});
headers.set("x-portkey-api-key", API_KEY);
return fetch(input, { ...init, headers });
};
}
async function main() {
console.log(`Fetching agent card from ${BASE_URL}...`);
const authFetch = createAuthenticatedFetch();
const resolverBaseUrl = BASE_URL.endsWith("/") ? BASE_URL : `${BASE_URL}/`;
const options = ClientFactoryOptions.createFrom(
ClientFactoryOptions.default,
{
cardResolver: new DefaultAgentCardResolver({
fetchImpl: authFetch,
}),
clientConfig: { interceptors: [new HeaderAuthInterceptor()] },
},
);
const factory = new ClientFactory(options);
const client = await factory.createFromUrl(resolverBaseUrl);
const card = client.agentCard;
if (!card) {
throw new Error("Unable to read agent card from SDK client instance.");
}
console.log(JSON.stringify(card, null, 2));
}
main().catch((error) => {
console.error(error);
process.exit(1);
});
```
## Further reading
> [card] [Agent Registry](/docs/product/agent-gateway/registry)
>
> Manage your agent integrations and control access to agents and their skills.
> [card] [Agent Servers](/docs/product/agent-gateway/servers)
>
> Learn how virtual agent servers work and how to host your own.
> [card] [Advanced code snippets and examples](/docs/product/agent-gateway/advanced-code-snippets-and-examples)
>
> Explore additional examples for fetching agent cards and invoking agents.
> [card] [API Keys](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
>
> Configure API keys and scopes to securely invoke your agents.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Agent Registry
Source: https://docs.portkey.ai/docs/product/agent-gateway/registry
Manage your agent integrations
The Agent Registry forms the core of the Agent Gateway, allowing admins to provision agents and granularly control access to them.
You can register your agents by following the getting started guide [here](/docs/product/agent-gateway/quickstart).
Once you have successfully registered your agent, you can do the following:
* Control access to the agent itself.

* Control access to the specific skills and capabilities that the agent provides.

## Coming soon
* Control access to specific users
* Control access to skills inside specific workspaces
* Control access to skills for specific users
## Further reading
> [card] [Quickstart](/docs/product/agent-gateway/quickstart)
>
> Get started with the Agent Gateway by registering your first agent.
> [card] [Agent Servers](/docs/product/agent-gateway/servers)
>
> Learn how virtual agent servers work and how to host your own.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Agent Servers
Source: https://docs.portkey.ai/docs/product/agent-gateway/servers
Host your agent servers
The Agent Servers are the virtual servers that act as a client to the upstream agent server and as a server to the downstream agent clients.
## Introduction
Instead of your clients (your users/your services) directly interacting with the upstream agent server,
Portkey allows you to:
* create virtual servers and provision access with virtual keys,
* control access to the agent itself and the specific skills and capabilities that the agent provides.
This way, your clients can be restricted to the necessary scopes and capabilities with full observability and logging.
## Usage
Simply replace your agent server URL wherever you are invoking it with the virtual server URL.
For example, if your slug is `test-server` your URL becomes `https://agents.portkey.ai/v1/agent/test-server`.
> [!NOTE]
>
> For self-hosted deployments, replace `agents.portkey.ai` with your gateway
> URL.
## Forwarding Caller Headers
By default, only the static headers configured on the agent are sent to the upstream agent. To also pass headers from the caller's request through to the agent, set `forward_headers` in the agent's configuration. It accepts the same shorthand, allowlist, and all-except forms as MCP servers, including header renaming and the same list of protected headers. See [Forwarding Headers](/docs/product/mcp-gateway/authentication/forwarding-headers) for the full format.
```json theme={"system"}
{
"forward_headers": ["x-request-id", "x-tenant-id"]
}
```
Static headers configured on the agent always replace a forwarded header of the same name. Connection-level headers (such as `host`, `connection`, `content-length`, and `accept-encoding`) are never forwarded.
## Logging
Every request to the virtual server will be logged and can be viewed in the [logs](/docs/product/observability/logs) section.
This forms the basis of the [observability](/docs/product/observability) and [governance](/docs/product/enterprise-offering/access-control-management) features at Portkey.

## Further reading
> [card] [Quickstart](/docs/product/agent-gateway/quickstart)
>
> Get started with the Agent Gateway by registering your first agent.
> [card] [Agent Registry](/docs/product/agent-gateway/registry)
>
> Manage your agent integrations and control access to agents and their skills.
> [card] [Advanced code snippets and examples](/docs/product/agent-gateway/advanced-code-snippets-and-examples)
>
> Explore additional examples for fetching agent cards and invoking agents.
> [card] [Logs](/docs/product/observability/logs)
>
> View and analyze logs for every request made through your agent servers.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# AI Gateway
Source: https://docs.portkey.ai/docs/product/ai-gateway
The world's fastest AI Gateway with advanced routing & integrated Guardrails.
## Features
> [card] [Universal API](/docs/product/ai-gateway/universal-api)
>
> Use any of the supported models with a universal API (REST and SDKs)
> [card] [Cache (Simple & Semantic)](/docs/product/ai-gateway/cache-simple-and-semantic)
>
> Save costs and decrease latencies by using a cache
> [card] [MCP Support](/docs/product/ai-gateway/remote-mcp)
>
> Connect to Remote MCP severs, allowing you to connect external tools and data sources.
> [card] [Fallbacks](/docs/product/ai-gateway/fallbacks)
>
> Fallback between providers and models for resilience
> [card] [Conditional Routing](/docs/product/ai-gateway/conditional-routing)
>
> Route to different targets based on custom conditional checks
> [card] [Multimodality](/docs/product/ai-gateway/multimodal-capabilities)
>
> Use vision, audio, image generation, and more models
> [card] [Automatic Retries](/docs/product/ai-gateway/automatic-retries)
>
> Setup automatic retry strategies
> [card] [Circuit Breaker](/docs/product/ai-gateway/circuit-breaker)
>
> Configure per-strategy circuit protection and failure handling
> [card] [Load Balancing](/docs/product/ai-gateway/load-balancing)
>
> Load balance between various API Keys to counter rate-limits
> [card] [Canary Testing](/docs/product/ai-gateway/canary-testing)
>
> Canary test new models in production
> [card] [gRPC (Beta)](/docs/product/ai-gateway/grpc)
>
> Use gRPC transport for lower latency and efficient binary serialization
> [card] [Request Timeout](/docs/product/ai-gateway/request-timeouts)
>
> Easily handle unresponsive LLM requests
> [card] [Budget Limits](/docs/product/model-catalog/integrations#3-budget-%26-rate-limits)
>
> Set usage limits based on costs incurred or tokens used
> [card] [Rate Limits](/docs/product/model-catalog/integrations#3-budget-%26-rate-limits)
>
> Set hourly, daily, or per minute rate limits on requests or tokens sent
> [card] [Custom Hosts](/docs/product/ai-gateway/custom-hosts)
>
> Route requests to privately hosted or local models using custom host URLs
> [card] [Gateway to other APIs](/docs/api-reference/inference-api/gateway-for-other-apis)
>
> Call rerank, video, listen, and other provider paths through [https://api.portkey.ai/v1/](https://api.portkey.ai/v1/)... with the same configs and logging as unified routes
## Using the Gateway
The various gateway strategies are implemented using Gateway configs. You can read more about configs below.
> [card] [Configs](/docs/product/ai-gateway/configs)
## Open Source
We've open sourced our battle-tested AI gateway to the community. You can run it locally with a single command:
```sh theme={"system"}
npx @portkey-ai/gateway
```
[**Contribute here**](https://github.com/portkey-ai/gateway).
While you're here, why not [give us a star](https://git.new/ai-gateway-docs)? It helps us a lot!

You can also [self-host](https://github.com/Portkey-AI/gateway/blob/main/docs/installation-deployments.md) the gateway and then connect it to Portkey. Please reach out on [hello@portkey.ai](mailto:hello@portkey.ai) and we'll help you set this up!
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Automatic Retries
Source: https://docs.portkey.ai/docs/product/ai-gateway/automatic-retries
Automatically retry failed LLM requests with exponential backoff.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
* Up to **5 retry attempts**
* Trigger on **specific error codes**
* **Exponential backoff** to prevent overload
* Optionally respect provider's `Retry-After` headers
## Examples
```json Basic (5 attempts) theme={"system"}
{
"retry": { "attempts": 5 },
"override_params": { "model": "@openai-prod/gpt-4o" }
}
```
```json Specific Error Codes theme={"system"}
{
"retry": { "attempts": 3, "on_status_codes": [429, 503] },
"override_params": { "model": "@openai-prod/gpt-4o" }
}
```
```json Respect Retry-After Headers theme={"system"}
{
"retry": { "attempts": 3, "on_status_codes": [429], "use_retry_after_headers": true },
"override_params": { "model": "@openai-prod/gpt-4o" }
}
```
> [!NOTE]
>
> The `@provider-slug/model-name` format automatically routes to the correct provider. Set up providers in [Model Catalog](https://app.portkey.ai/model-catalog).
## Retry on Specific Error Codes
Default retry codes: **\[429, 500, 502, 503, 504, 529]**
Override with `on_status_codes`:
```json theme={"system"}
{
"retry": { "attempts": 3, "on_status_codes": [408, 429, 500] },
"override_params": { "model": "@openai-prod/gpt-4o" }
}
```
> [!NOTE]
>
> When `on_status_codes` is set, retries trigger **only** on those codes—not the defaults.
## Respect Provider Retry Headers
Enable `use_retry_after_headers` to use the provider's `retry-after-ms`, `x-ms-retry-after-ms`, or `retry-after` headers instead of exponential backoff.
```json theme={"system"}
{
"retry": { "attempts": 3, "on_status_codes": [429], "use_retry_after_headers": true },
"override_params": { "model": "@openai-prod/gpt-4o" }
}
```
> [!NOTE]
>
> When `use_retry_after_headers` is set to true and the provider includes Retry-After or Retry-After-ms headers in their response, Portkey will use these values to determine the wait time before the next retry attempt, overriding the exponential backoff strategy.
> If the provider doesn't include these headers in the response, Portkey will fall back to the standard exponential backoff strategy.
> The cumulative retry wait time for a single request is capped at 60 seconds. For example, if the first retry has a wait time of 20 seconds, and the second retry response includes a Retry-After value of 50 seconds, the request will fail since the total wait time (20+50=70) exceeds the 60-second cap. Similarly, if any single Retry-After value exceeds 60 seconds, the request will fail immediately.
## Exponential Backoff
| Attempt | Wait Time |
| - | - |
| Initial | Immediate |
| 1st retry | 1 second |
| 2nd retry | 2 seconds |
| 3rd retry | 4 seconds |
| 4th retry | 8 seconds |
| 5th retry | 16 seconds |
## Retry Attempt Header
Check `x-portkey-retry-attempt-count` in responses:
| Value | Meaning |
| - | - |
| `-1` | All retries exhausted, request failed |
| `0` | No retries configured |
| `>0` | Successful on this retry attempt |
> [!NOTE]
>
> Retry attempts aren't logged individually. Response times are summed in a single log entry.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Unified Batch Inference
Source: https://docs.portkey.ai/docs/product/ai-gateway/batches
Run large‑scale inference jobs through one consistent endpoint
> [!NOTE]
>
> **Enterprise Feature** \
> Batch inference is available on **Enterprise** hybrid and self-hosted plans only. Contact the Portkey team to enable it for your Organization.
Portkey's AI Gateway lets you send a single request that fan‑outs to hundreds—or millions—of completions. Choose the mode that best fits cost, latency, and provider support.
## Choose Your Batching Mode
| Mode | When to pick it | Works with |
| - | - | - |
| **[Provider Batch API](#provider-batch-api-mode)** | *Cheapest* for overnight or offline jobs. Uses the provider's native batch endpoint & limits. | `OpenAI`, `Azure OpenAI`, `Bedrock`, `Vertex` |
| **[Portkey Batch API](#portkey-batch-api-mode)** | *Fastest* and provider‑agnostic. Batches at the Gateway layer; ideal when a provider has no native batch support or you need cross‑provider jobs. | Any provider supported by Portkey Gateway |
> [!TIP]
>
> **Quick rule of thumb →** \
> Need low latency or multi‑provider batching? **Portkey Batch API**. Otherwise, stick with the provider's native batch for cost savings.
***
## Before You Start
Have the following ready to start making batch requests:
1. **Portkey account & API key**.
2. [Data Service](/docs/changelog/data-service) to be enabled — required for **Portkey Managed Batching** or when **cost-attribution** is needed.
3. **Provider credentials** for each downstream model (OpenAI key, Bedrock IAM role, etc.).
4. A **Portkey File** (`input_file_id`) - **required only when using the Portkey Batch API (Mode #2)**. See [Files](/docs/product/ai-gateway/files) to upload one.
5. Optional: Familiarity with the [Create Batch OpenAPI spec](https://portkey.ai/docs/api-reference/inference-api/batch/create-batch).
***
## Provider Batch API Mode
Used to run batch jobs with the provider's native batch endpoint. Providers usually offer a cheaper rate for batch jobs, but you'll be limited by the provider's quota and limits. Most completion windows are about 24 hours.
> [!NOTE]
>
> **Polling for batch status**: Portkey's gateway is stateless and does not poll for completion status of batches on the provider side. You must poll the batch status manually using the unified API with the same signature for all supported providers. See [Retrieve Batch](/docs/api-reference/inference-api/batch/retrieve-batch) for details.
### Quickstart (OpenAI example)
```bash curl theme={"system"}
curl -X POST https://api.portkey.ai/v1/batches \
-H "Authorization: Bearer $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-H "x-portkey-provider: $@YOUR_PROVIDER_SLUG" \
-d '{
"input_file_id": "file_abc123",
"completion_window": "24h",
"endpoint": "/v1/chat/completions",
}'
```
```javascript Typescript theme={"system"}
import Portkey from 'portkey-ai';
const client = new Portkey({
apiKey: 'PORTKEY_API_KEY',
provider: '@YOUR_PROVIDER_SLUG'
});
async function main() {
const batch = await client.batches.create({
input_file_id: "file-abc123",
endpoint: "/v1/chat/completions",
completion_window: "24h"
});
console.log(batch);
}
main();
```
```python Python theme={"system"}
from portkey_ai import Portkey
client = Portkey(
api_key = "PORTKEY_API_KEY",
provider = "@YOUR_PROVIDER_SLUG"
)
client.batches.create(
input_file_id="file-abc123",
endpoint="/v1/chat/completions",
completion_window="24h"
)
```
> 🔗 Full schema: see the [OpenAPI reference](/docs/api-reference/inference-api/batch/create-batch).
### Supported Providers & Endpoints
| Provider | Endpoints |
| - | - |
| [OpenAI](/docs/integrations/llms/openai/batches) | `completions`, `chat completions`, `embeddings` |
| [Azure OpenAI](/docs/integrations/llms/azure-openai/batches) | `completions`, `chat completions`, `embeddings` |
| [Bedrock](/docs/integrations/llms/bedrock/batches) | `chat completions` |
| [Vertex AI](/docs/integrations/llms/vertex-ai/batches) | `chat completions`, `embeddings` |
> [!TIP]
>
> Need to redact PII or filter requests/responses on a provider batch? See [Guardrails for Batches](/docs/product/guardrails/guardrails-for-batches) — pass a config with `input_guardrails`/`output_guardrails` via `portkey_options` and Portkey applies them around the upstream batch.
### Defaults & Limits
| Property | Default | Notes |
| - | - | - |
| `completion_window` | `24h` | Set by provider (cannot be shorter). |
| Provider quota | Per provider | e.g., OpenAI ≤ 50k jobs/day. |
| Retries | Provider‑defined | Portkey surfaces job status; no Gateway retry. |
***
## Portkey Managed Batching
Portkey Managed Batching is a feature that allows you to manage batches across multiple providers with minimal effort and a unified API.
Read more about portkey file [here](/docs/product/ai-gateway/files).
### How It Works
1. Submit a batch request to Portkey with portkey file and provider information.
* Batch requests respect metadata, budgets, and other batch request parameters.
2. Portkey will automatically upload and start the batch with provider.
3. Portkey will periodically check the batch status and update the batch status in Portkey.
4. Once batch is completed, portkey will read the batch output for the following details which will be added to your portkey analytics.
* Token count
* Cost
* Success Request count
* Failed Request count
* Total Request count
> [!NOTE]
>
> **Note**: The automatic status polling and analytics described above apply only to **Portkey Managed Batching**. For **Provider Batch API Mode** (Unified Batch Inference), you must poll the batch status manually.
## Portkey Custom Batching ⭐️
Portkey custom batching is a feature that allows you to batch requests to the provider which doesn't have a native batch endpoint.
> [!WARNING]
>
> Portkey custom batching is not a discounted rate.
### How It Works
Set `completion_window` to `immediate` and Portkey aggregates your requests in memory, then fires them to the target provider in fixed buckets.
| Gateway default | Value |
| - | - |
| Batch size | **25** requests |
| Batch interval | **5 s** between flushes |
| Retries | **3** per request (configurable via `x-portkey-config`) |
*Coming soon*: configurable `batch_size`, `batch_interval`, and `max_retries`.
### Quickstart (provider‑agnostic)
```bash theme={"system"}
curl -X POST https://api.portkey.ai/v1/batches \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-d '{
"input_file_id": "pk_file_...",
"completion_window": "immediate",
"endpoint": "/v1/chat/completions",
"portkey_options": {
"x-portkey-config": "pc-example-config",
"x-portkey-metadata": "{\"_user\": \"user_123\"}"
}
}'
```
Because Portkey orchestrates the batching, this works even for providers without a native batch endpoint.
### Response & Monitoring
Identical to Provider mode; the difference is that `provider_job_id` is absent and cost is computed from individual calls.
### About Portkey Files
Portkey Files are files uploaded to Portkey that are then automatically uploaded to the provider. They're useful when you want to make multiple batch completions using the same file. Portkey will:
* Automatically upload the file to the provider on your behalf
* Reuse the content in your batch requests
* Check batch progress and provide post-batch analysis including token and cost calculations
* Make batch outputs available via the `GET /batches//output` endpoint
***
## Error Handling & Retries
| Layer | What Portkey does | How to override |
| - | - | - |
| Gateway (Portkey Batch) | Retries **3×** on network/429/5xx | `x-portkey-config: {"retry": {"max_attempts": 5}}` |
| Provider (native batch) | Provider rules | Not configurable via Portkey |
***
## Security & IAM
* **Files** are encrypted at rest (AES‑256) and custom encryption key is supported, if required.
* Portkey uploads on your behalf using *least‑privilege* scoped credentials; no long‑lived secrets are stored.
* Access to batch status & outputs is gated by your workspace role (`completions.write`).
***
## Glossary
| Term | Meaning |
| - | - |
| **Batch Job** | A collection of completion requests executed asynchronously. |
| **Portkey File** (`input_file_id`) | Files uploaded to Portkey that are automatically uploaded to the provider for batch processing. Useful for reusing the same file across multiple batch completions. |
| **Provider Slug** | A unique identifier for your AI provider (e.g., `@openai-prod`). Set up in [Model Catalog](https://app.portkey.ai/model-catalog). |
| **Completion Window** | Time frame in which the job must finish. `immediate` → handled by Portkey; `24h` → delegated to provider. |
***
## Roadmap
* Custom `batch_size`, `batch_interval`, `max_retries` (Q3 2025)
* Real‑time progress webhooks
* UI for canceling or pausing jobs
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Beta Features
Source: https://docs.portkey.ai/docs/product/ai-gateway/beta-features
Opt into early-access Portkey gateway capabilities using the x-portkey-beta header.
Portkey ships certain new gateway capabilities as **opt-in beta features** before they are promoted to stable APIs. To activate a beta feature, include the `x-portkey-beta` header (or the equivalent SDK parameter) in your request with the feature's version string.
```
x-portkey-beta:
```
To enable **multiple beta features** at once, pass a comma-separated list:
```
x-portkey-beta: feature-one-2026-01-01, feature-two-2026-06-01
```
Once a feature is promoted to stable, the header becomes a no-op and can be safely removed.
***
## Currently Available Beta Features
### Use Responses API for Messages Transforms
**Header value:** `use-responses-api-2026-07-30`
Disables the automatic transformation of `/v1/messages` requests to Chat Completions format for providers that don't natively support the Messages API. When this flag is set, requests are routed through the Responses API adapter instead.
**When to use it**
* You want to use the Responses API format internally while still calling the `/v1/messages` endpoint
* You need consistency with Responses API behavior across all your requests
* You're migrating from Messages API to Responses API and want to test the behavior without changing endpoints
**How it works**
By default, when you send a `/v1/messages` request to a provider that doesn't natively support Anthropic's Messages format (like OpenAI, Gemini, Bedrock, etc.), Portkey automatically transforms it to the Chat Completions format. With this beta flag enabled, that transformation is skipped and the request is handled by the Responses API adapter instead.
**How to send the header**
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-beta: use-responses-api-2026-07-30" \
-d '{
"model": "@openai-provider/gpt-4.1",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
```python Anthropic Python SDK theme={"system"}
import anthropic
client = anthropic.Anthropic(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai",
default_headers={
"x-portkey-beta": "use-responses-api-2026-07-30"
}
)
message = client.messages.create(
model="@openai-provider/gpt-4.1",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello!"}]
)
```
```typescript Anthropic Node SDK theme={"system"}
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai",
defaultHeaders: {
"x-portkey-beta": "use-responses-api-2026-07-30"
}
});
const message = await client.messages.create({
model: "@openai-provider/gpt-4.1",
max_tokens: 1024,
messages: [{ role: "user", content: "Hello!" }]
});
```
See the [Messages API guide](/docs/product/ai-gateway/messages-api) for more on using the Messages format across providers, and the [Responses API guide](/docs/product/ai-gateway/responses-api) for the Responses API specification.
***
### Server-Side MCP Execution
**Header value:** `server-side-mcp-2026-06-01`
Enables Portkey to fetch and execute MCP tools on your behalf — directly inside the gateway — rather than delegating execution to the upstream provider. This is required whenever you use the `@portkey-mcp` prefix in the Responses API or Messages API.
**When to use it**
* You are routing through a provider that does **not** natively support remote MCP tool execution (e.g. AWS Bedrock, Google Vertex AI).
* You want MCP credentials and tool invocations to stay within **your own VPC** and never touch provider infrastructure.
* You need per-user attribution, audit logs, and full observability over every MCP tool call.
**How to send the header**
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-beta: server-side-mcp-2026-06-01" \
-d '{
"model": "@your-provider-slug/your-model",
"tools": [
{
"type": "mcp",
"server_label": "@portkey-mcp/your-mcp-server-label"
}
],
"input": "your prompt here"
}'
```
```javascript OpenAI Node SDK theme={"system"}
import OpenAI from "openai";
import { PORTKEY_GATEWAY_URL, createHeaders } from "portkey-ai";
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "@your-provider-slug",
portkeyBeta: "server-side-mcp-2026-06-01",
}),
});
```
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="@your-provider-slug",
portkey_beta="server-side-mcp-2026-06-01",
)
)
```
```typescript Portkey Node SDK theme={"system"}
import Portkey from "portkey-ai";
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "@your-provider-slug",
portkeyBeta: "server-side-mcp-2026-06-01",
});
```
```python Portkey Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="@your-provider-slug",
portkey_beta="server-side-mcp-2026-06-01",
)
```
See the full [Remote MCP guide](/docs/product/ai-gateway/remote-mcp) for complete request examples, authentication options, and a comparison of Portkey-side vs provider-side MCP execution.
***
## SDK Parameter Reference
The `x-portkey-beta` HTTP header maps to the following SDK parameters:
| SDK | Parameter name |
| - | - |
| Portkey Node SDK | `portkeyBeta` |
| Portkey Python SDK | `portkey_beta` |
| OpenAI Node SDK (via `createHeaders`) | `portkeyBeta` |
| OpenAI Python SDK (via `createHeaders`) | `portkey_beta` |
| Anthropic Node SDK | `defaultHeaders: {"x-portkey-beta": "..."}` |
| Anthropic Python SDK | `default_headers={"x-portkey-beta": "..."}` |
| cURL / raw HTTP | `x-portkey-beta` header |
***
> [!NOTE]
>
> Beta features may change before they are promoted to stable. Breaking changes within the same beta version string will not be made, but the stable API may look different. Check the [changelog](/docs/changelog) for updates.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Cache (Simple & Semantic)
Source: https://docs.portkey.ai/docs/product/ai-gateway/cache-simple-and-semantic
Speed up requests and reduce costs by caching LLM responses.
> [!NOTE]
>
> **Simple** caching is available for all plans.
>
> **Semantic** caching requires a vector database and is only available on
> select Enterprise plans. [Contact
> us](https://portkey.ai/docs/support/contact-us) to learn more about enabling
> this feature.
Cache LLM responses to serve requests up to **20x faster** and cheaper.
| Mode | How it Works | Best For | Supported Routes |
| - | - | - | - |
| **Simple** | Exact match on input | Repeated identical prompts | All models including image generation |
| **Semantic** | Matches semantically similar requests | Denoising variations in phrasing | `/chat/completions`, `/completions` |
## Enable Cache
Add `cache` to your [config object](/docs/api-reference/config-object#cache-object-details):
```json Simple Cache theme={"system"}
{ "cache": { "mode": "simple" } }
```
```json Semantic Cache theme={"system"}
{ "cache": { "mode": "semantic" } }
```
```json With TTL (60 seconds) theme={"system"}
{ "cache": { "mode": "semantic", "max_age": 60 } }
```
> [!NOTE]
>
> Caching won't work if `x-portkey-debug: "false"` header is included.
## Simple Cache
Returns the cached response when the **exact same request** is sent again.
**Hit when all of these match a cached entry:**
* Full request body (`messages` or `prompt`, `model`, `temperature`, `max_tokens`, and every other parameter)
* `x-portkey-metadata` (if used)
* `x-portkey-cache-namespace` (if used)
* The entry is still within `max_age`
**Miss when:**
* The request is sent for the first time
* Any field in the body changes—even one character in the prompt or a different parameter
* The cached entry has expired
* `x-portkey-cache-force-refresh: true` is set on the request
## Semantic Cache
Matches requests with **similar meaning** using cosine similarity, not just identical text. [Learn more →](https://portkey.ai/blog/reducing-llm-costs-and-latency-semantic-cache/)
> [!NOTE]
>
> Semantic cache is a superset of simple cache. Portkey checks for an exact
> match first and only runs semantic search on a miss.
> [!NOTE]
>
> Semantic cache works with requests under 8,191 tokens and ≤4 messages.
**Hit when all of these are true (after a simple-cache miss):**
* User text has **similar meaning** to a cached request — cosine similarity above the threshold (default `0.95`)
* `model`, `temperature`, `max_tokens`, and any other body parameter **match exactly**
* `x-portkey-metadata` matches exactly (if used)
* The **system prompt is ignored** — changing it does not affect cache hits
* At least one `user` message must be present
**Example — same model, different wording → semantic hit:**
```json theme={"system"}
// First request (cached)
{
"model": "gpt-4o",
"messages": [{ "role": "user", "content": "Who is the US president?" }]
}
// Second request — SEMANTIC HIT
{
"model": "gpt-4o",
"messages": [{ "role": "user", "content": "Tell me who is the president of the US." }]
}
```
### Set up semantic caching (self-hosted)
To enable semantic caching on a self-hosted Portkey gateway, configure the embedding provider and a vector database.
**1. Configure the embedding provider**
Set the following environment variables in your gateway environment for generating vector embeddings:
```bash theme={"system"}
SEMANTIC_CACHE_EMBEDDING_PROVIDER=openai # supported: openai, azure-openai, google, vertex-ai
SEMANTIC_CACHE_EMBEDDINGS_URL=https://api.openai.com/v1/embeddings
SEMANTIC_CACHE_EMBEDDING_MODEL=text-embedding-3-small
SEMANTIC_CACHE_EMBEDDING_API_KEY=
SEMANTIC_CACHE_SIMILARITY_THRESHOLD=0.95
SEMANTIC_CACHE_EMBEDDING_DIMENSIONS=1536
```
`SEMANTIC_CACHE_EMBEDDING_PROVIDER` accepts `openai`, `azure-openai`, `google` (Gemini embeddings), or `vertex-ai` (Vertex AI embeddings). Set `SEMANTIC_CACHE_EMBEDDINGS_URL`, `SEMANTIC_CACHE_EMBEDDING_MODEL`, and `SEMANTIC_CACHE_EMBEDDING_DIMENSIONS` to match the chosen provider's embedding model.
For **Azure OpenAI**, set the variables as follows:
```bash theme={"system"}
SEMANTIC_CACHE_EMBEDDING_PROVIDER=azure-openai
SEMANTIC_CACHE_EMBEDDINGS_URL=https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/embeddings
SEMANTIC_CACHE_EMBEDDING_MODEL=text-embedding-3-small
SEMANTIC_CACHE_EMBEDDING_API_KEY=
SEMANTIC_CACHE_SIMILARITY_THRESHOLD=0.95
SEMANTIC_CACHE_EMBEDDING_DIMENSIONS=1536
```
`SEMANTIC_CACHE_EMBEDDING_MODEL` must match your Azure deployment name. `SEMANTIC_CACHE_EMBEDDING_API_KEY` must be a plain Azure OpenAI API key; Managed Identity / Entra ID token auth is not supported for this call.
**2. Configure the vector database**
Set the following environment variables in your gateway environment to connect to your vector store (Milvus or Pinecone):
```bash theme={"system"}
VECTOR_STORE=milvus # supported values: milvus, pinecone
VECTOR_STORE_ADDRESS=
VECTOR_STORE_COLLECTION_NAME=
VECTOR_STORE_API_KEY=
```
**Milvus**
Create a collection whose **name matches** `SEMANTIC_CACHE_EMBEDDING_MODEL` (for example, `text-embedding-3-small` when using that model). The collection must define these fields:
| Field | Type |
| - | - |
| `id` | `Varchar` |
| `values` | `FloatVector` with dimension **1536** (must match `SEMANTIC_CACHE_EMBEDDING_DIMENSIONS`) |
| `metadata` | `JSON` |
If you change the embedding model or dimension, update the collection schema and `SEMANTIC_CACHE_EMBEDDING_DIMENSIONS` so the vector field size stays aligned.
**Pinecone**
* **`VECTOR_STORE_COLLECTION_NAME`** — Omit this; it is not used for Pinecone.
* **`VECTOR_STORE_ADDRESS`** — Set to your **Pinecone index name** (not a generic host string).
* **`SEMANTIC_CACHE_EMBEDDING_DIMENSIONS`** — Must match the **dimension** configured on the index (same as your embedding vectors).
* In the Pinecone console, create or use an index with **cosine** as the similarity metric so it matches Portkey’s semantic cache behavior.
**3. Enable semantic caching per request**
Set the cache mode to `semantic` in your [config object](/docs/api-reference/config-object#cache-object-details) for each LLM request:
```json theme={"system"}
{ "cache": { "mode": "semantic" } }
```
> [!WARNING]
>
> **Limitations:** - Embedding generation supports OpenAI, Azure OpenAI, Google (Gemini), and
> Vertex AI embedding providers. - The LLM model used for generating responses
> must be OpenAI-compatible. - Each request must include at least one `user`
> message along with system messages. Requests with only system messages are
> dropped.
## Cache TTL
Set expiration with `max_age` (in seconds):
```json theme={"system"}
{ "cache": { "mode": "semantic", "max_age": 60 } }
```
| Setting | Value |
| - | - |
| Minimum | 60 seconds |
| Maximum | 90 days (7,776,000 seconds) |
| Default | 7 days (604,800 seconds) |
> [!NOTE]
>
> A `max_age` below the 60-second minimum is not raised to 60 seconds — it falls back to the 7-day default instead.
### Organization-Level TTL
Admins can set default TTL for all workspaces to align with data retention policies:
1. Go to **Admin Settings** → **Organization Properties** → **Cache Settings**
2. Enter default TTL (seconds)
3. Save
**Precedence:**
* No `max_age` in request → org default used
* Request `max_age` > org default → org default wins
* Request `max_age` \< org default → request value honored
Max org-level TTL: 25,923,000 seconds.
## Force Refresh
Fetch a fresh response even when a cached response exists. This is set **per-request** (not in Config):
```python Python theme={"system"}
response = portkey.with_options(
cache_force_refresh=True
).chat.completions.create(
messages=[{"role": "user", "content": "Hello!"}],
model="@openai-prod/gpt-4o"
)
```
```javascript Node theme={"system"}
const response = await portkey.chat.completions.create(
{
messages: [{ role: "user", content: "Hello" }],
model: "@openai-prod/gpt-4o",
},
{
cacheForceRefresh: true,
},
);
```
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pc-cache-xxx" \
-H "x-portkey-cache-force-refresh: true" \
-d '{"model": "@openai-prod/gpt-4o", "messages": [{"role": "user","content": "Hello!"}]}'
```
> [!NOTE]
>
> * Requires cache config to be passed - For semantic hits, refreshes ALL
> matching entries
## Cache Namespace
By default, Portkey partitions cache by all request headers. Use a custom namespace to partition only by your custom string—useful for per-user caching or optimizing hit ratio:
```python Python theme={"system"}
response = portkey.with_options(
cache_namespace="user-123"
).chat.completions.create(
messages=[{"role": "user", "content": "Hello!"}],
model="@openai-prod/gpt-4o"
)
```
```javascript Node theme={"system"}
const response = await portkey.chat.completions.create(
{
messages: [{ role: "user", content: "Hello" }],
model: "@openai-prod/gpt-4o",
},
{
cacheNamespace: "user-123",
},
);
```
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pc-cache-xxx" \
-H "x-portkey-cache-namespace: user-123" \
-d '{"model": "@openai-prod/gpt-4o", "messages": [{"role": "user","content": "Hello!"}]}'
```
## Cache with Configs
Set cache at top-level or per-target:
```json Top-Level (all targets) theme={"system"}
{
"cache": { "mode": "semantic", "max_age": 60 },
"strategy": { "mode": "fallback" },
"targets": [
{ "override_params": { "model": "@openai-prod/gpt-4o" } },
{
"override_params": {
"model": "@anthropic-prod/claude-3-5-sonnet-20241022"
}
}
]
}
```
```json Per-Target theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{
"override_params": { "model": "@openai-prod/gpt-4o" },
"cache": { "mode": "simple", "max_age": 200 }
},
{
"override_params": {
"model": "@anthropic-prod/claude-3-5-sonnet-20241022"
},
"cache": { "mode": "semantic", "max_age": 100 }
}
]
}
```
> [!NOTE]
>
> Target-level cache takes precedence over top-level.
> [!NOTE]
>
> Targets with `override_params` need that exact param combination cached before
> hits occur.
## Analytics & Logs
**Analytics** → Cache tab shows:
* Cache hit rate
* Latency savings
* Cost savings
**Logs** → Status column shows: `Cache Hit`, `Cache Semantic Hit`, `Cache Miss`, `Cache Refreshed`, or `Cache Disabled`. [Learn more →](/docs/product/observability/logs)

***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Canary Testing
Source: https://docs.portkey.ai/docs/product/ai-gateway/canary-testing
You can use Portkey's AI gateway to also canary test new models or prompts in different environments.
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
This uses the same techniques as [load balancing](/docs/product/ai-gateway/load-balancing) but to achieve a different outcome.
### Example: Test Llama2 on 5% of the traffic
Let's take an example where we want to introduce llama2 in our systems (through Anyscale) but we're not sure of the impact. We can create a config specifically for this use case to test llama2 in production.
The config object would look like this
```JSON theme={"system"}
{
"strategy": {
"mode": "loadbalance"
},
"targets": [
{
"provider":"@openai-prod",
"weight": 0.95
},
{
"provider":"@anyscale-prod",
"weight": 0.05,
"override_params": {
"model": "meta-llama/Llama-2-70b-chat-hf"
}
]
}
```
Here we are telling the gateway to send 5% of the traffic to anyscale's hosted llama2-70b model. Portkey handles all the request transforms to make sure you don't have to change your code.
You can now [use this config like this](/docs/product/ai-gateway/configs#using-configs) in your requests.
Once data starts flowing in, we can use Portkey's [analytics dashboards](/docs/product/observability/analytics) to see the impact of the new model on cost, latency, errors and feedback.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Chat Completions
Source: https://docs.portkey.ai/docs/product/ai-gateway/chat-completions
Use OpenAI-compatible Chat Completions with any LLM provider through Portkey's AI Gateway.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
The [Chat Completions](https://platform.openai.com/docs/api-reference/chat) API is the most widely adopted format for LLM interaction. Portkey makes it work with **every provider** — send the same `POST /v1/chat/completions` request to OpenAI, Anthropic, Gemini, Bedrock, or any of the 3000+ supported models.
## Quick Start
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "Explain quantum computing in simple terms"}]
)
print(response.choices[0].message.content)
```
```javascript JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "Explain quantum computing in simple terms" }]
});
console.log(response.choices[0].message.content);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4o",
"messages": [{"role": "user", "content": "Explain quantum computing in simple terms"}]
}'
```
> [!NOTE]
>
> Switch `model` to use any provider — `@anthropic-provider/claude-sonnet-4-5-20250514`, `@google-provider/gemini-2.0-flash`, or any of the 3000+ supported models.
### Using the OpenAI SDK
The Portkey SDK is a superset of the OpenAI SDK, so all Chat Completions methods work identically. The OpenAI SDK also works directly with Portkey's base URL:
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1"
)
response = client.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "Explain quantum computing in simple terms"}]
)
print(response.choices[0].message.content)
```
```javascript OpenAI Node SDK theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1"
});
const response = await client.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "Explain quantum computing in simple terms" }]
});
console.log(response.choices[0].message.content);
```
## System Messages
Set a system prompt using the `system` role in the messages array:
```python Python theme={"system"}
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[
{"role": "system", "content": "You are a pirate. Always respond in pirate speak."},
{"role": "user", "content": "Say hello."}
]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [
{ role: "system", content: "You are a pirate. Always respond in pirate speak." },
{ role: "user", content: "Say hello." }
]
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4o",
"messages": [
{"role": "system", "content": "You are a pirate. Always respond in pirate speak."},
{"role": "user", "content": "Say hello."}
]
}'
```
## Streaming
Stream responses token-by-token with `stream: true`.
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
stream = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "Write a haiku about AI"}],
stream=True
)
for chunk in stream:
if chunk.choices[0].delta.content:
print(chunk.choices[0].delta.content, end="", flush=True)
```
```javascript JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const stream = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "Write a haiku about AI" }],
stream: true
});
for await (const chunk of stream) {
const content = chunk.choices[0]?.delta?.content;
if (content) process.stdout.write(content);
}
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4o",
"messages": [{"role": "user", "content": "Write a haiku about AI"}],
"stream": true
}'
```
## Function Calling
Define tools with the `tools` parameter. Works across all providers that support function calling.
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "What's the weather in San Francisco?"}],
tools=[{
"type": "function",
"function": {
"name": "get_weather",
"description": "Get current weather for a location",
"parameters": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}
}]
)
tool_call = response.choices[0].message.tool_calls[0]
print(f"Function: {tool_call.function.name}")
print(f"Arguments: {tool_call.function.arguments}")
```
```javascript JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "What's the weather in San Francisco?" }],
tools: [{
type: "function",
function: {
name: "get_weather",
description: "Get current weather for a location",
parameters: {
type: "object",
properties: {
location: { type: "string", description: "City name" }
},
required: ["location"]
}
}
}]
});
const toolCall = response.choices[0].message.tool_calls[0];
console.log(`Function: ${toolCall.function.name}`);
console.log(`Arguments: ${toolCall.function.arguments}`);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4o",
"messages": [{"role": "user", "content": "What'\''s the weather in San Francisco?"}],
"tools": [{
"type": "function",
"function": {
"name": "get_weather",
"description": "Get current weather for a location",
"parameters": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}
}]
}'
```
### Function Call Results
Pass tool results back to continue the conversation:
```python Python theme={"system"}
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[
{"role": "user", "content": "What's the weather in Paris?"},
{"role": "assistant", "tool_calls": [{"id": "call_123", "type": "function", "function": {"name": "get_weather", "arguments": '{"location": "Paris"}'}}]},
{"role": "tool", "tool_call_id": "call_123", "content": '{"temp": "22°C", "condition": "sunny"}'}
]
)
print(response.choices[0].message.content)
```
```javascript JavaScript theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [
{ role: "user", content: "What's the weather in Paris?" },
{ role: "assistant", tool_calls: [{ id: "call_123", type: "function", function: { name: "get_weather", arguments: '{"location": "Paris"}' } }] },
{ role: "tool", tool_call_id: "call_123", content: '{"temp": "22°C", "condition": "sunny"}' }
]
});
console.log(response.choices[0].message.content);
```
## Vision
Send images in the `content` array using the `image_url` type. Works with all vision-capable models.
```python Python theme={"system"}
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{
"role": "user",
"content": [
{"type": "text", "text": "Describe this image"},
{"type": "image_url", "image_url": {"url": "https://example.com/image.jpg"}}
]
}]
)
print(response.choices[0].message.content)
```
```javascript JavaScript theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{
role: "user",
content: [
{ type: "text", text: "Describe this image" },
{ type: "image_url", image_url: { url: "https://example.com/image.jpg" } }
]
}]
});
console.log(response.choices[0].message.content);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4o",
"messages": [{
"role": "user",
"content": [
{"type": "text", "text": "Describe this image"},
{"type": "image_url", "image_url": {"url": "https://example.com/image.jpg"}}
]
}]
}'
```
Base64-encoded images are also supported — pass a data URL as the `url` value:
```python Python theme={"system"}
{"type": "image_url", "image_url": {"url": "data:image/jpeg;base64,/9j/4AAQ..."}}
```
## Structured Output
### JSON Schema
Force the model to return structured JSON matching a specific schema:
```python Python theme={"system"}
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "Extract: John is 30 years old"}],
response_format={
"type": "json_schema",
"json_schema": {
"name": "person",
"schema": {
"type": "object",
"properties": {
"name": {"type": "string"},
"age": {"type": "integer"}
},
"required": ["name", "age"],
"additionalProperties": False
}
}
}
)
print(response.choices[0].message.content) # {"name": "John", "age": 30}
```
```javascript JavaScript theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "Extract: John is 30 years old" }],
response_format: {
type: "json_schema",
json_schema: {
name: "person",
schema: {
type: "object",
properties: {
name: { type: "string" },
age: { type: "integer" }
},
required: ["name", "age"],
additionalProperties: false
}
}
}
});
console.log(response.choices[0].message.content);
```
### JSON Mode
For free-form JSON output without a strict schema:
```python Python theme={"system"}
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "List 3 programming languages and their main use cases as JSON"}],
response_format={"type": "json_object"}
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "List 3 programming languages and their main use cases as JSON" }],
response_format: { type: "json_object" }
});
```
## Multi-turn Conversations
Pass the full conversation history in the `messages` array:
```python Python theme={"system"}
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "My name is Alice."},
{"role": "assistant", "content": "Hello Alice! How can I help you?"},
{"role": "user", "content": "What is my name?"}
]
)
print(response.choices[0].message.content) # "Your name is Alice."
```
```javascript JavaScript theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [
{ role: "system", content: "You are a helpful assistant." },
{ role: "user", content: "My name is Alice." },
{ role: "assistant", content: "Hello Alice! How can I help you?" },
{ role: "user", content: "What is my name?" }
]
});
console.log(response.choices[0].message.content);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4o",
"messages": [
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "My name is Alice."},
{"role": "assistant", "content": "Hello Alice! How can I help you?"},
{"role": "user", "content": "What is my name?"}
]
}'
```
## Using with Portkey Features
Chat Completions works with all Portkey gateway features:
* **[Configs](/docs/product/ai-gateway/configs)** -- Route, load balance, and set fallbacks
* **[Caching](/docs/product/ai-gateway/cache-simple-and-semantic)** -- Cache responses for faster, cheaper calls
* **[Guardrails](/docs/product/guardrails)** -- Add input/output guardrails
* **[Observability](/docs/product/observability)** -- Full logging and tracing
```python Python theme={"system"}
portkey = Portkey(
api_key="PORTKEY_API_KEY",
config="pp-config-xxx" # Config with fallbacks, load balancing, etc.
)
response = portkey.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Hello!"}]
)
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pp-config-xxx" \
-d '{
"model": "gpt-4o",
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
## API Reference
* [Chat Completions](/docs/api-reference/inference-api/chat) -- `POST /v1/chat/completions`
> [card] [OpenAI Chat API Docs](https://platform.openai.com/docs/api-reference/chat)
>
> OpenAI specification
> [card] [API Reference](/docs/api-reference/inference-api/chat)
>
> Portkey Chat Completions reference
> [card] [Universal API](/docs/product/ai-gateway/universal-api)
>
> All three API formats
> [card] [Function Calling Guide](/docs/product/ai-gateway/multimodal-capabilities/function-calling)
>
> Detailed function calling guide
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Circuit Breaker
Source: https://docs.portkey.ai/docs/product/ai-gateway/circuit-breaker
Automatically stop routing to unhealthy targets until they recover.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
Circuit breakers prevent cascading failures by temporarily blocking requests to targets that are failing.
## Config Schema
| Field | Description |
| - | - |
| `failure_threshold` | Number of failures to open circuit |
| `failure_threshold_percentage` | Percentage failure rate to trip circuit *(optional)* |
| `cooldown_interval` | Milliseconds to wait before retrying (min: 30s) |
| `failure_status_codes` | HTTP codes considered failures *(optional, default: >500)* |
| `minimum_requests` | Requests required before evaluating failure rate *(optional)* |
> [!NOTE]
>
> * Strategies inherit `cb_config` from parent if not set
> * Targets inherit from their parent strategy
> [!WARNING]
>
> `conditional` mode strategies are **not** evaluated by circuit breaker.
## Example
```json theme={"system"}
{
"strategy": {
"mode": "fallback",
"cb_config": {
"failure_threshold_percentage": 20,
"minimum_requests": 10,
"cooldown_interval": 60000,
"failure_status_codes": [401, 429, 500]
}
},
"targets": [
{ "override_params": { "model": "@openai-prod/gpt-4o" } },
{ "override_params": { "model": "@anthropic-prod/claude-3-5-sonnet-20241022" } }
]
}
```
> [!NOTE]
>
> The `@provider-slug/model-name` format automatically routes to the correct provider. Set up providers in [Model Catalog](https://app.portkey.ai/model-catalog).
## How It Works
Circuit breaker tracks per strategy path:
* Failure and success counts
* Time of first failure
* Failure rate (when `minimum_requests` threshold met)
**Circuit opens (OPEN)** when:
* Failure count exceeds `failure_threshold`, or
* Failure rate exceeds `failure_threshold_percentage`
**Circuit closes (CLOSED)** automatically after `cooldown_interval` passes.
## Runtime Behavior
```mermaid theme={"system"}
flowchart TD
A[Request arrives] --> B[Evaluate strategy targets]
B --> C{All targets OPEN?}
C -->|Yes| D[Bypass circuit breaker]
D --> E[Use all targets]
C -->|No| F[Use healthy targets only]
E --> G[Route request]
F --> G
```
* Unhealthy targets removed from routing
* If all targets are OPEN, circuit breaker is bypassed
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Conditional Routing
Source: https://docs.portkey.ai/docs/product/ai-gateway/conditional-routing
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
Using Portkey Gateway, you can route your requests to different provider targets based on custom conditions you define. These can be conditions like:
* If this user is on the `paid plan`, route their request to a `custom fine-tuned model`
* If the model parameter is set to `fastest`, route to `gpt-4o-mini`, if `smartest`, route to `openai o1`
* If this user is an `EU resident`, call an `EU hosted model`
* If the `temperature` parameter is above `0.7`, route to a more creative model
* If the request is coming from `testing environment` with a `llm-pass-through` flag, route it to the `cheapest model`
* ..and more!
Using this strategy, you can set up sophisticated routing logic based on:
1. **Metadata** - Custom key-value pairs you pass with your requests
2. **Request Parameters** - Any parameter that you send in your original LLM request (like model, temperature, max\_tokens)
3. **Request URL Path** - Match against `url.pathname` (for example, route `/v1/embeddings` requests)
All routing happens very fast on the *gateway*, on *edge*.
## Enabling Conditional Routing
Conditional routing is one of the *strategies* in Portkey's [Gateway Configs](/docs/product/ai-gateway/configs). (others being `fallback` and `loadbalance`). To use it in your app,
1. You need to create a `conditional` config in Portkey UI.
2. Save the Config and get an associated Config ID.
3. And just pass the Config ID along with your requests using the `config` param.
## 1. Creating the `conditional` Config
Here's how a sample `conditional` config looks (along with its simpler, tree view).
> [tab] Sample Config
>
> ```json theme={"system"}
> {
> "strategy": {
> "mode": "conditional",
> "conditions": [
> ...conditions
> ],
> "default": "target_1"
> },
> "targets": [
> {
> "name": "target_1",
> "provider": "@xx"
> },
> {
> "name": "target_2",
> "provider": "@yy"
> }
> ]
> }
> ```
> [tab] Tree View
>
> ```
> │─ config
> │ │─ strategy mode:conditional
> │ │ │─ conditions
> │ │ │ │─ array of conditions
> │ │ │─ default
> │ │ │ │─ target name
> │ │─ targets
> │ │ │─ target 1
> │ │ │ │─ name
> │ │ │ │─ provider details
> │ │ │─ target 2
> │ │ │ │─ name
> │ │ │ │─ provider details
> ```
* `strategy.mode`: Set to `conditional`
* `strategy.conditions`: Query conditions with rules applied on metadata values or request parameters along with which target to call when the condition passes
* `strategy.default`: The default target name to call when none of the conditions pass
* `targets`: Array of target objects with unique `names` and provider details. These target names are referenced in the `conditions` objects above.
> [!NOTE]
>
> `conditions` and `default` are **required params** for the `conditional` strategy.
### Structure of `conditions` Object
`conditions` are where you will actually write the routing rules. Here's a sample `condition` object:
> [tab] Metadata Based
>
> ```json theme={"system"}
> {
> "query": { "metadata.user_plan": { "$eq": "paid" } },
> "then": "finetuned-gpt4"
> }
> ```
> [tab] Params Based
>
> ```json theme={"system"}
> {
> "query": { "params.model": { "$eq": "smartest" } },
> "then": "smartest-model-target"
> }
> ```
`query`: Write the exact rule for checking metadata values or request parameters
`then`: Define which target to call if the query `PASSES`
#### Supported Query Paths and Limits
* `metadata.`: Looks up `context.metadata[]`. Keys must be flat (no additional dots) and values should be primitive types.
* `params.`: Looks up `context.params[]`. Only primitive values are supported for comparisons.
* `url.pathname`: Matches against the full request path (for example, `/admin/users`).
Note: Only two-segment keys are supported (for example, `metadata.user_plan`, `params.model`). Nested paths like `metadata.features.new_model_enabled` are not supported.
### List of Condition Query Operators
| Operator | Description |
| - | - |
| `$eq` | Equals |
| `$ne` | Not equals |
| `$in` | In array |
| `$nin` | Not in array |
| `$regex` | Match the regex |
| `$gt` | Greater than |
| `$gte` | Greater than or equal to |
| `$lt` | Less than |
| `$lte` | Less than or equal to |
> [!NOTE]
>
> * `$regex` uses JavaScript regular expressions with no flags. Matching is case-sensitive by default, and invalid patterns simply cause the condition to evaluate to `false`.
### Logical Query Operators
* `$and`: All conditions must be true
* `$or`: At least one condition must be true
\*\* Example Condition objects with Logical Operators\*\*
> [tab] AND
>
> ```json theme={"system"}
> {
> "$and": [
> { "metadata.user_type": { "$eq": "pro" } },
> { "metadata.model": { "$eq": "gpt-4" } }
> ]
> }
> ```
> [tab] OR
>
> ```json theme={"system"}
> {
> "$or": [
> { "params.temperature": { "$gt": 0.7 } },
> { "params.top_p": { "$lt": 0.8 } }
> ]
> }
> ```
> [tab] MIXED Conditions
>
> ```json theme={"system"}
> {
> "$or": [
> {
> "$and": [
> { "metadata.user_type": { "$eq": "pro" } },
> { "params.model": { "$eq": "gpt-4o" } }
> ]
> },
> { "params.max_tokens": { "$gt": 1000 } }
> ]
> }
> ```
> [!NOTE]
>
> 1. You can write nested queries (with `$and`, `$or` operators)
> 2. When a condition evaluates to `false` or is malformed, Portkey moves on to the next condition until it finds a successful one.
> 3. If no conditions pass, then the `default` target name is called
> 4. Since Portkey iterates through the queries sequentially, the order of your conditions is important
> 5. If a referenced key is missing (in `metadata`, `params`, or `url`), the condition evaluates to `false`; it does not throw an error.
## 2. Getting Config ID
Based on the `conditions` and the Config structure described above, you can create your [Config in Portkey UI](https://app.portkey.ai/configs), and save it to get Config ID. The UI also helps you autofill and autoformat your Config.
## 3. Implementing Conditional Routing
Conditional routing is enabled through Portkey's [Gateway Configs](/docs/product/ai-gateway/configs) by following these steps:
1. Create a conditional config in Portkey UI ([app.portkey.ai/configs](https://app.portkey.ai/configs))
2. Save the config to get a Config ID
3. Use this Config ID in your requests
> [card] [Parameter-Based Routing](#routing-based-on-request-parameters)
>
> Route requests based on the values of parameters like `model`, `temperature`, or `max_tokens`
> [card] [Metadata-Based Routing](#routing-based-on-metadata)
>
> Route requests based on custom metadata fields you include with your request
You can also combine both approaches for [more sophisticated routing logic](#combined-routing-with-multiple-conditions)
### Routing Based on Request Parameters
With conditional routing, you can route based on any parameter in your LLM request (`model`, `temperature`, `max_tokens`, etc.).
> [!NOTE]
>
> Portkey only supports params routing for primitive types (string, number, boolean). Complex types like arrays and objects are not supported.
**Example: Model Parameter Based Routing**
This example routes based on the `model` parameter, allowing you to use aliases instead of specific model names:
```json theme={"system"}
{
"strategy": {
"mode": "conditional",
"conditions": [
{
"query": {
"params.model": {
"$eq": "fastest"
}
},
"then": "fastest-model-target"
},
{
"query": {
"params.model": {
"$eq": "smartest"
}
},
"then": "smartest-model-target"
}
],
"default": "fastest-model-target"
},
"targets": [
{
"name": "smartest-model-target",
"provider":"@anthropic-vk",
"override_params": {
"model": "claude-3.5-sonnet"
}
},
{
"name": "fastest-model-target",
"provider":"@oai-vk",
"override_params": {
"model": "gpt-4o-mini"
}
}
]
}
```
Using the config:
```python theme={"system"}
from portkey_ai import Portkey
client = Portkey(
api_key="PORTKEY_API_KEY",
config="model-routing-config-id"
)
# This will use the "smartest" model (claude-3.5-sonnet)
completion = client.chat.completions.create(
model="smartest", # This value matches our conditional routing condition
messages=[
{"role": "developer", "content": "You are a helpful assistant."},
{"role": "user", "content": "Explain quantum computing to a 5-year-old"}
]
)
# This will use the "fastest" model (gpt-4o-mini)
completion = client.chat.completions.create(
model="fastest", # This value matches our conditional routing condition
messages=[
{"role": "developer", "content": "You are a helpful assistant."},
{"role": "user", "content": "What's 2+2?"}
]
)
```
> [!NOTE]
>
> When using parameter-based routing, make sure to include the parameter specified in your routing condition in your request. In the example above, you need to include `model` in your request for routing to work properly.
### Routing Based on Metadata
Portkey support [metadata](/docs/product/observability/metadata)-based routing, which requires sending custom metadata with your request.
**Applying Conditional Routing Based on Metadata**
> [tab] Simple Conditional Config
>
> In this example we are routing our request based on `user_plan` metadata sent along request. If the user is on a `paid` plan, we route to a `finetuned-gpt4` model, otherwise we route to a `base-gpt4` model.
>
> ```json theme={"system"}
> {
> "strategy": {
> "mode": "conditional",
> "conditions": [
> {
> "query": { "metadata.user_plan": { "$eq": "paid" } },
> "then": "finetuned-gpt4"
> },
> {
> "query": { "metadata.user_plan": { "$eq": "free" } },
> "then": "base-gpt4"
> }
> ],
> "default": "base-gpt4"
> },
> "targets": [
> {
> "name": "finetuned-gpt4",
> "provider": "@xx",
> "override_params": {
> "model": "ft://gpt4-xxxxx"
> }
> },
> {
> "name": "base-gpt4",
> "provider": "@yy",
> "override_params": {
> "model": "gpt-4"
> }
> }
> ]
> }
> ```
> [tab] Nested Conditional Config
>
> ```json theme={"system"}
> {
> "strategy": {
> "mode": "conditional",
> "conditions": [
> {
> "query": {
> "$and": [
> { "metadata.user_type": { "$eq": "pro" } },
> { "metadata.user_tier": { "$eq": "tier-1" } }
> ]
> },
> "then": "gpt4_v2_target"
> },
> {
> "query": {
> "$or": [
> { "metadata.client": { "$eq": "UI" } },
> { "metadata.app_name": { "$regex": "my_app" } }
> ]
> },
> "then": "app_target"
> }
> ],
> "default": "default_target"
> },
> "targets": [
> { "name": "gpt4_v2_target", "provider":"@openai-xx"},
> { "name": "app_target", "provider":"@openai-yy" },
> { "name": "default_target", "provider":"@openai-zz" }
> ]
> }
> ```
Using the config:
```python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
config="my-conditional-router-config"
)
response = portkey.with_options(
metadata = {
"user_plan": "free",
"environment": "production",
"session_id": "1729"
}).chat.completions.create(
messages = [{ "role": 'user', "content": 'What is 1729' }]
)
```
> [!NOTE]
>
> You can combine both metadata and request parameters in your conditions. For example, you can route based on a combination of `metadata.user_plan` and `params.model`.
### Combined Routing with Multiple Conditions
You can combine metadata and parameter conditions for more sophisticated routing:
```python theme={"system"}
from portkey_ai import Portkey
client = Portkey(
api_key="PORTKEY_API_KEY",
config="combined-routing-config-id"
)
# Route based on both metadata and temperature parameter
completion = client.with_options(
metadata={"user_tier": "enterprise"}
).chat.completions.create(
temperature=0.9, # High temperature will route to creative model
messages=[{"role": "user", "content": "Write a story about dragons"}]
)
```
Config example for combined conditions:
```json theme={"system"}
{
"strategy": {
"mode": "conditional",
"conditions": [
{
"query": {
"$and": [
{ "metadata.user_tier": { "$eq": "enterprise" } },
{ "params.temperature": { "$gte": 0.7 } }
]
},
"then": "creative-premium-target"
}
],
"default": "standard-target"
},
"targets": [
{
"name": "creative-premium-target",
"provider":"@anthropic-vk",
"override_params": { "model": "claude-3-opus" }
},
{
"name": "standard-target",
"provider":"@openai-vk",
"override_params": { "model": "gpt-3.5-turbo" }
}
]
}
```
## More Examples Using Conditional Routing
Here are practical examples of how you can leverage conditional routing to handle real-world challenges in your LLM applications. These examples showcase common patterns that help optimize cost, performance, compliance, and feature deployment without changing your application code.
> [accordion] User-Based Routing
>
> > [tab] User Subscription Tier
> >
> > Route premium users to advanced models and free users to cost-effective ones.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "metadata.user_tier": { "$eq": "premium" } },
> > "then": "premium-model"
> > },
> > {
> > "query": { "metadata.user_tier": { "$eq": "free" } },
> > "then": "basic-model"
> > }
> > ],
> > "default": "basic-model"
> > },
> > "targets": [
> > {
> > "name": "premium-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o" }
> > },
> > {
> > "name": "basic-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-3.5-turbo" }
> > }
> > ]
> > }
> > ```
>
> > [tab] Regional Compliance
> >
> > Ensure GDPR compliance by routing EU users to EU-compliant deployments.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "metadata.user_region": { "$eq": "EU" } },
> > "then": "eu-compliant"
> > }
> > ],
> > "default": "standard-model"
> > },
> > "targets": [
> > {
> > "name": "eu-compliant", "provider":"@azure-eu-vk",
> > "override_params": { "model": "gpt-4" }
> > },
> > {
> > "name": "standard-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o" }
> > }
> > ]
> > }
> > ```
>
> > [tab] Data Sensitivity
> >
> > Route requests to different models based on data sensitivity levels.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "metadata.data_sensitivity": { "$eq": "high" } },
> > "then": "on-premises-model"
> > },
> > {
> > "query": { "metadata.data_sensitivity": { "$in": ["medium", "low"] } },
> > "then": "cloud-model"
> > }
> > ],
> > "default": "public-model"
> > },
> > "targets": [
> > {
> > "name": "public-model", "provider":"@openai-vk" },
> > {
> > "name": "on-premises-model", "provider":"@private-vk" },
> > {
> > "name": "cloud-model", "provider":"@azure-vk" }
> > ]
> > }
> > ```
> [accordion] Model Selection & Parameter Routing
>
> > [tab] Routing Based on Model Name Aliases
> >
> > Use intuitive aliases instead of remembering specific model names.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "params.model": { "$eq": "fastest" } },
> > "then": "fast-model"
> > },
> > {
> > "query": { "params.model": { "$eq": "smartest" } },
> > "then": "smart-model"
> > }
> > ],
> > "default": "balanced-model"
> > },
> > "targets": [
> > {
> > "name": "smart-model", "provider":"@anthropic-vk",
> > "override_params": { "model": "claude-3.5-sonnet" }
> > },
> > {
> > "name": "fast-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o-mini" }
> > },
> > {
> > "name": "balanced-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o" }
> > }
> > ]
> > }
> > ```
>
> > [tab] Model Hyperparam Based Routing
> >
> > Route creative vs factual requests to different optimized models.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "params.temperature": { "$gte": 0.7 } },
> > "then": "creative-model"
> > },
> > {
> > "query": { "params.temperature": { "$lt": 0.3 } },
> > "then": "factual-model"
> > }
> > ],
> > "default": "balanced-model"
> > },
> > "targets": [
> > {
> > "name": "creative-model", "provider":"@anthropic-vk",
> > "override_params": { "model": "claude-3-sonnet" }
> > },
> > {
> > "name": "factual-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o" }
> > },
> > {
> > "name": "balanced-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-3.5-turbo" }
> > }
> > ]
> > }
> > ```
>
> > [tab] Max Tokens Based Routing
> >
> > Route high-token requests to models with larger context windows.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "params.max_tokens": { "$gt": 4000 } },
> > "then": "high-capacity"
> > }
> > ],
> > "default": "standard-capacity"
> > },
> > "targets": [
> > {
> > "name": "high-capacity", "provider":"@anthropic-vk",
> > "override_params": { "model": "claude-3-opus" }
> > },
> > {
> > "name": "standard-capacity", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o-mini" }
> > }
> > ]
> > }
> > ```
> [accordion] Application Features & Testing
>
> > [tab] Task-Specific Routing
> >
> > Route different tasks to specialized models for optimal results.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "metadata.task": { "$eq": "coding" } },
> > "then": "coding-model"
> > },
> > {
> > "query": { "metadata.task": { "$eq": "writing" } },
> > "then": "writing-model"
> > }
> > ],
> > "default": "general-model"
> > },
> > "targets": [
> > {
> > "name": "coding-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o" }
> > },
> > {
> > "name": "writing-model", "provider":"@anthropic-vk",
> > "override_params": { "model": "claude-3-opus" }
> > },
> > {
> > "name": "general-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-3.5-turbo" }
> > }
> > ]
> > }
> > ```
>
> > [tab] A/B Testing
> >
> > Test new models with specific user groups before full rollout.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "metadata.user_group": { "$eq": "beta" } },
> > "then": "new-model"
> > }
> > ],
> > "default": "current-model"
> > },
> > "targets": [
> > {
> > "name": "new-model", "provider":"@anthropic-vk",
> > "override_params": { "model": "claude-3.5-sonnet" }
> > },
> > {
> > "name": "current-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-3.5-turbo" }
> > }
> > ]
> > }
> > ```
>
> > [tab] Feature Flags
> >
> > Control feature rollout with feature flags in metadata.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "metadata.new_model_enabled": { "$eq": true } },
> > "then": "new-model-target"
> > }
> > ],
> > "default": "standard-model"
> > },
> > "targets": [
> > {
> > "name": "new-model-target", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-4o" }
> > },
> > {
> > "name": "standard-model", "provider":"@openai-vk",
> > "override_params": { "model": "gpt-3.5-turbo" }
> > }
> > ]
> > }
> > ```
> [accordion] URL Path Routing
>
> > [tab] Route by URL Path
> >
> > Match requests based on the incoming request path.
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": { "url.pathname": { "$regex": "^/responses" } },
> > "then": "responses-model"
> > }
> > ],
> > "default": "standard-model"
> > },
> > "targets": [
> > { "name": "responses-model", "provider": "@openai-vk/gpt-4.1" },
> > { "name": "standard-model", "provider": "@openai-vk/gpt-3.5-turbo" }
> > ]
> > }
> > ```
> [accordion] Using Conditional Router with Guardrails
>
> > [tab] Input Guardrails
> >
> > You can apply input guardrails to specific targets in your conditional routing configuration. This allows you to validate or transform the input before it's sent to the LLM:
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": {
> > "metadata.user_plan": { "$eq": "paid" }
> > },
> > "then": "premium-model"
> > },
> > {
> > "query": {
> > "metadata.user_plan": { "$eq": "free" }
> > },
> > "then": "standard-model"
> > }
> > ],
> > "default": "standard-model"
> > },
> > "targets": [
> > {
> > "name": "premium-model",
> > "provider":"@openai-vk-xxx",
> > "input_guardrails": ["pg-pii-detector-xxx", "pg-toxic-content-xxx"]
> > },
> > {
> > "name": "standard-model",
> > "provider":"@openai-vk-yyy"
> > }
> > ]
> > }
> > ```
> >
> > In this example, when a user with the "paid" plan sends a request, it's routed to the premium model but first runs through two input guardrails: one for PII detection and another for toxic content filtering.
>
> > [tab] Output Guardrails
> >
> > You can also apply output guardrails to validate or transform the LLM's response:
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": {
> > "params.temperature": { "$gte": 0.7 }
> > },
> > "then": "creative-model"
> > }
> > ],
> > "default": "standard-model"
> > },
> > "targets": [
> > {
> > "name": "creative-model",
> > "provider":"@anthropic-vk-xxx",
> > "output_guardrails": [
> > "pg-fact-checker-xxx",
> > "pg-content-moderator-xxx"
> > ]
> > },
> > {
> > "name": "standard-model",
> > "provider":"@openai-vk-xxx"
> > }
> > ]
> > }
> > ```
> >
> > This configuration applies output guardrails to the "creative-model" target, which is used when the temperature parameter is high. The response from this model will be checked for factual accuracy and moderated for inappropriate content.
>
> > [tab] Both Input and Output Guardrails
> >
> > For comprehensive protection, you can apply both input and output guardrails to your targets:
> >
> > ```json theme={"system"}
> > {
> > "strategy": {
> > "mode": "conditional",
> > "conditions": [
> > {
> > "query": {
> > "metadata.user_plan": { "$eq": "paid" }
> > },
> > "then": "premium-model"
> > },
> > {
> > "query": {
> > "metadata.user_plan": { "$eq": "free" }
> > },
> > "then": "standard-model"
> > }
> > ],
> > "default": "standard-model"
> > },
> > "targets": [
> > {
> > "name": "premium-model",
> > "provider":"@openai-vk-xxx",
> > "input_guardrails": ["pg-pii-detector-xxx", "pg-toxic-content-xxx"],
> > "output_guardrails": ["pg-fact-checker-xxx", "pg-compliance-xxx"]
> > },
> > {
> > "name": "standard-model",
> > "provider":"@openai-vk-yyy",
> > "input_guardrails": ["pg-basic-filter-xxx"],
> > "output_guardrails": ["pg-basic-moderator-xxx"]
> > }
> > ]
> > }
> > ```
> >
> > This configuration provides end-to-end protection by:
> >
> > 1. First checking inputs with guardrails before sending to the LLM
> > 2. Then validating outputs with guardrails before returning to the user
> >
> > Each target can have its own set of guardrails, allowing you to apply different levels of protection based on your routing conditions.
>
> > [!NOTE]
> >
> > Guardrails are referenced by their IDs in the configuration. You can create guardrails in the Portkey UI and then reference them in your conditional routing config.
> >
> > Learn more about [Portkey Guardrails](/docs/product/guardrails) to understand how to create and manage different types of guardrails for your LLM applications.
## Combine with Other Strategies
Conditional routing targets are fully composable — each target can itself be a load balancer, a fallback chain, or another conditional router. Any strategy can nest inside any other.
> [card] [Scale One Model Across Multiple Providers](/docs/guides/use-cases/combining-routing-strategies#scale-one-model-across-multiple-providers)
>
> Route a model alias to a load balancer spanning Anthropic, Vertex AI, and Bedrock — triple the rate limits with no code changes.
> [card] [Give Each Model Its Own Fallback](/docs/guides/use-cases/combining-routing-strategies#give-each-model-its-own-fallback)
>
> Each conditional branch has its own independent fallback chain — an OpenAI outage only affects the GPT-4o branch, not Claude routing.
> [card] [Smart Failover by Request Context](/docs/guides/use-cases/combining-routing-strategies#smart-failover-by-request-context)
>
> When the primary fails, a conditional router picks the best backup based on request context — keeping EU users on EU infrastructure even during outages.
> [card] [Isolate Failures Between Model Families](/docs/guides/use-cases/combining-routing-strategies#isolate-failures-between-model-families)
>
> Each load-balanced slot has its own failover. An OpenAI outage only affects that slot — Anthropic traffic continues uninterrupted.
## Important Note
1. **Parameter Presence**: When routing based on request parameters, make sure the parameters specified in your conditions are included in your requests.
2. **Primitive Types Only**: Parameter-based routing works with primitive data types (strings, numbers, booleans) but not with arrays or nested objects.
3. **Order Matters**: Conditions are evaluated in the order they're defined, so place more specific conditions before more general ones.
4. **Missing Keys Do Not Error**: If your condition references a parameter or metadata key that doesn't exist in the request, the condition evaluates to `false`. The router tries the next condition, and if none pass, uses the `default` target.
5. **Multiple Parameter Types**: Portkey supports routing based on any parameter that can be sent in LLM requests including `model`, `temperature`, `top_p`, `frequency_penalty`, `presence_penalty`, `max_tokens`, and many others.
6. **Supported Query Paths**: `metadata.`, `params.`, and `url.pathname`. Nested paths beyond these (for example, `metadata.a.b`) are not supported.
> [!NOTE]
>
> [Reach out to us](https://support.portkey.ai/forms/customer-portal-ticket-form) to share your thoughts on this feature or to get help with setting up advanced routing scenarios.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configs
Source: https://docs.portkey.ai/docs/product/ai-gateway/configs
This feature is available on all Portkey plans.
> [!NOTE]
>
> Available on all Portkey plans.
Configs streamline your Gateway management, enabling you to programmatically control various aspects like fallbacks, load balancing, retries, caching, and more.
A configuration is a JSON object that can be used to define routing rules for all the requests coming to your gateway. You can configure multiple configs and use them in your requests.
## Creating Configs
Navigate to the ‘Configs’ page in the Portkey app and click 'Create' to start writing a new config.
## Using Configs
Configs are supported across all integrations.
* Through the config parameter of the Portkey SDK client(Directly or via [frameworks](/docs/integrations/llms))
* Through the config headers in the OpenAI SDK
* Via the REST API through the `x-portkey-config` header
### Applying Gateway Configs
Gateway [configs](/docs/product/ai-gateway/configs) allow you to unlock the gateway superpowers of Portkey. You can create a config in the UI and attach it's config id in the OpenAI client.
> [tab] NodeJS
>
> ```js theme={"system"}
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> config: "pc-***" // Supports a string config id or a config object
> });
> ```
> [tab] Python
>
> ```py theme={"system"}
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> config="pc-***" # Supports a string config id or a config object
> )
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY", // defaults to process.env["PORTKEY_API_KEY"]
> config: "CONFIG_ID" // Fetched from the UI
> })
> });
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> client = OpenAI(
> api_key="OPENAI_API_KEY", # defaults to os.environ.get("OPENAI_API_KEY")
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY", # defaults to os.environ.get("PORTKEY_API_KEY")
> config="CONFIG_ID"
> )
> )
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "Authorization: Bearer $OPENAI_API_KEY" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: openai" \
> -H "x-portkey-config: $CONFIG_ID" \
> -d '{
> "model": "gpt-3.5-turbo",
> "messages": [{
> "role": "user",
> "content": "Hello!"
> }]
> }'
> ```
If you want to attach the configuration to only a few requests instead of modifying the client, you can send it in the request headers for OpenAI or in the config parameter while using the Portkey SDK.
> Note: If you have a default configuration set in the client, but also include a configuration in a specific request, the request-specific configuration will take precedence and replace the default config for that particular request.
> [tab] NodeJS
>
> ```js theme={"system"}
> portkey.chat.completions.create({
> messages: [{role: "user", content: "Say this is a test"}],
> model: "gpt-3.5-turbo"
> }, {config: "pc-***"})
> ```
> [tab] Python
>
> ```py theme={"system"}
> portkey.with_options(config="pc-***").chat.completions.create(
> messages = [{ "role": 'user', "content": 'Say this is a test' }],
> model = 'gpt-3.5-turbo'
> })
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> let reqHeaders = createHeaders({config: "CONFIG_ID});
> openai.chat.completions.create({
> messages: [{role: "user", content: "Say this is a test"}],
> model: "gpt-3.5-turbo"
> }, {headers: reqHeaders})
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> reqHeaders = createHeaders(config="CONFIG_ID")
> client.with_options(headers=reqHeaders).chat.completions.create(
> messages = [{ "role": 'user', "content": 'Say this is a test' }],
> model = 'gpt-3.5-turbo'
> })
> ```
> [!NOTE]
>
> You can also add the config JSON as a string instead of the slug.
### Setting Default Configs on API Keys
You can attach a default config directly to an API key, which means all requests made with that key will automatically use the specified config without needing to include it in each request. This is particularly useful for:
* **Integrations that don't support custom headers** (like Open WebUI, LibreChat, and other OpenAI-compatible interfaces)
* **Enforcing organization-wide governance policies** without requiring code changes
* **Centralized configuration management** where all applications using a specific API key share the same routing, fallbacks, and caching rules
When you attach a default config to an API key, every request made with that key automatically applies the config's settings (routing, fallbacks, caching, etc.), even if the application doesn't send the `x-portkey-config` header.
To set a default config on an API key:
1. Navigate to [API Keys](https://app.portkey.ai/api-keys) in the Portkey dashboard
2. Create a new API key or edit an existing one
3. In the API key settings, select a config from the **Default Config** dropdown
4. Save the API key
See the [Default Configs documentation](/docs/product/administration/enforce-default-config) for detailed instructions and use cases.
> [!NOTE]
>
> If you specify a config in a request (via headers or SDK parameters), it will override the default config for that specific request. The default config only applies when no config is specified in the request itself.
## Default and drop params
Each config target can shape the request body before it reaches the upstream provider with three parameter fields:
| Field | Behavior |
| - | - |
| `default_params` | Injects parameters into the request body **only when not already present**. Unlike `override_params`, this respects values set by the client. |
| `override_params` | Always overwrites the matching field on the request body. |
| `drop_params` | Removes fields from the final request body using bracket-notation paths (see below). |
Execution order: `default_params` → `override_params` → `drop_params`. All three fields inherit through nested target configs the same way `override_params` does — values defined on a parent target apply to its children unless overridden.
### `drop_params` paths
Each entry in `drop_params` is a path into the request body. The gateway deletes the matching property before forwarding the request. Paths that do not exist on the request are silently ignored.
| Path style | Example | What it removes |
| - | - | - |
| Top-level key | `"logprobs"`, `"metadata"` | A field on the root object |
| Nested object | `"response_format.json_schema"` | A field at any depth (dot-separated segments) |
| Array index | `"tools[0].function.strict"`, `"messages[2]"` | One element in an array and anything nested under it |
| Wildcard array | `"tools[*].function.strict"`, `"messages[*].content[*].cache_control.scope"` | The same nested field on **every** array element (and nested arrays when using multiple `[*]`) |
### Example
```json theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{
"provider": "@openai-prod",
"default_params": { "temperature": 0.7, "max_tokens": 1024 },
"override_params": { "model": "gpt-4o" },
"drop_params": ["logprobs", "tools[0].function.strict", "tools[*].function.name"]
},
{
"provider": "@anthropic-backup",
"override_params": { "model": "claude-sonnet-4-20250514" }
}
]
}
```
In this example:
* If the client does not send `temperature` or `max_tokens`, the gateway injects the defaults; if the client does send them, the client's values win.
* `model` is always rewritten to `gpt-4o` regardless of what the client sends.
* `logprobs` is removed from the root body.
* `tools[0].function.strict` is removed only from the first tool entry.
* `function.name` is removed from **every** tool entry via the `tools[*]` wildcard.
## Passthrough targets
Passthrough targets allow config targets to defer provider resolution to the incoming request, instead of specifying a fixed provider in the config itself. This is useful when you want to define routing strategies (conditional, fallback, loadbalance) at the config level but let the caller decide which provider to use at request time.
### How it works
A target with `"passthrough": true` does not require a `provider` or `virtual_key` field. Instead, the gateway resolves the provider from the incoming request using the following sources, in priority order:
1. **`x-portkey-provider` header** — If the value starts with `@` (e.g., `@anthropic-dev`), the slug after `@` is used as the virtual key.
2. **Request body `model` field** — If the model uses the `@slug/model-name` format (e.g., `@anthropic-dev/claude-sonnet-4-20250514`), the slug is extracted as the virtual key and the model name is passed through to the provider.
### Config schema
Set the `passthrough` property to `true` on a target to enable passthrough resolution:
```json theme={"system"}
{
"passthrough": true
}
```
### Example: Fallback with passthrough targets
```json theme={"system"}
{
"strategy": {
"mode": "fallback"
},
"targets": [
{
"passthrough": true,
"override_params": { "model": "gpt-4o" }
},
{
"provider": "@anthropic-backup",
"override_params": { "model": "claude-sonnet-4-20250514" }
}
]
}
```
In this example, the first target resolves the provider from the incoming request. If that fails, the gateway falls back to the second target which uses a fixed provider.
### Example: Load balancing with passthrough targets
```json theme={"system"}
{
"strategy": {
"mode": "loadbalance"
},
"targets": [
{ "passthrough": true, "weight": 0.7 },
{ "provider": "@openai-backup", "weight": 0.3 }
]
}
```
> [!NOTE]
>
> When using passthrough targets, the incoming request must include provider information through one of the supported resolution methods. If the gateway cannot resolve a provider, the request will fail for that target.
## Configs in Logs
Portkey shows your Config usage smartly on the logs page with the **Status column** and gives you a snapshot of the Gateway activity for every request. [Read more about the status column here](https://portkey.ai/docs/product/observability/logs#request-status-guide).
You can also see the ID of the specific Config used for a request separately in the log details, and jump into viewing/editing it directly from the log details page.
## Config Object Documentation
Find detailed info about the Config object schema, and more examples:
> [card] [Config Schema](/docs/api-reference/inference-api/config-object)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Custom hosts
Source: https://docs.portkey.ai/docs/product/ai-gateway/custom-hosts
Route requests to privately hosted or local models using custom host URLs, and understand Portkey's host validation and security rules.
> [!NOTE]
>
> Custom hosts with private network routing — including the `TRUSTED_CUSTOM_HOSTS` allowlist — applies only to **hybrid and air-gapped enterprise deployments** of the Portkey AI Gateway. On Portkey SaaS, custom host URLs must be publicly reachable; routing to private or internal network IPs is not supported.
The `custom_host` parameter routes Portkey Gateway requests to your own model endpoints — whether running locally, in a private cloud, or on custom infrastructure. Portkey validates all custom host URLs to prevent [SSRF](https://owasp.org/www-community/attacks/Server_Side_Request_Forgery) attacks.
## Setting a custom host
Specify a custom host using one of these methods:
| Method | Parameter |
| - | - |
| HTTP header | `x-portkey-custom-host` |
| Python SDK | `custom_host` |
| Node.js SDK | `customHost` |
| Gateway config | `custom_host` (in the target object) |
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="openai",
custom_host="https://your-llm-server.com/v1/"
)
response = portkey.chat.completions.create(
model="your-model",
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript Node.js theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "openai",
customHost: "https://your-llm-server.com/v1/"
})
const response = await portkey.chat.completions.create({
model: "your-model",
messages: [{ role: "user", content: "Hello" }]
})
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: openai" \
-H "x-portkey-custom-host: https://your-llm-server.com/v1/" \
-d '{
"model": "your-model",
"messages": [{"role": "user", "content": "Hello"}]
}'
```
Also set `custom_host` in a [Gateway config](/docs/product/ai-gateway/configs) target:
```json theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{
"provider": "openai",
"custom_host": "https://your-private-llm.com/v1",
"forward_headers": ["Authorization"]
},
{
"provider": "openai",
"api_key": "sk-xxxxx"
}
]
}
```
> [!NOTE]
>
> Include the version path (e.g., `/v1`) in the `custom_host` URL. Portkey appends the endpoint path (`/chat/completions`, `/responses`, etc.) automatically.
> [!NOTE]
>
> `forward_headers` cannot include cloud metadata headers such as `metadata-flavor`, `x-aws-ec2-metadata-token`, or `x-google-metadata-request`, or the `x-portkey-forward-headers` header itself.
For a full guide on integrating private LLMs, see [Bring Your Own LLM](/docs/integrations/llms/byollm).
To pin a `custom_host` (and optional `custom_headers`) on a specific Model Catalog model instead of every request, see [Per-model custom host and headers](/docs/product/model-catalog/custom-models#per-model-custom-host-and-headers).
***
## How validation works
Portkey applies SSRF checks at two layers on **Node.js deployments**:
1. **Request time** — When a `custom_host` URL is accepted, the gateway validates the hostname, port, scheme, and URL shape before the request proceeds.
2. **Connection time** — On outbound requests, DNS resolution validates every returned IP against the same rules and pins the connection to safe addresses. This blocks DNS rebinding attacks where a hostname initially resolves to a public IP but later resolves to a private or metadata address.
On Cloudflare Workers, request-time validation still applies; connection-time DNS pinning is a Node.js-only hardening layer.
URLs must use `http://` or `https://`, must not embed credentials, and are capped at 2048 characters.
***
## Blocked host patterns
Portkey validates all custom host URLs to prevent requests to internal network resources. The following IP ranges and patterns are **blocked by default** (unless the hostname is explicitly trusted — see [Trusted custom hosts (allowlist)](#trusted-custom-hosts-allowlist)).
### Private IPv4 ranges
| Range | Description |
| - | - |
| `10.0.0.0/8` | Private network (Class A) |
| `172.16.0.0/12` | Private network (Class B) |
| `192.168.0.0/16` | Private network (Class C) |
### Reserved IPv4 ranges
| Range | Description |
| - | - |
| `127.0.0.0/8` | Loopback addresses (except `127.0.0.1` when trusted) |
| `169.254.0.0/16` | Link-local addresses |
| `100.64.0.0/10` | Carrier-grade NAT (CGNAT) |
| `0.0.0.0/8` | Non-routable (includes `0.0.0.0`) |
| `224.0.0.0/4` | Multicast, reserved, and broadcast |
| `198.18.0.0/15` | Benchmarking |
| `192.0.0.0/24` | IETF protocol assignments |
| `192.0.2.0/24`, `198.51.100.0/24`, `203.0.113.0/24` | TEST-NET ranges |
| `192.88.99.0/24` | Former 6to4 relay anycast |
### Cloud metadata endpoints
These addresses are **always blocked** and cannot be allowlisted:
| Address | Description |
| - | - |
| `169.254.169.254` | AWS / Azure / GCP / DO / Oracle / Hetzner / OpenStack IMDS (IPv4) |
| `169.254.169.0/24` | Full AWS IMDS IPv4 subnet |
| `169.254.170.2` | AWS ECS task metadata / credentials endpoint |
| `169.254.170.23` | AWS ECS task metadata v4 |
| `100.100.100.200` | Alibaba Cloud instance metadata |
| `168.63.129.16` | Azure platform (wireserver / DHCP / health) |
| `192.0.0.192` | Oracle Cloud Classic metadata |
| `fd00:ec2::/96` | AWS IMDSv2 IPv6 endpoint |
### Single-label blocked hostnames
These bare hostnames are always blocked (they often resolve to internal services via DNS search domains):
| Hostname | Description |
| - | - |
| `metadata` | Kubernetes / generic metadata short name |
| `instance-data` | AWS instance metadata alternate name |
| `kubernetes` | Kubernetes API short name |
### Blocked hostname suffixes
Subdomains of known cloud metadata and internal service FQDNs are blocked, including (but not limited to):
* `metadata.google.internal`, `metadata.gce.internal`, `metadata.goog`
* `metadata.azure.com`, `internal.cloudapp.net`
* `metadata.internal`, `metadata.do.internal`, `metadata.packet.net`
* `instance-data.ec2.internal`, `ec2.internal`, `compute.internal`
* `metadata.cloud.ibm.com`
* `kubernetes.default`, `kubernetes.default.svc`, `kubernetes.default.svc.cluster.local`
* `cluster.local`
* `consul` (and `*.service.consul`, `*.node.consul`)
These suffix checks run **before** the trusted-host allowlist and cannot be overridden.
### Wildcard DNS rebinding services
Hostnames that encode arbitrary IPs in the DNS label are blocked:
| Domain | Example |
| - | - |
| `nip.io` | `127.0.0.1.nip.io` |
| `sslip.io` | `169-254-169-254.sslip.io` |
| `xip.io` | Arbitrary IP encoding |
| `localtest.me`, `lvh.me`, `vcap.me`, `traefik.me` | Resolve to loopback |
| `localhost.run` | Public tunnel service |
### Blocked internal TLDs
Hostnames ending in these TLDs are blocked unless explicitly trusted:
`.local`, `.localdomain`, `.internal`, `.intranet`, `.lan`, `.home`, `.corp`, `.test`, `.invalid`, `.onion`, `.localhost`
### IPv6 local and private ranges
| Range | Description |
| - | - |
| `::1` | IPv6 loopback |
| `::` | IPv6 unspecified |
| `fc00::/7` | Unique local addresses (`fc*` / `fd*`) |
| `fe80::/10` | Link-local addresses |
| `fec0::/10` | Site-local addresses (deprecated) |
| `ff00::/8` | Multicast |
| `2001::/32` | Teredo |
| `100:0:0:1::/64` | RFC 9780 dummy prefix |
### IPv6 addresses with embedded IPv4
IPv6 literals that embed a blocked IPv4 address are rejected, including:
* IPv4-mapped (`::ffff:127.0.0.1`)
* IPv4-compatible (`::127.0.0.1`, `::7f00:1`)
* 6to4 (`2002:7f00:1::`)
* NAT64 (`64:ff9b::7f00:1`)
Public IPv6 addresses such as `2001:4860:4860::8888` remain allowed.
### IP obfuscation tricks
The following alternate IP representations are also blocked to prevent bypass attempts:
* **Decimal form** — e.g., `2130706433` (resolves to `127.0.0.1`)
* **Hexadecimal form** — e.g., `0x7f000001` (resolves to `127.0.0.1`)
* **Shortened IPv4** — e.g., `127.1` (resolves to `127.0.0.1`)
* **Octal notation** — e.g., `0177.0.0.1` (resolves to `127.0.0.1`)
* **Percent-encoded hostnames** — e.g., `%31%32%37...`
* **Punycode labels** — hostnames containing `xn--` labels
***
## Blocked ports
Even for trusted hostnames, Portkey blocks ports commonly used by non-HTTP internal services (SSH, databases, caches, admin APIs, etc.). Examples include `22`, `25`, `445`, `3306`, `5432`, `6379`, `6443`, `9200`, and `27017`.
HTTP and HTTPS service ports (such as `80`, `443`, `8000`, `8080`, `8443`) are allowed. Ports must be between `1` and `65535`.
***
## Trusted custom hosts (allowlist)
Portkey maintains a trusted hosts allowlist via the `TRUSTED_CUSTOM_HOSTS` environment variable. Trusted hostnames bypass private/reserved IP range checks at request time, and their DNS-resolved addresses bypass private/reserved IP checks at connection time.
> [!NOTE]
>
> `TRUSTED_CUSTOM_HOSTS` is available only on [self-hosted](/docs/self-hosting/hybrid-deployments/architecture) hybrid and air-gapped enterprise deployments of the Portkey AI Gateway.
### Default behavior
| Environment | `TRUSTED_CUSTOM_HOSTS` unset | Behavior |
| - | - | - |
| **Non-production** (`NODE_ENV` ≠ `production`) | Yes | Defaults to `localhost`, `127.0.0.1`, `::1`, and `host.docker.internal` |
| **Production** (`NODE_ENV` = `production`) | Yes | **Empty allowlist** — localhost and private IPs are blocked until you opt in |
| Any | Explicitly set | Uses **only** the hosts you specify (replaces defaults; does not merge) |
> [!WARNING]
>
> When setting `TRUSTED_CUSTOM_HOSTS` in non-production, include the default values (`localhost`, `127.0.0.1`, `::1`, `host.docker.internal`) along with your additions if you still need local development access.
### Adding hosts to the allowlist
To route to a private network IP (e.g., `172.31.2.45`), add it to the trusted hosts allowlist using the `TRUSTED_CUSTOM_HOSTS` environment variable.
Set the environment variable as a comma-separated list of hosts:
```bash theme={"system"}
TRUSTED_CUSTOM_HOSTS="localhost,127.0.0.1,::1,host.docker.internal,172.31.2.45,*.svc.internal"
```
Requests with `custom_host` set to `http://172.31.2.45:8008/v1/` will then pass validation.
### Entry format
Each entry can be:
| Format | Matches |
| - | - |
| `example.com` | Exact hostname only (`example.com`) |
| `*.example.com` | Apex domain and any subdomain (`example.com`, `api.example.com`, `v1.api.example.com`, etc.) |
| `172.31.2.45` | Exact IP literal only |
| `https://example.com:8080/path` | Normalized to `example.com` |
Wildcard entries (`*.domain`) are supported in `TRUSTED_CUSTOM_HOSTS`. Subdomains are **not** inherited from a bare domain entry — `example.com` does not allow `api.example.com`. To trust subdomains, add an explicit wildcard entry such as `*.example.com`.
Entries with schemes, ports, or paths are normalized automatically. Wildcard entries (`*.`) cannot target IP literals.
When `localhost` is trusted, subdomains ending in `.localhost` (e.g., `api.localhost`) are also allowed.
> [!WARNING]
>
> Cloud metadata endpoints, metadata FQDN suffixes, and wildcard DNS rebinding domains **cannot** be allowlisted. Entries that overlap always-blocked ranges are silently dropped from `TRUSTED_CUSTOM_HOSTS`.
### Validation rules for trusted hosts
Even for trusted hosts, Portkey enforces:
* **Port range** — The port must be between `1` and `65535`, and must not be on the blocked-ports list
* **Host-only matching** — Only the hostname or IP is checked against the allowlist, not the full URL
* **IP literals are exact-match only** — Trusting `127.0.0.1` does not unlock `x.127.0.0.1`
* **Subdomains require a wildcard** — Trusting `example.com` does not unlock `api.example.com`; add `*.example.com` to cover subdomains
* **Always-blocked overrides** — Cloud metadata, IMDS subnets, blocked hostname suffixes, wildcard rebinding domains, and dangerous IPv6-embedded-IPv4 forms remain blocked even when trusted
***
## Common scenarios
| Scenario | Default behavior | Action needed |
| - | - | - |
| **Local development** (e.g., Ollama on `localhost`) | Allowed in non-production — `localhost` and `127.0.0.1` are trusted by default | None in dev. In production, add to `TRUSTED_CUSTOM_HOSTS`. See the [Ollama integration guide](/docs/integrations/llms/ollama). |
| **Docker containers** (`host.docker.internal`) | Allowed in non-production — trusted by default | In production, add to `TRUSTED_CUSTOM_HOSTS` |
| **Private network IP** (e.g., `172.31.2.45:8008`) | Blocked — falls within `172.16.0.0/12` | Add the IP to `TRUSTED_CUSTOM_HOSTS` (hybrid/air-gapped only) |
| **Internal DNS name** (e.g., `llm.svc.internal`) | Blocked — `.internal` TLD | Add the hostname (or `*.svc.internal`) to `TRUSTED_CUSTOM_HOSTS` |
| **Cloud metadata** (`169.254.169.254`) | Always blocked | Cannot be allowlisted for security reasons |
| **DNS rebinding** (`127.0.0.1.nip.io`) | Always blocked | Cannot be allowlisted for security reasons |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Decisions
Source: https://docs.portkey.ai/docs/product/ai-gateway/decisions-api
Get typed judgments (probability, choice, or score) from models through Portkey's /v1/decisions endpoint.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
The Decisions API returns a **typed judgment** instead of generated text. Send the content to judge and a set of `questions`. The model returns one typed answer per question.
Use it for classification, routing, scoring, and yes/no checks, where a structured answer is needed and not free text.
> [!NOTE]
>
> `/v1/decisions` does not support streaming. A `stream` parameter in the request is ignored.
## Quick Start
Set `model` to `@integration-slug/model`. The integration holds the provider credentials, so no provider headers are needed.
Request shape depends on the provider. Workers AI (Cloudflare), TypeSafe, and OpenRouter use the **Jev shape**. OpenAI and Azure OpenAI use the **OpenAI shape**. The examples below are the same three questions in each shape.
```sh Jev shape theme={"system"}
curl --request POST \
--url https://api.portkey.ai/v1/decisions \
--header 'Content-Type: application/json' \
--header "x-portkey-api-key: $PORTKEY_API_KEY" \
--data '{
"model": "@your-cf-integration-slug/model",
"state": "I was charged twice for my order. Please return the extra charge.",
"questions": {
"refund_requested": {
"type": "noul",
"instructions": "Does the customer ask for a refund?"
},
"department": {
"type": "choice",
"instructions": "Which department should handle this complaint?",
"criteria": {
"billing": "Payments and refunds.",
"technical": "Product problems.",
"shipping": "Delivery and tracking.",
"other": "All other requests."
}
},
"severity": {
"type": "score",
"instructions": "How severe is this issue?",
"criteria": [
"Cosmetic: no lost functionality.",
"Workaround available: a task fails, but another way works.",
"Fully blocked: a task fails with no workaround."
]
}
}
}'
```
```sh OpenAI shape theme={"system"}
curl --request POST \
--url https://api.portkey.ai/v1/decisions \
--header 'Content-Type: application/json' \
--header "x-portkey-api-key: $PORTKEY_API_KEY" \
--data '{
"model": "@your-openai-integration-slug/gpt-6-luna",
"input": "I was charged twice for my order. Please return the extra charge.",
"questions": [
{
"type": "predicate",
"name": "refund_requested",
"instructions": "Does the customer ask for a refund?"
},
{
"type": "choice",
"name": "department",
"instructions": "Which department should handle this complaint?",
"choices": [
{"value": "billing", "description": "Payments and refunds."},
{"value": "technical", "description": "Product problems."},
{"value": "shipping", "description": "Delivery and tracking."},
{"value": "other", "description": "All other requests."}
]
},
{
"type": "score",
"name": "severity",
"instructions": "How severe is this issue?",
"levels": [
{"label": "Cosmetic", "description": "No lost functionality."},
{"label": "Workaround available", "description": "A task fails, but another way works."},
{"label": "Fully blocked", "description": "A task fails with no workaround."}
]
}
]
}'
```
Responses follow the shape of the request (values are illustrative):
```json Jev shape theme={"system"}
{
"model": "",
"answers": {
"refund_requested": { "type": "noul", "noul": 0.95 },
"department": {
"type": "choice",
"choice": "billing",
"probabilities": { "billing": 0.93, "technical": 0.03, "shipping": 0.01, "other": 0.03 },
"confidence": 0.9
},
"severity": {
"type": "score",
"score": 1.1,
"legend": {
"0": "Cosmetic: no lost functionality.",
"1": "Workaround available: a task fails, but another way works.",
"2": "Fully blocked: a task fails with no workaround."
},
"probabilities": { "0": 0.1, "1": 0.7, "2": 0.2 },
"confidence": 0.55
}
},
"usage": { "input_tokens": 162, "output_tokens": 0 },
"provider": "workers-ai"
}
```
```json OpenAI shape theme={"system"}
{
"model": "gpt-6-luna",
"answers": [
{ "type": "predicate", "name": "refund_requested", "probability": 0.95 },
{
"type": "choice",
"name": "department",
"choice": "billing",
"probabilities": [
{ "value": "billing", "probability": 0.93 },
{ "value": "technical", "probability": 0.03 },
{ "value": "shipping", "probability": 0.01 },
{ "value": "other", "probability": 0.03 }
],
"confidence": 0.9
},
{
"type": "score",
"name": "severity",
"score": 1.1,
"probabilities": [
{ "value": 0, "label": "Cosmetic", "probability": 0.1 },
{ "value": 1, "label": "Workaround available", "probability": 0.7 },
{ "value": 2, "label": "Fully blocked", "probability": 0.2 }
],
"confidence": 0.55
}
],
"usage": { "input_tokens": 162, "output_tokens": 0, "total_tokens": 162 },
"provider": "openai"
}
```
Either shape works with any provider. See [Switching Shapes](#switching-shapes).
## Supported Providers
| Provider | Slug | Native shape | Notes |
| :- | :- | :- | :- |
| [TypeSafe](/docs/integrations/llms/typesafe) | `typesafe` | Jev | `jev-latest` is the default model |
| [OpenRouter](/docs/integrations/llms/openrouter) | `openrouter` | Jev | Routes to Jev models |
| [Workers AI](/docs/integrations/llms/workers-ai) | `workers-ai` | Jev | Cloudflare model ID, for example `@your-cf-integration-slug/model` |
| [OpenAI](/docs/integrations/llms/openai) | `openai` | OpenAI | `gpt-6-luna` |
Any provider accepts either request shape. Portkey converts the request to the provider's native shape and converts the answers back. See [Switching Shapes](#switching-shapes).
## Request Shapes
The shape is detected from the body. A body that mixes fields from both shapes, or matches neither, returns `400`.
| Field | Jev shape | OpenAI shape |
| :- | :- | :- |
| Content to judge | `state`: string, object, or array | `input`: string, or user messages with `input_text` and `input_image` parts |
| Questions | `questions`: map of question ID to question | `questions`: array. Each question has a `name` |
| Yes/no type | `noul` | `predicate` |
| Choice options | `criteria`: map of label to description, or array of labels | `choices`: array of `{ value, description }` |
| Score levels | `criteria`: ordered array of labels or `{ label, description }` | `levels`: ordered array of `{ label, description }`, lowest to highest |
| `model` | Optional. Defaults to `jev-latest` | Required |
| Other | | `safety_identifier` |
## Question Types
Each question sets a `type`. The type sets the shape of the answer:
| Jev type | OpenAI type | Use for | Answer |
| :- | :- | :- | :- |
| `noul` | `predicate` | A yes/no judgment | Jev: `{ noul }`. OpenAI: `{ probability }`. A 0–1 probability |
| `choice` | `choice` | One label from a fixed set | `{ choice, probabilities, confidence }` |
| `score` | `score` | A position on an ordered scale | `{ score, probabilities, confidence }`, plus `legend` in the Jev shape |
A `score` is the probability-weighted average of the level indices, so it can fall between levels.
### Refusals
Any question can come back as `{ "type": "refusal" }` while other questions in the same request still return answers. In the OpenAI shape the refusal also carries the question `name`. Check each answer's `type` before reading its result.
Portkey also returns a refusal for a question the provider returned no answer for, when converting a Jev-shaped answer to the OpenAI shape.
## Response Shapes
| | Jev shape | OpenAI shape |
| :- | :- | :- |
| `answers` | Map keyed by question ID | Array, in question order |
| Choice and score `probabilities` | Map of label to probability | Array of `{ value, probability }`. Score entries also carry `label` |
| `usage` | `input_tokens`, `output_tokens` | Provider usage, passed through |
Every response includes `provider`, the slug that served the request.
## Switching Shapes
Portkey converts between shapes, so one request body works across providers. To fail over between a Jev provider and an OpenAI-native one, keep the same text-only body and switch the model per target.
```json Fallback config theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{ "override_params": { "model": "@your-typesafe-slug/jev-latest" } },
{ "override_params": { "model": "@your-openai-slug/gpt-6-luna" } }
]
}
```
Conversion rules:
* **Jev `state`** that is an object or array is JSON-stringified into `input`.
* **`noul` criteria** are appended to the question's `instructions`, since a `predicate` has no criteria field.
* **OpenAI `input`** is flattened to text for Jev providers. Only `input_text` parts are kept.
* **Unnamed questions** are keyed `q0`, `q1`, and so on.
Jev providers return a `400` for requests they cannot serve:
* `input_image` parts. Jev is text-only.
* `safety_identifier`.
* Duplicate question `name` values, since names become response keys.
## Errors
Upstream errors return the standard Portkey error shape. The message is prefixed with the provider slug, and `provider` is included:
```json theme={"system"}
{
"error": {
"message": "workers-ai error: model not found",
"type": "invalid_request_error",
"param": null,
"code": null
},
"provider": "workers-ai"
}
```
A `200` response from the provider without an `answers` field also returns an error, not an empty result.
## Gateway Features
Decisions requests go through the same gateway as other endpoints:
* **Routing** — Retries, fallbacks, load balancing, and circuit breaking through [Configs](/docs/product/ai-gateway/configs)
* **Caching** — [Simple and semantic caching](/docs/product/ai-gateway/cache-simple-and-semantic)
* **Guardrails** — Before-request checks on the content to judge only: `state` in the Jev shape, or the text in `input` in the OpenAI shape. See [Guardrails for Decisions](/docs/product/guardrails/decisions-guardrails)
* **Observability** — Logs, cost tracking, and analytics in [Observability](/docs/product/observability)
## API Reference
* [Create a Decision](/docs/api-reference/inference-api/decisions) -- `POST /v1/decisions`
> [card] [TypeSafe](/docs/integrations/llms/typesafe)
>
> Provider setup and pricing
> [card] [API Reference](/docs/api-reference/inference-api/decisions)
>
> Decisions API reference
> [card] [Universal API](/docs/product/ai-gateway/universal-api)
>
> All API formats
> [card] [Guardrails for Decisions](/docs/product/guardrails/decisions-guardrails)
>
> Scan the content to judge before it reaches the model
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Fallbacks
Source: https://docs.portkey.ai/docs/product/ai-gateway/fallbacks
Automatically switch to backup LLMs when the primary fails.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
Specify a prioritized list of providers/models. If the primary LLM fails, Portkey automatically falls back to the next in line.

## Examples
```json Between Models theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{ "override_params": { "model": "@openai-prod/gpt-4o" } },
{ "override_params": { "model": "@anthropic-prod/claude-3-5-sonnet-20241022" } }
]
}
```
```json Between Providers (model from request) theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{ "provider": "@openai-prod" },
{ "provider": "@azure-prod" }
]
}
```
```json On Rate Limit Only (429) theme={"system"}
{
"strategy": { "mode": "fallback", "on_status_codes": [429] },
"targets": [
{ "provider": "@openai-prod" },
{ "provider": "@azure-prod" }
]
}
```
```json Multi-tier Fallback theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{ "override_params": { "model": "@openai-prod/gpt-4o" } },
{ "override_params": { "model": "@anthropic-prod/claude-3-5-sonnet-20241022" } },
{ "override_params": { "model": "@google-prod/gemini-1.5-pro" } }
]
}
```
> [!NOTE]
>
> The `@provider-slug/model-name` format automatically routes to the correct provider. Set up providers in [Model Catalog](https://app.portkey.ai/model-catalog).
[Create](/docs/product/ai-gateway/configs#creating-configs) and [use](/docs/product/ai-gateway/configs#using-configs) configs in your requests.
## Trigger on Specific Status Codes
By default, fallback triggers on any **non-2xx** status code.
Customize with `on_status_codes`:
```json theme={"system"}
{
"strategy": { "mode": "fallback", "on_status_codes": [429, 503] },
"targets": [
{ "provider": "@openai-prod" },
{ "provider": "@azure-prod" }
]
}
```
## Tracing Fallback Requests
Portkey logs all requests in a fallback chain. To trace:
1. Filter logs by `Config ID` to see all requests using that config
2. Filter by `Trace ID` to see all attempts for a single request

## Combine with Other Strategies
Fallback targets are fully composable — each target can be a load balancer, a conditional router, or another fallback. Any strategy can nest inside any other.
> [card] [Fallback When the Whole Cluster Goes Down](/docs/guides/use-cases/combining-routing-strategies#fallback-when-the-whole-cluster-goes-down)
>
> The primary target is a load balancer cluster. Individual endpoint failures stay within the cluster — only a full provider outage triggers the cross-model backup.
> [card] [Smart Failover by Request Context](/docs/guides/use-cases/combining-routing-strategies#smart-failover-by-request-context)
>
> When the primary fails, a conditional router picks the best backup based on request context — keeping EU users on EU infrastructure even during outages.
> [card] [Isolate Failures Between Model Families](/docs/guides/use-cases/combining-routing-strategies#isolate-failures-between-model-families)
>
> Give each load-balanced slot its own independent fallback chain. One model family failing doesn't trigger another family's backup.
> [card] [All Patterns Together](/docs/guides/use-cases/combining-routing-strategies#the-full-config)
>
> See a complete config combining conditional routing, load balancing, and fallbacks across four model families.
## Considerations
* Ensure fallback LLMs are compatible with your use case
* A single request may invoke multiple LLMs
* Each LLM has different latency and pricing
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Files
Source: https://docs.portkey.ai/docs/product/ai-gateway/files
Upload files to Portkey and reuse the content in your requests
Portkey supports managing files in two ways:
1. **Provider Files**: Uploading and managing files directly to any provider using the unified signature
2. **Portkey Files**: Uploading files to Portkey and using them for batching/fine-tuning requests with any provider
***
## 1. Provider Files
Upload and manage files directly to providers (OpenAI, Bedrock, etc.) using Portkey's unified API signature. This approach is useful when you need provider-specific file features or want to manage files directly on the provider's platform.
### Supported Providers
* [Anthropic](/docs/integrations/llms/anthropic#files-api)
* [OpenAI](/docs/integrations/llms/openai/files)
* [Bedrock](/docs/integrations/llms/bedrock/files)
* [Azure OpenAI](/docs/integrations/llms/azure-openai/files)
* [Fireworks](/docs/integrations/llms/fireworks/files)
* [Vertex AI](/docs/integrations/llms/vertex-ai/files)
### Quick Example
```bash theme={"system"}
curl -X POST https://api.portkey.ai/v1/files \
-H "Authorization: Bearer $PORTKEY_API_KEY" \
-H "x-portkey-provider: openai" \
-F "purpose=fine-tune" \
-F "file=@training_data.jsonl"
```
***
## 2. Portkey Files
Upload files to Portkey and reuse them for [batching inference](/docs/product/ai-gateway/batches) with any provider and [fine-tuning](/docs/product/ai-gateway/fine-tuning) with supported providers. This approach is ideal for:
* Testing your data with different foundation models
* Performing A/B testing across multiple providers
* Batch inference with provider-agnostic file management
* Reusing the same file across multiple batch jobs
### File Requirements
* **Format**: JSONL files where each line contains a single request payload
### Uploading Files
```bash curl theme={"system"}
curl -X POST https://api.portkey.ai/v1/files \
-H "Authorization: Bearer $PORTKEY_API_KEY" \
-F "purpose=batch" \
-F "file=@batch_data.jsonl"
```
```javascript Typescript theme={"system"}
import Portkey from 'portkey-ai';
const client = new Portkey({
apiKey: 'PORTKEY_API_KEY'
});
const file = await client.files.create({
purpose: 'batch',
file: fs.createReadStream('batch_data.jsonl')
});
console.log(file);
```
```python Python theme={"system"}
from portkey_ai import Portkey
client = Portkey(api_key="PORTKEY_API_KEY")
with open('batch_data.jsonl', 'rb') as f:
file = client.files.create(
purpose='batch',
file=f
)
print(file)
```
### Listing Files
```bash curl theme={"system"}
curl -X GET https://api.portkey.ai/v1/files \
-H "Authorization: Bearer $PORTKEY_API_KEY"
```
```javascript Typescript theme={"system"}
const files = await client.files.list();
console.log(files);
```
```python Python theme={"system"}
files = client.files.list()
print(files)
```
### Get File Details
```bash curl theme={"system"}
curl -X GET https://api.portkey.ai/v1/files/{file_id} \
-H "Authorization: Bearer $PORTKEY_API_KEY"
```
```javascript Typescript theme={"system"}
const file = await client.files.retrieve('file_abc123');
console.log(file);
```
```python Python theme={"system"}
file = client.files.retrieve('file_abc123')
print(file)
```
### Get File Content
```bash curl theme={"system"}
curl -X GET https://api.portkey.ai/v1/files/{file_id}/content \
-H "Authorization: Bearer $PORTKEY_API_KEY"
```
```javascript Typescript theme={"system"}
const content = await client.files.content('file_abc123');
console.log(content);
```
```python Python theme={"system"}
content = client.files.content('file_abc123')
print(content)
```
***
## File Format Examples
### Batch Inference JSONL Format
Each line should be a valid JSON object representing a single request:
```jsonl theme={"system"}
{"custom_id": "request-1", "method": "POST", "url": "/v1/chat/completions", "body": {"model": "gpt-3.5-turbo-0125", "messages": [{"role": "system", "content": "You are a helpful assistant."},{"role": "user", "content": "Hello world!"}],"max_tokens": 1000}}
{"custom_id": "request-2", "method": "POST", "url": "/v1/chat/completions", "body": {"model": "gpt-3.5-turbo-0125", "messages": [{"role": "system", "content": "You are an unhelpful assistant."},{"role": "user", "content": "Hello world!"}],"max_tokens": 1000}}
```
### Fine-tuning JSONL Format
For fine-tuning, each line should contain training examples:
```jsonl theme={"system"}
{"messages": [{"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": "Hello"}, {"role": "assistant", "content": "Hi! How can I help you today?"}]}
{"messages": [{"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": "What's 2+2?"}, {"role": "assistant", "content": "2+2 equals 4."}]}
```
***
## Security & Best Practices
* **Encryption**: Files are encrypted at rest using AES-256
* **Access Control**: File access is gated by workspace permissions
* **Provider Upload**: Portkey uploads files to providers using least-privilege credentials
***
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Fine-tuning
Source: https://docs.portkey.ai/docs/product/ai-gateway/fine-tuning
Run your fine-tuning jobs with Portkey Gateway
> [!NOTE]
>
> [Data Service](/docs/changelog/data-service) must be enabled for **Portkey Managed Fine-tuning** or when **cost-attribution** is required.
Portkey Gateway supports fine-tuning in two ways:
1. Fine-tuning with portkey as a provider, supports multiple providers with a single unified API.
2. Fine-tuning with Portkey as a client, supports following providers:
* [OpenAI](/docs/integrations/llms/openai/fine-tuning)
* [Bedrock](/docs/integrations/llms/bedrock/fine-tuning)
* [Azure OpenAI](/docs/integrations/llms/azure-openai/fine-tuning)
* [Fireworks](/docs/integrations/llms/fireworks/fine-tuning)
* [Vertex](/docs/integrations/llms/vertex-ai/fine-tuning)
## 1. Fine-tuning with Portkey as a client
With Portkey acting as a client, gives you the following benefits:
1. Provider specific fine-tuning.
2. More control over the fine-tuning process.
3. Unified API for all providers.
## 2. Fine-tuning with Portkey as a provider
With Portkey acting as provider, gives you the following benefits:
1. Unified API for all providers
2. No need to manage multiple endpoints and keys
3. Easy to switch between providers with limited changes
4. Easier integration with Portkey's other features like batching, etc.
## How to use fine-tuning
Portkey supports a Unified Fine-tuning API for all providers which is based on OpenAI's Fine-tuning API.
While the signature of API is same for all providers, there are places where a specific provider require some more information which can be passed via headers if used as a client, or by `portkey_options` params if used as a provider.
### Fine-tuning with Portkey as a client
**Upload a File**
```sh theme={"system"}
curl -X POST --header 'x-portkey-api-key: ' \
--form 'file=@dataset.jsonl' \
--form 'purpose=fine-tune' \
'https://api.portkey.ai/v1/files'
```
> [!NOTE]
>
> Learn more about [files](/docs/product/ai-gateway/files)
**Create a Fine-tuning Job**
```sh theme={"system"}
curl -X POST --header 'Content-Type: application/json' \
--header 'x-portkey-api-key: ' \
--data \
$'{"model": "", "suffix": "", "training_file": "", "portkey_options": {"x-portkey-provider": "@openai-prod"}, "method": {"type": "supervised", "supervised": {"hyperparameters": {"n_epochs": 1}}}}\n' \
'https://api.portkey.ai/v1/fine_tuning/jobs'
```
> [!TIP]
>
> `portkey_options` supports all the options that are supported by each provider
> in the gateway. Values can be provider specific, refer to provider's
> documentation for each provider's specific options required for fine-tuning.
**List Fine-tuning Jobs**
```sh theme={"system"}
curl -X GET --header 'x-portkey-api-key: ' \
'https://api.portkey.ai/v1/fine_tuning/jobs'
```
**Get Fine-tuning Job**
```sh theme={"system"}
curl -X GET --header 'x-portkey-api-key: ' \
'https://api.portkey.ai/v1/fine_tuning/jobs/'
```
**Cancel Fine-tuning Job**
```sh theme={"system"}
curl -X POST --header 'x-portkey-api-key: ' \
'https://api.portkey.ai/v1/fine_tuning/jobs//cancel'
```
When you use Portkey as a provider for fine-tuning, everything is managed by Portkey hosted solution, this includes job submission with provider, monitoring job status and able to use the fine-tuned model with Portkey's Prompt Playground.
> [!NOTE]
>
> Providers like OpenAI, Azure OpenAPI does provider a straight forward approach
> to use the fine-tuned model for inference whereas providers like `Bedrock` abd
> `Vertex` does require you to manually provide compute which is hard for
> portkey to manage.
**Notes**:
* For `Bedrock`, `model` param should point to the `modelId` from `portkey` and the `modelId` to submit to the provider should be passed via `provider_options`. Example is available below.
```sh theme={"system"}
curl -X POST --header 'Content-Type: application/json' \
--header 'x-portkey-api-key: ' \
--data \
$'{"model": "amazon.titan-text-lite-v1:0", "suffix": "", "training_file": "", "provider_options": {"model": "amazon.titan-text-lite-v1:0:4k"}, "method": {"type": "supervised", "supervised": {"hyperparameters": {"n_epochs": 1}}}}\n' \
'https://api.portkey.ai/v1/fine_tuning/jobs'
```
> For more info about `modelId`, please refer to the provider's documentation.
Please refer to the provider's documentation for fine-tuning with Portkey as a gateway.
1. [OpenAI](/docs/integrations/llms/openai/fine-tuning)
2. [Bedrock](/docs/integrations/llms/bedrock/fine-tuning)
3. [Azure OpenAI](/docs/integrations/llms/azure-openai/fine-tuning)
4. [Fireworks](/docs/integrations/llms/fireworks/fine-tuning)
5. [Vertex](/docs/integrations/llms/vertex-ai/fine-tuning)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# gRPC (Beta)
Source: https://docs.portkey.ai/docs/product/ai-gateway/grpc
Use gRPC as an alternative transport protocol for lower latency and efficient binary serialization
> [!NOTE]
>
> **Enterprise Feature** \
> gRPC support is available on **Enterprise** self-hosted plans only. Contact the [Portkey team](/docs/support/contact-us) to enable it for your gateway deployment.
> [!NOTE]
>
> gRPC support is currently in **beta**. The API surface may change based on feedback.
The Portkey Gateway supports **gRPC** as an alternative transport protocol alongside HTTP/REST. This enables lower latency, efficient binary serialization via Protocol Buffers, and native streaming support for applications that prefer gRPC communication.
## How It Works
The gateway operates in two modes depending on the provider:
| Mode | Description | Use Case |
| - | - | - |
| **gRPC → HTTP Proxy** | Gateway accepts gRPC requests and converts them to HTTP internally | Works with all providers |
| **Native gRPC** | Gateway connects to the provider's native gRPC endpoint directly | Lower latency for supported providers (e.g., Google Gemini) |
```mermaid theme={"system"}
flowchart TD
subgraph gateway["Portkey Gateway"]
grpc["gRPC Server\n(port 8789)"]
router["Route Handler"]
proxy["HTTP Proxy\n(all providers)"]
native["Native gRPC\n(Google Gemini)"]
grpc --> router
router --> proxy
router --> native
end
proxy --> llm["LLM Provider\n(HTTP API)"]
native --> gemini["Google Gemini\n(gRPC API)"]
```
For providers without a native gRPC endpoint, the gateway transparently proxies gRPC requests over HTTP — so **every provider** supported by Portkey works out of the box. When a provider *does* expose a native gRPC API (currently Google Gemini), the gateway connects directly for optimal performance.
## Starting the gRPC Server
### Command Line Flags
```bash theme={"system"}
# Start only the gRPC server (default port 8789)
npm start -- --llm-grpc
# Start both HTTP and gRPC servers
npm start -- --llm-node --llm-grpc
# With custom ports
npm start -- --llm-node --llm-grpc --port 8787 --grpc-port 50051
```
### Environment Variables
| Variable | Default | Description |
| - | - | - |
| `GRPC_PORT` | `8789` | Port for the gRPC server |
| `PORT` | `8787` | Port for the HTTP server (used as base URL for internal routing) |
### Enabling TLS
The gRPC server supports TLS using the same certificates as the HTTP server:
```bash theme={"system"}
TLS_KEY_PATH=/path/to/key.pem \
TLS_CERT_PATH=/path/to/cert.pem \
npm start -- --llm-grpc
```
## Authentication
Pass your Portkey API key as gRPC metadata:
| Metadata Key | Description |
| - | - |
| `x-portkey-api-key` | Your Portkey API key |
With the [Model Catalog](/docs/product/model-catalog), the provider is specified in the model string itself (`@provider_slug/model_name`), so separate provider headers are typically not needed.
## Making Requests
All request bodies are sent as a JSON string in the `input` field of the `GatewayRequest` message. Each endpoint returns responses in a consistent format matching the API you called, regardless of the underlying provider:
* **ChatCompletions** and **Embeddings** — OpenAI-compatible format
* **Messages** — Anthropic Messages format
* **Responses** — OpenAI Responses API format
The gateway handles all provider-to-format translation automatically — you always get the format matching the endpoint you called, no matter which LLM is behind it.
### Model String Format
Portkey uses the [Model Catalog](/docs/product/model-catalog) format for model strings:
```
@provider_slug/model_name
```
Examples: `@openai/gpt-4o`, `@gemini/gemini-2.0-flash`, `@anthropic/claude-3-opus-20240229`, `@azure-openai/gpt-4`
### Chat Completions
> [tab] grpcurl
>
> ```bash theme={"system"}
> # Non-streaming
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@openai/gpt-4o\", \"messages\": [{\"role\": \"user\", \"content\": \"Hello!\"}]}"
> }' \
> localhost:8789 gateway.Gateway/ChatCompletions
> ```
>
> ```bash theme={"system"}
> # Streaming
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@openai/gpt-4o\", \"messages\": [{\"role\": \"user\", \"content\": \"Count from 1 to 5\"}], \"stream\": true}"
> }' \
> localhost:8789 gateway.Gateway/ChatCompletionsStream
> ```
> [tab] Python (grpcio)
>
> ```python theme={"system"}
> import grpc
> import json
>
> # Generate Python stubs from proto:
> # python -m grpc_tools.protoc -I. --python_out=. --grpc_python_out=. gateway.proto
>
> import gateway_pb2
> import gateway_pb2_grpc
>
> channel = grpc.insecure_channel('localhost:8789')
> stub = gateway_pb2_grpc.GatewayStub(channel)
>
> metadata = [
> ('x-portkey-api-key', 'YOUR_PORTKEY_KEY'),
> ]
>
> # Non-streaming
> request = gateway_pb2.GatewayRequest(
> input=json.dumps({
> "model": "@openai/gpt-4o",
> "messages": [{"role": "user", "content": "Hello!"}]
> })
> )
>
> response = stub.ChatCompletions(request, metadata=metadata)
> print(f"Status: {response.status_code}")
> print(f"Response: {response.body.decode('utf-8')}")
>
> # Streaming
> stream_request = gateway_pb2.GatewayRequest(
> input=json.dumps({
> "model": "@openai/gpt-4o",
> "messages": [{"role": "user", "content": "Count to 5"}],
> "stream": True
> })
> )
>
> for chunk in stub.ChatCompletionsStream(stream_request, metadata=metadata):
> print(f"Chunk: {chunk.data.decode('utf-8')}")
> ```
> [tab] Node.js (@grpc/grpc-js)
>
> ```javascript theme={"system"}
> // Using CommonJS require() for compatibility.
> // For ESM, use: import grpc from '@grpc/grpc-js';
> const grpc = require('@grpc/grpc-js');
> const protoLoader = require('@grpc/proto-loader');
>
> const packageDefinition = protoLoader.loadSync('gateway.proto', {
> keepCase: true,
> longs: String,
> enums: String,
> defaults: true,
> oneofs: true,
> });
>
> const gatewayProto = grpc.loadPackageDefinition(packageDefinition).gateway;
>
> const client = new gatewayProto.Gateway(
> 'localhost:8789',
> grpc.credentials.createInsecure()
> );
>
> const metadata = new grpc.Metadata();
> metadata.set('x-portkey-api-key', 'YOUR_PORTKEY_KEY');
>
> // Non-streaming
> client.ChatCompletions(
> {
> input: JSON.stringify({
> model: '@openai/gpt-4o',
> messages: [{ role: 'user', content: 'Hello!' }],
> }),
> },
> metadata,
> (error, response) => {
> if (error) {
> console.error('Error:', error);
> return;
> }
> console.log('Status:', response.status_code);
> console.log('Response:', response.body.toString('utf-8'));
> }
> );
>
> // Streaming
> const call = client.ChatCompletionsStream(
> {
> input: JSON.stringify({
> model: '@openai/gpt-4o',
> messages: [{ role: 'user', content: 'Count to 5' }],
> stream: true,
> }),
> },
> metadata
> );
>
> call.on('data', (chunk) => {
> console.log('Chunk:', chunk.data.toString('utf-8'));
> });
>
> call.on('end', () => {
> console.log('Stream ended');
> });
>
> call.on('error', (error) => {
> console.error('Stream error:', error);
> });
> ```
### Anthropic Messages
> [tab] grpcurl
>
> ```bash theme={"system"}
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@anthropic/claude-3-opus-20240229\", \"messages\": [{\"role\": \"user\", \"content\": \"What is the capital of France?\"}], \"max_tokens\": 100}"
> }' \
> localhost:8789 gateway.Gateway/Messages
> ```
> [tab] grpcurl (Streaming)
>
> ```bash theme={"system"}
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@anthropic/claude-3-opus-20240229\", \"messages\": [{\"role\": \"user\", \"content\": \"What is the capital of France?\"}], \"max_tokens\": 100, \"stream\": true}"
> }' \
> localhost:8789 gateway.Gateway/MessagesStream
> ```
### OpenAI Responses
> [tab] grpcurl
>
> ```bash theme={"system"}
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@openai/gpt-4o\", \"input\": \"Tell me a joke\"}"
> }' \
> localhost:8789 gateway.Gateway/Responses
> ```
> [tab] grpcurl (Streaming)
>
> ```bash theme={"system"}
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@openai/gpt-4o\", \"input\": \"Tell me a joke\", \"stream\": true}"
> }' \
> localhost:8789 gateway.Gateway/ResponsesStream
> ```
### Embeddings
```bash theme={"system"}
grpcurl -plaintext \
-H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
-d '{
"input": "{\"model\": \"@openai/text-embedding-3-small\", \"input\": \"The quick brown fox jumps over the lazy dog\"}"
}' \
localhost:8789 gateway.Gateway/Embeddings
```
### Health Check
```bash theme={"system"}
grpcurl -plaintext localhost:8789 gateway.Gateway/Health
```
```json theme={"system"}
{
"status": "success",
"message": "Server is healthy",
"version": "1.x.x"
}
```
## Native gRPC Providers
When a provider exposes a native gRPC API, the gateway bypasses HTTP entirely and makes direct gRPC calls for the lowest possible latency.
| Provider | Transport | Streaming | Endpoint |
| - | - | - | - |
| Google Gemini | Native gRPC | Yes | `generativelanguage.googleapis.com:443` |
| OpenAI | HTTP proxy | Yes | — |
| Anthropic | HTTP proxy | Yes | — |
| Azure OpenAI | HTTP proxy | Yes | — |
### How Native gRPC Works
When a request targets a native gRPC provider, the gateway:
1. Detects the gRPC transport via the `x-portkey-gateway-transport: grpc` header
2. Transforms the request into the provider's native gRPC format
3. Makes a direct gRPC call to the provider's endpoint
4. Transforms the response back to the format matching the endpoint you called
This eliminates HTTP/JSON serialization overhead, uses efficient binary Protocol Buffer encoding, and maintains persistent gRPC connections with client caching.
> [tab] Gemini (Non-Streaming)
>
> ```bash theme={"system"}
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@gemini/gemini-2.0-flash\", \"messages\": [{\"role\": \"user\", \"content\": \"Hello!\"}]}"
> }' \
> localhost:8789 gateway.Gateway/ChatCompletions
> ```
> [tab] Gemini (Streaming)
>
> ```bash theme={"system"}
> grpcurl -plaintext \
> -H 'x-portkey-api-key: YOUR_PORTKEY_KEY' \
> -d '{
> "input": "{\"model\": \"@gemini/gemini-2.0-flash\", \"messages\": [{\"role\": \"user\", \"content\": \"Explain quantum computing\"}], \"stream\": true}"
> }' \
> localhost:8789 gateway.Gateway/ChatCompletionsStream
> ```
> [!TIP]
>
> The gateway handles all format transformations automatically — you send requests in the format matching the endpoint (Chat Completions, Messages, or Responses) and receive responses in that same format, regardless of the underlying provider.
## gRPC Service Definition
The gateway exposes a single `Gateway` service with the following methods:
```protobuf theme={"system"}
service Gateway {
// Health check
rpc Health(Empty) returns (HealthResponse);
// Embeddings (non-streaming)
rpc Embeddings(GatewayRequest) returns (GatewayResponse);
// Chat completions
rpc ChatCompletions(GatewayRequest) returns (GatewayResponse);
rpc ChatCompletionsStream(GatewayRequest) returns (stream StreamChunk);
// Anthropic Messages
rpc Messages(GatewayRequest) returns (GatewayResponse);
rpc MessagesStream(GatewayRequest) returns (stream StreamChunk);
// OpenAI Responses
rpc Responses(GatewayRequest) returns (GatewayResponse);
rpc ResponsesStream(GatewayRequest) returns (stream StreamChunk);
}
```
### Message Types
```protobuf theme={"system"}
message GatewayRequest {
string input = 1; // JSON request body
}
message GatewayResponse {
int32 status_code = 1;
bytes body = 2; // JSON response body
}
message StreamChunk {
bytes data = 1; // SSE-formatted chunk data
}
message HealthResponse {
string status = 1;
string message = 2;
string version = 3;
}
```
### Service Discovery
The gRPC server supports reflection, enabling service discovery with tools like `grpcurl`:
```bash theme={"system"}
# List all services
grpcurl -plaintext localhost:8789 list
# Describe the Gateway service
grpcurl -plaintext localhost:8789 describe gateway.Gateway
# Describe a specific method
grpcurl -plaintext localhost:8789 describe gateway.Gateway.ChatCompletions
```
## Response Format
The `GatewayResponse` contains an HTTP status code and a JSON body. The response format depends on which endpoint you called — the gateway ensures consistency regardless of the underlying provider.
### ChatCompletions
Returns the standard OpenAI Chat Completions format:
> [tab] Non-Streaming
>
> ```json theme={"system"}
> {
> "id": "portkey-xxx",
> "object": "chat.completion",
> "created": 1234567890,
> "model": "gemini-2.0-flash",
> "provider": "google",
> "choices": [
> {
> "index": 0,
> "message": {
> "role": "assistant",
> "content": "Hello! How can I help you today?"
> },
> "finish_reason": "stop"
> }
> ],
> "usage": {
> "prompt_tokens": 10,
> "completion_tokens": 15,
> "total_tokens": 25
> }
> }
> ```
> [tab] Streaming
>
> Each `StreamChunk` contains SSE-formatted data:
>
> ```
> data: {"id":"portkey-xxx","object":"chat.completion.chunk","choices":[{"index":0,"delta":{"role":"assistant","content":"Hello"},"finish_reason":null}]}
>
> data: {"id":"portkey-xxx","object":"chat.completion.chunk","choices":[{"index":0,"delta":{"content":"!"},"finish_reason":null}]}
>
> data: {"id":"portkey-xxx","object":"chat.completion.chunk","choices":[{"index":0,"delta":{},"finish_reason":"stop"}],"usage":{"prompt_tokens":10,"completion_tokens":2,"total_tokens":12}}
>
> data: [DONE]
> ```
### Messages (Anthropic)
Returns the Anthropic Messages format — even when the underlying provider is not Anthropic (e.g., calling `Messages` with `@openai/gpt-4o`):
```json theme={"system"}
{
"id": "msg_xxx",
"type": "message",
"role": "assistant",
"content": [
{
"type": "text",
"text": "The capital of France is Paris."
}
],
"model": "claude-3-opus-20240229",
"stop_reason": "end_turn",
"usage": {
"input_tokens": 14,
"output_tokens": 10
}
}
```
### Responses (OpenAI Responses API)
Returns the OpenAI Responses API format:
```json theme={"system"}
{
"id": "resp_xxx",
"object": "response",
"created_at": 1234567890,
"model": "gpt-4o",
"output": [
{
"type": "message",
"role": "assistant",
"content": [
{
"type": "output_text",
"text": "Why did the chicken cross the road? To get to the other side!"
}
]
}
],
"usage": {
"input_tokens": 8,
"output_tokens": 18,
"total_tokens": 26
}
}
```
### Response Metadata
HTTP response headers are returned as gRPC trailing metadata:
```
x-portkey-trace-id: xxx-xxx-xxx
x-portkey-provider: google
x-portkey-cache-status: DISABLED
x-portkey-retry-attempt-count: 0
```
## Error Handling
Provider and request errors are returned inside the `GatewayResponse.status_code` field, not as gRPC status codes on the wire. The gRPC call itself will return `OK` unless there is a gateway infrastructure failure (e.g., server crash, proto parse error).
Use the table below to interpret the `status_code` value in the response:
| Status Code | Equivalent gRPC Status | Description |
| - | - | - |
| 200 | `OK` | Success |
| 400 | `INVALID_ARGUMENT` | Bad request |
| 401 | `UNAUTHENTICATED` | Invalid API key |
| 403 | `PERMISSION_DENIED` | Access denied |
| 404 | `NOT_FOUND` | Resource not found |
| 429 | `RESOURCE_EXHAUSTED` | Rate limited |
| 500 | `INTERNAL` | Server error |
| 503 | `UNAVAILABLE` | Service unavailable |
| 504 | `DEADLINE_EXCEEDED` | Timeout |
> [!NOTE]
>
> Always check `GatewayResponse.status_code` to detect errors — do not rely on the gRPC call status alone.
Error responses include details in the body:
```json theme={"system"}
{
"error": {
"message": "Invalid API key",
"type": "authentication_error",
"code": "invalid_api_key"
}
}
```
## When to Use gRPC vs HTTP
| Use gRPC when... | Use HTTP when... |
| - | - |
| You need the lowest possible latency | You have browser-based clients (gRPC-Web requires a proxy) |
| You have high-throughput streaming workloads | You need simple integrations with widely supported REST |
| You're in a service-to-service architecture with protobuf | You need easy debugging with standard HTTP tools |
| You want native gRPC connections to providers like Google Gemini | |
### Connection Management
The gateway maintains a cache of gRPC client connections:
* Connections are reused per API key for efficiency
* Stale connections are automatically cleaned up
* Default timeout: **60 seconds** (300 seconds for streaming)
## Limitations
> [!WARNING]
>
> The following limitations apply during the beta period:
* WebSocket-based realtime endpoints (`/v1/realtime`) are **not** available via gRPC
* File upload/download operations use HTTP proxy mode only
* Batch operations use HTTP proxy mode only
* Only server-side streaming is supported (no bidirectional streaming)
## Troubleshooting
### Connection Refused
```
Error: 14 UNAVAILABLE: Connection refused
```
Ensure the gRPC server is running with the `--llm-grpc` flag:
```bash theme={"system"}
npm start -- --llm-grpc
```
### Authentication Errors
```
Error: 16 UNAUTHENTICATED
```
Verify your Portkey API key is correctly passed as gRPC metadata:
```bash theme={"system"}
grpcurl -H 'x-portkey-api-key: YOUR_KEY' ...
```
### INVALID\_ARGUMENT Errors
```
Error: 3 INVALID_ARGUMENT
```
Check that your request JSON is valid and properly escaped in the `input` field. Ensure the model string follows the `@provider_slug/model_name` format.
### Timeout Issues
For long-running requests, increase the client-side timeout:
> [tab] Python
>
> ```python theme={"system"}
> response = stub.ChatCompletions(
> request,
> metadata=metadata,
> timeout=120.0 # 120 seconds
> )
> ```
> [tab] Node.js
>
> ```javascript theme={"system"}
> client.ChatCompletions(
> request,
> metadata,
> { deadline: Date.now() + 120000 },
> callback
> );
> ```
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Load Balancing
Source: https://docs.portkey.ai/docs/product/ai-gateway/load-balancing
Distribute traffic across multiple LLMs for high availability and optimal performance.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
Distribute traffic across multiple LLMs to prevent any single provider from becoming a bottleneck.
## Examples
```json Between Providers (model from request) theme={"system"}
{
"strategy": { "mode": "loadbalance" },
"targets": [
{ "provider": "@openai-prod", "weight": 0.7 },
{ "provider": "@azure-prod", "weight": 0.3 }
]
}
```
```json Between Models theme={"system"}
{
"strategy": { "mode": "loadbalance" },
"targets": [
{ "override_params": { "model": "@openai-prod/gpt-4o" }, "weight": 0.75 },
{ "override_params": { "model": "@anthropic-prod/claude-3-5-sonnet-20241022" }, "weight": 0.25 }
]
}
```
```json Multiple API Keys (same provider) theme={"system"}
{
"strategy": { "mode": "loadbalance" },
"targets": [
{ "provider": "@openai-key-1", "weight": 1 },
{ "provider": "@openai-key-2", "weight": 1 },
{ "provider": "@openai-key-3", "weight": 1 }
]
}
```
```json Cost Optimization (cheap vs premium) theme={"system"}
{
"strategy": { "mode": "loadbalance" },
"targets": [
{ "override_params": { "model": "@openai-prod/gpt-4o-mini" }, "weight": 0.8 },
{ "override_params": { "model": "@openai-prod/gpt-4o" }, "weight": 0.2 }
]
}
```
```json Gradual Migration (old to new model) theme={"system"}
{
"strategy": { "mode": "loadbalance" },
"targets": [
{ "override_params": { "model": "@anthropic-prod/claude-3-5-sonnet-20241022" }, "weight": 0.9 },
{ "override_params": { "model": "@anthropic-prod/claude-sonnet-4-20250514" }, "weight": 0.1 }
]
}
```
| Pattern | Use Case |
| - | - |
| **Between Providers** | Route to different providers; model comes from request |
| **Multiple API Keys** | Distribute load across rate limits from different accounts |
| **Cost Optimization** | Send most traffic to cheaper models, reserve premium for a portion |
| **Gradual Migration** | Test new models with small percentage before full rollout |
> [!NOTE]
>
> The `@provider-slug/model-name` format automatically routes to the correct provider. Set up providers in [Model Catalog](https://app.portkey.ai/model-catalog).
[Create](/docs/product/ai-gateway/configs#creating-configs) and [use](/docs/product/ai-gateway/configs#using-configs) configs in your requests.
## How It Works
1. **Define targets & weights** — Assign a `weight` to each target. Weights represent relative share of traffic.
2. **Weight normalization** — Portkey normalizes weights to sum to 100%. Example: weights 5, 3, 1 become 55%, 33%, 11%.
3. **Request distribution** — Each request routes to a target based on normalized probabilities.
> [!NOTE]
>
> * Default `weight`: `1`
> * Minimum `weight`: `0` (stops traffic without removing from config)
> * Unset weights default to `1`
## Considerations
* Ensure LLMs in your list are compatible with your use case
* Monitor usage per LLM—weight distribution affects spend
* Each LLM has different latency and pricing
## Sticky Load Balancing
Sticky load balancing ensures that requests with the same identifier are consistently routed to the same target. This is useful for:
* Maintaining conversation context across multiple requests
* Ensuring consistent model behavior for A/B testing
* Session-based routing for user-specific experiences
### Configuration
Add `sticky` to your load balancing strategy:
```json theme={"system"}
{
"strategy": {
"mode": "loadbalance",
"sticky": {
"enabled": true,
"hash_fields": ["metadata.user_id"],
"ttl": 3600
}
},
"targets": [
{
"provider": "@openai-prod",
"weight": 0.5
},
{
"provider": "@anthropic-prod",
"weight": 0.5
}
]
}
```
### Parameters
| Parameter | Type | Description |
| - | - | - |
| `enabled` | boolean | Turns sticky routing on or off. Must be `true` to activate sticky behavior. If omitted or `false`, sticky routing is disabled and normal weighted load balancing is used. |
| `hash_fields` | array | Fields to use for generating the sticky session identifier. Supports dot notation for nested fields (e.g., `metadata.user_id`, `metadata.session_id`) |
| `ttl` | number | Time-to-live in seconds for the sticky session. After this period, a new target may be selected. Default: 3600 (1 hour) |
### How It Works
1. **Identifier Generation**: When a request arrives, Portkey generates a hash from the specified `hash_fields` values
2. **Target Lookup**: The hash is used to look up the previously assigned target from cache
3. **Consistent Routing**: If a cached assignment exists and hasn't expired, the request goes to the same target
4. **New Assignment**: If no cached assignment exists, a new target is selected based on weights and cached for future requests
> [!NOTE]
>
> Sticky sessions use a two-tier cache system (in-memory + Redis) for fast lookups and persistence across gateway instances in distributed deployments.
## Combine with Other Strategies
Load balancing is composable with conditional routing and fallbacks — use it as a target inside another strategy, or nest other strategies inside each load-balanced slot.
> [card] [Scale One Model Across Multiple Providers](/docs/guides/use-cases/combining-routing-strategies#scale-one-model-across-multiple-providers)
>
> Use a conditional router to match a model alias, then send that branch to a load balancer across Anthropic, Vertex AI, and Bedrock.
> [card] [Fallback When the Whole Cluster Goes Down](/docs/guides/use-cases/combining-routing-strategies#fallback-when-the-whole-cluster-goes-down)
>
> Wrap a load balancer cluster in a fallback — individual failures stay within the cluster; only a full outage triggers the cross-model backup.
> [card] [Isolate Failures Between Model Families](/docs/guides/use-cases/combining-routing-strategies#isolate-failures-between-model-families)
>
> Give each load-balanced slot its own independent fallback. An OpenAI outage only affects that slot — the other models route normally.
> [card] [All Patterns Together](/docs/guides/use-cases/combining-routing-strategies#the-full-config)
>
> See a complete config combining conditional routing, load balancing, and fallbacks across four model families.
## Caveats and Considerations
While the Load Balancing feature offers numerous benefits, there are a few things to consider:
1. Ensure the LLMs in your list are compatible with your use case. Not all LLMs offer the same capabilities or respond in the same format.
2. Be aware of your usage with each LLM. Depending on your weight distribution, your usage with each LLM could vary significantly.
3. Keep in mind that each LLM has its own latency and pricing. Diversifying your traffic could have implications on the cost and response time.
4. **Sticky sessions** require Redis for persistence across gateway instances. Without Redis, sticky sessions will only work within a single gateway instance's memory.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Messages
Source: https://docs.portkey.ai/docs/product/ai-gateway/messages-api
Use Anthropic's Messages format with any provider — 3000+ models, one endpoint.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
Portkey's `/v1/messages` endpoint accepts the [Anthropic Messages API](https://docs.anthropic.com/en/api/messages) format and routes to any of [3000+ models](/docs/product/model-catalog) across all major providers. Tools built natively on the Messages format — like [Claude Code](/docs/integrations/libraries/claude-code) and the [Claude Agent SDK](/docs/integrations/agents/claude-agent-sdk) — work with any backend model through Portkey without modification.
## Why Messages API
* **Write once, run anywhere** — Any SDK or tool built on the Anthropic Messages format works instantly. No rewrites.
* **Switch providers with one string** — Change the `model` parameter to route to a different provider. Request format and response shape stay identical.
* **Full gateway features** — Fallbacks, load balancing, caching, and observability work transparently across all providers.
## Quick Start
Use the Anthropic SDK with Portkey's base URL. The `@provider/model` format routes requests to the correct provider.
```python Python theme={"system"}
import anthropic
client = anthropic.Anthropic(
api_key="dummy", # we will use portkey's provider slug
default_headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
base_url="https://api.portkey.ai"
)
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "Explain quantum computing in simple terms"}]
)
print(message.content[0].text)
```
```typescript TypeScript theme={"system"}
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai"
});
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [{ role: "user", content: "Explain quantum computing in simple terms" }]
});
console.log(message.content[0].text);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "Explain quantum computing in simple terms"}]
}'
```
> [!NOTE]
>
> `max_tokens` is required. See the [Model Catalog](/docs/product/model-catalog) for
> all supported provider and model strings.
## Switching Providers
Change the `model` string to route to any provider. Everything else stays the same.
```python Anthropic theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello"}]
)
```
```python OpenAI theme={"system"}
message = client.messages.create(
model="@openai-provider/gpt-4.1",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello"}]
)
```
```python Gemini theme={"system"}
message = client.messages.create(
model="@google-provider/gemini-2.5-flash",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello"}]
)
```
> [!NOTE]
>
> The SDK code, request format, and response shape are identical across all
> providers. Portkey translates the Messages format to each provider's native
> API. See [Provider Support](#provider-support) for how this works.
## Migrate in 2 Lines
Already using the Anthropic SDK? Point it at Portkey:
```python Python theme={"system"}
client = anthropic.Anthropic(
api_key="dummy", # we will use portkey's provider slug
default_headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
base_url="https://api.portkey.ai"
)
```
All existing Messages API calls work as-is. Use the `@anthropic-provider/` prefix to keep routing to Anthropic, or switch the model string to any other provider.
## Text Generation
### System Prompt
Set a system prompt with the top-level `system` parameter:
```python Python theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
system="You are a pirate. Always respond in pirate speak.",
messages=[{"role": "user", "content": "Say hello."}]
)
```
```typescript TypeScript theme={"system"}
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
system: "You are a pirate. Always respond in pirate speak.",
messages: [{ role: "user", content: "Say hello." }],
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"system": "You are a pirate. Always respond in pirate speak.",
"messages": [{"role": "user", "content": "Say hello."}]
}'
```
The `system` parameter also accepts an array of content blocks for prompt caching:
```python Python theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
system=[
{"type": "text", "text": "You are an expert on this topic..."},
{"type": "text", "text": "Here is the reference material...", "cache_control": {"type": "ephemeral"}}
],
messages=[{"role": "user", "content": "Summarize the key points"}]
)
```
### Streaming
Stream responses with `stream=True` in the SDK or `"stream": true` in cURL.
```python Python theme={"system"}
with client.messages.stream(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "Write a haiku about AI"}]
) as stream:
for text in stream.text_stream:
print(text, end="", flush=True)
```
```typescript TypeScript theme={"system"}
const stream = client.messages.stream({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [{ role: "user", content: "Write a haiku about AI" }],
});
for await (const event of stream) {
if (
event.type === "content_block_delta" &&
event.delta.type === "text_delta"
) {
process.stdout.write(event.delta.text);
}
}
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"stream": true,
"messages": [{"role": "user", "content": "Write a haiku about AI"}]
}'
```
Portkey normalizes all streaming responses to the Anthropic SSE event format, regardless of which provider handles the request.
> [accordion] SSE event reference
>
> Events are emitted in this sequence for every streaming response:
>
> | Event | Description |
> | - | - |
> | `message_start` | Opens the message with metadata (`id`, `model`, initial `usage`) |
> | `content_block_start` | Opens a content block — `type: "text"` for text, `type: "tool_use"` for tool calls |
> | `content_block_delta` | Incremental content — `text_delta` for text, `input_json_delta` for tool input |
> | `content_block_stop` | Closes a content block |
> | `message_delta` | Closes the message with `stop_reason` (`end_turn`, `max_tokens`, `tool_use`) and final `usage` |
> | `message_stop` | Final event signaling stream completion |
>
> Example `content_block_delta` event:
>
> ```
> event: content_block_delta
> data: {"type": "content_block_delta", "index": 0, "delta": {"type": "text_delta", "text": "Hello"}}
> ```
>
> Example `message_delta` event:
>
> ```
> event: message_delta
> data: {"type": "message_delta", "delta": {"stop_reason": "end_turn", "stop_sequence": null}, "usage": {"output_tokens": 42}}
> ```
### Multi-turn Conversations
Build conversations by passing the full message history. Messages must alternate between `user` and `assistant` roles.
```python Python theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[
{"role": "user", "content": "My name is Alice."},
{"role": "assistant", "content": "Hello Alice! How can I help you?"},
{"role": "user", "content": "What is my name?"}
]
)
print(message.content[0].text) # "Your name is Alice."
```
```typescript TypeScript theme={"system"}
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [
{ role: "user", content: "My name is Alice." },
{ role: "assistant", content: "Hello Alice! How can I help you?" },
{ role: "user", content: "What is my name?" }
]
});
console.log(message.content[0].text);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"messages": [
{"role": "user", "content": "My name is Alice."},
{"role": "assistant", "content": "Hello Alice! How can I help you?"},
{"role": "user", "content": "What is my name?"}
]
}'
```
### Generation Parameters
| Parameter | Type | Description |
| - | - | - |
| `max_tokens` | integer | Required. Maximum tokens in the response |
| `temperature` | float | Sampling temperature (0–1). Higher = more creative |
| `top_p` | float | Nucleus sampling threshold (0–1) |
| `top_k` | integer | Top-K sampling. Anthropic native only — silently dropped on adapter providers |
| `stop_sequences` | array | Stop strings. Translated to `stop` for adapter providers |
| `stream` | boolean | Enable streaming responses |
> [!NOTE]
>
> For Anthropic models (across all providers/routes), `temperature` and `top_p` are direct mappings when provided individually. If both are sent together, Portkey keeps `temperature` and drops `top_p` to match Anthropic constraints.
## Tool Use
Define tools with `name`, `description`, and `input_schema`:
```python Python theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "What's the weather in San Francisco?"}],
tools=[{
"name": "get_weather",
"description": "Get current weather for a location",
"input_schema": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}]
)
for block in message.content:
if block.type == "tool_use":
print(f"Tool: {block.name}, Input: {block.input}")
```
```typescript TypeScript theme={"system"}
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [{ role: "user", content: "What's the weather in San Francisco?" }],
tools: [{
name: "get_weather",
description: "Get current weather for a location",
input_schema: {
type: "object",
properties: {
location: { type: "string", description: "City name" }
},
required: ["location"]
}
}]
});
for (const block of message.content) {
if (block.type === "tool_use") {
console.log(`Tool: ${block.name}, Input: ${JSON.stringify(block.input)}`);
}
}
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "What'\''s the weather in San Francisco?"}],
"tools": [{
"name": "get_weather",
"description": "Get current weather for a location",
"input_schema": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}]
}'
```
### Tool Results
Pass tool results back in a `user` message with `tool_result` content blocks to continue the conversation:
```python Python theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[
{"role": "user", "content": "What's the weather in Paris?"},
{"role": "assistant", "content": [
{"type": "tool_use", "id": "tool_123", "name": "get_weather", "input": {"location": "Paris"}}
]},
{"role": "user", "content": [
{"type": "tool_result", "tool_use_id": "tool_123", "content": '{"temp": "22°C", "condition": "sunny"}'}
]}
],
tools=[{
"name": "get_weather",
"description": "Get weather for a location",
"input_schema": {"type": "object", "properties": {"location": {"type": "string"}}, "required": ["location"]}
}]
)
print(message.content[0].text)
```
```typescript TypeScript theme={"system"}
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [
{ role: "user", content: "What's the weather in Paris?" },
{ role: "assistant", content: [
{ type: "tool_use", id: "tool_123", name: "get_weather", input: { location: "Paris" } }
]},
{ role: "user", content: [
{ type: "tool_result", tool_use_id: "tool_123", content: '{"temp": "22°C", "condition": "sunny"}' }
]}
],
tools: [{
name: "get_weather",
description: "Get weather for a location",
input_schema: { type: "object", properties: { location: { type: "string" } }, required: ["location"] }
}]
});
console.log(message.content[0].text);
```
For MCP-based tool use, see [Remote MCP](/docs/product/ai-gateway/remote-mcp).
## Vision
Send images using content blocks. Supports both URLs and base64-encoded data.
```python URL theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{
"role": "user",
"content": [
{"type": "image", "source": {"type": "url", "url": "https://example.com/image.jpg"}},
{"type": "text", "text": "Describe this image"}
]
}]
)
print(message.content[0].text)
```
```python Base64 theme={"system"}
import base64, httpx
image_data = base64.standard_b64encode(httpx.get("https://example.com/image.jpg").content).decode("utf-8")
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{
"role": "user",
"content": [
{"type": "image", "source": {"type": "base64", "media_type": "image/jpeg", "data": image_data}},
{"type": "text", "text": "Describe this image"}
]
}]
)
```
```typescript TypeScript theme={"system"}
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [
{
role: "user",
content: [
{
type: "image",
source: { type: "url", url: "https://example.com/image.jpg" },
},
{ type: "text", text: "Describe this image" },
],
},
],
});
console.log(message.content[0].text);
```
## Structured Output
Use `output_config` to constrain responses to a JSON schema. Portkey maps this to `response_format` for adapter providers.
```python Python theme={"system"}
message = client.messages.create(
model="@openai-provider/gpt-4.1",
max_tokens=1024,
messages=[{"role": "user", "content": "Extract name and age from: Alice is 30 years old."}],
extra_body={
"output_config": {
"format": {
"type": "json_schema",
"schema": {
"type": "object",
"properties": {
"name": {"type": "string"},
"age": {"type": "integer"}
},
"required": ["name", "age"]
}
}
}
}
)
```
```typescript TypeScript theme={"system"}
const message = await (client.messages.create as any)({
model: "@openai-provider/gpt-4.1",
max_tokens: 1024,
messages: [
{
role: "user",
content: "Extract name and age from: Alice is 30 years old.",
},
],
output_config: {
format: {
type: "json_schema",
schema: {
type: "object",
properties: {
name: { type: "string" },
age: { type: "integer" },
},
required: ["name", "age"],
},
},
},
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-provider/gpt-4.1",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "Extract name and age from: Alice is 30 years old."}],
"output_config": {
"format": {
"type": "json_schema",
"schema": {
"type": "object",
"properties": {
"name": {"type": "string"},
"age": {"type": "integer"}
},
"required": ["name", "age"]
}
}
}
}'
```
> [!NOTE]
>
> `output_config` is a Portkey extension to the Messages API format. Only
> `json_schema` is supported — `json_object` is not available via the adapter.
## Extended Thinking
Two mechanisms for controlling model reasoning:
**`thinking` — Anthropic native.** Pass directly to Anthropic Claude models. Silently dropped on adapter providers.
**`output_config.effort` — Cross-provider.** Works across Anthropic, OpenAI o-series, and Gemini 2.5. Portkey maps it to each provider's native reasoning format.
```python Anthropic native theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=16000,
thinking={"type": "enabled", "budget_tokens": 10000},
messages=[{"role": "user", "content": "Analyze the implications of quantum computing on cryptography"}]
)
for block in message.content:
if block.type == "thinking":
print(f"Thinking: {block.thinking[:200]}...")
elif block.type == "text":
print(f"Response: {block.text}")
```
```python Any provider (unified) theme={"system"}
# Works with Anthropic, OpenAI o-series, Gemini 2.5
message = client.messages.create(
model="@openai-provider/o4-mini",
max_tokens=4096,
messages=[{"role": "user", "content": "Analyze the implications of quantum computing on cryptography"}],
extra_body={"output_config": {"effort": "high"}}
)
```
```typescript Any provider (unified) theme={"system"}
const message = await (client.messages.create as any)({
model: "@openai-provider/o4-mini",
max_tokens: 4096,
messages: [
{
role: "user",
content: "Analyze the implications of quantum computing on cryptography",
},
],
output_config: { effort: "high" },
});
```
> [!NOTE]
>
> When using Anthropic's `thinking` parameter, `max_tokens` must exceed
> `budget_tokens`. See [Thinking
> Mode](/docs/product/ai-gateway/multimodal-capabilities/thinking-mode) for
> provider-specific effort mappings.
## Prompt Caching
Use `cache_control` on system prompts, messages, and tool definitions to cache frequently-used content.
```python System prompt caching theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
system=[{
"type": "text",
"text": "You are an expert analyst. Here is a very long reference document...",
"cache_control": {"type": "ephemeral"}
}],
messages=[{"role": "user", "content": "Summarize the key points"}]
)
```
```python Message caching theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{
"role": "user",
"content": [
{"type": "text", "text": "Here is a long document to analyze...", "cache_control": {"type": "ephemeral"}},
{"type": "text", "text": "What are the key themes?"}
]
}]
)
```
```python Tool caching theme={"system"}
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "Search for AI news"}],
tools=[{
"name": "search",
"description": "Search the knowledge base",
"input_schema": {"type": "object", "properties": {"query": {"type": "string"}}},
"cache_control": {"type": "ephemeral"}
}]
)
```
Cached content reduces latency and cost. Cache usage is reflected in the `usage` object of the response.
> [!NOTE]
>
> `cache_control` is Anthropic-native and is stripped when routing to adapter
> providers. See [Anthropic prompt
> caching](/docs/integrations/llms/anthropic/prompt-caching) for details.
## Provider Support
Portkey handles the Messages API in two ways depending on the provider:
* **Native providers** — Requests pass through directly. All Anthropic-specific features work (`thinking`, `cache_control`, `top_k`, etc.).
* **Adapter providers** — Portkey translates between Messages format and the provider's native Chat Completions format. See [Parameter Compatibility](#parameter-compatibility) for what is and isn't supported.
The response always comes back in Anthropic Messages format, regardless of which provider handles the request.
**Native providers:** Anthropic, AWS Bedrock (Claude models)
**Adapter providers:** OpenAI, Azure OpenAI, Google Gemini, Google Vertex AI, AWS Bedrock (non-Claude), Mistral AI, Groq, Together AI, and [all other providers](/docs/product/model-catalog/integrations)
## Parameter Compatibility
Portkey's Messages adapter translates requests to each provider's [Chat Completions](/docs/product/ai-gateway/chat-completions) format for non-native providers.
**Unsupported parameters are silently dropped — no error is returned.**
Parameters translated for adapter providers:
| Messages API param | Adapter equivalent | Notes |
| - | - | - |
| `max_tokens` | `max_completion_tokens` | |
| `stop_sequences` | `stop` | |
| `system` | First message with `role: "system"` | String or array both handled |
| `tools[].input_schema` | `tools[].function.parameters` | Format converted |
| `tool_choice: {type: "auto"}` | `"auto"` | |
| `tool_choice: {type: "any"}` | `"required"` | |
| `tool_choice: {type: "tool", name: X}` | `{type: "function", function: {name: X}}` | |
| `metadata.user_id` | `user` | |
| `temperature`, `top_p`, `stream` | Direct pass-through | For Anthropic models: if both `temperature` and `top_p` are present, Portkey drops `top_p`. |
| `output_config.format` (`json_schema`) | `response_format` | Portkey extension; `json_object` not supported |
| `output_config.effort` | `reasoning_effort` | Portkey extension for cross-provider reasoning |
Parameters silently dropped on adapter providers:
* `thinking` — Anthropic-native; use `output_config.effort` for cross-provider reasoning control
* `top_k` — no Chat Completions equivalent
* `cache_control` — stripped during message transformation
* `container`, `mcp_servers`, `service_tier`, `anthropic_beta`
> [!WARNING]
>
> Provider-specific parameters (e.g. Gemini's `safety_settings`, Bedrock
> guardrail configs) cannot be passed through the Messages adapter. Use the
> provider's native integration or [Chat
> Completions](/docs/product/ai-gateway/chat-completions) instead.
## Using with Portkey Features
The Messages API works with all Portkey gateway features. Pass a config via header alongside any Anthropic SDK call:
```python Python theme={"system"}
import anthropic
client = anthropic.Anthropic(
api_key="dummy", # we will use portkey's provider slug
default_headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
base_url="https://api.portkey.ai"
)
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello!"}]
)
```
```typescript TypeScript theme={"system"}
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai",
defaultHeaders: {
"x-portkey-config": "pp-config-xxx"
}
});
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [{ role: "user", content: "Hello!" }]
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pp-config-xxx" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
> [card] [Configs](/docs/product/ai-gateway/configs)
>
> Route, load balance, and set fallbacks
> [card] [Caching](/docs/product/ai-gateway/cache-simple-and-semantic)
>
> Cache responses for faster, cheaper calls
> [card] [Fallbacks](/docs/product/ai-gateway/fallbacks)
>
> Automatic failover across providers
> [card] [Load Balancing](/docs/product/ai-gateway/load-balancing)
>
> Distribute traffic across models
> [card] [Guardrails](/docs/product/guardrails)
>
> Input/output guardrails
> [card] [Observability](/docs/product/observability)
>
> Full logging and tracing
## API Reference
* [Messages](/docs/api-reference/inference-api/anthropic-transform) — `POST /v1/messages`
> [card] [Anthropic API Docs](https://docs.anthropic.com/en/api/messages)
>
> Anthropic specification
> [card] [API Reference](/docs/api-reference/inference-api/anthropic-transform)
>
> Portkey Messages API reference
> [card] [Universal API](/docs/product/ai-gateway/universal-api)
>
> All three API formats
> [card] [Responses API](/docs/product/ai-gateway/responses-api)
>
> OpenAI Responses format
> [card] [Chat Completions](/docs/product/ai-gateway/chat-completions)
>
> OpenAI Chat Completions format
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Multimodal Capabilities
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
The Gateway is your unified interface for **multimodal models**, along with chat, text, and embedding models.
Using the Gateway, you can call `vision`, `audio (text-to-speech & speech-to-text)`, `image generation` and other multimodal models from multiple providers (like `OpenAI`, `Anthropic`, `Stability AI`, etc.) — all using the familiar OpenAI signature.

#### Explore the AI Gateway's Multimodal capabilities below:
> [card] [Vision](/docs/product/ai-gateway/multimodal-capabilities/vision)
> [card] [Image Generation](/docs/product/ai-gateway/multimodal-capabilities/image-generation)
> [card] [Function Calling](/docs/product/ai-gateway/multimodal-capabilities/function-calling)
> [card] [Speech-to-Text](/docs/product/ai-gateway/multimodal-capabilities/speech-to-text)
> [card] [Text-to-Speech](/docs/product/ai-gateway/multimodal-capabilities/text-to-speech)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Function Calling
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities/function-calling
Portkey's AI Gateway supports function calling across major foundational models. Define functions in your API call, and the model can output the function name with parameters.
## Functions Usage
Portkey supports the OpenAI signature to define functions. Pass the `tools` parameter to models that support function/tool calling.
> [tab] NodeJS
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> });
>
> async function run() {
> const response = await portkey.chat.completions.create({
> model: "MODEL_NAME",
> messages: [{ role: "user", content: "What's the weather like in Boston today?" }],
> tools: [{
> type: "function",
> function: {
> name: "get_current_weather",
> description: "Get the current weather in a given location",
> parameters: {
> type: "object",
> properties: {
> location: {
> type: "string",
> description: "The city and state, e.g. San Francisco, CA",
> },
> unit: { type: "string", enum: ["celsius", "fahrenheit"] },
> },
> required: ["location"],
> },
> }
> }],
> tool_choice: "auto",
> });
>
> console.log(response.choices[0].message.tool_calls);
> }
>
> run();
> ```
> [tab] Python
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> )
>
> completion = portkey.chat.completions.create(
> model="MODEL_NAME",
> messages=[{"role": "user", "content": "What's the weather like in Boston today?"}],
> tools=[{
> "type": "function",
> "function": {
> "name": "get_current_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA",
> },
> "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
> },
> "required": ["location"],
> },
> }
> }],
> tool_choice="auto"
> )
>
> print(completion.choices[0].message.tool_calls)
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> async function run() {
> const response = await openai.chat.completions.create({
> model: "MODEL_NAME",
> messages: [{ role: "user", content: "What's the weather like in Boston today?" }],
> tools: [{
> type: "function",
> function: {
> name: "get_current_weather",
> description: "Get the current weather in a given location",
> parameters: {
> type: "object",
> properties: {
> location: {
> type: "string",
> description: "The city and state, e.g. San Francisco, CA",
> },
> unit: { type: "string", enum: ["celsius", "fahrenheit"] },
> },
> required: ["location"],
> },
> }
> }],
> tool_choice: "auto",
> });
>
> console.log(response.choices[0].message.tool_calls);
> }
>
> run();
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> api_key="PORTKEY_API_KEY"
> )
> )
>
> completion = openai.chat.completions.create(
> model="MODEL_NAME",
> messages=[{"role": "user", "content": "What's the weather like in Boston today?"}],
> tools=[{
> "type": "function",
> "function": {
> "name": "get_current_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA",
> },
> "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
> },
> "required": ["location"],
> },
> }
> }],
> tool_choice="auto"
> )
>
> print(completion.choices[0].message.tool_calls)
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/chat/completions" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "model": "MODEL_NAME",
> "messages": [
> {
> "role": "user",
> "content": "What is the weather like in Boston?"
> }
> ],
> "tools": [
> {
> "type": "function",
> "function": {
> "name": "get_current_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA"
> },
> "unit": {
> "type": "string",
> "enum": ["celsius", "fahrenheit"]
> }
> },
> "required": ["location"]
> }
> }
> }
> ],
> "tool_choice": "auto"
> }'
> ```
### [API Reference](/docs/provider-endpoints/chat)
On completion, the request logs in the Portkey UI where tools and functions are visible. Portkey automatically formats the JSON blocks in the input and output for easier debugging.

## Managing Functions and Tools in Prompts
Create prompt templates with function/tool definitions in Portkey's Prompt Library. Set the `tool_choice` parameter, and Portkey validates your tool definition on the fly, eliminating syntax errors.

## Supported Providers and Models
Portkey provides native function calling support across all major AI providers.
If you discover a function-calling capable LLM that isn't working with Portkey, please let us know via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
## Cookbook
[**See the detailed cookbook on function calling.**](/docs/guides/getting-started/function-calling)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Image Generation
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities/image-generation
Portkey's AI gateway supports image generation capabilities that many foundational model providers offer.
The most common use case is that of **text-to-image** where the user sends a prompt which the image model processes and returns an image.
> [!NOTE]
>
> The guide for vision models is [available here](/docs/product/ai-gateway/multimodal-capabilities/vision).
## Text-to-Image Usage
Portkey supports the OpenAI signature to make text-to-image requests.
> [tab] NodeJS
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> async function main() {
> const image = await portkey.images.generate({
> model: "dall-e-3",
> prompt: "Lucy in the sky with diamonds"
> });
>
> console.log(image.data);
> }
>
> main();
> ```
> [tab] Python
>
> ```py theme={"system"}
> from portkey_ai import Portkey
> from IPython.display import display, Image
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> image = portkey.images.generate(
> model="dall-e-3",
> prompt="Lucy in the sky with diamonds"
> )
>
> # Display the image
> display(Image(url=image.data[0].url))
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> async function main() {
> const image = await openai.images.generate({
> model: "dall-e-3",
> prompt: "Lucy in the sky with diamonds"
> });
>
> console.log(image.data);
> }
>
> main();
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
> from IPython.display import display, Image
>
> client = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> image = client.images.generate(
> model="dall-e-3",
> prompt="Lucy in the sky with diamonds",
> n=1,
> size="1024x1024"
> )
>
> # Display the image
> display(Image(url=image.data[0].url))
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/images/generations" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: $OPENAI_PROVIDER" \
> -d '{
> "model": "dall-e-3",
> "prompt": "Lucy in the sky with diamonds"
> }'
> ```
## Image Editing
Portkey supports the OpenAI signature to make image edit requests using multipart form data.
```python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY", provider="openai")
with open("image.png", "rb") as image_file:
image = portkey.images.edit(
model="gpt-image-2",
prompt="Add snow",
image=[("image.png", image_file.read(), "image/png")],
size="1024x1024",
)
```
> [!NOTE]
>
> Image edit models currently do not support provider-prefixed model slugs in the request body. Pass the provider in headers and keep `model` as the raw provider model name.
### API Reference
* [Create Image](/docs/provider-endpoints/images/create-image)
* [Create Image Edit](/docs/provider-endpoints/images/create-image-edit)
### OpenAI gpt-image-1 Parameters
For OpenAI's `gpt-image-1` model, additional parameters are supported:
| Parameter | Type | Description |
| - | - | - |
| `moderation` | string | Content moderation level for generated images |
| `output_format` | string | Output format for the generated image |
| `output_compression` | number | Compression level (0-100) for the output image |
| `background` | string | Background style for the generated image |
| `partial_images` | number | Number of partial images to return (0-3) |
| `stream` | boolean | Whether to stream partial image results |
On completion, the request will get logged in the logs UI where the image can be viewed.
(*Note that providers may remove the hosted image after a period of time, so some logs might only contain the url*)

## Cookbook
[**Here's a detailed cookbook on image generation using Portkey**](https://github.com/Portkey-AI/portkey-cookbook/blob/main/examples/image-generation.ipynb) which demonstrates the use of multiple providers and routing between them through Configs.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Speech-to-Text
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities/speech-to-text
Use Portkey's AI gateway to transcribe and translate audio using speech-to-text models across all supported providers.
## Transcription & Translation Usage
Portkey supports both `Transcription` and `Translation` methods for STT models and follows the OpenAI signature where you can send the file (in `flac`, `mp3`, `mp4`, `mpeg`, `mpga`, `m4a`, `ogg`, `wav`, or `webm` formats) as part of the API request.
Here's an example:
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import fs from "fs";
> import OpenAI from "openai";
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: "API_KEY", // Replace with your standard API Key or a dummy string
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> apiKey: "PORTKEY_API_KEY",
> provider: "openai"
> })
> });
>
> // Transcription
>
> async function transcribe() {
> const transcription = await openai.audio.transcriptions.create({
> file: fs.createReadStream("/path/to/file.mp3"),
> model: "whisper-1",
> });
>
> console.log(transcription.text);
> }
> transcribe();
>
> // Translation
>
> async function translate() {
> const translation = await openai.audio.translations.create({
> file: fs.createReadStream("/path/to/file.mp3"),
> model: "whisper-1",
> });
> console.log(translation.text);
> }
> translate();
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> client = OpenAI(
> api_key="API_KEY", # Replace with your standard API Key or a dummy string
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> api_key="PORTKEY_API_KEY",
> provider="openai"
> )
> )
>
> audio_file= open("/path/to/file.mp3", "rb")
>
> # Transcription
>
> transcription = client.audio.transcriptions.create(
> model="whisper-1",
> file=audio_file
> )
> print(transcription.text)
>
> # Translation
>
> translation = client.audio.translations.create(
> model="whisper-1",
> file=audio_file
> )
> print(translation.text)
> ```
> [tab] Python SDK
>
> ```python theme={"system"}
> from pathlib import Path
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
> audio_file= open("/path/to/file.mp3", "rb")
>
> # Transcription
> transcription = portkey.audio.transcriptions.create(
> model="@openai/whisper-1",
> file=audio_file
> )
>
> print(transcription.text)
> # Translation
> translation = portkey.audio.translations.create(
> model="@openai/whisper-1",
> file=audio_file
> )
> print(translation.text)
> ```
> [tab] cURL
>
> For Transcriptions:
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/audio/transcriptions" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H 'Content-Type: multipart/form-data' \
> --form file=@/path/to/file/audio.mp3 \
> --form model=@openai/whisper-1
> ```
>
> For Translations:
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/audio/translations" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H 'Content-Type: multipart/form-data' \
> --form file=@/path/to/file/audio.mp3 \
> --form model=@openai/whisper-1
> ```
On completion, the request will get logged in the logs UI where you can see transcribed or translated text, along with the cost and latency incurred.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Text-to-Speech
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities/text-to-speech
Portkey's AI gateway supports text-to-speech models on OpenAI, Azure OpenAI, and Google Vertex AI.
## Usage
We follow the OpenAI signature where you can send the input text and the voice option as a part of the API request. All the output formats `mp3`, `opus`, `aac`, `flac`, and `pcm` are supported. Portkey also supports real time audio streaming for TTS models.
Here's an example:
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import fs from "fs";
> import path from "path";
> import OpenAI from "openai";
> import { PORTKEY_GATEWAY_URL } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: "PORTKEY_API_KEY",
> baseURL: PORTKEY_GATEWAY_URL
> });
>
> const speechFile = path.resolve("./speech.mp3");
>
> async function main() {
> const mp3 = await openai.audio.speech.create({
> model: "@openai/tts-1",
> voice: "alloy",
> input: "Today is a wonderful day to build something people love!",
> });
> const buffer = Buffer.from(await mp3.arrayBuffer());
> await fs.promises.writeFile(speechFile, buffer);
> }
>
> main();
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from pathlib import Path
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL
>
> client = OpenAI(
> api_key="PORTKEY_API_KEY",
> base_url=PORTKEY_GATEWAY_URL
> )
>
> speech_file_path = Path(__file__).parent / "speech.mp3"
>
> response = client.audio.speech.create(
> model="@openai/tts-1",
> voice="alloy",
> input="Today is a wonderful day to build something people love!"
> )
>
> f = open(speech_file_path, "wb")
> f.write(response.content)
> f.close()
> ```
> [tab] Python SDK
>
> ```python theme={"system"}
> from pathlib import Path
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> speech_file_path = Path(__file__).parent / "speech.mp3"
>
> response = portkey.audio.speech.create(
> model="@openai/tts-1",
> voice="alloy",
> input="Today is a wonderful day to build something people love!"
> )
>
> f = open(speech_file_path, "wb")
> f.write(response.content)
> f.close()
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/audio/speech" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "model": "@openai/tts-1",
> "input": "Today is a wonderful day to build something people love!",
> "voice": "alloy"
> }' \
> --output speech.mp3
> ```
On completion, the request will get logged in the logs UI and show the cost and latency incurred.
## SSE Streaming
OpenAI and Azure OpenAI support Server-Sent Events (SSE) streaming for the speech endpoint. Set `stream_format` to `"sse"` to receive audio data as a stream of events:
> [tab] Python
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@PROVIDER"
> )
>
> response = portkey.audio.speech.create(
> model="@openai/tts-1",
> voice="alloy",
> input="Today is a wonderful day to build something people love!",
> stream_format="sse"
> )
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/audio/speech" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "model": "@openai/tts-1",
> "input": "Today is a wonderful day to build something people love!",
> "voice": "alloy",
> "stream_format": "sse"
> }'
> ```
## Google Vertex AI TTS
Google Vertex AI offers Gemini TTS models with advanced features like multi-speaker synthesis and style control. Portkey supports two methods:
1. **Chat Completions with `speech_config`** - Use Gemini TTS through the chat completions endpoint
2. **Audio Speech endpoint** - OpenAI-compatible `/audio/speech` endpoint
> [tab] Chat Completions
>
> ```sh theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "model": "@vertex-ai/gemini-2.5-flash-tts",
> "messages": [{"role": "user", "content": "Say cheerfully: Hello!"}],
> "speech_config": {
> "voice_config": {"prebuilt_voice_config": {"voice_name": "Kore"}},
> "language_code": "en-US"
> }
> }'
> ```
> [tab] Audio Speech
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/audio/speech" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "model": "@vertex-ai/gemini-2.5-flash-tts",
> "input": "Hello! This is a test.",
> "voice": "Kore",
> "response_format": "mp3"
> }' \
> --output speech.mp3
> ```
For detailed documentation including multi-speaker synthesis, style prompts, and all available voices, see [Google Vertex AI Text-to-Speech](/docs/integrations/llms/vertex-ai/text-to-speech).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Thinking Mode
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities/thinking-mode
Thinking/Reasoning models represent a new generation of LLMs specifically trained to expose their internal reasoning process. Unlike traditional LLMs that only show final outputs, thinking models like Claude 3.7 Sonnet, OpenAI o1/o3, and Deepseek R1 are designed to "think out loud" - producing a detailed chain of thought before delivering their final response.
These reasoning-optimized models are built to excel in tasks requiring complex analysis, multi-step problem solving, and structured logical thinking. Portkey makes these advanced models accessible through a unified API specification that works consistently across providers.
## Supported Thinking Models
Portkey currently supports thinking-enabled models from **Anthropic**, **Google Vertex AI**, **Amazon Bedrock**, **OpenAI**, **Together AI**, and other **OpenAI-compatible providers**.
*Note: If a specific model is not supported for thinking on Portkey, please reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).*
## Using Thinking Mode
1. You must set `strict_open_ai_compliance=False` in your headers or client configuration
2. The thinking response is returned in a different format than standard completions
3. For streaming responses, the thinking content is in `response_chunk.choices[0].delta.content_blocks`
> [!WARNING]
>
> Extended thinking API through Portkey is currently in beta.
### Basic Example
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER",
> strict_open_ai_compliance=False # Required for thinking mode
> )
>
> # Create the request
> response = portkey.chat.completions.create(
> model="claude-3-7-sonnet-latest",
> max_tokens=3000,
> thinking={
> "type": "enabled",
> "budget_tokens": 2030 # Maximum tokens to use for thinking
> },
> stream=False,
> messages=[
> {
> "role": "user",
> "content": [
> {
> "type": "text",
> "text": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
> }
> ]
> }
> ]
> )
> print(response)
>
> # For streaming responses, handle content_blocks differently
> # response = portkey.chat.completions.create(
> # ...same config as above but with stream=True
> # )
> # for chunk in response:
> # if chunk.choices[0].delta:
> # content_blocks = chunk.choices[0].delta.get("content_blocks")
> # if content_blocks is not None:
> # for content_block in content_blocks:
> # print(content_block)
> ```
> [tab] Node.js
>
> ```javascript theme={"system"}
> import Portkey from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER",
> strictOpenAiCompliance: false // Required for thinking mode
> });
>
> // Generate a chat completion
> async function getChatCompletionWithThinking() {
> const response = await portkey.chat.completions.create({
> model: "claude-3-7-sonnet-latest",
> max_tokens: 3000,
> thinking: {
> type: "enabled",
> budget_tokens: 2030
> },
> stream: false,
> messages: [
> {
> role: "user",
> content: [
> {
> type: "text",
> text: "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
> }
> ]
> }
> ]
> });
> console.log(response);
>
> // For streaming responses:
> // const response = await portkey.chat.completions.create({
> // ...same config as above but with stream: true
> // });
> // for await (const chunk of response) {
> // if (chunk.choices[0].delta?.content_blocks) {
> // for (const contentBlock of chunk.choices[0].delta.content_blocks) {
> // console.log(contentBlock);
> // }
> // }
> // }
> }
>
> // Call the function
> getChatCompletionWithThinking();
> ```
> [tab] OpenAI SDK (JS)
>
> ```javascript theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'ANTHROPIC_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "anthropic",
> apiKey: "PORTKEY_API_KEY", // defaults to process.env["PORTKEY_API_KEY"]
> strictOpenAiCompliance: false
> })
> });
>
> // Generate a chat completion with thinking mode
> async function getChatCompletionFunctions(){
> const response = await openai.chat.completions.create({
> model: "claude-3-7-sonnet-latest",
> max_tokens: 3000,
> thinking: {
> type: "enabled",
> budget_tokens: 2030
> },
> stream: false,
> messages: [
> {
> role: "user",
> content: [
> {
> type: "text",
> text: "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
> }
> ]
> }
> ],
> });
>
> console.log(response)
> }
> await getChatCompletionFunctions();
> ```
> [tab] OpenAI SDK (Python)
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='ANTHROPIC_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="anthropic",
> api_key="PORTKEY_API_KEY",
> strict_open_ai_compliance=False
> )
> )
>
> response = openai.chat.completions.create(
> model="claude-3-7-sonnet-latest",
> max_tokens=3000,
> thinking={
> "type": "enabled",
> "budget_tokens": 2030
> },
> stream=False,
> messages=[
> {
> "role": "user",
> "content": [
> {
> "type": "text",
> "text": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
> }
> ]
> }
> ]
> )
>
> print(response)
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/chat/completions" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: anthropic" \
> -H "x-api-key: $ANTHROPIC_API_KEY" \
> -H "x-portkey-strict-open-ai-compliance: false" \
> -d '{
> "model": "claude-3-7-sonnet-latest",
> "max_tokens": 3000,
> "thinking": {
> "type": "enabled",
> "budget_tokens": 2030
> },
> "stream": false,
> "messages": [
> {
> "role": "user",
> "content": [
> {
> "type": "text",
> "text": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
> }
> ]
> }
> ]
> }'
> ```
## Multi-Turn Conversations
For multi-turn conversations, include the previous thinking content in the conversation history:
```py Python theme={"system"}
from portkey_ai import Portkey
# Initialize the Portkey client
portkey = Portkey(
api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
provider="@PROVIDER",
strict_open_ai_compliance=False
)
# Create the request
response = portkey.chat.completions.create(
model="claude-3-7-sonnet-latest",
max_tokens=3000,
thinking={
"type": "enabled",
"budget_tokens": 2030
},
stream=False,
messages=[
{
"role": "user",
"content": [
{
"type": "text",
"text": "when does the flight from baroda to bangalore land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}
]
},
{
"role": "assistant",
"content": [
{
"type": "thinking",
"thinking": "The user is asking several questions about a flight from Baroda (also known as Vadodara) to Bangalore:\n1. When does the flight land tomorrow\n2. What time does it land\n3. What is the flight number\n4. What is the baggage belt number at the arrival airport\n\nTo properly answer these questions, I would need access to airline flight schedules and airport information systems. However, I don't have:\n- Real-time or scheduled flight information\n- Access to airport baggage claim allocation systems\n- Information about specific flights between these cities\n- The ability to look up tomorrow's specific flight schedules\n\nThis question requires current, specific flight information that I don't have access to. Instead of guessing or providing potentially incorrect information, I should explain this limitation and suggest ways the user could find this information.",
"signature": "EqoBCkgIARABGAIiQBVA7FBNLRtWarDSy9TAjwtOpcTSYHJ+2GYEoaorq3V+d3eapde04bvEfykD/66xZXjJ5yyqogJ8DEkNMotspRsSDKzuUJ9FKhSNt/3PdxoMaFZuH+1z1aLF8OeQIjCrA1+T2lsErrbgrve6eDWeMvP+1sqVqv/JcIn1jOmuzrPi2tNz5M0oqkOO9txJf7QqEPPw6RG3JLO2h7nV1BMN6wE="
}
]
},
{
"role": "user",
"content": "thanks that's good to know, how about to chennai?"
}
]
)
print(response)
```
```ts NodeJS theme={"system"}
import Portkey from 'portkey-ai';
// Initialize the Portkey client
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider:"@PROVIDER",
strictOpenAiCompliance: false
});
// Generate a chat completion
async function getChatCompletionFunctions() {
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-3-7-sonnet-latest",
max_tokens: 3000,
thinking: {
type: "enabled",
budget_tokens: 2030
},
stream: false,
messages: [
{
role: "user",
content: [
{
type: "text",
text: "when does the flight from baroda to bangalore land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}
]
},
{
role: "assistant",
content: [
{
type: "thinking",
thinking: "The user is asking several questions about a flight from Baroda (also known as Vadodara) to Bangalore:\n1. When does the flight land tomorrow\n2. What time does it land\n3. What is the flight number\n4. What is the baggage belt number at the arrival airport\n\nTo properly answer these questions, I would need access to airline flight schedules and airport information systems. However, I don't have:\n- Real-time or scheduled flight information\n- Access to airport baggage claim allocation systems\n- Information about specific flights between these cities\n- The ability to look up tomorrow's specific flight schedules\n\nThis question requires current, specific flight information that I don't have access to. Instead of guessing or providing potentially incorrect information, I should explain this limitation and suggest ways the user could find this information.",
signature: "EqoBCkgIARABGAIiQBVA7FBNLRtWarDSy9TAjwtOpcTSYHJ+2GYEoaorq3V+d3eapde04bvEfykD/66xZXjJ5yyqogJ8DEkNMotspRsSDKzuUJ9FKhSNt/3PdxoMaFZuH+1z1aLF8OeQIjCrA1+T2lsErrbgrve6eDWeMvP+1sqVqv/JcIn1jOmuzrPi2tNz5M0oqkOO9txJf7QqEPPw6RG3JLO2h7nV1BMN6wE="
}
]
},
{
role: "user",
content: "thanks that's good to know, how about to chennai?"
}
]
});
console.log(response);
}
// Call the function
getChatCompletionFunctions();
```
```js OpenAI NodeJS theme={"system"}
import OpenAI from 'openai'; // We're using the v4 SDK
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const openai = new OpenAI({
apiKey: 'ANTHROPIC_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "anthropic",
apiKey: "PORTKEY_API_KEY", // defaults to process.env["PORTKEY_API_KEY"]
strict_open_ai_compliance: false
})
});
// Generate a chat completion with streaming
async function getChatCompletionFunctions(){
const response = await openai.chat.completions.create({
model: "@anthropic/claude-3-7-sonnet-latest",
max_tokens: 3000,
thinking: {
type: "enabled",
budget_tokens: 2030
},
stream: false,
messages: [
{
role: "user",
content: [
{
type: "text",
text: "when does the flight from baroda to bangalore land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}
]
},
{
role: "assistant",
content: [
{
type: "thinking",
thinking: "The user is asking several questions about a flight from Baroda (also known as Vadodara) to Bangalore:\n1. When does the flight land tomorrow\n2. What time does it land\n3. What is the flight number\n4. What is the baggage belt number at the arrival airport\n\nTo properly answer these questions, I would need access to airline flight schedules and airport information systems. However, I don't have:\n- Real-time or scheduled flight information\n- Access to airport baggage claim allocation systems\n- Information about specific flights between these cities\n- The ability to look up tomorrow's specific flight schedules\n\nThis question requires current, specific flight information that I don't have access to. Instead of guessing or providing potentially incorrect information, I should explain this limitation and suggest ways the user could find this information.",
signature: "EqoBCkgIARABGAIiQBVA7FBNLRtWarDSy9TAjwtOpcTSYHJ+2GYEoaorq3V+d3eapde04bvEfykD/66xZXjJ5yyqogJ8DEkNMotspRsSDKzuUJ9FKhSNt/3PdxoMaFZuH+1z1aLF8OeQIjCrA1+T2lsErrbgrve6eDWeMvP+1sqVqv/JcIn1jOmuzrPi2tNz5M0oqkOO9txJf7QqEPPw6RG3JLO2h7nV1BMN6wE="
}
]
},
{
role: "user",
content: "thanks that's good to know, how about to chennai?"
}
],
});
console.log(response)
}
await getChatCompletionFunctions();
```
```py OpenAI Python theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
openai = OpenAI(
api_key='PORTKEY_API_KEY',
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
strict_open_ai_compliance=False
)
)
response = openai.chat.completions.create(
model="@anthropic/claude-3-7-sonnet-latest",
max_tokens=3000,
thinking={
"type": "enabled",
"budget_tokens": 2030
},
stream=False,
messages=[
{
"role": "user",
"content": [
{
"type": "text",
"text": "when does the flight from baroda to bangalore land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}
]
},
{
"role": "assistant",
"content": [
{
"type": "thinking",
"thinking": "The user is asking several questions about a flight from Baroda (also known as Vadodara) to Bangalore:\n1. When does the flight land tomorrow\n2. What time does it land\n3. What is the flight number\n4. What is the baggage belt number at the arrival airport\n\nTo properly answer these questions, I would need access to airline flight schedules and airport information systems. However, I don't have:\n- Real-time or scheduled flight information\n- Access to airport baggage claim allocation systems\n- Information about specific flights between these cities\n- The ability to look up tomorrow's specific flight schedules\n\nThis question requires current, specific flight information that I don't have access to. Instead of guessing or providing potentially incorrect information, I should explain this limitation and suggest ways the user could find this information.",
signature: "EqoBCkgIARABGAIiQBVA7FBNLRtWarDSy9TAjwtOpcTSYHJ+2GYEoaorq3V+d3eapde04bvEfykD/66xZXjJ5yyqogJ8DEkNMotspRsSDKzuUJ9FKhSNt/3PdxoMaFZuH+1z1aLF8OeQIjCrA1+T2lsErrbgrve6eDWeMvP+1sqVqv/JcIn1jOmuzrPi2tNz5M0oqkOO9txJf7QqEPPw6RG3JLO2h7nV1BMN6wE="
}
]
},
{
"role": "user",
"content": "thanks that's good to know, how about to chennai?"
}
]
)
print(response)
```
```sh cURL theme={"system"}
curl "https://api.portkey.ai/v1/chat/completions" \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-strict-open-ai-compliance: false" \
-d '{
"model": "@anthropic/claude-3-7-sonnet-latest",
"max_tokens": 3000,
"thinking": {
"type": "enabled",
"budget_tokens": 2030
},
"stream": false,
"messages": [
{
"role": "user",
"content": [
{
"type": "text",
"text": "when does the flight from baroda to bangalore land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}
]
},
{
"role": "assistant",
"content": [
{
"type": "thinking",
"thinking": "The user is asking several questions about a flight from Baroda (also known as Vadodara) to Bangalore:\n1. When does the flight land tomorrow\n2. What time does it land\n3. What is the flight number\n4. What is the baggage belt number at the arrival airport\n\nTo properly answer these questions, I would need access to airline flight schedules and airport information systems. However, I don't have:\n- Real-time or scheduled flight information\n- Access to airport baggage claim allocation systems\n- Information about specific flights between these cities\n- The ability to look up tomorrow's specific flight schedules\n\nThis question requires current, specific flight information that I don't have access to. Instead of guessing or providing potentially incorrect information, I should explain this limitation and suggest ways the user could find this information.",
"signature": "EqoBCkgIARABGAIiQBVA7FBNLRtWarDSy9TAjwtOpcTSYHJ+2GYEoaorq3V+d3eapde04bvEfykD/66xZXjJ5yyqogJ8DEkNMotspRsSDKzuUJ9FKhSNt/3PdxoMaFZuH+1z1aLF8OeQIjCrA1+T2lsErrbgrve6eDWeMvP+1sqVqv/JcIn1jOmuzrPi2tNz5M0oqkOO9txJf7QqEPPw6RG3JLO2h7nV1BMN6wE="
}
]
},
{
"role": "user",
"content": "thanks that's good to know, how about to chennai?"
}
]
}'
```
## Understanding Response Format
When using thinking-enabled models, be aware of the special response format:
> [!NOTE]
>
> The assistant's thinking response is returned in the `response_chunk.choices[0].delta.content_blocks` array, not the `response.choices[0].message.content` string.
This is especially important for streaming responses, where you'll need to specifically parse and extract the thinking content from the content blocks.
## When to Use Thinking Models
Thinking models are particularly valuable in specific use cases:
* **Complex problem solving:** Break down multi-step tasks such as math, planning, debugging, or technical analysis where the model needs to reason through intermediate steps before answering.
* **High-stakes decision support:** Review contracts, policies, research, or operational runbooks where showing the reasoning path helps users audit the answer and catch missed assumptions.
* **Long-context analysis:** Compare multiple documents, synthesize evidence, or trace dependencies across large inputs where the model benefits from allocating tokens to structured reasoning.
* **Agentic workflows:** Power agents that need to plan tool calls, evaluate options, recover from errors, or explain why they chose a particular next step.
* **Quality-sensitive generation:** Produce answers that need stronger consistency, constraint following, and self-checking, such as code review, architecture recommendations, or data analysis.
For simple classification, extraction, summarization, or low-latency chat flows, a standard chat model is usually more cost-effective. Thinking mode adds reasoning tokens, so tune `budget_tokens` based on the complexity of the task and the amount of reasoning you want returned.
## FAQs
> [accordion] Can I use thinking mode with any model?
>
> No, thinking mode is only available on specific reasoning-optimized models. Currently, this includes Claude 3.7 Sonnet and will expand to other models as they become available.
> [accordion] Does thinking mode increase token usage?
>
> Yes, enabling thinking mode will increase your token usage since the model is generating additional content for its reasoning process. The `budget_tokens` parameter lets you control the maximum tokens allocated to thinking.
> [accordion] Do I need to handle the response differently for thinking mode?
>
> Yes, particularly for streaming responses. The thinking content is returned in the `content_blocks` array rather than the standard content field, so you'll need to adapt your response parsing logic.
> [accordion] Why do I need to set strict\_open\_ai\_compliance to false?
>
> The thinking mode response format extends beyond the standard OpenAI completion schema. Setting `strict_open_ai_compliance` to false allows Portkey to return this extended format with the thinking content.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Vision
Source: https://docs.portkey.ai/docs/product/ai-gateway/multimodal-capabilities/vision
Portkey's AI gateway supports vision models like GPT-4V by OpenAI, Gemini by Google and more.
> [!NOTE]
>
> **What are vision models?**
>
> Vision models are artificial intelligence systems that combine both vision and language modalities to process images and natural language text. These models are typically trained on large image and text datasets with different structures based on the pre-training objective.
## Vision Chat Completion Usage
Portkey supports the OpenAI signature to define messages with images as part of the API request. Images are made available to the model in two main ways: by passing a link to the image or by passing the base64 encoded image directly in the request.
Here's an example using OpenAI's `gpt-4o` model
> [tab] NodeJS
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> // Generate a chat completion with streaming
> async function getChatCompletionFunctions(){
> const response = await portkey.chat.completions.create({
> model: "gpt-4o-mini",
> messages: [{
> role: "user",
> content: [
> { type: "text", text: "What is in this image?" },
> {
> type: "image_url",
> image_url: {
> url: "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
> },
> },
> ],
> }],
> });
>
> console.log(response)
>
> }
> await getChatCompletionFunctions();
> ```
> [tab] Python
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> response = client.chat.completions.create(
> model="gpt-4o",
> messages=[{
> "role": "user",
> "content": [
> {"type": "text", "text": "What's in this image?"},
> {
> "type": "image_url",
> "image_url": {
> "url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
> },
> },
> ],
> }],
> )
>
> print(response)
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> // Generate a chat completion with streaming
> async function getChatCompletionFunctions(){
> const response = await openai.chat.completions.create({
> model: "gpt-4o-mini",
> messages: [{
> role: "user",
> content: [
> { type: "text", text: "What is in this image?" },
> {
> type: "image_url",
> image_url: {
> url: "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
> },
> },
> ],
> }],
> });
>
> console.log(response)
>
> }
> await getChatCompletionFunctions();
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> response = openai.chat.completions.create(
> model="gpt-4o-mini",
> messages=[{
> "role": "user",
> "content": [
> {"type": "text", "text": "What's in this image?"},
> {
> "type": "image_url",
> "image_url": {
> "url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
> },
> },
> ],
> }],
> )
>
>
> print(resonse)
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/chat/completions" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: openai" \
> -H "Authorization: Bearer $OPENAI_API_KEY" \
> -d '{
> "model": "gpt-4o-mini",
> "messages": [
> {
> "role": "user",
> "content": [
> {
> "type": "text",
> "text": "What is in this image?"
> },
> {
> "type": "image_url",
> "image_url": {
> "url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
> }
> }
> ]
> }
> ],
> "max_tokens": 300
> }'
> ```
### [API Reference](/docs/product/ai-gateway/multimodal-capabilities/vision#vision-chat-completion-usage)
On completion, the request will get logged in the logs UI where any image inputs or outputs can be viewed. Portkey will automatically load the image URLs or the base64 images making for a great debugging experience with vision models.

## Creating prompt templates for vision models
Portkey's prompt library supports creating templates with image inputs. If the same image will be used in all prompt calls, you can save it as part of the template's image URL itself. Or, if the image will be sent via the API as a variable, add a variable to the image link.
## Supported Providers and Models
Portkey supports all vision models from its integrated providers as they become available. The table below shows some examples of supported vision models. Please raise a [request](/docs/integrations/llms/suggest-a-new-integration) or a [PR](https://github.com/Portkey-AI/gateway/pulls) to add a provider to the AI gateway.
| Provider | Models | Functions |
| - | - | - |
| [OpenAI](/docs/integrations/llms/openai) | `gpt-4-vision-preview`, `gpt-4o`, `gpt-4o-mini ` | Create Chat Completion |
| [Azure OpenAI](/docs/integrations/llms/azure-openai) | `gpt-4-vision-preview`, `gpt-4o`, `gpt-4o-mini ` | Create Chat Completion |
| [Gemini](/docs/integrations/llms/gemini) | `gemini-1.0-pro-vision `, `gemini-1.5-flash`, `gemini-1.5-flash-8b`, `gemini-1.5-pro` | Create Chat Completion |
| [Anthropic](/docs/integrations/llms/anthropic) | `claude-3-sonnet`, `claude-3-haiku`, `claude-3-opus`, `claude-3.5-sonnet`, `claude-3.5-haiku` | Create Chat Completion |
| [AWS Bedrock](/docs/integrations/llms/aws-bedrock) | `anthropic.claude-3-5-sonnet anthropic.claude-3-5-haiku anthropic.claude-3-5-sonnet-20240620-v1:0` | Create Chat Completion |
For a complete list of all supported provider (including non-vision LLMs), check out our [providers documentation](/docs/integrations/llms).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Nitro Mode (Beta)
Source: https://docs.portkey.ai/docs/product/ai-gateway/nitro-mode
Forward the request body directly to the provider without any transformations. Best when your request and response structure already matches the provider's API.
> [!NOTE]
>
> Nitro mode is currently in **beta**. Behavior may change based on feedback. Contact the [Portkey account team](https://portkey.ai/docs/support/contact-us) to get access.
The Portkey Gateway supports **Nitro mode** through the `x-portkey-nitro-mode` header. When enabled, the gateway forwards your request body directly to the upstream provider **without reading or transforming it**. This is useful when your request and response structure already matches the provider's expected format and you don't need the gateway to modify the payload.
## How It Works
By default, the gateway reads the request body to power features like transformations, retries, fallbacks, guardrails, and other body-based configurations.
With Nitro mode enabled, the gateway **skips reading the request body entirely** and streams it straight to the provider. Since the body is never parsed, features that depend on inspecting or modifying the payload are not available in this mode. See [Limitations](#limitations) for details.
## When to Use Nitro Mode
Nitro mode is a good fit when:
* Your request and response structure **already matches the provider's API** and you don't need the gateway to transform the payload. This removes redundant request parsing, which is particularly beneficial for large payloads.
* You are routing to a **single provider** and don't need body-based gateway features like fallbacks, retries, or input guardrails.
If your use case depends on features like **fallbacks, retries, load balancing, request transformations, or input guardrails**, use the standard mode instead.
## Example
Add the header to your request:
| Header | Value |
| - | - |
| `x-portkey-nitro-mode` | `true` |
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: @openai-prod" \
-H "x-portkey-nitro-mode: true" \
-d '{"model": "gpt-4o", "messages": [{"role": "user", "content": "Hello"}]}'
```
```py Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="@openai-prod"
)
response = portkey.with_options(
extra_headers={"x-portkey-nitro-mode": "true"}
).chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Hello"}]
)
```
```js JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "@openai-prod"
});
const response = await portkey.chat.completions.create(
{ model: "gpt-4o", messages: [{ role: "user", content: "Hello" }] },
{ headers: { "x-portkey-nitro-mode": "true" } }
);
```
## Supported Endpoints
Nitro mode works only on the following endpoints:
| Endpoint | Description | Currently Supported Providers |
| - | - | - |
| `/v1/chat/completions` | Chat completions | OpenAI, Fireworks, OpenRouter |
| `/v1/embeddings` | Embeddings | OpenAI, Fireworks, OpenRouter |
| `/v1/messages` | Messages API | Anthropic |
| `/v1/responses` | Responses API | OpenAI, OpenRouter |
## Limitations
Since the gateway does not read the request body in Nitro mode, there are a few constraints on how you configure your request.
### Specifying the Provider
Because the body is never read, the provider **must** be specified through headers, not in the request body. There are two supported ways:
**Option 1: `x-portkey-provider` header**
Pass the provider slug directly as a header.
```sh theme={"system"}
-H "x-portkey-provider: @openai-prod"
```
**Option 2: `x-portkey-config` header**
Pass a config that contains a single provider at the top level.
```json theme={"system"}
// ✅ Works: single provider at top level
{
"provider": "@openai-prod"
}
```
```json theme={"system"}
// ❌ Does not work: multiple targets
{
"strategy": { "mode": "loadbalance" },
"targets": [
{ "provider": "@openai-prod" },
{ "provider": "@openai-backup" }
]
}
```
```json theme={"system"}
// ❌ Does not work: fallback strategy
{
"strategy": { "mode": "fallback" },
"targets": [
{ "provider": "@openai-prod" },
{ "provider": "@anthropic-prod" }
]
}
```
### Config Constraints
The following constraints apply when using `x-portkey-config`. If violated, the gateway returns an error (except for caching, which is silently ignored).
> [accordion] Single target only
>
> The config must route to exactly one provider. Strategies like `loadbalance`, `fallback`, or `conditional` with multiple targets are not supported.
>
> ```json theme={"system"}
> // ❌ Does not work
> {
> "strategy": { "mode": "loadbalance" },
> "targets": [
> { "provider": "@openai-prod" },
> { "provider": "@openai-backup" }
> ]
> }
> ```
>
> ```json theme={"system"}
> // ✅ Works
> {
> "provider": "@openai-prod"
> }
> ```
> [accordion] No retries
>
> Retries require re-reading the request body. Set `retry.attempts` to `0` or omit `retry` entirely.
>
> ```json theme={"system"}
> // ❌ Does not work
> {
> "provider": "@openai-prod",
> "retry": { "attempts": 3 }
> }
> ```
>
> ```json theme={"system"}
> // ✅ Works
> {
> "provider": "@openai-prod"
> }
> ```
> [accordion] No body-dependent hooks
>
> Hooks that inspect the request body (such as `input_guardrails` or `before_request_hooks`) are not supported. This also applies to default input guardrails set at the workspace or organisation level.
>
> ```json theme={"system"}
> // ❌ Does not work
> {
> "provider": "@openai-prod",
> "input_guardrails": [{ "id": "guardrail-1" }]
> }
> ```
>
> ```json theme={"system"}
> // ✅ Works
> {
> "provider": "@openai-prod"
> }
> ```
> [accordion] No override\_params
>
> Since the body is not read, `override_params` that change request body fields (such as `model` or `temperature`) have no effect and are not supported.
>
> ```json theme={"system"}
> // ❌ Does not work
> {
> "provider": "@openai-prod",
> "override_params": { "model": "gpt-4o-mini", "temperature": 0 }
> }
> ```
>
> ```json theme={"system"}
> // ✅ Works: pass model and parameters directly in the request body instead
> {
> "provider": "@openai-prod"
> }
> ```
> [accordion] Caching is ignored
>
> Caching requires reading the full request body to build cache keys. If your config includes `cache`, it will be **silently ignored**. No error is thrown, but the cache will not be used.
>
> ```json theme={"system"}
> // ⚠️ cache is silently ignored (no error, but no caching either)
> {
> "provider": "@openai-prod",
> "cache": { "mode": "simple" }
> }
> ```
## Errors
If your configuration violates any of the constraints above (except caching, which is silently ignored), the gateway returns an HTTP 4xx error describing the issue.
Fix the configuration as indicated in the error message, or remove the `x-portkey-nitro-mode` header to use standard gateway behavior.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Realtime API
Source: https://docs.portkey.ai/docs/product/ai-gateway/realtime-api
Use OpenAI's Realtime API with logs, cost tracking, and more!
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
[OpenAI's Realtime API](https://platform.openai.com/docs/guides/realtime) while the fastest way to use multi-modal generation, presents its own set of problems around logging, cost tracking and guardrails.
Portkey's AI Gateway provides a solution to these problems with a seamless integration. Portkeys logging is unique in that it captures the entire request and response, including the model's response, cost, and guardrail violations.
### Here's how to get started:
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import AsyncPortkey as Portkey, PORTKEY_GATEWAY_URL
> import asyncio
>
> async def main():
> client = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@PROVIDER",
> base_url=PORTKEY_GATEWAY_URL,
> )
>
> async with client.beta.realtime.connect(model="gpt-4o-realtime-preview-2024-10-01") as connection: #replace with the model you want to use
> await connection.session.update(session={'modalities': ['text']})
>
> await connection.conversation.item.create(
> item={
> "type": "message",
> "role": "user",
> "content": [{"type": "input_text", "text": "Say hello!"}],
> }
> )
> await connection.response.create()
>
> async for event in connection:
> if event.type == 'response.text.delta':
> print(event.delta, flush=True, end="")
>
> elif event.type == 'response.text.done':
> print()
>
> elif event.type == "response.done":
> break
>
> asyncio.run(main())
> ```
> [tab] NodeJS
>
> ```javascript theme={"system"}
> // coming soon
> ```
> [tab] OpenAI NodeJS
>
> ```javascript theme={"system"}
> // requires `yarn add ws @types/ws`
> import OpenAI from 'openai';
> import { OpenAIRealtimeWS } from 'openai/beta/realtime/ws';
> import { PORTKEY_GATEWAY_URL } from 'portkey-ai';
>
> const openai = new OpenAI({
> baseURL: PORTKEY_GATEWAY_URL,
> apiKey: "PORTKEY_API_KEY"
> });
> const rt = new OpenAIRealtimeWS({ model: '@PROVIDER/gpt-4o-realtime-preview-2024-12-17' }, openai);
>
> // access the underlying `ws.WebSocket` instance
> rt.socket.on('open', () => {
> console.log('Connection opened!');
> rt.send({
> type: 'session.update',
> session: {
> modalities: ['text'],
> model: 'gpt-4o-realtime-preview',
> },
> });
>
> rt.send({
> type: 'conversation.item.create',
> item: {
> type: 'message',
> role: 'user',
> content: [{ type: 'input_text', text: 'Say a couple paragraphs!' }],
> },
> });
>
> rt.send({ type: 'response.create' });
> });
>
> rt.on('error', (err) => {
> // in a real world scenario this should be logged somewhere as you
> // likely want to continue procesing events regardless of any errors
> throw err;
> });
>
> rt.on('session.created', (event) => {
> console.log('session created!', event.session);
> console.log();
> });
>
> rt.on('response.text.delta', (event) => process.stdout.write(event.delta));
> rt.on('response.text.done', () => console.log());
>
> rt.on('response.done', () => rt.close());
>
> rt.socket.on('close', () => console.log('\nConnection closed!'));
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> import asyncio
> from openai import AsyncOpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL
>
> async def main():
> client = AsyncOpenAI(
> base_url=PORTKEY_GATEWAY_URL,
> api_key="PORTKEY_API_KEY"
> )
>
> async with client.beta.realtime.connect(model="@PROVIDER/gpt-4o-realtime-preview") as connection: #replace with the model you want to use
> await connection.session.update(session={'modalities': ['text']})
>
> await connection.conversation.item.create(
> item={
> "type": "message",
> "role": "user",
> "content": [{"type": "input_text", "text": "Say hello!"}],
> }
> )
> await connection.response.create()
>
> async for event in connection:
> if event.type == 'response.text.delta':
> print(event.delta, flush=True, end="")
>
> elif event.type == 'response.text.done':
> print()
>
> elif event.type == "response.done":
> break
>
> asyncio.run(main())
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> # we're using websocat for this example, but you can use any websocket client
> websocat "wss://api.portkey.ai/v1/realtime?model=gpt-4o-realtime-preview-2024-10-01" \
> -H "x-portkey-provider: openai" \
> -H "x-portkey-provider: PROVIDER" \
> -H "x-portkey-OpenAI-Beta: realtime=v1" \
> -H "x-portkey-api-key: PORTKEY_API_KEY"
> # once connected, you can send your messages as you would with OpenAI's Realtime API
> ```
For advanced use cases, you can use configs ([https://portkey.ai/docs/product/ai-gateway/configs#configs](https://portkey.ai/docs/product/ai-gateway/configs#configs))
If you would not like to store your API Keys with Portkey, you can pass your openai key in the `Authorization` header.
## Fire Away!
You can see your logs in realtime with neatly visualized traces and cost tracking.

Realtime API Traces
## Next Steps
* [For more info on realtime API, refer here](https://platform.openai.com/docs/guides/realtime)
* [Portkeys OpenAI Integration](/docs/integrations/llms/openai)
* [Logs](/docs/product/observability/logs)
* [Traces](/docs/product/observability/traces)
* [Guardrails](/docs/product/guardrails)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Remote MCP
Source: https://docs.portkey.ai/docs/product/ai-gateway/remote-mcp
Portkey's AI gateway has MCP server support that many foundational model providers offer.
[Model Context Protocol](https://modelcontextprotocol.io/introduction) (MCP) is an open protocol that standardizes how applications provide tools and context to LLMs. The MCP tool in the Responses API allows developers to give the model access to tools hosted on **Remote MCP servers**. These are MCP servers maintained by developers and organizations across the internet that expose these tools to MCP clients, like the Responses API.
## Two Ways to Use Remote MCP
There are two ways to connect remote MCP servers through Portkey:
1. **Portkey Gateway execution** — Prefix the MCP server with `@portkey-mcp` in the [Responses API](#responses-api) or [Messages API](#messages-api), and send the following header `x-portkey-beta: server-side-mcp-2026-06-01`. Portkey fetches and executes tools on your behalf. See [Beta Features](/docs/product/ai-gateway/beta-features) for the full header reference.
2. **Provider execution** — Pass a `server_url` directly in the [OpenAI](#openai) or [Anthropic](#anthropic) sections below. The upstream provider connects to and executes MCP tools on their servers.
| | **Portkey Gateway (`@portkey-mcp`)** | **Provider Execution (`server_url`)** |
| - | - | - |
| **Where tools run** | Securely within your own VPC | On provider servers (OpenAI, Anthropic, etc.) |
| **Data exposure** | MCP credentials stay in your environment | Tokens may be exposed to provider training data and audit pipelines |
| **User attribution** | Actions attributed via your service/user API key | No per-user attribution |
| **Audit & logging** | MCP executions logged and available for audit | No execution logging or security controls |
> [!NOTE]
>
> **Using a Private MCP Server?** If your MCP server is behind a firewall, on localhost, or not publicly accessible, the model provider won't be able to reach it. Check out our guide on [Using Private MCP Servers](/docs/guides/use-cases/private-mcp-servers) to learn how to handle tool fetching and invocations on the client side.
## Responses API
When using upstream inference providers like bedrock, vertex-ai that do not support executing MCP tools remotely, you can pass the prefix `@portkey-mcp` to the mcp tool server\_label to execute the tool securely on the gateway and receive the response back from the gateway.
> [!NOTE]
>
> Fields in the MCP tool object like `server_description`, `server_url`, `require_approval` are not supported when using the `@portkey-mcp` prefix; they are ignored if passed.
```bash cURL theme={"system"}
curl --location 'https://api.portkey.ai/v1/responses' \
--header 'Content-Type: application/json' \
--header 'x-portkey-provider: @your-provider-slug' \
--header 'x-portkey-api-key: $PORTKEY_API_KEY' \
--header 'x-portkey-beta: server-side-mcp-2026-06-01' \
--data-raw '{
"model": "gpt-5.5",
"tools": [
{
"type": "mcp",
"server_label": "@portkey-mcp/your-mcp-server-label",
"allowed_tools": ["tool_name_1", "tool_name_2"] // Optional, default is all tools
}
],
"input": "what is portkey gateway"
}'
```
```javascript OpenAI Node SDK theme={"system"}
import OpenAI from "openai";
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "@your-provider-slug",
portkeyBeta: "server-side-mcp-2026-06-01",
})
});
const resp = await client.responses.create({
model: "gpt-5.5",
tools: [
{
type: "mcp",
server_label: "@portkey-mcp/your-mcp-server-label",
allowed_tools: ["tool_name_1", "tool_name_2"], // Optional, default is all tools
},
],
input: "what is portkey gateway",
});
console.log(resp.output_text);
```
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="@your-provider-slug",
portkeyBeta="server-side-mcp-2026-06-01",
)
)
resp = client.responses.create(
model="gpt-5.5",
tools=[
{
"type": "mcp",
"server_label": "@portkey-mcp/your-mcp-server-label",
"allowed_tools": ["tool_name_1", "tool_name_2"], # Optional, default is all tools
},
],
input="what is portkey gateway",
)
print(resp.output_text)
```
```typescript Portkey Node SDK theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "@your-provider-slug",
portkeyBeta: "server-side-mcp-2026-06-01"
});
const resp = await portkey.responses.create({
model: "gpt-5.5",
tools: [
{
type: "mcp",
server_label: "@portkey-mcp/your-mcp-server-label",
allowed_tools: ["tool_name_1", "tool_name_2"], // Optional, default is all tools
},
],
input: "what is portkey gateway",
});
console.log(resp.output_text);
```
```python Portkey Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="@your-provider-slug",
portkey_beta="server-side-mcp-2026-06-01"
)
resp = portkey.responses.create(
model="gpt-5.5",
tools=[
{
"type": "mcp",
"server_label": "@portkey-mcp/your-mcp-server-label",
"allowed_tools": ["tool_name_1", "tool_name_2"], # Optional, default is all tools
},
],
input="what is portkey gateway",
)
print(resp.output_text)
```
## Messages API
When using upstream inference providers like bedrock, vertex-ai that do not support executing MCP tools remotely, you can pass the prefix `@portkey-mcp` to the mcp tool mcp\_server\_name to execute the tool securely on the gateway and receive the response back from the gateway.
```bash cURL theme={"system"}
curl --location 'https://api.portkey.ai/v1/messages' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: $PORTKEY_API_KEY' \
--header 'x-portkey-beta: server-side-mcp-2026-06-01' \
--data-raw '{
"messages": [
{
"role": "user",
"content": "what is Portkey-AI gateway repository?"
}
],
"model": "@anthropic/claude-haiku-4-5",
"max_tokens": 10000,
"mcp_servers": [
{
"type": "url",
"url": "https://mcp.portkey.ai/server-name/mcp", // not required when using @portkey-mcp
"name": "@portkey-mcp/deepwiki"
}
],
"tools": {
"type": "mcp_toolset",
"mcp_server_name": "@portkey-mcp/deepwiki",
"default_config": {
"enabled": true
},
"configs": {
"specific_tool_name": {
"enabled": true
}
}
},
"stream": false
}'
```
```javascript Anthropic JS SDK theme={"system"}
import Anthropic from '@anthropic-ai/sdk'
const client = new Anthropic({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai",
defaultHeaders: {
"x-portkey-beta": "server-side-mcp-2026-06-01"
}
})
const message = await client.messages.create({
model: "@anthropic/claude-haiku-4-5",
max_tokens: 10000,
messages: [{
role: "user",
content: "what is Portkey-AI gateway repository?"
}],
mcp_servers: [{
type: "url",
name: "@portkey-mcp/deepwiki",
// url not required when using @portkey-mcp
}],
tools: {
type: "mcp_toolset",
mcp_server_name: "@portkey-mcp/deepwiki",
default_config: {
enabled: true
},
configs: {
specific_tool_name: {
enabled: true
}
}
},
stream: false
})
console.log(message.content)
```
```python Anthropic Python SDK theme={"system"}
import anthropic
client = anthropic.Anthropic(
api_key="dummy",
default_headers={
"x-portkey-api-key": "PORTKEY_API_KEY",
"x-portkey-beta": "server-side-mcp-2026-06-01"
},
base_url="https://api.portkey.ai"
)
message = client.messages.create(
model="@anthropic/claude-haiku-4-5",
max_tokens=10000,
messages=[{
"role": "user",
"content": "what is Portkey-AI gateway repository?"
}],
mcp_servers=[{
"type": "url",
"name": "@portkey-mcp/deepwiki",
# url not required when using @portkey-mcp
}],
tools={
"type": "mcp_toolset",
"mcp_server_name": "@portkey-mcp/deepwiki",
"default_config": {
"enabled": True
},
"configs": {
"specific_tool_name": {
"enabled": True
}
}
},
stream=False
)
print(message.content)
```
## OpenAI
A Responses API request to OpenAI with MCP tools enabled.
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@OPENAI_PROVIDER/gpt-4.1",
"tools": [
{
"type": "mcp",
"server_label": "deepwiki",
"server_url": "https://mcp.deepwiki.com/mcp",
"require_approval": "never"
}
],
"input": "What transport protocols are supported in the 2025-03-26 version of the MCP spec?"
}'
```
```javascript OpenAI Node SDK theme={"system"}
import OpenAI from "openai";
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: PORTKEY_GATEWAY_URL
});
const resp = await client.responses.create({
model: "@OPENAI_PROVIDER/gpt-4.1",
tools: [
{
type: "mcp",
server_label: "deepwiki",
server_url: "https://mcp.deepwiki.com/mcp",
require_approval: "never",
},
],
input: "What transport protocols are supported in the 2025-03-26 version of the MCP spec?",
});
console.log(resp.output_text);
```
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url=PORTKEY_GATEWAY_URL,
)
resp = client.responses.create(
model="@OPENAI_PROVIDER/gpt-4.1",
tools=[
{
"type": "mcp",
"server_label": "deepwiki",
"server_url": "https://mcp.deepwiki.com/mcp",
"require_approval": "never",
},
],
input="What transport protocols are supported in the 2025-03-26 version of the MCP spec?",
)
print(resp.output_text)
```
```typescript Portkey Node SDK theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
});
const resp = await portkey.responses.create({
model: "@OPENAI_PROVIDER/gpt-4.1",
tools: [
{
type: "mcp",
server_label: "deepwiki",
server_url: "https://mcp.deepwiki.com/mcp",
require_approval: "never",
},
],
input: "What transport protocols are supported in the 2025-03-26 version of the MCP spec?",
});
console.log(resp.output_text);
```
```python Portkey Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY"
)
resp = portkey.responses.create(
model="@OPENAI_PROVIDER/gpt-4.1",
tools=[
{
"type": "mcp",
"server_label": "deepwiki",
"server_url": "https://mcp.deepwiki.com/mcp",
"require_approval": "never",
},
],
input="What transport protocols are supported in the 2025-03-26 version of the MCP spec?",
)
print(resp.output_text)
```

Example Log for the request on Portkey
### MCP Server Authentication
Unlike the DeepWiki MCP server, most other MCP servers require authentication. The MCP tool in the Responses API gives you the ability to flexibly specify headers that should be included in any request made to a remote MCP server. These headers can be used to share API keys, oAuth access tokens, or any other authentication scheme the remote MCP server implements.
you can pass additional headers in the headers object or the oauth token in the authorization key.
Use Stripe MCP tool
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@OPENAI_PROVIDER/gpt-4.1",
"input": "Create a payment link for $20",
"tools": [
{
"type": "mcp",
"server_label": "stripe",
"server_url": "https://mcp.stripe.com",
"headers": {
"Authorization": "Bearer $STRIPE_API_KEY"
}
}
]
}'
```
```javascript OpenAI Node SDK theme={"system"}
import OpenAI from "openai";
import { PORTKEY_GATEWAY_URL } from 'portkey-ai'
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: PORTKEY_GATEWAY_URL
});
const resp = await client.responses.create({
model: "@OPENAI_PROVIDER/gpt-4.1",
input: "Create a payment link for $20",
tools: [
{
type: "mcp",
server_label: "stripe",
server_url: "https://mcp.stripe.com",
headers: {
Authorization: "Bearer $STRIPE_API_KEY"
}
}
]
});
console.log(resp.output_text);
```
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url=PORTKEY_GATEWAY_URL
)
resp = client.responses.create(
model="@OPENAI_PROVIDER/gpt-4.1",
input="Create a payment link for $20",
tools=[
{
"type": "mcp",
"server_label": "stripe",
"server_url": "https://mcp.stripe.com",
"headers": {
"Authorization": "Bearer $STRIPE_API_KEY"
}
}
]
)
print(resp.output_text)
```
```typescript Portkey Node SDK theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
});
const resp = await portkey.responses.create({
model: "@OPENAI_PROVIDER/gpt-4.1",
input: "Create a payment link for $20",
tools: [
{
type: "mcp",
server_label: "stripe",
server_url: "https://mcp.stripe.com",
headers: {
Authorization: "Bearer $STRIPE_API_KEY"
}
}
]
});
console.log(resp.output_text);
```
```python Portkey Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY"
)
resp = portkey.responses.create(
model="@OPENAI_PROVIDER/gpt-4.1",
input="Create a payment link for $20",
tools=[
{
"type": "mcp",
"server_label": "stripe",
"server_url": "https://mcp.stripe.com",
"headers": {
"Authorization": "Bearer $STRIPE_API_KEY"
}
}
]
)
print(resp.output_text)
```
To prevent the leakage of sensitive keys, the Responses API does not store the values of **any** string you provide in the `headers` object. These values will also not be visible in the Response object created. Additionally, because some remote MCP servers generate authenticated URLs, we also discard the *path* portion of the `server_url` in our responses (i.e. `example.com/mcp` becomes `example.com`). Because of this, you must send the full path of the MCP `server_url` and any relevant `headers` in every Responses API creation request you make.
### Using MCP Servers Registered on Portkey
If you have MCP servers registered on Portkey's [MCP Gateway](/docs/product/mcp-gateway), you can connect to them through the Responses API by passing the appropriate authentication in the tool definition.
* **No-auth or header-based auth servers**: Pass your Portkey API key as `x-portkey-api-key` inside the `headers` object.
* **OAuth-based servers**: Pass the OAuth access token using the `authorization` field on the tool.
#### Header-based auth (or no auth)
```json theme={"system"}
{
"model": "@OPENAI_PROVIDER/gpt-4.1",
"tools": [
{
"type": "mcp",
"server_label": "dmcp",
"server_description": "deepwiki mcp",
"server_url": "https://mcp.portkey.ai/deepwiki/mcp",
"headers": {
"x-portkey-api-key": "{{PORTKEY_API_KEY}}"
},
"require_approval": "never"
}
],
"input": "what is portkey gateway"
}
```
#### OAuth-based auth
```json theme={"system"}
{
"model": "@OPENAI_PROVIDER/gpt-4.1",
"tools": [
{
"type": "mcp",
"server_label": "dmcp",
"server_description": "deepwiki mcp",
"server_url": "https://mcp.portkey.ai/deepwiki/mcp",
"authorization": "{{OAUTH_TOKEN}}",
"require_approval": "never"
}
],
"input": "what is portkey gateway"
}
```
## Anthropic
Claude's Model Context Protocol (MCP) connector feature enables you to connect to remote MCP servers directly from the Messages API without a separate MCP client.
> [!NOTE]
>
> This feature requires the beta header: `"anthropic-beta": "mcp-client-2025-04-04"`
**Key features**
* **Direct API integration**: Connect to MCP servers without implementing an MCP client
* **Tool calling support**: Access MCP tools through the Messages API
* **OAuth authentication**: Support for OAuth Bearer tokens for authenticated servers
* **Multiple servers**: Connect to multiple MCP servers in a single request
#### Using the MCP connector in the Messages API
To connect to a remote MCP server, include the `mcp_servers` parameter in your Messages API request:
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "X-API-Key: dummy" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: mcp-client-2025-04-04" \
-H "x-portkey-api-key: PORTKEY_API_KEY" \
-d '{
"model": "@your-provider-slug/your-model-name",
"max_tokens": 1000,
"messages": [{"role": "user", "content": "What tools do you have available?"}],
"mcp_servers": [
{
"type": "url",
"url": "https://example-server.modelcontextprotocol.io/sse",
"name": "example-mcp",
"authorization_token": "YOUR_TOKEN"
}
]
}'
```
```typescript Anthropic TS SDK theme={"system"}
const response = await anthropic.beta.messages.create({
model: "claude-sonnet-4-20250514",
max_tokens: 1000,
messages: [
{
role: "user",
content: "What tools do you have available?",
},
],
mcp_servers: [
{
type: "url",
url: "https://example-server.modelcontextprotocol.io/sse",
name: "example-mcp",
authorization_token: "YOUR_TOKEN",
},
],
betas: ["mcp-client-2025-04-04"],
});
```
```python Anthropic Python SDK theme={"system"}
response = anthropic.beta.messages.create(
model="claude-sonnet-4-20250514",
max_tokens=1000,
messages=[{
"role": "user",
"content": "What tools do you have available?"
}],
mcp_servers=[{
"type": "url",
"url": "https://mcp.example.com/sse",
"name": "example-mcp",
"authorization_token": "YOUR_TOKEN"
}],
betas=["mcp-client-2025-04-04"]
)
```
```ts Python SDK theme={"system"}
Coming soon!
```
```ts Node SDK theme={"system"}
Coming soon!
```
**MCP server configuration**
Each MCP server in the `mcp_servers` array supports the following configuration:
```json theme={"system"}
{
"type": "url",
"url": "https://example-server.modelcontextprotocol.io/sse",
"name": "example-mcp",
"tool_configuration": {
"enabled": true,
"allowed_tools": ["example_tool_1", "example_tool_2"]
},
"authorization_token": "YOUR_TOKEN"
}
```
##### Field descriptions
| Property | Type | Required | Description |
| - | - | - | - |
| `type` | string | Yes | Currently only "url" is supported |
| `url` | string | Yes | The URL of the MCP server. Must start with https\:// |
| `name` | string | Yes | A unique identifier for this MCP server. It will be used in `mcp_tool_call` blocks to identify the server and to disambiguate tools to the model. |
| `tool_configuration` | object | No | Configure tool usage |
| `tool_configuration.enabled` | boolean | No | Whether to enable tools from this server (default: true) |
| `tool_configuration.allowed_tools` | array | No | List to restrict the tools to allow (by default, all tools are allowed) |
| `authorization_token` | string | No | OAuth authorization token if required by the MCP server. See [MCP specification](https://modelcontextprotocol.io/specification/2025-03-26/basic/authorization). |
#### Response content types
When Claude uses MCP tools, the response will include two new content block types:
##### MCP Tool Use Block
```json theme={"system"}
{
"type": "mcp_tool_use",
"id": "mcptoolu_014Q35RayjACSWkSj4X2yov1",
"name": "echo",
"server_name": "example-mcp",
"input": { "param1": "value1", "param2": "value2" }
}
```
##### MCP Tool Result Block
```json theme={"system"}
{
"type": "mcp_tool_result",
"tool_use_id": "mcptoolu_014Q35RayjACSWkSj4X2yov1",
"is_error": false,
"content": [
{
"type": "text",
"text": "Hello"
}
]
}
```
#### MCP Server Authentication
For MCP servers that require OAuth authentication, you'll need to obtain an access token. The MCP connector beta supports passing an `authorization_token` parameter in the MCP server definition.
API consumers are expected to handle the OAuth flow and obtain the access token prior to making the API call, as well as refreshing the token as needed.
##### Obtaining an access token for testing
The MCP inspector can guide you through the process of obtaining an access token for testing purposes.
1. Run the inspector with the following command. You need Node.js installed on your machine.
```bash theme={"system"}
npx @modelcontextprotocol/inspector
```
2. In the sidebar on the left, for "Transport type", select either "SSE" or "Streamable HTTP".
3. Enter the URL of the MCP server.
4. In the right area, click on the "Open Auth Settings" button after "Need to configure authentication?".
5. Click "Quick OAuth Flow" and authorize on the OAuth screen.
6. Follow the steps in the "OAuth Flow Progress" section of the inspector and click "Continue" until you reach "Authentication complete".
7. Copy the `access_token` value.
8. Paste it into the `authorization_token` field in your MCP server configuration.
##### Using the access token
Once you've obtained an access token using either OAuth flow above, you can use it in your MCP server configuration:
```json theme={"system"}
{
"mcp_servers": [
{
"type": "url",
"url": "https://example-server.modelcontextprotocol.io/sse",
"name": "authenticated-server",
"authorization_token": "YOUR_ACCESS_TOKEN_HERE"
}
]
}
```
For detailed explanations of the OAuth flow, refer to the [Authorization section](https://modelcontextprotocol.io/docs/concepts/authentication) in the MCP specification.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Request Timeouts
Source: https://docs.portkey.ai/docs/product/ai-gateway/request-timeouts
Manage unpredictable LLM latencies effectively with Portkey's **Request Timeouts**.
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
This feature allows automatic termination of requests that exceed a specified duration, letting you gracefully handle errors or make another, faster request.
## Enabling Request Timeouts
You can enable request timeouts while **making your request** or you can **set them in Configs**.
Request timeouts are specified in **milliseconds** (`integer)`
### While Making Request
Set request timeout while instantiating your Portkey client or if you're using the REST API, send the `x-portkey-request-timeout` header.
> [tab] NodeJS
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> requestTimeout: 3000
> })
>
> const chatCompletion = await portkey.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: '@openai/gpt-4o-mini',
> });
>
> console.log(chatCompletion.choices);
> ```
> [tab] Python
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> request_timeout=3000
> )
>
> completion = portkey.chat.completions.create(
> messages = [{ "role": 'user', "content": 'Say this is a test' }],
> model = '@openai/gpt-4o-mini'
> )
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl "https://api.portkey.ai/v1/chat/completions" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-request-timeout:5000" \
> -d '{
> "model": "@openai/gpt-4o-mini",
> "messages": [{"role": "user", "content": "Hello!"}]
> }'
> ```
### With Configs
In Configs, request timeouts are set at either (1) strategy level, or (2) target level.
For a 10-second timeout, it will be:
```json theme={"system"}
"request_timeout": 10000
```
### Setting Request Timeout at Strategy Level
```JSON theme={"system"}
{
"strategy": { "mode": "fallback" },
"request_timeout": 10000,
"targets": [
{ "provider":"@openai" },
{ "provider":"@azure-openai" }
]
}
```
Here, the request timeout of 10 seconds will be applied to \* **all**\* the targets in this Config.
### Setting Request Timeout at Target Level
```JSON theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{ "provider":"@openai", "request_timeout": 10000, },
{ "provider":"@azure-openai", "request_timeout": 2000,}
]
}
```
Here, for the first target, a request timeout of 10s will be set, while for the second target, a request timeout of 2s will be set.
> [!NOTE]
>
> Nested target objects inherit the top-level timeout, with the option to override it at any level for customized control.
### How timeouts work in nested Configs
```JSON theme={"system"}
{
"strategy": { "mode": "loadbalance" },
"request_timeout": 2000,
"targets": [
{
"strategy": { "mode":"fallback" },
"request_timeout": 5000,
"targets": [
{
"provider:"@openai"
},
{
"provider":"@azure-openai",
"request_timeout": 10000
}
],
"weight": 1
},
{
"provider":"@azure-openai",
"weight": 1
}
]
}
```
1. We've set a global timeout of **2s** at line #3
2. The first target has a nested fallback strategy, with a top level request timeout of **5s** at line #7
3. The first provider (at line #10), the **target-level** timeout of **5s** will be applied
4. For the second provider (i.e. `azure-openai`), there is a timeout override, set at **10s**, which will be applied only to this target
5. For the last provider (i.e. provider `azure-openai`), the top strategy-level timeout of **2s** will be applied
## Handling Request Timeouts
Portkey issues a standard **408 error** for timed-out requests. You can leverage this by setting up fallback or retry strategies through the `on_status_codes` parameter, ensuring robust handling of these scenarios.
### Triggering Fallbacks with Request Timeouts
```JSON theme={"system"}
{
"strategy": {
"mode": "fallback",
"on_status_codes": [408]
},
"targets": [
{ "provider":"@openai", "request_timeout": 2000, },
{ "provider":"@azure-openai"}
]
}
```
Here, fallback from OpenAI to Azure OpenAI will only be triggered if the first request times out after 2 seconds, otherwise the request will fail with a 408 error code.
### Triggering Retries with Request Timeouts
```JSON theme={"system"}
{
"request_timeout": 1000,
"retry": { "attempts": 3, "on_status_codes": [ 408 ] },
"provider":"@openai"
}
```
Here, retry is triggered upto 3 times whenever the request takes more than 1s to return a response. After 3 unsuccessful retries, it will fail with a 408 code.
[Here's a general guide on how to use Configs in your requests.](/docs/product/ai-gateway/configs)
### Caveats and Considerations
While the request timeout is a powerful feature to help you gracefully handle unruly models & their latencies, there are a few things to consider:
1. Ensure that you are setting reasonable timeouts - for example, models like `gpt-4` often have sub-10-second response times
2. Ensure that you gracefully handle 408 errors for whenever a request does get timed out - you can inform the user to rerun their query and setup some neat interactions on your app
3. For streaming requests, the timeout will not be triggered if it gets **atleast a chunk** before the specified duration.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Open Responses
Source: https://docs.portkey.ai/docs/product/ai-gateway/responses-api
Use the Responses API with any LLM provider through Portkey's AI Gateway — fully compliant with the Open Responses specification.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
[Open Responses](https://www.openresponses.org/) is an open-source specification for multi-provider, interoperable LLM interfaces based on the OpenAI Responses API. It defines a shared schema for calling language models, streaming results, and composing agentic workflows — independent of provider.
**Portkey is fully Open Responses compliant.** The Responses API works with every provider and model in Portkey's catalog — including Anthropic, Gemini, Bedrock, and 60+ other providers that don't natively support it.
## Why Responses API
The Responses API is becoming the standard for agentic AI:
* **Agentic loops** — Models emit tool calls, receive results, and continue autonomously
* **Items as atomic units** — Clear state machines for context management
* **Semantic streaming** — Predictable, provider-agnostic streaming events
* **Unified tool calling** — Consistent function calling interface across all providers
Previously, the Responses API only worked with OpenAI. Portkey extends it to all providers.
## Quick Start
Send a Responses API request to any provider. Change the `model` string -- the API format stays the same.
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Explain quantum computing in simple terms"
)
print(response.output_text)
```
```javascript JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Explain quantum computing in simple terms"
});
console.log(response.output_text);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"input": "Explain quantum computing in simple terms"
}'
```
> [!NOTE]
>
> The same code works for **any provider**. Switch the `@provider/model` string to use OpenAI, Gemini, Groq, Bedrock, or any of the 3000+ supported models. See [Model Catalog](/docs/product/model-catalog) for setup.
### Using the OpenAI SDK
The Portkey SDK is a superset of the OpenAI SDK, so `portkey.responses.create()` works identically. The OpenAI SDK also works directly with Portkey's base URL:
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1"
)
response = client.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Explain quantum computing in simple terms"
)
print(response.output_text)
```
```javascript OpenAI Node SDK theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1"
});
const response = await client.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Explain quantum computing in simple terms"
});
console.log(response.output_text);
```
## Text Generation
### Instructions (System Prompt)
Set a system prompt with `instructions` or pass a `system` role message in the `input` array. Both work identically.
```python Using instructions theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
instructions="You are a pirate. Always respond in pirate speak.",
input="Say hello."
)
```
```python Using system message theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[
{"type": "message", "role": "system", "content": "You are a pirate. Always respond in pirate speak."},
{"type": "message", "role": "user", "content": "Say hello."}
]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
instructions: "You are a pirate. Always respond in pirate speak.",
input: "Say hello."
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"instructions": "You are a pirate. Always respond in pirate speak.",
"input": "Say hello."
}'
```
### Streaming
Enable streaming with `stream: true`.
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
stream = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Write a haiku about AI",
stream=True
)
for event in stream:
if hasattr(event, 'delta'):
print(event.delta, end="", flush=True)
```
```javascript JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const stream = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Write a haiku about AI",
stream: true
});
for await (const event of stream) {
if (event.type === 'response.output_text.delta') {
process.stdout.write(event.delta);
}
}
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"input": "Write a haiku about AI",
"stream": true
}'
```
Portkey's adapter produces the same SSE event stream format (`response.created`, `response.output_text.delta`, `response.completed`, etc.) regardless of the underlying provider.
### Multi-turn Conversations
Pass previous messages in the `input` array for multi-turn conversations. Two formats are supported:
```python Shorthand format theme={"system"}
# Shorthand: just role + content
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[
{"role": "user", "content": "My name is Alice."},
{"role": "assistant", "content": "Hello Alice! How can I help you?"},
{"role": "user", "content": "What is my name?"}
]
)
```
```python Explicit format theme={"system"}
# Explicit: type: "message" wrapper (matches Open Responses spec)
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[
{"type": "message", "role": "user", "content": "My name is Alice."},
{"type": "message", "role": "assistant", "content": "Hello Alice! How can I help you?"},
{"type": "message", "role": "user", "content": "What is my name?"}
]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: [
{ type: "message", role: "user", content: "My name is Alice." },
{ type: "message", role: "assistant", content: "Hello Alice! How can I help you?" },
{ type: "message", role: "user", content: "What is my name?" }
]
});
```
Supported roles: `user`, `assistant`, `developer` (maps to system), `system`, and `tool`.
### Generation Parameters
Control generation behavior with optional parameters:
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Write a creative story",
max_output_tokens=2048,
temperature=0.8,
top_p=0.95,
parallel_tool_calls=True
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Write a creative story",
max_output_tokens: 2048,
temperature: 0.8,
top_p: 0.95,
parallel_tool_calls: true
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"input": "Write a creative story",
"max_output_tokens": 2048,
"temperature": 0.8,
"top_p": 0.95
}'
```
| Parameter | Type | Description |
| - | - | - |
| `max_output_tokens` | integer | Maximum tokens in the response. If not set, uses the provider's default |
| `temperature` | float | Sampling temperature (0-2). Higher = more creative |
| `top_p` | float | Nucleus sampling threshold (0-1) |
| `parallel_tool_calls` | boolean | Allow multiple tool calls in a single response (default: `true`) |
| `user` | string | End-user identifier for abuse tracking |
| `metadata` | object | Arbitrary metadata to attach to the response |
## Tool Calling
Define tools with the Responses API `function` tool format. Works across all providers that support function calling.
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="What's the weather in San Francisco?",
tools=[{
"type": "function",
"name": "get_weather",
"description": "Get current weather for a location",
"parameters": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}]
)
print(response.output)
```
```javascript JavaScript theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "What's the weather in San Francisco?",
tools: [{
type: "function",
name: "get_weather",
description: "Get current weather for a location",
parameters: {
type: "object",
properties: {
location: { type: "string", description: "City name" }
},
required: ["location"]
}
}]
});
console.log(response.output);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"input": "What'\''s the weather in San Francisco?",
"tools": [{
"type": "function",
"name": "get_weather",
"description": "Get current weather for a location",
"parameters": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}]
}'
```
### Tool Choice
Control tool usage with `tool_choice`:
| Value | Behavior |
| - | - |
| `"auto"` | Model decides whether to call a tool (default) |
| `"none"` | Model will not call any tools |
| `"required"` | Model must call at least one tool |
| `{"type": "function", "name": "get_weather"}` | Force a specific tool |
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="What's the weather in San Francisco?",
tools=[...],
tool_choice="required"
)
```
### Function Call Results
Return function call results in a multi-turn flow with `function_call` and `function_call_output` items:
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[
{"role": "user", "content": "What's the weather in Paris?"},
{"type": "function_call", "name": "get_weather", "call_id": "call_123", "arguments": '{"location": "Paris"}'},
{"type": "function_call_output", "call_id": "call_123", "output": '{"temp": "22°C", "condition": "sunny"}'}
],
tools=[{
"type": "function",
"name": "get_weather",
"description": "Get weather for a location",
"parameters": {"type": "object", "properties": {"location": {"type": "string"}}, "required": ["location"]}
}]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: [
{ role: "user", content: "What's the weather in Paris?" },
{ type: "function_call", name: "get_weather", call_id: "call_123", arguments: '{"location": "Paris"}' },
{ type: "function_call_output", call_id: "call_123", output: '{"temp": "22°C", "condition": "sunny"}' }
],
tools: [{
type: "function",
name: "get_weather",
description: "Get weather for a location",
parameters: { type: "object", properties: { location: { type: "string" } }, required: ["location"] }
}]
});
```
## Input Types
### Vision
Send images with the `input_image` content type. The optional `detail` parameter (`"high"`, `"low"`, `"auto"`) controls processing fidelity.
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[{
"role": "user",
"content": [
{"type": "input_image", "image_url": "https://example.com/image.jpg", "detail": "high"},
{"type": "input_text", "text": "Describe this image"}
]
}]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: [{
role: "user",
content: [
{ type: "input_image", image_url: "https://example.com/image.jpg", detail: "high" },
{ type: "input_text", text: "Describe this image" }
]
}]
});
```
### File Inputs
Send files with the `input_file` content type. Pass file data as a base64-encoded data URL or reference an existing file by `file_id`.
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[{
"role": "user",
"content": [
{"type": "input_file", "filename": "report.pdf", "file_data": "data:application/pdf;base64,JVBERi0xLjQ..."},
{"type": "input_text", "text": "Summarize this document"}
]
}]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: [{
role: "user",
content: [
{ type: "input_file", filename: "report.pdf", file_data: "data:application/pdf;base64,JVBERi0xLjQ..." },
{ type: "input_text", text: "Summarize this document" }
]
}]
});
```
## Structured Output
Control output format with `text.format`. Supports `json_schema` for strict structured output and `json_object` for free-form JSON.
### JSON Schema
```python Python theme={"system"}
response = portkey.responses.create(
model="@openai-provider/gpt-4.1",
input="Extract the name and age from: John is 30 years old.",
text={
"format": {
"type": "json_schema",
"name": "person",
"schema": {
"type": "object",
"properties": {
"name": {"type": "string"},
"age": {"type": "integer"}
},
"required": ["name", "age"]
}
}
}
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@openai-provider/gpt-4.1",
input: "Extract the name and age from: John is 30 years old.",
text: {
format: {
type: "json_schema",
name: "person",
schema: {
type: "object",
properties: {
name: { type: "string" },
age: { type: "integer" }
},
required: ["name", "age"]
}
}
}
});
```
### JSON Object
For free-form JSON output without a strict schema:
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="List 3 programming languages and their main use cases as JSON",
text={"format": {"type": "json_object"}}
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "List 3 programming languages and their main use cases as JSON",
text: { format: { type: "json_object" } }
});
```
## Reasoning and Thinking
Control reasoning with the unified `reasoning` parameter. Portkey maps this to each provider's native thinking mechanism automatically.
### Reasoning Effort
`reasoning.effort` controls how much the model reasons before responding. Works across OpenAI, Anthropic, and Gemini — Portkey translates to each provider's native format.
```python Anthropic theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Solve this step by step: What is 127 * 43?",
reasoning={"effort": "high"}
)
```
```python OpenAI theme={"system"}
response = portkey.responses.create(
model="@openai-provider/o4-mini",
input="Solve this step by step: What is 127 * 43?",
reasoning={"effort": "high"}
)
```
```python Gemini theme={"system"}
response = portkey.responses.create(
model="@google-provider/gemini-2.5-flash",
input="Solve this step by step: What is 127 * 43?",
reasoning={"effort": "high"}
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Solve this step by step: What is 127 * 43?",
reasoning: { effort: "high" }
});
```
Portkey maps `reasoning.effort` to each provider's native thinking configuration:
> [accordion] Anthropic — maps to thinking.budget\_tokens
>
> | Effort | Budget Tokens |
> | - | - |
> | `low` | 1,024 |
> | `medium` | 8,192 |
> | `high` | 16,384 |
> | `xhigh` | 32,768 |
> [accordion] Gemini 2.5 — maps to thinking\_config.thinking\_budget
>
> | Effort | Budget Tokens |
> | - | - |
> | `low` | 1,024 |
> | `medium` | 8,192 |
> | `high` | 24,576 |
> [accordion] OpenAI o-series
>
> Passed through as `reasoning_effort` natively. No translation needed.
### Anthropic Extended Thinking
For fine-grained control over Anthropic's extended thinking, pass the `thinking` parameter directly with an exact `budget_tokens` value. This takes precedence over `reasoning.effort` if both are set.
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Analyze the implications of quantum computing on cryptography",
thinking={"type": "enabled", "budget_tokens": 10000}
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Analyze the implications of quantum computing on cryptography",
thinking: { type: "enabled", budget_tokens: 10000 }
});
```
## Prompt Caching
Enable prompt caching with `cache_control` on content items and tools. Works with Anthropic and other compatible providers.
```python Python theme={"system"}
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input=[{
"role": "user",
"content": [
{"type": "input_text", "text": "Here is a long document to analyze...", "cache_control": {"type": "ephemeral"}},
{"type": "input_text", "text": "Summarize the key points"}
]
}]
)
```
```javascript JavaScript theme={"system"}
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: [{
role: "user",
content: [
{ type: "input_text", text: "Here is a long document to analyze...", cache_control: { type: "ephemeral" } },
{ type: "input_text", text: "Summarize the key points" }
]
}]
});
```
Cache control also works on tool definitions:
```python Python theme={"system"}
tools=[{
"type": "function",
"name": "search",
"description": "Search the knowledge base",
"parameters": {"type": "object", "properties": {"query": {"type": "string"}}},
"cache_control": {"type": "ephemeral"}
}]
```
## Using with Portkey Features
The Responses API works with all Portkey gateway features.
> [card] [Configs](/docs/product/ai-gateway/configs)
>
> Route, load balance, and set fallbacks
> [card] [Caching](/docs/product/ai-gateway/cache-simple-and-semantic)
>
> Cache responses for faster, cheaper calls
> [card] [Guardrails](/docs/product/guardrails)
>
> Input/output guardrails
> [card] [Observability](/docs/product/observability)
>
> Full logging and tracing
Pass features through headers or the config parameter:
```python Python theme={"system"}
portkey = Portkey(
api_key="PORTKEY_API_KEY",
config="pp-config-xxx" # Your Portkey config with fallbacks, load balancing, etc.
)
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Hello!"
)
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pp-config-xxx" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"input": "Hello!"
}'
```
## Provider Support
Portkey handles the Responses API in two ways depending on the provider:
* **Native providers** — Requests pass through directly to the provider's Responses API endpoint
* **Adapter providers** — Portkey automatically translates between Responses API and Chat Completions formats
This translation is transparent — the response format is identical regardless of which provider handles the request.
**Native providers:** OpenAI, Azure OpenAI, Grok (x.ai), Groq, OpenRouter, Azure AI, Perplexity AI
**Adapter providers:** Anthropic, Google Gemini, Google Vertex AI, AWS Bedrock, Mistral AI, Together AI, and [all other providers](/docs/integrations)
All features documented on this page — text generation, streaming, tool calling, reasoning, vision, structured output, prompt caching, and multi-turn conversations — work with both native and adapter providers.
### Native-Only Features
A few features require server-side state and are limited to native providers:
* **`previous_response_id`** — Use [multi-turn conversations](#multi-turn-conversations) to pass history in the `input` array instead
* **`store`** — Silently ignored on adapter providers; responses are not persisted server-side
* **Retrieve / Delete** — `GET` and `DELETE` on `/v1/responses/:id` are not available
* **Built-in tools** — `web_search`, `file_search`, `computer_use` are native-only. Use [Remote MCP](/docs/product/ai-gateway/remote-mcp) or custom function tools instead
Everything else — text generation, streaming, instructions, tool calling, structured output, reasoning, vision, file inputs, prompt caching, and multi-turn conversations — works with **every provider**.
## Reference
### Supported Parameters
Complete list of parameters supported by the Responses API and how they map internally:
| Responses API Parameter | Chat Completions Equivalent | Notes |
| - | - | - |
| `input` | `messages` | String, message array, or typed input items |
| `instructions` | System message (prepended) | Added as the first message with `role: system` |
| `model` | `model` | Use `@provider/model` format or set provider via headers |
| `stream` | `stream` | SSE events are translated to Responses API format |
| `max_output_tokens` | `max_tokens` | Only sent if explicitly set |
| `temperature` | `temperature` | Direct mapping |
| `top_p` | `top_p` | Direct mapping |
| `tools` | `tools` | Only `function` type is supported |
| `tool_choice` | `tool_choice` | `auto`, `none`, `required`, or specific function |
| `parallel_tool_calls` | `parallel_tool_calls` | Direct mapping |
| `text.format` | `response_format` | `json_schema` and `json_object` supported |
| `reasoning.effort` | Provider-specific | Mapped to thinking for Anthropic/Gemini, `reasoning_effort` for OpenAI |
| `thinking` | `thinking` | Anthropic-specific passthrough |
| `top_logprobs` | `top_logprobs` | Direct mapping |
| `user` | `user` | Direct mapping |
| `metadata` | `metadata` | Direct mapping |
> [accordion] Input Content Types
>
> | Content Type | Description |
> | - | - |
> | `input_text` | Text content (maps to `text` in Chat Completions) |
> | `input_image` | Image URL with optional `detail` parameter |
> | `input_file` | File with `filename` and `file_data` (base64 data URL) or `file_id` |
> | `function_call` | Tool call record with `name`, `call_id`, and `arguments` |
> | `function_call_output` | Tool result with `call_id` and `output` |
> [accordion] Response Output Types
>
> | Output Type | Description |
> | - | - |
> | `message` | Text response with `output_text` content |
> | `function_call` | Tool call with `name`, `call_id`, `arguments`, and `status` |
> | `reasoning` | Thinking/reasoning content with `summary` array (from providers that support it) |
### API Endpoints
* [Create a Response](/docs/api-reference/inference-api/responses/responses) -- `POST /v1/responses`
* [Retrieve a Response](/docs/api-reference/inference-api/responses/retrieve-response) -- `GET /v1/responses/{response_id}`
* [Delete a Response](/docs/api-reference/inference-api/responses/delete-response) -- `DELETE /v1/responses/{response_id}`
* [List Input Items](/docs/api-reference/inference-api/responses/retrieve-inputs) -- `GET /v1/responses/{response_id}/input_items`
> [card] [Open Responses Spec](https://www.openresponses.org/specification)
>
> Full specification
> [card] [API Reference](/docs/api-reference/inference-api/responses/responses)
>
> Responses API reference
> [card] [Remote MCP](/docs/product/ai-gateway/remote-mcp)
>
> MCP via Responses API
> [card] [Universal API](/docs/product/ai-gateway/universal-api)
>
> All three API formats
> [card] [Messages API](/docs/product/ai-gateway/messages-api)
>
> Anthropic Messages format
> [card] [Chat Completions](/docs/product/ai-gateway/chat-completions)
>
> OpenAI Chat Completions format
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Strict OpenAI Compliance
Source: https://docs.portkey.ai/docs/product/ai-gateway/strict-open-ai-compliance
By default, all the responses sent back from Portkey are compliant with the [OpenAI specification](https://platform.openai.com/docs/api-reference/chat/create).
In some cases, a response from a provider like Perplexity may contain useful fields which do not have a corresponding 1:1 mapping to OpenAI fields.
To get those fields in the response, you can do one of the following:
* Python SDK: Pass this parameter `strict_open_ai_compliance=false` when initializing the portkey client
* Node SDK: Pass this parameter `strictOpenAiCompliance: false` when initializing the portkey client
* HTTP requests: Pass this header `x-portkey-strict-open-ai-compliance: false` with your request
> [!NOTE]
>
> By default strict\_open\_ai\_compliance=false in Portkey Python and Node SDK
> [tab] Python SDK
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@PROVIDER",
> strict_open_ai_compliance=False
> )
> ```
> [tab] Node SDK
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> provider:"@PROVIDER",
> strictOpenAiCompliance: false
> })
> ```
> [tab] cURL
>
> Add the following header to your request
> `x-portkey-strict-open-ai-compliance: false`
> [tab] OpenAI python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> strict_open_ai_compliance=False
> )
> )
> ```
> [tab] OpenAI Node SDK
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY", // defaults to process.env["PORTKEY_API_KEY"],
> strictOpenAiCompliance: false
> })
> });
> ```
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Universal API
Source: https://docs.portkey.ai/docs/product/ai-gateway/universal-api
One API for 200+ LLMs across every major provider. Use OpenAI's Chat Completions, Responses API, or Anthropic's Messages format -- Portkey translates between them all.
> [!NOTE]
>
> Available on all Portkey [plans](https://portkey.ai/pricing).
Portkey's AI Gateway provides a single, unified API for 200+ models from every major provider. Write once in any format, switch providers by changing one parameter.
## Three API Formats, Any Provider
Portkey supports three API formats. Each works with **all providers** — Portkey handles translation automatically.
> [card] [Chat Completions](/docs/product/ai-gateway/chat-completions)
>
> **OpenAI spec** · `POST /v1/chat/completions`
>
> Widest ecosystem compatibility
> [card] [Responses API](/docs/product/ai-gateway/responses-api)
>
> **OpenAI spec** · `POST /v1/responses`
>
> Agentic AI with built-in tool use
> [card] [Messages API](/docs/product/ai-gateway/messages-api)
>
> **Anthropic spec** · `POST /v1/messages`
>
> Native Anthropic format across providers
### Chat Completions — `POST /v1/chat/completions`
OpenAI-compatible format with the widest ecosystem support. [Full guide →](/docs/product/ai-gateway/chat-completions)
```python Portkey Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.chat.completions.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
messages=[{"role": "user", "content": "Hello!"}]
)
print(response.choices[0].message.content)
```
```javascript Portkey Node.js theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const response = await portkey.chat.completions.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
messages: [{ role: "user", content: "Hello!" }]
});
console.log(response.choices[0].message.content);
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1"
)
response = client.chat.completions.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
messages=[{"role": "user", "content": "Hello!"}]
)
print(response.choices[0].message.content)
```
```javascript OpenAI Node.js theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1"
});
const response = await client.chat.completions.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
messages: [{ role: "user", content: "Hello!" }]
});
console.log(response.choices[0].message.content);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
### Responses API — `POST /v1/responses`
OpenAI's next-gen format for agentic AI with built-in tool use and reasoning. [Full guide →](/docs/product/ai-gateway/responses-api)
```python Portkey Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Hello!"
)
print(response.output_text)
```
```javascript Portkey Node.js theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const response = await portkey.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Hello!"
});
console.log(response.output_text);
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1"
)
response = client.responses.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
input="Hello!"
)
print(response.output_text)
```
```javascript OpenAI Node.js theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1"
});
const response = await client.responses.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
input: "Hello!"
});
console.log(response.output_text);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/responses \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"input": "Hello!"
}'
```
### Messages API — `POST /v1/messages`
Anthropic-native format using the Anthropic SDK pointed at Portkey's base URL. [Full guide →](/docs/product/ai-gateway/messages-api)
```python Python theme={"system"}
import anthropic
client = anthropic.Anthropic(
api_key="dummy", # we will use portkey's provider slug
default_headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
base_url="https://api.portkey.ai"
)
message = client.messages.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello!"}]
)
print(message.content[0].text)
```
```typescript TypeScript theme={"system"}
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai"
});
const message = await client.messages.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
max_tokens: 1024,
messages: [{ role: "user", content: "Hello!" }]
});
console.log(message.content[0].text);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic-provider/claude-sonnet-4-5-20250514",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
> [!NOTE]
>
> The Portkey SDK is a superset of the OpenAI SDK. The OpenAI SDK also works directly — point `base_url` at `https://api.portkey.ai/v1`. For the Messages API, use the Anthropic SDK. See [Model Catalog](/docs/product/model-catalog) for provider setup.
## Switching Providers
Change the `@provider/model` string to switch between any provider. The API format stays the same.
```python Portkey Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
# OpenAI
response = portkey.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "Hello"}]
)
# Switch to Anthropic -- same client, different model string
response = portkey.chat.completions.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
messages=[{"role": "user", "content": "Hello"}]
)
# Switch to Gemini
response = portkey.chat.completions.create(
model="@google-provider/gemini-2.0-flash",
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript Portkey Node.js theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
// OpenAI
const response = await portkey.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "Hello" }]
});
// Switch to Anthropic -- same client, different model string
const response2 = await portkey.chat.completions.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
messages: [{ role: "user", content: "Hello" }]
});
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1"
)
# OpenAI
response = client.chat.completions.create(
model="@openai-provider/gpt-4o",
messages=[{"role": "user", "content": "Hello"}]
)
# Switch to Anthropic -- same client, different model string
response = client.chat.completions.create(
model="@anthropic-provider/claude-sonnet-4-5-20250514",
messages=[{"role": "user", "content": "Hello"}]
)
# Switch to Gemini
response = client.chat.completions.create(
model="@google-provider/gemini-2.0-flash",
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript OpenAI Node.js theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1"
});
// OpenAI
const response = await client.chat.completions.create({
model: "@openai-provider/gpt-4o",
messages: [{ role: "user", content: "Hello" }]
});
// Switch to Anthropic -- same client, different model string
const response2 = await client.chat.completions.create({
model: "@anthropic-provider/claude-sonnet-4-5-20250514",
messages: [{ role: "user", content: "Hello" }]
});
```
```sh cURL theme={"system"}
# OpenAI
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{"model": "@openai-provider/gpt-4o", "messages": [{"role": "user", "content": "Hello"}]}'
# Switch to Anthropic -- same endpoint, different model string
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{"model": "@anthropic-provider/claude-sonnet-4-5-20250514", "messages": [{"role": "user", "content": "Hello"}]}'
```
> [!NOTE]
>
> Set up providers and credentials in the [Model Catalog](/docs/product/model-catalog). The `@provider-slug` in the model string routes requests to the correct provider automatically.
## Routing, Fallbacks, and Load Balancing
[Configs](/docs/product/ai-gateway/configs) enable routing strategies, fallbacks, and load balancing across providers.
```python Portkey Python theme={"system"}
from portkey_ai import Portkey
config = {
"strategy": {"mode": "fallback"},
"targets": [
{"override_params": {"model": "@openai-provider/gpt-4o"}},
{"override_params": {"model": "@anthropic-provider/claude-sonnet-4-5-20250514"}}
]
}
portkey = Portkey(api_key="PORTKEY_API_KEY", config=config)
# Automatically falls back to Anthropic if OpenAI fails
response = portkey.chat.completions.create(
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript Portkey Node.js theme={"system"}
import Portkey from 'portkey-ai';
const config = {
strategy: { mode: "fallback" },
targets: [
{ override_params: { model: "@openai-provider/gpt-4o" } },
{ override_params: { model: "@anthropic-provider/claude-sonnet-4-5-20250514" } }
]
};
const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY", config });
// Automatically falls back to Anthropic if OpenAI fails
const response = await portkey.chat.completions.create({
messages: [{ role: "user", content: "Hello" }]
});
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
# Use a saved config ID from Portkey dashboard
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1",
default_headers={"x-portkey-config": "pp-config-xxx"}
)
# Automatically falls back to Anthropic if OpenAI fails
response = client.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript OpenAI Node.js theme={"system"}
import OpenAI from 'openai';
// Use a saved config ID from Portkey dashboard
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1",
defaultHeaders: { "x-portkey-config": "pp-config-xxx" }
});
// Automatically falls back to Anthropic if OpenAI fails
const response = await client.chat.completions.create({
model: "gpt-4o",
messages: [{ role: "user", content: "Hello" }]
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pp-config-xxx" \
-d '{"messages": [{"role": "user", "content": "Hello"}]}'
```
Configs work with all three API formats -- Chat Completions, Responses, and Messages.
For more details, see [Configs](/docs/product/ai-gateway/configs) and [Conditional Routing](/docs/product/ai-gateway/conditional-routing).
## Local and Private Models
Route to local or private models with `custom_host`. The model must be compatible with a supported provider format.
```python Portkey Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="mistral-ai",
custom_host="http://MODEL_URL/v1/"
)
response = portkey.chat.completions.create(
model="mixtral-8x22b",
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript Portkey Node.js theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "mistral-ai",
customHost: "http://MODEL_URL/v1/"
});
const response = await portkey.chat.completions.create({
model: "mixtral-8x22b",
messages: [{ role: "user", content: "Hello" }]
});
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1",
default_headers={
"x-portkey-provider": "mistral-ai",
"x-portkey-custom-host": "http://MODEL_URL/v1/"
}
)
response = client.chat.completions.create(
model="mixtral-8x22b",
messages=[{"role": "user", "content": "Hello"}]
)
```
```javascript OpenAI Node.js theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1",
defaultHeaders: {
"x-portkey-provider": "mistral-ai",
"x-portkey-custom-host": "http://MODEL_URL/v1/"
}
});
const response = await client.chat.completions.create({
model: "mixtral-8x22b",
messages: [{ role: "user", content: "Hello" }]
});
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: mistral-ai" \
-H "x-portkey-custom-host: http://MODEL_URL/v1/" \
-d '{"model": "mixtral-8x22b", "messages": [{"role": "user", "content": "Hello"}]}'
```
> [!NOTE]
>
> Include the version identifier (e.g., `/v1`) in the `custom_host` URL. Portkey appends the endpoint path (`/chat/completions`, `/responses`, etc.) automatically. For Ollama, see the [Ollama integration](/docs/integrations/llms/ollama).
> [!NOTE]
>
> Portkey blocks requests to private and reserved IP ranges by default to prevent SSRF attacks. If you need to route to a private network IP, see [Custom hosts](/docs/product/ai-gateway/custom-hosts) for the full list of blocked patterns and how to allowlist specific hosts.
## Supported Endpoints
### Core Endpoints
* **[Chat Completions](/docs/product/ai-gateway/chat-completions)** — OpenAI-compatible text generation with streaming, function calling, and multimodal inputs
* **[Responses API](/docs/product/ai-gateway/responses-api)** — Next-gen format with built-in tool use and reasoning
* **[Messages API](/docs/product/ai-gateway/messages-api)** — Anthropic-compatible endpoint across all providers
* **[Images](/docs/api-reference/inference-api/images/create-image)** — Generate, edit, and create image variations (DALL-E, gpt-image-1, Stable Diffusion)
* **[Audio](/docs/api-reference/inference-api/audio/create-speech)** — Speech-to-text and text-to-speech
* **[OCR](/docs/api-reference/inference-api/ocr)** — Extract text and structured content from PDFs and images
### Advanced Capabilities
* **[Fine-tuning](/docs/product/ai-gateway/fine-tuning)** — Customize models on specific datasets
* **[Batch Processing](/docs/product/ai-gateway/batches)** — Process large request volumes efficiently
* **[Files](/docs/product/ai-gateway/files)** — Upload and manage files for fine-tuning and batch operations
* **[Moderations](/docs/api-reference/inference-api/moderations)** — Content safety and compliance checks
### Additional Endpoints
* **[Gateway to Other APIs](/docs/api-reference/inference-api/gateway-for-other-apis)** — Proxy requests to any provider endpoint
* **[Assistants API](/docs/api-reference/inference-api/assistants-api/assistants/create-assistant)** — OpenAI Assistants with persistent threads
* **[Completions](/docs/api-reference/inference-api/completions)** — Legacy text completion endpoint
* **[Decisions](/docs/product/ai-gateway/decisions-api)** — Typed judgments (choice, score, probability) via `/v1/decisions`, available through TypeSafe's Jev models, OpenRouter, Workers AI, OpenAI
### Multimodal Capabilities
Multimodal inputs work across all three API formats:
* **[Vision](/docs/product/ai-gateway/multimodal-capabilities/vision)** — Image understanding across providers
* **[Function Calling](/docs/product/ai-gateway/multimodal-capabilities/function-calling)** — Tool use and function calling
* **[Image Generation](/docs/product/ai-gateway/multimodal-capabilities/image-generation)** — Text-to-image generation
* **[Speech-to-Text](/docs/product/ai-gateway/multimodal-capabilities/speech-to-text)** — Audio transcription
* **[Text-to-Speech](/docs/product/ai-gateway/multimodal-capabilities/text-to-speech)** — Audio generation
* **[Thinking / Reasoning](/docs/product/ai-gateway/multimodal-capabilities/thinking-mode)** — Extended reasoning modes
> [!NOTE]
>
> Not all providers support every endpoint or modality. See the [provider compatibility matrix](/docs/api-reference/inference-api/supported-providers) for details.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Virtual Keys
Source: https://docs.portkey.ai/docs/product/ai-gateway/virtual-keys
Virtual Keys have been migrated to Model Catalog - learn about the new system
> [!WARNING]
>
> **Virtual Keys have been migrated to Model Catalog**
>
> The Virtual Keys feature has been upgraded to the **Model Catalog** system, which provides better governance, centralized management, and model-level controls. The core concept remains the same - one Portkey API key gives you access to multiple providers and models.
>
> [Learn more about Model Catalog →](/docs/product/model-catalog)
## What Changed?
The Virtual Keys feature has evolved into the **Model Catalog** system. Here's what you need to know:
### Core Concept (Still the Same)
* ✅ **One Portkey API key** → Access **multiple providers** → Use **hundreds of models**
* ✅ Provider credentials stored securely, never exposed in code
* ✅ Centralized management and governance
### What's New in Model Catalog
* **Organization-level management**: Share credentials across workspaces
* **Better governance**: Fine-grained budgets, rate limits, and model allow-lists
* **Simpler usage**: Just use `model="@provider-slug/model-name"` format
* **Enhanced security**: Improved credential management and access controls
## Migration Guide
If you're currently using Virtual Keys, see our step-by-step migration guide:
> [card] [Migration Guide](/docs/support/upgrade-to-model-catalog)
>
> Step-by-step guide to migrate from Virtual Keys to Model Catalog
## Quick Start with Model Catalog
1. **Add a Provider**: Go to [Model Catalog](https://app.portkey.ai/model-catalog) → Add Provider
2. **Use in Code**: Use the `@provider-slug/model-name` format in your requests
3. **Manage Access**: Set budgets, rate limits, and model access controls
```python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
# Use Model Catalog providers
response = portkey.chat.completions.create(
model="@openai-prod/gpt-4o", # Provider slug + model name
messages=[{"role": "user", "content": "Hello!"}]
)
```
## Related Resources
> [card] [Model Catalog](/docs/product/model-catalog)
>
> Complete guide to Model Catalog features
> [card] [Integrations](/docs/product/model-catalog/integrations)
>
> Managing credentials across workspaces
> [card] [Migration Guide](/docs/support/upgrade-to-model-catalog)
>
> Step-by-step migration from Virtual Keys
> [card] [API Reference](/docs/api-reference/inference-api/config-object)
>
> Config object reference for Model Catalog
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Connect Bedrock with Amazon Assumed Role
Source: https://docs.portkey.ai/docs/product/ai-gateway/virtual-keys/bedrock-amazon-assumed-role
How to create a new integration for Bedrock using Amazon Assumed Role Authentication
> [!NOTE]
>
> Available on all plans.
> [card] [Set Up Bedrock Authentication for Enterprise](https://github.com/Portkey-AI/helm/blob/main/charts/portkey-gateway/docs/Bedrock.md)
>
> On the Enterprise plan and need to connect to Bedrock using an AWS assumed role? Check out the documentation here.
## Select AWS Assumed Role Authentication
Create a new integration on Portkey, select **Bedrock** as the provider and **AWS Assumed Role** as the authentication method.

## Create an AWS Role for Portkey to Assume
This role you create will be used by Portkey to execute InvokeModel commands on Bedrock models in your AWS account. The setup process will establish a minimal-permission ("least privilege") role and set it up to allow Portkey to assume this role.
### Create a permission policy in your AWS account using the following JSON
```json theme={"system"}
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "BedrockConsole",
"Effect": "Allow",
"Action": [
"bedrock:InvokeModel",
"bedrock:InvokeModelWithResponseStream"
],
"Resource": "*"
}
]
}
```

### Create a new IAM role
Choose *AWS account* as the trusted entity type. If you set an external ID be sure to copy it, we will need it later.

### Add the above policy to the role
Search for the policy you created above and add it to the role.

### Configure Trust Relationship for the role
Once the role is created, open the role and navigate to the *Trust relationships* tab and click *Edit trust policy*.
This is where you will add the Portkey AWS account as a trusted entity.
```sh Portkey Account ARN theme={"system"}
arn:aws:iam::299329113195:role/portkey-app
```
> [!NOTE]
>
> The above ARN only works for our [hosted app](https://app.portkey.ai/).\\
>
> To enable **Assumed Role for AWS in your Portkey Enterprise deployment**, you can refer to [this guide](https://github.com/Portkey-AI/helm/blob/main/charts/portkey-gateway/docs/Bedrock.md). If you face any issue, please reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
Paste the following JSON into the trust policy editor and click *Update Trust Policy*.
```json theme={"system"}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"AWS": "arn:aws:iam::299329113195:role/portkey-app"
},
"Action": "sts:AssumeRole",
"Condition": {}
}
]
}
```
If you set an external ID, add it to the condition as shown below.
```json theme={"system"}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"AWS": ""
},
"Action": "sts:AssumeRole",
"Condition": {
"StringEquals": {
"sts:ExternalId": ""
}
}
}
]
}
```
## Configure the integration with the role ARN
Once the role is created, copy the role ARN and paste it into the Bedrock integrations modal in Portkey along with the external ID if you set one and the AWS region you are using.

You're all set! You can now use the providers inherited from your integration to invoke Bedrock models.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Budget Limits
Source: https://docs.portkey.ai/docs/product/ai-gateway/virtual-keys/budget-limits
Budget Limits lets you set cost limits on providers/integrations
Budget Limits lets you set cost or token limits on providers/integrations
> [!NOTE]
>
> Available on **Enterprise** plan and select **Pro** customers.
> [!TIP]
>
> To apply budgets and rate limits at the workspace level (across keys), see [Enforce Workspace Budget and Rate Limits](/docs/product/administration/enforce-workspace-budget-limts-and-rate-limits).
**Budget Limits on Providers** provide a simple way to manage your spending on AI providers (and LLMs) - giving you confidence and control over your application's costs.
Budget Limit is currently only available to **Portkey** [**Enterprise Plan**](https://portkey.ai/docs/product/enterprise-offering) customers. Reach out via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) if you would like to enable it for your org.
## Setting Budget Limits on Providers
When creating a new integration on Portkey, you can set limits in two ways:
### Cost-Based Limits
Set a budget limit in USD that, once reached, will automatically expire the key to prevent further usage and overspending.
### Token-Based Limits
Set a maximum number of tokens that can be consumed, allowing you to control usage independent of cost fluctuations.
And you can set both these limtis for each workspace.
> #### Key Considerations
>
> * Budget limits can be set as either cost-based (USD) or token-based
> * The minimum cost limit you can set is **\$1**
> * The minimum token limit you can set is **100 tokens**
> * Budget limits apply until exhausted or reset
> * Budget limits are applied only to requests made after the limit is set; they do not apply retroactively
> * Once set, budget limits **cannot be edited** by any organization member
> * Budget limit feature is available for **all LLMs** available on Portkey and will apply to **all members/workspaces** who have permission to use it.
## Alert Thresholds
You can now set alert thresholds to receive notifications before your budget limit is reached:
* For cost-based budgets, set thresholds in USD
* For token-based budgets, set thresholds in tokens
* Receive email notifications when usage reaches the threshold
* Continue using the key until the full budget limit is reached
## Periodic Reset Options
You can configure budget limits to automatically reset at regular intervals:

### Reset Period Options
* **No Periodic Reset**: The budget limit applies until exhausted with no automatic renewal
* **Reset Weekly**: Budget limits automatically reset every week
* **Reset Monthly**: Budget limits automatically reset every month
### Reset Timing
* Weekly resets occur at the beginning of each week (Sunday at 12 AM UTC)
* Monthly resets occur on the **1st** calendar day of the month, at **12 AM UTC**, irrespective of when the budget limit was set prior
## Editing Budget Limits
If you need to change or update a budget limit, you can **duplicate** the existing provider and create a new one with the desired limit.
## Monitoring Your Spending and Usage
You can track your spending and token usage for any specific provider by navigating to the Analytics tab and filtering by the **desired provider** and **timeframe**.
## Pricing Support and Limitations
Budget limits currently apply to all providers and models for which Portkey has pricing support. If a specific request log shows `0 cents` in the COST column, it means that Portkey does not currently track pricing for that model, and it will not count towards the providers's budget limit.
For token-based budgets, Portkey tracks both input and output tokens across all supported models.
It's important to note that budget limits cannot be applied retrospectively. The spend counter starts from zero only after you've set a budget limit for a key.
## Availability
Budget Limits is currently available **exclusively to Portkey Enterprise** customers and select Pro users. If you're interested in enabling this feature for your account, please reach out to us via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
## Enterprise Plan
To discuss Portkey Enterprise plan details and pricing, [you can schedule a quick call here](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Rate Limits
Source: https://docs.portkey.ai/docs/product/ai-gateway/virtual-keys/rate-limits
Set Rate Limts to your Integrations/Providers
Rate Limits lets you set request or token consumption limits on providers/integrations
> [!NOTE]
>
> Available on **Enterprise** plan and select **Pro** customers.
\*\*Rate Limits provide a powerful way to control the frequency of API requests or token consumption for your requests - giving you confidence and control over your application's usage patterns and performance.
Rate Limit is currently only available to **Portkey** [**Enterprise Plan**](https://portkey.ai/docs/product/enterprise-offering) customers and select Pro users. Reach out via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) if you would like to enable it for your org.
## Setting Rate Limits on Providers
When creating a new provider on Portkey, you can set rate limits in two ways:
### Request-Based Limits
Set a maximum number of requests that can be made within a specified time period (per minute, hour, or day).
### Token-Based Limits
Set a maximum number of tokens that can be consumed within a specified time period (per minute, hour, or day).

> #### Key Considerations
>
> * Rate limits can be set as either request-based or token-based
> * Time intervals can be configured as per minute, per hour, or per day
> * Setting the limit to 0 disables the provider
> * Rate limits apply immediately after being set
> * Once set, rate limits **cannot be edited** by any organization member
> * Rate limits work for **all providers** available on Portkey and apply to **all organization members** who use the provider
> * After a rate limit is reached, requests will be rejected until the time period resets
## Rate Limit Intervals
You can choose from three different time intervals for your rate limits:
* **Per Minute**: Limits reset every minute, ideal for fine-grained control
* **Per Hour**: Limits reset hourly, providing balanced usage control
* **Per Day**: Limits reset daily, suitable for broader usage patterns
## Exceeding Rate Limits
When a rate limit is reached:
* Subsequent requests are rejected with a specific error code
* Error messages clearly indicate that the rate limit has been exceeded
* The limit automatically resets after the specified time period has elapsed
## Editing Rate Limits
If you need to change or update a rate limit, you can **duplicate** the existing provider and create a new one with the desired limit.
## Monitoring Your Usage
You can track your request and token usage for any specific provider by navigating to the Analytics tab and filtering by the **desired provider** and **timeframe**.
## Use Cases for Rate Limits
* **Cost Control**: Prevent unexpected usage spikes that could lead to high costs
* **Performance Management**: Ensure your application maintains consistent performance
* **Fairness**: Distribute API access fairly across teams or users
* **Security**: Mitigate potential abuse or DoS attacks
* **Provider Compliance**: Stay within the rate limits imposed by underlying AI providers
## Availability
Rate Limits is currently available **exclusively to Portkey Enterprise** customers and select Pro users. If you're interested in enabling this feature for your account, please reach out to us via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
## Enterprise Plan
To discuss Portkey Enterprise plan details and pricing, [you can schedule a quick call here](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Coding Agents
Source: https://docs.portkey.ai/docs/product/coding-agent
The governance layer for Claude Code, Codex, and other AI coding agents — centralized credentials, cost controls, observability, and provider failover for platform teams.
When developers use Claude Code or Codex individually, it works fine. When 100 developers use it — raw API keys get scattered, costs spike overnight without attribution, and there's no fallback when a provider goes down.
Portkey is the gateway that sits between your team's coding agents and LLM providers. **Developers change nothing. You get full control.**
> [card] Secure
>
> Centralize provider credentials. Issue scoped API keys per team. Rotate or revoke access without touching developer configs.
> [card] Control
>
> Set hard budget and rate limits per developer, team, or workspace. Block requests when limits are hit.
> [card] Observe
>
> Log every request — cost, tokens, latency, model, and who made it. Attribute spend by team or project.
***
## Supported agents
> [card] [Claude Code](/docs/integrations/libraries/claude-code)
>
> The most widely deployed AI coding agent. Supports Anthropic direct, Bedrock, and Vertex AI through a single Portkey endpoint.
> [card] [OpenAI Codex](/docs/integrations/libraries/codex)
>
> OpenAI's terminal coding agent. Configure via `config.toml` with full provider flexibility.
> [card] [Cursor](/docs/integrations/libraries/cursor)
>
> Route Cursor's AI requests through Portkey for observability and cost controls.
> [card] [Cline](/docs/integrations/libraries/cline)
>
> Set Portkey as Cline's custom OpenAI base URL.
> [card] [Roo Code](/docs/integrations/libraries/roo-code)
>
> Drop-in Portkey integration via base URL override.
> [card] [Pi Agent](/docs/integrations/libraries/pi-agent)
>
> Minimal extensible terminal coding agent. Route through Portkey via custom provider config.
> [card] [Goose, opencode & more](/docs/integrations/libraries/opencode)
>
> Any OpenAI-compatible coding agent works with Portkey.
***
## What platform teams get
### Access control
Developers never see provider credentials. Every request is authenticated through a scoped Portkey key.
| Goal | What to use | Description |
| - | - | - |
| Centralize credentials | [Model Catalog](/docs/product/model-catalog) | Store Anthropic, Bedrock, and Vertex keys once. Issue scoped Portkey keys to teams — no raw key distribution. |
| Isolate teams | [Workspaces](/docs/product/enterprise-offering/org-management/workspaces) | Each team gets its own workspace with separate budgets, rate limits, and provider access. One team's usage never affects another's. |
| Manage team access | [API Keys](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz) | One key per developer or team. Rotate or revoke from one place without touching developer configs. |
| Provision access at scale | [SSO / SCIM](/docs/product/enterprise-offering/org-management/sso) | Connect your identity provider. Onboard and offboard developers automatically. |
### Cost management
Agentic loops are expensive. One uncapped session can rack up hundreds of dollars overnight.
| Goal | What to use | Description |
| - | - | - |
| Cap team spending | [Budget Policies](/docs/product/enterprise-offering/budget-policies) | Hard spend limits per developer, team, or workspace. Requests block when the limit is hit. |
| Prevent traffic starvation | [Rate Limits](/docs/product/model-catalog/rate-limits) | Stop any single user from consuming shared provider capacity. |
| Attribute costs by team | [Logs + Metadata](/docs/product/observability/metadata) | Every request logged with team, project, model, tokens, and exact cost. Answer spend questions in seconds. |

### Reliability
Coding agents fail silently when providers go down. Portkey routes around outages automatically.
| Goal | What to use | Description |
| - | - | - |
| Survive provider outages | [Fallbacks](/docs/product/ai-gateway/fallbacks) | Auto-retry on Bedrock or Vertex if Anthropic goes down — no developer intervention. |
| Handle team-scale volume | [Load Balancing](/docs/product/ai-gateway/load-balancing) | Distribute traffic across providers and API keys. |
### Governance
Coding agents operate with terminal-level access. Portkey adds the control layer.
| Goal | What to use | Description |
| - | - | - |
| Protect sensitive codebases | [Guardrails](/docs/product/guardrails) | PII detection, prompt injection protection, and content filtering before requests hit the model. |
| Govern MCP tool access | [MCP Gateway](/docs/product/mcp-gateway) | Centralized auth and full call logs for every MCP tool your agents use. |
| Maintain a compliance trail | [Audit Logs](/docs/product/enterprise-offering/audit-logs) | Immutable record of every access, config change, and policy action across the org. |
| Share coding standards | [Agent Skills](/docs/guides/coding-agents/skills) | Version prompt instructions and sync them to every developer's agent with one command. |
***
## Setting up Claude Code and Codex
For Claude Code and Codex, the [Portkey CLI](/docs/guides/coding-agents/agent-cli) sets up gateway routing, MCP servers, and team skills in one command:
```bash theme={"system"}
npx portkey
```
> [card] [Claude Code setup](/docs/integrations/libraries/claude-code)
>
> Anthropic direct, Bedrock, and Vertex AI
> [card] [Codex setup](/docs/integrations/libraries/codex)
>
> Full `config.toml` reference and provider options
***
## Next steps
> [card] [Budget Policies](/docs/product/enterprise-offering/budget-policies)
>
> Hard spend limits per team or developer
> [card] [Model Catalog](/docs/product/model-catalog)
>
> Centralized provider credentials and access controls
> [card] [Configs](/docs/product/ai-gateway/configs)
>
> Fallbacks, load balancing, and routing strategies
> [card] [MCP Gateway](/docs/product/mcp-gateway)
>
> Govern MCP tool access across your agent fleet
> [card] [Observability](/docs/product/observability)
>
> Logs, traces, and cost breakdowns for every session
> [card] [Agent Skills](/docs/guides/coding-agents/skills)
>
> Sync team coding standards to every developer's agent
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# MCP Gateway
Source: https://docs.portkey.ai/docs/product/mcp-gateway
Centralized authentication, access control, and observability for MCP servers.
The MCP Gateway is Portkey's solution for managing access to MCP servers. It acts as a proxy between MCP Clients and MCP servers, handling authentication, access control, and logging.
When connecting to MCP servers directly, each agent needs its own credentials and configuration for every server. With the MCP Gateway, clients authenticate once to Portkey. The Gateway handles credential injection, permission checks, and request logging for all configured servers.
> [card] [Quickstart](/docs/product/mcp-gateway/quickstart)
>
> Add an MCP server and connect an MCP client in 5 minutes.
> [card] [Integrations](/docs/product/mcp-gateway/integrations)
>
> Connect Claude Desktop, Cursor, VS Code, or custom agents.
***
## How It Works

When an AI Agent/MCP Client calls an MCP tool, the request flows through Portkey. The Gateway authenticates the request using the agent's API key (or IdP token), checks whether that user has access to the requested server and tool, then injects the appropriate credentials for the upstream server—OAuth tokens for services like GitHub and Slack, API keys for public servers, or identity headers for internal servers. The request is proxied to the MCP server, and the full request/response is logged.
This gives platform teams complete visibility into MCP usage—who accessed what, when, and with what parameters—while developers get access to tools without managing credentials or requesting permissions for each server.
***
## Capabilities
> [card] [Authentication](/docs/product/mcp-gateway/authentication)
>
> Configure OAuth, API keys, or custom headers per server. Supports external IdPs like Okta and Auth0.
> [card] [Access Control](/docs/product/mcp-gateway/access-control)
>
> Control which workspaces and users can access each server.
> [card] [Tool Provisioning](/docs/product/mcp-gateway/tool-provisioning)
>
> Enable or disable specific tools per user when a server exposes tools that shouldn't be available to everyone.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Every tool call logged with user, parameters, and response. Filter by server, user, or time range.
> [card] [Rate Limits](/docs/product/mcp-gateway/rate-limits)
>
> Throttle MCP tool calls by request count or token consumption per API key, server, or tool.
> [card] [Guardrails](/docs/product/mcp-gateway/guardrails)
>
> Content filters and approval workflows per server.
> [card] [Troubleshooting](/docs/help-center/mcp-gateway-troubleshooting)
>
> Fix common connection, authentication, OAuth, and scope issues.
***
## Usage
Add an MCP server to your organization's registry, configure its authentication, and provision access to workspaces. Then connect any MCP client to Portkey's endpoint:
```json theme={"system"}
{
"mcpServers": {
"portkey": {
"url": "https://mcp.portkey.ai/{server-slug}/mcp",
"headers": {
"Authorization": "Bearer YOUR_API_KEY"
}
}
}
}
```
The API key determines which servers and tools are accessible. See [Integrations](/docs/product/mcp-gateway/integrations) for setup guides for Claude Desktop, Cursor, VS Code, and custom agents.
***
## MCP Registry
The MCP Registry is where MCP servers are configured and managed. Add servers, set up authentication, and control which workspaces can access them.
> [card] [MCP Registry](/docs/product/mcp-gateway/mcp-registry)
>
> Add servers, configure authentication, and manage access.
**For platform teams:**
* Add MCP servers (external services, internal APIs, or public servers)
* Configure authentication (OAuth, API keys, custom headers)
* Provision access to specific workspaces
* View usage across the organization
**For developers:**
* Browse available servers and tools in your workspace
* Copy connection URLs
* Test tools directly from the UI
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Team Provisioning
Source: https://docs.portkey.ai/docs/product/mcp-gateway/access-control
Control which workspaces and users can access MCP servers and their capabilities.
Access control for MCP servers happens at two levels.
## Organization-level (MCP Registry)
> [!NOTE]
>
> Requires **Org Admin** or **Org Owner** role.
Control which workspaces can access an MCP server:
1. Click **MCP Registry** in the sidebar
2. Click on an MCP server
3. Open the **Access Control** tab
4. Toggle workspaces on/off

Enable **Automatically provision this integration for new workspaces** to include future workspaces by default.
## Workspace-level (MCP Servers)
> [!NOTE]
>
> Requires **Workspace Manager** or **Workspace Admin** role.
Control which users in your workspace can access an MCP server:
1. Go to **MCP** page in your workspace sidebar
2. Click on an MCP server
3. Use the **User Access** tab to toggle user access on/off

***
## Next Steps
> [card] [Tool Provisioning](/docs/product/mcp-gateway/tool-provisioning)
>
> Enable or disable specific tools at the organization level.
> [card] [Guardrails](/docs/product/mcp-gateway/guardrails)
>
> Apply rate limits, content filtering, and approval workflows.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# MCP Advanced Configuration
Source: https://docs.portkey.ai/docs/product/mcp-gateway/advanced-configuration
Control how the gateway authenticates, forwards context, and connects to upstream MCP servers.
When you add an MCP server to the registry, the UI handles the basics — server name, URL, auth type, static headers. That's enough for most setups.
Advanced Configuration is the JSON field at the bottom of the integration form.
It unlocks everything the UI fields don't cover:
* **Forward runtime headers** like trace IDs or tenant context to the upstream server
* **Tell the MCP server who's calling** by forwarding authenticated user identity
* **Validate tokens at the edge** before requests ever reach the upstream server
* **Customize OAuth behavior** when the upstream server's defaults don't work
* **Bring your own auth** with an external identity provider for enterprise SSO

***
## What You Can Configure
| Key | What it does | When you need it |
| - | - | - |
| [`forward_headers`](#forward-headers) | Pass client request headers to the upstream server | Distributed tracing, tenant context, custom metadata |
| [`oauth_metadata`](#oauth-metadata) | Override OAuth discovery defaults | Upstream server needs non-standard OAuth config |
| [`user_identity_forwarding`](#user-identity-forwarding) | Tell the upstream server *who* is making the request | Per-user authorization, audit logging, personalization |
| [`jwt_validation`](#jwt-validation) | Validate client JWTs at the gateway edge | Bring-your-own IdP, enforce auth before proxying |
| [`external_auth_config`](#external-auth-config) | Use an external OAuth provider instead of Portkey's | Enterprise SSO with your own IdP |
***
## Forward Headers
Forward specific headers from the incoming client request to the upstream MCP server. Unlike static headers, these are dynamic — they capture whatever the client sends at runtime.
Two modes: **allowlist** (only forward listed headers) and **all-except** (forward everything except listed headers).
```json theme={"system"}
{
"forward_headers": ["X-Request-Id", "X-Trace-Id", "X-Tenant-Id"]
}
```
Forwarded headers have the **lowest priority** — they never override auth headers or static values you've configured.
> [card] [Forwarding Headers](/docs/product/mcp-gateway/authentication/forwarding-headers)
>
> Allowlist vs all-except modes, priority rules, and full configuration options.
***
## OAuth Metadata
Override the OAuth endpoints and parameters that Portkey discovers from the upstream server's `/.well-known/oauth-authorization-server`. Only relevant when Auth Type is **OAuth 2.1**.
```json theme={"system"}
{
"oauth_metadata": {
"authorization_endpoint": "https://auth.example.com/authorize",
"token_endpoint": "https://auth.example.com/token",
"scopes_supported": ["read", "write", "admin"]
}
}
```
All fields are optional. Provided values override auto-discovered defaults.
> [card] [OAuth Client Metadata](/docs/product/mcp-gateway/authentication/oauth-client-metadata)
>
> Full list of overridable OAuth fields and registration customization.
***
## User Identity Forwarding
After authenticating a user, Portkey can forward their identity to the upstream MCP server. The server gets to know *who* is making the request — without implementing its own auth.
Three methods:
| Method | What the upstream server receives |
| - | - |
| `claims_header` | JSON object with user claims in `X-User-Claims` header |
| `bearer` | Original OAuth access token in `Authorization` header |
| `jwt_header` | Portkey-signed JWT with claims in `X-User-JWT` header |
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "workspace_id"]
}
}
```
> [card] [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding)
>
> Method comparison, claim selection, custom headers, and JWT verification.
***
## JWT Validation
Validate incoming client JWTs **before** proxying to the upstream server. The gateway rejects invalid tokens at the edge — the upstream server never sees them.
Supports three validation methods: **JWKS URI**, **inline JWKS keys**, and **token introspection** (RFC 7662). You can also enforce required claims and match claim values.
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://auth.example.com/.well-known/jwks.json",
"algorithms": ["RS256"],
"requiredClaims": ["sub", "email"]
}
}
```
> [card] [JWT Validation](/docs/product/mcp-gateway/authentication/jwt)
>
> JWKS, introspection, claim matching (exact, contains, regex), and full options reference.
***
## External Auth Config
> [!NOTE]
>
> Enterprise only — available for self-hosted deployments.
Use an external identity provider (Okta, Auth0, Azure AD, Cognito) instead of Portkey's built-in OAuth. Users authenticate with corporate credentials.
```json theme={"system"}
{
"external_auth_config": {
"authorization_endpoint": "https://idp.example.com/authorize",
"token_endpoint": "https://idp.example.com/token",
"scope": "openid profile mcp"
}
}
```
Supports both dynamic client registration and pre-registered client credentials.
> [card] [Bring Your Own Auth](/docs/product/mcp-gateway/authentication/external-oauth)
>
> Full setup for external OAuth providers, dynamic registration, and pre-registered credentials.
***
## Combining Options
You can combine multiple keys in a single configuration:
```json theme={"system"}
{
"forward_headers": ["X-Request-Id", "X-Trace-Id"],
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "workspace_id"]
},
"jwt_validation": {
"jwksUri": "https://auth.example.com/.well-known/jwks.json",
"requiredClaims": ["sub"],
"claimValues": {
"iss": {
"values": "https://auth.example.com",
"matchType": "exact"
}
}
}
}
```
This validates the client JWT, forwards trace headers, and sends user identity to the upstream — all in one integration.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Authentication
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication
How authentication works in MCP Gateway.
MCP Gateway handles authentication at two independent layers. Understanding this separation is key to configuring secure access.
## Two-Layer Architecture
```mermaid theme={"system"}
flowchart TB
Agent[Your Agent / Client]
Gateway[Portkey MCP Gateway]
Server[MCP Server]
Agent -- "API Key / OAuth / External IdP" --> Gateway
Gateway -- "OAuth Auto / Client Credentials / Headers" --> Server
```
| Layer | Who authenticates | Methods |
| - | - | - |
| **Gateway Auth** | Agent → Portkey | API Key, Portkey OAuth, External IdP |
| **Server Auth** | Portkey → MCP Server | OAuth Auto, Client Credentials, Headers |
These layers are independent. An agent authenticates to Portkey with an API key. Portkey authenticates to Linear with OAuth. The agent never sees Linear's OAuth tokens.
***
## Gateway Authentication
Agents prove their identity to Portkey before accessing MCP servers.
> [!NOTE]
>
> **How it works:** Requests with an API key use API key auth. Requests with a JWT from an external IdP (with JWT validation configured) use JWT validation. Requests with neither trigger the OAuth flow. No configuration needed—just include an API key or don't.
### API Key
The simplest method. Create an API key in Portkey and include it in requests.
```json theme={"system"}
{
"headers": {
"x-portkey-api-key": "your_api_key_here"
}
}
```
API keys are scoped to workspaces. The key determines which MCP servers the request can access.
Create keys in **Settings > API Keys**. The key must have **`mcp invoke`** permissions.
### OAuth 2.1
For browser-based flows where users authenticate interactively. If no API key is provided, Portkey acts as the OAuth provider and initiates the consent flow. After authentication, your app receives a token to use for MCP requests.
This is useful for:
* End-user applications where users log in
* Interactive tools like Claude Desktop or Cursor (when not using API keys)
* User-level attribution without managing API keys
See [OAuth](/docs/product/mcp-gateway/authentication/oauth) for details.
### External IdP (Bring Your Own Identity)
Use existing identity providers (Okta, Auth0, Azure AD, Cognito). Configure Portkey to validate tokens from your IdP. Users authenticate with existing identity systems—no Portkey accounts needed.
This is useful when:
* You have an existing IdP and want SSO
* Users who aren't in Portkey need MCP access
* Compliance requires your own identity infrastructure
See [External OAuth](/docs/product/mcp-gateway/authentication/external-oauth) for setup.
***
## MCP Server Authentication
Portkey needs credentials to access upstream MCP servers. Configure this when adding a server.
### OAuth Auto
For MCP servers that support OAuth 2.1 with dynamic client registration. Portkey handles the full OAuth flow automatically.
When a user first calls a tool, Portkey initiates OAuth with the MCP server. The user completes consent (e.g., authorizing access to their Linear account). Portkey stores and refreshes tokens automatically.
Each user gets their own OAuth tokens. User A's Linear access is separate from User B's.
Customize the OAuth client metadata Portkey uses during registration. See [OAuth Client Metadata](/docs/product/mcp-gateway/authentication/oauth-client-metadata).
### Client Credentials
For MCP servers using OAuth client credentials grant. You provide a client ID, client secret, and token endpoint when adding the server, and optionally a scope. Portkey fetches tokens and handles refresh.
The token endpoint must use HTTPS and cannot point to a private or reserved network address. Portkey requests only the scope you configure, and sends your server's custom and forwarded headers to the MCP server only, never to the token endpoint. If the client ID or token endpoint is missing, requests to the server fail instead of falling back to static headers.
All users share the same credentials to the MCP server. Use this for shared resources, not personal data.
See [Client Credentials (M2M)](/docs/product/mcp-gateway/authentication/client-credentials) for setup.
### Custom Headers
For MCP servers using API keys or static tokens. Add headers when configuring the server.
```json theme={"system"}
{
"headers": {
"x-portkey-api-key": "api_key_xxx",
"X-API-Key": "your_key"
}
}
```
Portkey includes these headers with every request. All users share the same credentials.
See [Custom Auth](/docs/product/mcp-gateway/authentication/custom-auth) for details.
***
## Data Flow: Headers and Identity
Beyond authentication, Portkey supports passing contextual information to MCP servers:
### Identity Forwarding
After authenticating a user, Portkey can forward their identity claims to MCP servers. MCP servers can then make authorization decisions without implementing OAuth themselves.
Three methods:
* **Claims Header**: JSON object with user claims
* **Bearer Passthrough**: Forward the original token
* **Signed JWT**: Portkey-signed JWT with claims (cryptographically verifiable)
See [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding).
### Header Forwarding
Forward headers from agent requests to MCP servers for distributed tracing, tenant context, or custom metadata.
```json theme={"system"}
{
"forward_headers": ["x-request-id", "x-trace-id", "x-tenant-id"]
}
```
See [Forwarding Headers](/docs/product/mcp-gateway/authentication/forwarding-headers).
***
## Choosing the Right Method
| Scenario | Gateway Auth | MCP Server Auth |
| - | - | - |
| Internal developers using Portkey | API Key | OAuth Auto (per-user) |
| End customers with your IdP | External OAuth | OAuth Auto (per-user) |
| Service-to-service access | API Key | Client Credentials or Headers |
| Shared read-only resources | API Key | Custom Headers |
**Use per-user OAuth** when the MCP server accesses user-specific data (email, repos, messages). Each user authorizes their own access.
**Use shared credentials** when the MCP server provides shared resources (knowledge bases, analytics). All users see the same data.
***
## Credential Isolation
Credentials never cross boundaries.
```
Agent knows: Portkey API key
Portkey knows: MCP server OAuth tokens, API keys, user identity claims
MCP Server knows: Its own credentials
```
Agents can't see MCP server credentials. Compromised agent tokens don't expose upstream access. Rotate MCP server credentials without updating agents.
***
## Quick Reference
| Topic | Description |
| - | - |
| [OAuth](/docs/product/mcp-gateway/authentication/oauth) | Portkey's built-in OAuth 2.1 authentication |
| [External OAuth](/docs/product/mcp-gateway/authentication/external-oauth) | Use your own identity provider |
| [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) | Validate JWTs from external IdPs |
| [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) | Pass user identity to MCP servers |
| [Forwarding Headers](/docs/product/mcp-gateway/authentication/forwarding-headers) | Pass headers from agents to MCP servers |
| [OAuth Client Metadata](/docs/product/mcp-gateway/authentication/oauth-client-metadata) | Customize OAuth registration |
| [Client Credentials (M2M)](/docs/product/mcp-gateway/authentication/client-credentials) | Machine-to-machine OAuth to MCP servers |
| [Custom Auth](/docs/product/mcp-gateway/authentication/custom-auth) | Configure custom headers for MCP servers |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Client Credentials (M2M)
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/client-credentials
Connect Portkey to MCP servers that use machine-to-machine OAuth, with no user sign-in.
Some MCP servers don't identify individual users. They trust a **service identity** instead: a client ID and secret issued by an identity provider (IdP), exchanged for a short-lived access token. This is the OAuth 2.0 **client credentials** grant, also called machine-to-machine (M2M) auth.
Configure it once on the MCP integration. Portkey requests tokens, caches them, refreshes them before they expire, and sends them to the MCP server. Agents never see the credentials.
```mermaid theme={"system"}
sequenceDiagram
participant Agent as Agent / Client
participant PK as Portkey MCP Gateway
participant IdP as Your IdP (token endpoint)
participant MCP as MCP Server
Agent->>PK: MCP request + Portkey API key
PK->>IdP: grant_type=client_credentials (client ID + secret)
IdP->>PK: Access token (expires_in)
PK->>MCP: MCP request + Authorization: Bearer token
MCP->>PK: Response
PK->>Agent: Response
Note over PK: Token cached and reused until shortly before expiry
```
***
## When to Use
Use client credentials when:
* The MCP server sits behind your own IdP (Keycloak, Microsoft Entra ID, Amazon Cognito, and similar) and accepts service tokens
* Access is to shared resources (knowledge bases, internal APIs, analytics) rather than personal data
* No user should be prompted to sign in to the MCP server
Use [OAuth 2.1](/docs/product/mcp-gateway/authentication/oauth) instead when each user needs their own access to the server, such as their email or repositories.
| | Client Credentials | OAuth 2.1 (per user) |
| - | - | - |
| **Who the MCP server sees** | One service identity | Each user |
| **User sign-in to the MCP server** | None | Required once per user |
| **Token** | One per server, per workspace | One per user |
| **Best for** | Shared resources, service-to-service | Personal data, per-user attribution |
> [!NOTE]
>
> Agents still authenticate to Portkey separately, with an API key or another [gateway auth method](/docs/product/mcp-gateway/authentication). Client credentials only covers the second hop, Portkey to the MCP server.
***
## Prerequisites
Set these up at your IdP first:
1. **A confidential client** that can use the client credentials grant, with a client ID and client secret
2. **A scope** the client may request (most IdPs require one). Portkey sends only the scope you configure
3. **The token endpoint URL.** It must use **HTTPS** and be reachable from the gateway
4. **An MCP server** that accepts access tokens from this IdP
Verify the client works before configuring Portkey:
```sh theme={"system"}
curl -s -u "$CLIENT_ID:$CLIENT_SECRET" \
-d grant_type=client_credentials \
-d scope="$SCOPE" \
"$TOKEN_ENDPOINT"
```
The response contains an `access_token` and `expires_in`. If this call fails, Portkey's request fails the same way.
### Where to find the token endpoint
| IdP | Token endpoint | Scope format |
| - | - | - |
| Okta | `https:///oauth2//v1/token` (`default` for the default server) | A custom scope you create on the authorization server, such as `mcp.read` |
| Keycloak | `https:///realms//protocol/openid-connect/token` | A client scope assigned to the client, such as `mcp.read` |
| Microsoft Entra ID | `https://login.microsoftonline.com//oauth2/v2.0/token` | `api:///.default` |
| Amazon Cognito | `https://.auth..amazoncognito.com/oauth2/token` | `/` |
For Okta, create an **API Services** app, add a custom scope to the authorization server, and add an access policy rule that allows the **Client Credentials** grant for that app.
> [!NOTE]
>
> Not every IdP and plan offers the client credentials grant. Okta, for example, offers it only to orgs with an NHI Authentication Token subscription purchased or renewed on or after August 14, 2026. If the token request fails with a message about a missing entitlement, check your IdP plan before debugging Portkey.
***
## Configure in the UI

**1. Add the server**
Go to **MCP Registry** and click **Add Server**. Enter the server's name, URL, and transport.
**2. Select the auth type**
Under **Authentication**, choose **OAuth Client Credentials**.
**3. Enter the credentials**
| Field | Value |
| - | - |
| **Token Endpoint** | The IdP's token URL. Must start with `https://` |
| **Client ID** | The client's ID |
| **Client Secret** | The client's secret |
| **Scope** | Optional. Space-separated scopes to request, such as `mcp.read mcp.write` |
**4. Provision and create**
Click **Next Step**, choose the workspaces that get access, and create the server.
Token Endpoint and Client ID are required. Client Secret is needed for most IdPs. Scope is optional: when empty, Portkey sends no scope and the IdP applies the client's defaults.
### Store credentials in a secret reference
Each field has a **Direct / Secret Ref** toggle. Switch a field to **Secret Ref** to read its value from your vault instead of storing it in Portkey. Store the client secret there at minimum.
See [Secret References](/docs/product/enterprise-offering/secret-references) to connect a vault.
> [!WARNING]
>
> Fields set to a secret reference aren't stored as direct values. If a field already had a direct value, switching to a secret reference and saving replaces it.
***
## Configure with the API
Create the integration with `auth_type` set to `oauth_client_credentials` and the credentials under `configurations.oauth_client_credentials`:
```sh cURL theme={"system"}
curl -X POST https://api.portkey.ai/v1/mcp-integrations \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"name": "Internal Knowledge Base",
"slug": "internal-kb",
"url": "https://mcp.example.com/mcp",
"transport": "http",
"auth_type": "oauth_client_credentials",
"configurations": {
"oauth_client_credentials": {
"token_endpoint": "https://auth.example.com/oauth2/token",
"client_id": "portkey-mcp-client",
"client_secret": "",
"scope": "mcp.read"
}
}
}'
```
```python Python theme={"system"}
import requests
resp = requests.post(
"https://api.portkey.ai/v1/mcp-integrations",
headers={"x-portkey-api-key": PORTKEY_API_KEY},
json={
"name": "Internal Knowledge Base",
"slug": "internal-kb",
"url": "https://mcp.example.com/mcp",
"transport": "http",
"auth_type": "oauth_client_credentials",
"configurations": {
"oauth_client_credentials": {
"token_endpoint": "https://auth.example.com/oauth2/token",
"client_id": "portkey-mcp-client",
"client_secret": CLIENT_SECRET,
"scope": "mcp.read"
}
}
}
)
```
```js JavaScript theme={"system"}
const resp = await fetch("https://api.portkey.ai/v1/mcp-integrations", {
method: "POST",
headers: {
"x-portkey-api-key": PORTKEY_API_KEY,
"Content-Type": "application/json"
},
body: JSON.stringify({
name: "Internal Knowledge Base",
slug: "internal-kb",
url: "https://mcp.example.com/mcp",
transport: "http",
auth_type: "oauth_client_credentials",
configurations: {
oauth_client_credentials: {
token_endpoint: "https://auth.example.com/oauth2/token",
client_id: "portkey-mcp-client",
client_secret: CLIENT_SECRET,
scope: "mcp.read"
}
}
})
})
```
### Configuration fields
All fields live under `configurations.oauth_client_credentials`.
| Field | Required | Description |
| - | - | - |
| `token_endpoint` | Yes | IdP token URL. Must be HTTPS |
| `client_id` | Yes | OAuth client ID |
| `client_secret` | Usually | OAuth client secret. Omit only for IdPs that don't require one |
| `scope` | No | Space-separated scopes to request. Nothing is sent when omitted |
| `token_endpoint_auth_methods_supported` | No | API only. How the secret is sent, such as `["client_secret_post"]`. Default is HTTP Basic |
| `issuer` | No | API only. Rarely needed. Defaults to the token endpoint's origin |
### Reference the secret from a vault
Map the secret with `secret_mappings` instead of sending `client_secret`:
```json theme={"system"}
{
"auth_type": "oauth_client_credentials",
"configurations": {
"oauth_client_credentials": {
"token_endpoint": "https://auth.example.com/oauth2/token",
"client_id": "portkey-mcp-client",
"scope": "mcp.read"
}
},
"secret_mappings": [{
"target_field": "configurations.oauth_client_credentials.client_secret",
"secret_reference_id": "my-mcp-client-secret"
}]
}
```
***
## How It Works
**Token requests.** Portkey sends a `POST` to the token endpoint with `grant_type=client_credentials`, plus `scope` when configured. The client ID and secret are sent with HTTP Basic authentication.
**Caching.** Portkey keeps one token per server per workspace and shares it across all users and gateway instances. It doesn't request a new token for every call.
**Refresh.** A token is replaced shortly before it expires, up to 60 seconds early (less for very short-lived tokens). If the IdP doesn't return `expires_in`, Portkey assumes one hour. If the MCP server answers `401`, Portkey requests a new token and retries once.
**Config changes.** Changing the credentials, scope, or endpoint takes effect without a restart, and Portkey requests a new token with the new values. See [Configuration changes aren't taking effect](/docs/help-center/mcp-gateway-troubleshooting#configuration-changes-aren-t-taking-effect) if a change seems stuck.
### What Portkey sends where
| Request | Goes to | Contains |
| - | - | - |
| Token request | IdP token endpoint | Client credentials and the standard OAuth headers only |
| MCP request | MCP server | `Authorization: Bearer `, plus your [custom headers](/docs/product/mcp-gateway/authentication/custom-auth), [forwarded headers](/docs/product/mcp-gateway/authentication/forwarding-headers), and [identity headers](/docs/product/mcp-gateway/authentication/identity-forwarding) |
Static, forwarded, and identity headers never reach the IdP.
***
## Security
* **HTTPS only.** Token endpoints that don't use HTTPS are rejected, since the secret is sent with every token request.
* **No private addresses.** Token endpoints that resolve to private or reserved network addresses are blocked. On self-hosted and hybrid gateways, allow an internal IdP by adding its host to `TRUSTED_CUSTOM_HOSTS`. See [Custom Hosts](/docs/product/ai-gateway/custom-hosts#trusted-custom-hosts-allowlist).
* **No silent fallback.** If the client ID or a valid token endpoint is missing, requests to the server fail. Portkey doesn't fall back to static headers.
* **Credential isolation.** Agents see only their Portkey credentials, never the client secret or access token.
* **Shared identity.** Every user of the server acts as the same service identity at the MCP server. Don't use it for per-user permissions or attribution. Use [OAuth 2.1](/docs/product/mcp-gateway/authentication/oauth) for those.
> [!WARNING]
>
> Client secrets are stored by Portkey unless you use a secret reference. Use a secret reference and rotate the secret at your IdP on a schedule.
***
## Rotate the Secret
1. Create a new secret for the client at your IdP. Keep the old one active
2. Update **Client Secret** in the integration (or the vault entry it references)
3. Wait for the change to propagate, then confirm requests to the MCP server succeed
4. Revoke the old secret
Portkey requests a new token with the new secret. Secret values read from a vault are cached for up to 5 minutes, so the old secret can still be in use until then. Revoking it earlier can make token renewal fail. No agent changes are needed.
***
## Limitations
Portkey sends only `grant_type` and `scope` on the token request.
* **No extra token parameters.** IdPs that require one, such as an `audience` or `resource` parameter, aren't supported yet. Auth0, for example, typically expects an audience
* **Client secret authentication only.** `private_key_jwt` and mutual TLS aren't supported
* **Scopes come from configuration.** A scope named in the MCP server's `WWW-Authenticate` challenge doesn't change the request
* **One identity per server.** The same credentials apply to every user and workspace that uses the integration
***
## Troubleshooting
The MCP client usually shows only a generic connection error. Look for the cause in your IdP's logs, where a failed token request appears.
| Symptom | Likely cause | Fix |
| - | - | - |
| IdP logs a failed client authentication, or returns `invalid_client` | Wrong client ID or secret, or the client isn't confidential | Re-check the values with the `curl` call from [Prerequisites](#prerequisites) |
| `invalid_scope` | The scope isn't allowed for this client | Assign the scope to the client at the IdP, or fix the **Scope** field |
| `unsupported_grant_type`, or `invalid_grant` with an entitlement message (Okta: "The NHI Authentication Tokens SKU is not enabled") | The IdP or plan doesn't allow client credentials | Enable the grant for the client, or check your IdP plan |
| IdP requires `audience` or another parameter | See [Limitations](#limitations) | Use an IdP configuration that doesn't require it |
| Saving is refused: "Token Endpoint must use https" | The endpoint starts with `http://` | Use the HTTPS URL |
| Requests fail right after saving | Token endpoint is missing, not HTTPS, or points to a private address | Fix the endpoint. For an internal IdP on a self-hosted gateway, add it to `TRUSTED_CUSTOM_HOSTS` |
| Token request succeeds, MCP server answers `401` | The server rejects the token: wrong issuer or audience, or a missing scope | Align the MCP server's validation with the IdP's token |
| Works for a while, then fails | Secret was rotated or revoked at the IdP | Update the secret in the integration |
***
## Related
| Topic | Description |
| - | - |
| [Authentication Overview](/docs/product/mcp-gateway/authentication) | How gateway and server authentication fit together |
| [OAuth 2.1](/docs/product/mcp-gateway/authentication/oauth) | Per-user authentication to MCP servers |
| [Custom Auth](/docs/product/mcp-gateway/authentication/custom-auth) | Static headers and API keys |
| [Secret References](/docs/product/enterprise-offering/secret-references) | Keep credentials in your own vault |
| [MCP Gateway Troubleshooting](/docs/help-center/mcp-gateway-troubleshooting) | Fix common connection problems |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Custom Auth
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/custom-auth
Configure custom authentication for MCP servers.
For MCP servers that don't use standard OAuth, configure custom authentication with headers. Use this for API key-based services, internal servers with static tokens, or any server expecting specific headers.
## When to Use
Custom auth is for MCP servers where:
* Authentication uses API keys instead of OAuth
* Internal servers use static tokens
* The server expects specific headers for authorization
* You want shared credentials (all users use the same authentication)
***
## Static Headers
Configure headers that Portkey includes with every request to the MCP server.
```json theme={"system"}
{
"headers": {
"Authorization": "Bearer your_api_key",
"X-API-Key": "your_key"
}
}
```
All requests to this MCP server include these headers. All users share the same credentials.
### Common Patterns
**Bearer token:**
```json theme={"system"}
{
"headers": {
"Authorization": "Bearer sk_live_xxx"
}
}
```
**API key header:**
```json theme={"system"}
{
"headers": {
"X-API-Key": "your_api_key"
}
}
```
**Basic authentication:**
```json theme={"system"}
{
"headers": {
"Authorization": "Basic dXNlcm5hbWU6cGFzc3dvcmQ="
}
}
```
**Multiple headers:**
```json theme={"system"}
{
"headers": {
"Authorization": "Bearer api_key",
"X-Custom-Auth": "additional_token"
}
}
```
***
## Passthrough Headers
Add static metadata headers separate from authentication:
```json theme={"system"}
{
"passthrough_headers": {
"X-API-Version": "2024-01",
"X-Client": "portkey-gateway"
}
}
```
These are included alongside auth headers. Use for:
* API versioning
* Client identification
* Metadata the server expects
***
## Header Merge Order
When multiple header sources are configured, they merge in this order (later values override earlier):
| Priority | Source | Description |
| - | - | - |
| 1 (lowest) | Forwarded headers | Headers from agent requests (via `forward_headers`) |
| 2 | Auth headers | `headers` configured on the MCP server |
| 3 | Passthrough headers | `passthrough_headers` configured on the server |
| 4 (highest) | Identity headers | Headers from identity forwarding |
**What this means:**
* Auth headers override anything forwarded from agents
* Passthrough headers override auth headers if there's a conflict
* Identity headers always win (prevents spoofing)
**Example conflict:**
```
Agent sends: X-Custom: agent-value
Server auth headers: X-Custom: auth-value
```
Result: MCP server receives `X-Custom: auth-value` (auth headers take precedence).
***
## Combining with Forwarded Headers
Combine static headers with [forwarded headers](/docs/product/mcp-gateway/authentication/forwarding-headers):
```json theme={"system"}
{
"headers": {
"Authorization": "Bearer api_key_xxx"
},
"passthrough_headers": {
"X-API-Version": "v2"
},
"forward_headers": ["x-request-id", "x-trace-id"]
}
```
Every request to the MCP server includes:
* `Authorization: Bearer api_key_xxx` (authentication)
* `X-API-Version: v2` (static metadata)
* `x-request-id` and `x-trace-id` (from agent, if provided)
This is useful for:
* Shared authentication to the MCP server
* Distributed tracing from agents
* Consistent API versioning
***
## Complete Configuration Example
Full server configuration combining all header features:
```json theme={"system"}
{
"mcp_integration_details": {
"transport": "http",
"auth_type": "custom",
"configurations": {
"headers": {
"Authorization": "Bearer sk_live_xxx"
},
"passthrough_headers": {
"X-API-Version": "2024-01",
"X-Client-ID": "portkey-mcp-gateway"
},
"forward_headers": ["x-request-id", "x-correlation-id", "x-tenant-id"],
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "workspace_id"]
}
}
}
}
```
**Result for each request:**
| Header | Source | Value |
| - | - | - |
| `Authorization` | Auth headers | `Bearer sk_live_xxx` |
| `X-API-Version` | Passthrough | `2024-01` |
| `X-Client-ID` | Passthrough | `portkey-mcp-gateway` |
| `x-request-id` | Forwarded | From agent request |
| `x-correlation-id` | Forwarded | From agent request |
| `x-tenant-id` | Forwarded | From agent request |
| `X-User-Claims` | Identity | JSON with user claims |
***
## When to Use Shared Credentials
Shared credentials make sense when:
* The MCP server provides shared resources (knowledge bases, analytics)
* All users should see the same data
* You don't need per-user attribution at the MCP server level
* The external service doesn't support per-user OAuth
Shared credentials **don't** make sense when:
* Users access personal data (email, messages, private repos)
* Actions need attribution to individual users
* The MCP server enforces per-user permissions
For per-user access, use OAuth Auto. Each user authorizes their own access, and Portkey manages tokens per user.
***
## Security Considerations
### Credential Storage
Headers configured in the MCP Registry are stored encrypted. They're never exposed to agents or included in logs.
### Credential Isolation
```
Agent knows: Portkey API key only
Portkey knows: MCP server auth headers
MCP Server knows: Its own credentials
```
Agents never see the MCP server's authentication credentials. If an agent's Portkey API key is compromised, the attacker still can't access the raw MCP server credentials.
### Rotation
To rotate MCP server credentials:
1. Generate new credentials with the MCP server
2. Update the headers in Portkey's MCP Registry
3. Old credentials can be revoked immediately
No agent configuration changes required.
***
## Related
| Topic | Description |
| - | - |
| [Forwarding Headers](/docs/product/mcp-gateway/authentication/forwarding-headers) | Pass headers from agents to MCP servers |
| [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) | Pass user identity to MCP servers |
| [Authentication Overview](/docs/product/mcp-gateway/authentication) | Understanding gateway authentication |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Bring Your Own Auth
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/external-oauth
Use your own identity provider for gateway authentication.
External OAuth enables using your existing identity provider (Okta, Auth0, Azure AD, Descope, Cognito) instead of Portkey's built-in authentication. Users authenticate with corporate credentials—no Portkey accounts needed.
## When to Use
Organizations with existing IdPs can use External OAuth. Users authenticate through the IdP for other services, and MCP access works the same way.
Common scenarios:
* **SSO for internal developers.** Engineers use corporate credentials to access MCP servers
* **B2B applications.** Your customers authenticate through their own IdP
* **Compliance requirements.** Mandate use of your own identity infrastructure
* **No Portkey accounts.** Users who aren't in Portkey need MCP access
***
## How It Works
```
1. The request authenticates to the Portkey gateway
(Portkey API key, or a JWT carrying Portkey org claims)
2. User authenticates with your IdP and obtains a token (JWT or opaque)
3. User includes that token in the MCP request to Portkey
4. Portkey validates the token against your IdP (JWKS or introspection)
5. Request proceeds with the user identity attached
```
Step 1 establishes your organization context; the `jwt_validation` in step 4 is a per-server check layered on top of it. Portkey never handles user credentials—your IdP remains the source of truth for identity.
***
## Configuration
Configure JWT validation for your MCP server. Portkey validates incoming tokens using your IdP's public keys or introspection endpoint.
### Option 1: JWKS URI (Recommended)
The most common setup. Portkey fetches public keys from your IdP's JWKS endpoint.
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"algorithms": ["RS256"],
"requiredClaims": ["sub", "email"]
}
}
```
**How it works:**
* Portkey fetches and caches your IdP's public keys
* Keys are cached for 24 hours by default
* If a key rotates, Portkey automatically refetches
* Validation happens locally (no network call per request)
### Option 2: Token Introspection
For opaque tokens requiring real-time validation, or for immediate revocation.
```json theme={"system"}
{
"jwt_validation": {
"introspectEndpoint": "https://your-idp.com/oauth/introspect",
"introspectContentType": "application/x-www-form-urlencoded",
"introspectClientId": "",
"introspectClientSecret": "",
"headerKey": "X-Auth-Token",
"introspectCacheMaxAge": 0
}
}
```
**How it works:**
* The request authenticates to the gateway first (Portkey API key or org-claim JWT); introspection runs **after** that step.
* Portkey reads the end-user's opaque token from the header named by `headerKey` (default: `Authorization`). Use a dedicated header such as `X-Auth-Token` so it doesn't collide with the gateway credential.
* Portkey POSTs to your `introspectEndpoint` per [RFC 7662](https://datatracker.ietf.org/doc/html/rfc7662): the token in the request body as `token=…`, and—when `introspectClientId`/`introspectClientSecret` are set—an `Authorization: Basic base64(client_id:client_secret)` header to identify Portkey to your endpoint.
* Your endpoint must return `{ "active": true, ... }`. Include a `sub` claim so the user is attributed correctly in logs and analytics.
* Responses are cached for `introspectCacheMaxAge` seconds (default: `0`, no caching).
**Caching tradeoff:**
* `0` (no cache): Every request calls the introspection endpoint (slower, but immediate revocation)
* `> 0`: Better performance, but revocation takes up to the cache TTL to take effect
> [!NOTE]
>
> Token introspection validates the **end-user's** token; it does **not** authenticate the gateway. You still need a Portkey API key or an org-claim JWT on the request (see the callout at the top of this page). An opaque token on its own is not sufficient.
See [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) for full configuration options.
***
## Client Configuration
Every request needs a **gateway credential** (a Portkey API key or an org-claim JWT) so Portkey can resolve your organization. When you use token introspection, the **end-user token** goes in a separate header—the one you set as `headerKey`:
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY",
"X-Auth-Token": "opaque-or-idp-token..."
}
}
}
}
```
If your IdP issues **JWTs that already carry Portkey org claims** (`portkey_oid` / `organisation_id`, `portkey_workspace` / `workspace_slug`), you can pass that JWT in `x-portkey-api-key` and it serves as the gateway credential on its own—see [Organization JWT Authentication](/docs/product/enterprise-offering/org-management/jwt). In that case no separate Portkey API key is required.
Or in code:
> [tab] Python
>
> ```python theme={"system"}
> # Get the end-user token from your IdP (example using OIDC)
> token = get_idp_token() # Your IdP client
>
> headers = {
> "x-portkey-api-key": "YOUR_PORTKEY_API_KEY", # gateway credential
> "X-Auth-Token": token, # end-user token (introspected)
> }
>
> async with streamablehttp_client(
> "https://mcp.portkey.ai/linear/mcp",
> headers=headers
> ) as (read, write, _):
> # MCP operations...
> ```
> [tab] TypeScript
>
> ```typescript theme={"system"}
> // Get the end-user token from your IdP
> const token = await getIdpToken(); // Your IdP client
>
> const client = new MCPClient({
> url: "https://mcp.portkey.ai/linear/mcp",
> headers: {
> "x-portkey-api-key": "YOUR_PORTKEY_API_KEY", // gateway credential
> "X-Auth-Token": token, // end-user token (introspected)
> },
> });
> ```
***
## Validating Claim Values
Validate that tokens are issued by the correct IdP and intended for MCP access:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"algorithms": ["RS256"],
"requiredClaims": ["sub", "email"],
"claimValues": {
"iss": {
"values": "https://your-idp.com",
"matchType": "exact"
},
"aud": {
"values": ["api://mcp", "https://mcp.yourcompany.com"],
"matchType": "contains"
}
}
}
}
```
This prevents:
* Tokens from other IdPs being accepted
* Tokens intended for other services being used for MCP
***
## Combining with Identity Forwarding
External OAuth pairs naturally with identity forwarding. Portkey validates the incoming JWT, extracts user claims, and forwards them to MCP servers.
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"requiredClaims": ["sub", "email", "groups"]
},
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "groups"]
}
}
```
The MCP server receives user identity without handling OAuth itself. It can use this for:
* **Authorization**: Check if user belongs to required groups
* **Logging**: Audit trail with user identity
* **Personalization**: Customize responses based on user
See [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding).
***
## IdP-Specific Examples
### Descope
1. Create a project in the [Descope Console](https://app.descope.com)
2. Note your Project ID (found in **[Project Settings](https://app.descope.com/settings/project)**)
3. Enable DCR, under DCR Settings under Inbound Applications
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://api.descope.com/{project-id}/.well-known/jwks.json",
"algorithms": ["RS256"],
"claimValues": {
"iss": {
"values": "https://api.descope.com/v1/apps/{project-id}",
"matchType": "exact"
}
}
}
}
```
### Okta
1. Create an authorization server in Okta Admin Console
2. Create an OAuth application (Web or SPA)
3. Note your issuer URL (e.g., `https://dev-12345.okta.com/oauth2/default`)
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://dev-12345.okta.com/oauth2/default/v1/keys",
"algorithms": ["RS256"],
"claimValues": {
"iss": {
"values": "https://dev-12345.okta.com/oauth2/default",
"matchType": "exact"
}
}
}
}
```
### Auth0
1. Create an API in Auth0 Dashboard
2. Note your tenant domain and API identifier
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-tenant.auth0.com/.well-known/jwks.json",
"algorithms": ["RS256"],
"claimValues": {
"iss": {
"values": "https://your-tenant.auth0.com/",
"matchType": "exact"
},
"aud": {
"values": "https://your-api-identifier",
"matchType": "exact"
}
}
}
}
```
### Azure AD / Entra ID
1. Register an application in Azure Portal
2. Note your tenant ID and client ID
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://login.microsoftonline.com/{tenant-id}/discovery/v2.0/keys",
"algorithms": ["RS256"],
"claimValues": {
"iss": {
"values": "https://login.microsoftonline.com/{tenant-id}/v2.0",
"matchType": "exact"
},
"aud": {
"values": "{client-id}",
"matchType": "exact"
}
}
}
}
```
### AWS Cognito
1. Create a User Pool in AWS Console
2. Note your region and pool ID
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://cognito-idp.{region}.amazonaws.com/{pool-id}/.well-known/jwks.json",
"algorithms": ["RS256"],
"claimValues": {
"iss": {
"values": "https://cognito-idp.{region}.amazonaws.com/{pool-id}",
"matchType": "exact"
}
}
}
}
```
***
## Securing Your Setup
### Validate Issuer and Audience
Always configure `claimValues` to verify `iss` and `aud`:
```json theme={"system"}
{
"claimValues": {
"iss": {
"values": "https://your-idp.com",
"matchType": "exact"
},
"aud": {
"values": "your-client-id-or-api-identifier",
"matchType": "exact"
}
}
}
```
Without this, tokens intended for other applications might be accepted.
### Require Essential Claims
Require essential claims:
```json theme={"system"}
{
"requiredClaims": ["sub", "email"]
}
```
If a claim is missing, the request is rejected.
### Use Short Token Lifetimes
Configure the IdP to issue short-lived access tokens (15-60 minutes). This limits the window if a token is compromised.
***
## Troubleshooting
### 401 Unauthorized when sending only an end-user token
If you send only an opaque (or IdP) token with no Portkey API key and no org-claim JWT, the gateway can't resolve your organization, so it rejects the request *before* introspection runs (your introspection endpoint is never called, and the client may fall into a browser OAuth prompt). Add a gateway credential—`x-portkey-api-key` or an org-claim JWT—and pass the end-user token in the `headerKey` header.
### "Invalid issuer" Error
The token's `iss` claim doesn't match your configuration. Verify the issuer URL exactly matches—including trailing slashes.
### "Missing required claims" Error
The token doesn't include claims you specified in `requiredClaims`. Check your IdP's token configuration and scopes.
### "Invalid audience" Error
The token's `aud` claim doesn't match your configuration. Verify the correct API identifier or client ID.
### "JWKS fetch failed" Error
Portkey couldn't fetch keys from your JWKS URI. Verify the URL is accessible and returns valid JWKS JSON.
***
## Related
| Topic | Description |
| - | - |
| [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) | Full configuration reference for JWT validation |
| [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) | Pass validated claims to MCP servers |
| [Authentication Overview](/docs/product/mcp-gateway/authentication) | Understanding gateway authentication |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Forwarding Headers
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/forwarding-headers
Pass headers from agent requests to MCP servers.
Header forwarding passes specific headers from agent requests through to MCP servers. Use for distributed tracing, tenant context, or custom metadata that needs to reach the upstream server.
You can also **rename headers inline** using object entries, so client-side header names can differ from what the upstream server expects.
## When to Use
Your agent includes headers with context that the MCP server needs. Maybe a trace ID for distributed tracing. Maybe a tenant ID for multi-tenant servers. Maybe custom metadata your server expects.
Without header forwarding, these headers stop at Portkey. With it, they pass through to the MCP server.
Common scenarios:
* **Distributed tracing.** Forward `x-request-id`, `x-trace-id`, `x-correlation-id` to correlate logs across services.
* **Multi-tenancy.** Forward `x-tenant-id`, `x-org-id` for tenant-scoped operations.
* **User context.** Forward `x-user-id`, `x-user-role` for upstream authorization.
* **Custom metadata.** Forward application-specific headers your MCP server expects.
***
## Configuration
Configure `forward_headers` when adding or editing an MCP server in the MCP Registry.
### Shorthand (string array)
Forward only the headers you specify. No renaming support in this form:
```json theme={"system"}
{
"forward_headers": ["x-request-id", "x-trace-id", "x-tenant-id"]
}
```
Other headers from the agent request are dropped.
### Allowlist mode
The same behavior with explicit configuration. Entries in the `headers` array can be:
* **A string** — forwards the header as-is.
* **An object** `{ "from": "", "to": "" }` — forwards the header with its name changed.
```json theme={"system"}
{
"forward_headers": {
"mode": "allowlist",
"headers": [
"x-trace-id",
{ "from": "x-tenant-id", "to": "X-Organization-Id" },
{ "from": "x-env", "to": "X-Deploy-Environment" }
]
}
}
```
In this example, `x-trace-id` is forwarded as-is, `x-tenant-id` arrives at the upstream as `X-Organization-Id`, and `x-env` arrives as `X-Deploy-Environment`.
### All-except mode
Forward everything except headers you exclude. String entries are excluded; object entries rename forwarded headers:
```json theme={"system"}
{
"forward_headers": {
"mode": "all-except",
"headers": [
"host",
"connection",
{ "from": "x-tenant-id", "to": "X-Org-Id" }
]
}
}
```
Here, `host` and `connection` are excluded. All other headers are forwarded. Additionally, `x-tenant-id` is renamed to `X-Org-Id` before reaching the upstream server.
> [!WARNING]
>
> Use `all-except` mode carefully. It forwards more headers than you might expect, which could leak information or cause conflicts. Prefer explicit allowlists when possible.
***
## Security
### Protected Headers
These headers are **never forwarded** regardless of your configuration:
| Header | Reason |
| - | - |
| `cookie` | Session data should not leak |
| `set-cookie` | Response header, not request |
| `x-api-key` | Could leak API keys |
| `x-portkey-api-key` | Portkey authentication |
| `api-key` | Could leak API keys |
| `apikey` | Could leak API keys |
| `x-auth-token` | Could leak tokens |
| `x-access-token` | Could leak tokens |
| `x-user-claims` | Identity spoofing prevention |
| `x-user-jwt` | Identity spoofing prevention |
In `all-except` mode, these are automatically added to the blocklist. You cannot override this behavior.
### Header mapping validation
When using object entries for header renaming, **both** the source (`from`) and target (`to`) header names are validated against the protected headers blocklist. If either name is protected, the mapping is rejected and the header is not forwarded.
Header matching on the source name is **case-insensitive**.
```json theme={"system"}
// This mapping is rejected — x-api-key is protected
{ "from": "x-api-key", "to": "X-Custom-Key" }
// This mapping is also rejected — the target is protected
{ "from": "x-custom", "to": "x-auth-token" }
```
### Identity Headers Are Protected
If you use [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding), identity headers are also protected:
* `X-User-Claims`
* `X-User-JWT`
This prevents clients from spoofing user identity by sending fake identity headers.
***
## Header Priority
When multiple sources provide headers, they merge in this order (later values override earlier ones):
| Priority | Source | Description |
| - | - | - |
| 1 (lowest) | Forwarded headers | Headers from the agent request |
| 2 | Auth headers | `headers` configured on the MCP server |
| 3 | Passthrough headers | `passthrough_headers` configured on the server |
| 4 (highest) | Identity headers | Headers from [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) |
**Why this order matters:**
* Authentication headers configured on the server cannot be overridden by agents
* Static passthrough headers take precedence over agent headers
* Identity headers always win—agents cannot spoof user identity
**Example:**
```
Agent sends: X-Custom: agent-value
Server config: X-Custom: server-value (in passthrough_headers)
```
Result: MCP server receives `X-Custom: server-value` (server config wins).
***
## Agent Configuration
Include headers in your MCP client configuration:
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "pk_xxx",
"x-request-id": "req-12345",
"x-tenant-id": "tenant-abc"
}
}
}
}
```
Or set headers per request in code:
> [tab] Python
>
> ```python theme={"system"}
> import uuid
>
> headers = {
> "x-portkey-api-key": "pk_xxx",
> "x-request-id": str(uuid.uuid4()),
> "x-trace-id": current_trace_id,
> "x-tenant-id": "tenant-abc"
> }
>
> async with streamablehttp_client(url, headers=headers) as (read, write, _):
> # x-request-id, x-trace-id, and x-tenant-id forwarded to MCP server
> ...
> ```
> [tab] TypeScript
>
> ```typescript theme={"system"}
> import { randomUUID } from 'crypto';
>
> const headers = {
> "x-portkey-api-key": "pk_xxx",
> "x-request-id": randomUUID(),
> "x-trace-id": currentTraceId,
> "x-tenant-id": "tenant-abc"
> };
>
> // Headers forwarded based on forward_headers configuration
> ```
***
## Example: Distributed Tracing
You want to correlate MCP requests with your application's traces.
**Server configuration:**
```json theme={"system"}
{
"forward_headers": ["x-request-id", "x-trace-id", "traceparent"]
}
```
**Agent request:**
```json theme={"system"}
{
"headers": {
"x-portkey-api-key": "pk_xxx",
"x-request-id": "req-abc123",
"x-trace-id": "trace-xyz789",
"traceparent": "00-0af7651916cd43dd8448eb211c80319c-b7ad6b7169203331-01"
}
}
```
**MCP server receives:**
```
x-request-id: req-abc123
x-trace-id: trace-xyz789
traceparent: 00-0af7651916cd43dd8448eb211c80319c-b7ad6b7169203331-01
```
Now your MCP server logs include the same trace IDs as your application.
***
## Example: Multi-Tenant Server
Your internal MCP server needs tenant context to scope data access.
**Server configuration:**
```json theme={"system"}
{
"forward_headers": ["x-tenant-id", "x-org-id"]
}
```
**Agent request:**
```json theme={"system"}
{
"headers": {
"x-portkey-api-key": "pk_xxx",
"x-tenant-id": "tenant-acme",
"x-org-id": "org-12345"
}
}
```
**MCP server receives:**
```
x-tenant-id: tenant-acme
x-org-id: org-12345
```
Your server uses these headers to filter data to the correct tenant.
***
## Example: Header renaming
Your agent sends `x-tenant-id` but your upstream MCP server expects `X-Organization-Id`.
**Server configuration:**
```json theme={"system"}
{
"forward_headers": {
"mode": "allowlist",
"headers": [
"x-request-id",
{ "from": "x-tenant-id", "to": "X-Organization-Id" }
]
}
}
```
**Agent request:**
```json theme={"system"}
{
"headers": {
"x-portkey-api-key": "pk_xxx",
"x-request-id": "req-abc123",
"x-tenant-id": "tenant-acme"
}
}
```
**MCP server receives:**
```
x-request-id: req-abc123
X-Organization-Id: tenant-acme
```
The `x-tenant-id` header is renamed to `X-Organization-Id` before reaching the upstream server.
***
## Combining with Identity Forwarding
Header forwarding and identity forwarding serve different purposes:
| Feature | Purpose | Source |
| - | - | - |
| **Header Forwarding** | Pass metadata (traces, tenants) | Agent request |
| **Identity Forwarding** | Pass authenticated user claims | Portkey (from validated token) |
Use both together:
```json theme={"system"}
{
"forward_headers": ["x-request-id", "x-trace-id"],
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "workspace_id"]
}
}
```
The MCP server receives:
* `x-request-id` and `x-trace-id` from the agent (for tracing)
* `X-User-Claims` from Portkey (for user identity)
***
## Related
| Topic | Description |
| - | - |
| [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) | Pass authenticated user claims to MCP servers |
| [Custom Auth](/docs/product/mcp-gateway/authentication/custom-auth) | Configure static headers for MCP servers |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Identity Forwarding
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/identity-forwarding
Pass authenticated user identity to MCP servers.
Identity forwarding sends authenticated user information to MCP servers. The server can use this for authorization, logging, or personalization—without implementing its own authentication.
## When to Use
MCP servers often need to know who is making requests—for access controls based on user roles, audit logging, or personalized responses.
Without identity forwarding, the MCP server sees requests coming from Portkey, not from individual users. Identity forwarding bridges that gap.
Common scenarios:
* **Audit logging.** MCP server logs user identity for compliance
* **Authorization.** MCP server enforces per-user permissions
* **Multi-tenancy.** MCP server scopes data by user or organization
* **Analytics.** Track usage patterns by user or team
* **Personalization.** Customize responses based on user context
***
## How It Works
```
1. User authenticates to Portkey (API key, OAuth, or external IdP)
2. Portkey extracts user claims from the authentication
3. Portkey forwards claims to the MCP server (as configured)
4. MCP server uses claims for authorization/logging/personalization
```
The MCP server doesn't need to validate tokens or implement OAuth. It receives trusted user identity from Portkey.
***
## Forwarding Methods
### Claims Header
Send user claims as a JSON header. Simple to parse, no cryptographic verification needed.
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "workspace_id"],
"header_name": "X-User-Claims"
}
}
```
The MCP server receives:
```
X-User-Claims: {"sub":"user123","email":"user@example.com","workspace_id":"ws_abc"}
```
Parse the JSON to get user identity:
> [tab] Python
>
> ```python theme={"system"}
> import json
>
> def get_user_identity(request):
> claims_header = request.headers.get("X-User-Claims")
> if claims_header:
> return json.loads(claims_header)
> return None
> ```
> [tab] TypeScript
>
> ```typescript theme={"system"}
> function getUserIdentity(request: Request) {
> const claimsHeader = request.headers.get("X-User-Claims");
> if (claimsHeader) {
> return JSON.parse(claimsHeader);
> }
> return null;
> }
> ```
**Best for:** Internal MCP servers in trusted networks that trust Portkey's claims without cryptographic verification.
### Bearer Token Passthrough
Forward the original access token unchanged.
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "bearer"
}
}
```
The MCP server receives:
```
Authorization: Bearer
```
The MCP server validates the token itself against the same IdP that issued it.
**Best for:** When the MCP server already has token validation infrastructure and uses the same IdP.
### Signed JWT
Portkey generates a new JWT containing user claims, signed with Portkey's private key.
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "jwt_header",
"include_claims": ["sub", "email", "workspace_id", "organisation_id"],
"header_name": "X-User-JWT",
"jwt_expiry_seconds": 300
}
}
```
The MCP server receives:
```
X-User-JWT: eyJhbGciOiJSUzI1NiIsInR5cCI6IkpXVCIsImtpZCI6ImFiYzEyMyJ9...
```
The JWT contains:
* User claims (filtered by `include_claims`)
* `iss`: `"portkey-mcp-gateway"`
* `iat`: Issued at timestamp
* `exp`: Expiration timestamp
**Best for:** Cryptographic proof that Portkey issued the claims. MCP servers verify the signature without trusting the network.
***
## Configuration Options
| Field | Type | Default | Description |
| - | - | - | - |
| `method` | string | Required | `"claims_header"`, `"bearer"`, or `"jwt_header"` |
| `include_claims` | string\[] | See below | Claims to include |
| `header_name` | string | Method-specific | Custom header name |
| `jwt_expiry_seconds` | number | `300` | JWT expiry (only for `jwt_header`) |
### Default Header Names
| Method | Default Header |
| - | - |
| `claims_header` | `X-User-Claims` |
| `bearer` | `Authorization` |
| `jwt_header` | `X-User-JWT` |
### Default Claims
If you don't specify `include_claims`, Portkey includes:
| Claim | Description |
| - | - |
| `sub` | Subject (user identifier) |
| `email` | User's email address |
| `username` | Username |
| `user_id` | Portkey user ID |
| `workspace_id` | Workspace identifier |
| `organisation_id` | Organization identifier |
| `scope` | OAuth scopes |
| `client_id` | OAuth client ID |
These defaults cover common authorization and logging needs. Customize `include_claims` to add or restrict which claims are forwarded.
***
## Verifying Signed JWTs
For `jwt_header`, MCP servers verify tokens using Portkey's public keys.
### Fetch Public Keys
```
GET https://mcp.portkey.ai/.well-known/jwks.json
```
Response:
```json theme={"system"}
{
"keys": [
{
"kty": "RSA",
"n": "0vx7agoebGcQSuu...",
"e": "AQAB",
"kid": "key-id-123",
"use": "sig",
"alg": "RS256"
}
]
}
```
### Verify in Your MCP Server
Standard JWT libraries fetch and cache these keys automatically:
> [tab] Python
>
> ```python theme={"system"}
> import jwt
> from jwt import PyJWKClient
>
> # Initialize JWKS client (caches keys automatically)
> jwks_client = PyJWKClient("https://mcp.portkey.ai/.well-known/jwks.json")
>
> def verify_user_jwt(request):
> token = request.headers.get("X-User-JWT")
> if not token:
> return None
>
> try:
> signing_key = jwks_client.get_signing_key_from_jwt(token)
> claims = jwt.decode(
> token,
> signing_key.key,
> algorithms=["RS256"],
> issuer="portkey-mcp-gateway"
> )
> return claims
> except jwt.InvalidTokenError:
> return None
> ```
> [tab] TypeScript
>
> ```typescript theme={"system"}
> import * as jose from 'jose';
>
> const JWKS = jose.createRemoteJWKSet(
> new URL('https://mcp.portkey.ai/.well-known/jwks.json')
> );
>
> async function verifyUserJwt(request: Request) {
> const token = request.headers.get('X-User-JWT');
> if (!token) return null;
>
> try {
> const { payload } = await jose.jwtVerify(token, JWKS, {
> issuer: 'portkey-mcp-gateway',
> algorithms: ['RS256']
> });
> return payload;
> } catch {
> return null;
> }
> }
> ```
***
## Security
### Identity Headers Are Protected
Portkey adds identity headers (`X-User-Claims`, `X-User-JWT`) to the protected headers list. This means:
* **Clients cannot spoof identity.** If an agent sends a fake `X-User-Claims` header, it's stripped before processing.
* **Identity headers have highest priority.** They override any other headers with the same name.
* **Header forwarding cannot bypass this.** Even with `forward_headers: { mode: "all-except", headers: [] }`, identity headers from clients are blocked.
This ensures MCP servers can trust identity information from Portkey.
### JWT Security Properties
Signed JWTs provide:
* **Integrity**: Claims cannot be modified without invalidating the signature
* **Authenticity**: Only Portkey can sign with its private key
* **Expiry**: Short-lived tokens (default 5 minutes) limit replay window
The signing key is RSA-2048, and JWTs use RS256 algorithm.
***
## Performance
### JWT Caching
Signing JWTs involves expensive cryptographic operations. Portkey caches signed JWTs to avoid this overhead:
| Scenario | Latency |
| - | - |
| Cache hit | \~0.01ms |
| Cache miss (signing) | \~1ms |
Cache details:
* Max 10,000 cached entries
* LRU eviction when full
* Cache key includes user identity and included claims
* Cache entries expire with the JWT
### JWKS Caching on MCP Server
Cache Portkey's JWKS on the MCP server. Most JWT libraries handle this automatically with configurable TTL.
***
## Self-Hosted Setup
Self-hosted Portkey deployments using `jwt_header` require a signing key.
### Generate Key Pair
```bash theme={"system"}
# Generate RSA private key
openssl genrsa -out private.pem 2048
# Extract public key
openssl rsa -in private.pem -pubout -out public.pem
```
### Configure Environment
```bash theme={"system"}
export JWT_PRIVATE_KEY="$(cat private.pem)"
```
Portkey automatically exposes the public key at `/.well-known/jwks.json` for MCP servers to verify.
***
## Examples
### Basic Claims Forwarding
Forward essential identity for logging:
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email"]
}
}
```
### Signed JWT with Custom Expiry
MCP servers needing cryptographic verification with longer validity:
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "jwt_header",
"include_claims": ["sub", "email", "workspace_id", "organisation_id", "groups"],
"jwt_expiry_seconds": 600
}
}
```
### Combined with External OAuth
Authenticate via IdP and forward validated claims to MCP servers:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"requiredClaims": ["sub", "email", "groups"]
},
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "groups"]
}
}
```
Flow:
1. User authenticates with your IdP, gets token
2. User sends request to Portkey with IdP token
3. Portkey validates token against your IdP
4. Portkey extracts claims and forwards to MCP server
5. MCP server uses claims for authorization
***
## Use Case: Per-User Authorization
An MCP server exposes project management tools. Users should only access their own projects.
**Configuration:**
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "jwt_header",
"include_claims": ["sub", "email", "org_id"]
}
}
```
**MCP Server Implementation:**
```python theme={"system"}
async def list_projects(request):
claims = verify_user_jwt(request)
if not claims:
raise Unauthorized("Missing or invalid user identity")
# Scope query to user's organization
projects = await db.query(
"SELECT * FROM projects WHERE org_id = ?",
claims["org_id"]
)
return projects
```
***
## Use Case: Audit Logging
Log every tool call with user identity:
**Configuration:**
```json theme={"system"}
{
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "workspace_id"]
}
}
```
**MCP Server Logging:**
```python theme={"system"}
import json
import logging
def log_tool_call(request, tool_name, params):
claims = json.loads(request.headers.get("X-User-Claims", "{}"))
logging.info(
"Tool called",
extra={
"tool": tool_name,
"params": params,
"user_sub": claims.get("sub"),
"user_email": claims.get("email"),
"workspace_id": claims.get("workspace_id")
}
)
```
***
## Related
| Topic | Description |
| - | - |
| [External OAuth](/docs/product/mcp-gateway/authentication/external-oauth) | Use your own IdP for gateway authentication |
| [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) | Validate tokens from external IdPs |
| [Forwarding Headers](/docs/product/mcp-gateway/authentication/forwarding-headers) | Pass request headers to MCP servers |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# JWT Validation
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/jwt
Validate JWTs from external identity providers.
JWT validation enables Portkey to verify tokens from your identity provider before processing MCP requests. Use with [External OAuth](/docs/product/mcp-gateway/authentication/external-oauth) to bring your own IdP.
## When to Use
Organizations with existing identity providers (Okta, Auth0, Azure AD, Cognito) can use JWT validation. Users authenticate through the IdP, and MCP access works the same way.
Flow:
1. Users get a token from the IdP
2. Token included in MCP requests
3. Portkey validates the token against the IdP
4. Valid requests proceed with user identity attached
Portkey never handles user credentials. Your IdP remains the source of truth for identity.
***
## Validation Methods
Configure one validation method per MCP server. Each has different tradeoffs.
### JWKS URI
Fetch public keys from your IdP's JWKS endpoint. This is the standard approach for most identity providers.
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"algorithms": ["RS256", "ES256"]
}
}
```
Portkey fetches keys and caches them (default: 24 hours). When a key rotates, Portkey automatically refetches the JWKS if verification fails with the cached key.
**Best for:** Most production deployments. Minimal configuration, automatic key rotation.
#### Multiple JWKS URIs
When your infrastructure uses multiple identity providers or key sets, pass a comma-separated list of JWKS endpoints:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://idp-1.example.com/.well-known/jwks.json, https://idp-2.example.com/.well-known/jwks.json",
"algorithms": ["RS256"]
}
}
```
Portkey fetches all endpoints in parallel, merges their key sets, and finds the matching key by `kid`. If one endpoint is unavailable, tokens are still verified against the keys from the remaining endpoints.
> [!NOTE]
>
> URLs that contain commas in query strings (e.g., `?tenants=a,b`) are handled correctly — Portkey only splits on commas that separate distinct URLs.
### Inline JWKS
Embed public keys directly in the configuration. Use for self-contained deployments or environments without a JWKS endpoint.
```json theme={"system"}
{
"jwt_validation": {
"jwks": {
"keys": [{
"kty": "RSA",
"n": "0vx7agoebGcQSuu...",
"e": "AQAB",
"kid": "key-id-1",
"use": "sig",
"alg": "RS256"
}]
}
}
}
```
Update keys manually when they rotate.
**Best for:** Air-gapped environments, testing, or when IdP doesn't expose JWKS.
### Token Introspection (RFC 7662)
For opaque tokens that require real-time validation. Portkey calls your IdP's introspection endpoint.
```json theme={"system"}
{
"jwt_validation": {
"introspectEndpoint": "https://your-idp.com/oauth/introspect",
"introspectContentType": "application/json",
"introspectCacheMaxAge": 300
}
}
```
The introspection endpoint must return a JSON response with an `active` boolean field per RFC 7662.
**Best for:** Opaque tokens, real-time revocation checking, or validating token status against the IdP on every request.
***
## Configuration Reference
### Core Options
| Field | Type | Default | Description |
| - | - | - | - |
| `jwksUri` | string | - | URL to fetch public keys |
| `jwks` | object | - | Inline JWKS object with `keys` array |
| `introspectEndpoint` | string | - | Token introspection URL (RFC 7662) |
| `headerKey` | string | `"Authorization"` | Header to read the token from |
| `algorithms` | string\[] | `["RS256"]` | Allowed signing algorithms |
### Timing Options
| Field | Type | Default | Description |
| - | - | - | - |
| `clockTolerance` | number | `5` | Clock skew tolerance in seconds |
| `cacheMaxAge` | number | `86400` | JWKS cache TTL in seconds (24 hours) |
| `maxTokenAge` | string | - | Max token age (e.g., `"30m"`, `"12h"`) |
### Introspection Options
| Field | Type | Default | Description |
| - | - | - | - |
| `introspectEndpoint` | string | - | Token introspection URL |
| `introspectContentType` | string | `"application/json"` | Content-Type for introspection requests |
| `introspectCacheMaxAge` | number | - | Cache introspection results (seconds) |
### Claim Validation Options
| Field | Type | Default | Description |
| - | - | - | - |
| `requiredClaims` | string\[] | - | Claims that must be present |
| `claimValues` | object | - | Expected claim values with match types |
| `headerPayloadMatch` | string\[] | - | Header claims that must match payload claims |
***
## Custom Token Header
By default, Portkey reads the token from the `Authorization` header. For a different header:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"headerKey": "X-Auth-Token"
}
}
```
Agents then send:
```json theme={"system"}
{
"headers": {
"X-Auth-Token": "Bearer eyJhbGciOiJSUzI1NiIs..."
}
}
```
***
## Require Specific Claims
Tokens must include these claims or they're rejected:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"requiredClaims": ["sub", "email", "groups"]
}
}
```
If a token is missing `sub`, `email`, or `groups`, Portkey returns:
```json theme={"system"}
{
"error": "unauthorized",
"error_description": "Missing required claims: groups"
}
```
***
## Validate Claim Values
Check that claims have expected values:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"claimValues": {
"iss": {
"values": "https://your-idp.com",
"matchType": "exact"
},
"aud": {
"values": ["api", "mcp", "portkey"],
"matchType": "contains"
},
"scope": {
"values": ["mcp:read", "mcp:write"],
"matchType": "containsAll"
},
"email": {
"values": "@yourcompany\\.com$",
"matchType": "regex"
}
}
}
}
```
### Match Types
| Type | Description | Example |
| - | - | - |
| `exact` | Value must match exactly | `iss` must equal `"https://your-idp.com"` |
| `contains` | Payload must include at least one value (OR) | `aud` must include `"api"` OR `"mcp"` OR `"portkey"` |
| `containsAll` | Payload must include all values (AND) | `scope` must include `"mcp:read"` AND `"mcp:write"` |
| `regex` | Match against a regular expression | `email` must match `@yourcompany\.com$` |
***
## Header-Payload Matching
Ensure that claims in the JWT header match claims in the payload. This provides additional security for tokens that include claims in both locations.
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"headerPayloadMatch": ["kid", "alg"]
}
}
```
If a specified claim exists in both the header and payload, they must have identical values. If they don't match, the token is rejected.
**Use case:** Some IdPs include certain claims in both the protected header and the payload. This validation ensures consistency and detects tampering.
***
## Caching Behavior
### JWKS Caching
* Keys cached for 24 hours by default (configurable via `cacheMaxAge`)
* CryptoKeys are pre-imported and cached for performance
* If signature verification fails with a cached key, Portkey refetches the JWKS (handles key rotation)
### Introspection Caching
* Not cached by default (every request calls the introspection endpoint)
* Enable caching with `introspectCacheMaxAge` (in seconds)
* Cached results respect token expiry—expired tokens aren't served from cache
**Example with caching:**
```json theme={"system"}
{
"jwt_validation": {
"introspectEndpoint": "https://your-idp.com/oauth/introspect",
"introspectCacheMaxAge": 300
}
}
```
With this configuration:
* First request: calls introspection endpoint, caches result
* Subsequent requests (within 5 minutes): uses cached result
* After 5 minutes: calls introspection endpoint again
**Tradeoff:** Shorter cache means more latency but faster revocation detection. Longer cache means better performance but slower revocation response.
***
## Performance Optimizations
Portkey optimizes JWT validation for production workloads:
| Optimization | Description |
| - | - |
| **Fail-fast expiry check** | Checks token expiry before expensive signature verification |
| **JWKS caching** | Keys cached and pre-imported as CryptoKeys |
| **Key rotation handling** | Auto-refetch JWKS if key not found |
| **Introspection caching** | Optional caching of introspection results |
Typical validation latency:
* JWKS (cache hit): \< 1ms
* JWKS (cache miss): 50-200ms (network fetch)
* Introspection (uncached): 50-300ms (depends on IdP)
* Introspection (cached): \< 1ms
***
## Example: Okta Integration
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://dev-12345.okta.com/oauth2/aus123/v1/keys",
"algorithms": ["RS256"],
"clockTolerance": 5,
"requiredClaims": ["sub", "email"],
"claimValues": {
"iss": {
"values": "https://dev-12345.okta.com/oauth2/aus123",
"matchType": "exact"
},
"aud": {
"values": "api://mcp",
"matchType": "exact"
}
}
}
}
```
## Example: Auth0 Integration
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-tenant.auth0.com/.well-known/jwks.json",
"algorithms": ["RS256"],
"requiredClaims": ["sub", "email"],
"claimValues": {
"iss": {
"values": "https://your-tenant.auth0.com/",
"matchType": "exact"
},
"aud": {
"values": "https://mcp.yourcompany.com",
"matchType": "exact"
}
}
}
}
```
## Example: Azure AD Integration
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://login.microsoftonline.com/{tenant-id}/discovery/v2.0/keys",
"algorithms": ["RS256"],
"requiredClaims": ["sub", "email", "groups"],
"claimValues": {
"iss": {
"values": "https://login.microsoftonline.com/{tenant-id}/v2.0",
"matchType": "exact"
},
"aud": {
"values": "{client-id}",
"matchType": "exact"
}
}
}
}
```
***
## Combining with Identity Forwarding
JWT validation extracts user claims from the token. Identity forwarding passes those claims to MCP servers:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"requiredClaims": ["sub", "email", "groups"]
},
"user_identity_forwarding": {
"method": "claims_header",
"include_claims": ["sub", "email", "groups"]
}
}
```
Flow:
1. User sends request with IdP token
2. Portkey validates token, extracts claims
3. Portkey forwards claims to MCP server
4. MCP server uses claims for authorization/logging
See [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding).
***
## Error Responses
| Error | Description |
| - | - |
| `Missing Authorization header` | No token provided |
| `Invalid authorization header format` | Not in `Bearer ` format |
| `JWT validation failed` | Signature invalid or token malformed |
| `Token is expired` | Token's `exp` claim is in the past |
| `Token is not yet valid` | Token's `nbf` claim is in the future |
| `Missing required claims: ` | Token missing required claims |
| `Token is not active` | Introspection returned `active: false` |
***
## Related
| Topic | Description |
| - | - |
| [External OAuth](/docs/product/mcp-gateway/authentication/external-oauth) | Overview of using external IdPs |
| [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) | Pass validated claims to MCP servers |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# OAuth
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/oauth
Portkey's built-in OAuth 2.1 authentication for MCP Gateway.
Portkey provides built-in OAuth 2.1 authentication for MCP Gateway. When users access MCP servers without an API key, Portkey acts as the OAuth provider and handles the authentication flow.
## When to use
Use Portkey's OAuth when:
* Building browser-based applications where users authenticate interactively
* Using MCP clients like Claude Desktop or Cursor without API keys
* User-level attribution without managing API keys
* Quick setup without configuring an external IdP
## How it works
```
1. User requests access to an MCP server
2. No API key provided
3. Portkey initiates OAuth 2.1 flow with PKCE
4. User authenticates with Portkey
5. Portkey issues access token
6. Token used for subsequent MCP requests
```
The flow uses OAuth 2.1 with PKCE (Proof Key for Code Exchange) for enhanced security. No client secrets are exposed to browser-based applications.
## Configuration
Portkey's OAuth is enabled by default. No configuration required.
When a request arrives without an API key or bearer token, Portkey automatically initiates the OAuth flow.
## Client integration
### Browser applications
For browser-based apps, redirect users to the authorization endpoint:
```
https://mcp.portkey.ai/oauth/authorize?
response_type=code&
client_id=YOUR_CLIENT_ID&
redirect_uri=YOUR_REDIRECT_URI&
code_challenge=GENERATED_CHALLENGE&
code_challenge_method=S256&
scope=mcp
```
After authorization, exchange the code for tokens:
```bash theme={"system"}
curl -X POST https://mcp.portkey.ai/oauth/token \
-d "grant_type=authorization_code" \
-d "code=AUTHORIZATION_CODE" \
-d "redirect_uri=YOUR_REDIRECT_URI" \
-d "code_verifier=YOUR_CODE_VERIFIER"
```
### MCP clients
MCP clients like Claude Desktop and Cursor handle OAuth automatically. Configuring a server URL without an API key triggers the OAuth flow when needed.
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp"
}
}
}
```
On first tool use, the client opens a browser for authentication.
## Token management
Portkey handles token lifecycle:
* **Access tokens**: Short-lived, used for MCP requests
* **Refresh tokens**: Long-lived, used to obtain new access tokens
* **Automatic refresh**: Tokens refreshed transparently before expiration
## Scopes
| Scope | Description |
| - | - |
| `mcp` | Access MCP servers provisioned to the user's workspace |
| `mcp:read` | Read-only access to MCP tools |
| `mcp:write` | Write access to MCP tools |
## Combining with external OAuth
Portkey's OAuth works alongside external OAuth. Portkey determines the authentication method based on what's in the request:
| Request contains | Authentication method |
| - | - |
| Portkey API key | API key authentication |
| External IdP token | External OAuth 2.0 validation |
| Nothing | Portkey OAuth 2.1 flow |
## Security considerations
* OAuth 2.1 with PKCE prevents authorization code interception
* Tokens are scoped to specific workspaces
* Refresh tokens can be revoked instantly
* All token operations are logged
## Related
| Topic | Description |
| - | - |
| [External OAuth](/docs/product/mcp-gateway/authentication/external-oauth) | Use your own identity provider |
| [API Keys](/docs/product/mcp-gateway/authentication#api-key) | Simpler authentication for programmatic access |
| [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) | Validate tokens from external IdPs |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# OAuth Client Metadata
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authentication/oauth-client-metadata
Customize OAuth client metadata for MCP servers.
When Portkey connects to OAuth-protected MCP servers using **OAuth Auto**, it registers as an OAuth client with the server's authorization endpoint. By default, Portkey uses standard client metadata. For compliance or branding requirements, you can customize this.
## When to Use
Customize OAuth client metadata when:
* The OAuth server requires a pre-registered `software_id` or specific scopes
* You need custom branding during OAuth consent screens (your company name/logo instead of Portkey's)
* Compliance requires specific contact info, terms of service, or privacy policy URLs
* The MCP server expects specific OAuth client configuration
***
## How It Works
When a user first accesses an OAuth-protected MCP server, Portkey initiates the OAuth flow. As part of this process, Portkey presents client metadata to the authorization server (per RFC 7591 - OAuth 2.0 Dynamic Client Registration).
```
1. User requests tool from MCP server
2. Portkey initiates OAuth flow with authorization server
3. Authorization server shows consent screen with client metadata
4. User sees your company name/logo instead of default Portkey branding
5. User authorizes access
6. Flow completes normally
```
***
## Configuration
When setting up your MCP integration in the MCP Registry, expand **Advanced Settings** and paste your client metadata into the **OAuth Metadata** field as a plain JSON object:
```json theme={"system"}
{
"client_name": "Your Company Name",
"client_uri": "https://yourcompany.com",
"logo_uri": "https://yourcompany.com/logo.png",
"software_id": "com.yourcompany.mcp-gateway",
"scope": "mcp:servers:read mcp:tools:execute",
"contacts": ["support@yourcompany.com"],
"tos_uri": "https://yourcompany.com/terms",
"policy_uri": "https://yourcompany.com/privacy"
}
```
> [!WARNING]
>
> Do **not** wrap this in an outer `oauth_metadata` key when using the **OAuth Metadata** field. The field's contents are stored as your OAuth metadata directly, so an extra wrapper nests your settings one level too deep and Portkey ignores them silently — including a `client_id`, which causes Portkey to fall back to Dynamic Client Registration.
>
> The wrapper is only correct in the separate **Advanced Configuration** JSON box, which merges its top-level keys into the integration's configuration:
>
> ```json theme={"system"}
> {
> "oauth_metadata": {
> "client_name": "Your Company Name",
> "client_uri": "https://yourcompany.com",
> "logo_uri": "https://yourcompany.com/logo.png",
> "software_id": "com.yourcompany.mcp-gateway",
> "scope": "mcp:servers:read mcp:tools:execute",
> "contacts": ["support@yourcompany.com"],
> "tos_uri": "https://yourcompany.com/terms",
> "policy_uri": "https://yourcompany.com/privacy"
> }
> }
> ```
All the examples on this page show the contents of the **OAuth Metadata** field. If you use the **Advanced Configuration** box instead, nest each one under `oauth_metadata`.
***
## Available Fields
| Field | Type | Description |
| - | - | - |
| `client_id` | string | Pre-registered OAuth client ID. Setting this disables Dynamic Client Registration for the integration |
| `client_secret` | string | Pre-registered OAuth client secret, for confidential clients |
| `client_name` | string | Name shown during OAuth consent |
| `client_uri` | string | Organization's homepage URL |
| `logo_uri` | string | Logo shown during consent (should be HTTPS) |
| `scope` | string | Space-separated OAuth scopes to request |
| `software_id` | string | Unique client identifier (useful for pre-registered clients) |
| `software_version` | string | Client software version |
| `grant_types` | string\[] | OAuth grant types (default: `["authorization_code", "refresh_token"]`) |
| `response_types` | string\[] | OAuth response types (default: `["code"]`) |
| `token_endpoint_auth_method` | string | Token endpoint auth method (default: `"none"`) |
| `contacts` | string\[] | Contact email addresses |
| `tos_uri` | string | Terms of Service URL |
| `policy_uri` | string | Privacy policy URL |
| `authorization_params` | object | Extra query parameters appended to the upstream authorization URL (string values only) |
***
## Default Values
If not customized, Portkey uses:
| Field | Default Value |
| - | - |
| `client_name` | `"Portkey (workspaceId/serverId)"` |
| `client_uri` | `"https://portkey.ai"` |
| `logo_uri` | Portkey logo |
| `software_id` | `"ai.portkey.mcp"` |
| `grant_types` | `["authorization_code", "refresh_token"]` |
| `response_types` | `["code"]` |
| `token_endpoint_auth_method` | `"none"` |
***
## Security Notes
### redirect\_uris Cannot Be Customized
The `redirect_uris` field is **never customizable**. Portkey always uses its own callback URL for OAuth flows:
```
/oauth/upstream-callback
```
This ensures OAuth tokens are delivered securely to Portkey's gateway, not to an arbitrary URL.
### Fields That Cannot Be Set
The following fields are excluded from customization:
* `redirect_uris` - Must be gateway-controlled for security
* `jwks_uri` - Not yet supported
* `jwks` - Not yet supported
* `software_statement` - Not yet supported
If you include these fields, they're ignored.
### Authorization Parameters That Cannot Be Set
`authorization_params` cannot override the parameters Portkey and the MCP SDK own, because doing so would break PKCE or the callback correlation:
`response_type`, `client_id`, `client_secret`, `code_challenge`, `code_challenge_method`, `redirect_uri`, `state`, `scope`, `resource`
Any of these keys in `authorization_params` are ignored and logged as a warning. Use the `scope` field of `oauth_metadata` to change requested scopes.
***
## Example: Enterprise Compliance
Your enterprise requires all OAuth registrations to include legal contact information and link to corporate policies:
```json theme={"system"}
{
"client_name": "Acme Corp MCP Gateway",
"client_uri": "https://acme.com",
"logo_uri": "https://acme.com/assets/logo.png",
"software_id": "com.acme.mcp-gateway",
"software_version": "1.0.0",
"scope": "mcp:read mcp:write",
"contacts": ["security@acme.com", "legal@acme.com"],
"tos_uri": "https://acme.com/legal/terms",
"policy_uri": "https://acme.com/legal/privacy"
}
```
When users authorize access, they see "Acme Corp MCP Gateway" with your logo instead of generic Portkey branding.
***
## Example: Pre-Registered Client
Some OAuth servers require clients to be pre-registered with a specific `software_id`:
```json theme={"system"}
{
"software_id": "registered-client-12345",
"client_name": "Pre-Registered MCP Client"
}
```
***
## Example: Custom Scopes
Request specific OAuth scopes from the MCP server:
```json theme={"system"}
{
"scope": "read:projects write:issues admin:webhooks"
}
```
The authorization server will request consent for these specific scopes.
***
## Example: Servers Without Dynamic Client Registration (GitHub)
Some MCP servers like GitHub don't support OAuth Dynamic Client Registration (DCR). For these servers, create an OAuth App manually and provide the credentials to Portkey.
**Required fields for non-DCR servers:**
| Field | Description |
| - | - |
| `client_id` | OAuth App client ID from the service |
| `client_secret` | OAuth App client secret from the service (only for confidential apps) |
| `scope` | Scopes to request during authorization |
| `token_endpoint_auth_method` | Set to `client_secret_post` or `client_secret_basic` if the OAuth App is registered as a confidential/web client. The default is `none`, which such apps reject at token exchange. |
Providing a `client_id` disables Dynamic Client Registration entirely for that integration — Portkey presents the client you configured instead of trying to register a new one.
**GitHub example:**
```json theme={"system"}
{
"client_id": "Iv1.a1b2c3d4e5f6g7h8",
"client_secret": "your_github_oauth_client_secret",
"scope": "repo read:org"
}
```
> [!NOTE]
>
> Set the OAuth App's **Authorization callback URL** to Portkey's callback, `/oauth/upstream-callback`. On Portkey's managed gateway that is `https://mcp.portkey.ai/oauth/upstream-callback`; on a self-hosted or hybrid deployment, use your own gateway host (the value of `MCP_GATEWAY_BASE_URL`). This URL is always controlled by the gateway, so a `redirect_uri` set in your OAuth metadata is ignored.
See the [GitHub MCP server guide](/docs/integrations/mcp-servers/github-mcp-server#connect-via-portkey-mcp-gateway) for complete setup instructions.
***
## Example: Provider-Specific Authorization Parameters (Google)
Some providers require query parameters on the authorization request that the OAuth spec doesn't define. Google is the common case: it only returns a **refresh token** when the authorization request carries `access_type=offline`, and only re-issues one for a user who has already consented when `prompt=consent` is also present.
Without a refresh token, Portkey has nothing to renew the connection with, so the user is pushed back through consent once the access token expires (one hour for Google).
Add these with `authorization_params`:
```json theme={"system"}
{
"oauth_metadata": {
"client_id": "...apps.googleusercontent.com",
"client_secret": "your_google_oauth_client_secret",
"redirect_uri": "https://mcp.portkey.ai/oauth/upstream-callback",
"scope": "https://www.googleapis.com/auth/drive.readonly",
"authorization_params": {
"access_type": "offline",
"prompt": "consent"
}
}
}
```
Portkey appends every key in `authorization_params` to the upstream authorization URL on each auth flow. Values must be strings; non-string values are ignored.
> [!NOTE]
>
> Connections authorized **before** this setting was added have no stored refresh token, and Google skips consent for a user who has already granted access — so the setting alone won't fix them. Remove the affected user's connection and have them authorize again; `prompt=consent` guarantees a refresh token on that pass.
For external authorization providers, set `authorization_params` inside `external_auth_config` instead.
## Troubleshooting
**Portkey still attempts Dynamic Client Registration even though I set a `client_id`.**
Portkey resolved no client ID from your configuration, so it fell back to registration. Check that the JSON in the **OAuth Metadata** field has `client_id` at the top level, with no outer `oauth_metadata` wrapper. If you configured it through the **Advanced Configuration** box instead, the wrapper is required there — but it must appear exactly once.
**Consent succeeds, then the token exchange fails.**
The client ID is being presented correctly and the failure is now on the provider side. In order of likelihood: the OAuth App is registered as a confidential/web client while Portkey defaults to `token_endpoint_auth_method: "none"` (set it explicitly, and supply `client_secret`); the callback URL registered on the provider doesn't exactly match `/oauth/upstream-callback`; or the app is missing a granted scope or the `refresh_token` grant, which Portkey requests by default.
***
## Related
| Topic | Description |
| - | - |
| [Authentication Overview](/docs/product/mcp-gateway/authentication) | How authentication layers work |
| [External MCP Servers](/docs/product/mcp-gateway/external-mcp-servers) | Adding OAuth-protected external servers |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Authorization
Source: https://docs.portkey.ai/docs/product/mcp-gateway/authorization
Control what users can access at the MCP server and tool level.
Authorization determines what authenticated users can access. While [authentication](/docs/product/mcp-gateway/authentication) verifies *who* a user is, authorization controls *what* they can do.
## Authorization Layers
MCP Gateway provides authorization at multiple levels:
| Level | What it controls | Status |
| - | - | - |
| **Workspace** | Which teams can access which MCP servers | Available |
| **MCP Server** | Access to specific servers based on claims | Available |
| **Tool** | Access to specific tools within a server | Coming soon |
***
## Server-Level Claim-Based Authorization
Control access to MCP servers based on JWT claims. This is configured through [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) using `requiredClaims` and `claimValues`.
### Require Specific Claims
Ensure tokens include specific claims before allowing access:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"requiredClaims": ["sub", "email", "groups"]
}
}
```
If a token is missing any required claim, access is denied.
### Validate Claim Values
Authorize based on claim values—group membership, roles, or other attributes:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"claimValues": {
"groups": {
"values": ["engineering", "platform"],
"matchType": "contains"
},
"iss": {
"values": "https://your-idp.com",
"matchType": "exact"
}
}
}
}
```
Users whose tokens don't match the required claim values receive an authorization error.
### Match Types
| Type | Description | Example |
| - | - | - |
| `exact` | Claim value must match exactly | `iss` must equal `"https://your-idp.com"` |
| `contains` | Claim must include at least one value (OR) | User must be in `engineering` OR `platform` group |
| `containsAll` | Claim must include all values (AND) | User must have both `mcp:read` AND `mcp:write` scopes |
| `regex` | Match against a regular expression | Email must match `@yourcompany\.com$` |
### Example: Restrict to Engineering Team
Only allow users in the engineering group:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"requiredClaims": ["sub", "groups"],
"claimValues": {
"groups": {
"values": ["engineering"],
"matchType": "contains"
}
}
}
}
```
### Example: Require Admin Role
Only allow users with admin role:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"claimValues": {
"role": {
"values": "admin",
"matchType": "exact"
}
}
}
}
```
### Example: Restrict by Email Domain
Only allow users from your company domain:
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"claimValues": {
"email": {
"values": "@yourcompany\\.com$",
"matchType": "regex"
}
}
}
}
```
See [JWT Validation](/docs/product/mcp-gateway/authentication/jwt) for complete configuration options.
***
## Tool-Level Authorization
> [!NOTE]
>
> Tool-level claim-based authorization is coming in a future release.
Fine-grained authorization at the tool level based on JWT claims. Control tool access by user attributes:
```json theme={"system"}
{
"tool_authorization": {
"delete_issue": {
"required_claims": {
"role": {
"values": ["admin", "maintainer"],
"matchType": "contains"
}
}
}
}
}
```
Enables scenarios like:
* Allow read tools for all users, write tools for specific roles
* Restrict dangerous operations to admins
* Enable different tool sets for different teams
***
## Webhooks for Authorization
> [!NOTE]
>
> Webhook-based authorization is coming in a future release.
Call your custom authorization service before each MCP request. Implement dynamic, context-aware access decisions.
```json theme={"system"}
{
"authorization_webhook": {
"url": "https://your-service.com/authorize",
"timeout_ms": 1000,
"on_error": "deny"
}
}
```
Your webhook will receive:
* User identity and claims
* Target MCP server
* Tool being called
* Request parameters
Return `allow` or `deny` with an optional reason.
Enables:
* Dynamic authorization based on external systems
* Context-aware decisions (time of day, request patterns)
* Integration with existing authorization infrastructure
* Custom business logic for access control
***
## Combining with Team Provisioning
Authorization works alongside [Team Provisioning](/docs/product/mcp-gateway/access-control):
1. **Team Provisioning** controls which workspaces see which servers
2. **JWT Validation** adds claim-based rules on top
A user must pass both checks to access an MCP server.
```
User Request
│
▼
┌─────────────────────────────┐
│ Team Provisioning Check │ Is server provisioned to user's workspace?
└─────────────────────────────┘
│ ✓
▼
┌─────────────────────────────┐
│ JWT Claim Validation │ Does token have required claims/values?
└─────────────────────────────┘
│ ✓
▼
Access Granted
```
***
## Next Steps
> [card] [JWT Validation](/docs/product/mcp-gateway/authentication/jwt)
>
> Configure claim validation for authorization.
> [card] [Team Provisioning](/docs/product/mcp-gateway/access-control)
>
> Control workspace access to MCP servers.
> [card] [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding)
>
> Pass user identity to MCP servers for downstream authorization.
> [card] [Tool Provisioning](/docs/product/mcp-gateway/tool-provisioning)
>
> Enable or disable specific tools.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Circuit Breakers
Source: https://docs.portkey.ai/docs/product/mcp-gateway/circuit-breakers
Automatic failure handling for upstream MCP servers.
> [!NOTE]
>
> This feature is coming soon. Contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) for early access.
Circuit breakers automatically detect unhealthy upstream MCP servers and fail fast to protect your agents.
## What's coming
* **Automatic detection.** Monitor failure rates and response times.
* **Fast failure.** Stop sending requests to unhealthy servers immediately.
* **Recovery checks.** Periodically test if servers have recovered.
* **Configurable thresholds.** Set failure rate and latency thresholds per server.
* **Status visibility.** See circuit state (closed, open, half-open) in the dashboard.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Add External MCP Servers
Source: https://docs.portkey.ai/docs/product/mcp-gateway/external-mcp-servers
Connect third-party MCP servers like Linear, GitHub, Slack, and more through Portkey.
External MCP servers are third-party services that expose their APIs through the MCP protocol. Linear, GitHub, Slack, Notion—these services offer MCP endpoints that your agents can use.
**Add external servers to Portkey.** Get centralized access control, logging, and credential management without building infrastructure.
***
## Why Use Portkey for External MCP Servers
* **Centralized credential management.** OAuth tokens for Linear, GitHub, Slack—all managed in one place. Users authenticate once, Portkey handles token refresh.
* **Team-based access control.** Control which teams can access which external services. Revoke access instantly without rotating credentials.
* **Full observability.** See exactly which tools your agents are calling, who's using them, and what data is flowing through.
* **Unified authentication.** Your agents authenticate to Portkey with a single API key. Portkey handles the complexity of OAuth flows with each external service.
***
## Architecture
```mermaid theme={"system"}
sequenceDiagram
participant User as User/Agent
participant PK as Portkey Gateway
participant MCP as External MCP Server
User->>PK: MCP Request + API Key
PK->>PK: Validate & check access
PK->>MCP: Forward request + OAuth token
MCP->>PK: Response
PK->>PK: Log interaction
PK->>User: Response
```
Two independent authentication layers:
| Layer | Purpose | Options |
| - | - | - |
| **Gateway** | User proves identity to Portkey | API Key, OAuth, External IdP |
| **Server** | Portkey authenticates to external service | OAuth 2.1, Client Credentials, Headers |
Users authenticate to Portkey. Portkey authenticates to external services. Users never see external service credentials.
***
## Setup
### Add to MCP Registry
Go to **MCP Registry** → **Add MCP Integration**.
| Field | Value |
| - | - |
| **Name** | Display name (e.g., "Linear") |
| **Slug** | URL identifier (e.g., `linear`) |
| **Server URL** | The service's MCP endpoint |
| **Auth Type** | Usually OAuth 2.1 for external services |
### Configure OAuth
Most external MCP servers use OAuth. Adding a server with OAuth:
1. Portkey registers as an OAuth client with the service
2. Users complete OAuth consent when they first use the server
3. Portkey stores and refreshes tokens automatically
Each user gets their own OAuth tokens. User A's Linear access is separate from User B's.
#### Servers with Dynamic Client Registration (DCR)
Many MCP servers support OAuth 2.1 with Dynamic Client Registration. For these servers, just select **OAuth 2.1** as the auth type—Portkey handles client registration automatically.
#### Servers Requiring Manual OAuth App Setup
Some services (like **GitHub**) don't support DCR. For these:
1. Create an OAuth App in the service's developer settings
2. Set the callback URL to `https://mcp.portkey.ai/oauth/upstream-callback`
3. Add the `client_id`, `client_secret`, and `redirect_uri` in Portkey's **Advanced Configuration**
See the [GitHub MCP server guide](/docs/integrations/mcp-servers/github-mcp-server#connect-via-portkey-mcp-gateway) for a detailed walkthrough.
### Provision Access
In **Access Control & Limits**, select which workspaces can access this server. Toggle per workspace or enable auto-provisioning for new workspaces.
### Connect
Users connect through Portkey:
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": ""
}
}
}
}
```
The API key determines permissions. When a user first calls a tool, Portkey initiates OAuth with the external service if needed.
***
## OAuth Flows
### Per-User OAuth
When an MCP server uses per-user OAuth:
1. User calls a tool through Portkey
2. If no token exists, Portkey returns an authorization URL
3. User completes OAuth consent
4. Portkey stores the token
5. Subsequent requests use the stored token
This flow is common for services with user-specific data (Linear issues, GitHub repos, Slack messages).
### Shared Credentials
Some servers use shared credentials via client credentials grant or API keys:
* **Client Credentials**: Portkey fetches tokens using client ID/secret
* **Headers**: Static API keys sent with every request
Use shared credentials for services without user-specific data or for uniform access across users.
***
## Governance
**Observability** — Every request logged with tool name, parameters, response, user, team, timestamp, latency, and status.
**Access control** — Control which teams access which external services. The model is subtractive—each level can only remove access.
**Tool provisioning** — Enable or disable specific tools. Allow read operations while blocking writes.
***
## Next Steps
> [card] [Authentication](/docs/product/mcp-gateway/authentication)
>
> Gateway auth and upstream server auth configuration.
> [card] [Team Provisioning](/docs/product/mcp-gateway/access-control)
>
> Manage team and user permissions.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Guardrails
Source: https://docs.portkey.ai/docs/product/mcp-gateway/guardrails
Apply security and compliance guardrails to MCP tool calls — regex filters, content validation, webhook checks, JSON schema enforcement, and more.
When AI agents invoke tools through MCP servers, sensitive data can flow in both directions — tool inputs may contain PII or restricted content, and tool outputs may return confidential data. MCP Guardrails let you intercept and enforce policies on `tools/call` requests at two stages:
| Stage | What it covers |
| - | - |
| **Input** | The arguments sent *to* the MCP tool |
| **Output** | The result returned *from* the MCP tool |
You can apply guardrails at the **workspace level** (default for all MCP servers in a workspace) or at the **server level** (targeting specific MCP servers and even individual tools).
***
## How It Works
MCP guardrails use the same policy engine as LLM guardrails, with the `target` field set to `mcp_tools`. This keeps MCP and LLM guardrails separate — existing LLM guardrails are unaffected.
Each guardrail consists of **checks** (the validation rules) and **actions** (what happens when a check fails). You then **map** the guardrail to one or more MCP servers, choosing whether it runs on tool inputs, outputs, or both.
When both workspace-level and server-level guardrails are configured, server-level guardrails are applied **in addition to** workspace defaults.
***
## Supported Checks
The following guardrail checks are available for MCP tool calls (`target: "mcp_tools"`):
| Check ID | Name | Description |
| - | - | - |
| `default.regexMatch` | Regex Match | Match patterns in tool inputs or outputs |
| `default.regexReplace` | Regex Replace | Match and replace patterns in tool data |
| `default.contains` | Contains | Check if content contains any, all, or none of specified words/phrases |
| `default.endsWith` | Ends With | Check if content ends with a specific string |
| `default.webhook` | Webhook | Send tool call data to an external service for custom validation |
| `default.jsonSchema` | JSON Schema | Validate tool input/output against a JSON schema |
| `default.jsonKeys` | JSON Keys | Check for required keys in JSON tool data |
| `default.sentenceCount` | Sentence Count | Enforce sentence count ranges |
| `default.wordCount` | Word Count | Enforce word count ranges |
| `default.characterCount` | Character Count | Enforce character count ranges |
| `default.containsCode` | Contains Code | Detect code (SQL, Python, TypeScript, etc.) in tool data |
| `default.validUrls` | Valid URLs | Validate that all URLs in tool data are well-formed |
| `default.isAllLowerCase` | Lowercase Check | Check if content is all lowercase |
| `default.alluppercase` | Uppercase Check | Check if content is all uppercase |
| `default.notNull` | Not Null | Ensure tool output is not null, undefined, or empty |
| `default.requiredMetadataKeys` | Required Metadata Keys | Check that metadata contains all required keys |
| `default.requiredMetadataKeyPairs` | Required Metadata Key-Value Pairs | Check for specific key-value pairs in metadata |
| `default.requestParametersCheck` | Request Parameters Check | Validate request parameters |
> [!NOTE]
>
> LLM-specific checks (PII detection, content moderation, language checks, and third-party provider checks like Patronus, Azure, Bedrock, etc.) are not available for MCP tool calls. Use the checks listed above for MCP guardrails.
***
## Key Concepts
### Target
Every guardrail has a `target` field:
| Target | Description |
| - | - |
| `llm` | Applied to LLM API requests (default, existing behavior) |
| `mcp_tools` | Applied to MCP tool calls |
When creating a guardrail for MCP, set `target` to `"mcp_tools"`.
### Run On
Each MCP server mapping includes a `run_on` field that controls *when* the guardrail executes:
| Value | Description |
| - | - |
| `input` | Run the guardrail on tool call **arguments** (before the tool executes) |
| `output` | Run the guardrail on tool call **results** (after the tool executes) |
You can set `run_on` to `["input"]`, `["output"]`, or `["input", "output"]` for both.
### Capability Scoping
By default, a guardrail mapping applies to **all tools** on an MCP server. To narrow the scope to specific tools, pass `mcp_integration_capability_ids` — an array of tool capability UUIDs. The guardrail will only run on calls to those specific tools.
***
## Workflow
### Step 1: Create an MCP Guardrail
Create a guardrail with `target: "mcp_tools"`. Unlike LLM guardrails, `checks` and `actions` are optional at creation time — you can configure them later.
```bash cURL theme={"system"}
curl -X POST "https://api.portkey.ai/v1/guardrails" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"name": "MCP Tool Content Filter",
"target": "mcp_tools",
"checks": [
{
"id": "default.regexMatch",
"parameters": {
"rule": "(?i)(password|secret|api_key)",
"onFail": "deny"
}
},
{
"id": "default.contains",
"parameters": {
"words": ["DROP TABLE", "DELETE FROM"],
"operator": "none",
"onFail": "deny"
}
}
],
"actions": {
"on_fail": "deny"
}
}'
```
**Response:**
```json theme={"system"}
{
"id": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
"slug": "pg-mcp-tool-content-filter-a1b2c3",
"version_id": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
"created_at": "2025-09-03T00:00:00.000Z",
"created_by": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx"
}
```
### Step 2: Map the Guardrail to MCP Servers
Attach the guardrail to one or more MCP servers. You can use either the **bulk sync** endpoint (replace all mappings at once) or the **single upsert** endpoint.
#### Bulk Sync (Recommended)
This is a declarative, idempotent operation — it replaces the full set of MCP server mappings for the guardrail.
```bash cURL theme={"system"}
curl -X PUT "https://api.portkey.ai/v1/guardrails/{guardrailId}/mcp-servers" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"mcp_servers": {
"": {
"run_on": ["input", "output"]
},
"": {
"run_on": ["input"],
"mcp_integration_capability_ids": [""]
}
}
}'
```
**Response:**
```json theme={"system"}
{
"changed": true,
"added": 2,
"updated": 0,
"removed": 0
}
```
#### Single Server Upsert
Map or update a guardrail for a single MCP server:
```bash cURL theme={"system"}
curl -X PUT "https://api.portkey.ai/v1/guardrails/{guardrailId}/mcp-servers/{mcpServerId}" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"run_on": ["input", "output"],
"mcp_integration_capability_ids": ["", ""]
}'
```
**Response:**
```json theme={"system"}
{
"map_id": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx"
}
```
### Step 3: Verify the Configuration
List all MCP server mappings for a guardrail:
```bash cURL theme={"system"}
curl "https://api.portkey.ai/v1/guardrails/{guardrailId}/mcp-servers" \
-H "x-portkey-api-key: $PORTKEY_API_KEY"
```
**Response:**
```json theme={"system"}
[
{
"id": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
"guardrail_id": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
"mcp_server_id": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
"run_on": ["input", "output"],
"capability_ids": ["xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx"]
}
]
```
### Workspace-Level Defaults
You can set MCP guardrails as workspace defaults so they apply to all MCP servers in a workspace. Configure `mcp_input_guardrails` and `mcp_output_guardrails` in your workspace settings.
***
## Blocked Request Response
When a guardrail blocks an MCP tool call, the gateway returns an MCP-compliant JSON-RPC error:
```json theme={"system"}
{
"jsonrpc": "2.0",
"id": 1,
"error": {
"code": -32446,
"message": "Request blocked by guardrail",
"data": {
"guardrail_id": "default.regexMatch",
"reason": "Input matched restricted pattern"
}
}
}
```
***
## API Reference
### Create Guardrail
Create a new guardrail. Set `target` to `"mcp_tools"` for MCP guardrails.
```
POST /v1/guardrails
```
| Field | Type | Required | Description |
| - | - | - | - |
| `name` | string | Yes | Display name for the guardrail |
| `target` | string | No | `"llm"` (default) or `"mcp_tools"` |
| `checks` | array | Conditional | Required for `llm` target; optional for `mcp_tools` |
| `actions` | object | Conditional | Required for `llm` target; optional for `mcp_tools` |
***
### List Guardrails
Retrieve guardrails with optional filtering by target.
```
GET /v1/guardrails
```
| Parameter | Type | Required | Description |
| - | - | - | - |
| `target` | string | No | Comma-separated: `"llm"`, `"mcp_tools"`, or both |
| `page_size` | integer | No | Results per page (default: 100) |
| `current_page` | integer | No | Page number (default: 0) |
| `search` | string | No | Search guardrails by name |
| `id` | string | No | Comma-separated guardrail IDs |
***
### Get Guardrail
Retrieve a single guardrail by ID or slug. For `mcp_tools` target guardrails, the response includes `mcp_server_mappings`.
```
GET /v1/guardrails/{guardrailId}
```
| Parameter | Type | Description |
| - | - | - |
| `guardrailId` | string | Guardrail UUID or slug (e.g., `pg-pii-filter-a1b2c3`) |
> [!NOTE]
>
> `mcp_server_mappings` is only included in the response when `target` is `"mcp_tools"`.
***
### Update Guardrail
Update a guardrail's name, checks, or actions.
```
PUT /v1/guardrails/{guardrailId}
```
| Field | Type | Description |
| - | - | - |
| `name` | string | Updated display name |
| `checks` | array | Updated checks configuration |
| `actions` | object | Updated actions configuration |
***
### Delete Guardrail
Archive a guardrail. This also removes all MCP server mappings.
```
DELETE /v1/guardrails/{guardrailId}
```
> [!WARNING]
>
> A guardrail cannot be deleted if it is currently used in workspace or organisation defaults (including `mcp_input_guardrails` and `mcp_output_guardrails`). Remove it from defaults first.
***
### Bulk Sync MCP Server Mappings
Declaratively sync all MCP server mappings for a guardrail. This replaces the entire set — servers not included in the request body are removed.
```
PUT /v1/guardrails/{guardrailId}/mcp-servers
```
**Request Body:**
| Field | Type | Required | Description |
| - | - | - | - |
| `mcp_servers` | object | Yes | Map of MCP server UUID → config |
| `mcp_servers.*.run_on` | string\[] | No | `["input"]`, `["output"]`, or `["input", "output"]` (default: `["input", "output"]`) |
| `mcp_servers.*.mcp_integration_capability_ids` | string\[] | No | Scope to specific tool capabilities |
**Validation rules:**
* The guardrail must have `target: "mcp_tools"`
* All MCP server IDs must be valid UUIDs
* `run_on` must be a non-empty array containing `"input"` and/or `"output"`
* All `mcp_integration_capability_ids` must exist in the database
***
### Upsert Single MCP Server Mapping
Create or update a guardrail mapping for a single MCP server.
```
PUT /v1/guardrails/{guardrailId}/mcp-servers/{mcpServerId}
```
| Field | Type | Required | Description |
| - | - | - | - |
| `run_on` | string\[] | No | `["input"]`, `["output"]`, or `["input", "output"]` (default: `["input", "output"]`) |
| `mcp_integration_capability_ids` | string\[] | No | Scope to specific tool capabilities |
***
### List MCP Server Mappings
List all MCP server mappings for a guardrail.
```
GET /v1/guardrails/{guardrailId}/mcp-servers
```
***
## Error Responses
| Status | Code | Description |
| - | - | - |
| `400` | `validation_failed` | Invalid request body or parameters |
| `401` | `unauthorized` | Missing or invalid API key |
| `403` | `forbidden` | Insufficient permissions or feature not enabled |
| `404` | `not_found` | Guardrail, MCP server, or capability not found |
| `500` | `server_error` | Internal server error |
***
## Next Steps
> [card] [Guardrail Checks](/docs/product/guardrails/list-of-guardrail-checks)
>
> Full list of available guardrail checks and parameters.
> [card] [Rate Limits](/docs/product/mcp-gateway/rate-limits)
>
> Throttle MCP tool call requests and token consumption.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Monitor MCP tool call logs and usage analytics.
> [card] [Access Control](/docs/product/mcp-gateway/access-control)
>
> Control which workspaces and users can access MCP servers.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Integrations
Source: https://docs.portkey.ai/docs/product/mcp-gateway/integrations
Connect MCP servers to AI agents and applications.
Portkey MCP Gateway works with any MCP client. Connect your agents using a URL and API key.
## Find your connection URL
Go to **MCP** in your workspace sidebar. Click on a server to see its connection details.
Each server has a URL:
```
https://mcp.portkey.ai/{server-slug}/mcp
```
Copy this URL to use in your agent configuration.
> [!NOTE]
>
> For self-hosted deployments, replace `mcp.portkey.ai` with your gateway URL.
## Claude Desktop
Add to your Claude Desktop config file.
**macOS:** `~/Library/Application Support/Claude/claude_desktop_config.json`
**Windows:** `%APPDATA%\Claude\claude_desktop_config.json`
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"
}
}
}
}
```
Restart Claude Desktop after saving. The tools appear in your conversation.
If the server uses OAuth, Claude prompts you to authenticate when you first use a tool.
## Cursor
Open **Cmd/Ctrl + Shift + P** > **Cursor Settings: Open MCP Settings**.
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"
}
}
}
}
```
The tools are available in Cursor's agent mode.
## VS Code
With GitHub Copilot and the MCP extension:
```json theme={"system"}
{
"mcp.servers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"
}
}
}
}
```
## Python
```bash theme={"system"}
pip install mcp
```
```python theme={"system"}
from mcp import ClientSession
from mcp.client.streamable_http import streamablehttp_client
url = "https://mcp.portkey.ai/linear/mcp"
headers = {"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"}
async with streamablehttp_client(url, headers=headers) as (read, write, _):
async with ClientSession(read, write) as session:
await session.initialize()
# List tools
tools = await session.list_tools()
for tool in tools.tools:
print(f"{tool.name}: {tool.description}")
# Call a tool
result = await session.call_tool(
"create_issue",
{"title": "Bug report", "priority": "high"}
)
print(result)
```
## TypeScript
```bash theme={"system"}
npm install @modelcontextprotocol/sdk
```
```typescript theme={"system"}
import { Client } from "@modelcontextprotocol/sdk/client/index.js";
import { StreamableHTTPClientTransport } from "@modelcontextprotocol/sdk/client/streamableHttp.js";
const transport = new StreamableHTTPClientTransport(
new URL("https://mcp.portkey.ai/linear/mcp"),
{
requestInit: {
headers: { "x-portkey-api-key": "YOUR_PORTKEY_API_KEY" }
}
}
);
const client = new Client({ name: "my-agent", version: "1.0.0" });
await client.connect(transport);
const tools = await client.listTools();
console.log(tools);
const result = await client.callTool({
name: "search_issues",
arguments: { query: "bug" }
});
console.log(result);
```
## API keys
Create API keys in **Settings > API Keys**. Keys are scoped to teams, so the key determines which MCP servers your agent can access.
> [!NOTE]
>
> When creating your workspace API key, ensure it has **MCP Invoke** permissions enabled.
## Handling OAuth
If an MCP server uses OAuth for per-user authentication, users need to complete OAuth consent before using tools.
The first time a user calls a tool, Portkey returns an error with an authorization URL. Redirect the user to complete OAuth. After consent, retry the request.
```python theme={"system"}
try:
result = await session.call_tool("get_repos", {})
except Exception as e:
if "authorization_url" in str(e):
# Redirect user to authorize
print(f"Please authorize: {authorization_url}")
```
After authorization, Portkey stores the user's tokens and handles refresh automatically.
## AI Gateway integration
If you use Portkey's AI Gateway for LLM calls, MCP integrates automatically:
* Unified dashboard for LLM and MCP activity
* Traces span model calls and tool use
* Single API key for both services
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Add Internal MCP Servers
Source: https://docs.portkey.ai/docs/product/mcp-gateway/internal-mcp-servers
Add your internal MCP servers to Portkey. Get enterprise-grade auth, access control, and logging without building it.
Your team has built MCP servers for internal docs, proprietary APIs, databases. Now you need authentication, access control, and logging for each one. Building that infrastructure is expensive. Maintaining it is harder.
**Add your internal servers to Portkey.** Get enterprise-grade infrastructure without writing a line of auth code.
***
## Why Use Portkey's MCP Gateway
* **Authentication without building auth.** Every MCP server needs it. Without Portkey, you build OAuth flows, validate tokens, manage sessions—for every server. With Portkey, authentication happens once at the gateway. Your servers receive authenticated requests.
* **User identity forwarding.** Your server often needs to know *who* is making a request. Portkey forwards user claims (email, team, roles) automatically. No OAuth implementation required.
* **Access control without deployments.** Control who accesses which servers and tools. When someone leaves a team, revoke access in Portkey. No code changes.
* **Full observability.** Every tool call logged—who called what, with what parameters, what was returned. Debug issues in minutes.
***
## Architecture
```mermaid theme={"system"}
sequenceDiagram
participant User as User/Agent
participant PK as Portkey Gateway
participant MCP as Your MCP Server
User->>PK: MCP Request + API Key
PK->>PK: Validate & check access
PK->>MCP: Forward request + user identity
MCP->>PK: Response
PK->>PK: Log interaction
PK->>User: Response
```
Two independent authentication layers:
| Layer | Purpose | Options |
| - | - | - |
| **Gateway** | User proves identity to Portkey | API Key, OAuth, External IdP |
| **Server** | Portkey authenticates to your server | OAuth Auto, API Key None, Headers |
Users authenticate to Portkey with SSO. Portkey authenticates to your server with an API key. Users never see your server's credentials.
***
## Setup
Your MCP server must be accessible over HTTP and implement MCP protocol over Streamable HTTP transport.
> [!NOTE]
>
> Using STDIO transport? Expose it as an HTTP endpoint first.
### Add to MCP Registry
Go to **MCP Registry** → **Add MCP Integration**.
| Field | Value |
| - | - |
| **Name** | Display name (e.g., "Internal Documentation") |
| **Slug** | URL identifier (e.g., `internal-docs`) |
| **Server URL** | Your server's MCP endpoint |
| **Auth Type** | How Portkey authenticates to your server |
For **Auth Type**: use `None` if your server is in a private network, `Headers` for API keys, or `OAuth Auto` for servers supporting OAuth 2.1.
### Configure Identity Forwarding
For servers that need to know who's making requests, add identity forwarding config in **Advanced Configuration**.
> [tab] JWT Header
>
> Portkey generates a signed JWT with user claims. Your server verifies using Portkey's public keys.
>
> ```json theme={"system"}
> {
> "user_identity_forwarding": {
> "method": "jwt_header",
> "include_claims": ["sub", "email", "workspace_id"],
> "header_name": "X-User-JWT"
> }
> }
> ```
>
> Verify the JWT using `GET https://mcp.portkey.ai/.well-known/jwks.json`
> [tab] Claims Header
>
> Portkey sends user claims as JSON. Simpler, no cryptographic verification.
>
> ```json theme={"system"}
> {
> "user_identity_forwarding": {
> "method": "claims_header",
> "include_claims": ["sub", "email", "workspace_id"],
> "header_name": "X-User-Claims"
> }
> }
> ```
> [tab] Bearer Passthrough
>
> Forwards the original token unchanged. Use when your server validates tokens from the same IdP.
>
> ```json theme={"system"}
> {
> "user_identity_forwarding": {
> "method": "bearer"
> }
> }
> ```
### Provision Access
In **Access Control & Limits**, select which workspaces can access this server. Toggle per workspace, enable auto-provisioning for new workspaces, or set tool-level permissions.
### Connect
Users connect through Portkey:
```json theme={"system"}
{
"mcpServers": {
"internal-docs": {
"url": "https://mcp.portkey.ai/internal-docs/mcp",
"headers": {
"x-portkey-api-key": ""
}
}
}
}
```
The API key determines permissions. Your server receives authenticated requests with user identity attached.
***
## Gateway Authentication
Three ways for users to authenticate to Portkey:
**Portkey OAuth 2.1** — For browser apps. If no API key provided, Portkey initiates an OAuth 2.1 flow with PKCE.
**External IdP (OAuth 2.0)** — Connect Okta, Azure AD, or Auth0. Users authenticate with corporate credentials.
**Portkey API Key** — Create keys in **Settings → API Keys**. Keys are scoped to workspaces.
```json theme={"system"}
{
"jwt_validation": {
"jwksUri": "https://your-idp.com/.well-known/jwks.json",
"algorithms": ["RS256"]
}
}
```
***
## Governance
**Observability** — Every request logged with tool name, parameters, response, user, team, timestamp, latency, and status. View in **Logs** with filters.
**Access control** — Three levels: Organization (which servers exist), Workspace (which teams access which servers), User (individual permissions). The model is subtractive—each level can only remove access.
**Tool provisioning** — Enable or disable specific tools at any level. Block dangerous operations org-wide, restrict write tools for read-only teams, phase out deprecated tools. Disabled tools don't appear in listings.
**Rate limits** — Coming soon. Control request volume per user, team, or server.
***
## Example: Documentation Server
Your company built an MCP server for querying internal docs.
**Add to registry:** Name it "Internal Documentation", slug `internal-docs`, point to your server URL, configure headers auth with your internal API key.
**Configure identity:** Enable claims header forwarding with `sub`, `email`, `workspace_id`.
**Provision access:** Enable for Engineering and Product workspaces.
**Developers connect:**
```json theme={"system"}
{
"mcpServers": {
"docs": {
"url": "https://mcp.portkey.ai/internal-docs/mcp",
"headers": { "x-portkey-api-key": "pk_xxx" }
}
}
}
```
Developers use their Portkey API key. Your server receives user identity. Every query appears in Portkey logs. Access control managed centrally—no server changes needed.
***
## Next Steps
> [card] [Authentication](/docs/product/mcp-gateway/authentication)
>
> Gateway auth and upstream server auth configuration.
> [card] [Team Provisioning](/docs/product/mcp-gateway/access-control)
>
> Manage team and user permissions.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# MCP Registry
Source: https://docs.portkey.ai/docs/product/mcp-gateway/mcp-registry
Add, manage, and govern MCP servers across your organization.
The MCP Registry is the central catalog of all MCP server integrations in your organization. Organization admins add servers here, configure authentication, and control which teams can access them.

> [!NOTE]
>
> **Developer note:** Most developers won't add servers here. After an org admin provisions a server, use it from the **workspace MCP page** to copy the connection URL and test tools.
The MCP Registry supports:
* Adding MCP servers (from catalog or custom URL)
* Configuring authentication for each server
* Viewing connection status and health metrics
* Controlling which teams access which servers
* Managing capabilities (tools, resources, prompts) per server
> [card] [Quickstart](/docs/product/mcp-gateway/quickstart)
>
> New to MCP Gateway? Add your first server in 5 minutes.
> [card] [Registry API (Beta)](/docs/product/mcp-gateway/registry-api)
>
> Serve this catalog to governance-aware MCP clients as standard `server.json`.
***
## Adding Servers
Click **MCP Registry** in the sidebar, then click **Add MCP Server**.
| Field | Description |
| - | - |
| Name | Display name for the server |
| Slug | URL-friendly identifier (e.g., `linear`, `internal-api`) |
| Server URL | MCP endpoint (e.g., `https://mcp.linear.app/mcp`) |
| Server Type | `HTTP` for remote servers |
| Auth Type | Authentication method (see below) |
> [!NOTE]
>
> Portkey supports remote MCP servers over HTTP. Local STDIO servers need to be exposed as HTTP endpoints first.
***
## Authentication
> [!NOTE]
>
> This section covers how Portkey authenticates to **upstream MCP servers**. For how your agents and MCP clients authenticate to Portkey, see [Gateway Authentication](/docs/product/mcp-gateway/authentication).
When adding a server, choose the auth method based on what the MCP server supports:
| Auth Type | When to Use |
| - | - |
| **None** | Public servers with no authentication required |
| **OAuth 2.1** | Servers with user-level OAuth. Each user gets their own tokens. |
| **Client Credentials** | Servers using OAuth client credentials. Shared across users. |
| **Headers** | Servers using API keys or static tokens. |
**Quick summary:**
* **OAuth (user-level)**: Each user authorizes their own access. Use for servers with user-specific data (Linear, GitHub, Slack).
* **Client Credentials**: Shared OAuth tokens. Use for service accounts or shared resources.
* **Headers**: Static API keys sent with every request. Use for simple token-based auth.
> [card] [Authentication Deep Dive](/docs/product/mcp-gateway/authentication)
>
> Gateway authentication, external OAuth, identity forwarding, JWT validation, and more.
***
## Access Control
Access control for MCP servers happens at two levels.
## Organization-level (MCP Registry)
> [!NOTE]
>
> Requires **Org Admin** or **Org Owner** role.
Control which workspaces can access an MCP server:
1. Click **MCP Registry** in the sidebar
2. Click on an MCP server
3. Open the **Access Control** tab
4. Toggle workspaces on/off

Enable **Automatically provision this integration for new workspaces** to include future workspaces by default.
## Workspace-level (MCP Servers)
> [!NOTE]
>
> Requires **Workspace Manager** or **Workspace Admin** role.
Control which users in your workspace can access an MCP server:
1. Go to **MCP** page in your workspace sidebar
2. Click on an MCP server
3. Use the **User Access** tab to toggle user access on/off

***
## Tool Provisioning
The **Capabilities** tab lists all tools, resources, and prompts exposed by an MCP server. Toggle them on or off, or use **Enable All** / **Disable All** for bulk changes.

Tool provisioning can be done at two levels:
| Location | Who | Scope |
| - | - | - |
| **MCP Registry** → Server → Capabilities | Org Admins/Owners | Organization-wide |
| **MCP Servers** → Server → Capabilities | Workspace Managers/Admins | Workspace-only |
Disabled capabilities are hidden and return errors if called directly. Use this to block dangerous operations, untested tools, or deprecated functionality.
***
## Server Overview
Once added, each server has a detail page with four tabs: **Overview**, **Capabilities**, **Setup & Code**, and **Access Control & Limits**.

**Overview tab** shows:
* **Server Status**: Health score, uptime, average response time, total requests
* **Security & Authentication**: Auth type, grant type, transport protocol
* **Configuration**: Server URL, version, connection details
***
## Next Steps
> [card] [Add Internal MCP Servers](/docs/product/mcp-gateway/internal-mcp-servers)
>
> Connect your own MCP servers with enterprise auth, access control, and logging.
> [card] [Integrations](/docs/product/mcp-gateway/integrations)
>
> Setup guides for Claude Desktop, Cursor, Python SDK, TypeScript SDK, and more.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Monitor MCP traffic, debug issues, track usage.
> [card] [Guardrails](/docs/product/mcp-gateway/guardrails)
>
> Apply rate limits, content filtering, and approval workflows.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Observability
Source: https://docs.portkey.ai/docs/product/mcp-gateway/observability
Log, monitor, and debug MCP interactions.
Every MCP request through the gateway is logged automatically. No setup required.
## What gets logged
Each request captures:
| Field | Description |
| - | - |
| Tool | Which tool was called |
| Parameters | Request payload |
| Response | Full response data |
| User | Who made the request |
| Team | Which team (workspace) |
| Timestamp | When it happened |
| Latency | How long it took |
| Status | Success or error |
| MCP Server | Which upstream server |
## View logs
Go to **Logs** in the dashboard. Filter by:
* MCP server
* Team
* User
* Tool name
* Time range
* Status (success/error)
Click any entry for full details: the exact request parameters sent, the response received, and timing breakdown.
## Usage analytics
The dashboard shows aggregate metrics:
* Requests over time
* Requests by server
* Requests by team
* Requests by user
* Error rates
* Latency percentiles
* Most used tools
Use these to understand adoption patterns. Which tools are popular? Which teams are using MCP the most? Are error rates increasing?
## Debugging
When something breaks, logs tell you exactly what happened.
**Tool returning errors?** Check the response data. The MCP server's error message is captured.
**Wrong results?** Check the parameters. Maybe the agent sent incorrect arguments.
**Slow responses?** Check the latency breakdown. Is it the MCP server or the network?
**Access denied?** Check the user and team. Do they have permission for this tool?
A typical debugging flow:
1. Filter logs by the user who reported the issue
2. Find the failing request
3. Check parameters and response
4. Identify the root cause
## Metadata
Each request includes rich context from authentication, available for both API key and OAuth flows:
| Field | Description |
| - | - |
| `organisation_id` | Organization identifier |
| `organisation_name` | Organization display name |
| `workspace_id` | Workspace identifier |
| `workspace_name` | Workspace display name |
| `workspace_slug` | Workspace slug |
| `user_id` | User identifier |
| `api_key_id` | API key identifier (if using API key auth) |
| `mcp_server_id` | Which MCP server handled the request |
| `mcp.auth.type` | Authentication method (`api_key` or `Bearer`) |
This metadata enables:
* Per-user usage tracking
* Per-team cost allocation
* Compliance auditing
* Chargeback reporting
* Authentication flow analysis
## Forward metadata to MCP servers
Use [Identity Forwarding](/docs/product/mcp-gateway/authentication/identity-forwarding) to send user context to MCP servers.
The MCP server receives information about who made the request. It can then:
* Log with Portkey context
* Enforce its own access controls
* Personalize responses
* Attribute actions to users
## Integration with AI Gateway
For Portkey AI Gateway users, MCP logs integrate with existing observability:
* Traces span LLM calls and tool use
* Single dashboard for agent activity
* Correlate tool calls with model outputs
* See the full picture of what your agents are doing
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Quickstart
Source: https://docs.portkey.ai/docs/product/mcp-gateway/quickstart
Add DeepWiki to Portkey MCP Gateway and connect it to Claude.
This quickstart covers:
1. Adding the DeepWiki MCP server to your organization's MCP Registry
2. Getting your MCP connection URL from your workspace
3. Using the URL in Claude (Desktop / Code) via MCP configuration
> [!NOTE]
>
> **Who does what:** MCP integrations can be added by **org admin and members**. The MCP server can be used by **workspace admin, manager, and members**.
***
## 1) Add DeepWiki to MCP Registry
**1. Open MCP Registry**
Go to **MCP Registry** in your org settings, then click **Add Server**.

**2. Fill in the server details**
Enter the following:
| Field | Value |
| - | - |
| **Name** | `deepwiki-test-mcp-server` |
| **Short Description** | A short note about the MCP Integration |
| **URL** | `https://mcp.deepwiki.com/mcp` |
| **Slug** | `deepwiki-test-mcp-server` |
| **Server Type** | Http |
| **Auth Type** | None |
> [!NOTE]
>
> DeepWiki is a public MCP server that doesn't require authentication, so set **Auth Type** to `None`. Learn more about [DeepWiki MCP](https://docs.devin.ai/work-with-devin/deepwiki-mcp).
The form includes **Workspace Provisioning** settings. Select the workspace(s) that should have access to this MCP server.

**3. Test & save**
Click **Test Connection**, then **Add Server**.
***
## 2) Get Your Connection URL
Once enabled, go to the **MCP** page in your workspace sidebar and copy the DeepWiki connection URL.

The URL will look like:
```
https://mcp.portkey.ai/deepwiki-test-mcp-server/mcp
```
***
## 3) Use the URL in Claude (Desktop / Code)
Add a new MCP server that points to the Portkey URL. You have two authentication options:
> [tab] OAuth (Recommended)
>
> The simplest setup—just the URL, no credentials to manage:
>
> ```json theme={"system"}
> {
> "mcpServers": {
> "deepwiki": {
> "url": "https://mcp.portkey.ai/deepwiki-test-mcp-server/mcp"
> }
> }
> }
> ```
>
> On first use, Claude will prompt you to authenticate with Portkey via OAuth 2.1. After you log in, your session is stored and refreshed automatically.
>
> > [!NOTE]
> >
> > **Best for:** Interactive use in Claude Desktop, Cursor, or VS Code. No API keys to create, rotate, or accidentally leak.
> [tab] API Key
>
> For programmatic access or when you prefer explicit credentials:
>
> ```json theme={"system"}
> {
> "mcpServers": {
> "deepwiki": {
> "url": "https://mcp.portkey.ai/deepwiki-test-mcp-server/mcp",
> "headers": {
> "x-portkey-api-key": ""
> }
> }
> }
> }
> ```
>
> Get your Portkey API key at [app.portkey.ai/api-keys](https://app.portkey.ai/api-keys). Use a **workspace user API key** with **`mcp invoke`** permissions.
>
> > [!NOTE]
> >
> > When creating your workspace API key, ensure it has **MCP Invoke** permissions enabled.
>
> > [!NOTE]
> >
> > **Best for:** CI/CD pipelines, backend services, or automated agents where interactive OAuth isn't possible.
> [!NOTE]
>
> Even though DeepWiki doesn't require authentication to the upstream server, you still need to authenticate with Portkey (via OAuth or API key) to access the server through the gateway.
***
## Next Steps
> [card] [Add MCP Servers](/docs/product/mcp-gateway/internal-mcp-servers)
>
> Add internal and external MCP servers, configure authentication, and control access.
> [card] [Using MCP Servers](/docs/product/mcp-gateway/using-mcp-servers)
>
> Connect MCP clients like Cursor, VS Code, Claude Desktop, or build your own integration.
> [card] [Team Provisioning](/docs/product/mcp-gateway/access-control)
>
> Control which teams and users can access which MCP servers and tools.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Monitor and debug MCP tool calls with full context and logs.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Rate Limits
Source: https://docs.portkey.ai/docs/product/mcp-gateway/rate-limits
Throttle MCP tool call requests and token consumption per API key, server, or tool.
> [!NOTE]
>
> Requires **Gateway v2.18.0+** and **Backend v1.24.0+**.
Rate limits control the volume of MCP tool calls across your organization. You can limit by request count or token consumption, scoped to specific servers, tools, or API keys.
MCP rate limits use the same policy engine as LLM rate limits, with a new `target` field set to `mcp_tools`. This keeps MCP and LLM policies separate — existing LLM rate limits are unaffected.
***
## How It Works
MCP rate limit policies are workspace-scoped. When a tool call comes through the MCP Gateway, Portkey checks all active `mcp_tools` rate limit policies for that workspace. If any policy's limit has been reached, the request is rejected with a rate limit error.
Policies support two limit types:
* **Requests** — Limit the number of tool calls (per minute, hour, or day)
* **Tokens** — Limit token consumption (per minute, hour, or day)
***
## Supported Condition and Group-By Keys
Conditions determine **which requests** a policy applies to. Group-by keys determine **how limits are bucketed** — each unique combination gets its own counter.
| Key | Description | Example Value |
| - | - | - |
| `api_key` | Match by API key ID | `"uuid_of_api_key"` |
| `workspace_id` | Match by workspace ID | `"workspace_uuid"` |
| `mcp_server` | Match by MCP server slug | `"slack"`, `"github"` |
| `mcp_tool` | Match by tool name | `"send_message"`, `"create_issue"` |
| `metadata.*` | Match by request metadata | `"metadata._user"` with value `"user123"` |
> [!WARNING]
>
> `api_key` is not available in OAuth-based MCP flows, since those requests are authenticated via identity provider tokens and do not carry an API key. Use `mcp_server`, `mcp_tool`, or `metadata.*` keys instead.
### Conditions
Conditions filter which requests a policy applies to. All conditions must match (AND logic). Each condition supports:
| Field | Type | Description |
| - | - | - |
| `key` | string | The dimension to match against |
| `value` | string \| string\[] | Value(s) to match (OR logic for arrays). Use `"*"` for wildcard. |
| `excludes` | string \| string\[] | Value(s) to exclude from matching |
### Group-By
Group-by keys determine how limits are tracked independently. For example, grouping by `api_key` means each API key gets its own counter — one key hitting the limit doesn't affect others.
***
## Rate Limit Units
| Unit | Description |
| - | - |
| `rpm` | Requests/Tokens per minute |
| `rph` | Requests/Tokens per hour |
| `rpd` | Requests/Tokens per day |
| `rpw` | Requests/Tokens per week |
***
## Use Cases
### Use Case 1: Global MCP Rate Limit
Limit all MCP tool calls in a workspace to 500 requests per minute.
```json theme={"system"}
{
"name": "Global MCP rate limit",
"target": "mcp_tools",
"type": "requests",
"unit": "rpm",
"value": 500,
"conditions": [
{ "key": "api_key", "value": "*" }
],
"status": "active"
}
```
***
### Use Case 2: Per-User MCP Rate Limit
Limit each user (identified by `_user` metadata) to 50 MCP tool calls per minute.
```json theme={"system"}
{
"name": "Per-user MCP rate limit",
"target": "mcp_tools",
"type": "requests",
"unit": "rpm",
"value": 50,
"conditions": [
{ "key": "metadata._user", "value": "*" }
],
"group_by": [
{ "key": "metadata._user" }
],
"status": "active"
}
```
***
### Use Case 3: Per-Server Rate Limit
Cap total throughput to the Slack MCP server to 1000 requests per hour.
```json theme={"system"}
{
"name": "Slack server rate limit",
"target": "mcp_tools",
"type": "requests",
"unit": "rph",
"value": 1000,
"conditions": [
{ "key": "mcp_server", "value": "slack" }
],
"status": "active"
}
```
***
### Use Case 4: Limit a Specific Tool
Throttle the `send_message` tool to 100 calls per minute, regardless of which server it's on.
```json theme={"system"}
{
"name": "send_message rate limit",
"target": "mcp_tools",
"type": "requests",
"unit": "rpm",
"value": 100,
"conditions": [
{ "key": "mcp_tool", "value": "send_message" }
],
"status": "active"
}
```
***
### Use Case 5: Per-Server Token Limit
Limit token consumption on the GitHub MCP server to 500,000 tokens per day.
```json theme={"system"}
{
"name": "GitHub server token limit",
"target": "mcp_tools",
"type": "tokens",
"unit": "tpd",
"value": 500000,
"conditions": [
{ "key": "mcp_server", "value": "github" }
],
"status": "active"
}
```
***
### Use Case 6: Per-API-Key Limits Grouped by Server
Give each API key its own rate limit, tracked independently per MCP server.
```json theme={"system"}
{
"name": "Per-key per-server MCP limit",
"target": "mcp_tools",
"type": "requests",
"unit": "rpm",
"value": 100,
"conditions": [
{ "key": "api_key", "value": "*" }
],
"group_by": [
{ "key": "api_key" },
{ "key": "mcp_server" }
],
"status": "active"
}
```
***
### Use Case 7: Per-Team Rate Limit by Server
Track and limit MCP usage separately for each team and server combination.
```json theme={"system"}
{
"name": "Per-team per-server MCP limit",
"target": "mcp_tools",
"type": "requests",
"unit": "rph",
"value": 500,
"conditions": [
{ "key": "metadata._team", "value": "*" }
],
"group_by": [
{ "key": "metadata._team" },
{ "key": "mcp_server" }
],
"status": "active"
}
```
***
### Use Case 8: Exclude Specific Tools from a Server Limit
Apply rate limit to all Slack tools except `list_channels`.
```json theme={"system"}
{
"name": "Slack tools limit (excluding list_channels)",
"target": "mcp_tools",
"type": "requests",
"unit": "rpm",
"value": 200,
"conditions": [
{ "key": "mcp_server", "value": "slack" },
{ "key": "mcp_tool", "value": "*", "excludes": "list_channels" }
],
"status": "active"
}
```
***
## Creating a Policy
You can create MCP rate limit policies from the Portkey UI or via the Admin API.

Use the Admin API to create a rate limit policy with `target` set to `mcp_tools`.
```bash cURL theme={"system"}
curl -X POST "https://api.portkey.ai/v1/policies/rate-limits" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"name": "Slack send_message limit",
"description": "Throttle send_message calls on the Slack MCP server",
"target": "mcp_tools",
"type": "requests",
"unit": "rpm",
"value": 100,
"conditions": [
{ "key": "mcp_tool", "value": "send_message" }
],
"group_by": [
{ "key": "api_key" }
]
}'
```
***
## Key Considerations
* **Target is immutable.** A policy's `target` cannot be changed after creation. To switch between `llm` and `mcp_tools`, archive the existing policy and create a new one.
* **Existing policies are unaffected.** All existing rate limit policies default to `target: llm`. No migration is needed.
* **OAuth flows and `api_key`.** The `api_key` condition and group-by key is not available in OAuth-based MCP flows. Use `mcp_server`, `mcp_tool`, `workspace_id`, or `metadata.*` instead.
* **Workspace-scoped only.** MCP rate limit policies are scoped to the workspace level. Org-wide MCP policies are not supported in this release.
***
## Exceeding Rate Limits
When a rate limit is exceeded, Portkey returns a **429 Too Many Requests** HTTP status code.
* The error message indicates which limit was exceeded
* The limit resets automatically after the configured time interval
***
## Next Steps
> [card] [Usage & Rate Limit Policies](/docs/product/enterprise-offering/budget-policies)
>
> Full policy reference with conditions, group-by, and validation rules.
> [card] [Rate Limits API](/docs/api-reference/admin-api/control-plane/policies/rate-limits/create-rate-limits-policy)
>
> API reference for creating and managing rate limit policies.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Monitor MCP tool call logs and usage analytics.
> [card] [Access Control](/docs/product/mcp-gateway/access-control)
>
> Control which workspaces and users can access MCP servers.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Registry API (Beta)
Source: https://docs.portkey.ai/docs/product/mcp-gateway/registry-api
Serve your approved MCP servers as a standards-compliant catalog that governance-aware clients can consume.
> [!WARNING]
>
> This API is in beta. The response format follows MCP Registry `v0.1` and may change as the upstream spec evolves.
The Registry API serves every MCP server approved in your organization as a catalog in the standard [MCP Registry](https://github.com/modelcontextprotocol/registry) `server.json` format.
Point a governance-aware MCP client at this endpoint to restrict users to an approved set of servers. Anything outside the catalog is blocked by the client.
> [!NOTE]
>
> This is the machine-readable counterpart to the [MCP Registry](/docs/product/mcp-gateway/mcp-registry) dashboard. Admins approve servers in the UI; this endpoint serves that same list to clients.
***
## Endpoint
```bash theme={"system"}
GET https://mcp.portkey.ai/v0.1/servers
```
Authenticate with the `x-portkey-api-key` header. The key needs the `mcp_servers.list` scope.
```sh cURL theme={"system"}
curl https://mcp.portkey.ai/v0.1/servers \
-H "x-portkey-api-key: $PORTKEY_API_KEY"
```
```python Python theme={"system"}
import requests
resp = requests.get(
"https://mcp.portkey.ai/v0.1/servers",
headers={"x-portkey-api-key": PORTKEY_API_KEY}
)
catalog = resp.json()
```
```js JavaScript theme={"system"}
const resp = await fetch("https://mcp.portkey.ai/v0.1/servers", {
headers: { "x-portkey-api-key": PORTKEY_API_KEY }
})
const catalog = await resp.json()
```
> [!NOTE]
>
> The header is the only accepted credential. Bearer tokens and query-parameter API keys are not supported on this endpoint.
For self-hosted deployments, swap the host for your own MCP Gateway URL:
```bash theme={"system"}
GET https:///v0.1/servers
```
The registry is part of the MCP Gateway itself, not a separate service. Any deployment that serves MCP traffic also serves its own catalog.
***
## Query parameters
**limit** `integer` (default: 50)
Number of servers per page. Range `1`–`100`.
**cursor** `string`
Opaque pagination cursor. Pass the `nextCursor` from the previous response.
**search** `string`
Case-insensitive substring match on the server name.
**updated\_since** `string`
ISO 8601 timestamp. Returns only servers modified after this time. Use it for incremental syncs.
**workspace\_id** `string`
Workspace UUID or slug (`ws-acme-corp`). Narrows an org-wide key to a single workspace.
***
## Response
```json theme={"system"}
{
"servers": [
{
"server": {
"$schema": "https://static.modelcontextprotocol.io/schemas/2025-12-11/server.schema.json",
"name": "ai.portkey.ws-acme-corp/github-tools",
"title": "GitHub Tools",
"description": "Code search and PR management",
"version": "1.2.0",
"websiteUrl": "https://github.com",
"remotes": [
{
"type": "streamable-http",
"url": "https://mcp.portkey.ai/github-tools/mcp"
}
]
},
"_meta": {
"io.portkey.ai/registry": {
"publishedAt": "2025-11-01T08:30:00.000Z",
"updatedAt": "2026-02-15T14:22:00.000Z",
"isLatest": true
}
}
}
],
"metadata": {
"count": 1,
"nextCursor": "MjAyNS0xMS0wMVQwODozMDowMC4wMDBafGFiYzEyMw"
}
}
```
### Field reference
| Field | Description |
| - | - |
| `name` | Unique identifier, built as `ai.portkey.{workspace-slug}/{server-slug}` |
| `title` | Display name from the upstream server, falling back to the name set in Portkey |
| `description` | Description from the upstream server, falling back to the one set in Portkey |
| `version` | Version reported by the upstream MCP server. Defaults to `0.0.0` when the server doesn't report one |
| `remotes[].url` | Portkey Gateway URL for the server. Clients connect here, not to the upstream server |
| `remotes[].type` | Always `streamable-http` |
| `websiteUrl`, `icons` | Included only when the upstream server reports them |
| `_meta` | Portkey extensions: `publishedAt`, `updatedAt`, and `isLatest` |
| `metadata.count` | Number of servers in this page, not the org-wide total |
| `metadata.nextCursor` | Present only when more pages exist |
> [!NOTE]
>
> `remotes[].url` always points at the Portkey Gateway. Traffic keeps flowing through Portkey, so access control, guardrails, rate limits, and logging still apply.
***
## Pagination
Results are cursor-paginated and sorted newest-first. When `metadata.nextCursor` is present, pass it back as `cursor` to fetch the next page. When it's absent, the catalog is fully read.
```python theme={"system"}
servers, cursor = [], None
while True:
params = {"limit": 100}
if cursor:
params["cursor"] = cursor
page = requests.get(
"https://mcp.portkey.ai/v0.1/servers",
headers={"x-portkey-api-key": PORTKEY_API_KEY},
params=params
).json()
servers.extend(page["servers"])
cursor = page["metadata"].get("nextCursor")
if not cursor:
break
```
Treat the cursor as opaque. Don't construct or parse it — an unrecognized cursor returns `400`.
***
## Which servers appear
The catalog reflects what admins approved in the dashboard. A server is listed only when the server, its integration, its workspace, and the workspace's access grant are all active. Archived servers and revoked workspace access disappear from the catalog automatically.
Scope follows the API key:
| Key type | Servers returned |
| - | - |
| Organization (admin) | Every approved server across all workspaces in the org |
| Workspace | Only servers approved for that workspace |
Add `workspace_id` to narrow an organization key to a single workspace. A workspace key can't read a workspace other than its own.
> [!NOTE]
>
> Use an organization key to publish one catalog covering the whole company. Use workspace keys to give each team a catalog scoped to what they're entitled to.
***
## Serving the catalog to static-URL clients
Some governance-aware clients fetch their registry from a plain HTTPS URL and can't attach custom headers. Because this endpoint requires `x-portkey-api-key`, put a small proxy in front of it:
**1. Fetch the catalog**
Call the Registry API with your API key from a scheduled job.
**2. Publish the JSON**
Write the response to a static HTTPS location — S3, nginx, or any web server the client can reach.
**3. Point the client at it**
Configure the client's registry URL to your static endpoint.
**4. Refresh on a schedule**
Re-run the job on the client's sync interval. Use `updated_since` to pull only what changed.
This keeps the API key server-side and never exposes it to end users.
***
## Errors
| Status | Cause |
| - | - |
| `400` | Invalid query parameter, or an unrecognized `cursor` |
| `401` | Missing or invalid `x-portkey-api-key` |
| `403` | Key lacks the `mcp_servers.list` scope, or requests a workspace it can't access |
| `404` | `workspace_id` doesn't exist |
***
## Next steps
> [card] [MCP Registry](/docs/product/mcp-gateway/mcp-registry)
>
> Approve servers, configure auth, and manage the catalog from the dashboard.
> [card] [Team Provisioning](/docs/product/mcp-gateway/access-control)
>
> Control which workspaces see which servers.
> [card] [Using MCP Servers](/docs/product/mcp-gateway/using-mcp-servers)
>
> Connect clients to servers from the catalog.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Monitor MCP traffic and usage.
# Tool Provisioning
Source: https://docs.portkey.ai/docs/product/mcp-gateway/tool-provisioning
Control which tools, resources, and prompts are available to your organization and workspaces.
The **Capabilities** tab lists all tools, resources, and prompts exposed by an MCP server. Toggle them on or off, or use **Enable All** / **Disable All** for bulk changes.

Tool provisioning can be done at two levels:
| Location | Who | Scope |
| - | - | - |
| **MCP Registry** → Server → Capabilities | Org Admins/Owners | Organization-wide |
| **MCP Servers** → Server → Capabilities | Workspace Managers/Admins | Workspace-only |
Disabled capabilities are hidden and return errors if called directly. Use this to block dangerous operations, untested tools, or deprecated functionality.
***
## Next Steps
> [card] [Team Provisioning](/docs/product/mcp-gateway/access-control)
>
> Control which teams and users can access MCP servers.
> [card] [Guardrails](/docs/product/mcp-gateway/guardrails)
>
> Apply rate limits, content filtering, and approval workflows.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Using MCP Servers
Source: https://docs.portkey.ai/docs/product/mcp-gateway/using-mcp-servers
Connect to MCP servers from AI agents and applications.
After an admin provisions MCP servers to your workspace, connect from any MCP client—Claude Desktop, Cursor, VS Code, or custom applications.
## Find your connection URL
Go to **MCP** in your workspace sidebar. Click on a server to see its connection details.
Each server has a URL:
```
https://mcp.portkey.ai/{server-slug}/mcp
```
Copy this URL to use in your agent configuration.
> [!NOTE]
>
> For self-hosted deployments, replace `mcp.portkey.ai` with your gateway URL.
***
## MCP Clients
### Claude Desktop
Add to your Claude Desktop config file.
**macOS:** `~/Library/Application Support/Claude/claude_desktop_config.json`
**Windows:** `%APPDATA%\Claude\claude_desktop_config.json`
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"
}
}
}
}
```
Restart Claude Desktop after saving. The tools appear in your conversation.
For OAuth-enabled servers, Claude prompts for authentication on first tool use.
### Cursor
Open **Cmd/Ctrl + Shift + P** > **Cursor Settings: Open MCP Settings**.
```json theme={"system"}
{
"mcpServers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"
}
}
}
}
```
The tools are available in Cursor's agent mode.
### VS Code
With GitHub Copilot and the MCP extension:
```json theme={"system"}
{
"mcp.servers": {
"linear": {
"url": "https://mcp.portkey.ai/linear/mcp",
"headers": {
"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"
}
}
}
}
```
***
## Transport
MCP Gateway uses **HTTP Streamable** transport for all connections. This is the standard MCP transport that supports bidirectional communication over HTTP.
> [!NOTE]
>
> Sessions are ephemeral—each request is independent. There's no session persistence between requests, which simplifies scaling and removes the need for sticky sessions.
***
## SDKs
### Python
```bash theme={"system"}
pip install mcp
```
```python theme={"system"}
from mcp import ClientSession
from mcp.client.streamable_http import streamablehttp_client
url = "https://mcp.portkey.ai/linear/mcp"
headers = {"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"}
async with streamablehttp_client(url, headers=headers) as (read, write, _):
async with ClientSession(read, write) as session:
await session.initialize()
# List tools
tools = await session.list_tools()
for tool in tools.tools:
print(f"{tool.name}: {tool.description}")
# Call a tool
result = await session.call_tool(
"create_issue",
{"title": "Bug report", "priority": "high"}
)
print(result)
```
### TypeScript
```bash theme={"system"}
npm install @modelcontextprotocol/sdk
```
```typescript theme={"system"}
import { Client } from "@modelcontextprotocol/sdk/client/index.js";
import { StreamableHTTPClientTransport } from "@modelcontextprotocol/sdk/client/streamableHttp.js";
const transport = new StreamableHTTPClientTransport(
new URL("https://mcp.portkey.ai/linear/mcp"),
{
requestInit: {
headers: { "x-portkey-api-key": "YOUR_PORTKEY_API_KEY" }
}
}
);
const client = new Client({ name: "my-agent", version: "1.0.0" });
await client.connect(transport);
const tools = await client.listTools();
console.log(tools);
const result = await client.callTool({
name: "search_issues",
arguments: { query: "bug" }
});
console.log(result);
```
***
## API Keys
Create API keys in **Settings > API Keys**. Keys are scoped to workspaces, so the key determines which MCP servers your agent can access.
> [!NOTE]
>
> When creating your workspace API key, ensure it has **MCP Invoke** permissions enabled.
***
## Handling OAuth
MCP servers with OAuth require users to complete consent before using tools.
The first time a user calls a tool, Portkey returns an error with an authorization URL. Redirect the user to complete OAuth. After consent, retry the request.
```python theme={"system"}
try:
result = await session.call_tool("get_repos", {})
except Exception as e:
if "authorization_url" in str(e):
# Redirect user to authorize
print(f"Please authorize: {authorization_url}")
```
After authorization, Portkey stores the user's tokens and handles refresh automatically.
***
## AI Gateway Integration
For Portkey AI Gateway users, MCP integrates automatically:
* Unified dashboard for LLM and MCP activity
* Traces span model calls and tool use
* Single API key for both services
***
## Next Steps
> [card] [Authentication](/docs/product/mcp-gateway/authentication)
>
> Authentication options for MCP Gateway.
> [card] [Observability](/docs/product/mcp-gateway/observability)
>
> Monitor MCP traffic and debug issues.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Model Catalog
Source: https://docs.portkey.ai/docs/product/model-catalog
A single pane to view and manage every AI provider and model in your organization. It provides centralized governance, discovery, and usage controls for all your AI resources.
The Model Catalog is a centralized hub for viewing and managing all AI providers and models within your organization. It abstracts raw API keys and scattered environment variables into governed Provider Integrations and Models, giving you complete control over how your teams access and use AI.
> [!NOTE]
>
> #### [Upgrading from Virtual Keys](/docs/support/upgrade-to-model-catalog)
>
> The Model Catalog upgrades the Virtual Key experience by introducing a centralized, organization-level management layer, offering advantages like:
>
> * Centralized provider and model management - no more duplicate configs across workspaces.
> * Fine-grained control: budgets, rate limits, and model allow-lists at both org and workspace level.
> * Inline usage: just pass `model="@provider/model_slug"`
>
> **Need help?** See our [Migration Guide ➜](/docs/support/upgrade-to-model-catalog)
> [card] AI Providers
>
> AI Providers are what you use in your code. Each provider has:
>
> * ✅ A unique slug (e.g., `@openai-prod`)
> * ✅ Securely stored credentials
> * ✅ Budget and rate limits
> * ✅ Access to specific models
>
> **To use:** Add a provider, then use `@provider-slug/model-name` in your code.
> [card] Models
>
> The Models section is a gallery of all AI models available in your workspace. Each Model entry includes:
>
> * ✅ Model slug (`@openai-prod/gpt-4o`)
> * ✅ Ready-to-use code snippets
> * ✅ Input/output token limits
> * ✅ Pricing information (where available)
>
> [View all available models →](https://app.portkey.ai/model-catalog/models)
## Adding an AI Provider
Add providers via **UI** (follow the steps below) or [**API**](/docs/api-reference/admin-api/introduction).
**1. Go to AI Providers → Add Provider**
Navigate to the [Model Catalog](https://app.portkey.ai/model-catalog) in your Portkey dashboard.

**2. Select the AI Service**
Choose from list (OpenAI, Anthropic, etc.) or *Self-hosted / Custom*.

**3. Choose or Create Credentials**
**If credentials already exist:**
* Select from the dropdown (if your org admin set them up)
* Skip to step 4 - no API keys needed!
**If creating new credentials:**
* Choose "Create new credentials"
* Enter your API keys here
> [!NOTE]
>
> Creating new credentials here automatically creates a workspace-linked integration. To share credentials across multiple workspaces, create them in the [Integrations](/docs/product/model-catalog/integrations) page (org admin only).

**4. Name your provider & save**
Choose a name and slug for this provider. The slug (e.g., `openai-prod`) will be used in your code like `@openai-prod/gpt-4o`.

## Using Provider Models
Once you have AI Providers set up, use their models in your applications. There are three methods - we recommend the model prefix format for clarity.
In Portkey, model strings follow this format:
`@provider_slug/model_name`

For example, `@openai-prod/gpt-4o`, `@anthropic/claude-3-sonnet`, `@bedrock-us/claude-3-sonnet-v1`
```javascript Javascript SDK theme={"system"}
import { Portkey } from 'portkey-ai';
const client = new Portkey({ apiKey: "PORTKEY_API_KEY" });
const resp = await client.chat.completions.create({
model: '@openai-prod/gpt-4o',
messages: [{ role: 'user', content: 'Hello!' }]
});
```
```python Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
resp = portkey.chat.completions.create(
model="@openai-prod/gpt-4o",
messages=[{"role":"user","content":"Hello"}]
)
```
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
client = OpenAI(api_key="PORTKEY_API_KEY", base_url="https://api.portkey.ai/v1")
client.chat.completions.create(
model="@openai-prod/gpt-4o",
messages=[{"role": "user", "content": "Hello!"}]
)
```
```javascript OpenAI JS SDK theme={"system"}
import OpenAI from 'openai';
const openai = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1"
});
const completion = await openai.chat.completions.create({
model: "@openai-prod/gpt-4o",
messages: [{ role: 'user', content: 'Hello!' }]
});
```
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-prod/gpt-4o",
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
### 2. Using the `provider` header
Specify the provider separately using the `provider` parameter. Remember to add the `@` before your provider slug.
```javascript Javascript SDK theme={"system"}
import { Portkey } from 'portkey-ai';
const client = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "@openai-prod"
});
const resp = await client.chat.completions.create({
model: 'gpt-4o',
messages: [{ role: 'user', content: 'Hello!' }]
});
```
```python Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="@openai-prod"
)
resp = portkey.chat.completions.create(
model="gpt-4o",
messages=[{"role":"user","content":"Hello"}]
)
```
```python OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import createHeaders
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url="https://api.portkey.ai/v1",
default_headers=createHeaders(
provider="@openai-prod"
)
)
client.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Hello!"}]
)
```
```javascript OpenAI JS SDK theme={"system"}
import OpenAI from 'openai';
import { createHeaders } from 'portkey-ai'
const openai = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai/v1",
defaultHeaders: createHeaders({
provider: "@openai-prod"
})
});
const completion = await openai.chat.completions.create({
model: "gpt-4o",
messages: [{ role: 'user', content: 'Hello!' }]
});
```
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: @openai-prod" \
-d '{
"model": "gpt-4o",
"messages": [{"role": "user", "content": "Hello!"}]
}'
```
### 3. Specify `provider` in the config
Portkey's configs are simple JSON structures that help you define routing logic for LLM requests. Learn more [here](/docs/product/ai-gateway/configs).
There are three ways to specify providers in configs:
**Method 1: Model in override\_params (Recommended)**
Specify provider and model together in `override_params`. Works great with multi-provider strategies:
```json theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [{
"override_params": { "model": "@openai-prod/gpt-4o" }
}, {
"override_params": { "model": "@anthropic/claude-3-sonnet" }
}]
}
```
**Method 2: Provider in target**
Specify provider directly in the target (remember the `@` symbol):
```json theme={"system"}
{
"strategy": { "mode": "single" },
"targets": [{
"provider": "@openai-prod",
"override_params": {
"model": "gpt-4o"
}
}]
}
```
**Method 3: Legacy virtual\_key (Backwards Compatible)**
The `virtual_key` field still works:
```json theme={"system"}
{
"strategy": { "mode": "single" },
"targets": [{
"virtual_key": "openai-prod"
}]
}
```
> **Ordering:** `config` (if provided) defines base; `override_params` merges on top (last write wins for scalars, deep merge for objects like `metadata`).
## Integrations
At the heart of Model Catalog is a simple concept: your AI provider credentials need to be stored securely, governed carefully and managed centrally. In Portkey, these stored credentials are called **Integrations**. Think of an Integration as a secure vault for your API keys - whether it's your OpenAI API key, AWS Bedrock credentials, or Azure OpenAI configuration.

Once you create an Integration (by storing your credentials), you can use it to create multiple AI Providers. For example, you might have one OpenAI Integration, but create three different AI Providers from it:
* `@openai-dev` for development with strict rate limits
* `@openai-staging` for testing with moderate budgets
* `@openai-prod` for production with higher limits
This separation gives you granular control over how different teams and environments use the same underlying credentials.
> [card] [Integrations](/docs/product/model-catalog/integrations)
>
> Learn how to create and manage AI service credentials across your organization
## Managing Access and Controls
Each Integration in Portkey acts as a control point where you can configure:
### Budget Limits
Set spending controls at the Integration level to prevent unexpected costs. You can configure:
* **Cost-based limits**: Maximum spend in USD (e.g., \$1000/month)
* **Token-based limits**: Maximum tokens consumed (e.g., 10M tokens/week)
* **Periodic resets**: Weekly or monthly budget refreshes

These limits cascade down to all AI Providers created from that Integration.
> [card] [Budget Management](/docs/product/model-catalog/integrations#3-budget-%26-rate-limits)
>
> Set up cost controls and spending limits for your AI usage
### Rate Limits
Control request rates to manage load and prevent abuse:
* **Requests per minute/hour/day**: Set appropriate throughput limits
* **Concurrent request limits**: Control parallel processing
* **Burst protection**: Prevent sudden spikes in usage
Rate limits help you maintain service quality and prevent any single user or team from monopolizing resources.
> [card] [Rate Limiting](/docs/product/model-catalog/integrations#3-budget-%26-rate-limits)
>
> Configure request rate controls to ensure fair usage and prevent abuse
### Workspace Provisioning
Control which workspaces in your organization can access specific AI Providers:
* **Selective access**: Choose which teams can use production vs development providers
* **Environment isolation**: Keep staging and production resources separate
* **Department-level control**: Give finance different access than engineering

This hierarchical approach ensures teams only have access to the resources they need.
> [card] [Workspace Provisioning](/docs/product/model-catalog/integrations#1-workspace-provisioning)
>
> Manage workspace access to AI providers and models
### Model Provisioning
Fine-tune which models are available through each Integration:
* **Model allowlists**: Only expose specific models (e.g., only GPT-4 for production)
* **Model denylists**: Block access to expensive or experimental models
* **Custom model addition**: Add your fine-tuned or self-hosted models

Model provisioning helps you maintain consistency and control costs across your organization.
> [card] [Model Provisioning](/docs/product/model-catalog/integrations#2-model-provisioning)
>
> Configure which models are available through each integration
## Advanced Model Management
### Custom Models
The Model Catalog isn't limited to standard provider models. You can add:
* **Fine-tuned models**: Your custom OpenAI or Anthropic fine-tunes
* **Self-hosted models**: Models running on your infrastructure
* **Private models**: Internal models not publicly available
Each custom model gets the same governance controls as standard models.
> [card] [Custom Models](/docs/product/model-catalog/custom-models)
>
> Add and manage your fine-tuned, self-hosted, or private models
### Overriding Model Details (Custom Pricing)
Override default model pricing for:
* **Negotiated rates**: If you have enterprise agreements with providers
* **Internal chargebacks**: Set custom rates for internal cost allocation
* **Free tier models**: Mark certain models as free for specific teams
Custom pricing ensures your cost tracking accurately reflects your actual spend.
> [card] [Custom Pricing](/docs/product/model-catalog/model-overrides)
>
> Configure custom pricing for models with special rates
## Self-hosted AI Providers
> [card] Coming Soon
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Budget Limits
Source: https://docs.portkey.ai/docs/product/model-catalog/budget-limits
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Connect Bedrock with Amazon Assumed Role
Source: https://docs.portkey.ai/docs/product/model-catalog/connect-bedrock-with-amazon-assumed-role
How to create an integrate Bedrock using Amazon Assumed Role Authentication on Portkey
> [card] [Set Up Bedrock Authentication for Enterprise](https://github.com/Portkey-AI/helm/blob/main/charts/portkey-gateway/docs/Bedrock.md)
>
> On the Enterprise plan and need to connect to Bedrock using an AWS assumed role? Check out the documentation here.
## Select AWS Assumed Role Authentication
Create a new integration on Portkey, select **Bedrock** as the provider and **AWS Assumed Role** as the authentication method.

## Create an AWS Role for Portkey to Assume
This role you create will be used by Porktey to execute InvokeModel commands on Bedrock models in your AWS account. The setup process will establish a minimal-permission ("least privilege") role and set it up to allow Porktey to assume this role.
### Create a permission policy in your AWS account using the following JSON
```json theme={"system"}
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "BedrockConsole",
"Effect": "Allow",
"Action": [
"bedrock:InvokeModel",
"bedrock:InvokeModelWithResponseStream"
],
"Resource": "*"
}
]
}
```

### Create a new IAM role
Choose *AWS account* as the trusted entity type. If you set an external ID be sure to copy it, we will need it later.

### Add the above policy to the role
Search for the policy you created above and add it to the role.

### Configure Trust Relationship for the role
Once the role is created, open the role and navigate to the *Trust relationships* tab and click *Edit trust policy*.
This is where you will add the Portkey AWS account as a trusted entity.
```sh Portkey Account ARN theme={"system"}
arn:aws:iam::299329113195:role/portkey-app
```
> [!NOTE]
>
> The above ARN only works for our [hosted app](https://app.portkey.ai/).\\
>
> To enable **Assumed Role for AWS in your Portkey Enterprise deployment**, you can refer to [this guide](https://github.com/Portkey-AI/helm/blob/main/charts/portkey-gateway/docs/Bedrock.md). If you face any issue, please reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
Paste the following JSON into the trust policy editor and click *Update Trust Policy*.
```json theme={"system"}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"AWS": "arn:aws:iam::299329113195:role/portkey-app"
},
"Action": "sts:AssumeRole",
"Condition": {}
}
]
}
```
If you set an external ID, add it to the condition as shown below.
```json theme={"system"}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"AWS": ""
},
"Action": "sts:AssumeRole",
"Condition": {
"StringEquals": {
"sts:ExternalId": ""
}
}
}
]
}
```
## Configure the integration with the role ARN
Once the role is created, copy the role ARN and paste it into the Bedrock integrations modal in Portkey along with the external ID if you set one and the AWS region you are using.

You're all set! You can now use the new provider to invoke Bedrock models.
## Attribute Cost and Usage with Session Tags
You can attribute Bedrock cost and audit trails to individual applications, teams, or environments while sharing a single assumed role. Any metadata you send on a request is forwarded to AWS as [STS session tags](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_session-tags.html), so you can segregate spend in AWS Cost Explorer and CloudTrail without provisioning a separate IAM role per application.
> [!NOTE]
>
> This feature requires the `AWS_BEDROCK_STS_SESSION_TAGS_ENABLED` environment variable to be set to `true` on the gateway container.
Pass the tags using the `metadata` field (or the `x-portkey-metadata` header):
```sh theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: $PROVIDER_SLUG" \
-H 'x-portkey-metadata: {"app": "chatbot", "team": "platform", "env": "prod"}' \
-d '{ "model": "anthropic.claude-3-5-sonnet-20240620-v1:0", "messages": [{"role": "user", "content": "Hello"}] }'
```
> [!NOTE]
>
> For AWS to accept session tags, add the `sts:TagSession` action to the trust policy of the role Portkey assumes, alongside the existing `sts:AssumeRole` action.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Adding Custom Models
Source: https://docs.portkey.ai/docs/product/model-catalog/custom-models
Learn how to add custom and fine-tuned models to your Portkey Model Catalog for seamless integration.
Portkey's Model Catalog is designed to be a central hub for all the models you use, providing a unified interface for both supported and private models. By adding your custom or fine-tuned models to the catalog, you can seamlessly integrate them into your applications, leverage Portkey's unified API signature, and benefit from centralized logging, monitoring, and management.
This is especially useful for:
* **Fine-tuned Models**: Integrating your fine-tuned versions of popular models (e.g., `ft:gpt-4.1-nano`).
* **Internal/Proprietary Models**: Using your own in-house models through the Portkey gateway.
* **Models Not Natively Supported**: Adding models from providers that Portkey doesn't yet have a direct integration with, while mapping them to a compatible API signature.
## Adding a New Custom Model
You can add a custom model directly from your Portkey dashboard.
1. Navigate to the relevant [**Integration**](https://app.portkey.ai/integrations) in your Portkey account, select the Integration for which you want to add a custom model.
2. Select the **Model Provisioning** step from steps.
3. Click the **Add Model** button on the top-right corner of the page.
This will open the **Add Custom Model** form.

### Configuration Fields
Here’s a breakdown of each field in the form:
> [card] Model Slug
>
> A unique, lowercase identifier for your model (e.g., `my-custom-model-v1`). This slug is what you will use in your API requests to reference this model.
> [card] Short Description
>
> An optional, brief description to help you and your team understand the model's purpose or version.
> [card] Model Type
>
> Specify the nature of your model:
>
> * **Fine-tuned model**: Select this if you are adding a fine-tuned version of a base model (like `ft:gpt-3.5-turbo`).
> * **Custom model**: Select this for any other model, such as proprietary in-house models.
> [card] Base Model
>
> Select an existing model that your custom model is based on in terms of **API compatibility**. For example, if your custom model accepts the same request payload and returns the same response structure as `gpt-4`, you would select `gpt-4` here. This ensures Portkey can correctly format requests and parse responses.
> [card] Add custom pricing for this model?
>
> Enable this toggle if you want to associate specific input and output costs with your model. This is useful for accurate cost tracking and budget management within Portkey's dashboard.
> [!NOTE]
>
> A model with custom pricing is billed at exactly that price — [pricing adjustments](/docs/product/model-catalog/pricing-adjustments) set at the model level or the Integration level are ignored for it. Build any discount or markup into the custom price itself.
## Per-model custom host and headers
Each integration model can carry its own routing config — useful when several custom models share one integration but hit different upstreams or need different headers.
| Field | Purpose |
| :- | :- |
| `custom_host` | Upstream base URL for this model (e.g. a private or regional endpoint) |
| `custom_headers` | String-to-string map of headers Portkey sends with requests for this model |
**Precedence**
* Model-level `custom_headers` override integration-level `custom_headers` for that model.
* A request-time / header-level `custom_host` still takes priority over the model-level value.
Configure via the [Update Model Access](/docs/api-reference/admin-api/control-plane/integrations/models/update-model-access) API (`models[].configurations`), or set the fields when editing the model in Model Provisioning.
```bash theme={"system"}
curl -X PUT "https://api.portkey.ai/v1/integrations/YOUR_INTEGRATION_SLUG/models" \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"models": [
{
"slug": "my-custom-model-v1",
"enabled": true,
"is_custom": true,
"base_model_slug": "gpt-4o",
"configurations": {
"custom_host": "https://llm.internal.example.com/v1",
"custom_headers": {
"x-tenant-id": "acme-prod",
"x-region": "us-east-1"
}
}
}
]
}'
```
> [!NOTE]
>
> `custom_headers` must be a flat string-to-string object. See [Custom hosts](/docs/product/ai-gateway/custom-hosts) for URL validation rules on `custom_host`.
## Using Your Custom Model
Once you've added your custom model, you can use it just like any other model in the catalog. Simply reference its **Model Slug** in your API calls.
For example, to use a custom model with the slug `my-custom-model-v1` in a chat completion request, you would set it as the `model` in your provider configuration or pass it directly in the request header:
> [tab] cURL
>
> ```bash theme={"system"}
> curl -X POST https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: YOUR_PORTKEY_API_KEY" \
> -d '{
> "model": "@provider/my-custom-model-v1",
> "messages": [
> {
> "role": "user",
> "content": "Hello, what can you do?"
> }
> ]
> }'
> ```
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> client = Portkey(
> api_key="YOUR_PORTKEY_API_KEY"
> )
>
> response = client.chat.completions.create(
> model="@provider/my-custom-model-v1",
> messages=[
> {
> "role": "user",
> "content": "Hello, what can you do?"
> }
> ]
> )
>
> print(response.choices[0].message.content)
> ```
Portkey will route the request to the provider associated with the base model you selected, using your custom model's slug.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Integrations
Source: https://docs.portkey.ai/docs/product/model-catalog/integrations
Securely store and manage AI provider credentials across your organization with centralized governance controls
> [!NOTE]
>
> **For Organization Admins:** This page is for managing credentials across multiple workspaces. To use AI models in your workspace, see the [Model Catalog](/docs/product/model-catalog) documentation.
**What are Integrations?**
A place to store credentials once and share them with multiple workspaces.
**Why use them?**
* **Save time:** Store API keys once, use in many workspaces
* **Control access:** Decide which workspaces can use which credentials
* **Control models:** Enable or disable specific models at the Integration level
* **Set limits:** Different budgets and rate limits per workspace
**How it works:**
1. Store credentials here (creates an Integration)
2. Choose which models are available (enable/disable models)
3. Share with workspaces (they see it as a Provider in their Model Catalog)
4. Each workspace can use the same credentials with different limits, but only access models you've enabled
**Simple analogy:** Like a shared password vault. Store your OpenAI API key once, then share it with multiple workspaces. Each workspace can use the same credentials but with different budgets and rate limits.
When you create an Integration, you control:
* **Who** can use these credentials (which workspaces)
* **What** models they can access
* **How much** they can spend (budget limits)
* **How fast** they can make requests (rate limits)
## Why Use Integrations?
Instead of each workspace entering the same API keys separately, store them once and share them:
1. **Save time** - No need to re-enter credentials in each workspace
2. **Control access** - Decide which workspaces can use which credentials
3. **Set limits** - Different budgets and rate limits per workspace
4. **Stay secure** - API keys are encrypted and never exposed to end users
5. **Track everything** - See usage and costs across all workspaces
## Understanding the Integrations Dashboard
Navigate to the [Integrations page](https://app.portkey.ai/integrations) in your Portkey organization settings. The page is organized into three tabs, each serving a distinct purpose:
* **`All`**: This is a comprehensive list of all 50+ providers Portkey supports. This is your starting point for connecting a new provider to your organization.
* **`Connected`**: This tab lists all the integrations that you have personally connected at the organization level. It's your primary view for managing your centrally-governed providers.
* **`Workspace-Created`**: This tab gives you complete visibility and governance over any integrations created *by Workspace Admins* for their specific workspaces. It ensures that even with delegated control, you maintain a full audit trail and can manage these instances if needed.
## Creating an Integration
Let's walk through creating an Integration for AWS Bedrock as an example:
**1. Navigate to Integrations**
From your admin panel, go to [**Integrations**](https://app.portkey.ai/model-catalog/providers) and click **Create New Integration** (or click **Connect** from the **`All`** tab).
**2. Select Your AI Provider**
Choose from 200+ supported providers. Each provider may have different credential requirements.

**3. Configure Integration Details**
* **Name**: A descriptive name for this integration (e.g., "Bedrock Production")
* **Slug**: A unique identifier used in API calls (e.g., "bedrock-prod")
* **Description**: Optional context about this integration's purpose
* **Endpoint Type**: Choose between Public or Private endpoints
**4. Enter Provider Credentials**
Each provider requires different credentials:
**For OpenAI:**

* API Key
* Optional: Organization ID, Project ID
**For AWS Bedrock:**
* AWS Access Key
* AWS Secret Access Key
* AWS Access Key ID
* AWS Region
> [card] [Connect Bedrock with Amazon Assumed Role](/docs/product/model-catalog/connect-bedrock-with-amazon-assumed-role)
>
> How to integrate Bedrock using Amazon Assumed Role Authentication
Similarly for:
* Azure OpenAI
* Google Vertex AI
* Anthropic
* Gemini
and more...
***
# Configuring Your Integration Access & Limits
After creating your Integration, you'll need to configure three key aspects that work together to control access and usage:
## 1. Workspace Provisioning
Workspace provisioning determines which teams and projects can access this Integration. This is crucial for maintaining security boundaries and ensuring teams only access approved AI resources.
#### How It Works
When you share credentials with a workspace:
1. That workspace sees it as an **AI Provider** in their Model Catalog
2. They can use it immediately - no need to enter credentials again
3. Set different budgets/rate limits for each workspace
4. Revoke access anytime
#### Setting Up Workspace Provisioning

1. In your Integration settings, navigate to **Workspace Provisioning**
2. Select which workspaces should have access:
* **All Workspaces**: Grants access to every workspace in your organization
* **Specific Workspaces**: Choose individual workspaces that need access
3. For each workspace, click the `Edit Budget & Rate Limits` icon to configure:
* Custom budget limits (see Budget Limits section below)
* Custom rate limits (see Rate Limits section below)
* Specific model access
#### Best Practices
* **Principle of Least Privilege**: Only provision to workspaces that genuinely need access
* **Environment Separation**: Create separate Integrations for dev/staging/production
* **Regular Audits**: Review workspace provisioning quarterly to remove unnecessary access
***
## 2. Model Provisioning
**Model lists are tied to Integrations.** When you create an Integration, you control which models are available. All Providers created from that Integration will only have access to the models you've enabled.
This is essential for:
* **Controlling costs:** Restrict access to expensive models
* **Ensuring compliance:** Limit models to approved ones
* **Maintaining consistency:** Standardize model usage across teams
#### Setting Up Model Provisioning

1. In your Integration settings, navigate to **Model Provisioning**
2. Select the configuration options:
* **Allow All Models**: Provides access to all models offered by the provider
* **Allow Specific Models**: Create an allowlist of approved models
**Important:** The model list you set here applies to all Providers created from this Integration. Workspaces will only see and be able to use the models you've enabled.
#### Advanced Model Management
### Custom Models
The Model Catalog isn't limited to standard provider models. You can add:
* **Fine-tuned models**: Your custom OpenAI or Anthropic fine-tunes
* **Self-hosted models**: Models running on your infrastructure
* **Private models**: Internal models not publicly available
Each custom model gets the same governance controls as standard models. Per-model `custom_host` and `custom_headers` let different models under the same integration route to different upstreams or send different headers — model-level headers override integration-level headers.
> [card] [Custom Models](/docs/product/model-catalog/custom-models)
>
> Add and manage your fine-tuned, self-hosted, or private models
### Overriding Model Details (Custom Pricing)
Override default model pricing for:
* **Negotiated rates**: If you have enterprise agreements with providers
* **Internal chargebacks**: Set custom rates for internal cost allocation
* **Free tier models**: Mark certain models as free for specific teams
Custom pricing ensures your cost tracking accurately reflects your actual spend.
> [card] [Custom Pricing](/docs/product/model-catalog/model-overrides)
>
> Configure custom pricing for models with special rates
***
## 3. Budget & Rate Limits
Budget and rate limits are configured within Workspace Provisioning and provide financial and usage guardrails for your AI operations.

### Budget Limits
**Budget Limits on Integrations** provide a simple way to manage your spending on AI providers (and LLMs) - giving you confidence and control over your application's costs. They act as financial guardrails, preventing unexpected AI costs across your organization. These limits cascade down to all AI Providers created from this Integration.
#### Setting Budget Limits
1. In your Integration settings, navigate to **Workspace Provisioning**
2. Select which workspaces should have access:
* **All Workspaces**: Grants access to every workspace in your organization
* **Specific Workspaces**: Choose individual workspaces that need access
3. Click on the `Edit Budget & Rate Limits` icon to edit the budget limits for the selected workspace
4. Set your desired budget Limits
5. Optionally, Select the `Apply to every workspace where this integration is enabled` checkbox to apply the same budget limits to all workspaces where this integration is enabled
#### Cost-Based Limits
Set a budget limit in USD that, once reached, will automatically expire the key to prevent further usage and overspending.
#### Token-Based Limits
Set a maximum number of tokens that can be consumed, allowing you to control usage independent of cost fluctuations.
> #### Key Considerations for Budget Limits
>
> * Budget limits can be set as either cost-based (USD) or token-based
> * The minimum cost limit you can set is **\$1**
> * The minimum token limit you can set is **100 tokens**
> * Budget limits apply until exhausted or reset
> * Budget limits are applied only to requests made after the limit is set; they do not apply retroactively
> * Once set, budget limits **cannot be edited** by any organization member
> * Budget limits work for **all AI provider** created on Portkey using the given **integration**
#### Alert Thresholds
Set alert thresholds to receive notifications before your budget limit is reached:
* For cost-based budgets, set thresholds in USD
* For token-based budgets, set thresholds in tokens
* Receive email notifications when usage reaches the threshold
* Continue using the key until the full budget limit is reached
#### Periodic Reset Options
Configure budget limits to automatically reset at regular intervals:
**Reset Period Options:**
* **No Periodic Reset**: The budget limit applies until exhausted with no automatic renewal
* **Reset Weekly**: Budget limits automatically reset every week
* **Reset Monthly**: Budget limits automatically reset every month
**Reset Timing:**
* Weekly resets occur at the beginning of each week (Sunday at 12 AM UTC)
* Monthly resets occur on the **1st** calendar day of the month, at **12 AM UTC**, irrespective of when the budget limit was set prior
### Rate Limits
Rate limits control the velocity of API usage, protecting against runaway processes and ensuring fair resource distribution across teams.
#### Setting Rate Limits
1. In your Integration settings, navigate to **Workspace Provisioning**
2. Select which workspaces should have access:
* **All Workspaces**: Grants access to every workspace in your organization
* **Specific Workspaces**: Choose individual workspaces that need access
3. Click on the `Edit Budget & Rate Limits` icon to edit the rate limits for the selected workspace
4. Set your desired rate Limits
5. Optionally, Select the `Apply to every workspace where this integration is enabled` checkbox to apply the same rate limits to all workspaces where this integration is enabled
#### Configuration Options
**Limit Types:**
* **Request-based**: Limit number of API calls (e.g., 1000 requests/minute)
* **Token-based**: Limit token consumption rate (e.g., 1M tokens/hour)
**Time Windows:**
Choose from three different time intervals for your rate limits:
* **Per Minute**: Limits reset every minute, ideal for fine-grained control
* **Per Hour**: Limits reset hourly, providing balanced usage control
* **Per Day**: Limits reset daily, suitable for broader usage patterns
> #### Key Considerations for Rate Limits
>
> * Rate limits can be set as either request-based or token-based
> * Time intervals can be configured as per minute, per hour, or per day
> * Setting the limit to 0 disables the provider
> * Rate limits apply immediately after being set
> * Once set, rate limits **cannot be edited** by any organization member
> * Rate limits work for **all providers** available on Portkey and apply to **all organization members** who use the provider
> * After a rate limit is reached, requests will be rejected until the time period resets
#### Use Cases for Rate Limits
* **Cost Control**: Prevent unexpected usage spikes that could lead to high costs
* **Performance Management**: Ensure your application maintains consistent performance
* **Fairness**: Distribute API access fairly across teams or users
* **Security**: Mitigate potential abuse or DoS attacks
* **Provider Compliance**: Stay within the rate limits imposed by underlying AI providers
#### Exceeding Rate Limits
When a rate limit is reached:
* Subsequent requests are rejected with a specific error code
* Error messages clearly indicate that the rate limit has been exceeded
* The limit automatically resets after the specified time period has elapsed
***
## Monitoring and Analytics
### Tracking Spending and Usage
Track spending, usage, and 40+ crucial metrics for any specific AI integration by navigating to the Analytics tab and filtering by the **desired key** and **timeframe**.

***
## FAQs
> [accordion] How are provider API keys stored?
>
> Your API keys are always encrypted and stored in secure, isolated vaults. They are only decrypted in-memory, within sandboxed workers, at the exact moment a request is made to the provider. This ensures the highest level of security for your credentials.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Overriding Model Details
Source: https://docs.portkey.ai/docs/product/model-catalog/model-overrides
Learn how to set custom pricing for any base model in your Portkey Model Catalog to reflect your specific costs.
Portkey's Model Catalog automatically includes the standard pay-as-you-go pricing for supported models, which is used to calculate costs on your dashboard. However, you may have different pricing arrangements with your model providers, such as negotiated discounts, committed use contracts, or your own internal pricing for private models.
To ensure your cost and usage analytics are accurate, Portkey allows you to override the default pricing for any model in the catalog.
## How to Override Model Pricing
You can change the pricing for any model directly from your Portkey dashboard.

1. Navigate to the relevant [**Integration**](https://app.portkey.ai/integrations) in your Portkey account, select the Integration for which you want to add a custom model.
2. Select the **Model Provisioning** step from steps.
3. Find the model whose pricing you want to change in the list.
4. Click the **Edit** (pencil) icon on the right side of the model's row.
This will open a form where you can set your custom pricing.

### Pricing Fields
When you edit a model, you can set the following pricing values:
> [card] Input Cost
>
> Enter your custom cost for **1 million input tokens** in USD. This is the cost associated with the tokens you send to the model.
> [card] Output Cost
>
> Enter your custom cost for **1 million output tokens** in USD. This is the cost associated with the tokens the model generates in response.
Once you save the changes, Portkey will use these new rates to calculate the cost of all subsequent requests made with this model, providing you with an accurate view of your AI expenditure.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# AI Model Provisioning
Source: https://docs.portkey.ai/docs/product/model-catalog/model-provisioning
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Portkey Models
Source: https://docs.portkey.ai/docs/product/model-catalog/portkey-models
GET https://api.portkey.ai/model-configs/pricing/{provider}/{model}
Open-source pricing and configuration database for 2,300+ LLMs across 35+ providers
> [!NOTE]
>
> **Portkey Models** is a free, open-source pricing database for LLMs. No API key required — just query any model's pricing directly.
> [card] [Explore Models](https://portkey.ai/models)
>
> Browse 2,300+ models
> [card] [Model Rankings](https://portkey.ai/rankings)
>
> Top models by usage
> [card] [GitHub](https://github.com/Portkey-AI/models)
>
> View source & contribute
***
## Quick Start
Get pricing for any model with a single API call:
```bash cURL theme={"system"}
curl https://api.portkey.ai/model-configs/pricing/openai/gpt-4o
```
```javascript JavaScript theme={"system"}
const response = await fetch(
'https://api.portkey.ai/model-configs/pricing/anthropic/claude-3-5-sonnet-20241022'
);
const pricing = await response.json();
console.log(pricing.pay_as_you_go.request_token.price); // Input cost
console.log(pricing.pay_as_you_go.response_token.price); // Output cost
```
```python Python theme={"system"}
import requests
pricing = requests.get(
'https://api.portkey.ai/model-configs/pricing/google/gemini-2.0-flash-001'
).json()
input_cost = pricing['pay_as_you_go']['request_token']['price']
output_cost = pricing['pay_as_you_go']['response_token']['price']
```
> [!TIP]
>
> **Need to discover all models for a provider?** Instead of querying each model individually, you can fetch pricing for all models at once:
>
> ```bash theme={"system"}
> curl https://configs.portkey.ai/pricing/{provider}.json
> ```
>
> [See detailed documentation below ↓](#get-all-models-for-a-provider)
***
## Understanding Pricing Units
> [!WARNING]
>
> **Prices are in cents per token, not dollars.**
| API Response | Per 1K Tokens | Per 1M Tokens |
| - | - | - |
| `0.003` | \$0.03 | \$30 |
| `0.00025` | \$0.0025 | \$2.50 |
| `0.0001` | \$0.001 | \$1.00 |
**Calculate cost in dollars:**
```javascript theme={"system"}
const costInDollars = (tokens * priceFromAPI) / 100;
```
***
## API Reference
### Get Model Pricing
Returns pricing configuration for a specific model.
```
GET https://api.portkey.ai/model-configs/pricing/{provider}/{model}
```
#### Path Parameters
**provider** `string` *required*
Provider identifier. Use lowercase with hyphens.
Examples: `openai`, `anthropic`, `google`, `azure-openai`, `bedrock`, `together-ai`, `groq`, `deepseek`, `x-ai`, `mistral-ai`, `cohere`, `fireworks-ai`, `perplexity-ai`, `anyscale`, `deepinfra`, `cerebras`
**model** `string` *required*
Model identifier. Use the exact model name as specified by the provider.
Examples: `gpt-4o`, `gpt-4-turbo`, `claude-3-5-sonnet-20241022`, `claude-3-opus-20240229`, `gemini-2.0-flash-001`, `gemini-1.5-pro`
#### Response Schema
**pay\_as\_you\_go** `object`
Token-based pricing. All prices in USD **cents per token**.
**properties**
**request\_token** `object`
Input token pricing.
**properties**
**price** `number`
Price in USD cents per token. Example: `0.00025` = \$0.0025 per 1K tokens
**response\_token** `object`
Output token pricing.
**properties**
**price** `number`
Price in USD cents per token.
**cache\_read\_input\_token** `object`
Prompt cache read pricing (when available).
**properties**
**price** `number`
Price in USD cents per token.
**cache\_write\_input\_token** `object`
Prompt cache write pricing (when available).
**properties**
**price** `number`
Price in USD cents per token.
**request\_audio\_token** `object`
Audio input token pricing (for multimodal models).
**properties**
**price** `number`
Price in USD cents per token.
**response\_audio\_token** `object`
Audio output token pricing (for multimodal models).
**properties**
**price** `number`
Price in USD cents per token.
**additional\_units** `object`
Provider-specific pricing for features beyond tokens.
Common units:
* `web_search` — Web search tool usage
* `file_search` — File search tool usage
* `thinking_token` — Chain-of-thought reasoning tokens
* `image_token` — Image generation/processing
* `video_duration_seconds_*` — Video generation (by resolution)
**image** `object`
Image generation pricing by quality and size (for image models).
Structure: `{ "quality": { "resolution": { "price": number } } }`
**calculate** `object`
Cost calculation formulas for complex pricing scenarios.
**properties**
**request** `object`
Formula for calculating request (input) cost.
**response** `object`
Formula for calculating response (output) cost.
**currency** `string`
Currency code. Always `USD`.
**finetune\_config** `object`
Fine-tuning pricing (when available).
**properties**
**pay\_per\_token** `object`
Training cost per token.
**pay\_per\_hour** `object`
Training cost per hour.
#### Example Responses
```json OpenAI GPT-4o theme={"system"}
{
"pay_as_you_go": {
"request_token": { "price": 0.00025 },
"response_token": { "price": 0.001 },
"cache_write_input_token": { "price": 0 },
"cache_read_input_token": { "price": 0.000125 },
"additional_units": {
"web_search": { "price": 1 },
"file_search": { "price": 0.25 }
}
},
"calculate": {
"request": {
"operation": "sum",
"operands": [
{ "operation": "multiply", "operands": [{ "value": "input_tokens" }, { "value": "rates.request_token" }] },
{ "operation": "multiply", "operands": [{ "value": "cache_write_tokens" }, { "value": "rates.cache_write_input_token" }] },
{ "operation": "multiply", "operands": [{ "value": "cache_read_tokens" }, { "value": "rates.cache_read_input_token" }] }
]
},
"response": {
"operation": "multiply",
"operands": [{ "value": "output_tokens" }, { "value": "rates.response_token" }]
}
},
"currency": "USD"
}
```
```json Anthropic Claude 3.5 Sonnet theme={"system"}
{
"pay_as_you_go": {
"request_token": { "price": 0.0003 },
"response_token": { "price": 0.0015 },
"cache_read_input_token": { "price": 0.00003 },
"cache_write_input_token": { "price": 0.000375 }
},
"currency": "USD"
}
```
```json Google Gemini 2.5 Pro theme={"system"}
{
"pay_as_you_go": {
"request_token": { "price": 0.000125 },
"response_token": { "price": 0.001 },
"additional_units": {
"thinking_token": { "price": 0.001 },
"web_search": { "price": 3.5 },
"search": { "price": 3.5 }
}
},
"currency": "USD"
}
```
```json OpenAI DALL-E 3 (Image Model) theme={"system"}
{
"pay_as_you_go": {
"image": {
"standard": {
"1024x1024": { "price": 4 },
"1024x1792": { "price": 8 },
"1792x1024": { "price": 8 }
},
"hd": {
"1024x1024": { "price": 8 },
"1024x1792": { "price": 12 },
"1792x1024": { "price": 12 }
}
}
},
"currency": "USD"
}
```
***
### Get Model Configuration
Returns general configuration and capabilities for a specific model.
```
GET https://api.portkey.ai/model-configs/general/{provider}/{model}
```
#### Path Parameters
**provider** `string` *required*
Provider identifier (e.g., `openai`, `anthropic`, `google`)
**model** `string` *required*
Model identifier (e.g., `gpt-4o`, `claude-3-opus`)
#### Response Schema
**params** `array`
Model parameters with their constraints.
**item properties**
**key** `string`
Parameter name (e.g., `max_tokens`, `temperature`, `top_p`)
**defaultValue** `any`
Default value for the parameter.
**minValue** `number`
Minimum allowed value.
**maxValue** `number`
Maximum allowed value.
**type** `string`
Parameter type (e.g., `boolean`, `string`, `array-of-strings`)
**options** `array`
Available options for enum-type parameters.
**type** `object`
Model type classification.
**properties**
**primary** `string`
Primary model type: `chat`, `text`, `embedding`, `image`, `audio`, `moderation`
**supported** `array`
Supported features: `tools`, `image`, `cache_control`, `json_mode`
**messages** `object`
Message configuration.
**properties**
**options** `array`
Supported message roles: `system`, `user`, `assistant`, `developer`
**disablePlayground** `boolean`
If `true`, model is not available in Portkey playground.
**isDefault** `boolean`
If `true`, this is the default model for the provider.
#### Example Responses
```json OpenAI GPT-4o theme={"system"}
{
"params": [
{
"key": "max_tokens",
"maxValue": 16384
},
{
"key": "response_format",
"defaultValue": null,
"options": [
{ "value": null, "name": "Text" },
{ "value": "json_object", "name": "JSON Object" },
{ "value": "json_schema", "name": "JSON Schema" }
],
"type": "string"
},
{
"key": "temperature",
"minValue": 0,
"maxValue": 2,
"defaultValue": 1
}
],
"type": {
"primary": "chat",
"supported": ["tools", "image"]
}
}
```
```json Anthropic Claude 3 Opus theme={"system"}
{
"params": [
{
"key": "max_tokens",
"maxValue": 4096
}
],
"type": {
"primary": "chat",
"supported": ["tools", "image", "cache_control"]
},
"messages": {
"options": ["system", "user", "assistant"]
}
}
```
***
### Get All Models for a Provider
Returns pricing configuration for all models from a specific provider in a single response.
```
GET https://configs.portkey.ai/pricing/{provider}.json
```
> [!NOTE]
>
> Use this endpoint to discover all available models and their pricing for a provider, instead of querying each model individually.
#### Path Parameters
**provider** `string` *required*
Provider identifier. Use lowercase with hyphens.
Examples: `openai`, `anthropic`, `google`, `bedrock`, `azure-openai`, `together-ai`, `groq`, `deepseek`, `x-ai`, `mistral-ai`
#### Response Schema
Returns a JSON object where:
* Keys are model identifiers
* Values contain `pricing_config` objects with the same structure as the individual model pricing endpoint
* A `default` key provides the base pricing template
**\{model-id}** `object`
Pricing configuration for a specific model.
**properties**
**pricing\_config** `object`
Contains the same pricing structure as the individual model endpoint: `pay_as_you_go`, `calculate`, `currency`, etc.
#### Example Response
```bash cURL theme={"system"}
curl --request GET \
--url https://configs.portkey.ai/pricing/bedrock.json
```
```javascript JavaScript theme={"system"}
const response = await fetch('https://configs.portkey.ai/pricing/bedrock.json');
const allModels = await response.json();
// Access specific model pricing
const claudePrice = allModels['anthropic.claude-3-5-sonnet-20241022-v2:0'];
console.log(claudePrice.pricing_config.pay_as_you_go);
```
```python Python theme={"system"}
import requests
all_models = requests.get(
'https://configs.portkey.ai/pricing/bedrock.json'
).json()
# List all available models
for model_id in all_models.keys():
if model_id != 'default':
print(model_id)
```
> [accordion] Sample Response (Bedrock)
>
> ```json theme={"system"}
> {
> "default": {
> "pricing_config": {
> "pay_as_you_go": {
> "request_token": { "price": 0 },
> "response_token": { "price": 0 }
> },
> "calculate": {
> "request": {
> "operation": "multiply",
> "operands": [
> { "value": "input_tokens" },
> { "value": "rates.request_token" }
> ]
> },
> "response": {
> "operation": "multiply",
> "operands": [
> { "value": "output_tokens" },
> { "value": "rates.response_token" }
> ]
> }
> },
> "currency": "USD"
> }
> },
> "anthropic.claude-3-5-sonnet-20241022-v2:0": {
> "pricing_config": {
> "pay_as_you_go": {
> "request_token": { "price": 0.0003 },
> "response_token": { "price": 0.0015 },
> "cache_write_input_token": { "price": 0.000375 },
> "cache_read_input_token": { "price": 0.00003 }
> }
> }
> },
> "anthropic.claude-3-haiku-20240307-v1:0": {
> "pricing_config": {
> "pay_as_you_go": {
> "request_token": { "price": 0.000025 },
> "response_token": { "price": 0.000125 }
> }
> }
> },
> "meta.llama3-1-405b-instruct-v1:0": {
> "pricing_config": {
> "pay_as_you_go": {
> "request_token": { "price": 0.000532 },
> "response_token": { "price": 0.0016 }
> }
> }
> },
> "amazon.nova-pro-v1:0": {
> "pricing_config": {
> "pay_as_you_go": {
> "request_token": { "price": 0.00008 },
> "response_token": { "price": 0.00002 },
> "cache_read_input_token": { "price": 0.00004 },
> "cache_write_input_token": { "price": 0.00016 }
> }
> }
> }
> }
> ```
***
## Additional Units Reference
Provider-specific pricing for features beyond standard token costs:
| Unit | Description | Providers | Price Range (¢) |
| - | - | - | - |
| `web_search` | Web search tool usage | OpenAI, Azure, Google, Vertex AI, Perplexity | 0.5 - 3.5 |
| `file_search` | File search tool usage | OpenAI, Azure | 0.25 |
| `search` | Google search grounding | Google, Vertex AI | 1.4 - 3.5 |
| `thinking_token` | Chain-of-thought reasoning | Google, Vertex AI | 0.00004 - 0.0012 |
| `image_token` | Image processing tokens | Google, Vertex AI | 0.003 |
| `image_1k` | Image generation (1K units) | Google | 3.9 |
| `megapixels` | Image generation by megapixel | Together AI | 0.0027 - 0.08 |
| `video_seconds` | Video generation | Vertex AI | 10 - 50 |
| `video_duration_seconds_720_1280` | Video (720p) | OpenAI Sora | 10 - 30 |
| `video_duration_seconds_1080_1920` | Video (1080p) | OpenAI Sora | 50 |
| `routing_units` | Azure OpenAI routing | Azure OpenAI | 0.000014 |
| `input_image` | Image input | Vertex AI | 0.01 |
| `input_video_essential` | Video input (essential) | Vertex AI | 0.05 |
| `input_video_standard` | Video input (standard) | Vertex AI | 0.1 |
| `input_video_plus` | Video input (plus) | Vertex AI | 0.2 |
> [accordion] Perplexity Context-Based Pricing
>
> Perplexity has context-dependent web search pricing:
>
> | Unit | Price (¢) |
> | - | - |
> | `web_search_low_context` | 0.5 - 0.6 |
> | `web_search_medium_context` | 0.8 - 1.0 |
> | `web_search_high_context` | 1.2 - 1.4 |
***
## Supported Providers
> [accordion] 40+ providers supported
>
> AI21, Anthropic, Anyscale, Azure AI, Azure OpenAI, AWS Bedrock, Cerebras, Cohere, Dashscope, Deepbricks, DeepInfra, DeepSeek, Fireworks AI, GitHub, Google, Groq, Inference.net, Jina, Lambda, Lemonfox AI, Mistral AI, MonsterAPI, Nebius, Nomic, Novita AI, OpenAI, OpenRouter, Oracle, PaLM, Perplexity AI, Predibase, Reka AI, Sagemaker, Segmind, Stability AI, Together AI, TypeSafe, Vertex AI, Workers AI, X.AI, Zhipu
***
## Use with Portkey
Portkey Models powers automatic cost tracking for all requests through the Portkey Gateway. When you make requests via Portkey, costs are calculated automatically using this pricing data.
> [card] [Cost Analytics](/docs/product/observability/analytics)
>
> View real-time spend across all your LLM usage
> [card] [Budget Limits](/docs/product/model-catalog/integrations#3-budget--rate-limits)
>
> Set spending caps that automatically enforce limits
If you have negotiated enterprise rates, you can override the default pricing:
> [card] [Custom Pricing](/docs/product/model-catalog/model-overrides)
>
> Set custom input/output costs to match your contracts
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Adding Pricing Adjustments
Source: https://docs.portkey.ai/docs/product/model-catalog/pricing-adjustments
Learn how to apply discount or markup multipliers to a Portkey Integration so cost tracking reflects your effective rate with a provider.
Pricing Adjustments let you apply a discount or markup to an Integration, so cost tracking reflects your effective rate with that provider. A multiplier of `1` leaves pricing unchanged. `0.8` applies a 20% discount. `1.2` applies a 20% markup.
> [!NOTE]
>
> Requires:
>
> * Gateway version **2.7.0** or higher
> * Backend version **1.15.0** or higher (for air-gapped deployments)
> * Frontend version **1.8.1** or higher (for air-gapped deployments).
This is especially useful for:
* **Negotiated Discounts**: Reflect enterprise contracts or committed-use rates from a provider on the corresponding Integration.
* **Internal Cost Showback**: Apply a markup so the cost reported to internal teams or workspaces includes your platform overhead.
* **Custom Per-Integration Rates**: Maintain different effective pricing across multiple Integrations of the same provider (e.g. a discounted production Integration alongside a standard-rate sandbox).
## Adding Pricing Adjustments to an Integration
You can configure Pricing Adjustments directly from your Portkey dashboard, in the **Basic Integration Details** step.

1. Navigate to the relevant [**Integration**](https://app.portkey.ai/integrations) in your Portkey account, and create a new Integration or open an existing one.
2. On the **Integration Details** step, toggle **Pricing Adjustments** on.
3. Choose a **Multiplier** mode:
* **Default**: Quick form for the most common token types.
* **Custom**: JSON editor for the full multiplier shape, including reasoning, audio, image, and additional units.
4. Enter your multipliers. Empty fields inherit from `Default`.
5. Save the Integration.
> [!TIP]
>
> For a discount, convert the percentage to a multiplier with:
>
> `multiplier = 1 - (discount% / 100)`
>
> Example: a 10% discount on `Default` and a 15% discount on `Request Tokens`:
>
> * `Default` → `1 - (10 / 100) = 0.90`
> * `Request Tokens` → `1 - (15 / 100) = 0.85`
>
> `Request Tokens` use `0.85`; `Response Tokens`, `Cache Read Tokens`, and `Cache Write Tokens` inherit `0.90` from `Default`.
### Configuration Fields
Default mode exposes the five most common multipliers:
> [card] Default
>
> Multiplier applied to every token type unless a more specific multiplier is set below. A flat 20% discount across the Integration is just `0.8` here.
> [card] Request Tokens
>
> Multiplier applied to input/request token cost.
> [card] Response Tokens
>
> Multiplier applied to output/response token cost.
> [card] Cache Read Tokens
>
> Multiplier applied to cache-read input token cost.
> [card] Cache Write Tokens
>
> Multiplier applied to cache-write input token cost.
For other token types — reasoning, audio/image/text variants, image generation, or per-unit charges like `web_search` — switch to **Custom** mode and provide a JSON object with the keys you want to adjust:
```json theme={"system"}
{
"multiplier": {
"default": 0.8,
"request_token": 0.7,
"response_token": 0.9,
"reasoning_token": 0.5,
"image": { "default": 0.9 },
"additional_units": { "web_search": 0.7 }
}
}
```
The multiplier keys mirror the pricing keys in [Portkey Models](/docs/product/model-catalog/portkey-models) — the open-source pricing database backing Portkey's cost tracking. Any key present in a model's `pay_as_you_go` (or in `additional_units`) can be adjusted here.
> [accordion] Full multiplier reference
>
> | Field | Applies to |
> | - | - |
> | `default` | Every token type unless a more specific multiplier is set |
> | `request_token` / `response_token` | Standard input and output tokens |
> | `cache_read_input_token` / `cache_write_input_token` | Prompt cache reads and writes |
> | `reasoning_token` | Reasoning/thinking tokens |
> | `request_audio_token` / `response_audio_token` / `cache_read_audio_input_token` | Audio modality tokens |
> | `request_text_token` / `response_text_token` / `cache_*_text_input_token` | Text-modality breakdowns where the provider reports them separately |
> | `request_image_token` / `response_image_token` / `cache_*_image_input_token` | Image-modality breakdowns |
> | `prediction_accepted_token` / `prediction_rejected_token` | Predicted-output tokens |
> | `image.default` | Per-image generation pricing across all qualities and sizes |
> | `additional_units.` | Per-unit charges such as `web_search`, `file_search`, `input_image`, `input_video_standard`. See [Additional Units Reference](/docs/product/model-catalog/portkey-models#additional-units-reference). |
## Per-Model Pricing Adjustments
Adjustments can also be set on an individual model within an Integration, using the same `pricing_adjustments` shape. This is useful when a negotiated rate applies to only part of a provider's catalog — for example a committed-use discount on one model family while the rest of the Integration bills at list price.
> [!NOTE]
>
> Per-model adjustments require Gateway version **2.22.0** or higher.
A model-level adjustment **fully replaces** the Integration-level one for that model — the two are not merged key by key. If a model defines `pricing_adjustments`, every multiplier for requests to that model comes from the model-level object, and any keys it omits fall back to `default` within that same object rather than to the Integration-level adjustment.
> [!WARNING]
>
> Because the replacement is whole-object, an Integration-level 20% discount does **not** carry over to a model that sets its own adjustment. Repeat any multipliers you still want, including `default`.
Models without their own `pricing_adjustments` continue to use the Integration-level adjustment.
> [!NOTE]
>
> If a model has its own custom pricing, that price is billed exactly as written — pricing adjustments set at the **model level or the Integration level are ignored** for that model. Other models in the same Integration are unaffected. To discount or mark up a custom-priced model, build the adjustment into the custom price itself.
## Setting Pricing Adjustments via the API
You can also configure Pricing Adjustments programmatically through the [Integrations API](/docs/api-reference/admin-api/control-plane/integrations/create-integration). Pass `pricing_adjustments` when creating or updating an Integration. Send `null` to clear all adjustments.
> [tab] cURL
>
> ```bash theme={"system"}
> curl -X PUT https://api.portkey.ai/v2/integrations/{integrationId} \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: YOUR_PORTKEY_API_KEY" \
> -d '{
> "pricing_adjustments": {
> "multiplier": {
> "default": 0.8,
> "cache_read_input_token": 0.9,
> "cache_write_input_token": 0.9
> }
> }
> }'
> ```
> [tab] Python
>
> ```python theme={"system"}
> import requests
>
> requests.put(
> "https://api.portkey.ai/v2/integrations/{integrationId}",
> headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
> json={
> "pricing_adjustments": {
> "multiplier": {
> "default": 0.8,
> "cache_read_input_token": 0.9,
> "cache_write_input_token": 0.9,
> }
> }
> },
> )
> ```
Once saved, Portkey applies the multipliers to the base pricing for every subsequent request through this Integration, and the adjusted cost flows into logs, analytics, and budget tracking.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Rate Limits
Source: https://docs.portkey.ai/docs/product/model-catalog/rate-limits
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Workload Identity Federation
Source: https://docs.portkey.ai/docs/product/model-catalog/workload-identity-federation
Connect OpenAI and Anthropic to Portkey without long-lived API keys, using short-lived tokens from Microsoft Entra ID, Okta, or any OIDC identity provider.
Workload Identity Federation (WIF) replaces a stored provider API key with a short-lived token from your own identity provider (IdP). Portkey never holds an OpenAI or Anthropic key. Revoke access by disabling the IdP app, the provider-side mapping, or the federation rule.
Supported providers: **OpenAI** and **Anthropic**.
Supported identity source: **Configured IdP** (`configuredIdp`). Portkey uses the OAuth 2.0 client credentials flow against your IdP.
## How it works
```mermaid theme={"system"}
sequenceDiagram
participant App as Your app
participant GW as Portkey Gateway
participant IdP as Your IdP (Entra / Okta)
participant P as OpenAI / Anthropic
App->>GW: Request with @provider-slug
GW->>IdP: 1. client_credentials (client_id + client_secret)
IdP-->>GW: Signed JWT (subject token)
GW->>P: 2. Exchange JWT at provider token endpoint
P-->>GW: Short-lived provider access token
GW->>P: Inference request (Authorization: Bearer)
```
1. **IdP token:** Portkey sends a `client_credentials` request to your IdP's token endpoint. The IdP returns a signed JWT for the Portkey client app.
2. **Provider exchange:** Portkey exchanges that JWT with the provider:
| Provider | Token endpoint | Grant |
| - | - | - |
| OpenAI | `https://auth.openai.com/oauth/token` | RFC 8693 token exchange (`subject_token`) |
| Anthropic | `https://api.anthropic.com/v1/oauth/token` | RFC 7523 JWT bearer (`assertion`) |
The provider verifies the JWT signature with your IdP's public keys. It checks `iss`, `aud`, and `sub` against your configured rules, then issues a short-lived access token for a service account.
Portkey caches both tokens and refreshes them before they expire. Provider tokens are cached for no more than 15 minutes. Rotating the client secret invalidates the cache.
## Setup overview
| Where | What to configure | Values to copy |
| - | - | - |
| **Identity provider** | A confidential client app that can use client credentials | Token endpoint, client ID, client secret, scope, and the issued token's `iss`, `aud`, and `sub` |
| **OpenAI / Anthropic** | Trust the IdP issuer, map the token to a service account | OpenAI: identity provider ID, service account ID. Anthropic: federation rule ID, organization ID, service account ID, and optional workspace ID |
| **Portkey** | An OpenAI or Anthropic integration that uses **Workload Identity Federation** | Everything from the first two rows |
Start with the IdP. The provider side needs the exact `iss`, `aud`, and `sub` values from a real token.
## Step 1: Configure the identity provider
> [tab] Microsoft Entra ID
>
> **1. Register an API app (the audience)**
>
> 1. Go to **Entra admin center → App registrations → New registration**. Name it `portkey-wif-api`.
> 2. Open **Expose an API** and set the **Application ID URI**, for example `api://`.
> 3. Open **Manifest** and set `requestedAccessTokenVersion` to `2`. In the legacy manifest, set `accessTokenAcceptedVersion` to `2`. This makes Entra issue v2 tokens with a stable issuer.
>
> **2. Register the client app (Portkey's identity)**
>
> 1. Create another registration named `portkey-wif-client`.
> 2. Go to **Certificates & secrets → New client secret**. Copy the secret value.
> 3. Optional but recommended: add an app role to `portkey-wif-api` with **Allowed member types: Applications**. Grant it to `portkey-wif-client` under **API permissions → Application permissions**, then grant admin consent.
>
> **3. Collect the values**
>
> | Portkey field | Value |
> | - | - |
> | Token Endpoint | `https://login.microsoftonline.com//oauth2/v2.0/token` |
> | Client ID | Client ID of `portkey-wif-client` |
> | Client Secret | Secret from step 2 |
> | Scope | `api:///.default` |
> | Audience | Leave empty |
>
> The resulting token contains:
>
> | Claim | Value |
> | - | - |
> | `iss` | `https://login.microsoftonline.com//v2.0` |
> | `aud` | Client ID of `portkey-wif-api` (a GUID) |
> | `sub` | Object ID of the `portkey-wif-client` **service principal** (Enterprise applications → Object ID), not its app registration object ID |
>
> > [!NOTE]
> >
> > Entra access tokens last 60–90 minutes. For Anthropic, set the issuer's maximum JWT lifetime to at least `5400` seconds. See [Step 2](#step-2-configure-the-provider).
> [tab] Okta
>
> **1. Set up a custom authorization server**
>
> Client credentials with custom scopes require a custom authorization server. The Okta org authorization server doesn't support them.
>
> 1. Go to **Security → API → Authorization Servers**. Use `default` or create a server named `portkey-wif`.
> 2. Set its **Audience**, for example `api://portkey-wif`.
> 3. Under **Scopes**, add a scope such as `portkey.wif`.
> 4. Under **Access Policies**, add a policy assigned to the client app. Add a rule that allows the **Client Credentials** grant and the `portkey.wif` scope.
>
> **2. Create the client app**
>
> 1. Go to **Applications → Create App Integration → API Services**. Name it `portkey-wif-client`.
> 2. Use client secret authentication. Portkey sends `client_id` and `client_secret` in the form body (`client_secret_post`).
> 3. Copy the client ID and secret.
>
> **3. Collect the values**
>
> | Portkey field | Value |
> | - | - |
> | Token Endpoint | `https:///oauth2//v1/token` |
> | Client ID | Client ID of `portkey-wif-client` |
> | Client Secret | Client secret |
> | Scope | `portkey.wif` |
> | Audience | Leave empty |
>
> The resulting token contains:
>
> | Claim | Value |
> | - | - |
> | `iss` | `https:///oauth2/` |
> | `aud` | The authorization server's Audience, for example `api://portkey-wif` |
> | `sub` | Client ID of `portkey-wif-client` |
> [tab] Other OIDC IdPs
>
> Any IdP works if it:
>
> * Supports the client credentials grant with `client_secret_post`
> * Returns a **signed JWT** access token, not an opaque token
> * Publishes OIDC discovery (`/.well-known/openid-configuration`) and a JWKS on a public HTTPS URL, or lets you upload or link a JWKS on the provider side
>
> Use **Audience** only when the IdP requires an `audience` form parameter, as Auth0 does. Portkey sends **Scope** as `scope` and **Audience** as `audience` in the token request.
### Verify the token
Request a token manually and decode it locally before configuring the provider. Don't paste production tokens into third-party JWT sites.
```sh theme={"system"}
curl -s -X POST "" \
-d grant_type=client_credentials \
--data-urlencode client_id="" \
--data-urlencode client_secret="" \
--data-urlencode scope="" \
| jq '.access_token | split(".")[1] | gsub("-"; "+") | gsub("_"; "/") | . + ("=" * ((4 - length % 4) % 4)) | @base64d | fromjson | {iss, aud, sub, iat, exp}'
```
The payload is unpadded base64url, so the `jq` filter converts it to padded Base64 before decoding.
Copy `iss`, `aud`, and `sub`. The provider configuration must match them exactly.
## Step 2: Configure the provider
> [tab] OpenAI
>
> Requires permission to manage Workload Identity Providers in the OpenAI organization.
>
> **1. Create a Workload Identity Provider**
>
> Go to [**Organization Settings → Security → Workload Identity Provider**](https://platform.openai.com/settings/organization/security/workload-identity-provider) and create an **OIDC** provider:
>
> | Field | Entra ID | Okta |
> | - | - | - |
> | OIDC Issuer URL | `https://login.microsoftonline.com//v2.0` | `https:///oauth2/` |
> | Audience | Client ID of `portkey-wif-api` | Authorization server Audience |
>
> Leave custom discovery and uploaded JWKS off. OpenAI fetches keys from the issuer's discovery document.
>
> **2. Add a service account mapping**
>
> From the provider details page, add a mapping:
>
> | Field | Value |
> | - | - |
> | Key | `sub` |
> | Value | Entra: service principal object ID. Okta: client ID |
> | Project | The project Portkey should use |
> | Service account | Create one or select an existing service account |
> | Permissions | Optional. Restrict the permissions Portkey needs, for example model inference |
>
> Use exact values instead of wildcards. If more than one enabled mapping matches, OpenAI rejects the exchange.
>
> **3. Copy the IDs**
>
> * **Identity Provider ID**: from the Workload Identity Provider
> * **Service Account ID**: from the mapped service account
>
> See OpenAI's [workload identity federation guide](https://developers.openai.com/api/docs/guides/workload-identity-federation) for CEL attribute transformations and JWKS options.
> [tab] Anthropic
>
> Requires an Anthropic organization admin. Configure it in **Claude Console → Workload identity** or with the [Admin API](https://platform.claude.com/docs/en/api/administration-api).
>
> **1. Create a service account**
>
> Create a service account and add it to the workspace Portkey should use. Copy the **Service Account ID**.
>
> **2. Register a federation issuer**
>
> | Field | Entra ID | Okta |
> | - | - | - |
> | Issuer URL | `https://login.microsoftonline.com//v2.0` | `https:///oauth2/` |
> | JWKS | OIDC discovery | OIDC discovery |
> | Max JWT lifetime | `5400` or higher, because Entra tokens last up to 90 minutes | Default (`3600`) |
> | Check JTI (replay protection) | Not applicable, because Entra tokens have no `jti` | **Disable** |
>
> > [!WARNING]
> >
> > Portkey reuses its cached IdP token while it's valid, including when it refreshes the Anthropic token. Okta tokens include a `jti`. With JTI checks enabled, Anthropic rejects the second exchange with that token. Disable JTI checks on Okta issuers used by Portkey.
>
> **3. Create a federation rule**
>
> | Field | Value |
> | - | - |
> | Issuer | The issuer from step 2 |
> | Match → subject | Exact `sub`. Entra: service principal object ID. Okta: client ID |
> | Match → audience | The token's `aud` |
> | OAuth scope | `workspace:inference` |
> | Target | The service account from step 1 |
> | Workspaces | One workspace, or all workspaces |
>
> **4. Copy the IDs**
>
> * **Federation Rule ID**
> * **Organization ID** from Console organization settings
> * **Service Account ID**
> * **Workspace ID**: required only when the rule applies to more than one workspace
## Step 3: Create the integration in Portkey
1. Go to [**Model Catalog → Add Provider**](https://app.portkey.ai/model-catalog/providers). Select **OpenAI** or **Anthropic**.
2. Select **Workload Identity Federation** as the authentication type.
3. Enter the IdP values from Step 1:
| Field | Description |
| - | - |
| Token Endpoint | IdP token endpoint. Must use public HTTPS unless the host is on your organization's egress allowlist |
| Client ID | IdP client app ID |
| Client Secret | IdP client secret. Stored encrypted and masked after saving; can reference a [secret](/docs/product/enterprise-offering/secret-references) |
| Scope (optional) | Scope sent in the client credentials request |
| Audience (optional) | `audience` parameter for IdPs that require it |
4. Enter the provider values from Step 2:
| OpenAI | Anthropic |
| - | - |
| Identity Provider ID | Federation Rule ID |
| Service Account ID | Organization ID |
| | Service Account ID |
| | Workspace ID (optional) |
5. Save, then create a provider, for example `@openai-wif`.
Requests don't change. Use the provider slug as usual:
```python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY", provider="@openai-wif")
response = portkey.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Hello"}],
)
```
### Create via Admin API
Use `provider_auth_type: "wif"` in `configurations` when calling [Create Integration](/docs/api-reference/admin-api/control-plane/integrations/create-integration). Don't send `key`. WIF integrations don't use a provider API key.
```json OpenAI theme={"system"}
{
"name": "OpenAI (WIF)",
"ai_provider_id": "open-ai",
"configurations": {
"provider_auth_type": "wif",
"wif_identity_source": "configuredIdp",
"oauth_token_endpoint": "https://login.microsoftonline.com//oauth2/v2.0/token",
"oauth_client_id": "",
"oauth_client_secret": "",
"oauth_scope": "api:///.default",
"openai_identity_provider_id": "",
"openai_service_account_id": ""
}
}
```
```json Anthropic theme={"system"}
{
"name": "Anthropic (WIF)",
"ai_provider_id": "anthropic",
"configurations": {
"provider_auth_type": "wif",
"wif_identity_source": "configuredIdp",
"oauth_token_endpoint": "https:///oauth2//v1/token",
"oauth_client_id": "",
"oauth_client_secret": "",
"oauth_scope": "portkey.wif",
"anthropic_federation_rule_id": "",
"anthropic_organization_id": "",
"anthropic_service_account_id": "",
"anthropic_workspace_id": ""
}
}
```
| Field | Required | Description |
| - | - | - |
| `provider_auth_type` | Yes | `wif` |
| `wif_identity_source` | No | `configuredIdp`. This is the default and only supported value |
| `oauth_token_endpoint` | Yes | IdP token endpoint |
| `oauth_client_id` | Yes | IdP client ID |
| `oauth_client_secret` | Yes | IdP client secret |
| `oauth_scope` | No | Scope for the IdP request |
| `oauth_audience` | No | `audience` parameter for the IdP request |
| `openai_identity_provider_id` | OpenAI | OpenAI Workload Identity Provider ID |
| `openai_service_account_id` | OpenAI | OpenAI service account ID |
| `openai_organization`, `openai_project` | No | Sent as `OpenAI-Organization` and `OpenAI-Project` headers |
| `anthropic_federation_rule_id` | Anthropic | Anthropic federation rule ID |
| `anthropic_organization_id` | Anthropic | Anthropic organization ID |
| `anthropic_service_account_id` | Anthropic | Anthropic service account ID |
| `anthropic_workspace_id` | No | Required when the rule spans multiple workspaces |
## Troubleshooting
Portkey returns only the standard OAuth error code, such as `invalid_client`. The full IdP or provider response stays in gateway logs and never goes back to the caller.
| Error | Cause | Fix |
| - | - | - |
| `OAuth token acquisition failed: invalid client credentials` | The IdP rejected the client ID or secret | Check the secret value and expiry. In Okta, confirm the app allows `client_secret_post` |
| `OAuth token endpoint returned 400 (invalid_scope)` | The scope isn't allowed | Entra: use `api:///.default`. Okta: add the scope to the access policy rule |
| `OpenAI WIF token exchange failed: subject token rejected` | OpenAI rejected the JWT or no mapping matched | Compare `iss` and `aud` with the provider, and `sub` with the mapping. Check that exactly one mapping is enabled |
| `Anthropic WIF token exchange failed: subject token rejected` | Anthropic rejected the JWT or no rule matched | Compare the issuer URL, rule subject, and audience. Check the max JWT lifetime for Entra and JTI checks for Okta |
| `WIF config incomplete: ... required` | A provider ID is missing | Fill in every required provider field |
| `Invalid or unsafe URL` | The token endpoint is private or uses HTTP | Use the IdP's public HTTPS endpoint, or add the host to the egress allowlist |
## Security recommendations
* Use a dedicated IdP client app and provider service account for each Portkey integration and environment.
* Match `sub` exactly. Avoid wildcard or prefix matches.
* Restrict provider permissions: use mapping **Permissions** in OpenAI and `workspace:inference` in Anthropic.
* Store the client secret in a [secret manager](/docs/product/enterprise-offering/secret-references) and rotate it regularly.
* To revoke access immediately, disable the OpenAI mapping or Anthropic rule. Cached tokens expire within 15 minutes.
# Workspace Provisioning
Source: https://docs.portkey.ai/docs/product/model-catalog/workspace-provisioning
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Observability (OpenTelemetry)
Source: https://docs.portkey.ai/docs/product/observability
Gain real-time insights, track key metrics, and streamline debugging with our comprehensive observability suite.
If you're working with an LLM - visibility across all your requests can be a BIG pain. How do you trace and measure cost, latency, accuracy of your requests?
Portkey's OpenTelemetry-compliant observability suite gives you complete control over all your requests. And Portkey's analytics dashboards provide the insights you're looking for. Fast.

## Features
> [card] [Logs](/docs/product/observability/logs)
>
> Portkey records all your multimodal requests and responses, making it easy to view, monitor, and debug interactions.
> [card] [Tracing](/docs/product/observability/traces)
>
> Portkey supports request tracing to help you monitor your applications throughout the lifecycle of a request.
> [card] [Analytics](/docs/product/observability/analytics)
>
> A comprehensive view of 21+ key metrics. Use it to analyze data, spot trends, and make informed decisions.
> [card] [Filters](/docs/product/observability/filters)
>
> Streamline your data view with customizable filters. Zero in on data that matters most.
> [card] [Custom Metadata](/docs/product/observability/metadata)
>
> Enrich your LLM APIs with custom metadata. Assign unique tags for swift grouping and troubleshooting.
> [card] [Feedback](/docs/product/observability/feedback)
>
> Add feedback values and weights to complete the loop.
> [card] [Budget Limits](/docs/product/model-catalog/integrations#3-budget-%26-rate-limits)
>
> Set up budget limits for your provider API keys and gain confidence over your application's costs.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Analytics
Source: https://docs.portkey.ai/docs/product/observability/analytics
> [!NOTE]
>
> This feature is available for all plans:-
>
> * [Developer](https://app.portkey.ai/): 30 days retention
> * [Production](https://app.portkey.ai/): 365 days retention
> * [Enterprise](https://portkey.ai/docs/product/enterprise-offering): Unlimited
As soon as you integrate Portkey, you can start to view detailed & real-time analytics on cost, latency and accuracy across all your LLM requests.
The analytics dashboard provides an interactive interface to understand your LLM application Here, you can see various graphs and metrics related to requests to different LLMs, costs, latencies, tokens, user activity, feedback, cache hits, errors, and much more.
The metrics in the Analytics section can help you understand the overall efficiency of your application, discover patterns, identify areas of optimization, and much more.

## Charts
The dashboard provides insights into your [users](/docs/product/observability/analytics#users), [errors](/docs/product/observability/analytics#errors), [cache](/docs/product/observability/analytics#cache), [feedback](/docs/product/observability/analytics#feedback) and a configurable [summary](/docs/product/observability/analytics#summary) view across your requests.
### Overview
The overview tab is a 70,000ft view of your application's performance. This highlights the cost, tokens used, mean latency, requests and information on your users and top models.
This is a good starting point to then dive deeper.
### Users
The users tab provides an overview of the user information associated with your Portkey requests. This data is derived from the `user` parameter in OpenAI SDK requests or the special `_user` key in the Portkey [metadata header](/docs/product/observability/metadata).
Portkey currently does not provide analytics on usage patterns for individual team members in your Portkey organization. The users tab is designed to track end-user behavior in your application, not internal team usage.

### Errors
Portkey captures errors automatically for API and Accuracy errors. The charts give you a quick sense of error rates allowing you to debug further when needed.
The dashboard also shows you the number of requests rescued by Portkey through the various AI gateway strategies.

Error Analytics Dashboard
### Cache
When you enable cache through the AI gateway, you can view data on the latency improvements and cost savings due to cache.
### Feedback
Portkey allows you to collect feedback on LLM requests through the logs dashboard or via API. You can view analytics on this feedback collected on this dashboard.
### Summary
Group your request data by any dimension — AI Service, model, metadata key, and more — to unlock insights on usage. Select the dimension in the dropdown to view aggregate metrics (total requests, total cost, average latency, success rate, average tokens, last seen) for each value.
This lets you answer questions like:
1. Which AI services are we spending the most on?
2. Which models have the lowest success rate?
3. Which users or organisations have the highest latency?

Summary Analytics
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Auto-Instrumentation [BETA]
Source: https://docs.portkey.ai/docs/product/observability/auto-instrumentation
Portkey's auto-instrumentation allows you to instrument tracing and logging for multiple LLM/Agent frameworks and view the logs, traces, and metrics in a single place.
> [!WARNING]
>
> This feature is currently in beta. We're rolling out support for more frameworks and will also be exposing the otel collector endpoint to view the traces and logs.
## Overview
There's two main components to auto-instrumentation:
1. The Portkey SDK, which can be used for tracing along with being used as a unified API gateway.
2. The Portkey dashboard, which can be used to view the logs, traces, and metrics.
## Portkey SDK
Using portkey for auto-instrumentation is fairly straightforward. A one line addition at the top of your code execution will start sending traces and logs to Portkey.
```python theme={"system"}
from portkey import Portkey
Portkey(api_key="{{PORTKEY_API_KEY}}", instrumentation=True)
```
## Portkey Dashboard
The Portkey dashboard can be used to view the logs, traces, and metrics.

## Supported Frameworks
We currently support auto-instrumentation for the following frameworks:
* [CrewAI](/docs/integrations/agents/crewai#auto-instrumentation)
* [LangGraph](/docs/integrations/agents/langgraph#auto-instrumentation)
> [!NOTE]
>
> To request support for another framework, please reach out to us via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Budget Limits
Source: https://docs.portkey.ai/docs/product/observability/budget-limits
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Model Pricing and Cost Management
Source: https://docs.portkey.ai/docs/product/observability/cost-management
Learn how Portkey handles pricing data, cost calculations, and pricing updates across different deployment modes.
Portkey tracks pricing for all providers and models for which it has pricing support, providing real-time cost visibility and budget management capabilities. The platform automatically handles pricing updates and supports custom pricing configurations for enterprise customers.
## How Pricing Data Works
### Pricing JSON System
Portkey uses a centralized pricing JSON system to maintain accurate cost information:
* **Automatic Updates**: If you're on the latest versions, this JSON updates automatically with the latest numbers
* **Caching Strategy**: Pricing data is cached for 24 hours, after which the latest values are pulled from the central control plane
* **Version Requirements**: This automatic pricing update feature is available in gateway version 1.12 series and later
### Cost Calculation
For token-based budgets, Portkey tracks both input and output tokens across all supported models. Cost calculations include:
* Input token costs based on provider pricing
* Output token costs with different rates where applicable
* Real-time cost tracking per request
* Aggregated cost reporting across time periods
## Deployment-Specific Pricing Management
Portkey supports two deployment modes for new customers, each with different pricing update mechanisms. Air-gapped is documented below for existing deployments only.
### 1. SaaS Deployment (Portkey Cloud)
* **Update Frequency**: Instant pricing updates
* **Management**: Fully managed by Portkey
* **Maintenance**: No action required from customers
### 2. Hybrid Deployment
* **Update Frequency**: Automatic updates every 24 hours
* **Gateway Version**: Requires version 1.12+ for automatic updates
* **Maintenance**: Minimal - pricing JSON updates automatically from central control plane
* **Manual Updates**: Only required when new pricing features are introduced
### 3. Air-Gapped Deployment (Legacy)
> [!NOTE]
>
> Air-gapped deployment is no longer offered for new customers. This section applies to existing air-gapped deployments, which remain supported.
* **Update Frequency**: Configurable — can be automatic (with outbound access) or manual
* **Management**: Customer-managed pricing sources
* **Process**: Pricing data can be fetched from Portkey's hosted config service, loaded from a log store, or mounted as local files. See the [Air-Gapped Model Pricing guide](/docs/self-hosting/airgapped/model-pricing) for setup options
* **Requirements**: Helm chart `app-1.5.0+`, Backend `v1.7.0+`, Enterprise Gateway `v2.0.0+`
## Model Catalog and Custom Pricing
### Upgrading to Model Catalog
The [Model Catalog](/docs/product/model-catalog) is the evolution of Virtual Keys, providing a centralized and powerful way to manage, discover, and use AI models within your workspace. Key benefits include:
* **Centralized Management**: Create a single (or multiple) provider integration at the organization level, and securely provision it to multiple workspaces
* [**Custom Pricing Support**](/docs/product/model-catalog/custom-models): Update pricing for models directly from the UI
* [**Model Overrides**](/docs/product/model-catalog/model-overrides): Create custom models with specific pricing configurations
### Custom Model Pricing
For customers with preferential pricing from providers, Portkey offers:
* **UI-Based Updates**: Modify pricing for existing models through the dashboard
* [**Custom Models**](/docs/product/model-catalog/custom-models): Create new model entries with specific pricing
* [**Model Overrides**](/docs/product/model-catalog/model-overrides): Override default pricing for specific use cases
* [**Pricing Adjustments**](/docs/product/model-catalog/pricing-adjustments): Apply a discount or markup multiplier across an entire Integration
## Cost Tracking and Analytics
### Real-Time Monitoring
The AI gateway records real-time API requests, including cost and guardrail violations, providing:
* Per-request cost visibility
* Token usage tracking
* Provider-specific cost breakdown
* Time-based cost analysis
### Analytics Dashboard
You can track your spending and token usage for any specific providers and model by navigating to the [Analytics tab](/docs/product/observability/analytics) and filtering by the desired key and timeframe.
**Available Metrics**:
* Total spend across providers
* Cost per model/provider/token
* Usage patterns and trends
* Budget utilization tracking
## Pricing Support Coverage
### Supported Models
Budget limits currently apply to all providers and models for which Portkey has pricing support. This includes:
* All major LLM providers (OpenAI, Claude, etc.)
* Vision and multimodal models
* Audio processing models
* Image generation models
### Unsupported Models
If a specific request log shows 0 cents in the COST column, it means that Portkey does not currently track pricing for that model, and it will not count towards the provider's budget limit.
For models without pricing support:
* Cost tracking shows \$0.00
* Budget limits don't apply
* Manual cost tracking may be required
## Troubleshooting Pricing Issues
### Common Issues and Solutions
**Q: Pricing data seems outdated**
* **A**: Ensure you're running gateway version 1.12+. Pricing updates automatically every 24 hours.
**Q: Custom pricing not reflecting in dashboard**
* **A**: Upgrade to Model Catalog for UI-based pricing management. Contact enterprise support for custom pricing configuration.
**Q: Token count and cost show as 0 for streaming requests**
* **A**: When `stream: true`, the provider does not return usage data by default — no token counts means no cost calculation. Add `stream_options: { include_usage: true }` to your request:
```python Python theme={"system"}
response = client.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Hello"}],
stream=True,
stream_options={"include_usage": True}
)
```
```js JavaScript theme={"system"}
const response = await client.chat.completions.create({
model: "gpt-4o",
messages: [{ role: "user", content: "Hello" }],
stream: true,
stream_options: { include_usage: true }
})
```
This applies to all OpenAI-compatible providers (including Azure OpenAI). Non-streaming requests include usage data automatically and are unaffected.
**Q: Budget limits not working for specific models**
* **A**: Verify that Portkey has pricing support for those models. Unsupported models show \$0.00 in cost tracking.
**Q: Air-gapped deployment has stale pricing**
* **A**: Configure dynamic pricing fetching via the [Air-Gapped Model Pricing guide](/docs/self-hosting/airgapped/model-pricing). You can pull from Portkey's hosted config service, maintain a local copy from the [Portkey Models repo](https://github.com/Portkey-AI/models), or mount pricing files as volumes.
### Enterprise Support
For enterprise customers requiring:
* Custom pricing configurations
* Advanced budget management
* Pricing data exports
* Integration assistance
Contact: [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form)
## Best Practices
### Cost Optimization
1. **Use Budget Limits**: Set appropriate spending limits to prevent overages
2. **Monitor Usage**: Regularly review cost analytics to identify optimization opportunities
3. **Model Selection**: Use cost-effective models for appropriate use cases
4. **Caching**: Leverage Portkey's caching features to reduce redundant API calls
### Pricing Management
1. **Stay Updated**: Keep gateway versions current for automatic pricing updates
2. **Regular Reviews**: Monitor pricing changes across providers
3. **Custom Pricing**: Configure preferential rates when available
4. **Budget Planning**: Set realistic budgets based on usage patterns
## Support and Resources
### Community Resources
* [GitHub repository](https://github.com/portkey-ai/gateway) for technical issues
***
*This documentation covers Portkey's pricing management capabilities. For the most current information about specific model pricing or enterprise features, please [Contact support](https://support.portkey.ai/forms/customer-portal-ticket-form).*
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Feedback
Source: https://docs.portkey.ai/docs/product/observability/feedback
Portkey's Feedback APIs provide a simple way to get weighted feedback from customers on any request you served, at any stage in your app.
> [!NOTE]
>
> This feature is available on all Portkey plans.
You can capture this feedback on a request or conversation level and analyze it by adding meta data to the relevant request.
## Adding Feedback to Requests
### 1. Find the \`trace-id\`
Portkey adds trace ids to all incoming requests. You can find this in the `x-portkey-trace-id` response header.
To use your own trace IDs, send them as part of the request headers - [Adding a trace ID to your requests](/docs/product/observability/traces#how-to-enable-request-tracing)
### 2. Add feedback
You can append feedback to a request through the SDKs or the REST API.
> [tab] NodeJS
>
> ```js theme={"system"}
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY"
> });
>
> // Add the feedback
> portkey.feedback.create({
> traceID: "your trace id",
> value: 5, // Integer between -10 and 10
> weight: 1, // Optional
> metadata: {
> ... // Pass any additional context here like comments, _user and more
> }
> })
> ```
> [tab] Python
>
> ```python theme={"system"}
> portkey = Portkey(
> api_key="PORTKEY_API_KEY"
> )
>
> feedback = portkey.feedback.create(
> trace_id="TRACE_ID",
> value=5, # Integer between -10 and 10
> weight=1, # Optional
> metadata={
> # Pass any additional context here like comments, _user and more
> }
> )
> print(feedback)
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl --location 'https://api.portkey.ai/v1/feedback' \
> --header 'x-portkey-api-key: YOUR_API_KEY' \
> --header 'Content-Type: application/json' \
> --data '{
> "trace_id": "YOUR_TRACE_ID",
> "value": -10,
> "weight": 0.5,
> "metadata": {
> "text": "title was irrelevant",
> "_user": "fef653",
> "_organisation": "o9876",
> "_prompt": "test_prompt",
> "_environment": "production"
> }
> }'
> ```
The **Payload** takes the following keys: `trace_id, value, weight, metadata`
| Key | Required? | Description | Type |
| - | - | - | - |
| trace\_id | Required | The trace id on which the feedback will be logged | string |
| value | Required | Feedback value | integer between \[-10,10] |
| weight | Optional | Add weight value to feedback value. Helpful if you're collecting multiple feedback for a single trace | float between \[0,1], Default = 1.0 |
| metadata | Optional | JSON string of any metadata you want to send along with the feedback.\_user, \_organisation, \_prompt and \_environment are special fields indexed by default | string |
### Examples
A simple & effective feedback from the user is a thumbs up or thumbs down. Just set `value` to `1` for 👍 and -1 for 👎. `Weight` would be default `1.0`.
> [tab] NodeJS
>
> ```js theme={"system"}
> portkey.feedback.create({
> traceID: "your trace id",
> value: 1
> })
> ```
> [tab] Python
>
> ```py theme={"system"}
> portkey.feedback.create(
> trace_id = "your trace id",
> value = 1
> )
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl --location 'https://api.portkey.ai/v1/feedback' \
> --header 'x-portkey-api-key: ' \
> --header 'Content-Type: application/json' \
> --data '{
> 'trace_id': 'REQUEST_TRACE_ID',
> 'value': 1
> }'
> ```
#### Other Ideas for collecting feedback
* Business metrics make for great feedback. If you're generating an email, the email being sent out could be a positive feedback metric. The level of editing could indicate the value.
* When a user retries a generation, store the negative feedback since something probably went wrong. Use a lower weight for this feedback since it could be circumstantial.
### Feedback Analytics
You can see the `Feedback Count` and `Value: Weight` pairs for each `trace-id` on the logs page. You can also view the feedback details on [Analytics](/docs/product/observability/analytics#feedback) and on the Prompt Eval tabs.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Filters
Source: https://docs.portkey.ai/docs/product/observability/filters
> [!NOTE]
>
> This feature is available on all Portkey plans.
You can filter analytics & logs by the following parameters:
1. **Model Used**: The AI provider and the model used.
2. **Cost**: The cost of the request in cents
3. **Tokens**: The total number of tokens used in the request
4. **Status**: The API status of the response that was received from the LLM provider
5. **Meta**: The [metadata](/docs/product/observability/metadata) properties sent to Portkey
6. **Avg Weighted Feedback**: The average weighted feedback scores calculated for the requests
7. **Provider:** The provider that's used
8. **Config:** The Config ID that's passed to the request
9. **Trace ID:** Request trace ID
10. **Time Range**: The date and time range for the analytics & logs
11. **API Key**: The API Key used to make the request
12. **Prompt ID**: The unique request ID
13. **Cache Status**: The status of the cache for the request
14. **Workspace**: The workspace used to make the request
15. **Saved Filters**: The saved filters that you can use to quickly access your frequently used filter combinations
> [!NOTE]
>
> Depending on your role in the organization, you may have access to different filters.

## Saved Filters
Quickly access your frequently used filter combinations with the `Saved Filters` feature. Save any set of filters directly from the search bar on the Logs or Analytics pages. Saved filters allow you to instantly apply complex filter rules without retyping them every time.

Saved filters are accessible to all organization members, who can also edit, rename, or delete them as needed. Share saved filters with teammates to streamline collaboration and ensure everyone has access to the right data views.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Logs
Source: https://docs.portkey.ai/docs/product/observability/logs
The Logs section presents a chronological list of all the requests processed through Portkey.
> [!NOTE]
>
> This feature is available for all plans:
>
> * [Developer](https://app.portkey.ai/): 10k Logs / Month with 3 day Log Retention
> * [Production](https://app.portkey.ai/): 100k Logs / Month + \$9 for additional 100k with 30 Days Log Retention
> * [Enterprise](https://portkey.ai/docs/product/enterprise-offering): Unlimited
Each log entry provides useful data such as the timestamp, request type, LLM used, tokens generated, thinking tokens and cost. For [multimodal models](/docs/product/ai-gateway/multimodal-capabilities), Logs will also show the image sent with vision/image models, as well as the image generated.
By clicking on an entry, a side panel opens up, revealing the entire raw data with the request and response objects.
This detailed log can be invaluable when troubleshooting issues or understanding specific interactions. It provides full transparency into each request and response, enabling you to see exactly what data was sent and received.

## Share Logs with Teammates
Each log on Portkey has a unique URL. You can copy the link from the address bar and directly share it with anyone in your org.
## Request Status Guide
The Status column on the Logs page gives you a snapshot of the gateway activity for every request.
Portkey’s gateway features—[Cache](/docs/product/ai-gateway/cache-simple-and-semantic), [Retries](/docs/product/ai-gateway/automatic-retries), [Fallback](/docs/product/ai-gateway/fallbacks), [Loadbalance](/docs/product/ai-gateway/load-balancing) are tracked here with their exact states (`disabled`, `triggered`, etc.), making it a breeze to monitor and optimize your usage.
**Common Queries Answered:**
* **Is the cache working?**: Enabled caching but unsure if it's active? The Status column will confirm it for you.
* **How many retries happened?**: Curious about the retry count for a successful request? See it in a glance.
* **Fallback and Loadbalance**: Want to know if load balance is active or which fallback option was triggered? See it in a glance.

| Option | 🔴 Inactive State | 🟢 Possible Active States |
| - | - | - |
| **Cache** | Cache Disabled | Cache Miss,Cache Refreshed,Cache Hit,Cache Semantic Hit |
| **Retry** | Retry Not Triggered | Retry Success on Tries,Retry Failed |
| **Fallback** | Fallback Disabled | Fallback Active |
| **Loadbalance** | Loadbalancer Disabled | Loadbalancer Active |
## Manual Feedback
As you're viewing logs, you can also add manual feedback on the logs to be analysed and filtered later. This data can be viewed on the [feedback analytics dashboards](/docs/product/observability/analytics#feedback).

## Configs & Prompt IDs in Logs
If your request has an attached [Config](/docs/product/ai-gateway/configs) or if it's originating from a [prompt template](/docs/product/prompt-library), you can see the relevant Config or Prompt IDs separately in the log's details on Portkey. And to dig deeper, you can just click on the IDs and Portkey will take you to the respective Config or Prompt playground where you can view the full details.

## Debug Requests with Log Replay
You can rerun any buggy request with just one click, straight from the log details page. The `Replay` button opens your request in a fresh prompt playground where you can rerun the request and edit it right there until it works.

> [!NOTE]
>
> `Replay` **button will be inactive for a log in the following cases:**
>
> 1. If the request is sent to any endpoint other than `/chat/completions,` `/completions`, `/embeddings`
> 2. If the provider used in the log is archived on Portkey
> 3. If the request originates from a prompt template which is called from inside a Config target
## DO NOT TRACK
The `DO NOT TRACK` option allows you to process requests without logging the request and response data. When enabled, only high-level statistics like **tokens** used, **cost**, and **latency** will be recorded, while the actual request and response content will be omitted from the logs.
This feature is particularly useful when dealing with sensitive data or complying with data privacy regulations. It ensures that you can still capture critical operational metrics without storing potentially sensitive information in your logs.
To enable `DO NOT TRACK` for a specific request, set the `debug` flag to `false` when instantiating your **Portkey** or **OpenAI** client, or include the `x-portkey-debug:false` header with your request.
> [tab] Node SDK
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> provider:"@OPENAI_PROVIDER",
> apiKey: "PORTKEY_API_KEY",
> debug: false
> })
>
> async function main(){
> const response = await portkey.chat.completions.create({
> messages: [{ role: 'user', content: '1729' }],
> model: 'gpt-4',
> });
> console.log(response.choices[0].message?.content)
> }
>
> main()
> ```
> [tab] Python SDK
>
> ```Python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@OPENAI_PROVIDER",
> debug=False
> )
>
> response = portkey.chat.completions.create(
> messages=[{'role': 'user', 'content': 'Say this is a test'}],
> model='gpt-4'
> )
>
> print(response.choices[0].message.content)
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl 'https://api.portkey.ai/v1/chat/completions' \
> -H 'Content-Type: application/json' \
> -H 'x-portkey-provider: $OPENAI_PROVIDER' \
> -H 'x-portkey-api-key: $PORTKEY_API_KEY' \
> -H 'x-portkey-debug: false' \
> -d '{
> "model": "gpt-4o",
> "messages": [
> {
> "role": "system",
> "content": "You are a helpful assistant"
> },
> {
> "role": "user",
> "content": "what is a portkey?"
> }
> ]
> }'
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> client = OpenAI(
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="@OPENAI_PROVIDER",
> api_key="PORTKEY_API_KEY",
> debug=False
> )
> )
>
> chat_complete = client.chat.completions.create(
> model="gpt-4",
> messages=[{"role": "user", "content": "Say this is a test"}],
> )
>
> print(chat_complete.choices[0].message.content)
> ```
> [tab] OpenAI Node
>
> ```js theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider:"@OPENAI_PROVIDER",
> apiKey: "PORTKEY_API_KEY",
> debug: false
> })
> });
>
> async function main() {
> const chatCompletion = await openai.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: 'gpt-3.5-turbo',
> });
> console.log(chatCompletion.choices);
> }
>
> main();
> ```
### Side-by-side comparison on how a `debug:false` request will be logged

***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Logs Export
Source: https://docs.portkey.ai/docs/product/observability/logs-export
Easily access your Portkey logs data for further analysis and reporting
> [!NOTE]
>
> Logs export feature is only available on the enterprise plan. For more info reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form)
> [!NOTE]
>
> [Data Service](/docs/changelog/data-service) must be enabled to use the Logs Export feature for Self Hosted Enterprise customers.
At Portkey, we understand the importance of data analysis and reporting for businesses and teams. That's why we provide a comprehensive logs export feature that allows you to download your Portkey logs data in a **structured format**, enabling you to gain valuable insights into your LLM usage, performance, costs, and more.
## Exporting Logs In-App
You can now export logs directly from the Portkey application by following these steps:
1. Navigate to the **Exports** section on the main sidebar.
2. Click the **Request Data** button in the top-right corner.
3. Configure your export parameters:
* **Time Range**: Select the period for which you want to export logs
* **Logs Limits**: Choose maximum number of logs or set a custom offset
* **Requested Fields**: Select which data columns to include in your export

4. After setting your parameters, click **Request Export**.
## Available Export Fields
When configuring your log export, you can select from the following fields:
| Field Name | Description |
| - | - |
| ID | Unique identifier for the log entry |
| Trace ID | Identifier for tracing related requests |
| Created At | Timestamp of the request |
| Request | Request JSON payload |
| Response | Response JSON payload |
| AI Provider | Name of the AI provider used |
| AI Model | Name of the AI model used |
| Request Tokens | Number of tokens in the request |
| Response Tokens | Number of tokens in the response |
| Total Tokens | Total number of tokens (request + response) |
| Cost | Cost of the request in cents (USD) |
| Cost Currency | Currency of the cost (USD) |
| Response Time | Response time in milliseconds |
| Status Code | HTTP response status code |
| Config | Config ID used for the request |
| Prompt Slug | Prompt ID used for the request |
| Metadata | Custom metadata key-value pairs |
> [!NOTE]
>
> Admins can block specific fields from being exported. See [Restricting exportable fields](#restricting-exportable-fields) below.
5. Once your export is processed, you'll see it in the exports list with a status indicator:
* **Draft**: Export job created but not yet started
* **Success**: Export completed successfully
* **Failure**: Export job failed. Click on the `Start Again` button to retry the job.
6. Clik on the **Start** button the dashboard to start the logs-export job
7. For completed exports, click the **Download** button to get your logs data file. You can

> [!NOTE]
>
> Currently we only support exporting 50k logs per job. For more help reach out to the Portkey team via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form)
## Restricting Exportable Fields
Organisation owners and admins can prevent sensitive log fields — such as `request` and `response` payloads or `metadata` — from leaving Portkey through exports.
Set `export_settings.deniedFields` on the organisation to apply the restriction everywhere:
```json theme={"system"}
{
"export_settings": {
"deniedFields": ["request", "response", "metadata"]
}
}
```
Every entry must be a valid log export field id (`id`, `trace_id`, `created_at`, `request`, `response`, `ai_org`, `ai_model`, `req_units`, `res_units`, `total_units`, `request_url`, `cost`, `cost_currency`, `response_time`, `response_status_code`, `config`, `prompt_slug`, `metadata`).
Individual workspaces can set their own `export_settings` only if the organisation has enabled the `export_settings` [workspace override](/docs/product/administration/enforce-default-config). Otherwise the organisation's list applies to all workspaces.
Creating or updating an export that requests a denied field is rejected. To check what a workspace is allowed to export before building a request, call:
```bash theme={"system"}
curl "https://api.portkey.ai/v1/logs/exports/field-restrictions?workspace_id=WORKSPACE_ID" \
-H "x-portkey-api-key: YOUR_PORTKEY_API_KEY"
```
## Export File Details
Exported logs are provided in JSONL format (JSON Lines), where each line is a valid JSON object representing a single log entry. This format is ideal for data processing and analysis with tools like Python's Pandas or other data analysis frameworks.
Each export includes:
* Up to 50,000 logs per export job (as shown in the preview panel)
* All fields selected during the export configuration
* A timestamp indicating when the export was created
## Use Cases for Exported Logs
With your exported logs data, you can:
* Generate custom reports for stakeholders
* Feed data into business intelligence tools
* Identify patterns in user behavior and model performance
You can analyze your API usage patterns, monitor performance, optimize costs, and make data-driven decisions for your business or team.
## Exporting logs via API
You can programmatically export logs using the Log Export API. This follows an asynchronous workflow:
1. **Create an export job** — Define your export parameters
2. **Start the export** — Begin processing the export
3. **Poll for status** — Check until the job completes
4. **Download the file** — Retrieve the JSONL file via signed URL
### Prerequisites
* API key with `logs.export` scope enabled
* For completion logs, the `completion` scope may also be required
### Step 1: Create a log export
Create an export job by specifying the time range and fields you want to export.
```python Python theme={"system"}
from portkey_ai import Portkey
client = Portkey(api_key="YOUR_PORTKEY_API_KEY")
export = client.logs.exports.create(
filters={
"created_at": {
"gte": "2024-01-01T00:00:00Z",
"lte": "2024-01-31T23:59:59Z"
}
},
requested_data=[
"id",
"trace_id",
"created_at",
"request",
"response",
"ai_provider",
"ai_model",
"request_tokens",
"response_tokens",
"total_tokens",
"cost",
"response_time",
"status_code"
],
workspace_id="YOUR_WORKSPACE_ID" # Optional
)
export_id = export.id
print(f"Export created with ID: {export_id}")
```
```typescript Node.js theme={"system"}
import Portkey from "portkey-ai";
const client = new Portkey({ apiKey: "YOUR_PORTKEY_API_KEY" });
const exportJob = await client.logs.exports.create({
filters: {
created_at: {
gte: "2024-01-01T00:00:00Z",
lte: "2024-01-31T23:59:59Z",
},
},
requested_data: [
"id",
"trace_id",
"created_at",
"request",
"response",
"ai_provider",
"ai_model",
"request_tokens",
"response_tokens",
"total_tokens",
"cost",
"response_time",
"status_code",
],
workspace_id: "YOUR_WORKSPACE_ID", // Optional
});
const exportId = exportJob.id;
console.log(`Export created with ID: ${exportId}`);
```
```bash cURL theme={"system"}
curl -X POST "https://api.portkey.ai/v1/logs/exports" \
-H "x-portkey-api-key: YOUR_PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"filters": {
"created_at": {
"gte": "2024-01-01T00:00:00Z",
"lte": "2024-01-31T23:59:59Z"
}
},
"requested_data": [
"id",
"trace_id",
"created_at",
"request",
"response",
"ai_provider",
"ai_model",
"request_tokens",
"response_tokens",
"total_tokens",
"cost",
"response_time",
"status_code"
]
}'
```
### Step 2: Start the export
Once the export job is created, start processing it.
```python Python theme={"system"}
client.logs.exports.start(export_id)
print("Export job started")
```
```typescript Node.js theme={"system"}
await client.logs.exports.start(exportId);
console.log("Export job started");
```
```bash cURL theme={"system"}
curl -X POST "https://api.portkey.ai/v1/logs/exports/{export_id}/start" \
-H "x-portkey-api-key: YOUR_PORTKEY_API_KEY"
```
### Step 3: Poll for completion
Check the export status until it returns `success`.
```python Python theme={"system"}
import time
while True:
status = client.logs.exports.retrieve(export_id)
print(f"Status: {status.status}")
if status.status == "success":
print("Export completed!")
break
elif status.status == "failure":
print(f"Export failed: {status.error}")
break
time.sleep(5) # Wait 5 seconds before polling again
```
```typescript Node.js theme={"system"}
const pollForCompletion = async (exportId: string) => {
while (true) {
const status = await client.logs.exports.retrieve(exportId);
console.log(`Status: ${status.status}`);
if (status.status === "success") {
console.log("Export completed!");
break;
} else if (status.status === "failure") {
console.log(`Export failed: ${status.error}`);
break;
}
await new Promise((resolve) => setTimeout(resolve, 5000)); // Wait 5 seconds
}
};
await pollForCompletion(exportId);
```
```bash cURL theme={"system"}
curl "https://api.portkey.ai/v1/logs/exports/{export_id}" \
-H "x-portkey-api-key: YOUR_PORTKEY_API_KEY"
```
### Step 4: Download the export
Once the export is complete, retrieve the signed download URL.
```python Python theme={"system"}
download_response = client.logs.exports.download(export_id)
download_url = download_response.url
print(f"Download URL: {download_url}")
# Download the file
import requests
response = requests.get(download_url)
with open("logs_export.jsonl", "wb") as f:
f.write(response.content)
print("Logs exported to logs_export.jsonl")
```
```typescript Node.js theme={"system"}
const downloadResponse = await client.logs.exports.download(exportId);
const downloadUrl = downloadResponse.url;
console.log(`Download URL: ${downloadUrl}`);
// Download the file using fetch
const fileResponse = await fetch(downloadUrl);
const fileContent = await fileResponse.text();
// Save to file (Node.js)
import fs from "fs";
fs.writeFileSync("logs_export.jsonl", fileContent);
console.log("Logs exported to logs_export.jsonl");
```
```bash cURL theme={"system"}
# Get the download URL
curl "https://api.portkey.ai/v1/logs/exports/{export_id}/download" \
-H "x-portkey-api-key: YOUR_PORTKEY_API_KEY"
# Then download using the returned URL
curl -o logs_export.jsonl "{signed_download_url}"
```
### Complete example
Here's a complete script that creates, starts, monitors, and downloads a log export:
```python Python theme={"system"}
import time
import requests
from portkey_ai import Portkey
client = Portkey(api_key="YOUR_PORTKEY_API_KEY")
# Step 1: Create export
export = client.logs.exports.create(
filters={
"created_at": {
"gte": "2024-01-01T00:00:00Z",
"lte": "2024-01-31T23:59:59Z"
}
},
requested_data=["id", "created_at", "ai_model", "total_tokens", "cost"]
)
export_id = export.id
print(f"Created export: {export_id}")
# Step 2: Start export
client.logs.exports.start(export_id)
print("Export started")
# Step 3: Poll until complete
while True:
status = client.logs.exports.retrieve(export_id)
if status.status == "success":
break
elif status.status == "failure":
raise Exception(f"Export failed: {status.error}")
time.sleep(5)
# Step 4: Download
download_url = client.logs.exports.download(export_id).url
response = requests.get(download_url)
with open("logs_export.jsonl", "wb") as f:
f.write(response.content)
print("Export complete! File saved to logs_export.jsonl")
```
```typescript Node.js theme={"system"}
import Portkey from "portkey-ai";
import fs from "fs";
const client = new Portkey({ apiKey: "YOUR_PORTKEY_API_KEY" });
async function exportLogs() {
// Step 1: Create export
const exportJob = await client.logs.exports.create({
filters: {
created_at: {
gte: "2024-01-01T00:00:00Z",
lte: "2024-01-31T23:59:59Z",
},
},
requested_data: ["id", "created_at", "ai_model", "total_tokens", "cost"],
});
const exportId = exportJob.id;
console.log(`Created export: ${exportId}`);
// Step 2: Start export
await client.logs.exports.start(exportId);
console.log("Export started");
// Step 3: Poll until complete
while (true) {
const status = await client.logs.exports.retrieve(exportId);
if (status.status === "success") break;
if (status.status === "failure") throw new Error(`Export failed: ${status.error}`);
await new Promise((r) => setTimeout(r, 5000));
}
// Step 4: Download
const downloadUrl = (await client.logs.exports.download(exportId)).url;
const response = await fetch(downloadUrl);
const content = await response.text();
fs.writeFileSync("logs_export.jsonl", content);
console.log("Export complete! File saved to logs_export.jsonl");
}
exportLogs();
```
### API reference
For detailed API specifications, see the [Log Exports API reference](/docs/api-reference/admin-api/data-plane/logs/log-exports-beta/create-a-log-export).
| Endpoint | Description |
| - | - |
| `POST /v1/logs/exports` | Create a new export job |
| `POST /v1/logs/exports/{id}/start` | Start processing an export |
| `GET /v1/logs/exports/{id}` | Retrieve export status |
| `GET /v1/logs/exports/{id}/download` | Get signed download URL |
| `POST /v1/logs/exports/{id}/cancel` | Cancel an in-progress export |
| `DELETE /v1/logs/exports/{id}` | Delete an export job |
| `GET /v1/logs/{id}` | Fetch a single log entry |
## Support
If you have any questions or need assistance with the logs export feature, reach out to the Portkey team via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
> [card] [(Deprecated) Logs Export Page](/docs/product/observability/logs-export-deprecated)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Metadata
Source: https://docs.portkey.ai/docs/product/observability/metadata
Add custom context to your AI requests for better observability and analytics
> [!NOTE]
>
> This feature is available on all Portkey plans.
## What is Metadata?
Metadata in Portkey allows you to attach custom contextual information to your AI requests. Think of it as tagging your requests with important business context that helps you:
* **Track usage** across different users, environments, or features
* **Filter logs** to isolate specific request types
* **Analyze patterns** in how your AI is being used
* **Audit activities** for compliance and security
```python theme={"system"}
# Example metadata
{
"_user": "user-123", # Who made this request?
"environment": "prod", # Where was it made from?
"feature": "chat-assist", # What feature was using AI?
"request_id": "42aff12" # Your internal tracking ID
}
```
## Quick Implementation
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@OPENAI_PROVIDER"
> )
>
> # Add metadata to track context
> response = portkey.with_options(
> metadata={
> "_user": "user-123",
> "environment": "production",
> "feature": "summarization",
> "request_id": "1729"
> }
> ).chat.completions.create(
> messages=[{"role": "user", "content": "Summarize this article"}],
> model="gpt-4"
> )
> ```
> [tab] NodeJS
>
> ```javascript theme={"system"}
> import {Portkey} from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> provider:"@OPENAI_PROVIDER"
> })
>
> // Request with business context metadata
> const completion = await portkey.chat.completions.create(
> {
> messages: [{ role: 'user', content: 'Summarize this article' }],
> model: 'gpt-4',
> },
> {
> metadata: {
> "_user": "user-123",
> "environment": "production",
> "feature": "summarization",
> "request_id": "1729"
> }
> }
> );
> ```
> [tab] OpenAI SDK
>
> ```javascript theme={"system"}
> // Using with OpenAI SDK
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> apiKey: "PORTKEY_API_KEY",
> metadata: {
> "_user": "user-123",
> "feature": "customer-support"
> }
> })
> });
>
> const completion = await openai.chat.completions.create({
> messages: [{ role: 'user', content: 'Help with my order' }],
> model: 'gpt-4',
> });
> ```
> [tab] cURL
>
> ```bash theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: $OPENAI_PROVIDER" \
> -H "x-portkey-metadata: {\"_user\":\"user-123\",\"feature\":\"search\"}" \
> -d '{
> "model": "gpt-4",
> "messages": [{"role": "user","content": "Find relevant docs"}]
> }'
> ```
## Common Use Cases
> [card] User Analytics
>
> Track which users are using AI features by adding the `_user` identifier in metadata
> [card] Cost Attribution
>
> Attribute AI costs to teams, features or products by adding identifiers in metadata
> [card] Environment Tracking
>
> Differentiate between dev/staging/prod usage with the `environment` metadata key
> [card] Feature Usage
>
> See which product features are using AI most heavily with feature identifiers
## Metadata Keys and Values
* You can send **any number** of metadata keys with each request
* All values must be **strings** with a maximum length of **128** characters
* Keys can be any string, but some have special meaning (like `_user`)
### Special Metadata Keys
| Key | Purpose | Notes |
| - | - | - |
| `_user` | User tracking | Powers user-level analytics in the Portkey dashboard |
> [!NOTE]
>
> **About the `_user` key:** If you pass a `user` field in your OpenAI request body, we'll automatically copy it to the `_user` metadata key. If both exist, the explicit `_user` metadata value takes precedence.
## Where to See Your Metadata
### Analytics Dashboard
The Analytics dashboard's [Summary tab](/docs/product/observability/analytics#summary) lets you group requests by any metadata key to view aggregate stats:

### Request Logs
You can also apply any metadata filters to the logs or analytics and filter data by any metadata key you've used:

## Automatic Metadata from Headers (Self-Hosted)
> [!NOTE]
>
> Available on **Enterprise** Self Hosting plan. Requires gateway **2.5.0** or higher.
For self-hosted deployments, you can automatically inject request header values into metadata using the `HEADERS_TO_METADATA` environment variable. This is useful for enriching observability data with upstream context without requiring clients to set `x-portkey-metadata`.
```
HEADERS_TO_METADATA=x-request-id,x-caller-service,x-environment
```
When configured, the gateway extracts the specified header values from each incoming request and merges them into the request metadata. Header names are matched case-insensitively.
## Enterprise Features
For enterprise users, Portkey offers advanced metadata governance and lets you define metadata at multiple levels:
1. **Request level** - Applied to a single request
2. **API key level** - Applied to all requests using that key
3. **Workspace level** - Applied to all requests in a workspace
> [card] [Enforcing Required Metadata](/docs/product/administration/enforcing-request-metadata)
>
> Define mandatory metadata fields that must be included with all requests
When the same key appears at multiple levels, the **precedence order** is:
1. Workspace metadata (highest priority)
2. API key metadata
3. Request metadata (lowest priority)
> [!NOTE]
>
> Please note that before 1.10.20, the precedence order was:
>
> 1. Request metadata (highest priority)
> 2. API key metadata
> 3. Workspace metadata (lowest priority)
## Best Practices
* Use **consistent keys** across your organization
* Create **naming conventions** for metadata keys
* Consider adding these common fields:
* `_user`: Who initiated this request
* `environment`: Which environment (dev/staging/prod)
* `feature` or `component`: Which part of your product
* `version`: API or app version
* `session_id`: To group related requests
* `request_id`: Your internal tracking ID
* For proper tracking, **always include the `_user` field** when the request is on behalf of an end-user
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# OpenTelemetry for LLM Observability
Source: https://docs.portkey.ai/docs/product/observability/opentelemetry
Leverage OpenTelemetry with Portkey for comprehensive LLM application observability, combining gateway insights with full-stack telemetry.
[OpenTelemetry (OTel)](https://opentelemetry.io/) is a Cloud Native Computing Foundation (CNCF) open-source framework. It provides a standardized way to collect, process, and export telemetry data (traces, metrics, and logs) from your applications. This is vital for monitoring performance, debugging issues, and understanding complex system behavior.
Many popular AI development tools and SDKs, like the Vercel AI SDK, LlamaIndex, OpenLLMetry, and Logfire, utilize OpenTelemetry for observability. Portkey now embraces OTel, allowing you to send telemetry data from any OTel-compatible source directly into Portkey's observability platform.
## The Portkey Advantage: Gateway Intelligence Meets Full-Stack Observability
Portkey's strength lies in its unique combination of an intelligent **LLM Gateway** and a powerful **Observability** backend.
* **Enriched Data from the Gateway:** Your LLM calls routed through the Portkey Gateway are automatically enriched with deep contextual information—provider configuration, caching status, retry attempts, prompt versions, and more. This data flows seamlessly into Portkey Observability.
* **Holistic View with OpenTelemetry:** By adding an OTel endpoint, Portkey now ingests traces and logs from your *entire* application stack, not just the LLM calls. Instrument your frontend, backend services, databases, and any other component with OTel, and send that data to Portkey.
This combination provides an unparalleled, end-to-end view of your LLM application's performance, cost, and behavior. You can correlate application-level events with specific LLM interactions managed by the Portkey Gateway.
## How OpenTelemetry Data Flows to Portkey
The following diagram illustrates how telemetry data from your instrumented applications and the Portkey Gateway itself is consolidated within Portkey Observability:
```mermaid theme={"system"}
graph LR
subgraph Your Application Stack
A[Application Code]
LIB[OTel Libraries e.g. Logfire]
A -- Instruments with --> LIB
end
PG[Portkey Gateway]
PK_OTEL[Portkey OTel Endpoint api.portkey.ai/v1/otel]
PK_OBS[Portkey Observability Backend]
LIB -- Direct Export --> PK_OTEL
A -- LLM Calls via --> PG
PG -- Rich Telemetry & Logs --> PK_OBS
PK_OTEL -- Ingests Data --> PK_OBS
```
**Explanation:**
1. Your **Application Code** is instrumented using **OTel Instrumentation Libraries**.
2. This telemetry data (traces, logs) can be sent to the **Portkey OTel Backend Endpoint**.
3. Simultaneously, LLM calls made via the **Portkey Gateway** generate their own rich, structured telemetry.
4. All this data is consolidated in the **Portkey Observability Stack**, giving you a unified view.
## Setting Up Portkey as an OpenTelemetry Backend
To send your OpenTelemetry data to Portkey, configure your OTel exporter to point to Portkey's OTLP endpoint and provide your Portkey API Key for authentication.
**Key Environment Variables:**
```bash theme={"system"}
# Portkey's OTLP HTTP Endpoint for traces and logs
OTEL_EXPORTER_OTLP_ENDPOINT="https://api.portkey.ai/v1/otel"
# Your Portkey API Key (ensure it's a Server Key)
OTEL_EXPORTER_OTLP_HEADERS="x-portkey-api-key=YOUR_PORTKEY_API_KEY"
```
> [!NOTE]
>
> Replace `YOUR_PORTKEY_API_KEY` with your actual Portkey API Key found in your Portkey Dashboard.
**Signal-Specific Endpoints:**
If your OTel collector or SDK strictly requires signal-specific endpoints:
**For Traces:**
`OTEL_EXPORTER_OTLP_TRACES_ENDPOINT="https://api.portkey.ai/v1/otel/v1/traces"`
**For Logs:**
`OTEL_EXPORTER_OTLP_LOGS_ENDPOINT="https://api.portkey.ai/v1/otel/v1/logs"`
> [!NOTE]
>
> Remember to include the `OTEL_EXPORTER_OTLP_HEADERS` with your API key for these as well.
## Viewing Traces
Once configured, your OpenTelemetry traces appear in the Portkey dashboard with full visibility for your AI application:

## GenAI Semantic Conventions Support
Portkey automatically enriches OpenTelemetry traces with cost and token metrics following the [GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/). When you send traces with GenAI attributes, Portkey automatically:
* **Extracts Token Counts**: Reads `gen_ai.usage.input_tokens` and `gen_ai.usage.output_tokens` from trace attributes
* **Calculates Costs**: Automatically computes costs based on token usage and model pricing
* **Identifies Models & Providers**: Extracts model information from `gen_ai.request.model` or `gen_ai.response.model` and provider from `gen_ai.system`
* **Enriches Analytics**: Makes all trace data available for cost attribution and usage analysis
This means traces sent from OpenTelemetry-instrumented applications automatically get the same cost tracking and analytics as requests made directly through the Portkey Gateway.
> [!NOTE]
>
> This feature is particularly powerful for applications using frameworks like LangChain, LlamaIndex, or other tools with built-in OpenTelemetry instrumentation that follow GenAI semantic conventions.
## W3C Trace Context Headers
When making requests to the Portkey Gateway, you can use standard W3C trace context headers (`traceparent` and `baggage`) instead of Portkey-specific headers. This enables seamless integration with existing OpenTelemetry-instrumented applications.
* **`traceparent`**: The trace ID and span ID are automatically extracted and used for Portkey's tracing
* **`baggage`**: Key-value pairs are parsed and merged into the request metadata
For detailed usage examples and header specifications, see the [W3C Trace Context Support section in the Tracing documentation](/docs/product/observability/traces#w3c-trace-context-support).
## Why Use OpenTelemetry with Portkey?
Portkey's OTel backend is compatible with any OTel-compliant library. Here are a few popular ones for GenAI and general application observability:
> [card] Language Agnostic
>
> Works with any programming language that supports OpenTelemetry - Python, JavaScript, Java, Go, and more
> [card] Framework Support
>
> Compatible with all major LLM frameworks through their OTel instrumentation
> [card] Zero Code Changes
>
> Many libraries offer auto-instrumentation that requires no changes to your application code
> [card] Standards-Based
>
> Built on industry-standard protocols ensuring long-term compatibility
Navigate to the [Logs page](https://app.portkey.ai/logs) to view your traces, filter by various attributes, and drill down into specific requests.
> [card] [Supported OTel Libraries](/docs/product/observability/opentelemetry/list-of-supported-otel-instrumenters)
## Getting Started
**1. Get your Portkey API key**
Sign up for [Portkey](https://app.portkey.ai) and grab your API key from the settings page
**2. Choose an instrumentation library**
Pick from our [supported integrations](#supported-integrations) based on your stack
**3. Configure the endpoint**
Point your OTel exporter to `https://api.portkey.ai/v1/logs/otel` with your API key
**4. Start tracing**
Run your application and view traces in the Portkey dashboard
## Next Steps
> [card] [Explore Integrations](/docs/integrations/observability-integrations)
>
> Browse all available OpenTelemetry integrations
> [card] [View Traces](/docs/product/observability/logs)
>
> Learn how to analyze traces in Portkey
> [card] [Auto-Instrumentation](/docs/product/observability/auto-instrumentation)
>
> Discover Portkey's native auto-instrumentation features
## Experimental Features
### Push Logs to an OpenTelemetry compatible endpoint `[Enterprise/Self-Hosted]`
> [!WARNING]
>
> [OpenTelemetry conventions on GenAI Traces](https://opentelemetry.io/docs/specs/semconv/gen-ai/gen-ai-spans/) are still under development and have not been widely adapted, hence the feature is still experimental.
When enabled, Portkey Gateway pushes logs to an OpenTelemetry-compatible endpoint following the [semconv 1.40.0](https://opentelemetry.io/docs/specs/semconv/) semantic conventions for GenAI. This includes rich attributes such as:
* Operation and provider: `gen_ai.operation.name`, `gen_ai.provider.name`
* Request attributes: `gen_ai.request.model`, `gen_ai.request.max_tokens`, `gen_ai.request.temperature`, `gen_ai.request.top_k`, etc.
* Response attributes: `gen_ai.response.id`, `gen_ai.response.model`, `gen_ai.response.finish_reasons`
* Token usage: `gen_ai.usage.input_tokens`, `gen_ai.usage.output_tokens`, `gen_ai.usage.cache_creation.input_tokens`, `gen_ai.usage.cache_read.input_tokens`
* Structured messages: `gen_ai.input.messages`, `gen_ai.output.messages`, `gen_ai.system_instructions`
* Tool definitions: `gen_ai.tool.definitions`
* Embeddings support: `gen_ai.request.encoding_formats`, `gen_ai.embeddings.dimension.count`
To push logs to an OpenTelemetry compatible endpoint, you can set the following environment variables in your deployment configuration:
This is an example configuration for LangSmith, but all OpenTelemetry compatible endpoints are supported.
```yaml theme={"system"}
EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED: "true"
EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT: https://api.smith.langchain.com/otel
EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS: x-api-key=langsmith-api-key
EXPERIMENTAL_GEN_AI_OTEL_RESOURCE_ATTRIBUTES: deployment.environment=production,service.version=1.0
```
**Environment Variables:**
* `EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED`: Set to `"true"` to enable pushing logs to an OpenTelemetry endpoint
* `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT`: The OpenTelemetry OTLP endpoint URL (e.g., `https://api.smith.langchain.com/otel`)
* `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS`: Comma-separated list of headers in the format `key=value` (e.g., `x-api-key=langsmith-api-key`)
* `EXPERIMENTAL_GEN_AI_OTEL_RESOURCE_ATTRIBUTES`: Comma-separated `key=value` pairs added as OTLP resource attributes (e.g., `deployment.environment=production`)
The logs are pushed to the endpoint specified in `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT` at the `/v1/traces` path.
> [card] [Detailed Documentation](/docs/product/enterprise-offering/otel/complete-logs)
>
> View comprehensive documentation including attribute mapping, span structure, and integration guides.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Supported OTel Libraries
Source: https://docs.portkey.ai/docs/product/observability/opentelemetry/list-of-supported-otel-instrumenters
Portkey works with any OpenTelemetry-compatible instrumentation. Here are some popular options.
> [card] [Pydantic Logfire](/docs/integrations/tracing-providers/logfire)
> [card] [OpenLIT](/docs/integrations/tracing-providers/openlit)
> [card] [Phoenix OTel (Arize)](/docs/integrations/tracing-providers/phoenix)
> [card] [MLflow](/docs/integrations/tracing-providers/ml-flow)
> [card] [OTel SDK (Python)](/docs/integrations/tracing-providers/opentelemetry-python-sdk)
> [card] [Traceloop (OpenLLMetry)](/docs/integrations/tracing-providers/traceloop)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Tracing
Source: https://docs.portkey.ai/docs/product/observability/traces
The **Tracing** capabilities in Portkey empowers you to monitor the lifecycle of your LLM requests in a unified, chronological view.
> [!NOTE]
>
> This feature is available for all plans:-
>
> * [Developer](https://app.portkey.ai/): 10k Logs / Month with 3 day Log Retention
> * [Production](https://app.portkey.ai/): 100k Logs / Month + \$9 for additional 100k with 30 Days Log Retention
> * [Enterprise](https://portkey.ai/docs/product/enterprise-offering): Unlimited
This is perfect for **agentic workflows**, **chatbots**, or **multi-step LLM calls**, by helping you understand and optimize your AI application's performance.

## How Tracing Works
Portkey implements OpenTelemetry-compliant tracing. When you include a `trace ID` with your requests, all related LLM calls are grouped together in the Traces View, appearing as "spans" within that trace.
> "Span" is another word for subgrouping of LLM calls. Based on how you instrument, it can refer to another group within your trace or to a single LLM call.
## Trace Tree Structure
Portkey uses a tree data structure for tracing, **similar to OTel.**
Each node in the tree is a span with a unique `spanId` and optional `spanName`. Child spans link to a parent via the `parentSpanId`. Parentless spans become root nodes.
```
traceId
├─ parentSpanId
│ ├─ spanId
│ ├─ spanName
```
| Key - Node | Key - Python | Expected Value | Required? |
| - | - | - | - |
| traceId | trace\_id | Unique string | YES |
| spanId | span\_id | Unique string | NO |
| spanName | span\_name | string | NO |
| parentSpanId | parent\_span\_id | Unique string | NO |
***
## W3C Trace Context Support
Portkey supports the [W3C Trace Context](https://www.w3.org/TR/trace-context/) standard headers, making it easy to integrate with existing OpenTelemetry-instrumented applications. If you're already using OpenTelemetry in your stack, you can pass the standard `traceparent` and `baggage` headers instead of Portkey-specific headers.
### traceparent Header
The `traceparent` header follows the W3C format: `version-trace_id-parent_id-trace_flags`
**Example:** `00-bad90143930ea019df8f681254fb2393-42df8ac2dde4ac52-00`
When you send a request with the `traceparent` header:
* The `trace_id` (32 hex characters) is extracted and used as `x-portkey-trace-id`
* The `parent_id` (16 hex characters) is extracted and used as `x-portkey-parent-span-id` (the caller's span)
* A new `span_id` is automatically generated for the gateway's span
* The `span_name` is automatically set to the HTTP method and path (e.g., `POST /v1/chat/completions`)
> [!NOTE]
>
> If you provide both `traceparent` and Portkey-specific headers (`x-portkey-trace-id`, `x-portkey-span-id`), the Portkey-specific headers take precedence.
### baggage Header
The `baggage` header allows you to pass key-value metadata following the [W3C Baggage](https://www.w3.org/TR/baggage/) specification.
**Example:** `userId=alice,environment=production,requestType=chat`
When you send a request with the `baggage` header:
* Key-value pairs are parsed and merged into the request metadata
* Existing metadata (from `x-portkey-metadata` header) takes precedence over baggage values
* Values are URL-decoded automatically
### Example: Using W3C Headers
> [tab] cURL
>
> ```sh theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "Authorization: Bearer $OPENAI_API_KEY" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: openai" \
> -H "traceparent: 00-bad90143930ea019df8f681254fb2393-42df8ac2dde4ac52-00" \
> -H "baggage: userId=alice,environment=production" \
> -d '{
> "model": "gpt-4o",
> "messages": [{"role": "user","content": "Hello!"}]
> }'
> ```
> [tab] Python
>
> ```python theme={"system"}
> import requests
>
> headers = {
> "Content-Type": "application/json",
> "Authorization": f"Bearer {OPENAI_API_KEY}",
> "x-portkey-api-key": PORTKEY_API_KEY,
> "x-portkey-provider": "openai",
> "traceparent": "00-bad90143930ea019df8f681254fb2393-42df8ac2dde4ac52-00",
> "baggage": "userId=alice,environment=production"
> }
>
> response = requests.post(
> "https://api.portkey.ai/v1/chat/completions",
> headers=headers,
> json={
> "model": "gpt-4o",
> "messages": [{"role": "user", "content": "Hello!"}]
> }
> )
> ```
> [tab] Node.js
>
> ```javascript theme={"system"}
> const response = await fetch('https://api.portkey.ai/v1/chat/completions', {
> method: 'POST',
> headers: {
> 'Content-Type': 'application/json',
> 'Authorization': `Bearer ${OPENAI_API_KEY}`,
> 'x-portkey-api-key': PORTKEY_API_KEY,
> 'x-portkey-provider': 'openai',
> 'traceparent': '00-bad90143930ea019df8f681254fb2393-42df8ac2dde4ac52-00',
> 'baggage': 'userId=alice,environment=production'
> },
> body: JSON.stringify({
> model: 'gpt-4o',
> messages: [{ role: 'user', content: 'Hello!' }]
> })
> });
> ```
> [!NOTE]
>
> W3C Trace Context support is particularly useful when integrating Portkey into applications that already use OpenTelemetry for distributed tracing, as it allows seamless correlation between your existing traces and LLM calls.
***
## Enabling Tracing
You can enable tracing by passing the `trace tree` values while making your request (or while instantiating your client).
Based on these values, Portkey will instrument your requests, and will show the exact trace with its spans on the "Traces" view in Logs page.
> [tab] NodeJS
>
> **Add tracing details to a single request (recommended)**
>
> ```js theme={"system"}
> const requestOptions = {
> traceId: "1729",
> spanId: "11",
> spanName: "LLM Call"
> }
>
> const chatCompletion = await portkey.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: 'gpt-4o',
> }, requestOptions);
> ```
>
> #### Or, add trace details while instantiating your client
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> provider:"@PROVIDER",
> traceId: "1729",
> spanId: "11",
> spanName: "LLM Call"
> })
> ```
> [tab] Python
>
> ```python theme={"system"}
> completion = portkey.with_options(
> trace_id="1729",
> span_id="11",
> span_name="LLM Call"
> ).chat.completions.create(
> messages = [{ "role": 'user', "content": 'Say this is a test' }],
> model = 'gpt-3.5-turbo'
> )
> ```
>
> #### Pass Trace details while instantiating your client
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@PROVIDER",
> trace_id="1729",
> span_id="11",
> span_name="LLM Call"
> )
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import { createHeaders } from 'portkey-ai'
>
> const requestOptions = {
> traceId: "1729",
> spanId: "11",
> spanName: "LLM Call"
> }
>
> const chatCompletion = await openai.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: 'gpt-3.5-turbo',
> }, requestOptions);
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from portkey_ai import createHeaders
>
> req_headers = createHeaders(
> trace_id="1729",
> span_id="11",
> span_name="LLM Call
> )
>
> chat_complete = client.with_options(headers=req_headers).chat.completions.create(
> model="gpt-4",
> messages=[{"role": "user", "content": "Say this is a test"}],
> )
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "Authorization: Bearer $OPENAI_API_KEY" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: openai" \
> -H "x-portkey-trace-id: 1729"\
> -H "x-portkey-span-id: 11"\
> -H "x-portkey-span-name: LLM_CALL"\
> -d '{
> "model": "gpt-4o",
> "messages": [{"role": "user","content": "Hello!"}]
> }'
> ```
> [!NOTE]
>
> If you are only passing trace ID and not the span details, you can set the trace ID while making your request or while instantiating your client.
> [tab] NodeJS
>
> ```js theme={"system"}
> const requestOptions = {traceID: "YOUR_TRACE_ID"}
>
> const chatCompletion = await portkey.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: 'gpt-4o',
> }, requestOptions);
>
> console.log(chatCompletion.choices);
> ```
>
> #### Pass Trace ID while instantiating your client
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> provider:"@PROVIDER",
> traceID: "TRACE_ID"
> })
> ```
> [tab] Python
>
> ```python theme={"system"}
> completion = portkey.with_options(
> trace_id = "TRACE_ID"
> ).chat.completions.create(
> messages = [{ "role": 'user', "content": 'Say this is a test' }],
> model = 'gpt-3.5-turbo'
> )
> ```
>
> #### Pass Trace ID while instantiating your client
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@PROVIDER",
> trace_id="TRACE_ID"
> )
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import { createHeaders } from 'portkey-ai'
>
> const reqHeaders = {headers: createHeaders({"traceID": "TRACE_ID"})}
>
> const chatCompletion = await openai.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: 'gpt-3.5-turbo',
> }, reqHeaders);
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from portkey_ai import createHeaders
>
> req_headers = createHeaders(trace_id="TRACE_ID")
>
> chat_complete = client.with_options(headers=req_headers).chat.completions.create(
> model="gpt-4",
> messages=[{"role": "user", "content": "Say this is a test"}],
> )
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "Authorization: Bearer $OPENAI_API_KEY" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: openai" \
> -H "x-portkey-trace-id: TRACE_ID" \
> -d '{
> "model": "gpt-4-turbo",
> "messages": [{
> "role": "system",
> "content": "You are a helpful assistant."
> },{
> "role": "user",
> "content": "Hello!"
> }]
> }'
> ```
## See Tracing in Action
[YouTube video player](https://www.youtube.com/embed/Y-EKz_tVNHs?si=Ycv93wxZCLInlwaf)
## Tracing in Langchain
Portkey has a dedicated handler that can instrument your Langchain chains and agents to trace them.
> [tab] Trace Langchain Requests (Python)
>
> 1. First, install Portkey SDK, and Langchain's packages
>
> ```sh theme={"system"}
> $ pip install langchain_OpenAI portkey-ai langchain_community
> ```
>
> 2. Import the packages
>
> ```py theme={"system"}
> from langchain_openai import ChatOpenAI
> from langchain.chains import LLMChain
> from portkey_ai.langchain import LangchainCallbackHandler
> from portkey_ai import createHeaders
> ```
>
> 3. Instantiate Portkey's Langchain Callback Handler
>
> ```py theme={"system"}
> portkey_handler = LangchainCallbackHandler(
> api_key="YOUR_PORTKEY_API_KEY",
> metadata={
> "user_name": "User_Name",
> "traceId": "Langchain_sample_callback_handler"
> }
> )
> ```
>
> 4. Add the callback to the `ChatOpenAI` instance
>
> ```py theme={"system"}
> llm = ChatOpenAI(
> api_key="OPENAI_API_KEY",
> callbacks=[portkey_handler],
> )
> ```
>
> 5. Also add the callback when you define or run your LLM chain
>
> ```py theme={"system"}
> chain = LLMChain(
> llm=llm,
> prompt=prompt,
> callbacks=[portkey_handler]
> )
>
> handler_config = {'callbacks' : [portkey_handler]}
>
> chain.invoke({"input": "what is langchain?"}, config=handler_config)
> ```
***
## Tracing Llamaindex Requests
Portkey has a dedicated handler to instrument your Llamaindex requests on Portkey.
> [tab] Trace Llamaindex Requests
>
> 1. First, install Portkey SDK, and LlamaIndex packages
>
> ```sh theme={"system"}
> $ pip install openai portkey-ai llama-index
> ```
>
> 2. Import the packages
>
> ```py theme={"system"}
> from llama_index.llms.openai import OpenAI
> from portkey_ai.llamaindex import LlamaIndexCallbackHandler
> ```
>
> 3. Instantiate Portkey's LlamaIndex Callback Handler
>
> ```py theme={"system"}
> portkey_handler = LlamaIndexCallbackHandler(
> api_key="PORTKEY_API_KEY",
> metadata={
> "user_name": "User_Name",
> "traceId": "Llamaindex_sample_callback_handler"
> }
> )
> ```
>
> 4. Add it to `OpenAI` llm class
>
> ```py theme={"system"}
> llm = OpenAI(
> model="gpt-4o",
> api_key="OPENAI_API_KEY",
> callback_manager=[portkey_handler],
> )
> ```
>
> 5. In Llama Index, you can also set the callback at a global level
>
> ```python theme={"system"}
> from llama_index.core import Settings
> from llama_index.core.callbacks import CallbackManager
>
> Settings.callback_manager = CallbackManager([portkey_handler])
> Settings.llm = llm
> ```
***
## Inserting Logs
If you are using the [Insert Log API](/docs/portkey-endpoints/logs/insert-a-log) to add logs to Portkey, your `traceId`, `spanId` etc. will become part of the metadata object in your log, and Portkey will instrument your requests to take those values into account.
The logger endpoint supports inserting a single log as well as log array, and helps you build traces of any depth or complexity. For more, check here:
> [card] [Insert a Log](/docs/portkey-endpoints/logs/insert-a-log)
***
## Tracing for Gateway Features
Tracing also works very well to capture the Gateway behavior on retries, fallbacks, and other routing mechanisms on Portkey Gateway.
Portkey automatically groups all the requests that were part of a single fallback or retry config and shows the failed and succeeded requests chronologically as "spans" inside a "trace".
This is especially useful when you want to understand the total latency and behavior of your app when retry or fallbacks were triggered.
For more, check out the [Fallback](/docs/product/ai-gateway/fallbacks) & [Automatic Retries](/docs/product/ai-gateway/automatic-retries) docs.
***
## Why Use Tracing?
* **Cost Insights**: View aggregate LLM costs at the trace level.
* **Debugging**: Easily browse all requests in a single trace and identify failures.
* **Performance Analysis**: Understand your entire request lifecycle and total trace duration.
* **User Feedback Integration**: Link user feedback to specific traces for targeted improvements.
***
## Capturing User Feedback
Trace IDs can also be used to link user feedback to specific generations. This can be used in a system where users provide feedback, like a thumbs up or thumbs down, or something more complex via our feedback APIs. This feedback can be linked to traces which can span over a single generation or multiple ones. Read more here:
> [card] [Feedback](/docs/product/observability/feedback)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Engineering Studio
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio
Effective prompt management is crucial for getting the most out of Large Language Models (LLMs). Portkey provides a comprehensive solution for creating, managing, versioning, and deploying prompts across your AI applications.
Portkey's Prompt Engineering Studio offers a robust ecosystem of tools to streamline your prompt engineering workflow:
* **Create and compare prompts** in the interactive Multimodal Playground
* **Version** your prompts for production use
* **Deploy** optimized prompts via simple API endpoints
* **Monitor performance** with built-in observability
* **Collaborate** with your team through shared prompt library
Whether you're experimenting with different prompts or managing them at scale in production, Prompt Engineering Studio provides the tools you need to build production ready AI applications.
> [!NOTE]
>
> You can easily access Prompt Engineering Studio using [https://prompt.new](https://prompt.new)
## Setting Up AI Providers
Before you can create and manage prompts, you'll need to set up your [LLM integrations](/docs/product/model-catalog/integrations). After configuring your keys, the respective AI providers become available for running and managing prompts.
Portkey supports over 1600+ models across all the major providers including OpenAI, Anthropic, Google, and many others. This allows you to build and test prompts across multiple models and providers from a single interface.
## [Prompt Playground & Templates](/docs/product/prompt-engineering-studio/prompt-playground)
The [Prompt Playground](/docs/product/prompt-engineering-studio/prompt-playground) is a complete Prompt Engineering IDE for crafting and testing prompts. It provides a rich set of features:
* **Run on any LLM**: Test your prompts across different models and providers to find the best fit for your use case
* **Multimodal support**: Input and analyze images alongside text in your prompts
* **Side-by-side comparisons**: Compare responses across 1600+ models or prompts in parallel
* **Tool integration**: Add and test custom [tools](/docs/product/prompt-engineering-studio/tool-library) for more powerful interactions
* **Prompt templates**: Create dynamic prompts that can change based on the variables passed in
* **AI-assisted improvements**: Leverage AI to refine your prompts
The playground provides immediate feedback, allowing you to rapidly iterate on your prompt designs before deploying them to production. Once you're satisfied with a prompt, you can save it to the [prompt library](/docs/product/prompt-engineering-studio/prompt-library) and use it in your code simply.
## [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning)
Prompt versioning allows you to maintain a history of your prompt changes and promote stable versions to production.
Any update on the saved prompt will create a new version. You can switch back to an older version anytime.
Versioning ensures you can safely experiment while maintaining stable prompts in production.
## [Prompt Library](/docs/product/prompt-engineering-studio/prompt-library)
The Prompt Library is your central repository for managing all prompts across your organization. Within the library, you can organize prompts in folders, set access controls, and collaborate with team members. The library makes it easy to maintain a consistent prompt strategy across your applications and teams.
## [Prompt Partials](/docs/product/prompt-engineering-studio/prompt-partial)
Prompt Partials allow you to create reusable components that can be shared across multiple prompts. These are especially useful for standard instructions or context that appears in multiple prompts. Partials help reduce duplication and maintain consistency in your prompt library.
## [Prompt Observability](/docs/product/prompt-engineering-studio/prompt-observability)
Prompt Observability provides insights into how your prompts are performing in production through usage logs, performance metrics, and version comparison. These insights help you continuously improve your prompts based on real-world usage.
## [Prompt API](/docs/product/prompt-engineering-studio/prompt-api)
The Prompt API allows you to integrate your saved prompts directly into your applications through Completions and Render endpoints. The API makes it simple to use your optimized prompts in production applications, with CRUD operations coming soon.
## Additional Resources
Explore these additional features to get the most out of Portkey's Prompt Engineering Studio:
> [card] [Tool Library](/docs/product/prompt-engineering-studio/tool-library)
> [card] [Integrations](/docs/product/prompt-engineering-studio/prompt-integration)
> [card] [Guides](/docs/product/prompt-engineering-studio/prompt-guides)
***
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Library
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-library
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
Portkey's Prompt Library serves as your central repository for managing, organizing, and collaborating on prompts across your organization. This feature enables teams to maintain consistent prompt strategies while making prompt templates easily accessible to all team members.
The Prompt Library offers a structured way to store and manage your prompt templates. It provides:
* A central location for all your prompt templates
* Folder organization for logical grouping
* Collaboration capabilities for team environments
This centralized approach helps maintain consistency in your AI interactions while making it easy to reuse proven prompt patterns across different applications.
## Accessing the Prompt Library
You can access the Prompt Library from the left navigation menu by clicking on "Prompts" under the Prompt Engineering section. This opens the main library view where you can see all your prompt templates and folders.

## Library Organization
Prompts can be organized into folders for better categorization. For example, you might create separate folders for:
* Customer service prompts
* Content generation prompts
* Data analysis prompts
* Agent-specific prompts
## Creating New Prompts
To add a new prompt to your library:
1. Click the "Create" button in the top-right corner
2. Select "Prompt" from the dropdown menu
3. Build your prompt in the [Prompt Playground](/docs/product/prompt-engineering-studio/prompt-playground)
4. Save the prompt to add it to your library
New prompts are automatically assigned a unique ID that you can use to reference them in your applications via the [Prompt API](/docs/product/prompt-engineering-studio/prompt-api).
### Organizing with Folders
To create a new folder:
1. Click "Create" in the top-right corner
2. Select "Folder" from the dropdown
3. Name your folder based on its purpose or content type
To move prompts into folders:
1. Select the prompts you want to organize
2. Use the move option to place them in the appropriate folder
## Collaboration Features
The Prompt Library is designed for team collaboration:
* All team members with appropriate permissions can access shared prompts
* Changes are tracked by user and timestamp through [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning)
* Multiple team members can work on different prompts simultaneously
This collaborative approach ensures that your team maintains consistent prompt strategies while allowing everyone to contribute their expertise.
### Sharing across workspaces
Share prompts with other workspaces in your organization with read-only access. Recipients can use the prompt via the Prompt API or fork it into their own workspace to customize. See [Sharing prompts and partials](/docs/product/prompt-engineering-studio/prompt-sharing) for the full flow.
For more details on implementing prompts in your code, see the [Prompt API](/docs/product/prompt-engineering-studio/prompt-api) documentation.
## Next Steps
Now that you understand the basics of the Prompt Library, explore these related features:
* [Prompt Playground](/docs/product/prompt-engineering-studio/prompt-playground) - Create and test new prompts
* [Prompt Partials](/docs/product/prompt-engineering-studio/prompt-partial) - Create reusable prompt components
* [Sharing prompts and partials](/docs/product/prompt-engineering-studio/prompt-sharing) - Share prompts across workspaces
* [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) - Track changes to your prompts
* [Prompt API](/docs/product/prompt-engineering-studio/prompt-api) - Integrate prompts into your applications
* [Prompt Observability](/docs/product/prompt-engineering-studio/prompt-observability) - Monitor prompt performance
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Observability
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-observability
Portkey's Prompt Observability provides comprehensive insights into how your prompts are performing in production. This feature allows you to track usage, monitor performance metrics, and analyze trends to continuously improve your prompts based on real-world usage.
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
## Overview
Prompt Observability gives you visibility into your prompt usage and performance through analytics dashboards, detailed logs, and template history. By monitoring these metrics, you can identify which prompts are performing well and which need optimization, helping you make data-driven decisions about your AI applications.
## Accessing Prompt Observability
You can access observability data in several ways:
1. **From the Prompt Template page**: View history and performance metrics for a specific prompt
2. **From the Analytics dashboard**: Filter analytics by prompt ID
3. **From the Logs section**: Filter logs by prompt ID to see detailed usage information
## Prompt Analytics
The Analytics dashboard provides high-level metrics for your prompts, showing important information like costs, token usage, latency, request volume, and user engagement. You can easily filter your prompts using `prompt-id` in the analytics dashboard.

The dashboard enables you to understand trends in your prompt usage over time and identify potential opportunities for optimization. For more details on using the analytics dashboard and available filters, refer to Portkey's [Analytics documentation](/docs/product/observability/analytics).
## Prompt Logs
The Logs section on Portkey's dashboard provides detailed information about each individual prompt call, giving you visibility into exactly how your prompts are being used in real-time. You can easily filter your prompts using `prompt-id` in the logs view.

Each log entry shows the timestamp, model used, request path, user, tokens consumed, cost, and status. This granular data helps you understand exactly how your prompts are performing in production and identify any issues that need attention.
For information on filtering and searching logs, refer to Portkey's [Logs documentation](/docs/product/observability/logs).
> [!NOTE]
>
> **Render Calls**: Note that `prompts.render` API calls are not logged in the observability features. Only `prompts.completions` calls are tracked.
## Prompt Template History
Each prompt template includes a "Recent" tab that shows the history of calls made using that specific template:

This chronological view makes it easy to see how your template is being used and how it's performing over time. You can quickly access detailed information about each call directly from this history view.
The template history is particularly useful when you're iterating on a prompt design, as it allows you to see the immediate impact of your changes. Combined with [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning), this gives you a complete view of your prompt's evolution and performance.
## Next Steps
Now that you understand how to monitor your prompts, explore these related features:
* [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) - Track changes to your prompts over time
* [Prompt API](/docs/product/prompt-engineering-studio/prompt-api) - Integrate optimized prompts into your applications
* [Prompt Playground](/docs/product/prompt-engineering-studio/prompt-playground) - Test and refine your prompts based on observability insights
* [Prompt Partials](/docs/product/prompt-engineering-studio/prompt-partial) - Create reusable components for your prompts
* [Tool Library](/docs/product/prompt-engineering-studio/tool-library) - Enhance your prompts with specialized tools
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Playground
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-playground
> [!NOTE]
>
> This feature is available for all plans:
>
> * [**Developer**](https://portkey.ai/pricing): 3 Prompt Templates
> * [**Production**](https://portkey.ai/pricing) & [**Enterprise**](https://portkey.ai/docs/product/enterprise-offering): Unlimited Prompt Templates
> [!NOTE]
>
> You can easily access Prompt Engineering Studio using [https://prompt.new](https://prompt.new)
## What is the Prompt Playground?
Portkey's Prompt Playground is a place to compare, test and deploy perfect prompts for your AI application. It's where you experiment with different models, test variables, compare outputs, and refine your prompt engineering strategy before deploying to production.

## Getting Started
When you first open the Playground, you'll see a clean interface with a few key components:
* A model selector where you can choose from 1600+ models across 20+ providers
* A messaging area where you'll craft your prompt
* A completion area where you'll see model responses
The beauty of the Playground is its simplicity - write a prompt, click "Generate Completion", and instantly see how the model responds.
### Crafting Your First Prompt
Creating a prompt is straightforward:
1. Select your model of choice - from OpenAI's GPT-4o to Anthropic's Claude or any model from your configured providers
2. Enter a system message (like "You're a helpful assistant")
3. Add your user message or query
4. Click "Generate Completion" to see the response
You can continue the conversation by adding more messages, helping you simulate real-world interactions with your AI.
### Using Prompt Templates in Your Application
Once you save a prompt in the Playground, you'll receive a `prompt ID` that you can use directly in your application code. This makes it easy to move from experimentation to production:
> [tab] NodeJS SDK
>
> ```ts theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "YOUR_PORTKEY_API_KEY"
> })
>
> async function main() {
> // Call your saved prompt template using its ID
> const response = await portkey.prompts.completions.create({
> promptID: "pp-system-pro-34a60b",
> })
>
> console.log(response)
> }
>
> main()
> ```
> [tab] Python SDK
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="YOUR_PORTKEY_API_KEY"
> )
>
> # Call your saved prompt template using its ID
> response = portkey.prompts.completions.create(
> prompt_id="pp-system-pro-34a60b"
> )
>
> print(response)
> ```
This approach allows you to separate prompt engineering from your application code, making both easier to maintain. For more details on integrating prompts in your applications, check out our [Prompt API](/docs/product/prompt-engineering-studio/prompt-api) documentation.
### Comparing Models Side-by-Side
Wondering which model works best for your use case? The side-by-side comparison feature lets you see how different models handle the same prompt.
Click the "+ Compare" button to add another column, select a different model, and generate completions simultaneously. You will be able to see how each model responds to the same prompt, along with crucial metrics like latency, total tokens, and throughput helping you make informed decisions about which model to use in production.
You can run comparisons on the same prompt template by selecting the template from the "New Template" dropdown in the UI along with the versions button across multiple models. Once you figure out what is working, you can click on the "Update Prompt" button to update the prompt template with a new version. You can also compare different [prompt versions](/docs/product/prompt-engineering-studio/prompt-versioning) by selecting the version from the UI.
The variables you define apply across all templates in the comparison, ensuring you're testing against identical inputs.

### Enhancing Prompts with Tools
Some models support function calling, allowing the AI to request specific information or take actions. The Playground makes it easy to experiment with these capabilities.
Click "Add Tool" button to define functions the model can call. For example:

```json theme={"system"}
{
"type": "function",
"function": {
"name": "get_weather",
"description": "Get current weather for a location",
"parameters": {
"type": "object",
"properties": {
"location": {
"type": "string",
"description": "City and state, e.g., San Francisco, CA"
}
},
"required": ["location"]
}
}
}
```
You can add multiple tools from the [tool library](/docs/product/prompt-engineering-studio/tool-library) for the specific prompt template. You can also choose the parameter "tool\_choice" from the UI to control how the model uses the available tools.
This tool definition teaches the model how to request weather information for a specific location.
### Configuring Model Parameters
Each model offers various parameters that affect its output. Access these by clicking the "Parameters" button:
* **Temperature**: Controls randomness (lower = more deterministic)
* **Top P**: Alternative to temperature for controlling diversity
* **Max Tokens**: Limits response length
* **Response Format**: An important setting that allows users to define how they want the model to output. Currently there are 3 options:
* Text (default free-form text)
* JSON object (structured JSON response)
* JSON schema (requires providing a schema in the menu to make the model conform to your exact structure)
* **Thinking Mode**: Reasoning models think before they answer, producing a long internal chain of thought before responding to the user. You can access to the model's reasoning/thinking process sent by the provider. This feature:
* Is only available for select reasoning-capable models (like Claude 3.7 Sonnet)
* Can be activated by checking the "Thinking" checkbox in the Parameters panel
* Allows you to set a budget of tokens dedicated specifically to the thinking process (if the provider supports it)
And more... Experiment with these settings to find the perfect balance for your use case.
### Pretty Mode vs JSON Mode
The Playground offers two interface modes for working with prompts:
**Pretty Mode**
The default user-friendly interface with formatted messages and simple controls. This is ideal for most prompt engineering tasks and provides an intuitive way to craft and test prompts.
**JSON Mode**
For advanced users who need granular control, you can toggle to JSON mode by clicking the "JSON" button. This reveals the raw JSON structure of your prompt, allowing for precise editing and advanced configurations.
JSON mode is particularly useful when:
* Working with multimodal inputs like images
* Creating complex conditional logic
* Defining precise message structures
* Debugging API integration issues
You can switch between modes at any time using the toggle in the interface.
### Multimodality: Working with Images
For multimodal models that support images, you can upload images directly in the Playground using the 🧷 icon on the message input box.
Alternatively, you can use JSON mode to incorporate images using variables. Toggle from PRETTY to JSON mode using the button on the dashboard, then structure your prompt like this:
```json theme={"system"}
[
{
"content": [
{
"type": "text",
"text": "You're a helpful assistant."
}
],
"role": "system"
},
{
"role": "user",
"content": [
{ "type": "text", "text": "what's in this image?" },
{
"type": "image_url",
"image_url": {
"url" : "{{your_image_url}}"
}
}
]
}
]
```
Now you can pass the image URL as a variable in your prompt template, and the model will be able to analyze the image content.
# Prompt Templates
**Portkey uses** [**Mustache**](https://mustache.github.io/mustache.5.html) **under the hood to power the prompt templates.**
Mustache is a commonly used logic-less templating engine that follows a simple schema for defining variables and more.
With Mustache, prompt templates become even more extensible by letting you incorporate various `{{tags}}` in your prompt template and easily pass your data.
The most common usage of mustache templates is for `{{variables}}`, used to pass a value at runtime.
### Using Variables in Prompt Templates
Let's look at the following template:

As you can see, `{{customer_data}}` and `{{chat_query}}` are defined as variables in the template and you can pass their value at runtime:
> [tab] NodeJS SDK
>
> ```ts theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey()
>
> async function main() {
> const response = await portkey.prompts.completions.create({
> promptID: "pp-hr-bot-5c8c6e",
> variables: {
> "customer_data":"",
> "chat_query":""
> }
> })
>
> console.log(response)
> }
>
> main()
> ```
> [tab] Python SDK
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey()
>
> response = portkey.prompts.completions.create({
> prompt_id="pp-hr-bot-5c8c6e",
> variables= {
> "customer_data":"",
> "chat_query":""
> }
> })
> ```
**Using variables is just the start! Portkey supports multiple Mustache tags that let you extend the template functionality:**
### Supported Variable Tags
| Tag | Functionality | Example |
| - | - | - |
| `{{variable}}` | Variable | Template: Hi! My name is `{{name}}`. I work at `{{company}}`. Data: `Copy{ "name": "Chris", "company": "GitHub" }` Output: Hi! My name is Chris. I work at Github. |
| `{{#variable}}` `` `{{/variable}}` | Render `` only if variable is true or non Empty | Template: Hello I am Tesla bot.`{{#chat_mode_pleasant}}` Excited to chat with you! `{{chat_mode_pleasant}}`What can I help you with? Data: Copy`{ "chat_mode_pleasant": False }` Output: Hello I am Tesla bot. What can I help you with? |
| `{{^variable}}` ```{{/variable}}` | Render `` only if variable is false or empty | Template: Hello I am Tesla bot.`{{^chat_mode_pleasant}}` Excited to chat with you! `{{/chat_mode_pleasant}}`What can I help you with? Data: Copy`{ "chat_mode_pleasant": False }` Output: Hello I am Tesla bot. Excited to chat with you! What can I help you with? |
| `{{#variable}}` `{{sub_variable}}` `{{/variable}}` | Iteratively render all the values of sub\_variable if variable is true or non Empty | Template: Give atomic symbols for the following: `{{#variable}}` - `{{sub_variable}}` `{{/variable}}` Data: Copy`{ "variable": \[ { "sub\_variable": "Gold" }, { "sub\_variable": "Carbon" }, { "sub\_variable": "Zinc" } \] } ` Output: Give atomic symbols for the following: - Gold - Carbon - Zinc |
| `{{! Comment}} ` | Comments that are ignored | Template: Hello I am Tesla bot.`{{! How do tags work?}}` What can I help you with? Data: Copy Output: Hello I am Tesla bot. What can I help you with? |
| `{{>Partials}} ` | "Mini-templates" that can be called at runtime. On Portkey, you can save [partials](/docs/product/prompt-engineering-studio/prompt-partial) separately and call them in your prompt templates by typing `{{>` | Template: Hello I am Tesla bot.`{{>pp-tesla-template}}` What can I help you with? Data in `pp-tesla-template`: CopyTake the context from `{{context}}`. And answer user questions. Output: Hello I am Tesla bot. Take the context from `{{context}}`. And answer user questions. What can I help you with? |
| `{{>>Partial Variables}} ` | Pass your privately saved partials to Portkey by creating tags with double >>Like: `{{>> }}` This is helpful if you do not want to save your partials with Portkey but are maintaining them elsewhere | Template: Hello I am Tesla bot.`{{>>My Private Partial}}` What can I help you with? |
### Structural Mustache and `is_raw_template`
Standard Mustache `{{variable}}` tags work inside string values in any mode. However, when you need a section block like `{{#has_image}}...{{/has_image}}` to **conditionally include or exclude an entire JSON object** inside a messages array (for example, adding an `image_url` content block only when an image is present), the template is structurally invalid JSON until after Mustache renders it.
For this use case you must:
1. Use **JSON Mode** in the Playground UI (toggle from Pretty to JSON)
2. Set `"is_raw_template": 1` when creating the prompt via the API
This tells Portkey to run Mustache rendering first and then parse the result as valid JSON, rather than treating the stored string as JSON immediately.
**Example: Conditionally including an image content block**
The template string stored in the prompt (note: `{{#has_image}}` wraps an entire JSON object in the array):
```json theme={"system"}
[{
"role": "user",
"content": [
{ "type": "text", "text": "{{user_prompt}}" },
{{#has_image}}
{ "type": "image_url", "image_url": { "url": "{{image_url}}" } },
{{/has_image}}
{ "type": "text", "text": "Please analyze accordingly." }
]
}]
```
**Create this prompt via API:**
> [tab] cURL
>
> ```bash theme={"system"}
> curl --request POST \
> --url https://api.portkey.ai/v1/prompts \
> --header 'Content-Type: application/json' \
> --header 'x-portkey-api-key: $PORTKEY_API_KEY' \
> --data '{
> "collection_id": "YOUR_COLLECTION_ID",
> "name": "vision-conditional-prompt",
> "model": "YOUR_MODEL",
> "parameters": {
> "max_tokens": 512,
> "temperature": 0.5,
> "top_p": 0.9,
> "n": 1,
> "stream": true
> },
> "string": "[{\"role\":\"user\",\"content\":[{\"type\":\"text\",\"text\":\"{{user_prompt}}\"}{{#has_image}},{\"type\":\"image_url\",\"image_url\":{\"url\":\"{{image_url}}\"}}{{/has_image}},{\"type\":\"text\",\"text\":\"Please analyze accordingly.\"}]}]",
> "is_raw_template": 1,
> "virtual_key": "YOUR_VIRTUAL_KEY",
> "version_description": "Conditional vision prompt with Mustache section",
> "template_metadata": {
> "template_type": "chat"
> }
> }'
> ```
**Call the saved prompt at runtime:**
> [tab] With image (cURL)
>
> ```bash theme={"system"}
> curl --request POST \
> --url https://api.portkey.ai/v1/prompts/YOUR_PROMPT_ID/completions \
> --header 'Content-Type: application/json' \
> --header 'x-portkey-api-key: $PORTKEY_API_KEY' \
> --data '{
> "variables": {
> "user_prompt": "What objects are visible in this image?",
> "has_image": true,
> "image_url": "https://example.com/photo.png"
> }
> }'
> ```
> [tab] Without image (cURL)
>
> ```bash theme={"system"}
> curl --request POST \
> --url https://api.portkey.ai/v1/prompts/YOUR_PROMPT_ID/completions \
> --header 'Content-Type: application/json' \
> --header 'x-portkey-api-key: $PORTKEY_API_KEY' \
> --data '{
> "variables": {
> "user_prompt": "Summarize this topic.",
> "has_image": false
> }
> }'
> ```
> [tab] Python SDK
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(api_key="PORTKEY_API_KEY")
>
> # With image
> response = portkey.prompts.completions.create(
> prompt_id="YOUR_PROMPT_ID",
> variables={
> "user_prompt": "What objects are visible in this image?",
> "has_image": True,
> "image_url": "https://example.com/photo.png"
> }
> )
>
> # Without image — omit has_image or pass False
> response = portkey.prompts.completions.create(
> prompt_id="YOUR_PROMPT_ID",
> variables={
> "user_prompt": "Summarize this topic.",
> "has_image": False
> }
> )
> ```
> [tab] NodeJS SDK
>
> ```javascript theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({ apiKey: "PORTKEY_API_KEY" });
>
> // With image
> const response = await portkey.prompts.completions.create({
> promptID: "YOUR_PROMPT_ID",
> variables: {
> user_prompt: "What objects are visible in this image?",
> has_image: true,
> image_url: "https://example.com/photo.png"
> }
> });
>
> // Without image — omit has_image or pass false
> const response = await portkey.prompts.completions.create({
> promptID: "YOUR_PROMPT_ID",
> variables: {
> user_prompt: "Summarize this topic.",
> has_image: false
> }
> });
> ```
> [!NOTE]
>
> When `has_image` is `false` or absent, Mustache skips the entire `image_url` object, and the final messages array sent to the model will contain only the text content blocks. No changes to the saved template are needed.
### Using Variable Tags
You can directly pass your data object containing all the variable/tags info (in JSON) to Portkey's `prompts.completions` method with the `variables` property.
**For example, here's a [prompt partial](/docs/product/prompt-engineering-studio/prompt-partial) containing the key instructions for an AI support bot:**

**And the prompt template uses the partial like this:**

**We can pass the data object inside the variables:**
> [tab] NodeJS SDK
>
> ```ts theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "YOUR_PORTKEY_API_KEY"
> })
>
> const data = {
> "company": "NESTLE",
> "product": "MAGGI",
> "benefits": "HEALTH",
> "phone number": "123456",
> "name": "Sheila",
> "device": "iOS",
> "query": "Product related",
> "test_variable":"Something unrelated" // Your data object can also contain unrelated variables
> }
>
> async function main() {
> // Make the prompt creation call with the variables
> const response = await portkey.prompts.completions.create({
> promptID: "pp-system-pro-34a60b",
> variables: {
> ...data,
> "user_query": "I ate Maggi and I think it was stale."
> }
> })
>
> console.log(response)
> }
>
> main()
> ```
> [tab] Python SDK
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="YOUR_PORTKEY_API_KEY"
> )
>
> data = {
> "company": "NESTLE",
> "product": "MAGGI",
> "benefits": "HEALTH",
> "phone number": "123456",
> "name": "Sheila",
> "device": "iOS",
> "query": "Product related",
> "test_variable": "Something unrelated" # Your data object can also contain unrelated variables
> }
>
> # Make the prompt creation call with the variables
> response = portkey.prompts.completions.create(
> prompt_id="pp-system-pro-34a60b",
> variables={
> **data,
> "user_query": "I ate Maggi and I think it was stale."
> }
> )
>
> print(response)
> ```
## From Experiment to Production
Once you've crafted the perfect prompt, save it with a click of the "Save Prompt" button. Your prompt will be [versioned](/docs/product/prompt-engineering-studio/prompt-versioning) automatically, allowing you to track changes over time.
Saved prompts can be:
* Called directly from your application using the [Prompt API](/docs/product/prompt-engineering-studio/prompt-api)
* Shared with team members for collaboration through the [Prompt Library](/docs/product/prompt-engineering-studio/prompt-library)
* Monitored for performance in production with [Prompt Observability](/docs/product/prompt-engineering-studio/prompt-observability)
## Next Steps
Now that you understand the basics of the Prompt Playground, you're ready to create powerful, dynamic prompts for your AI applications. Start by experimenting with different models and prompts to see what works best for your use case.
Looking for more advanced techniques? Check out our guides on:
* [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning)
* [Prompt Partials](/docs/product/prompt-engineering-studio/prompt-partial)
* [Prompt API](/docs/product/prompt-engineering-studio/prompt-api)
* [Tool Library](/docs/product/prompt-engineering-studio/tool-library)
* [Prompt Integrations](/docs/product/prompt-engineering-studio/prompt-integration)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Versioning & Labels
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-versioning
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
Effective prompt management includes tracking changes, controlling access, and deploying the right version at the right time. Portkey's prompt versioning system helps you maintain a history of your prompt iterations while ensuring production stability.
## Understanding Prompt Versioning
Every time you make changes to a prompt template, Portkey tracks these modifications. The versioning system allows you to:
* Try and test different prompt variations
* Keep a complete history of all prompt changes
* Compare different versions
* Revert to previous versions when needed
* Deploy specific versions to different environments
**Updating vs. Publishing a Prompt Template**
When working with prompts in Portkey, it's important to understand the difference between updating and publishing:
* **Update**: When you edit a prompt, changes are saved as a new version but not pushed to production
* **Publish**: Making a specific version the "production" version that's used by default
## Managing Prompt Versions
### Creating New Versions
Whenever any changes are made to your prompt template, Portkey saves your changes in the browser **but** they are **not pushed** to production. You can click on the `Update` button on the top right to save the latest version of the prompt on Portkey.

### Publishing Prompts
Publishing a prompt version marks it as the default version that will be used when no specific version is requested. This is especially important for production environments.
Updating the Prompt does not automatically update your prompt in production. While updating, you can tick `Publish prompt changes` which will also update your prompt deployment to the latest version.
1. Create and test your new prompt version
2. When ready for production, click "Update" and check "Publish prompt changes"
3. Portkey will save the new version and mark it as the published version
4. All default API calls will now use this version

### Viewing Version History
**All** of your prompt versions can be seen by clicking the `Version History` button on the playground:

You can `Restore` or `Publish` any of the previous versions by clicking on the ellipsis menu.
### Comparing Versions
To compare different versions of your prompt:
1. Select the versions you want to compare from the version history panel
2. Click "Compare on playground" to see a side-by-side of different prompt versions
This helps you understand how prompts have evolved and which changes might have impacted performance.
## Using Different Prompt Versions
By default, when you pass the `PROMPT_ID` in `prompts.completions.create` method, Portkey sends the request to the `Published` version of your prompt.
You can also call any specific prompt version by appending version identifiers to your `PROMPT_ID`.
### Version Number References
**For example:**
```js theme={"system"}
response = portkey.prompts.completions.create(
prompt_id="pp-classification-prompt@12",
variables={ }
)
```
Here, the request is sent to **Version 12** of the prompt template.
### Special Version References
Portkey supports special version references:
```js theme={"system"}
// Latest version (may not be published)
response = portkey.prompts.completions.create(
prompt_id="pp-classification-prompt@latest",
variables={ }
)
// Published version (default when no suffix is provided)
response = portkey.prompts.completions.create(
prompt_id="pp-classification-prompt",
variables={ }
)
```
**Important Notes:**
* `@latest` refers to the most recent version, regardless of publication status
* When no suffix is provided, Portkey defaults to the `Published` version
* Each version is immutable once created - to make changes, you must create a new version
## Prompt Labels
Labels provide a more flexible and meaningful way to reference prompt versions compared to version numbers. You can add version tags/labels like `platform-team`, `gpt-model-prompt` to any prompt version to track changes and call them directly:

### Using Labels in Your Code
```ts @staging {2} theme={"system"}
const promptCompletion = portkey.prompts.completions.create({
promptID: "pp-article-xx@staging",
variables: {"":""}
})
```
```ts @develpoment {2} theme={"system"}
const promptCompletion = portkey.prompts.completions.create({
promptID: "pp-article-xx@development",
variables: {"":""}
})
```
```ts @production {2} theme={"system"}
const promptCompletion = portkey.prompts.completions.create({
promptID: "pp-article-xx@production",
variables: {"":""}
})
```
```ts @lorem-ipsum {2} theme={"system"}
const promptCompletion = portkey.prompts.completions.create({
promptID: "pp-article-xx@lorem-ipsum",
variables: {"":""}
})
```
### Creating and Managing Labels
To create or manage labels:
1. Navigate to the prompt version sidebar
2. Click on "Labels" to view all available labels
3. Select a version and apply the desired label
4. You can move labels between versions as needed
> [!NOTE]
>
> You can now assign multiple custom labels to a single prompt version in Portkey. This makes it easier to promote a prompt version in it's developemtn cycle.
> [!NOTE]
>
> * There are 3 default labels: `production`, `staging`, `development` which cannot be removed.
> * Custom labels are unique to the workspace where they are created.
> * If you delete a custom label, any prompt completion requests to that label will start failing.
### Best Practices for Using Labels
* Use `development` for experimental versions
* Use `staging` for versions ready for testing
* Use `production` for versions ready for real users
* Create custom labels for specific use cases or experiments
Labels make it easy for you to test prompt versions through different environments.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# How to Contribute
Source: https://docs.portkey.ai/docs/README
[](https://deepwiki.com/Portkey-AI/gateway)
# Portkey AI Docs
This repository contains the source code for [Portkey AI](https://portkey.ai)'s documentation, built using [Mintlify](https://mintlify.com).\
We welcome contributions to improve the accuracy, clarity, and coverage of our docs.
***
## Getting Started
To contribute or preview the documentation locally:
### 1. Clone the Repository
```bash theme={"system"}
git clone https://github.com/portkey-ai/docs-core.git
cd docs-core
```
### 2. Install Mintlify CLI
The documentation is built using Mintlify. Install the `mint` CLI globally with any of the following:
```bash theme={"system"}
npm install -g mint
# OR
pnpm add -g mint
# OR
yarn global add mint
```
Refer to the [Mintlify Docs](https://mintlify.com/docs) if you run into issues.
### 3. Run the Local Server
```bash theme={"system"}
mint dev
```
This will start a local server so you can preview your changes as you edit.
***
## How to Contribute
We appreciate all contributions—small or large. Here's how you can help:
1. **Fork** the repository.
2. **Create a branch** for your changes:
```bash theme={"system"}
git checkout -b your-branch-name
```
3. **Make edits** and test them locally using `mint dev`.
4. **Commit and push** your changes.
5. **Open a pull request** to the `main` branch with a clear description.
***
## What You Can Contribute
* Fix typos or broken links
* Improve explanations or formatting
* Add missing documentation
* Suggest structural improvements
* Maintain existing integrations with Portkey
***
## Need Help?
Reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) to ask questions or share suggestions.
You can also open an issue here on GitHub.
## Community
Join our growing community around the world, for help, ideas, and discussions on AI.
* View our official [Blog](https://portkey.wiki/gh-78)
* Follow us on [Twitter](https://portkey.wiki/gh-79)
* Connect with us on [LinkedIn](https://portkey.wiki/gh-80)
* Visit us on [YouTube](https://portkey.wiki/gh-103)
* Join our [Dev community](https://portkey.wiki/gh-82)
***
# Integrations
Source: https://docs.portkey.ai/docs/integrations/ecosystem
> [card] [LLM Integrations](/docs/integrations/llms)
> [card] [Plugins](/docs/integrations/plugins)
> [card] [Agents](/docs/integrations/agents)
> [card] [Guardrails](/docs/product/guardrails/list-of-guardrail-checks)
> [card] [AI Apps](/docs/integrations/ai-apps)
> [card] [Libraries](/docs/integrations/libraries)
> [card] [Cloud Platforms](/docs/integrations/cloud)
> [card] [Tracing Providers](/docs/product/observability/opentelemetry/list-of-supported-otel-instrumenters)
> [card] [MCP Clients](/docs/product/mcp-gateway/mcp-clients)
> [card] [MCP Servers](/docs/integrations/mcp-servers)
# Preferred Partners
> [card] [OpenAI Agents](/docs/integrations/agents/openai-agents)
>
> OpenAI Agents SDK enables building powerful AI agents with tools, memory, and multi-step reasoning capabilities.
> [card] [Cline](/docs/integrations/libraries/cline)
>
> Cline is an AI coding assistant that integrates directly into your VS Code environment, providing autonomous coding capabilities
> [card] [Jan](/docs/integrations/libraries/janhq)
>
> Jan is an open source alternative to ChatGPT that runs 100% offline on your computer
> [card] [Anything LLM](/docs/integrations/libraries/anythingllm)
>
> All in one AI with built in RAG, Agents and Chat Interface.
> [card] [Zed](/docs/integrations/libraries/zed)
>
> Fast, AI-assisted code editor for power users.
> [card] [Pangea](/docs/product/guardrails/pangea)
>
> Composable security platform against LLM threats like prompt injection and sensitive data leakage.
> [card] [Tooljet](https://docs.tooljet.com/docs/marketplace/plugins/marketplace-plugin-portkey/)
>
> Low-code platform for building internal tools
> [card] [F5](https://portkey.ai/blog/portkey-and-f5-empowering-secure-and-intelligent-ai-application-delivery/)
>
> Network security and application delivery solutions
> [card] [Qdrant](integrations/vector-databases/qdrant)
>
> Qdrant is an Open-Source Vector Database and Vector Search Engine written in Rust.
> [card] [Roo Code](/docs/integrations/libraries/roo-code)
>
> Roo is an AI coding assistant that integrates directly into your VS Code environment, providing autonomous coding capabilities.
> [card] [Goose](/docs/integrations/libraries/goose)
>
> Goose is a local, extensible, open source AI agent that automates engineering tasks.
> [card] [Milvus](integrations/vector-databases/milvus)
>
> Qdrant is an Open-Source Vector Database and Vector Search Engine written in Rust.
> [card] [MongoDB](/docs/integrations/libraries/mongodb)
>
> Flexible and scalable document database
> [card] [Appsmith](https://www.appsmith.com/)
>
> Open-source framework focused on simplifying internal tool development.
> [card] [AWS Marketplace](/docs/product/enterprise-offering/private-cloud-deployments/aws)
>
> Cloud computing services and marketplace
> [card] [Azure Marketplace](https://azuremarketplace.microsoft.com/en-in/marketplace/apps/portkey.enterprise-saas?tab=Overview)
>
> Cloud platform and services marketplace
> [card] [JACB.AI](https://www.jacb.ai/)
>
> AI-powered solutions tailored for business efficiency.
> [card] [Qualifire](/docs/integrations/guardrails/qualifire)
>
> State-of-the-art agentic evaluation and guardrails
> [card] [Patronus AI](/docs/integrations/guardrails/patronus-ai)
>
> Automated evaluation and security platform for AI models, focusing on performance scoring and reliability.
> [card] [Aporia](/docs/integrations/guardrails/aporia)
>
> ML observability and monitoring
> [card] [Pillar](/docs/integrations/guardrails/pillar)
>
> All-in-one platform that empowers organizations to monitor, assess risks, and secure their AI activities.
> [card] [Vercel](/docs/integrations/libraries/vercel)
>
> Frontend deployment and hosting platform
> [card] [Langchain](/docs/integrations/libraries/langchain-python)
>
> Framework for developing LLM applications
> [card] [LlamaIndex](/docs/integrations/libraries/llama-index-python)
>
> Data framework for LLM applications
> [card] [Promptfoo](/docs/integrations/libraries/promptfoo)
>
> Prompt engineering and testing tool
> [card] [CrewAI](/docs/integrations/agents/crewai)
>
> Multi-agent framework for AI applications
> [card] [AutoGen](/docs/integrations/agents/autogen)
>
> Framework for automated AI agent creation
> [card] [DSPy](/docs/integrations/libraries/dspy)
>
> Programming framework for AI-powered applications
> [card] [LibreChat](/docs/integrations/libraries/librechat)
>
> Open-source chat platform
> [card] [Instructor](/docs/integrations/libraries/instructor)
>
> Tools for structured outputs from LLMs
> [card] [Anyscale](/docs/integrations/llms/anyscale-llama2-mistral-zephyr)
>
> Distributed computing platform for AI
> [card] [Carbon](https://carbon.ai/)
>
> AI-powered solutions for sustainability
> [card] [CopilotKit](https://www.copilotkit.ai/)
>
> AI-powered development assistant
> [card] [MindsDB](https://mindsdb.com/)
>
> Your LLM with the built-in power to answer data questions for agents & apps.
> [card] [Tembo](https://tembo.io/docs/product/stacks/ai/vectordb/portkey)
>
> Improve the experience of deploying, managing, and scaling Postgres
# Become Portkey Partner
**To Join Portkey's Partner Ecosystem, Schedule a Call Below**
[https://portkey.sh/partner?hide\_event\_type\_details=1\&hide\_gdpr\_banner=1](https://portkey.sh/partner?hide_event_type_details=1\&hide_gdpr_banner=1)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Bring Your Own Guardrails
Source: https://docs.portkey.ai/docs/integrations/guardrails/bring-your-own-guardrails
Integrate your custom guardrails with Portkey using webhooks
Portkey's webhook guardrails allow you to integrate your existing guardrail infrastructure with our AI Gateway. This is perfect for teams that have already built custom guardrail pipelines (like PII redaction, sensitive content filtering, or data validation) and want to:
* Enforce guardrails directly within the AI request flow
* Make existing guardrail systems production-ready
* Modify AI requests and responses in real-time
## How It Works
1. You add a Webhook as a Guardrail Check in Portkey
2. When a request passes through Portkey's Gateway:
* Portkey sends relevant data to your webhook endpoint
* Your webhook evaluates the request/response and returns a verdict
* Based on your webhook's response, Portkey either allows the request to proceed, modifies it if required, or applies your configured guardrail actions
## Setting Up a Webhook Guardrail
### Configure Your Webhook in Portkey App

In the Guardrail configuration UI, you'll need to provide:
| Field | Description | Type |
| :- | :- | :- |
| **Webhook URL** | Your webhook's endpoint URL | `string` |
| **Headers** | Headers to include with webhook requests | `JSON` |
| **Timeout** | Maximum wait time for webhook response | `number` (ms) |
| **Fail on Error** | Treat a non-200 response or a timeout as a failed check | `boolean` |
| **Forward Headers** | Client headers to forward to your webhook | `string[]` |
| **Execute on Proxy** | Also run this webhook on proxy (`/v1/*`) requests | `boolean` |
#### Webhook URL
This should be a publicly accessible URL where your webhook is hosted. On self-hosted gateways, webhooks on private networks must be allowlisted in `TRUSTED_CUSTOM_HOSTS`.
#### Headers
Specify headers as a JSON object:
```json theme={"system"}
{
"Authorization": "Bearer YOUR_API_KEY",
"Content-Type": "application/json"
}
```
#### Timeout
The maximum time Portkey will wait for your webhook to respond before proceeding with a default `verdict: true`.
* Default: `3000ms` (3 seconds)
* If your webhook processing is time-intensive, consider increasing this value
### Configure Your Webhook Inline in a Config
Skip the portal entirely and pass the webhook check inline in the request config. Any hook that carries its own `checks` array runs as-is — no guardrail is created and no ID is looked up.
```json Inline webhook guardrail theme={"system"}
{
"before_request_hooks": [{
"id": "inline-input-webhook",
"type": "guardrail",
"deny": true,
"checks": [{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://guardrails.example.com/pre-check",
"headers": { "Authorization": "Bearer WEBHOOK_TOKEN" },
"timeout": 5000,
"failOnError": true
}
}]
}],
"after_request_hooks": [{
"id": "inline-output-webhook",
"type": "guardrail",
"deny": false,
"checks": [{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://guardrails.example.com/post-check",
"timeout": 3000
}
}]
}]
}
```
Send the config with any inference request:
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H 'x-portkey-config: {"before_request_hooks":[{"id":"inline-input-webhook","type":"guardrail","deny":true,"checks":[{"id":"default.webhook","parameters":{"webhookURL":"https://guardrails.example.com/pre-check","timeout":5000,"failOnError":true}}]}]}' \
-d '{
"model": "@my-openai/gpt-4o-mini",
"messages": [{"role": "user", "content": "Say Hi"}]
}'
```
```python Python theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
config={
"before_request_hooks": [{
"id": "inline-input-webhook",
"type": "guardrail",
"deny": True,
"checks": [{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://guardrails.example.com/pre-check",
"headers": {"Authorization": "Bearer WEBHOOK_TOKEN"},
"timeout": 5000,
"failOnError": True
}
}]
}]
}
)
response = portkey.chat.completions.create(
model="@my-openai/gpt-4o-mini",
messages=[{"role": "user", "content": "Say Hi"}]
)
```
```js NodeJS theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
config: {
before_request_hooks: [{
id: "inline-input-webhook",
type: "guardrail",
deny: true,
checks: [{
id: "default.webhook",
parameters: {
webhookURL: "https://guardrails.example.com/pre-check",
headers: { Authorization: "Bearer WEBHOOK_TOKEN" },
timeout: 5000,
failOnError: true
}
}]
}]
}
})
const response = await portkey.chat.completions.create({
model: "@my-openai/gpt-4o-mini",
messages: [{ role: "user", content: "Say Hi" }]
})
```
#### Hook Fields
| Field | Description | Type |
| :- | :- | :- |
| `id` | Label for the hook, shown in logs. Any string works — it is never looked up | `string` |
| `type` | Always `guardrail` for webhook checks | `string` |
| `checks` | The checks to run. One `default.webhook` entry per endpoint | `array` |
| `deny` | Block the request when the webhook returns `verdict: false` | `boolean` |
| `async` | Run the check without blocking the request | `boolean` |
| `sequential` | Run checks one after another instead of in parallel | `boolean` |
To call several webhooks, add more entries to `checks`. They run in parallel unless `sequential` is `true`.
Results come back under `hook_results.before_request_hooks` and `hook_results.after_request_hooks` in the response, exactly as they do for saved guardrails.
> [!NOTE]
>
> Inline checks still respect org-level guardrail settings — checks belonging to a disabled guardrail category are skipped. Configs travel in a request header, so very large inline configs can hit proxy header size limits. For big or shared guardrails, create a saved guardrail and reference it by ID instead.
### Webhook Request Structure
Your webhook should accept `POST` requests with the following structure:
#### Request Headers
| Header | Description |
| :- | :- |
| `Content-Type` | Always set to `application/json` |
| Custom Headers | Any headers you configured in the Portkey UI |
| Forwarded Headers | Client request headers configured via `parameters.forwardHeaders` on the check |
#### Request Body
Portkey sends comprehensive information about the AI request to your webhook:
**Webhook Request Structure**
**request** `object`
Information about the user's request to the LLM
**Properties**
**json** `object`
OpenAI compliant request body json.
**text** `string`
Last message/prompt content from the overall request body.
**isStreamingRequest** `boolean`
Whether the request uses streaming
**response** `object`
Information about the LLM's response (empty for beforeRequestHook)
**Properties**
**json** `object`
OpenAI compliant response body json.
**text** `string`
Last message/prompt content from the overall response body.
**statusCode** `number`
HTTP status code from LLM provider
**provider** `string`
Portkey provider slug. Example: `openai`, `azure-openai`, etc.
**requestType** `string`
Type of request: `chatComplete`, `complete`, or `embed`
**metadata** `object`
Custom metadata passed with the request. Can come from: 1) the `x-portkey-metadata` header, 2) default API key settings, or 3) workspace defaults.
**eventType** `string`
When the hook is triggered: `beforeRequestHook` or `afterRequestHook`
#### Event Types
Your webhook can be triggered at two points:
* **beforeRequestHook**: Before the request is sent to the LLM provider
* **afterRequestHook**: After receiving a response from the LLM provider
```JSON beforeRequestHook Example [expandable] theme={"system"}
{
"request": {
"json": {
"stream": false,
"messages": [
{
"role": "system",
"content": "You are a helpful assistant"
},
{
"role": "user",
"content": "Say Hi"
}
],
"max_tokens": 20,
"n": 1,
"model": "gpt-4o-mini"
},
"text": "Say Hi",
"isStreamingRequest": false,
"isTransformed": false
},
"response": {
"json": {},
"text": "",
"statusCode": null,
"isTransformed": false
},
"provider": "openai",
"requestType": "chatComplete",
"metadata": {
"_user": "visarg123"
},
"eventType": "beforeRequestHook"
}
```
```JSON afterRequestHook Example [expandable] theme={"system"}
{
"request": {
"json": {
"stream": false,
"messages": [
{
"role": "system",
"content": "You are a helpful assistant"
},
{
"role": "user",
"content": "Say Hi"
}
],
"max_tokens": 20,
"n": 1,
"model": "gpt-4o-mini"
},
"text": "Say Hi",
"isStreamingRequest": false,
"isTransformed": false
},
"response": {
"json": {
"id": "chatcmpl-B9SAAj7zd4mq12omkeEImYvYnjbOr",
"object": "chat.completion",
"created": 1741592910,
"model": "gpt-4o-mini-2024-07-18",
"choices": [
{
"index": 0,
"message": {
"role": "assistant",
"content": "Hi! How can I assist you today?",
"refusal": null
},
"logprobs": null,
"finish_reason": "stop"
}
],
"usage": {
"prompt_tokens": 18,
"completion_tokens": 10,
"total_tokens": 28,
"prompt_tokens_details": {
"cached_tokens": 0,
"audio_tokens": 0
},
"completion_tokens_details": {
"reasoning_tokens": 0,
"audio_tokens": 0,
"accepted_prediction_tokens": 0,
"rejected_prediction_tokens": 0
}
},
"service_tier": "default",
"system_fingerprint": "fp_06737a9306"
},
"text": "Hi! How can I assist you today?",
"statusCode": 200,
"isTransformed": false
},
"provider": "openai",
"requestType": "chatComplete",
"metadata": {
"_user": "visarg123"
},
"eventType": "afterRequestHook"
}
```
### Webhook Response Structure
Your webhook must return a response that follows this structure:
#### Response Body
**Webhook Response Schema**
**verdict** `boolean` *required*
Whether the request/response passes your guardrail check:
* `true`: No violations detected
* `false`: Violations detected
**transformedData** `object`
Optional field to modify the request or response
**Properties**
**request** `object`
Modified request data (only for beforeRequestHook)
If this field is found in the Webhook response, Portkey will fully override the existing request body with the returned data.
**response** `object`
Modified response data (only for afterRequestHook)
If this field is found in the Webhook response, Portkey will fully override the existing response body with the returned data.
## Webhook Capabilities
Your webhook can perform three main actions:
### Simple Validation
Return a verdict without modifying the request/response:
```json theme={"system"}
{
"verdict": true // or false if the request violates your guardrails
}
```
### Request Transformation
Modify the user's request before it reaches the LLM provider:
> [tab] Example: Adding Content Policy
>
> ```json theme={"system"}
> {
> "verdict": true,
> "transformedData": {
> "request": {
> "json": {
> "messages": [
> {
> "role": "system",
> "content": "You are a helpful assistant. Do not provide harmful content."
> },
> {
> "role": "user",
> "content": "Original user message"
> }
> ],
> "max_tokens": 100,
> "model": "gpt-4o"
> }
> }
> }
> }
> ```
> [tab] Example: PII Redaction
>
> ```json theme={"system"}
> {
> "verdict": true,
> "transformedData": {
> "request": {
> "json": {
> "messages": [
> {
> "role": "system",
> "content": "You are a helpful assistant"
> },
> {
> "role": "user",
> "content": "My name is [REDACTED] and my email is [REDACTED]"
> }
> ],
> "max_tokens": 100,
> "model": "gpt-4o"
> }
> }
> }
> }
> ```
### Response Transformation
Modify the LLM's response before it reaches the user:
> [tab] Example: Content Filtering
>
> ```json theme={"system"}
> {
> "verdict": true,
> "transformedData": {
> "response": {
> "json": {
> "id": "chatcmpl-123",
> "object": "chat.completion",
> "created": 1741592832,
> "model": "gpt-4o-mini",
> "choices": [
> {
> "index": 0,
> "message": {
> "role": "assistant",
> "content": "I've filtered this response to comply with our content policies."
> },
> "finish_reason": "stop"
> }
> ],
> "usage": {
> "prompt_tokens": 23,
> "completion_tokens": 12,
> "total_tokens": 35
> }
> },
> "text": "I've filtered this response to comply with our content policies."
> }
> }
> }
> ```
> [tab] Example: Response Enhancement
>
> ```json theme={"system"}
> {
> "verdict": true,
> "transformedData": {
> "response": {
> "json": {
> "id": "chatcmpl-123",
> "object": "chat.completion",
> "created": 1741592832,
> "model": "gpt-4o-mini",
> "choices": [
> {
> "index": 0,
> "message": {
> "role": "assistant",
> "content": "Original response with additional disclaimer: This response is provided for informational purposes only."
> },
> "finish_reason": "stop"
> }
> ],
> "usage": {
> "prompt_tokens": 23,
> "completion_tokens": 20,
> "total_tokens": 43
> }
> },
> "text": "Original response with additional disclaimer: This response is provided for informational purposes only."
> }
> }
> }
> ```
## Passing Metadata to Your Webhook
You can include additional context with each request using Portkey's metadata feature:
```json theme={"system"}
// In your API request to Portkey
"x-portkey-metadata": {"user": "john", "context": "customer_support"}
```
This metadata will be forwarded to your webhook in the `metadata` field. [Learn more about metadata](/docs/product/observability/metadata).
## Forwarding Client Headers
You can forward specific client request headers to your webhook by adding `forwardHeaders` to the check's `parameters`. This is useful for passing trace IDs, session context, or tenant identifiers directly to your webhook endpoint.
```json theme={"system"}
{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://my-guardrail.example.com/check",
"forwardHeaders": ["x-session-id", "x-tenant-id", "traceparent"]
}
}
```
Your webhook will receive these headers alongside `Content-Type` and any custom headers configured in the UI.
> [card] [Forwarding Headers](/docs/product/guardrails/forwarding-headers)
## Running on Proxy Requests
By default, webhook guardrails only run on managed `/v1/chat/completions`-style requests where Portkey parses the full request/response body. Enable `executeOnProxy` to also run your webhook on raw proxy (`/v1/*`) pass-through requests.
```json theme={"system"}
{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://my-guardrail.example.com/check",
"executeOnProxy": true
}
}
```
When triggered on a proxy request, the webhook payload includes `method`, `path`, and `content-type` metadata instead of a fully parsed request body. This is useful for blocking or auditing traffic that bypasses the standard chat completions route.
## Important Implementation Notes
1. **Complete Transformations**: When using `transformedData`, include all fields in your transformed object, not just the changed portions.
2. **Independent Verdict and Transformation**: The `verdict` and any transformations are independent. You can return `verdict: false` while still returning transformations.
3. **Default Behavior**: If your webhook fails to respond within the timeout period, Portkey will default to `verdict: true`.
4. **Event Type Awareness**: When implementing transformations, ensure your webhook checks the `eventType` field to determine whether it's being called before or after the LLM request.
## Example Implementation
Check out our Guardrail Webhook implementation on GitHub:
> [card] [Guardrail Webhook Implementation](https://github.com/Portkey-AI/gateway/blob/main/plugins/default/webhook.ts)
## Get Help
Building custom webhooks? Reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) for support and to share your implementation experiences!
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Overview
Source: https://docs.portkey.ai/docs/integrations/llms
Portkey connects with all major LLM providers and orchestration frameworks.
## Supported AI Providers
> [card] [OpenAI](/docs/integrations/llms/openai)
>
> 
> [card] [Anthropic](/docs/integrations/llms/anthropic)
>
> 
> [card] [Azure OpenAI](/docs/integrations/llms/azure-openai)
>
> 
> [card] [AWS Bedrock](/docs/integrations/llms/aws-bedrock)
>
> 
> [card] [Cerebras](/docs/integrations/llms/cerebras)
>
> 
> [card] [TypeSafe](/docs/integrations/llms/typesafe)
> [card] [Google Gemini](/docs/integrations/llms/gemini)
>
> 
> [card] [Vertex AI](/docs/integrations/llms/vertex-ai)
>
> 
> [card] [Cohere](/docs/integrations/llms/cohere)
>
> 
> [card] [Perplexity AI](/docs/integrations/llms/perplexity-ai)
>
> 
> [card] [AI21](/docs/integrations/llms/ai21)
>
> 
> [card] [Anyscale](/docs/integrations/llms/anyscale-llama2-mistral-zephyr)
>
> 
> [card] [Byollm](/docs/integrations/llms/byollm)
> [card] [Dashscope](/docs/integrations/llms/dashscope)
>
> 
> [card] [Deepbricks](/docs/integrations/llms/deepbricks)
>
> 
> [card] [DeepInfra](/docs/integrations/llms/deepinfra)
>
> 
> [card] [DeepSeek](/docs/integrations/llms/deepseek)
>
> 
> [card] [Fireworks AI](/docs/integrations/llms/fireworks)
>
> 
> [card] [Featherless AI](/docs/integrations/llms/featherless)
>
> 
> [card] [Github Models](/docs/integrations/llms/github)
>
> 
> [card] [Google Palm](/docs/integrations/llms/google-palm)
>
> 
> [card] [Groq](/docs/integrations/llms/groq)
>
> 
> [card] [Jina AI](/docs/integrations/llms/jina-ai)
>
> 
> [card] [Lambda](/docs/integrations/llms/lambda)
>
> 
> [card] [Lemonfox AI](/docs/integrations/llms/lemon-fox)
>
> 
> [card] [Lepton AI](/docs/integrations/llms/lepton)
>
> 
> [card] [Lingyi (01.ai)](/docs/integrations/llms/lingyi-01.ai)
>
> 
> [card] [LocalAI](/docs/integrations/llms/local-ai)
>
> 
> [card] [Mistral AI](/docs/integrations/llms/mistral-ai)
>
> 
> [card] [MonsterAPI](/docs/integrations/llms/monster-api)
>
> 
> [card] [Moonshot](/docs/integrations/llms/moonshot)
>
> 
> [card] [nCompass](/docs/integrations/llms/ncompass)
>
> 
> [card] [Nebius](/docs/integrations/llms/nebius)
>
> 
> [card] [Nomic AI](/docs/integrations/llms/nomic)
>
> 
> [card] [Nscale](/docs/integrations/llms/nscale)
>
> 
> [card] [Ollama](/docs/integrations/llms/ollama)
>
> 
> [card] [Openrouter](/docs/integrations/llms/openrouter)
>
> 
> [card] [Predibase](/docs/integrations/llms/predibase)
>
> 
> [card] [Recraft AI](/docs/integrations/llms/recraft-ai)
>
> 
> [card] [Siliconflow](/docs/integrations/llms/siliconflow)
>
> 
> [card] [Snowflake Cortex](/docs/integrations/llms/snowflake-cortex)
>
> 
> [card] [Stability AI](/docs/integrations/llms/stability-ai)
>
> 
> [card] [Together AI](/docs/integrations/llms/together-ai)
>
> 
> [card] [Triton](/docs/integrations/llms/triton)
>
> 
> [card] [Upstage](/docs/integrations/llms/upstage)
>
> 
> [card] [Voyage-AI](/docs/integrations/llms/voyage-ai)
>
> 
> [card] [Workers AI](/docs/integrations/llms/workers-ai)
>
> 
> [card] [ZhipuAI](/docs/integrations/llms/zhipu)
>
> 
> [card] [Z AI](/docs/integrations/llms/z-ai)
>
> 
## Endpoints Supported
For a detailed breakdown of supported endpoints and features per provider, refer to the table below:
> [card] [Supported Providers](/docs/provider-endpoints/supported-providers)
## Supported Frameworks
Portkey has native integrations with the following frameworks. Click to read their getting started guides.
> [card] [Langchain](/docs/integrations/libraries/langchain-python)
>
> 
> [card] [LlamaIndex](/docs/integrations/libraries/llama-index-python)
>
> 
> [card] [Autogen](/docs/integrations/libraries/autogen)
>
> 
> [card] [Vercel](/docs/integrations/libraries/vercel)
>
> 
> [card] [Instructor](/docs/integrations/libraries/instructor)
>
> 
> [card] [DSPy](/docs/integrations/libraries/dspy)
>
> 
> [card] [Promptfoo](/docs/integrations/libraries/promptfoo)
>
> 
Have a suggestion for an integration with Portkey? Drop us a message via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
While you're here, why not [give us a star](https://git.new/ai-gateway-docs)? It helps us a lot!
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Anthropic
Source: https://docs.portkey.ai/docs/integrations/llms/anthropic
Integrate Anthropic's Claude models with Portkey's AI Gateway
Portkey provides a robust and secure gateway to integrate various Large Language Models (LLMs) into applications, including [Anthropic's Claude APIs](https://docs.anthropic.com/claude/reference/getting-started-with-the-api).
With Portkey, take advantage of features like fast AI gateway access, observability, prompt management, and more, while securely managing API keys through [Model Catalog](/docs/product/model-catalog).
> [card] All Models
>
> Full support for all Claude models including Sonnet and Haiku 4-5
> [card] All Endpoints
>
> `/messages`, `count-tokens` and more fully supported
> [card] Multi-Provider Support
>
> Use Claude from Anthropic, Bedrock, and Vertex with native SDK support
## Quick Start
Get Anthropic working in 3 steps:
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
# 1. Install: pip install portkey-ai
# 2. Add @anthropic provider in model catalog
# 3. Use it:
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.chat.completions.create(
model="@anthropic/claude-sonnet-4-5-20250929",
messages=[{"role": "user", "content": "What is Portkey's AI Gateway?"}],
max_tokens=250 # Required for Anthropic
)
print(response.choices[0].message.content)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
// 1. Install: npm install portkey-ai
// 2. Add @anthropic provider in model catalog
// 3. Use it:
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
})
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
messages: [{ role: "user", content: "What is Portkey's AI Gateway?" }],
max_tokens: 250 // Required for Anthropic
})
console.log(response.choices[0].message.content)
```
```python OpenAI Py icon="python" theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL
# 1. Install: pip install openai portkey-ai
# 2. Add @anthropic provider in model catalog
# 3. Use it:
client = OpenAI(
api_key="PORTKEY_API_KEY", # Portkey API key
base_url=PORTKEY_GATEWAY_URL
)
response = client.chat.completions.create(
model="@anthropic/claude-sonnet-4-5-20250929",
messages=[{"role": "user", "content": "What is Portkey's AI Gateway?"}],
max_tokens=250 # Required for Anthropic
)
print(response.choices[0].message.content)
```
```js OpenAI JS icon="square-js" theme={"system"}
import OpenAI from "openai"
import { PORTKEY_GATEWAY_URL } from "portkey-ai"
// 1. Install: npm install openai portkey-ai
// 2. Add @anthropic provider in model catalog
// 3. Use it:
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY", // Portkey API key
baseURL: PORTKEY_GATEWAY_URL
})
const response = await client.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
messages: [{ role: "user", content: "What is Portkey's AI Gateway?" }],
max_tokens: 250 // Required for Anthropic
})
console.log(response.choices[0].message.content)
```
```sh cURL icon="square-terminal" theme={"system"}
# 1. Add @anthropic provider in model catalog
# 2. Use it:
# /chat/completions endpoint (OpenAI-compatible)
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic/claude-sonnet-4-5-20250929",
"messages": [
{ "role": "user", "content": "What is Portkey's AI Gateway?" }
],
"max_tokens": 250
}'
# /messages endpoint (Anthropic native) - also supported
curl https://api.portkey.ai/v1/messages \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@anthropic/claude-sonnet-4-5-20250929",
"max_tokens": 250,
"messages": [
{ "role": "user", "content": "What is Portkey's AI Gateway?" }
]
}'
```
```python Anthropic Py theme={"system"}
import anthropic
# 1. Install: pip install anthropic portkey-ai
# 2. Add @anthropic provider in model catalog
# 3. Use it:
client = anthropic.Anthropic(
api_key="dummy", # we will use portkey's provider slug
default_headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
base_url="https://api.portkey.ai"
)
message = client.messages.create(
model="@anthropic/claude-sonnet-4-5-20250929",
max_tokens=250,
messages=[{"role": "user", "content": "What is Portkey's AI Gateway?"}]
)
print(message.content)
```
```typescript Anthropic TS theme={"system"}
import Anthropic from '@anthropic-ai/sdk'
// 1. Install: npm install @anthropic-ai/sdk portkey-ai
// 2. Add @anthropic provider in model catalog
// 3. Use it:
const anthropic = new Anthropic({
apiKey: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai"
})
const msg = await anthropic.messages.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
max_tokens: 250,
messages: [{ role: "user", content: "What is Portkey's AI Gateway?" }],
})
console.log(msg)
```
> [!NOTE]
>
> **Tip:** You can also set `provider="@anthropic"` in `Portkey()` and use just `model="claude-sonnet-4-5-20250929"` in the request.
* **`max_tokens` is required** - Always specify this parameter
* **System prompts** - Handled differently (see System Prompts section below)
* **Model naming** - Use full model names like `claude-sonnet-4-5-20250929`
## Add Provider in Model Catalog
1. Go to [**Model Catalog → Add Provider**](https://app.portkey.ai/model-catalog/providers)
2. Select **Anthropic**
3. Choose existing credentials or create new by entering your [Anthropic API key](https://console.anthropic.com/settings/keys)
4. Name your provider (e.g., `anthropic-prod`)
To connect without an API key, use [Workload Identity Federation](/docs/product/model-catalog/workload-identity-federation) with Microsoft Entra ID, Okta, or another OIDC identity provider.
> [card] [Complete Setup Guide →](/docs/product/model-catalog)
>
> See all setup options, code examples, and detailed instructions
## Basic Usage
### Chat Completions
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
})
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
messages: [
{ role: "system", content: "You are a helpful assistant." },
{ role: "user", content: "What is Portkey's AI Gateway?" }
],
max_tokens: 250 // Required
})
console.log(response.choices[0].message.content)
```
### System Prompts
Anthropic handles system prompts differently than OpenAI. With Portkey, you can use the OpenAI-compatible format:
```python Python icon="python" theme={"system"}
response = portkey.chat.completions.create(
model="@anthropic/claude-sonnet-4-5-20250929",
messages=[
{"role": "system", "content": "You are a snarky assistant."},
{"role": "user", "content": "How do I boil water?"}
],
max_tokens=250
)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
messages: [
{ role: "system", content: "You are a snarky assistant." },
{ role: "user", content: "How do I boil water?" }
],
max_tokens: 250
})
```
Portkey automatically formats this for Anthropic's API.
### Streaming
Streaming works the same as OpenAI:
```python Python icon="python" theme={"system"}
response = portkey.chat.completions.create(
model="@anthropic/claude-sonnet-4-5-20250929",
messages=[{"role": "user", "content": "Tell me a story"}],
max_tokens=500,
stream=True
)
for chunk in response:
if chunk.choices[0].delta.content:
print(chunk.choices[0].delta.content, end="")
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
messages: [{ role: "user", content: "Tell me a story" }],
max_tokens: 500,
stream: true
})
for await (const chunk of response) {
if (chunk.choices[0].delta.content) {
process.stdout.write(chunk.choices[0].delta.content)
}
}
```
### Catch Overloaded Error on Stream
Anthropic's API can return an `overloaded_error` inside a streaming response with HTTP status 200. The error appears as an SSE event:
```text theme={"system"}
event: error
data: {"type": "error", "error": {"type": "overloaded_error", "message": "Overloaded"}}
```
By default, the gateway treats this as a successful (status 200) response and streams the error directly to the client, which means retry, fallback, and circuit breaker strategies do not activate (they rely on HTTP status codes).
When **Catch Overloaded Error on Stream** is enabled on an Anthropic integration, the gateway intercepts these errors before they reach the client and converts them into HTTP `529` responses, allowing your retry and fallback strategies to trigger automatically.
> [!NOTE]
>
> This feature is only available for the Anthropic provider. Other providers (e.g., Bedrock) handle overload errors at the HTTP level, where existing retry/fallback already applies. It also only applies to **streaming** requests — non-streaming Anthropic requests already return HTTP 529 directly.
#### How it works
When enabled on an integration, the gateway:
1. Reads the first chunk of the Anthropic streaming response before committing it to the client
2. Skips any keepalive ping events
3. If the first meaningful event is an `overloaded_error`, returns an HTTP `529` response instead of the stream
4. If the first event is normal content, continues streaming as usual with no data loss
If no retry strategy is present and an `overloaded_error` is found, the request fails as a normal request with error `529`.
The `529` response integrates with the gateway's existing error handling and supports all existing config combinations:
* **Retry**: Triggers automatically when retry is configured
* **Fallback**: Moves to the next target in a fallback strategy
* **Circuit breaker**: Counts as a failure for circuit breaker thresholds
> [!NOTE]
>
> Performance: There is zero overhead when the setting is disabled. When enabled, only the first event is inspected before the stream is committed.
#### How to enable
**1. Enable the flag on your Anthropic integration**
Go to **Model Catalog → Integrations → Anthropic** and enable the **Catch Overloaded Error on Stream** flag, then create or update the integration.
**2. Add 529 to your retry status codes**
In your [config](/docs/product/ai-gateway/configs), add `529` to the retry `on_status_codes` (or fallback `on_status_codes`). This supports all existing config combinations.
**3. Attach the config to your API key**
Attach the updated config to your API key so the new behavior applies to all routed requests.
Once enabled, all Anthropic streaming requests routed through the gateway are checked for overloaded errors.
#### Example: Fallback on overload
With a fallback config using two Anthropic integrations (both with **Catch Overloaded Error on Stream** enabled), if the primary returns an overloaded error during streaming, the gateway automatically retries with the backup:
```json theme={"system"}
{
"strategy": { "mode": "fallback" },
"targets": [
{ "provider": "anthropic", "virtual_key": "anthropic-primary" },
{ "provider": "anthropic", "virtual_key": "anthropic-backup" }
]
}
```
#### Error response
When an overloaded error is detected, the client receives:
```http theme={"system"}
HTTP/1.1 529
{
"error": {
"message": "Overloaded",
"type": "overloaded_error",
"param": null,
"code": null
}
}
```
## Advanced Features
### Vision (Multimodal)
Portkey supports Anthropic's vision models including `claude-sonnet-4-5-20250929`, `claude-3-5-sonnet`, `claude-3-haiku`, `claude-3-opus`, and `claude-3.7-sonnet`. Use the same format as OpenAI:
> [!NOTE]
>
> Anthropic **only accepts base64-encoded images** and does not support image URLs. Use the same base64 format to send images to both Anthropic and OpenAI models.
```python Python icon="python" theme={"system"}
import base64
import httpx
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
# Fetch and encode the image
image_url = "https://upload.wikimedia.org/wikipedia/commons/a/a7/Camponotus_flavomarginatus_ant.jpg"
image_data = base64.b64encode(httpx.get(image_url).content).decode("utf-8")
response = portkey.chat.completions.create(
model="@anthropic/claude-sonnet-4-5-20250929",
messages=[{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": f"data:image/jpeg;base64,{image_data}"}},
{"type": "text", "text": "What's in this image?"}
]
}],
max_tokens=300
)
print(response.choices[0].message.content)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
import axios from 'axios'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
})
// Fetch and encode the image
const imageUrl = "https://upload.wikimedia.org/wikipedia/commons/a/a7/Camponotus_flavomarginatus_ant.jpg"
const imageResponse = await axios.get(imageUrl, { responseType: 'arraybuffer' })
const imageBase64 = Buffer.from(imageResponse.data).toString('base64')
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
messages: [{
role: "user",
content: [
{ type: "image_url", image_url: { url: `data:image/jpeg;base64,${imageBase64}` } },
{ type: "text", text: "What's in this image?" }
]
}],
max_tokens: 300
})
console.log(response.choices[0].message.content)
```
> [!NOTE]
>
> To prompt with PDFs, update the `url` field to: `data:application/pdf;base64,BASE64_PDF_DATA`
### PDF Support
Anthropic Claude processes PDFs to extract text, analyze charts, and understand visual content. PDF support is available on:
* Claude 3.7 Sonnet (`claude-3-7-sonnet-20250219`)
* Claude 3.5 Sonnet (`claude-3-5-sonnet-20241022`, `claude-3-5-sonnet-20240620`)
* Claude Sonnet 4-5 (`claude-sonnet-4-5-20250929`)
* Claude 3.5 Haiku (`claude-3-5-haiku-20241022`)
**Limitations:**
* Maximum request size: 32MB
* Maximum pages per request: 100
* Format: Standard PDF (no passwords/encryption)
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
import base64
import httpx
portkey = Portkey(api_key="PORTKEY_API_KEY")
# Fetch and encode the PDF
pdf_url = "https://assets.anthropic.com/m/1cd9d098ac3e6467/original/Claude-3-Model-Card-October-Addendum.pdf"
pdf_data = base64.standard_b64encode(httpx.get(pdf_url).content).decode("utf-8")
response = portkey.chat.completions.create(
model="@anthropic/claude-sonnet-4-5-20250929",
max_tokens=1024,
messages=[
{"role": "system", "content": "You are a helpful document analysis assistant."},
{
"role": "user",
"content": [
{"type": "text", "text": "What are the key findings in this document?"},
{"type": "file", "file": {"mime_type": "application/pdf", "file_data": pdf_data}}
]
}
]
)
print(response.choices[0].message.content)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
import axios from 'axios'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
})
// Fetch and encode the PDF
const pdfUrl = "https://assets.anthropic.com/m/1cd9d098ac3e6467/original/Claude-3-Model-Card-October-Addendum.pdf"
const pdfResponse = await axios.get(pdfUrl, { responseType: 'arraybuffer' })
const pdfBase64 = Buffer.from(pdfResponse.data).toString('base64')
const pdfData = `data:application/pdf;base64,${pdfBase64}`
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-sonnet-4-5-20250929",
max_tokens: 1024,
messages: [
{ role: "system", content: "You are a helpful document analysis assistant." },
{
role: "user",
content: [
{ type: "text", text: "What are the key findings in this document?" },
{ type: "file", file: { mime_type: "application/pdf", file_data: pdfData } }
]
}
]
})
console.log(response.choices[0].message.content)
```
### Extended Thinking (Reasoning Models)
Models like `claude-3-7-sonnet-latest` support [extended thinking](https://docs.anthropic.com/en/docs/build-with-claude/extended-thinking#streaming-extended-thinking). Get the model's reasoning as it processes the request.
> [!NOTE]
>
> The assistant's thinking response is returned in the `response_chunk.choices[0].delta.content_blocks` array, not the `response.choices[0].message.content` string.
Set `strict_open_ai_compliance=False` to use this feature:
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
strict_open_ai_compliance=False
)
response = portkey.chat.completions.create(
model="@anthropic/claude-3-7-sonnet-latest",
max_tokens=3000,
thinking={"type": "enabled", "budget_tokens": 2030},
stream=False,
messages=[{
"role": "user",
"content": [{
"type": "text",
"text": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}]
}]
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
strictOpenAiCompliance: false
})
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-3-7-sonnet-latest",
max_tokens: 3000,
thinking: { type: "enabled", budget_tokens: 2030 },
stream: false,
messages: [{
role: "user",
content: [{
type: "text",
text: "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number, and what is its baggage belt?"
}]
}]
})
console.log(response)
```
### Using /messages Route
Portkey supports Anthropic's `/messages` endpoint, allowing you to use either Anthropic's native SDK or Portkey's SDK with full gateway features.
#### Using Anthropic's Native SDK
```python Anthropic Py theme={"system"}
import anthropic
client = anthropic.Anthropic(
api_key="dummy", # we will use portkey's provider slug
default_headers={"x-portkey-api-key": "YOUR_PORTKEY_API_KEY"},
base_url="https://api.portkey.ai"
)
message = client.messages.create(
model="@your-provider-slug/claude-sonnet-4-5-20250929",
max_tokens=250,
messages=[{"role": "user", "content": "Hello, Claude"}]
)
print(message.content)
```
```typescript Anthropic TS theme={"system"}
import Anthropic from '@anthropic-ai/sdk'
const anthropic = new Anthropic({
apiKey: "YOUR_PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai"
})
const msg = await anthropic.messages.create({
model: "@your-provider-slug/claude-sonnet-4-5-20250929",
max_tokens: 1024,
messages: [{ role: "user", content: "Hello, Claude" }]
})
console.log(msg)
```
#### Using Portkey's SDK
```sh cURL icon="square-terminal" theme={"system"}
curl --location 'https://api.portkey.ai/v1/messages' \
--header 'x-portkey-provider: anthropic' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: YOUR_PORTKEY_API_KEY' \
--data-raw '{
"model": "@your-provider-slug/claude-sonnet-4-5-20250929",
"max_tokens": 1024,
"stream": true,
"messages": [
{
"role": "user",
"content": "What is the weather like in Chennai?"
}
]
}'
```
> [!NOTE]
>
> You can use all Portkey features (like caching, observability, configs) with this route. Just add the `x-portkey-config`, `x-portkey-provider`, `x-portkey-...` headers.
### Prompt Caching
Portkey works with Anthropic's prompt caching feature to save time and money. Refer to this guide:
> [card] [Prompt Caching](/docs/integrations/llms/anthropic/prompt-caching)
>
> Learn how to enable prompt caching for Anthropic requests
### Structured Outputs
Ensure that the model always follows your supplied JSON schema with Portkey's structured outputs support.
> [card] [Structured Outputs](/docs/integrations/llms/anthropic/structured-outputs)
>
> Learn how to use Pydantic, Zod, or JSON schema for structured data from Anthropic
### Web Search
Anthropic Claude models support web search as a tool, allowing the model to search the web for up-to-date information.
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
strict_open_ai_compliance=False
)
response = portkey.chat.completions.create(
model="@anthropic/claude-haiku-4-5-20250929",
max_tokens=1024,
messages=[{"role": "user", "content": "What is the latest news on Poland?"}],
tools=[{
"type": "web_search",
"web_search": {
"name": "web_search_20250305",
"max_uses": 2
}
}]
)
print(response.choices[0].message.content)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
strictOpenAiCompliance: false
})
const response = await portkey.chat.completions.create({
model: "@anthropic/claude-haiku-4-5-20250929",
max_tokens: 1024,
messages: [{ role: "user", content: "What is the latest news on Poland?" }],
tools: [{
type: "web_search",
web_search: {
name: "web_search_20250305",
max_uses: 2
}
}]
})
console.log(response.choices[0].message.content)
```
```sh cURL icon="square-terminal" theme={"system"}
curl POST 'https://api.portkey.ai/v1/chat/completions' \
--header 'x-portkey-provider: @my-anthropic' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: $PORTKEY_API_KEY' \
--header 'x-portkey-strict-open-ai-compliance: false' \
--data '{
"model": "claude-haiku-4-5",
"max_tokens": 1024,
"messages": [
{
"role": "user",
"content": "What is the latest news on Poland?"
}
],
"tools": [
{
"type": "web_search",
"web_search": {
"name": "web_search_20250305",
"max_uses": 2
}
}
]
}'
```
> [!NOTE]
>
> Set `strict_open_ai_compliance` to `false` (or use the header `x-portkey-strict-open-ai-compliance: false`) to receive citations in the response.
### Files API
Portkey supports Anthropic's [Files API](https://docs.anthropic.com/en/docs/build-with-claude/files) (beta), enabling you to upload, list, retrieve, and delete files through the gateway. Uploaded files can be referenced in chat completions using `file_id` instead of re-uploading content each request.
> [card] [Files API](/docs/integrations/llms/anthropic/files)
>
> Upload, list, retrieve, and delete files — then use them in chat completions
### Service Tier
When routing Chat Completions requests to Anthropic, Portkey automatically translates OpenAI's `service_tier` parameter to Anthropic's native `speed` parameter:
| `service_tier` | Anthropic `speed` |
| - | - |
| `auto` | `fast` |
| `standard_only` | `standard` |
| `default` | `standard` |
| `fast` | `fast` |
| `standard` | `standard` |
| unknown value | omitted |
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
provider="@anthropic"
)
response = portkey.chat.completions.create(
model="claude-sonnet-4-5",
max_tokens=1024,
messages=[{"role": "user", "content": "Hello!"}],
service_tier="auto" # maps to speed: "fast" on Anthropic
)
```
```js JavaScript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "@anthropic"
})
const response = await portkey.chat.completions.create({
model: "claude-sonnet-4-5",
max_tokens: 1024,
messages: [{ role: "user", content: "Hello!" }],
service_tier: "auto" // maps to speed: "fast" on Anthropic
})
```
```sh cURL icon="square-terminal" theme={"system"}
curl -X POST https://api.portkey.ai/v1/chat/completions \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: @anthropic" \
-H "Content-Type: application/json" \
-d '{
"model": "claude-sonnet-4-5",
"max_tokens": 1024,
"messages": [{"role": "user", "content": "Hello!"}],
"service_tier": "auto"
}'
```
### Beta Features
Portkey supports Anthropic's beta features through headers. Pass the beta feature name as the value:
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
client = Portkey(
api_key="PORTKEY_API_KEY",
provider="@anthropic",
anthropic_beta="token-efficient-tools-2025-02-19",
strict_open_ai_compliance=False
)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "@anthropic",
anthropicBeta: "token-efficient-tools-2025-02-19",
strictOpenAiCompliance: false
})
```
```sh cURL icon="square-terminal" theme={"system"}
x-portkey-anthropic-beta: "token-efficient-tools-2025-02-19"
```
## Managing Anthropic Prompts
Manage all prompt templates to Anthropic in the [Prompt Library](/docs/product/prompt-library). All current Anthropic models are supported, and you can easily test different prompts.
Use the `portkey.prompts.completions.create` interface to use the prompt in an application.
## Next Steps
> [card] [Add Metadata](/docs/product/observability/metadata)
>
> Add metadata to your Anthropic requests
> [card] [Gateway Configs](/docs/product/ai-gateway/configs)
>
> Add gateway configs to your Anthropic requests
> [card] [Tracing](/docs/product/observability/traces)
>
> Trace your Anthropic requests
> [card] [Fallbacks](/docs/product/ai-gateway/fallbacks)
>
> Setup fallback from OpenAI to Anthropic
For complete SDK documentation:
> [card] [SDK Reference](/docs/api-reference/sdk/list)
>
> Complete Portkey SDK documentation
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Structured Outputs
Source: https://docs.portkey.ai/docs/integrations/llms/anthropic/structured-outputs
Direct models to return data that conforms to a specific JSON schema.
Structured Outputs ensure that models follow your supplied [JSON schema](https://json-schema.org/overview/what-is-jsonschema). Portkey supports this for Anthropic models using a unified `response_format` interface.
Define object schemas using [Pydantic](https://docs.pydantic.dev/latest/) (Python) or [Zod](https://zod.dev/) (JavaScript) to extract structured information from unstructured text.
### 1. Using Pydantic or Zod (Recommended)
This approach provides type hinting and automatic validation.
```python Portkey Python SDK theme={"system"}
from portkey_ai import Portkey
from pydantic import BaseModel
class Step(BaseModel):
explanation: str
output: str
class MathReasoning(BaseModel):
steps: list[Step]
final_answer: str
portkey = Portkey(
api_key="PORTKEY_API_KEY"
)
# Use .parse() for automatic parsing
completion = portkey.chat.completions.parse(
model="@anthropic-testing/claude-sonnet-4-6",
messages=[
{"role": "system", "content": "You are a helpful math tutor. Guide the user through the solution step by step."},
{"role": "user", "content": "how can I solve 8x + 7 = -23"}
],
response_format=MathReasoning
)
print(completion.choices[0].message.parsed)
```
```javascript Portkey Node SDK theme={"system"}
import { Portkey } from 'portkey-ai';
import { z } from 'zod';
import { zodResponseFormat } from "openai/helpers/zod";
const MathReasoning = z.object({
steps: z.array(z.object({ explanation: z.string(), output: z.string() })),
final_answer: z.string()
});
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
});
async function runMathTutor() {
try {
const completion = await portkey.chat.completions.create({
model: "@anthropic-testing/claude-sonnet-4-6",
messages: [
{ role: "system", content: "You are a helpful math tutor." },
{ role: "user", content: "Solve 8x + 7 = -23" }
],
response_format: zodResponseFormat(MathReasoning, "MathReasoning")
});
console.log(JSON.parse(completion.choices[0].message.content));
} catch (error) {
console.error("Error running math tutor:", error);
}
}
runMathTutor();
```
```python Anthropic Python SDK theme={"system"}
import json, re
from anthropic import Anthropic
from pydantic import BaseModel
class Step(BaseModel):
explanation: str
output: str
class MathReasoning(BaseModel):
steps: list[Step]
final_answer: str
def parse(client, model, messages, response_model):
schema = response_model.model_json_schema()
msg = client.messages.create(
model=model,
max_tokens=1024,
system=f"Return ONLY JSON matching this schema:\n{json.dumps(schema)}",
messages=messages
)
text = msg.content[0].text
json_text = re.search(r"\{.*\}", text, re.S).group(0)
return response_model.model_validate(json.loads(json_text))
client = Anthropic(
auth_token="PORTKEY_API_KEY",
base_url="https://api.portkey.ai"
)
completion = parse(
client,
"@anthropic-testing/claude-sonnet-4-6",
[{"role": "user", "content": "how can I solve 8x + 7 = -23"}],
MathReasoning
)
print(completion)
```
```javascript Anthropic JS SDK theme={"system"}
import Anthropic from "@anthropic-ai/sdk";
import { z } from "zod";
const Step = z.object({
explanation: z.string(),
output: z.string(),
});
const MathReasoning = z.object({
steps: z.array(Step),
final_answer: z.string(),
});
const client = new Anthropic({
authToken: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai",
});
async function main() {
const completion = await client.messages.create({
model: "@anthropic-testing/claude-sonnet-4-6",
max_tokens: 1024,
system: "Return ONLY valid JSON matching the schema: {steps:[{explanation:string,output:string}], final_answer:string}",
messages: [
{ role: "user", content: "how can I solve 8x + 7 = -23" }
],
});
const text = completion.content[0].text;
const jsonText = text.match(/\{[\s\S]*\}/)[0];
const result = MathReasoning.parse(JSON.parse(jsonText));
console.log(result);
}
main().catch(console.error);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "@anthropic-provider/claude-3-5-sonnet-20241022",
"messages": [
{"role": "system", "content": "You are a helpful math tutor. Guide the user through the solution step by step."},
{"role": "user", "content": "how can I solve 8x + 7 = -23"}
],
"response_format": {
"type": "json_schema",
"json_schema": {
"name": "math_reasoning",
"schema": {
"type": "object",
"properties": {
"steps": {
"type": "array",
"items": {
"type": "object",
"properties": {
"explanation": {"type": "string"},
"output": {"type": "string"}
},
"required": ["explanation", "output"],
"additionalProperties": false
}
},
"final_answer": {"type": "string"}
},
"required": ["steps", "final_answer"],
"additionalProperties": false
}
}
}
}'
```
### 2. Using Raw JSON Schema
For cross-language compatibility or dynamic schemas, pass a standard JSON schema directly.
```python Portkey Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY"
)
completion = portkey.chat.completions.create(
model="@anthropic-provider/claude-3-5-sonnet-20241022",
messages=[
{"role": "system", "content": "Extract the event information."},
{"role": "user", "content": "Alice and Bob are going to a science fair on Friday."}
],
response_format={
"type": "json_schema",
"json_schema": {
"name": "event_extraction",
"schema": {
"type": "object",
"properties": {
"location": { "type": "string" },
"date": { "type": "string" },
"participants": { "type": "array", "items": { "type": "string" } }
},
"required": ["location", "date", "participants"],
"additionalProperties": False
},
"strict": True
}
}
)
print(completion.choices[0].message.content)
```
```javascript Portkey Node SDK theme={"system"}
import { Portkey } from "portkey-ai";
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
});
async function main() {
try {
const completion = await portkey.chat.completions.create({
model: "@anthropic-provider/claude-3-5-sonnet-20241022",
messages: [
{ role: "system", content: "Extract the event information." },
{ role: "user", content: "Alice and Bob are going to a science fair on Friday." }
],
response_format: {
type: "json_schema",
json_schema: {
name: "event_extraction",
schema: {
type: "object",
properties: {
location: { type: "string" },
date: { type: "string" },
participants: { type: "array", items: { type: "string" } }
},
required: ["location", "date", "participants"],
additionalProperties: false
},
strict: true
}
}
});
console.log(completion.choices[0].message.content);
} catch (error) {
console.error("Error extracting event:", error);
}
}
main();
```
```python Anthropic Python SDK theme={"system"}
from anthropic import Anthropic
import json
client = Anthropic(
auth_token="PORTKEY_API_KEY",
base_url="https://api.portkey.ai" )
schema = {
"type": "object",
"properties": {
"location": {"type": "string"},
"date": {"type": "string"},
"participants": {
"type": "array",
"items": {"type": "string"}
}
},
"required": ["location", "date", "participants"],
"additionalProperties": False
}
prompt = f"""
Extract the event information from the sentence.
Return ONLY valid JSON matching this schema:
{json.dumps(schema, indent=2)}
Sentence:
Alice and Bob are going to a science fair on Friday.
"""
response = client.messages.create(
model="@anthropic-testing/claude-sonnet-4-6",
max_tokens=200,
system="You are an information extraction system. Only return valid JSON.",
messages=[
{
"role": "user",
"content": prompt
}
]
)
print(response.content[0].text)
```
```javascript Anthropic JS SDK theme={"system"}
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic({
authToken: "PORTKEY_API_KEY",
baseURL: "https://api.portkey.ai",
});
async function main() {
const message = await client.messages.create({
model: "@anthropic-testing/claude-sonnet-4-6",
max_tokens: 1024,
messages: [{ role: "user", content: "Alice and Bob are going to a science fair on Friday." }],
response_format: {
type: "json_schema",
json_schema: {
name: "event_extraction",
schema: {
type: "object",
properties: {
location: { type: "string" },
date: { type: "string" },
participants: { type: "array", items: { type: "string" } }
},
required: ["location", "date", "participants"],
additionalProperties: false
},
strict: true
}
}
});
console.log(message.content);
}
main().catch(console.error);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "@anthropic-provider/claude-3-5-sonnet-20241022",
"messages": [
{ "role": "system", "content": "Extract event information." },
{ "role": "user", "content": "Alice and Bob are going to a science fair on Friday." }
],
"response_format": {
"type": "json_schema",
"json_schema": {
"name": "event_extraction",
"schema": {
"type": "object",
"properties": {
"location": { "type": "string" },
"date": { "type": "string" },
"participants": { "type": "array", "items": { "type": "string" } }
},
"required": ["location", "date", "participants"],
"additionalProperties": false
},
"strict": true
}
}
}'
```
For more, refer to Anthropic's [detailed documentation on Structured Outputs here](https://docs.anthropic.com/en/docs/build-with-claude/structured-outputs).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# OpenAI
Source: https://docs.portkey.ai/docs/integrations/llms/openai
Integrate OpenAI's GPT models with Portkey's AI Gateway
Portkey provides a robust and secure gateway to integrate [OpenAI's APIs](https://platform.openai.com/docs/api-reference/introduction) into your applications, including GPT-4o, o1, DALL·E, Whisper, and more.
With Portkey, take advantage of features like fast AI gateway access, observability, prompt management, and more, while securely managing API keys through [Model Catalog](/docs/product/model-catalog).
> [card] All Models
>
> Full support for GPT-4o, o1, GPT-4, GPT-3.5, and all OpenAI models
> [card] All Endpoints
>
> Chat, completions, embeddings, audio, images, and more fully supported
> [card] Multi-SDK Support
>
> Use with OpenAI SDK, Portkey SDK, or popular frameworks like LangChain
## Quick Start
Get OpenAI working in 3 steps:
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
# 1. Install: pip install portkey-ai
# 2. Add @openai provider in model catalog
# 3. Use it:
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.chat.completions.create(
model="@openai/gpt-4o",
messages=[{"role": "user", "content": "Say this is a test"}]
)
print(response.choices[0].message.content)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
// 1. Install: npm install portkey-ai
// 2. Add @openai provider in model catalog
// 3. Use it:
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
})
const response = await portkey.chat.completions.create({
model: "@openai/gpt-4o",
messages: [{ role: "user", content: "Say this is a test" }]
})
console.log(response.choices[0].message.content)
```
```python OpenAI Py icon="python" theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL
# 1. Install: pip install openai portkey-ai
# 2. Add @openai provider in model catalog
# 3. Use it:
client = OpenAI(
api_key="PORTKEY_API_KEY", # Portkey API key
base_url=PORTKEY_GATEWAY_URL
)
response = client.chat.completions.create(
model="@openai/gpt-4o",
messages=[{"role": "user", "content": "Say this is a test"}]
)
print(response.choices[0].message.content)
```
```js OpenAI JS icon="square-js" theme={"system"}
import OpenAI from "openai"
import { PORTKEY_GATEWAY_URL } from "portkey-ai"
// 1. Install: npm install openai portkey-ai
// 2. Add @openai provider in model catalog
// 3. Use it:
const client = new OpenAI({
apiKey: "PORTKEY_API_KEY", // Portkey API key
baseURL: PORTKEY_GATEWAY_URL
})
const response = await client.chat.completions.create({
model: "@openai/gpt-4o",
messages: [{ role: "user", content: "Say this is a test" }]
})
console.log(response.choices[0].message.content)
```
```sh cURL icon="square-terminal" theme={"system"}
# 1. Add @openai provider in model catalog
# 2. Use it:
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: @openai" \
-d '{
"model": "gpt-4o",
"messages": [
{ "role": "user", "content": "Say this is a test" }
]
}'
```
> [!NOTE]
>
> **Tip:** You can also set `provider="@openai"` in `Portkey()` and use just `model="gpt-4o"` in the request.
>
> **Legacy support:** The `virtual_key` parameter still works for backwards compatibility.
## Add Provider in Model Catalog
1. Go to [**Model Catalog → Add Provider**](https://app.portkey.ai/model-catalog/providers)
2. Select **OpenAI**
3. Choose existing credentials or create new by entering your [OpenAI API key](https://platform.openai.com/api-keys)
4. (Optional) Add your OpenAI **Organization ID** and **Project ID** for better cost tracking
5. Name your provider (e.g., `openai-prod`)
To connect without an API key, use [Workload Identity Federation](/docs/product/model-catalog/workload-identity-federation) with Microsoft Entra ID, Okta, or another OIDC identity provider.
> [card] [Complete Setup Guide →](/docs/product/model-catalog)
>
> See all setup options, code examples, and detailed instructions
## Basic Usage
### Streaming
Stream responses for real-time output in your applications:
```python Python icon="python" theme={"system"}
response = portkey.chat.completions.create(
model="@openai/gpt-4o",
messages=[{"role": "user", "content": "Tell me a story"}],
stream=True
)
for chunk in response:
if chunk.choices[0].delta.content:
print(chunk.choices[0].delta.content, end="", flush=True)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.chat.completions.create({
model: "@openai/gpt-4o",
messages: [{ role: "user", content: "Tell me a story" }],
stream: true
})
for await (const chunk of response) {
if (chunk.choices[0]?.delta?.content) {
process.stdout.write(chunk.choices[0].delta.content)
}
}
```
## Advanced Features
### Responses API
OpenAI's Responses API combines the best of both Chat Completions and Assistants APIs. Portkey fully supports this API with both the Portkey SDK and OpenAI SDK.
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
response = portkey.responses.create(
model="@openai/gpt-4.1",
input="Tell me a three sentence bedtime story about a unicorn."
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from 'portkey-ai'
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY"
})
const response = await portkey.responses.create({
model: "@openai/gpt-4.1",
input: "Tell me a three sentence bedtime story about a unicorn."
})
console.log(response)
```
```python OpenAI Py icon="python" theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL
client = OpenAI(
api_key="PORTKEY_API_KEY",
base_url=PORTKEY_GATEWAY_URL
)
response = client.responses.create(
model="@openai/gpt-4.1",
input="Tell me a three sentence bedtime story about a unicorn."
)
print(response)
```
```js OpenAI JS icon="square-js" theme={"system"}
import OpenAI from 'openai'
import { PORTKEY_GATEWAY_URL } from 'portkey-ai'
const openai = new OpenAI({
apiKey: "PORTKEY_API_KEY",
baseURL: PORTKEY_GATEWAY_URL
})
const response = await openai.responses.create({
model: "@openai/gpt-4.1",
input: "Tell me a three sentence bedtime story about a unicorn."
})
console.log(response)
```
> [!NOTE]
>
> The Responses API provides a more flexible foundation for building agentic applications with built-in tools that execute automatically.
> [card] [Remote MCP support on Responses API](/docs/product/ai-gateway/remote-mcp)
>
> Portkey supports Remote MCP support by OpenAI on its Responses API. Learn More
#### Streaming with Responses API
```python Python icon="python" theme={"system"}
response = portkey.responses.create(
model="@openai/gpt-4.1",
instructions="You are a helpful assistant.",
input="Hello!",
stream=True
)
for event in response:
print(event)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.responses.create({
model: "@openai/gpt-4.1",
instructions: "You are a helpful assistant.",
input: "Hello!",
stream: true
})
for await (const event of response) {
console.log(event)
}
```
```python OpenAI Py icon="python" theme={"system"}
response = client.responses.create(
model="gpt-4.1",
instructions="You are a helpful assistant.",
input="Hello!",
stream=True
)
for event in response:
print(event)
```
```js OpenAI JS icon="square-js" theme={"system"}
const response = await openai.responses.create({
model: "gpt-4.1",
instructions: "You are a helpful assistant.",
input: "Hello!",
stream: true
})
for await (const event of response) {
console.log(event)
}
```
### Realtime API
Portkey supports OpenAI's Realtime API with a seamless integration. This allows you to use Portkey's logging, cost tracking, and guardrail features while using the Realtime API.
> [card] [Realtime API](/docs/product/ai-gateway/realtime-api)
### Using Vision Models
Portkey's multimodal Gateway fully supports OpenAI vision models as well. See this guide for more info:
> [!NOTE]
>
> [Vision](/docs/product/ai-gateway/multimodal-capabilities/vision)
#### Vision with the Responses API
The Responses API also processes images alongside text:
```python Python icon="python" theme={"system"}
response = portkey.responses.create(
model="@openai/gpt-4.1",
input=[
{
"role": "user",
"content": [
{ "type": "input_text", "text": "What is in this image?" },
{
"type": "input_image",
"image_url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
}
]
}
]
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.responses.create({
model: "@openai/gpt-4.1",
input: [
{
role: "user",
content: [
{ type: "input_text", text: "What is in this image?" },
{
type: "input_image",
image_url: "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
}
]
}
]
})
console.log(response)
```
```python OpenAI Py icon="python" theme={"system"}
response = client.responses.create(
model="gpt-4.1",
input=[
{
"role": "user",
"content": [
{ "type": "input_text", "text": "What is in this image?" },
{
"type": "input_image",
"image_url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
}
]
}
]
)
print(response)
```
```js OpenAI JS icon="square-js" theme={"system"}
const response = await openai.responses.create({
model: "gpt-4.1",
input: [
{
role: "user",
content: [
{ type: "input_text", text: "What is in this image?" },
{
type: "input_image",
image_url: "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
}
]
}
]
})
console.log(response)
```
### Function Calling
Function calls within your OpenAI or Portkey SDK operations remain standard. These logs will appear in Portkey, highlighting the utilized functions and their outputs.
Additionally, you can define functions within your prompts and invoke the `portkey.prompts.completions.create` method as above.
#### Function Calling with the Responses API
The Responses API also supports function calling with the same powerful capabilities:
```python Python icon="python" theme={"system"}
tools = [
{
"type": "function",
"name": "get_current_weather",
"description": "Get the current weather in a given location",
"parameters": {
"type": "object",
"properties": {
"location": {
"type": "string",
"description": "The city and state, e.g. San Francisco, CA"
},
"unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}
},
"required": ["location", "unit"]
}
}
]
response = portkey.responses.create(
model="@openai/gpt-4.1",
tools=tools,
input="What is the weather like in Boston today?",
tool_choice="auto"
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
const tools = [
{
type: "function",
name: "get_current_weather",
description: "Get the current weather in a given location",
parameters: {
type: "object",
properties: {
location: {
type: "string",
description: "The city and state, e.g. San Francisco, CA"
},
unit: { type: "string", enum: ["celsius", "fahrenheit"] }
},
required: ["location", "unit"]
}
}
]
const response = await portkey.responses.create({
model: "@openai/gpt-4.1",
tools: tools,
input: "What is the weather like in Boston today?",
tool_choice: "auto"
})
console.log(response)
```
```python OpenAI Py icon="python" theme={"system"}
tools = [
{
"type": "function",
"name": "get_current_weather",
"description": "Get the current weather in a given location",
"parameters": {
"type": "object",
"properties": {
"location": {
"type": "string",
"description": "The city and state, e.g. San Francisco, CA"
},
"unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}
},
"required": ["location", "unit"]
}
}
]
response = client.responses.create(
model="gpt-4.1",
tools=tools,
input="What is the weather like in Boston today?",
tool_choice="auto"
)
print(response)
```
```js OpenAI JS icon="square-js" theme={"system"}
const tools = [
{
type: "function",
name: "get_current_weather",
description: "Get the current weather in a given location",
parameters: {
type: "object",
properties: {
location: {
type: "string",
description: "The city and state, e.g. San Francisco, CA"
},
unit: { type: "string", enum: ["celsius", "fahrenheit"] }
},
required: ["location", "unit"]
}
}
]
const response = await openai.responses.create({
model: "gpt-4.1",
tools: tools,
input: "What is the weather like in Boston today?",
tool_choice: "auto"
})
console.log(response)
```
### Fine-Tuning
Please refer to our fine-tuning guides to take advantage of Portkey's advanced [continuous fine-tuning](/docs/product/autonomous-fine-tuning) capabilities.
### Image Generation
Portkey supports multiple modalities for OpenAI. Make image generation requests through Portkey's AI Gateway the same way as making completion calls.
```js Javascript icon="square-js" theme={"system"}
// Define the OpenAI client as shown above
const image = await openai.images.generate({
model:"dall-e-3",
prompt:"Lucy in the sky with diamonds",
size:"1024x1024"
})
```
```python Python icon="python" theme={"system"}
# Define the OpenAI client as shown above
image = openai.images.generate(
model="dall-e-3",
prompt="Lucy in the sky with diamonds",
size="1024x1024"
)
```
Portkey's fast AI gateway captures the information about the request on your Portkey Dashboard. On your logs screen, you'd be able to see this request with the request and response.

Log view for an image generation request on OpenAI
More information on image generation is available in the [API Reference](/docs/provider-endpoints/images/create-image#create-image).
### Video Generation with Sora
Portkey supports OpenAI's Sora video generation models through the AI Gateway. Generate videos using the Portkey Python SDK:
```python theme={"system"}
from portkey_ai import Portkey
client = Portkey(
api_key="PORTKEY_API_KEY"
)
video = client.videos.create(
model="@openai/sora-2",
prompt="A video of a cool cat on a motorcycle in the night",
)
print("Video generation started:", video)
```
> [!NOTE]
>
> Pricing for video generation requests will be visible on your Portkey dashboard, allowing you to track costs alongside your other API usage.
### Audio - Transcription, Translation, and Text-to-Speech
Portkey's multimodal Gateway also supports the `audio` methods on OpenAI API. Check out the below guides for more info:
Check out the below guides for more info:
> [!NOTE]
>
> [Text-to-Speech](/docs/product/ai-gateway/multimodal-capabilities/text-to-speech)
> [!NOTE]
>
> [Speech-to-Text](/docs/product/ai-gateway/multimodal-capabilities/speech-to-text)
***
## Integrated Tools with Responses API
### Web Search Tool
Web search delivers accurate and clearly-cited answers from the web, using the same tool as search in ChatGPT:
```python Python icon="python" theme={"system"}
response = portkey.responses.create(
model="@openai/gpt-4.1",
tools=[{
"type": "web_search_preview",
"search_context_size": "medium", # Options: "high", "medium" (default), or "low"
"user_location": { # Optional - for localized results
"type": "approximate",
"country": "US",
"city": "San Francisco",
"region": "California"
}
}],
input="What was a positive news story from today?"
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.responses.create({
model: "@openai/gpt-4.1",
tools: [{
type: "web_search_preview",
search_context_size: "medium", // Options: "high", "medium" (default), or "low"
user_location: { // Optional - for localized results
type: "approximate",
country: "US",
city: "San Francisco",
region: "California"
}
}],
input: "What was a positive news story from today?"
})
console.log(response)
```
> [!NOTE]
>
> **Options for `search_context_size`:**
>
> * `high`: Most comprehensive context, higher cost, slower response
> * `medium`: Balanced context, cost, and latency (default)
> * `low`: Minimal context, lowest cost, fastest response
>
> Responses include citations for URLs found in search results, with clickable references.
### File Search Tool
File search enables quick retrieval from your knowledge base across multiple file types:
```python Python icon="python" theme={"system"}
response = portkey.responses.create(
model="@openai/gpt-4.1",
tools=[{
"type": "file_search",
"vector_store_ids": ["vs_1234567890"],
"max_num_results": 20,
"filters": { # Optional - filter by metadata
"type": "eq",
"key": "document_type",
"value": "report"
}
}],
input="What are the attributes of an ancient brown dragon?"
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.responses.create({
model: "@openai/gpt-4.1",
tools: [{
type: "file_search",
vector_store_ids: ["vs_1234567890"],
max_num_results: 20,
filters: { // Optional - filter by metadata
type: "eq",
key: "document_type",
value: "report"
}
}],
input: "What are the attributes of an ancient brown dragon?"
})
console.log(response)
```
> [!NOTE]
>
> This tool requires you to first create a vector store and upload files to it. Supports various file formats including PDFs, DOCXs, TXT, and more. Results include file citations in the response.
### Enhanced Reasoning
Control the depth of model reasoning for more comprehensive analysis:
```python Python icon="python" theme={"system"}
response = portkey.responses.create(
model="@openai/o3-mini",
input="How much wood would a woodchuck chuck?",
reasoning={
"effort": "high" # Options: "high", "medium", or "low"
}
)
print(response)
```
```js Javascript icon="square-js" theme={"system"}
const response = await portkey.responses.create({
model: "@openai/o3-mini",
input: "How much wood would a woodchuck chuck?",
reasoning: {
effort: "high" // Options: "high", "medium", or "low"
}
})
console.log(response)
```
### Computer Use Assistant
Portkey also supports the Computer Use Assistant (CUA) tool, which helps agents control computers or virtual machines through screenshots and actions. This feature is available for select developers as a research preview on premium tiers.
> [card]
>
> Learn More about Computer use tool here
>
> [Open](https://platform.openai.com/docs/guides/tools-computer-use?lang=python)
## Managing OpenAI Projects & Organizations in Portkey
When integrating OpenAI with Portkey, specify your OpenAI organization and project IDs along with your API key. This is particularly useful if you belong to multiple organizations or are accessing projects through a legacy user API key.
Specifying the organization and project IDs helps you maintain better control over your access rules, usage, and costs.
Add your Org & Project details using:
1. Adding in Model Catalog (Recommended)
2. Defining a Gateway Config
3. Passing Details in a Request
Let's explore each method in more detail.
### Using Model Catalog
When adding OpenAI from the Model Catalog, Portkey automatically displays optional fields for the organization ID and project ID alongside the API key field.
[Get your OpenAI API key from here](https://platform.openai.com/api-keys), then add it to Portkey along with your org/project details.

> [!NOTE]
>
> [Model Catalog](/docs/product/model-catalog)
Portkey takes budget management a step further than OpenAI. While OpenAI allows setting budget limits per project, Portkey enables you to set budget limits for each provider you create. For more information on budget limits, refer to this documentation:
> [!NOTE]
>
> [Budget Limits](/docs/product/ai-gateway/virtual-keys/budget-limits)
### Using the Gateway Config
You can also specify the organization and project details in the gateway config, either at the root level or within a specific target.
```json theme={"system"}
{
"provider": "@openai",
"openai_organization": "org-xxxxxx",
"openai_project": "proj_xxxxxxxx"
}
```
### While Making a Request
You can also pass your organization and project details directly when making a request using curl, the OpenAI SDK, or the Portkey SDK.
```python OpenAI Py icon="python" theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL
client = OpenAI(
api_key="PORTKEY_API_KEY",
organization="org-xxxxxxxxxx",
project="proj_xxxxxxxxx",
base_url=PORTKEY_GATEWAY_URL
)
chat_complete = client.chat.completions.create(
model="@openai/gpt-4o",
messages=[{"role": "user", "content": "Say this is a test"}],
)
print(chat_complete.choices[0].message.content)
```
```js OpenAI JS icon="square-js" theme={"system"}
import OpenAI from "openai"
import { PORTKEY_GATEWAY_URL } from "portkey-ai"
const openai = new OpenAI({
apiKey: "PORTKEY_API_KEY",
organization: "org-xxxxxx",
project: "proj_xxxxxxx",
baseURL: PORTKEY_GATEWAY_URL
})
async function main() {
const chatCompletion = await openai.chat.completions.create({
messages: [{ role: "user", content: "Say this is a test" }],
model: "@openai/gpt-4o",
})
console.log(chatCompletion.choices)
}
main()
```
```sh cURL icon="square-terminal" theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-H "x-portkey-openai-organization: org-xxxxxxx" \
-H "x-portkey-openai-project: proj_xxxxxxx" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: @openai" \
-d '{
"model": "gpt-4o",
"messages": [{"role": "user","content": "Hello!"}]
}'
```
```python Python icon="python" theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(
api_key="PORTKEY_API_KEY",
Authorization="Bearer OPENAI_API_KEY",
openai_organization="org-xxxxxxxxx",
openai_project="proj_xxxxxxxxx",
)
chat_complete = portkey.chat.completions.create(
model="@openai/gpt-4o",
messages=[{"role": "user", "content": "Say this is a test"}],
)
print(chat_complete.choices[0].message.content)
```
```js Javascript icon="square-js" theme={"system"}
import Portkey from "portkey-ai"
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
Authorization: "Bearer OPENAI_API_KEY",
openaiOrganization: "org-xxxxxxxxxxx",
openaiProject: "proj_xxxxxxxxxxxxx",
})
async function main() {
const chatCompletion = await portkey.chat.completions.create({
messages: [{ role: "user", content: "Say this is a test" }],
model: "@openai/gpt-4o",
})
console.log(chatCompletion.choices)
}
main()
```
***
## Frequently Asked Questions
### General FAQs
> [accordion] How to get the OpenAI API key?
>
> You can sign up to OpenAI [here](https://platform.openai.com/docs/overview) and grab your scoped API key [here](https://platform.openai.com/api-keys).
> [accordion] Is it free to use the OpenAI API?
>
> The OpenAI API can be used by signing up to the OpenAI platform. You can find the pricing info [here](https://openai.com/api/pricing/)
> [accordion] I am getting rate limited on OpenAI API
>
> You can find your current rate limits imposed by OpenAI [here](https://platform.openai.com/settings/organization/limits). For more tips, check out [this guide](/docs/guides/getting-started/tackling-rate-limiting).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Batches
Source: https://docs.portkey.ai/docs/integrations/llms/openai/batches
Perform batch inference with OpenAI
Portkey exposes [OpenAI’s Batch API](https://platform.openai.com/docs/guides/batch) through one consistent endpoint, so you can run large, asynchronous evaluation jobs at 50 % lower cost.
Use batches when you need to run large jobs offline — e.g. nightly evals, A/B tests, or bulk embeddings.
## Create Batch Job
Upload your .jsonl file first — see [Files API](/docs/integrations/llms/openai/files) for more details and then use the following code to create a batch job.
```python Python theme={"system"}
from portkey_ai import Portkey
# Initialize the Portkey client
portkey = Portkey(
api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
provider="@PROVIDER"
)
start_batch_response = portkey.batches.create(
input_file_id="file_id", # file id of the input file
endpoint="/v1/chat/completions",
completion_window="24h",
metadata={} # metadata for the batch
)
print(start_batch_response)
```
```javascript Typescript theme={"system"}
import { Portkey } from 'portkey-ai';
// Initialize the Portkey client
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
provider:"@PROVIDER"
});
const startBatch = async () => {
const startBatchResponse = await portkey.batches.create({
input_file_id: "file_id", // file id of the input file
endpoint: "/v1/chat/completions",
completion_window: "24h",
metadata: {} // metadata for the batch
});
console.log(startBatchResponse);
}
await startBatch();
```
```bash curl theme={"system"}
curl --location 'https://api.portkey.ai/v1/batches' \
--header 'x-portkey-api-key: ' \
--header 'x-portkey-provider: @provider' \
--header 'Content-Type: application/json' \
--data '{
"input_file_id": "",
"endpoint": "/v1/chat/completions",
"completion_window": "24h",
"metadata": {}
}'
```
```javascript OpenAI NodeJS theme={"system"}
import OpenAI from 'openai'; // We're using the v4 SDK
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const openai = new OpenAI({
apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "openai",
apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
})
});
const startBatch = async () => {
const startBatchResponse = await openai.batches.create({
input_file_id: "file_id", // file id of the input file
endpoint: "/v1/chat/completions",
completion_window: "24h",
metadata: {} // metadata for the batch
});
console.log(startBatchResponse);
}
await startBatch();
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
openai = OpenAI(
api_key='OPENAI_API_KEY',
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="openai",
api_key="PORTKEY_API_KEY"
)
)
start_batch_response = openai.batches.create(
input_file_id="file_id", # file id of the input file
endpoint="/v1/chat/completions",
completion_window="24h",
metadata={} # metadata for the batch
)
print(start_batch_response)
```
## List Batch Jobs
```python Python theme={"system"}
from portkey_ai import Portkey
# Initialize the Portkey client
portkey = Portkey(
api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
provider="@PROVIDER"
)
batches = portkey.batches.list()
print(batches)
```
```javascript Typescript theme={"system"}
import { Portkey } from 'portkey-ai';
// Initialize the Portkey client
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
provider:"@PROVIDER"
});
const listBatches = async () => {
const batches = await portkey.batches.list();
console.log(batches);
}
await listBatches();
```
```bash curl theme={"system"}
curl --location 'https://api.portkey.ai/v1/batches' \
--header 'x-portkey-api-key: ' \
--header 'x-portkey-provider: @provider'
```
```javascript OpenAI NodeJS theme={"system"}
import OpenAI from 'openai'; // We're using the v4 SDK
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const openai = new OpenAI({
apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "openai",
apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
})
});
const listBatches = async () => {
const batches = await openai.batches.list();
console.log(batches);
}
await listBatches();
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
openai = OpenAI(
api_key='OPENAI_API_KEY',
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="openai",
api_key="PORTKEY_API_KEY"
)
)
batches = openai.batches.list()
print(batches)
```
## Get Batch Job Details
```python Python theme={"system"}
from portkey_ai import Portkey
# Initialize the Portkey client
portkey = Portkey(
api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
provider="@PROVIDER"
)
batch = portkey.batches.retrieve(batch_id="batch_id")
print(batch)
```
```javascript Typescript theme={"system"}
import { Portkey } from 'portkey-ai';
// Initialize the Portkey client
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
provider:"@PROVIDER"
});
const getBatch = async () => {
const batch = await portkey.batches.retrieve(batch_id="batch_id");
console.log(batch);
}
await getBatch();
```
```bash curl theme={"system"}
curl --location 'https://api.portkey.ai/v1/batches/' \
--header 'x-portkey-api-key: ' \
--header 'x-portkey-provider: @provider'
```
```javascript OpenAI NodeJS theme={"system"}
import OpenAI from 'openai'; // We're using the v4 SDK
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const openai = new OpenAI({
apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "openai",
apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
})
});
const getBatch = async () => {
const batch = await openai.batches.retrieve(batch_id="batch_id");
console.log(batch);
}
await getBatch();
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
openai = OpenAI(
api_key='OPENAI_API_KEY',
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="openai",
api_key="PORTKEY_API_KEY"
)
)
batch = openai.batches.retrieve(batch_id="batch_id")
print(batch)
```
The status of a given Batch object can be any of the following:
| Status | Description |
| - | - |
| validating | the input file is being validated before the batch can begin |
| failed | the input file has failed the validation process |
| file\_upload\_failed | the batch job failed to upload the file to the provider after validation |
| batch\_start\_failed | the file upload succeeded but the batch job submission to the provider failed |
| in\_progress | the input file was successfully validated and the batch is currently being run |
| finalizing | the batch has completed and the results are being prepared |
| completed | the batch has been completed and the results are ready |
| expired | the batch was not able to be completed within the 24-hour time window |
| cancelling | the batch is being cancelled (may take up to 10 minutes) |
| cancelled | the batch was cancelled |
## Get Batch Output
```bash curl theme={"system"}
curl --location 'https://api.portkey.ai/v1/batches//output' \
--header 'x-portkey-api-key: ' \
--header 'x-portkey-provider: @provider'
```
## Cancel Batch Job
```python Python theme={"system"}
from portkey_ai import Portkey
# Initialize the Portkey client
portkey = Portkey(
api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
provider="@PROVIDER"
)
cancel_batch_response = portkey.batches.cancel(batch_id="batch_id")
print(cancel_batch_response)
```
```javascript Typescript theme={"system"}
import { Portkey } from 'portkey-ai';
// Initialize the Portkey client
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
provider:"@PROVIDER"
});
const cancelBatch = async () => {
const cancel_batch_response = await portkey.batches.cancel(batch_id="batch_id");
console.log(cancel_batch_response);
}
await cancelBatch();
```
```bash curl theme={"system"}
curl --request POST --location 'https://api.portkey.ai/v1/batches//cancel' \
--header 'x-portkey-api-key: ' \
--header 'x-portkey-provider: @provider'
```
```javascript OpenAI NodeJS theme={"system"}
import OpenAI from 'openai'; // We're using the v4 SDK
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
const openai = new OpenAI({
apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
provider: "openai",
apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
})
});
const cancelBatch = async () => {
const cancel_batch_response = await openai.batches.cancel(batch_id="batch_id");
console.log(cancel_batch_response);
}
await cancelBatch();
```
```python OpenAI Python theme={"system"}
from openai import OpenAI
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
openai = OpenAI(
api_key='OPENAI_API_KEY',
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="openai",
api_key="PORTKEY_API_KEY"
)
)
cancel_batch_response = openai.batches.cancel(batch_id="batch_id")
print(cancel_batch_response)
```
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Embeddings
Source: https://docs.portkey.ai/docs/integrations/llms/openai/embeddings
Generate vector embeddings from text using OpenAI's embedding models through Portkey.
OpenAI's embedding models transform text into lists of floating-point numbers (vectors). Smaller distances between vectors indicate higher semantic similarity, making them useful for semantic search, content clustering, recommendations, and anomaly detection.
## Usage
```python Python theme={"system"}
from portkey_ai import Portkey
client = Portkey(
api_key="PORTKEY_API_KEY",
provider="@OPENAI_PROVIDER"
)
response = client.embeddings.create(
input="Your text string goes here",
model="text-embedding-3-small"
)
print(response.data[0].embedding)
```
```ts Node.js theme={"system"}
import Portkey from 'portkey-ai';
const client = new Portkey({
apiKey: 'PORTKEY_API_KEY',
provider: '@OPENAI_PROVIDER'
});
const response = await client.embeddings.create({
input: "Your text string goes here",
model: "text-embedding-3-small"
});
console.log(response.data[0].embedding);
```
```py OpenAI Python SDK theme={"system"}
from openai import OpenAI
from portkey_ai import createHeaders, PORTKEY_GATEWAY_URL
client = OpenAI(
api_key="OPENAI_API_KEY",
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
api_key="PORTKEY_API_KEY",
provider="@OPENAI_PROVIDER"
)
)
response = client.embeddings.create(
input="Your text string goes here",
model="text-embedding-3-small"
)
print(response.data[0].embedding)
```
```ts OpenAI Node.js SDK theme={"system"}
import OpenAI from 'openai';
import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
const openai = new OpenAI({
apiKey: 'OPENAI_API_KEY',
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
apiKey: "PORTKEY_API_KEY",
provider: "@OPENAI_PROVIDER"
})
});
const response = await openai.embeddings.create({
input: "Your text string goes here",
model: "text-embedding-3-small"
});
console.log(response.data[0].embedding);
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/embeddings \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-provider: $PORTKEY_PROVIDER" \
-d '{
"input": "Your text string goes here",
"model": "text-embedding-3-small"
}'
```
## Supported Models
| Model | Dimensions | Notes |
| - | - | - |
| `text-embedding-3-small` | 1536 | Best cost/performance ratio |
| `text-embedding-3-large` | 3072 | Highest accuracy |
| `text-embedding-ada-002` | 1536 | Legacy model |
## Supported Parameters
| Parameter | Type | Description |
| - | - | - |
| `model` | string | Embedding model ID |
| `input` | string or array | Text to embed. Pass an array to embed multiple strings in one request |
| `encoding_format` | string | `float` (default) or `base64` |
| `dimensions` | integer | Reduce output dimensions (supported on v3 models only) |
| `user` | string | End-user ID for tracking |
## FAQs
> [accordion] How can I tell how many tokens a string has before I embed it?
>
> Use OpenAI's [Tiktoken library](https://cookbook.openai.com/examples/how_to_count_tokens_with_tiktoken) to count tokens before making an embedding request.
> [accordion] How can I retrieve K nearest embedding vectors quickly?
>
> Use a specialized vector database. See [OpenAI's vector database cookbook](https://cookbook.openai.com/examples/vector_databases/readme) for options and examples.
> [accordion] Do V3 embedding models know about recent events?
>
> The knowledge cutoff for `text-embedding-3-large` and `text-embedding-3-small` is September 2021.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Files
Source: https://docs.portkey.ai/docs/integrations/llms/openai/files
Upload files to OpenAI
## Uploading Files
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> upload_file_response = portkey.files.create(
> purpose="batch",
> file=open("file.pdf", "rb")
> )
>
> print(upload_file_response)
> ```
> [tab] NodeJS
>
> ```js theme={"system"}
> import { Portkey } from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> const uploadFile = async () => {
> const file = await portkey.files.create({
> purpose: "batch",
> file: fs.createReadStream("file.pdf")
> });
>
> console.log(file);
> }
>
> await uploadFile();
>
> ```
> [tab] REST
>
> ```sh theme={"system"}
> curl --location --request POST 'https://api.portkey.ai/v1/files' \
> --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider' \
> --form 'purpose=""' \
> --form 'file=@""'
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> const uploadFile = async () => {
> const file = await openai.files.create({
> purpose: "batch",
> file: fs.createReadStream("file.pdf")
> });
>
> console.log(file);
> }
>
> await uploadFile();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> upload_file_response = openai.files.create(
> purpose="batch",
> file=open("file.pdf", "rb")
> )
>
> print(upload_file_response)
> ```
## List Files
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> files = portkey.files.list()
>
> print(files)
> ```
> [tab] NodeJS
>
> ```js theme={"system"}
> import { Portkey } from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> const listFiles = async () => {
> const files = await portkey.files.list();
>
> console.log(files);
> }
>
> await listFiles();
>
> ```
> [tab] REST
>
> ```sh theme={"system"}
> curl --location 'https://api.portkey.ai/v1/files' \
> --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider'
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> const listFiles = async () => {
> const files = await openai.files.list();
>
> console.log(file);
> }
>
> await listFiles();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> files = openai.files.list()
>
> print(files)
> ```
## Get File
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> file = portkey.files.retrieve(file_id="file_id")
>
> print(file)
> ```
> [tab] NodeJS
>
> ```js theme={"system"}
> import { Portkey } from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> const getFile = async () => {
> const file = await portkey.files.retrieve(file_id="file_id");
>
> console.log(file);
> }
>
> await getFile();
>
> ```
> [tab] REST
>
> ```sh theme={"system"}
> curl --location 'https://api.portkey.ai/v1/files/' \
> --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider'
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> const getFile = async () => {
> const file = await openai.files.retrieve(file_id="file_id");
>
> console.log(file);
> }
>
> await getFile();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> file = openai.files.retrieve(file_id="file_id")
>
> print(file)
> ```
## Get File Content
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> file_content = portkey.files.content(file_id="file_id")
>
> print(file_content)
> ```
> [tab] NodeJS
>
> ```js theme={"system"}
> import { Portkey } from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> const getFileContent = async () => {
> const file_content = await portkey.files.content(file_id="file_id");
>
> console.log(file_content);
> }
>
> await getFileContent();
>
> ```
> [tab] REST
>
> ```sh theme={"system"}
> curl --location 'https://api.portkey.ai/v1/files//content' \
> --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider'
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> const getFileContent = async () => {
> const file_content = await openai.files.content(file_id="file_id");
>
> console.log(file_content);
> }
>
> await getFileContent();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> file_content = openai.files.content(file_id="file_id")
>
> print(file_content)
> ```
## Delete File
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> delete_file_response = portkey.files.delete(file_id="file_id")
>
> print(delete_file_response)
> ```
> [tab] NodeJS
>
> ```js theme={"system"}
> import { Portkey } from 'portkey-ai';
>
> // Initialize the Portkey client
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> const deleteFile = async () => {
> const delete_file_response = await portkey.files.delete(file_id="file_id");
>
> console.log(delete_file_response);
> }
>
> await deleteFile();
>
> ```
> [tab] REST
>
> ```sh theme={"system"}
> curl --location --request DELETE 'https://api.portkey.ai/v1/files/' \
> --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider'
> ```
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import OpenAI from 'openai'; // We're using the v4 SDK
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY', // defaults to process.env["OPENAI_API_KEY"],
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY" // defaults to process.env["PORTKEY_API_KEY"]
> })
> });
>
> const deleteFile = async () => {
> const delete_file_response = await openai.files.delete(file_id="file_id");
>
> console.log(delete_file_response);
> }
>
> await deleteFile();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> delete_file_response = openai.files.delete(file_id="file_id")
>
> print(delete_file_response)
> ```
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Fine-tune
Source: https://docs.portkey.ai/docs/integrations/llms/openai/fine-tuning
Fine-tune your models with OpenAI
### Upload a file
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> # Upload a file for fine-tuning
> file = portkey.files.create(
> file=open("dataset.jsonl", "rb"),
> purpose="fine-tune"
> )
>
> print(file)
> ```
> [tab] NodeJS
>
> ```typescript theme={"system"}
> import { Portkey } from "portkey-ai";
> import * as fs from 'fs';
>
> // Initialize the Portkey client
> const portkey = Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> (async () => {
> // Upload a file for fine-tuning
> const file = await portkey.files.create({
> file: fs.createReadStream("dataset.jsonl"),
> purpose: "fine-tune"
> });
>
> console.log(file);
> })();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="@PROVIDER",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> # Upload a file for fine-tuning
> file = openai.files.create(
> file=open("dataset.jsonl", "rb"),
> purpose="fine-tune"
> )
>
> print(file)
> ```
> [tab] OpenAI NodeJS
>
> ```typescript theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
> import * as fs from 'fs';
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY',
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider:"@PROVIDER",
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> (async () => {
> // Upload a file for fine-tuning
> const file = await openai.files.create({
> file: fs.createReadStream("dataset.jsonl"),
> purpose: "fine-tune"
> });
>
> console.log(file);
> })();
> ```
> [tab] REST API
>
> ```sh theme={"system"}
> curl -X POST --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider' \
> --form 'file=@dataset.jsonl' \
> --form 'purpose=fine-tune' \
> 'https://api.portkey.ai/v1/files'
> ```
### Create a fine-tuning job
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> # Create a fine-tuning job
> fine_tune_job = portkey.fine_tuning.jobs.create(
> model="gpt-3.5-turbo", # Base model to fine-tune
> training_file="file_id", # ID of the uploaded training file
> validation_file="file_id", # Optional: ID of the uploaded validation file
> suffix="finetune_name", # Custom suffix for the fine-tuned model name
> hyperparameters={
> "n_epochs": 1
> }
> )
>
> print(fine_tune_job)
> ```
> [tab] NodeJS
>
> ```typescript theme={"system"}
> import { Portkey } from "portkey-ai";
>
> // Initialize the Portkey client
> const portkey = Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> (async () => {
> // Create a fine-tuning job
> const fineTuneJob = await portkey.fineTuning.jobs.create({
> model: "gpt-3.5-turbo", // Base model to fine-tune
> training_file: "file_id", // ID of the uploaded training file
> validation_file: "file_id", // Optional: ID of the uploaded validation file
> suffix: "finetune_name", // Custom suffix for the fine-tuned model name
> hyperparameters: {
> n_epochs: 1
> }
> });
>
> console.log(fineTuneJob);
> })();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="@PROVIDER",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> # Create a fine-tuning job
> fine_tune_job = openai.fine_tuning.jobs.create(
> model="gpt-3.5-turbo", # Base model to fine-tune
> training_file="file_id", # ID of the uploaded training file
> validation_file="file_id", # Optional: ID of the uploaded validation file
> suffix="finetune_name", # Custom suffix for the fine-tuned model name
> hyperparameters={
> "n_epochs": 1
> }
> )
>
> print(fine_tune_job)
> ```
> [tab] OpenAI NodeJS
>
> ```typescript theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY',
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider:"@PROVIDER",
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> (async () => {
> // Create a fine-tuning job
> const fineTuneJob = await openai.fineTuning.jobs.create({
> model: "gpt-3.5-turbo", // Base model to fine-tune
> training_file: "file_id", // ID of the uploaded training file
> validation_file: "file_id", // Optional: ID of the uploaded validation file
> suffix: "finetune_name", // Custom suffix for the fine-tuned model name
> hyperparameters: {
> n_epochs: 1
> }
> });
>
> console.log(fineTuneJob);
> })();
> ```
> [tab] REST API
>
> ```sh theme={"system"}
> curl -X POST --header 'Content-Type: application/json' \
> --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider' \
> --data \
> $'{"model": "", "suffix": "", "training_file": "", "validation_file": "", "method": {"type": "supervised", "supervised": {"hyperparameters": {"n_epochs": 1}}}}\n' \
> 'https://api.portkey.ai/v1/fine_tuning/jobs'
> ```
### List fine-tuning jobs
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> # List all fine-tuning jobs
> jobs = portkey.fine_tuning.jobs.list(
> limit=10 # Optional: Number of jobs to retrieve (default: 20)
> )
>
> print(jobs)
> ```
> [tab] NodeJS
>
> ```typescript theme={"system"}
> import { Portkey } from "portkey-ai";
>
> // Initialize the Portkey client
> const portkey = Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> (async () => {
> // List all fine-tuning jobs
> const jobs = await portkey.fineTuning.jobs.list({
> limit: 10 // Optional: Number of jobs to retrieve (default: 20)
> });
>
> console.log(jobs);
> })();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="@PROVIDER",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> # List all fine-tuning jobs
> jobs = openai.fine_tuning.jobs.list(
> limit=10 # Optional: Number of jobs to retrieve (default: 20)
> )
>
> print(jobs)
> ```
> [tab] OpenAI NodeJS
>
> ```typescript theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY',
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider:"@PROVIDER",
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> (async () => {
> // List all fine-tuning jobs
> const jobs = await openai.fineTuning.jobs.list({
> limit: 10 // Optional: Number of jobs to retrieve (default: 20)
> });
>
> console.log(jobs);
> })();
> ```
> [tab] REST API
>
> ```sh theme={"system"}
> curl -X GET --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider' \
> 'https://api.portkey.ai/v1/fine_tuning/jobs'
> ```
### Get a fine-tuning job
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> # Retrieve a specific fine-tuning job
> job = portkey.fine_tuning.jobs.retrieve(
> "job_id" # The ID of the fine-tuning job to retrieve
> )
>
> print(job)
> ```
> [tab] NodeJS
>
> ```typescript theme={"system"}
> import { Portkey } from "portkey-ai";
>
> // Initialize the Portkey client
> const portkey = Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> (async () => {
> // Retrieve a specific fine-tuning job
> const job = await portkey.fineTuning.jobs.retrieve(
> "job_id" // The ID of the fine-tuning job to retrieve
> );
>
> console.log(job);
> })();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="@PROVIDER",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> # Retrieve a specific fine-tuning job
> job = openai.fine_tuning.jobs.retrieve(
> fine_tuning_job_id="job_id" # The ID of the fine-tuning job to retrieve
> )
>
> print(job)
> ```
> [tab] OpenAI NodeJS
>
> ```typescript theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY',
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider:"@PROVIDER",
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> (async () => {
> // Retrieve a specific fine-tuning job
> const job = await openai.fineTuning.jobs.retrieve(
> "job_id" // The ID of the fine-tuning job to retrieve
> );
>
> console.log(job);
> })();
> ```
> [tab] REST API
>
> ```sh theme={"system"}
> curl -X GET --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider' \
> 'https://api.portkey.ai/v1/fine_tuning/jobs/'
> ```
### Cancel a fine-tuning job
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> # Initialize the Portkey client
> portkey = Portkey(
> api_key="PORTKEY_API_KEY", # Replace with your Portkey API key
> provider="@PROVIDER"
> )
>
> # Cancel a fine-tuning job
> cancelled_job = portkey.fine_tuning.jobs.cancel(
> "job_id" # The ID of the fine-tuning job to cancel
> )
>
> print(cancelled_job)
> ```
> [tab] NodeJS
>
> ```typescript theme={"system"}
> import { Portkey } from "portkey-ai";
>
> // Initialize the Portkey client
> const portkey = Portkey({
> apiKey: "PORTKEY_API_KEY", // Replace with your Portkey API key
> provider:"@PROVIDER"
> });
>
> (async () => {
> // Cancel a fine-tuning job
> const cancelledJob = await portkey.fineTuning.jobs.cancel(
> "job_id" // The ID of the fine-tuning job to cancel
> );
>
> console.log(cancelledJob);
> })();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
>
> openai = OpenAI(
> api_key='OPENAI_API_KEY',
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="@PROVIDER",
> api_key="PORTKEY_API_KEY"
> )
> )
>
> # Cancel a fine-tuning job
> cancelled_job = openai.fine_tuning.jobs.cancel(
> "job_id" # The ID of the fine-tuning job to cancel
> )
>
> print(cancelled_job)
> ```
> [tab] OpenAI NodeJS
>
> ```typescript theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai';
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY',
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider:"@PROVIDER",
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> (async () => {
> // Cancel a fine-tuning job
> const cancelledJob = await openai.fineTuning.jobs.cancel(
> "job_id" // The ID of the fine-tuning job to cancel
> );
>
> console.log(cancelledJob);
> })();
> ```
> [tab] REST API
>
> ```sh theme={"system"}
> curl -X POST --header 'x-portkey-api-key: ' \
> --header 'x-portkey-provider: @provider' \
> 'https://api.portkey.ai/v1/fine_tuning/jobs//cancel'
> ```
Refer to [OpenAI's fine-tuning documentation](https://platform.openai.com/docs/api-reference/fine-tuning) for more information on the parameters and options available.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Caching
Source: https://docs.portkey.ai/docs/integrations/llms/openai/prompt-caching-openai
OpenAI now offers prompt caching, a feature that can significantly reduce both latency and costs for your API requests. This feature is particularly beneficial for prompts exceeding 1024 tokens, offering up to an 80% reduction in latency for longer prompts over 10,000 tokens.
**Prompt Caching is enabled for following models**
* `gpt-4o (excludes gpt-4o-2024-05-13)`
* `gpt-4o-mini`
* `o1-preview`
* `o1-mini`
Portkey supports OpenAI's prompt caching feature out of the box. Here is an examples on of how to use it:
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@OPENAI_PROVIDER",
> )
>
> # Define tools (for function calling example)
> tools = [
> {
> "type": "function",
> "function": {
> "name": "get_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA",
> },
> "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
> },
> "required": ["location"],
> },
> }
> }
> ]
>
>
> # Example: Function calling with caching
> response = portkey.chat.completions.create(
> model="gpt-4",
> messages=[
> {"role": "system", "content": "You are a helpful assistant that can check the weather."},
> {"role": "user", "content": "What's the weather like in San Francisco?"}
> ],
> tools=tools,
> tool_choice="auto"
> )
> print(json.dumps(response.model_dump(), indent=2))
> ```
> [tab] NodeJs
>
> ```javascript theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY", // defaults to process.env["PORTKEY_API_KEY"]
> provider:"@PROVIDER" // Your OpenAI Provider Slug
> })
>
> // Define tools (for function calling example)
> const tools = [
> {
> "type": "function",
> "function": {
> "name": "get_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA",
> },
> "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
> },
> "required": ["location"],
> },
> }
> }
> ];
>
> async function Examples() {
>
> // Example : Function calling with caching
> completion = await openai.chat.completions.create({
> messages: [
> {"role": "system", "content": "You are a helpful assistant that can check the weather."},
> {"role": "user", "content": "What's the weather like in San Francisco?"}
> ],
> model: "gpt-4",
> tools: tools,
> tool_choice: "auto"
> });
> console.log(JSON.stringify(completion, null, 2));
> }
>
> Examples();
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
> import os
> import json
>
> client = OpenAI(
> api_key=os.environ.get("OPENAI_API_KEY"),
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> provider="openai",
> api_key=os.environ.get("PORTKEY_API_KEY")
> )
> )
>
> # Define tools (for function calling example)
> tools = [
> {
> "type": "function",
> "function": {
> "name": "get_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA",
> },
> "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
> },
> "required": ["location"],
> },
> }
> }
> ]
>
>
> # Example: Function calling with caching
> response = client.chat.completions.create(
> model="gpt-4",
> messages=[
> {"role": "system", "content": "You are a helpful assistant that can check the weather."},
> {"role": "user", "content": "What's the weather like in San Francisco?"}
> ],
> tools=tools,
> tool_choice="auto"
> )
> print(json.dumps(response.model_dump(), indent=2))
> ```
> [tab] OpenAI NodeJS
>
> ```javascript theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: "OPENAI_API_KEY",
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> provider: "openai",
> apiKey: "PORTKEY_API_KEY"
> })
> });
>
> // Define tools (for function calling example)
> const tools = [
> {
> "type": "function",
> "function": {
> "name": "get_weather",
> "description": "Get the current weather in a given location",
> "parameters": {
> "type": "object",
> "properties": {
> "location": {
> "type": "string",
> "description": "The city and state, e.g. San Francisco, CA",
> },
> "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
> },
> "required": ["location"],
> },
> }
> }
> ];
>
> async function Examples() {
>
> // Example : Function calling with caching
> completion = await openai.chat.completions.create({
> messages: [
> {"role": "system", "content": "You are a helpful assistant that can check the weather."},
> {"role": "user", "content": "What's the weather like in San Francisco?"}
> ],
> model: "gpt-4",
> tools: tools,
> tool_choice: "auto"
> });
> console.log(JSON.stringify(completion, null, 2));
> }
>
> Examples();
> ```
### What can be cached
* **Messages:** The complete messages array, encompassing system, user, and assistant interactions.
* **Images:** Images included in user messages, either as links or as base64-encoded data, as well as multiple images can be sent. Ensure the detail parameter is set identically, as it impacts image tokenization.
* **Tool use:** Both the messages array and the list of available `tools` can be cached, contributing to the minimum 1024 token requirement.
* **Structured outputs:** The structured output schema serves as a prefix to the system message and can be cached.
### What's Not Supported
* Completions API (only Chat Completions API is supported)
* Streaming responses (caching works, but streaming itself is not affected)
### Monitoring Cache Performance
Prompt caching requests & responses based on OpenAI's calculations here:

All requests, including those with fewer than 1024 tokens, will display a `cached_tokens` field of the `usage.prompt_tokens_details` [chat completions object](https://platform.openai.com/docs/api-reference/chat/object) indicating how many of the prompt tokens were a cache hit.
For requests under 1024 tokens, `cached_tokens` will be zero.

`cached_tokens` field of the `usage.prompt_tokens_details`
**Key Features:**
* Reduced Latency: Especially significant for longer prompts.
* Lower Costs: Cached portions of prompts are billed at a discounted rate.
* Improved Efficiency: Allows for more context in prompts without increasing costs proportionally.
* Zero Data Retention: No data is stored during the caching process, making it eligible for zero data retention policies.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Remote MCP Support
Source: https://docs.portkey.ai/docs/integrations/llms/openai/remote-mcp
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Structured Outputs
Source: https://docs.portkey.ai/docs/integrations/llms/openai/structured-outputs
Structured Outputs ensure that the model always follows your supplied [JSON schema](https://json-schema.org/overview/what-is-jsonschema). Portkey supports OpenAI's Structured Outputs feature out of the box with our SDKs & APIs.
> [!NOTE]
>
> Structured Outputs is different from OpenAI's `JSON Mode` as well as `Function Calling`. [Check out this table](#difference-between-structured-outputs-json-mode-and-function-calling) for a quick comparison.
Portkey SDKs for [Python](https://github.com/openai/openai-python/blob/main/helpers.md#structured-outputs-parsing-helpers) and [JavaScript](https://github.com/openai/openai-node/blob/master/helpers.md#structured-outputs-parsing-helpers) also make it easy to define object schemas using [Pydantic](https://docs.pydantic.dev/latest/) and [Zod](https://zod.dev/) respectively. Below, you can see how to extract information from unstructured text that conforms to a schema defined in code.
> [tab] Pydantic with Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
> from pydantic import BaseModel
>
> class Step(BaseModel):
> explanation: str
> output: str
>
> class MathReasoning(BaseModel):
> steps: list[Step]
> final_answer: str
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@OPENAI_PROVIDER"
> )
>
> completion = portkey.chat.completions.parse(
> model="gpt-4o-2024-08-06",
> messages=[
> {"role": "system", "content": "You are a helpful math tutor. Guide the user through the solution step by step."},
> {"role": "user", "content": "how can I solve 8x + 7 = -23"}
> ],
> response_format=MathReasoning,
> )
>
> print(completion.choices[0].message)
> print(completion.choices[0].message.parsed)
> ```
> [tab] Zod with NodeJS
>
> ```typescript theme={"system"}
> import { Portkey } from 'portkey-ai';
> import { z } from 'zod';
> import { zodResponseFormat } from "openai/helpers/zod";
>
> const MathReasoning = z.object({
> steps: z.array(z.object({ explanation: z.string(), output: z.string() })),
> final_answer: z.string()
> });
>
> const portkey = new Portkey({
> apiKey: "YOUR_API_KEY",
> provider:"@YOUR_PROVIDER"
> });
>
> async function runMathTutor() {
> try {
> const completion = await portkey.chat.completions.create({
> model: "gpt-4o-2024-08-06",
> messages: [
> { role: "system", content: "You are a helpful math tutor." },
> { role: "user", content: "Solve 8x + 7 = -23" }
> ],
> response_format: zodResponseFormat(MathReasoning, "MathReasoning")
> });
>
> console.log(completion.choices[0].message.content);
> } catch (error) {
> console.error("Error:", error);
> }
> }
>
> runMathTutor();
> ```
The second approach, shown in the subsequent examples, uses a JSON schema directly in the API call. This method is more portable across different languages and doesn't require additional libraries, but lacks the integrated type checking of the Pydantic/Zod approach. Choose the method that best fits your project's needs and language ecosystem.
> [tab] NodeJS
>
> ```typescript theme={"system"}
> import Portkey from "portkey-ai";
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> provider:"@OPENAI_PROVIDER",
> });
>
> async function main() {
> const completion = await portkey.chat.completions.create({
> model: "gpt-4o-2024-08-06",
> messages: [
> { role: "system", content: "Extract the event information." },
> {
> role: "user",
> content: "Alice and Bob are going to a science fair on Friday.",
> },
> ],
> response_format: {
> type: "json_schema",
> json_schema: {
> name: "math_reasoning",
> schema: {
> type: "object",
> properties: {
> steps: {
> type: "array",
> items: {
> type: "object",
> properties: {
> explanation: { type: "string" },
> output: { type: "string" },
> },
> required: ["explanation", "output"],
> additionalProperties: false,
> },
> },
> final_answer: { type: "string" },
> },
> required: ["steps", "final_answer"],
> additionalProperties: false,
> },
> strict: true,
> },
> },
> });
> const event = completion.choices[0].message?.content;
> console.log(event);
> }
>
> main();
> ```
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> provider="@OPENAI_PROVIDER"
> )
>
> completion = portkey.chat.completions.create(
> model="gpt-4o-2024-08-06",
> messages=[
> {"role": "system", "content": "Extract the event information."},
> {"role": "user", "content": "A meteor the size of 1000 football stadiums will hit earth this Sunday"},
> ],
> response_format={
> "type": "json_schema",
> "json_schema": {
> "name": "math_reasoning",
> "schema": {
> "type": "object",
> "properties": {
> "steps": {
> "type": "array",
> "items": {
> "type": "object",
> "properties": {
> "explanation": { "type": "string" },
> "output": { "type": "string" }
> },
> "required": ["explanation", "output"],
> "additionalProperties": False
> }
> },
> "final_answer": { "type": "string" }
> },
> "required": ["steps", "final_answer"],
> "additionalProperties": False
> },
> "strict": True
> }
> },
> )
>
> print(completion.choices[0].message.content)
> ```
> [tab] cURL
>
> ```sh theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-provider: $OPENAI_PROVIDER" \
> -H "Content-Type: application/json" \
> -d '{
> "model": "gpt-4o-2024-08-06",
> "messages": [
> {
> "role": "system",
> "content": "You are a helpful math tutor. Guide the user through the solution step by step."
> },
> {
> "role": "user",
> "content": "how can I solve 8x + 7 = -23"
> }
> ],
> "response_format": {
> "type": "json_schema",
> "json_schema": {
> "name": "math_reasoning",
> "schema": {
> "type": "object",
> "properties": {
> "steps": {
> "type": "array",
> "items": {
> "type": "object",
> "properties": {
> "explanation": { "type": "string" },
> "output": { "type": "string" }
> },
> "required": ["explanation", "output"],
> "additionalProperties": false
> }
> },
> "final_answer": { "type": "string" }
> },
> "required": ["steps", "final_answer"],
> "additionalProperties": false
> },
> "strict": true
> }
> }
> }'
> ```
## Difference Between Structured Outputs, JSON Mode, and Function Calling
* If you are connecting the model to tools, functions, data, etc. in your system, then you should use **function calling.**
* And if you want to structure the model's output when it responds to the user, then you should use a structured `response_format`.
* In `response_format`, you can set it as `{ "type": "json_object" }` to enable the [JSON Mode](https://platform.openai.com/docs/guides/structured-outputs/json-mode).
* And you can set it as `{ "type": "json_schema" }` to use the [Structured Outputs Mode described above](https://platform.openai.com/docs/guides/structured-outputs).
For more, refer to OpenAI's [detailed documentation on Structured Outputs here](https://platform.openai.com/docs/guides/structured-outputs/supported-schemas).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Submit an Integration
Source: https://docs.portkey.ai/docs/integrations/partner
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Analytics Access Permissions for Workspaces
Source: https://docs.portkey.ai/docs/product/administration/configure-analytics-access-permissions
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
Analytics Management in Portkey enables Organization administrators to control who can view analytics within workspaces. This feature provides granular permissions to restrict analytics visibility for workspace managers and members while keeping full access for organization owners and admins.
## Accessing Analytics Management
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Analytics Management** section
## Permission Settings
The Analytics Management section provides two permission options:
| Permission | Description |
| - | - |
| **Managers View Analytics** | Allow workspace managers to view analytics within their workspace |
| **Members View Analytics** | Allow workspace members to view analytics within their workspace |
Both permissions are **enabled by default**.
> [!NOTE]
>
> Organization **Owners** and **Admins** always have full access to analytics regardless of these settings.
## Workspace-Level Overrides
Analytics access permissions support **workspace-level overrides**, allowing you to configure different analytics access settings per workspace.
When workspace-level overrides are enabled for analytics:
* Each workspace can have its own `membersViewAnalytics` and `managersViewAnalytics` settings
* Workspace settings take precedence over organization-level settings
To configure workspace-level overrides:
1. Enable the **Allow workspace-level configuration** toggle for Analytics in the Security settings
2. Navigate to the specific workspace settings to configure per-workspace analytics access
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
> [card] [Logs Access Permissions](/docs/product/administration/configure-logs-access-permissions-in-workspace)
>
> Configure who can view logs and log metadata within workspaces
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure API Key Access Permissions for Workspaces
Source: https://docs.portkey.ai/docs/product/administration/configure-api-key-access-permissions
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
API Key Management in Portkey enables Organization administrators to control how workspace managers and members interact with API keys within their workspaces. This feature offers granular control over who can view and manage different types of API keys, providing enhanced security and appropriate access levels across your organization.
## Accessing API Key Management Permissions
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **API Key Management** section
## Permission Settings
The API Key Management section provides four distinct permission options:
| Permission | Description |
| - | - |
| **View Keys (Workspace Managers)** | Enable workspace managers to view both user API keys and service API keys within their workspace. Keys are limited to those created by workspace administrators. |
| **Manage Keys (Workspace Managers)** | Allow workspace managers to create, update, and delete both user API keys and service API keys within their workspace. Managers can also create API keys on behalf of other users by specifying a `user_id`. |
| **View Keys (Workspace Members)** | Enable workspace members to view user API keys only. Members can only see keys created for them by workspace managers or administrators. |
| **Manage Keys (Workspace Members)** | Allow workspace members to create, update, and delete user API keys only. Members can only manage keys created for them by workspace managers or administrators. |

API Key Management settings
## Understanding API Key Types
**Note**: Service API keys provide system-level access and are distinct from user API keys which grant individual user access.
* **Service API Keys**: Used for automated processes, integrations, and system-level operations. These keys typically have broader permissions and are not tied to individual users.
* **User API Keys**: Associated with specific users and provide individualized access to Portkey resources. These keys are generally more limited in scope and tied to the permissions of the specific user.
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's comprehensive access control features including user roles and organization hierarchy
> [card] [API Keys (AuthN and AuthZ)](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
>
> Understand the difference between Admin and Workspace API Keys in Portkey
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Data Visibility Settings for Workspaces
Source: https://docs.portkey.ai/docs/product/administration/configure-data-visibility-settings
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
> [!NOTE]
>
> **Prerequisites & Availability**
>
> * **Enterprise (Hybrid Gateway)**: Gateway **v2.2.4** or later is required. Only logs generated from this version onward will be considered for user-level filtering.
> * **Airgapped Deployments**: Requires Gateway **v2.2.4**, backend **v1.11.0**, and frontend **v1.6.4** or later. Only logs generated after upgrading to these versions will be considered for user-level filtering.
> * **SaaS Users**: This setting will be applied to logs starting from **19th February 2026**.
## Overview
Data Visibility settings in Portkey enable Organization administrators to control whether workspace managers and members can view all observability data (logs, analytics, and traces) within a workspace, or only the data generated by their own API keys. This is useful for teams where individual users should only have visibility into their own requests.
## Accessing Data Visibility Settings
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Data Visibility** section
## Permission Settings
The Data Visibility section provides two permission options:
| Permission | Description |
| - | - |
| **Managers View All Data** | Allow workspace managers to view logs, analytics, and traces generated by all users in the workspace |
| **Members View All Data** | Allow workspace members to view logs, analytics, and traces generated by all users in the workspace |
Both permissions are **enabled by default**, meaning all workspace users can see all data.
When a permission is **disabled**, users with that role will only see data generated by their own API keys across logs, analytics, and traces pages.
> [!NOTE]
>
> Organization **Owners** and **Admins** always have full access to all data regardless of these settings.
## How It Works
When data visibility is restricted for a role:
* **Logs**: The user only sees log entries for requests made with their own API keys
* **Analytics**: Charts and metrics are scoped to the user's own usage
* **Traces**: Only traces initiated by the user's API keys are visible
This restriction applies to both browser sessions and workspace-user API keys. Organization-level and workspace-level service API keys are not affected.
* **Workspace-User API Keys**: When a workspace-user API key is used to fetch analytics or export logs via the API, the same data visibility settings are applied based on the role of the user the key is scoped to.
* **Service API Keys**: Organization-level and workspace-level service API keys bypass data visibility restrictions entirely and always return all data.
* **Visibility of Service API Key Logs**: Logs generated by service API keys are not attributed to a specific user. If data visibility is restricted for a role, users with that role will not be able to see any logs generated by service API keys.
## Limitations
* **[JWT Authentication](/docs/product/enterprise-offering/org-management/jwt)**: Requests made using JWT auth are not attributed to a specific Portkey user, so they cannot be filtered by user. If data visibility restrictions are enabled, logs originating from JWT-authenticated requests will not appear for restricted users.
## Workspace-Level Overrides
Data Visibility settings support **workspace-level overrides**, allowing you to configure different data visibility rules per workspace.
When workspace-level overrides are enabled for Data Visibility:
* Each workspace can have its own `membersViewAllData` and `managersViewAllData` settings
* Workspace settings take precedence over organization-level settings
* Workspaces without explicit overrides fall back to the organization-level settings
To configure workspace-level overrides:
1. Enable the **Allow workspace-level configuration** toggle for Data Visibility in the Security settings
2. Navigate to the specific workspace settings to configure per-workspace data visibility
## Related Features
> [card] [Logs Access Permissions](/docs/product/administration/configure-logs-access-permissions-in-workspace)
>
> Configure who can view logs and log metadata within workspaces
> [card] [Analytics Access Permissions](/docs/product/administration/configure-analytics-access-permissions)
>
> Configure who can view analytics within workspaces
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Guardrail Access Permissions for Workspaces
Source: https://docs.portkey.ai/docs/product/administration/configure-guardrail-access-permissions
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
Guardrail Management in Portkey enables organization administrators to control who can view and manage guardrails within workspaces. This helps teams enforce governance while ensuring members only get the level of guardrail access they need.
## Accessing Guardrail Management
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Guardrail Management** section
## Permission Settings
The Guardrail Management section provides three permission options:
| Permission | Description |
| - | - |
| **Managers View Guardrails** | Allow workspace managers to view guardrails within their workspace |
| **Managers Write Guardrails** | Allow workspace managers to create, update, and delete guardrails within their workspace |
| **Members View Guardrails** | Allow workspace members to view guardrails within their workspace |
**Default settings:**
* Managers can view and write guardrails
* Members can view guardrails
* Members do not get a Manage Guardrails toggle (shown as N/A in the UI)

Guardrail Management settings
## Workspace-Level Overrides
Guardrail access permissions support **workspace-level overrides**, allowing you to configure different guardrail access settings per workspace.
When workspace-level overrides are enabled for guardrails:
* Each workspace can have its own `membersViewGuardrails`, `managersViewGuardrails`, and `managersWriteGuardrails` settings
* Workspace settings take precedence over organization-level settings and inherit organization settings by default
To configure workspace-level overrides:
1. Enable the **Allow workspace-level configuration** toggle in the Guardrail Management section under organization Security settings
2. Navigate to the specific workspace settings to configure per-workspace guardrail access
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
> [card] [Prompt Access Permissions](/docs/product/administration/configure-prompt-access-permissions)
>
> Configure who can view and manage prompts within workspaces
> [card] [Enforcing Org Level Guardrails](/docs/product/administration/enforce-orgnization-level-guardrails)
>
> Learn how to enforce organization-level request guardrails across all workspaces
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Integration Access Permissions for Workspaces
Source: https://docs.portkey.ai/docs/product/administration/configure-integration-access-permissions
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
Integration Access Management in Portkey enables Organization administrators to control whether workspace managers can create, update, and delete integrations, MCP integrations, and MCP servers within their workspaces. Organization owners and admins always retain full access.
## Accessing Integration Management
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Integration Management** section
## Permission Settings
The Integration Management section provides three permission options:
| Permission | Description |
| - | - |
| **Managers Write Workspace Integrations** | Allow workspace managers to create, update, and delete AI integrations within their workspace |
| **Managers Write MCP Integrations** | Allow workspace managers to create, update, and delete MCP integrations within their workspace |
| **Managers Write MCP Servers** | Allow workspace managers to create, update, and delete MCP servers within their workspace |
All permissions are **enabled by default**.
> [!NOTE]
>
> Organization **Owners** and **Admins** always have full access to integrations regardless of these settings.
## Workspace-Level Overrides
Integration access permissions support **workspace-level overrides**, allowing you to configure different settings per workspace.
When workspace-level overrides are enabled:
* Each workspace can have its own `managersWriteWsIntegrations`, `managersWriteWsMcpIntegrations`, and `managersWriteMcpServers` settings
* Workspace settings take precedence over organization-level settings
To configure workspace-level overrides:
1. Enable the **Allow workspace-level configuration** toggle for the relevant integration type in the Security settings
2. Navigate to the specific workspace settings to configure per-workspace access
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
> [card] [Prompt Access Permissions](/docs/product/administration/configure-prompt-access-permissions)
>
> Configure who can view and edit prompts within workspaces
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Logs Access Permissions for Workspace
Source: https://docs.portkey.ai/docs/product/administration/configure-logs-access-permissions-in-workspace
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
Logs Management in Portkey enables organization and workspace administrators to control who can access logs and log metadata within workspaces. This feature provides granular permissions for workspace managers, workspace members, and organization admins while protecting sensitive information.
## Accessing Logs Management
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Logs Management** section
## Permission Settings
The Logs Management section provides six distinct permission options:
| Permission | Description |
| - | - |
| **Managers View Logs** | Allow workspace managers to view logs within their workspace |
| **Managers View Logs Metadata** | Allow workspace managers to view logs metadata within their workspace |
| **Members View Logs** | Allow workspace members to view logs within their workspace |
| **Members View Logs Metadata** | Allow workspace members to view logs metadata within their workspace |
| **Org-Admin View Logs** | Allow organization admins to view logs within workspaces |
| **Org-Admin View Logs Metadata** | Allow organization admins to view logs metadata within workspaces |
**Default settings:**
* Managers can view logs and log metadata
* Members can view logs and log metadata
* Organization admins can view logs and log metadata

Logs Management settings
## Logs vs. Logs Metadata
* **Logs**: Complete log entries including request and response payloads
* **Logs Metadata**: Information such as timestamps, model used, tokens consumed, and other metrics without the actual content
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
> [card] [Logs Export](/docs/product/observability/logs-export)
>
> Export logs for longer-term storage or analysis
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Model Access Permissioning for AI Integrations
Source: https://docs.portkey.ai/docs/product/administration/configure-model-access-permissioning-for-ai-integratinon
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Prompt Access Permissions for Workspaces
Source: https://docs.portkey.ai/docs/product/administration/configure-prompt-access-permissions
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
Prompt Management in Portkey enables Organization administrators to control who can view and edit prompts within workspaces. This feature provides granular permissions to restrict prompt access for workspace managers and members while keeping full access for organization owners and admins.
## Accessing Prompt Management
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Prompt Management** section
## Permission Settings
The Prompt Management section provides four permission options:
| Permission | Description |
| - | - |
| **Managers View Prompts** | Allow workspace managers to view prompts within their workspace |
| **Managers Write Prompts** | Allow workspace managers to create, update, and delete prompts within their workspace |
| **Members View Prompts** | Allow workspace members to view prompts within their workspace |
| **Members Write Prompts** | Allow workspace members to create, update, and delete prompts within their workspace |
**Default settings:**
* Managers can view and write prompts
* Members can view prompts but cannot write
> [!NOTE]
>
> Organization **Owners** and **Admins** always have full access to prompts regardless of these settings.
## Workspace-Level Overrides
Prompt access permissions support **workspace-level overrides**, allowing you to configure different prompt access settings per workspace.
When workspace-level overrides are enabled for prompts:
* Each workspace can have its own `membersViewPrompts`, `membersWritePrompts`, `managersViewPrompts`, and `managersWritePrompts` settings
* Workspace settings take precedence over organization-level settings
To configure workspace-level overrides:
1. Enable the **Allow workspace-level configuration** toggle for Prompts in the Security settings
2. Navigate to the specific workspace settings to configure per-workspace prompt access
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
> [card] [Logs Access Permissions](/docs/product/administration/configure-logs-access-permissions-in-workspace)
>
> Configure who can view logs and log metadata within workspaces
> [card] [Analytics Access Permissions](/docs/product/administration/configure-analytics-access-permissions)
>
> Configure who can view analytics within workspaces
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Provider Access Permissions
Source: https://docs.portkey.ai/docs/product/administration/configure-virtual-key-access-permissions
> [!TIP]
>
> This is a Portkey [Enterprise](/docs/product/enterprise-offering) plan feature.
## Overview
Provider Management in Portkey allows Organization administrators to define who can view and manage providers within workspaces. This feature provides granular control over access to providers, which are critical for managing connections to external AI services.
## Accessing Provider Management Permissions
1. Navigate to **Admin Settings** in the Portkey dashboard
2. Select the **Security** tab from the left sidebar
3. Locate the **Provider Management** section
## Permission Settings
The Provider Management section includes a toggle for **Allow workspace-level configuration** and provides granular permission controls for different user roles:
| Permission | Description | Managers | Members |
| - | - | - | - |
| **View Providers** | View all providers within their workspace. | Yes | Yes |
| **Manage Providers** | Create, update, and delete providers within their workspace. | Yes | N/A |
> [!NOTE]
>
> Members cannot create, modify, or delete providers by default. Only Managers have access to manage providers.

Provider Management settings in Admin Settings > Security
## Understanding Providers in Model Catalog
Providers in Portkey's [Model Catalog](/docs/product/model-catalog) securely store your API credentials and enable:
* Centralized management of AI provider credentials
* Abstraction of actual API keys from end users
* Definition of routing rules, fallbacks, and other advanced features
* Application of usage limits and tracking across providers
By controlling who can view and manage providers, organizations can maintain security while enabling appropriate access for different team roles.
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Learn about Portkey's access control features including user roles and organization hierarchy
> [card] [Model Catalog](/docs/product/model-catalog)
>
> Understand how to add and manage providers in the Model Catalog
> [card] [Budget Limits](/docs/product/model-catalog/integrations#3-budget-%26-rate-limits)
>
> Learn how to set budget limits on providers to control spending
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Workspace Provisioning for Your AI Integrations
Source: https://docs.portkey.ai/docs/product/administration/configure-workspace-provisioning-for-your-ai-integrations
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Configure Request Logging
Source: https://docs.portkey.ai/docs/product/administration/configuring-request-logging
Control what data is stored for all LLM requests in your organization
> [!TIP]
>
> This is a Portkey [**Enterprise**](https://portkey.ai/docs/product/enterprise-offering) plan feature.
## Overview
Portkey allows organization owners to control what data is logged for all LLM requests across their organization. This feature provides flexibility between complete observability and privacy compliance, enabling organizations to choose the appropriate logging level based on their security and compliance requirements.
## How It Works
Organization owners can configure two aspects of request logging:
1. **Logging Mode**: Choose between Full Logging or Metrics Only mode
2. **Workspace Override**: Allow or restrict workspace managers from changing the organization-level logging settings
These settings apply to all requests made within the organization, ensuring consistent data handling practices across all teams and projects.
## Configuration
### Setting Up Request Logging
1. Navigate to `Admin Settings` in the Portkey dashboard
2. Go to the `Organization Properties` section
3. Find the `Request Logging` settings
4. Configure your logging preferences
5. Save your changes

### Logging Modes
#### Full Logging
When enabled, Portkey stores:
* Complete request payloads
* Full response content
* All associated metrics and metadata
This mode provides comprehensive observability for debugging, monitoring, and optimization purposes.
#### Metrics Only (Privacy Mode)
When enabled, Portkey only tracks:
* Usage statistics (tokens, latency, costs)
* Request metadata
* Error information (without sensitive content)
This mode ensures privacy compliance by not storing any request or response content, while still maintaining essential operational metrics.
### Workspace-Level Control
The **"Allow respective workspace managers to toggle Request Logging"** option determines whether workspace managers can override the organization-level settings:
* **When enabled**: Workspace managers can change logging settings for their specific workspace
* **When disabled**: All workspaces inherit and must use the organization-level logging settings
> [!NOTE]
>
> When workspace-level control is disabled, any existing workspace-specific logging settings will be overridden by the organization settings.
## Workspace Configuration
If workspace-level control is enabled, workspace managers can configure logging for their workspace:
1. Navigate to the workspace settings
2. Click on your workspace and select the **Edit (🖊️) option**
3. In the **Edit Workspace** menu, head over to Workspace Properties
4. Configure the **Request Logging** setting
5. Save your changes
> [!WARNING]
>
> Changing from Full Logging to Metrics Only will not retroactively remove previously logged data. [Contact support](https://support.portkey.ai/forms/customer-portal-ticket-form) if you need to purge historical logs.
## Precedence Order
When different logging settings exist at multiple levels:
1. **Workspace settings** (highest priority) - if workspace-level control is enabled
2. **Organization settings** (applies when workspace control is disabled)
## Support
For questions about configuring request logging or assistance with compliance requirements, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforce Budget Limits and Rate Limits for Your API Keys
Source: https://docs.portkey.ai/docs/product/administration/enforce-budget-and-rate-limit
Configure budget and rate limits on API keys to effectively manage AI spending and usage across your organization
> [!NOTE]
>
> Available on **Enterprise** plan and select **Pro** customers.
> [!TIP]
>
> Looking to set limits for an entire workspace instead of individual API keys? See [Enforce Workspace Budget and Rate Limits](/docs/product/administration/enforce-workspace-budget-limts-and-rate-limits).
## Overview
For enterprises deploying AI at scale, maintaining financial oversight and operational control is crucial. Portkey's governance features for API keys provide finance teams, IT departments, and executives with the transparency and guardrails needed to confidently scale AI adoption across the organization.
By implementing budget and rate limits on API keys at both organization and workspace levels, you can:
* Prevent unexpected cost overruns through automated spending caps
* Maintain performance and availability through usage rate controls
* Receive timely notifications when thresholds are approached
* Enforce consistent governance policies across teams and departments
These capabilities ensure your organization can innovate with AI while maintaining predictable costs and usage patterns.
## Budget Limits
Budget limits allow you to set maximum LLM spending or token usage thresholds on your API keys, automatically preventing further usage when limits are reached.
When creating or editing an API key, you can establish spending parameters that align with your financial planning:
### Setting Up Budget Limits
When creating a new API key or editing an existing one:
1. Toggle on **Add Budget Limit**
2. Choose between two limit types:
* **Cost**: Set a maximum spend in USD (minimum \$1)
* **Tokens**: Set a maximum token usage

Budget limit configuration
### Alert Thresholds
You can configure alert thresholds to receive notifications before reaching your full budget:
1. Enter a value in the **Alert Threshold** field
2. When usage reaches this threshold, notifications will be sent to configured recipients
3. The API key continues to function until the full budget limit is reached
### Periodic Reset Options
Budget limits can be set to automatically reset at regular intervals:

Periodic reset options
* **No Periodic Reset**: The budget limit applies until exhausted
* **Reset Weekly**: Budget limits reset every Sunday at 12 AM UTC
* **Reset Monthly**: Budget limits reset on the 1st of each month at 12 AM UTC
## Rate Limits
Rate limits control how frequently an API key can be used, helping you maintain application performance and prevent unexpected usage spikes.
### Setting Up Rate Limits
When creating a new API key or editing an existing one:
1. Toggle on **Add Rate Limit**
2. Choose your limit type:
* **Requests**: Limit based on number of API calls
* **Tokens**: Limit based on token consumption
3. Specify the limit value and time interval

Rate limit configuration
### Time Intervals
Rate limits can be applied using three different time intervals:
* **Per Minute**: For granular control of high-frequency applications
* **Per Hour**: For balanced control of moderate usage
* **Per Day**: For broader usage management
When a rate limit is reached, subsequent requests are rejected until the time interval resets.
## Email Notifications
Email notifications keep relevant stakeholders informed about API key usage and when limits are approached or reached.
### Configuring Notifications
To set up email notifications for an API key with budget limits:
1. Toggle on **Email Notifications** when creating/editing an API key
2. Add recipient email addresses:
* Type an email address and click **New** or press Enter
* Add multiple recipients as needed

Email notification setup
### Default Recipients
When limits are reached or thresholds are crossed, Portkey automatically sends notifications to:
* Organization administrators
* Organization owners
* The API key creator/owner
You can add additional recipients such as finance team members, department heads, or project managers who need visibility into AI usage.
## Availability
These features are available to Portkey Enterprise customers and select Pro users. To enable these features for your account, please contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
To learn more about the Portkey Enterprise plan, [schedule a consultation](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforce Budget Limits on Your AI Provider
Source: https://docs.portkey.ai/docs/product/administration/enforce-budget-limits-on-your-ai-provider
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforcing Default Configs on API Keys
Source: https://docs.portkey.ai/docs/product/administration/enforce-default-config
Learn how to attach default configs to API keys for enforcing governance controls across your organization
## Overview
Portkey allows you to attach default configs to API keys, enabling you to enforce specific routing rules, security controls, and other governance measures across all API calls made with those keys. This feature provides a powerful way to implement organization-wide policies without requiring changes to individual application code.
> [!NOTE]
>
> This feature is available on all Portkey plans.
## How It Works
When you attach a default config to an API key:
1. All API calls made using that key will automatically apply the config settings
2. Users don't need to specify config IDs in their code
3. Administrators can update governance controls by simply updating the config, without requiring code changes
This creates a clean separation between application development and governance controls.
> [card] [Learn more about Configs](/docs/product/ai-gateway/configs)
>
> Create and manage configs to define routing rules, fallbacks, caching, and more
## Benefits of Default Configs
Attaching default configs to API keys provides several governance benefits:
* **Centralized Control**: Update policies for multiple applications by changing a single config
* **Access Management**: Control which models and providers users can access
* **Cost Control**: Implement budget limits and control spending across teams
* **Reliability**: Enforce fallbacks, retries, and timeout settings organization-wide
* **Security**: Apply guardrails and content moderation across all applications
* **Consistent Settings**: Ensure all applications use the same routing logic
## Setting Up Default Configs
### Prerequisites
Before attaching a config to an API key, you need to:
1. Create a [config](/docs/product/ai-gateway/configs) on Portkey app with your desired settings
2. Note the config ID that want to attach to your API keys
### Attaching Configs via the UI
Navigate to **API Keys** in the sidebar, then:
* **New Keys**: Click **Create** and select your desired config from the **Config** dropdown
* **Existing Keys**: Click the edit icon on any key and update the config selection
* **Config Override**: Enable or Disable config override flag.
* **ON** (default): Users can specify their own configs in requests, which will override the default config attached to the API key
* **OFF**: Any attempt to override the default config in a request will result in a 400 error, enforcing the use of only the pre-approved config

> [!NOTE]
>
> You can attach only one config to an API key. This applies to both workspace API keys and admin API keys.
### Attaching Config via the API
You can also programmatically attach config when creating or updating API keys using the Portkey API.
#### Creating a New API Key with Default Config
> [tab] Python
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(api_key="YOUR_ADMIN_API_KEY")
>
> api_key = portkey.api_keys.create(
> name="engineering-team",
> type="organisation",
> workspace_id="YOUR_WORKSPACE_ID",
> defaults={
> "config_id": "pc-your-config-id",
> "metadata": {
> "environment": "production",
> "department": "engineering"
> }
> },
> scopes=["logs.view", "configs.read"]
> )
>
> print(f"API Key created: {api_key.key}")
> ```
> [tab] JavaScript
>
> ```javascript theme={"system"}
> import { Portkey } from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: 'YOUR_ADMIN_API_KEY'
> });
>
> async function createApiKey() {
> const apiKey = await portkey.apiKeys.create({
> name: 'engineering-team',
> type: 'organisation',
> workspace_id: 'YOUR_WORKSPACE_ID',
> defaults: {
> config_id: 'pc-your-config-id',
> metadata: {
> environment: 'production',
> department: 'engineering'
> }
> },
> scopes: ['logs.view', 'configs.read']
> });
>
> console.log(`API Key created: ${apiKey.key}`);
> }
>
> createApiKey();
> ```
> [tab] cURL
>
> ```bash theme={"system"}
> curl -X POST https://api.portkey.ai/v1/admin/api-keys \
> -H "Content-Type: application/json" \
> -H "Authorization: Bearer YOUR_ADMIN_API_KEY" \
> -d '{
> "name": "engineering-team",
> "type": "organisation",
> "workspace_id": "YOUR_WORKSPACE_ID",
> "defaults": {
> "config_id": "pc-your-config-id",
> "metadata": {
> "environment": "production",
> "department": "engineering"
> }
> },
> "scopes": ["logs.view", "configs.read"]
> }'
> ```
#### Updating an Existing API Key
For detailed information on API key management, refer to our API documentation:
> [card] [Create API Key](/docs/api-reference/admin-api/control-plane/api-keys/create-api-key)
>
> Learn how to create API keys with default configs
> [card] [Update API Key](/docs/api-reference/admin-api/control-plane/api-keys/update-api-key)
>
> Learn how to update existing API keys with new default configs
## Default Workspace User API Key Auto-Create
Organisation owners can set **`default_workspace_user_api_key_auto_create`** (org-only, Backend `v1.17.0+`) to control whether workspace-user API keys are auto-provisioned when users join the organisation's **default workspace**. This is separate from per-workspace **`user_api_key_auto_create`** overrides.
## Default Scopes for Auto-Created User API Keys
Organisation and workspace admins can set **`user_api_key_auto_create_scopes`** (with workspace-level override, Backend `v1.24.2+`) to control which data-plane scopes are granted to auto-created workspace-user API keys. When set, auto-provisioned keys receive only the listed scopes instead of the full default scope set.
* Accepts an array of valid data-plane scope strings (e.g. `["completions"]`)
* Supports workspace-level override via the `user_api_key_auto_create_scopes` workspace override toggle
* When not set, auto-created keys receive the default full scope set
## Workspace Default Config for User API Keys
Organisation admins can set a workspace-level default config for workspace-user API keys via `defaults.user_api_key_config` on workspace create/update (Backend `v1.16.2+`).
* Accepts a config **ID** or **slug** belonging to the workspace
* **Auto-created** workspace-user API keys (from `user_api_key_auto_create`) inherit this config when no per-key default is set
* **Manual** workspace-user API key creation falls back to this config when `defaults.config_id` is omitted
* `GET` workspace returns the config **slug** in `defaults.user_api_key_config`
* A config cannot be deleted while it is set as a workspace's `user_api_key_config` default
```json theme={"system"}
{
"defaults": {
"user_api_key_config": "pc-your-config-id"
}
}
```
## Embedding Default Configs in JWT Tokens
If you use [JWT-based authentication](/docs/product/enterprise-offering/org-management/jwt), you can also embed a default config directly in the JWT payload using the `defaults` claim — no need to attach it to an API key. This is useful when different users or services need different default configs, controlled at token issuance time.
```json theme={"system"}
{
"portkey_oid": "your-org-id",
"portkey_workspace": "your-workspace",
"scope": ["completions.write"],
"exp": 1735689600,
"defaults": {
"config_id": "pc-your-config-id",
"metadata": { "team": "backend" }
}
}
```
> [card] [JWT Authentication — Default Configs](/docs/product/enterprise-offering/org-management/jwt#embedding-default-configs-in-jwt)
>
> Learn more about embedding default configs in JWT tokens
## Config Precedence
When using API keys with default configs, Portkey provides flexible options for controlling config behavior:
* The default config attached to the API key will be automatically applied to all requests made with that key
* By default, if a user explicitly specifies a config ID in their request, that config will override the default config attached to the API key
* You can now disable config overrides by toggling off "Allow Config Override" when creating or editing API keys
This flexibility allows for centralized governance while still enabling exceptions when needed.
## Use Cases
### Enterprise AI Governance
For large organizations with multiple AI applications, attaching default configs to API keys enables centralized governance:
1. Create department-specific API keys with appropriate configs
2. Apply budget limits and define model usage per department
3. Track usage and spending per team by filtering logs by config\_id
4. Update policies centrally without requiring code changes
### Security and Compliance
Ensure all API interactions follow security protocols by enforcing:
* Specific models that have been approved for use
* Content moderation with input/output guardrails
* PII detection and redaction
### Cost Management
Control AI spending by:
* Routing to cost-effective models by default
* Implementing caching for frequently used prompts
* Applying rate limits to prevent unexpected usage spikes
## Support
For questions about configuring default settings for API keys or troubleshooting issues, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforcing Org Level Guardrails
Source: https://docs.portkey.ai/docs/product/administration/enforce-orgnization-level-guardrails
## Overview
Portkey enables organization owners to enforce request guardrails at the organization level. This feature ensures that all API requests made within the organization comply with predefined policies, enhancing security, compliance, and governance.
## How It Works
Organization owners can define input and output guardrails in the Organization Guardrails section. These guardrails are enforced on all API requests made within the organization, ensuring uniform policy enforcement across all users and applications.
* **Input Guardrails**: Define checks and constraints for incoming LLM requests.
* **Output Guardrails**: Ensure LLM responses align with organizational policies.
The guardrails available here are the same as those found in the Guardrails section of the Portkey platform. Multiple providers are supported for setting up guardrails. For a detailed list of supported providers and configurations
> [card] [Guardrials Docs](/docs/product/guardrails)
>
> Learn about the different Guardrails you can set up in Portkey
## Configuration
### Setting Up Guardrails Requirements
1. Head to `Admin Settings` on the Portkey dashboard
2. Navigate to the `Organisation Guardrails` section
3. Add your `Input` and/or `Output` Guardrails
4. Save your changes
Once configured, these guardrails will be enforced on all API requests across the organization.
## Excluding Workspaces
Some workspaces — an internal evaluation sandbox, for example — may need to run without the organisation's default guardrails. You can exempt them individually while every other workspace stays covered.
Exclusions are managed per guardrail direction through the Admin API, and require an organisation service API key with the `organisation_exclusions.update` and `organisation_exclusions.list` scopes.
> [!NOTE]
>
> Workspace exclusions are currently available via the API only. Support for managing them from the Portkey dashboard is coming shortly.
```bash theme={"system"}
curl -X PUT "https://api.portkey.ai/v1/workspace-exclusions/input-guardrails" \
-H "x-portkey-api-key: YOUR_ADMIN_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"organisation_id": "ORGANISATION_ID",
"workspaces": [
{ "workspace_id": "WORKSPACE_ID", "excluded": true }
]
}'
```
Use `/workspace-exclusions/output-guardrails` for output guardrails, and set `excluded` to `false` to bring a workspace back under enforcement. Pass `override_existing: true` to replace the current exclusion list rather than merge into it. The matching `GET` endpoint returns the workspaces currently excluded.
> [!NOTE]
>
> Best Practices
>
> * Clearly communicate guardrail requirements to all developers in your organization.
> * Maintain internal documentation on your guardrail policies to ensure consistency.
## Support
For questions about configuring metadata schemas or troubleshooting issues, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforcing Policies with Start Hooks
Source: https://docs.portkey.ai/docs/product/administration/enforce-policies-with-start-hooks
Apply start hook guardrails to every request in a workspace or your whole organization, so header, metadata, identity, and endpoint rules can't be skipped by individual clients.
[Start hooks](/docs/product/guardrails/start-hooks) can be attached to a single request through its config. To enforce a policy instead, attach them as **defaults** on a workspace or on the organization. The gateway then runs them on every request, whatever config the client sends.
Use this to guarantee rules such as:
* Every request carries the metadata your cost reports depend on
* Clients can't turn off request logging
* Only approved endpoints are reachable
* Callers present a valid JWT, and their identity comes from the token rather than from headers they set themselves
## How Enforcement Works
For each request, the gateway collects start hooks from three places, in this order:
1. **Organization** start hooks
2. **Workspace** start hooks, for the workspace the API key belongs to
3. **Config** `start_hooks`, from the config attached to the request
All of them run. Defaults are added to the hooks in the config, never replaced by them, so a client can't opt out by sending a different config. If any hook with `deny: true` fails, the request is blocked.
| Level | Set by | Applies to |
| :- | :- | :- |
| Organization | Organization owners | Every workspace |
| Workspace | Workspace owners | Every request in that workspace |
| Config | Whoever builds the request | Requests that use that config |
> [!NOTE]
>
> Start hooks enforced at the organization or workspace level run in addition to input and output guardrails you've already configured at those levels. See [Enforcing Org Level Guardrails](/docs/product/administration/enforce-orgnization-level-guardrails) and [Enforcing Workspace Level Guardrails](/docs/product/administration/enforce-workspace-level-guardials).
## Enforce at the Organization Level
1. Create a guardrail made only of [checks that support start hooks](/docs/product/guardrails/start-hooks#supported-checks). See [Start Hooks](/docs/product/guardrails/start-hooks#create-a-start-hook).
2. Go to `Admin Settings` in the Portkey dashboard.
3. Open the `Organisation Guardrails` section.
4. In **Start Hooks**, add the guardrail.
5. Save your changes.
The hook now runs on requests in all workspaces. The section describes this setting as enforcing policies before request processing: validating headers, JWT tokens, metadata, and endpoint access.
> [!NOTE]
>
> An organization-level start hook must be an organization-level guardrail, not one created inside a single workspace.
> [!NOTE]
>
> If you create the guardrail from the **Start Hooks** section here, the check list only shows checks that support start hooks. A guardrail you created elsewhere may contain other checks, so make sure it only uses [checks that support start hooks](/docs/product/guardrails/start-hooks#supported-checks).
## Enforce at the Workspace Level
1. Open your workspace's settings.
2. Go to **Workspace Guardrails**.
3. Under **Start Hook Guardrail**, select a start hook guardrail created in the workspace.
4. Click **Update**.
All requests made with API keys in this workspace now run the hook.
> [!WARNING]
>
> The workspace dropdown lists all guardrails in the workspace, not only ones that work at the start stage. Select a guardrail made only of [checks that support start hooks](/docs/product/guardrails/start-hooks#supported-checks): Header Check, Header Transform, Required Metadata Keys, Allowed Request Types, JWT, or Webhook. The dashboard won't stop you from attaching an incompatible guardrail, and it may not enforce what you intended.
## Enforce Through a Config
A config only applies to requests that use it, and a client can choose its own config. To make a config enforce a policy, attach it as the **default config** of an API key and turn off **Allow Config Override**. Requests made with that key then always run the config's `start_hooks`, and a request that sends its own config gets a `400` error. See [Enforcing Default Configs on API Keys](/docs/product/administration/enforce-default-config).
> [!NOTE]
>
> If config override is left on, a client can send a different config and the `start_hooks` in your default config no longer run. Start hooks set at the organization or workspace level are not affected, because they run in addition to any config.
## Policy Recipes
Each recipe below shows two ways to set up the same policy. Use the tab that fits how you enforce it:
* **Dashboard**: create a regular guardrail on the **Guardrails** page with the check, parameters, and actions shown, then attach it as a start hook at the [organization](#enforce-at-the-organization-level) or [workspace](#enforce-at-the-workspace-level) level.
* **Config**: add the `start_hooks` entry shown to a config, alongside your usual provider settings, and [enforce it with a default config](#enforce-through-a-config).
Use only [checks that support start hooks](/docs/product/guardrails/start-hooks#supported-checks).
### Require Request Metadata
Block requests that don't say who or what they're for, so logs and reports can always be attributed, before any LLM spend happens.
> [tab] Dashboard
>
> **Check:** Required Metadata Keys
>
> * **Operator:** `all`
> * **Metadata Keys:** `user_id`, `team`
> * **Action:** Deny on Failure
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "require-attribution",
> "deny": true,
> "checks": [
> {
> "id": "default.requiredMetadataKeys",
> "parameters": {
> "metadataKeys": ["user_id", "team"],
> "operator": "all"
> }
> }
> ]
> }
> ]
> }
> ```
With `all`, a request missing any listed key is blocked. Use `any` to require at least one key, or `none` to prohibit keys, for example to reject requests that include a key reserved for your own systems.
### Prevent Clients from Disabling Logging
Block requests that send `x-portkey-debug: false`.
> [tab] Dashboard
>
> **Check:** Header Check
>
> * **Operator:** `none`
> * **Header Key-Value Pairs:** `{"x-portkey-debug": "false"}`
> * **Action:** Deny on Failure
>
> For a step-by-step walkthrough with screenshots, see [Start Hooks](/docs/product/guardrails/start-hooks#example-block-clients-from-turning-off-request-logging).
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "enforce-debug-logging",
> "deny": true,
> "checks": [
> {
> "id": "default.headerCheck",
> "parameters": {
> "headerPairs": { "x-portkey-debug": "false" },
> "operator": "none"
> }
> }
> ]
> }
> ]
> }
> ```
`none` means the check passes only if none of the listed pairs match. A request with `x-portkey-debug: false` is blocked with `446`. A request without the header, or with `x-portkey-debug: true`, goes through.
### Allow Only Specific Endpoints
Allow chat and embeddings requests, and block everything else.
> [tab] Dashboard
>
> **Check:** Allowed Request Types
>
> * **Allowed Request Types (Multi-select):** `chatComplete`, `embed`
> * **Action:** Deny on Failure
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "endpoint-allowlist",
> "deny": true,
> "checks": [
> {
> "id": "default.allowedRequestTypes",
> "parameters": {
> "allowedTypes": ["chatComplete", "embed"]
> }
> }
> ]
> }
> ]
> }
> ```
The check works out the request type from the path, for example `/v1/chat/completions` becomes `chatComplete`. A request to any type not in the list, including paths such as `/v1/models`, is blocked. See [Allowed Request Types](/docs/product/guardrails/start-hooks#allowed-request-types) for the full list of request types.
### Block Specific Endpoints
Block batch and fine-tuning requests and allow everything else.
> [tab] Dashboard
>
> **Check:** Allowed Request Types
>
> * **Blocked Request Types (Multi-select):** `createBatch`, `createFinetune`
> * **Action:** Deny on Failure
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "block-expensive-ops",
> "deny": true,
> "checks": [
> {
> "id": "default.allowedRequestTypes",
> "parameters": {
> "blockedTypes": ["createBatch", "createFinetune"]
> }
> }
> ]
> }
> ]
> }
> ```
> [!NOTE]
>
> In a start hook, `createBatch` and `createFinetune` stand for their whole endpoint families. This policy blocks every request to `/v1/batches` and `/v1/fine_tuning/jobs`, including listing and retrieving jobs, not only creating them.
### Require a Valid JWT and Take Identity from It
Validate the caller's token, check its claims, and write trusted claims into the request so they can't be spoofed.
> [tab] Dashboard
>
> **Check:** JWT
>
> * **Header Key:** `Authorization`
> * **JWKS URI:** `https://auth.example.com/.well-known/jwks.json`
> * **Required Claims:** `sub`, `email`, `org_id`
> * **Claim Values:** `{"org_id": {"values": "org_12345", "matchType": "exact"}}`
> * **Extract Claims:** `sub`, `email`, `org_id`
> * **Claim Prefix:** `x-jwt-`
> * **Action:** Deny on Failure
>
> 
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "jwt-auth",
> "deny": true,
> "checks": [
> {
> "id": "default.jwt",
> "parameters": {
> "headerKey": "Authorization",
> "jwksUri": "https://auth.example.com/.well-known/jwks.json",
> "requiredClaims": ["sub", "email", "org_id"],
> "claimValues": {
> "org_id": { "values": "org_12345", "matchType": "exact" }
> },
> "extractClaims": ["sub", "email", "org_id"],
> "claimPrefix": "x-jwt-",
> "failOnError": true
> }
> }
> ]
> }
> ]
> }
> ```
With these parameters:
* The token signature is verified against the JWKS URI, and a missing, expired, or invalid token is blocked
* `sub`, `email`, and `org_id` must be present, and `org_id` must equal `org_12345`
* The extracted claims are written to the `x-jwt-sub`, `x-jwt-email`, and `x-jwt-org_id` headers, and to request metadata under their raw names (set `metadataPrefix` to add a prefix)
* Any value the client sent for those headers or keys is overwritten, or removed if the token doesn't have the claim
`failOnError: true` makes an error, such as an unreachable JWKS endpoint, block the request instead of letting it through. The dashboard doesn't show this option for the JWT check, so use the Config tab if you need it. See the [JWT guardrail](/docs/integrations/guardrails/jwt) for validation options.
### Normalize Headers
Remove client-controlled headers your downstream services shouldn't trust, and stamp the request with values you control.
> [tab] Dashboard
>
> **Check:** Header Transform
>
> * **Headers to Remove:** `["x-internal-override"]`
> * **Headers to Set:** `{"x-gateway-env": "production"}`
> * **Execute guardrails sequentially:** on
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "normalize-headers",
> "deny": true,
> "sequential": true,
> "checks": [
> {
> "id": "default.headerTransform",
> "parameters": {
> "remove": ["x-internal-override"],
> "set": { "x-gateway-env": "production" }
> }
> }
> ]
> }
> ]
> }
> ```
Header Transform never blocks a request. Authentication headers and `x-portkey-*` headers can't be changed, and headers the gateway reads itself, such as `anthropic-beta`, are not affected. The provider may also ignore the headers you set. See [Header Transform](/docs/product/guardrails/start-hooks#header-transform).
> [!NOTE]
>
> To keep clients from using an `anthropic-beta` feature you haven't approved, don't try to strip the header with Header Transform. A Header Check can block the request instead, but it matches an exact header value, so it only works when you know the exact value clients send.
### Keep an Agent's Requests on the Same Workers AI Instance
[Workers AI prompt caching](https://developers.cloudflare.com/workers-ai/features/prompt-caching/) routes requests that carry the same `x-session-affinity` value to the same model instance, so a long shared prefix such as a system prompt and tool definitions is reused instead of reprocessed. Header Transform can add this header for clients that don't send it.
> [tab] Dashboard
>
> **Check:** Header Transform
>
> * **Headers to Set:** `{"x-session-affinity": "support-agent"}`
>
> This replaces any `x-session-affinity` value the client sends. To keep a value the client sends, use the Config tab.
>
> 
> [tab] Config
>
> Set the header on every request:
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "pin-session-affinity",
> "deny": true,
> "checks": [
> {
> "id": "default.headerTransform",
> "parameters": {
> "set": { "x-session-affinity": "support-agent" }
> }
> }
> ]
> }
> ]
> }
> ```
>
> Or set it only when the client didn't send one:
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "default-session-affinity",
> "deny": true,
> "checks": [
> {
> "id": "default.headerTransform",
> "parameters": {
> "setIf": {
> "x-session-affinity": {
> "exists": false,
> "set": { "x-session-affinity": "support-agent" }
> }
> }
> }
> }
> ]
> }
> ]
> }
> ```
Headers that Header Transform sets are forwarded to the provider, and the Workers AI provider passes them through. A few things to keep in mind:
* **Use one value per agent.** The value is a fixed string. If every request in the organization or workspace gets the same value, they all go to one instance, which removes the benefit and can overload it. Use this on a workspace or API key dedicated to one agent, or let each client send its own per-session value and use the `setIf` version only as a fallback.
* **It reaches every provider in the request.** The start hook runs once per request, not per target, so the header is also sent to any fallback or load-balance targets in the same config. Most providers ignore an unknown header.
* **You can't see the effect in the response headers or body fields the gateway adds.** Cloudflare doesn't echo the header back. The gateway returns Cloudflare's `usage` object unchanged, so check it for cached token counts on models that support prefix caching, as described in Cloudflare's guide.
### Delegate the Decision to an External Policy Service
Send the request context to your own service, such as an internal access control system, and let it decide.
> [tab] Dashboard
>
> **Check:** Webhook
>
> * **Webhook URL:** `https://policy.internal.example.com/v1/check`
> * **Headers:** `{"x-service-auth": "YOUR_SERVICE_TOKEN"}`
> * **Timeout:** `3000`
> * **Fail if the webhook returns a non-200 status or times out:** on
> * **Action:** Deny on Failure
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "external-policy-check",
> "deny": true,
> "checks": [
> {
> "id": "default.webhook",
> "parameters": {
> "webhookURL": "https://policy.internal.example.com/v1/check",
> "headers": { "x-service-auth": "YOUR_SERVICE_TOKEN" },
> "timeout": 3000,
> "failOnError": true
> }
> }
> ]
> }
> ]
> }
> ```
The gateway sends your service the request context: the request metadata, request path and type, and provider. Request headers are not sent, so a webhook can't see the caller's credentials. To pass specific headers, list them in `forwardHeaders`. See [Forwarding headers](/docs/product/guardrails/forwarding-headers).
Your service replies with a JSON body like `{ "verdict": true, "data": { ... } }`. If `verdict` is `false`, the request is blocked and `data` is included in the check result. Set `failOnError` so that a timeout or error from your service blocks the request. Without it, an unreachable service lets every request through.
### Audit Without Adding Latency
Run a check after the response has been sent, so it records the request without slowing it down.
> [tab] Dashboard
>
> **Check:** Webhook
>
> * **Webhook URL:** `https://compliance.internal.example.com/v1/audit`
> * **Action:** Run Asynchronously
>
> 
>
> 
> [tab] Config
>
> ```json theme={"system"}
> {
> "start_hooks": [
> {
> "type": "guardrail",
> "id": "async-compliance-check",
> "deny": false,
> "async": true,
> "checks": [
> {
> "id": "default.webhook",
> "parameters": {
> "webhookURL": "https://compliance.internal.example.com/v1/audit"
> }
> }
> ]
> }
> ]
> }
> ```
An async start hook can't block the request or change its headers or metadata. Its result appears in your logs, so use it for compliance auditing.
## Combine Multiple Checks and Policies
You can stack checks and policies instead of using one per hook:
* **Several checks in one guardrail.** Add more than one check to a single guardrail. The guardrail passes only if every check passes. For example, put a JWT check and an Allowed Request Types check in one guardrail to require a valid token and an approved endpoint.
* **A transform followed by a check.** Add Header Transform and then Header Check to the same guardrail, with **Execute guardrails sequentially** turned on, so the check sees the headers as the transform left them. For example, Header Transform sets `x-gateway-env: production`, and Header Check then verifies that `x-gateway-env` is `production`, or that a header you removed is gone. Without sequential execution, the checks run in parallel and the Header Check sees the original headers.
* **Several guardrails.** Attach more than one guardrail as a start hook at the same level. Each is evaluated on its own, and the request is blocked if any guardrail with **Deny on Failure** fails. Use separate guardrails when you want each policy reported and managed independently, for example to run one in observe mode (without **Deny on Failure**) while the others enforce.
In a config, the checks go in the `checks` array of one hook, and separate guardrails are separate entries in `start_hooks`:
```json theme={"system"}
{
"start_hooks": [
{
"type": "guardrail",
"id": "stamp-and-verify",
"deny": true,
"sequential": true,
"checks": [
{
"id": "default.headerTransform",
"parameters": { "set": { "x-gateway-env": "production" } }
},
{
"id": "default.headerCheck",
"parameters": {
"headerPairs": { "x-gateway-env": "production" },
"operator": "all"
}
}
]
}
]
}
```
## Roll Out Safely
Start hooks run before everything else, so a misconfigured one can block all traffic. A safe rollout:
1. **Observe.** Attach the hook with `deny: false`. Violations don't block anything, but they appear in `hook_results` and in your logs, so you can see who would be affected.
2. **Fix clients.** Update the applications that fail the check.
3. **Soft deny, if needed.** Set `deny: true` and `soft_deny_200: true` for clients that can't handle non-`2xx` errors. They get a `200` response that carries the failure message.
4. **Enforce.** Switch to `deny: true` without soft deny, so violations return `446`.
## Verify a Policy
Send a request that breaks the rule and check the response. For the metadata example above:
```bash theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "@openai-xxx/gpt-4o-mini",
"messages": [{ "role": "user", "content": "Hello" }]
}'
```
With the hook enforced and no `user_id` or `team` metadata, the request returns `446` and never reaches the provider:
```json theme={"system"}
{
"status": "failure",
"message": "Request denied by start hook guardrail",
"details": {
"hookId": "pg-required-metadata-xxx",
"checks": [
{
"id": "default.requiredMetadataKeys",
"verdict": false,
"data": {
"explanation": "Check failed for 'all' metadata keys. Some metadata keys were missing.",
"missing_metadata_keys": ["user_id", "team"],
"found_metadata_keys": [],
"operator": "all"
}
}
]
}
}
```
Add the metadata with the `x-portkey-metadata` header and the same request goes through. Set a [custom error message](/docs/product/guardrails/start-hooks#hard-deny-446) on the guardrail so developers know how to fix the request.
> [!NOTE]
>
> Best Practices
>
> * Start with `deny: false` and move to enforcement once you've reviewed the logs.
> * Put one policy in each guardrail, so a failure points to a single rule and you can change or remove rules independently.
> * Set `failOnError` on checks that call external services, such as a webhook, or a JWT check with a remote JWKS. For JWT, set it in a config, since the dashboard doesn't show it.
> * Tell developers what is enforced and how to comply, using a clear custom error message.
> * A guardrail that's in use as an organization or workspace default can't be deleted until you remove it from those settings.
## Related
> [card] [Start Hooks](/docs/product/guardrails/start-hooks)
>
> How start hooks work and the checks they support
> [card] [Enforcing Request Metadata](/docs/product/administration/enforcing-request-metadata)
>
> Make metadata mandatory on requests
## Support
For questions about configuring start hooks or troubleshooting issues, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
# Enforce Rate Limits on Your AI Provider
Source: https://docs.portkey.ai/docs/product/administration/enforce-rate-limits-on-your-ai-provider
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforcing Saved-Only Resources
Source: https://docs.portkey.ai/docs/product/administration/enforce-saved-only-config
Lock the Gateway to admin-curated providers, configs, and integrations by rejecting inline provider configuration at request time.
> [!WARNING]
>
> Hybrid enterprise customers require **Gateway version `2.11.0` or later** to enforce saved-only mode. On earlier versions the setting has no effect and inline configuration is not blocked.
## Overview
Portkey lets administrators define **saved** resources (providers, integrations, and configs) that callers reference by slug. **Saved-only mode** (the **Block Inline Configs** data-plane security setting) enforces that callers can *only* use these admin-curated resources.
When the setting is enabled, the Gateway inspects every inference request and rejects any attempt to **select a provider, endpoint, or config inline**. Callers can no longer bring their own provider name, base URL, or ad-hoc config object in the request. Instead, they must reference a saved entity created and governed by an administrator.
This keeps every request on resources your team has set up, so the governance, allowlists, budget controls, and audit attribution attached to those resources apply consistently, without relying on configuration supplied at request time.
> [!NOTE]
>
> This setting sits alongside the other security settings you manage for API keys, providers, and workspaces. It is available on both **SaaS** and **self-hosted** deployments.
## How It Works
Saved-only mode is a **data-plane** control: it is enforced by the Portkey Gateway on every request, independently of which API key or workspace the request belongs to.
When a request arrives, the Gateway resolves whether saved-only mode is active for the caller's organization (and workspace). If it is, the Gateway runs a single check at the very start of request processing, **before** the request is forwarded to any provider:
1. The request is scanned for any signal that selects a provider, endpoint, or config **inline** (rather than by slug).
2. If such a signal is found, the request is **rejected immediately with an HTTP `400`** and a specific, machine-readable error code identifying exactly what was blocked.
3. If the request only references **saved** entities (a config slug, a saved provider, a saved model), it proceeds normally.
Because the check runs at a single point before routing, blocked requests never reach an upstream provider, and every rejection is emitted from one consistent place, making the errors easy to detect, log, and alert on.
## Default Behavior and Rollout
How this setting is initialized depends on when your organization was created:
* **Organizations created on or after June 19, 2026** have saved-only mode **enabled (blocked) by default**. Inline provider configuration is rejected out of the box, and administrators can turn it off if they want to allow inline configuration.
* **Organizations created before June 19, 2026** have saved-only mode **disabled by default** to preserve backward compatibility. Existing traffic is unaffected until an administrator turns it on.
New workspaces inherit their organization's setting at the time of creation.
> [!NOTE]
>
> Existing organizations can adopt saved-only mode at any time by enabling it from the **Admin Settings** panel (see below). No code changes are required on the caller side as long as requests already reference saved resources.
## Enabling Saved-Only Mode
### From the Dashboard (SaaS and self-hosted)
Administrators can enable the setting per organization:
1. Navigate to **Admin Settings** in the Portkey dashboard.
2. Open the **Security** tab.
3. Locate the **Data Plane Security Settings** section.
4. Toggle on **Block Inline Configs**.
The change applies to all subsequent requests for the organization. Existing workspaces are kept in sync with the organization setting.
### Via Environment Variable (self-hosted only)
Self-hosted deployments can additionally enforce saved-only mode across the entire Gateway, regardless of the per-organization setting:
```sh theme={"system"}
# Force saved-only mode on every request through this Gateway
BLOCK_INLINE_CONFIG=true
```
The organization setting and the Gateway environment variable **combine to make policy stricter**: if *either* one enables saved-only mode, it is enforced. Neither can loosen the other. This lets platform teams set a baseline at the infrastructure layer that applies across organizations.
> [!NOTE]
>
> The environment variable applies to self-hosted Gateways only and is ignored on Portkey's managed SaaS.
## What Gets Blocked
When saved-only mode is enabled, the following inline inputs are rejected. Each one returns an HTTP `400` with its own error code so you can pinpoint exactly what was blocked.
| Blocked input | What the caller tried to do | Error code |
| :- | :- | :- |
| **Inline config JSON** | Passed a raw config object instead of referencing a saved config by its `pc-...` slug | `inline_config_blocked` |
| **Raw provider name** | Named a provider directly (e.g. `openai`) instead of a saved provider slug (`@my-provider`) | `inline_provider_blocked` |
| **Inline custom host** | Supplied a custom base URL for the upstream provider at request time | `inline_custom_host_blocked` |
| **Inline provider URL** | Overrode a provider-specific endpoint at request time (e.g. a Hugging Face base URL, Azure Foundry URL, or Databricks workspace) | `inline_provider_url_blocked` |
| **Inline forward headers** | Asked the Gateway to forward arbitrary request headers to the upstream provider | `inline_forward_headers_blocked` |
A few notes on why each is included:
* **Inline custom host** and **inline provider URL** are blocked because they point the Gateway at an endpoint defined at request time rather than the one on the curated provider.
* **Inline forward headers** are blocked because forwarded headers are layered on top of a saved provider's authentication headers downstream, so an inline list could override the curated credentials. Forwarding is still allowed when an administrator has configured it on the saved provider itself.
## What Stays Allowed
Saved-only mode is designed to be transparent to callers that already reference saved resources. The following continue to work:
* **Saved configs** referenced by slug, e.g. `x-portkey-config: pc-...`
* **Saved providers / integrations** referenced by slug, e.g. `x-portkey-provider: @my-provider`
* **Saved model references** in the request body, e.g. `"model": "@my-provider/model-name"`
* **Forward headers configured by an administrator** on a saved provider (as opposed to passed inline on the request)
* **Credentials passed directly** via the `Authorization` header (credentials alone cannot select a provider)
## Error Responses
When a request is blocked, the Gateway returns an HTTP `400` with a structured body. The `error.code` field identifies the violation, and `error.field` names the specific input that triggered it.
```json theme={"system"}
{
"status": "failure",
"error": {
"code": "inline_provider_blocked",
"message": "Inline provider names are not allowed when saved-only mode is enabled. Use a saved integration via '@slug' instead.",
"field": "x-portkey-provider"
},
"message": "Inline provider names are not allowed when saved-only mode is enabled. Use a saved integration via '@slug' instead."
}
```
Each error code maps to one blocked input:
| Error code | Meaning | How to fix |
| :- | :- | :- |
| `inline_config_blocked` | A raw config object was passed inline | Save the config and reference it by its `pc-...` slug |
| `inline_provider_blocked` | A provider was named directly | Reference a saved provider via `@slug` |
| `inline_custom_host_blocked` | A custom host was supplied inline | Configure the custom host on a saved provider |
| `inline_provider_url_blocked` | A provider-specific URL was supplied inline | Configure the endpoint on a saved provider |
| `inline_forward_headers_blocked` | Header forwarding was requested inline | Configure `forward_headers` on a saved provider |
The Gateway checks for violations in order and returns the **first** one it finds, so a request with multiple inline inputs surfaces one error code at a time.
## Use Cases
### Centralized Provider Governance
Saved-only mode keeps every request on admin-curated resources, so the budget limits, guardrails, and model allowlists attached to your saved providers and configs consistently apply across all callers.
### Shared and Multi-Tenant Gateways
When many teams or applications share a Gateway, saved-only mode keeps each request scoped to the resources an administrator has set up, rather than endpoints or headers supplied at request time.
### Clear Audit Attribution
Because every request references a named, saved resource, logs and analytics attribute usage to known providers and configs rather than to inline payloads.
## Related
> [card] [Enforce Default Configs](/docs/product/administration/enforce-default-config)
>
> Attach default configs to API keys for org-wide governance.
> [card] [Configs](/docs/product/ai-gateway/configs)
>
> Save and reference Gateway configs by slug.
> [card] [Model Catalog](/docs/product/model-catalog)
>
> Create saved providers and integrations.
> [card] [Gateway Headers](/docs/api-reference/inference-api/headers)
>
> Full reference for the `x-portkey-*` request headers.
## Support
For questions about saved-only mode or other data-plane security settings, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforce Workspace Budget and Rate Limits
Source: https://docs.portkey.ai/docs/product/administration/enforce-workspace-budget-limts-and-rate-limits
Configure budget and rate limits at the workspace level to effectively manage AI spending and resource allocation
> [!NOTE]
>
> Available on **Enterprise** plan and select **Pro** customers.
## Overview
Workspace Budget Limits provide granular financial and usage control at the workspace level, allowing organization admins/owners and workspace admins to allocate resources effectively across teams and projects. This feature complements API key-level budget controls, creating a comprehensive governance framework for AI spending across your organization.
By implementing budget and rate limits at the workspace level, you can:
* Allocate specific budgets to different departments, teams, or projects
* Prevent individual workspaces from consuming disproportionate resources
* Establish rate limits to ensure equitable API access across workspaces
* Maintain greater visibility and control over organization-wide AI expenditure
## Accessing Workspace Budget Controls
To configure budget limits for a workspace:
1. In the app sidebar, click **Workspace Control** for the workspace you want to manage
2. Select the **Budget Allocation** tab
3. Add your workspace rate limits and budgets, then click **Update**
### Who can manage workspace budgets
> [!NOTE]
>
> The following roles can configure workspace budgets and rate limits:
>
> * Organization owners and organization admins
> * Workspace admins
> * Workspace managers (if the org admin has enabled "Workspace Management Permissions" in Admin Settings)

## Setting Rate Limits
Rate limits control how frequently requests can be made from a workspace, helping you maintain application performance and prevent unexpected usage spikes.
To set up rate limits for a workspace:
1. Toggle on **Add Rate Limit**
2. Choose your limit type:
* **Requests**: Limit based on number of API calls
* **Tokens**: Limit based on token consumption
3. Specify the limit value in the **Set Rate Limit** field
4. Select a time interval from the dropdown (Requests/Minute, Requests/Hour, Requests/Day)
When a workspace reaches its rate limit, all subsequent requests from that workspace will be rejected until the time interval resets, regardless of which API key is used.
## Setting Budget Limits
Budget limits allow you to set maximum spending or token usage thresholds for an entire workspace, automatically preventing further usage when limits are reached.
To set up budget limits for a workspace:
1. Toggle on **Add Budget**
2. Choose your limit type:
* **Cost**: Set a maximum spend in USD
* **Tokens**: Set a maximum token usage
3. Enter the budget amount in the **Budget Limit (\$)** field
4. Optionally, set an **Alert Threshold (\$)** to receive notifications before reaching the full budget
5. Select a **Periodic Reset** option to determine when the budget refreshes
### Alert Thresholds
Alert thresholds trigger notifications when a percentage of the workspace budget has been consumed:
1. Enter a value in the **Alert Threshold (\$)** field
2. When usage reaches this threshold, notifications will be sent to configured recipients
3. The workspace continues to function until the full budget limit is reached
### Periodic Reset Options
Workspace budgets can be set to automatically reset at regular intervals:
* **No Periodic Reset**: The budget limit applies until exhausted
* **Reset Weekly**: Budget limits reset every Sunday at 12 AM UTC
* **Reset Monthly**: Budget limits reset on the 1st of each month at 12 AM UTC
* **Custom Reset Days**: Set a custom reset interval between 1 and 365 days using `periodic_reset_days` via the API. You can also specify a `next_usage_reset_at` date (ISO 8601) to control when the first reset occurs
> [!NOTE]
>
> `periodic_reset` and `periodic_reset_days` are mutually exclusive. You cannot set both on the same usage limit.
> The configuration options for workspace budgets and rate limits are the same as other budget and rate limit controls in the Portkey app (for API keys and providers). If you're familiar with those, this will feel identical—just applied at the workspace level.
## Notification System
When workspace limits are approached or reached, Portkey automatically sends notifications to:
* Organization administrators and owners
## Use Cases
Workspace budget limits are particularly useful for:
* **Departmental Allocations**: Assign specific AI budgets to different departments (Marketing, Customer Support, R\&D)
* **Project Management**: Allocate resources based on project priority and requirements
* **Cost Center Tracking**: Monitor and control spending across different cost centers
* **Phased Rollouts**: Gradually increase limits as teams demonstrate value and mature their AI use cases
### Set Workspace Budget and Rate Limits using Portkey Admin API
Use the Admin API to programmatically manage workspace budgets and rate limits.
* The endpoint updates a workspace and accepts both `usage_limits` (budgets) and `rate_limits`.
* Budget limits mirror the app controls: cost- or token-based, optional `alert_threshold`, and optional `periodic_reset` of `weekly` or `monthly`.
* Rate limits support request- or token-based throttling with units `rpm` (per minute), `rph` (per hour), or `rpd` (per day).
```python Python SDK theme={"system"}
from portkey_ai import Portkey
portkey = Portkey(api_key="PORTKEY_API_KEY")
workspace = portkey.admin.workspaces.update(
workspace_id="WORKSPACE_ID",
# Workspace budgets (usage_limits): supports multiple entries
usage_limits=[
{
"type": "cost", # or "tokens"
"credit_limit": 500, # integer >= 1; dollars if type == "cost"
"alert_threshold": 400, # optional; integer >= 1
"periodic_reset": "monthly" # optional; "weekly" | "monthly"
# OR use custom reset days:
# "periodic_reset_days": 14, # 1-365; mutually exclusive with periodic_reset
# "next_usage_reset_at": "2026-03-01T00:00:00Z" # optional; ISO 8601 date for first reset
},
],
# Workspace rate limits: supports multiple entries
rate_limits=[
{
"type": "requests", # or "tokens"
"unit": "rpm", # "rpm" | "rph" | "rpd"
"value": 120 # integer
},
],
)
print(workspace)
```
Learn more here:
> [card] [Portkey Admin API](/docs/api-reference/admin-api/control-plane/workspaces/update-workspace)
>
> Portkey Workspace API documentation
## Availability
Workspace Budget Limits are available to Portkey Enterprise customers and select Pro users. To enable these features for your account, please contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforcing Workspace Level Guardrails
Source: https://docs.portkey.ai/docs/product/administration/enforce-workspace-level-guardials
## Overview
Portkey allows workspace owners to enforce request guardrails at the workspace level. This feature ensures that all API requests made within a workspace comply with predefined policies, enhancing security, compliance, and governance at a more granular level.
## How It Works
Workspace owners can define input and output guardrails in the workspace settings. These guardrails are enforced on all API requests made within the workspace, ensuring uniform policy enforcement across all users and applications in that workspace.
* **Input Guardrails**: Define checks and constraints for incoming LLM requests within the workspace.
* **Output Guardrails**: Ensure LLM responses align with the defined guardrail policies.
The guardrails available here are the ones created within the user's workspace. Users can select any of these as the default input/output guardrails for their workspace. Multiple providers are supported for setting up guardrails. For a detailed list of supported providers and configurations:
> [card] [Guardrails Docs](/docs/product/guardrails)
>
> Learn about the different Guardrails you can set up in Portkey
## Configuration
### Setting Up Workspace-Level Guardrails
1. Head to the Portkey dashboard and navigate to the sidebar.
2. Click on your workspace and select the **Edit (🖊️) option**.
3. In the **Edit Workspace** menu:
* Choose an **Input Guardrail** and **Output Guardrail** from the options (created in the workspace) .
4. Save your changes.
Once configured, these guardrails will be enforced on all API requests within the workspace.
> [!NOTE]
>
> **Best Practices**
>
> * Clearly communicate guardrail requirements to all members in your workspace.
> * Maintain internal documentation on your workspace guardrail policies to ensure consistency.
## Support
For questions about configuring workspace-level guardrails or troubleshooting issues, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enforcing Request Metadata
Source: https://docs.portkey.ai/docs/product/administration/enforcing-request-metadata
## Overview
Portkey allows organisation owners to define mandatory [metadata](/docs/product/observability/metadata) fields that must be included with every API request. This feature enables granular observability across your organisation's LLM usage.
## How It Works
Organisation owners can define JSON schemas specifying required metadata properties for:
* API keys
* Workspaces
These metadata requirements are strictly enforced whenever:
* A new API key is created
* A new workspace is created
> [!NOTE]
>
> Existing API keys and Workspaces will not be affected by the new metadata schema. The new schema will only be enforced on NEW API keys, Workspaces or when existing API keys are updated.
## Configuration
### Setting Up Metadata Requirements
1. Head to `Admin Settings` on the Portkey dashboard
2. Navigate to the `Organisation Properties` section
3. Select either `API Key Metadata Schema` or `Workspace Metadata Schema`
4. Create a [JSON schema](#json-schema-requirements) specifying your required metadata fields
5. Add or modify the metadata schem. Save your changes
## JSON Schema Requirements
The metadata schema follows [JSON Schema draft-07](https://json-schema.org/draft-07) with certain modifications:
### Required Schema Properties
* `"type": "object"` at the top level must always be present
* `"additionalProperties": true` must be present and always set to `true`
* Properties inside the schema must always have `"type": "string"`
| Requirement | Description |
| - | - |
| `"type": "object"` | The top-level schema must be declared as an object |
| `"properties": {...}` | Define the metadata fields and their constraints |
| `"additionalProperties": true` | Additional properties must be allowed |
> [accordion] Basic Schema
>
> ```json theme={"system"}
> {
> "type": "object",
> "properties": {
> "team_id": {
> "type": "string"
> },
> "environment": {
> "type": "string"
> }
> },
> "additionalProperties": true
> }
> ```
> [accordion] Schema With Required Fields
>
> ```json theme={"system"}
> {
> "type": "object",
> "required": ["team_id", "service_id"],
> "properties": {
> "team_id": {
> "type": "string"
> },
> "service_id": {
> "type": "string"
> },
> "environment": {
> "type": "string"
> }
> },
> "additionalProperties": true
> }
> ```
> [accordion] Schema With Default Values
>
> ```json theme={"system"}
> {
> "type": "object",
> "properties": {
> "usertype": {
> "type": "string"
> },
> "environment": {
> "type": "string",
> "default": "dev"
> }
> },
> "additionalProperties": true
> }
> ```
> [accordion] Schema With Enum Values
>
> ```json theme={"system"}
> {
> "type": "object",
> "properties": {
> "use_case": {
> "type": "string",
> "enum": [
> "research",
> "instruction",
> "administrative"
> ]
> }
> },
> "additionalProperties": true
> }
> ```
## Using this Metadata in Portkey
Metadata validation on the schema is enforced on API Key/Workspace creation time.
### When Creating API Keys
When creating a new API key (either Service or User type), you must provide metadata that conforms to the defined schema:
1. Navigate to the API Keys section
2. Click `Create`
3. Fill in the key details
4. In the Metadata field, provide a [JSON schema](#json-schema-requirements) with all required fields
5. If any required fields are missing, you'll receive an error
### When Creating Workspaces
When creating a new workspace, you must provide metadata that conforms to the defined schema:
1. Navigate to Workspaces on the left sidebar
2. Click `+Add Workspace`
3. Fill in the workspace details
4. In the Metadata field, provide a [JSON schema](#json-schema-requirements) with all required fields
5. If any required fields are missing, you'll receive an error
### Default Values
* Properties with default values will be automatically added if not specified
* User-provided values take precedence over default values
## Metadata Precedence Order
When the same key appears at multiple levels, the **precedence order** is:
1. Workspace metadata (highest priority)
2. API key metadata
3. Request metadata (lowest priority)
> [!NOTE]
>
> Please note that before 1.10.20, the precedence order was:
>
> 1. Request metadata (highest priority)
> 2. API key metadata
> 3. Workspace metadata (lowest priority)
> [!NOTE]
>
> Best Practices
>
> * Organisation owners should clearly communicate metadata requirements to all developers
> * Maintain internal documentation of your metadata schema
## Support
For questions about configuring metadata schemas or troubleshooting issues, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enterprise Offering
Source: https://docs.portkey.ai/docs/product/enterprise-offering
> [card] Custom Retention Periods
>
> Set custom retention periods for different users to meet your data storage requirements.
> [card] Budget Limits on Keys
>
> Set monthly or custom budget limits on LLM usage, at provider or Portkey key level.
> [card] Org Management
>
> Organize your teams and entities with more access control in Portkey.
> [card] Custom Rate Limits
>
> Programmatically set rate limits at API key level and prevent abuse.
> [card] Advanced Routing
>
> Route requests based on your custom-defined criteria.
> [card] Data Isolation
>
> Ensure the highest level of data privacy & security with isolated storage infrastructure.
> [card] Compliances & Certificates
>
> Portkey complies with SOC 2, GDPR, ISO27001, HIPAA to meet the most demanding industry standards.
> [card] Custom BAAs
>
> Protect sensitive healthcare data with BAAs tailored to your organization's requirements.
> [card] SSO Integrations
>
> Portkey has seamless integrations with your preferred Single Sign-On (SSO) providers like Okta and Microsoft.
> [card] Export to Data Lakes
>
> Easily export all your data to your preferred data lake for long-term storage.
> [card] Unlimited Prompts
>
> Create & manage unlimited prompt templates on Portkey.
> [card] Unlimited Cache TTL
>
> Leverage unlimited caching with customizable Time-to-Live (TTL) settings.
> [card] Access Rules
>
> Team & individual level RBAC for AI services, LLMs, logs, and more.
> [card] Universal API
>
> Integrate multiple LLM providers and their auth mechanissms (JWT, IAM etc) over a common, unified API.
> [card] Central Guardrails
>
> Deploy org-wide guardrails like PII redaction, company policy adherence, and more across *all* AI calls.
> [card] AI-Native Observability
>
> Purpose-built telemetry & analytics to monitor AI service performance & ensure SLA adherence.
> [card] Executive Reporting
>
> Executive-only dashboards to track AI adoption, ROI, and strategic impact across your organization.
> [card] Audit Logs
>
> System-wide audit trails for all AI services, and all the Portkey features described above.
> [card] KMS Integration
>
> Bring your own encryption keys to Portkey AI to encrypt data at rest.
## Interested? Schedule a Call Below
[https://www.paloaltonetworks.com/ai-security/ai-gateway#:\~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Access Control Management
Source: https://docs.portkey.ai/docs/product/enterprise-offering/access-control-management
With customizable user roles, API key management, and comprehensive audit logs, Portkey provides the flexibility and control needed to ensure secure collaboration & maintain a strong security posture
> [!TIP]
>
> This is a Portkey [**Enterprise**](https://portkey.ai/docs/product/enterprise-offering) plan feature.
At Portkey, we understand the critical importance of access control and data security for enterprise customers. Our platform provides a robust and flexible access control management system that enables you to safeguard your sensitive information while empowering your teams to collaborate effectively.
## 1. Isolated and Customizable Organizations
Portkey's enterprise version allows you to create multiple `organizations`, each serving as a secure and isolated environment for your teams or projects. This multi-tenant architecture ensures that your data, logs, analytics, prompts, integrations, providers, configs, guardrails, and API keys are strictly confined within each `organization`, preventing unauthorized access and maintaining data confidentiality.

With the ability to create and manage multiple organizations, you can tailor access control to match your company's structure and project requirements. Users can be assigned to specific organizations, and they can seamlessly switch between them using Portkey's intuitive user interface.

Organization switcher on the Portkey UI
## 2. Fine-Grained User Roles and Permissions
Portkey offers a comprehensive Role-Based Access Control (RBAC) system that allows you to define and assign user roles with granular permissions. By default, Portkey provides three roles: `Owner`, `Admin`, and `Member`, each with a predefined set of permissions across various features.
* `Owners` have complete control over the organization, including user management, billing, and all platform features.
* `Admins` have elevated privileges, allowing them to manage users, prompts, configs, guardrails, integrations, providers, and API keys.
* `Members` have access to essential features like logs, analytics, prompts, configs, and integrations, providers, with limited permissions.
| Feature | Owner Role | Admin Role | Member Role |
| - | - | - | - |
| Logs and Analytics | View, Filter, Group | View, Filter, Group | View, Filter, Group |
| Prompts | List, View, Create, Update, Delete, Publish | List, View, Create, Update, Delete, Publish | List, View, Create, Update |
| Configs | List, View, Create, Update, Delete | List, View, Create, Update, Delete | List, View, Create, Update, Delete |
| Guardrails | List, View, Create, Update, Delete | List, View, Create, Update, Delete | List, View |
| Integrations | List, Create, Edit, Duplicate, Delete, Copy | List, Create, Edit, Duplicate, Delete, Copy | List, Copy |
| Model Catalog: Providers | List, Create, Edit, Duplicate, Delete, Copy | List, Create, Edit, Duplicate, Delete, Copy | List, Copy |
| Model Catalog: Models | List, Create, Edit, Duplicate, Delete, Copy | List, Create, Edit, Duplicate, Delete, Copy | List, Copy |
| Team | Add users, assign roles | Add users, assign roles | - |
| Organisation | Update | Update | - |
| API Keys (Service) | Create, Edit, Delete, Update, Rotate | Create, Edit, Delete, Update, Rotate | - |
| API Keys (User) | Create, Edit, Delete, Update, Rotate | Create, Edit, Delete, Update, Rotate | Create, Edit, Delete, Update, Rotate (own keys only) |
| MCP Servers | List, View, Create, Update, Delete | List, View, Create, Update, Delete | List, View |
| Agent Servers | List, View, Create, Update, Delete | List, View, Create, Update, Delete | List, View |
| Policies | List, View, Create, Update, Delete | List, View, Create, Update, Delete | List, View |
| Billing | Manage | - | - |
> [!WARNING]
>
> **API Key Privilege Escalation Prevention**: A user cannot modify an API key that carries permissions exceeding their own role. This is a security measure to prevent privilege escalation. If a legacy API key needs updating, an admin should retire it and create a new one with appropriately scoped permissions.
You can easily add team members to your organization and assign them appropriate roles based on their responsibilities. Portkey's user-friendly interface simplifies the process of inviting users and managing their roles, ensuring that the right people have access to the right resources.

Team Management on the Portkey UI
## 3. Secure and Customizable API Key Management
Portkey provides a secure and flexible API key management system that allows you to create and manage multiple API keys with fine-grained permissions. Each API key can be customized to grant specific access levels to different features, such as metrics, completions, prompts, configs, guardrails, integrations, providers, team management, and API key management.
| Feature | Permissions | Default |
| - | - | - |
| Metrics | Disabled, Enabled | Disabled |
| Completions (all LLM calls) | Disabled, Enabled | Enabled |
| Prompts | Disabled, Read, Write, Delete | Read |
| Configs | Disabled, Read, Write, Delete | Disabled |
| Guardrails | Disabled, Read, Write, Delete | Disabled |
| Integrations | Disabled, Read, Write, Delete | Disabled |
| Model Catalog: Providers | Disabled, Read, Write, Delete | Disabled |
| Model Catalog: Models | Disabled, Read, Write, Delete | Disabled |
| Users (Team Management) | Disabled, Read, Write, Delete | Disabled |
By default, a new organization is provisioned with a master API key that has all permissions enabled. Owners and admins can edit and manage these keys, as well as create new API keys with tailored permissions. This granular control enables you to enforce the principle of least privilege, ensuring that each API key has access only to the necessary resources.
Portkey's API key management system provides a secure and auditable way to control access to your organization's data and resources, reducing the risk of unauthorized access and data breaches.
## Audit Logs
Portkey maintains detailed audit logs that capture all administrative activities across the platform. These logs provide visibility into actions related to prompts, configs, guardrails, integrations, providers, team management, organization updates, and API key modifications.
Each log entry includes information about the user, the action performed, the affected resource, and a timestamp. This ensures traceability and accountability, helping teams monitor changes and investigate any unauthorized activity.
Audit logs can be filtered by user, action type, resource, and time range, making it easy to track specific events. Organizations can use this data to enforce security policies, ensure compliance, and maintain operational integrity.

Portkey’s audit logging system provides a clear and structured way to review platform activity, ensuring security and compliance across all operations.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Audit Logs
Source: https://docs.portkey.ai/docs/product/enterprise-offering/audit-logs
Track and monitor all administrative activities across your Portkey organization with comprehensive audit logging.
> [!TIP]
>
> This is a Portkey [**Enterprise**](https://portkey.ai/docs/product/enterprise-offering) plan feature.
## Overview
Audit Logs in Portkey provide a comprehensive record of all administrative activities across your organization. These logs capture detailed information about who performed what actions, on which resources, and when those actions occurred. This level of visibility is crucial for security monitoring, compliance requirements, and troubleshooting operational issues.

## Key Benefits
* **Enhanced Security**: Track all changes to your organization's resources and configurations
* **Compliance Support**: Maintain detailed records to help meet regulatory requirements
* **Operational Visibility**: Understand who is making changes and when
* **Troubleshooting**: Investigate issues by reviewing recent configuration changes
* **Accountability**: Ensure users are responsible for their actions within the platform
## Logged Information
Each audit log entry contains detailed information about administrative activities:
| Field | Description |
| - | - |
| Timestamp | Date and time when the action occurred |
| User | The individual who performed the action |
| Workspace | The workspace context in which the action was performed (if applicable) |
| Action | The type of operation performed (create, update, delete, etc.) |
| Resource | The specific resource or entity that was affected |
| Response Status | HTTP status code indicating the result of the action |
| Client IP | IP address from which the request originated |
| Country | Geographic location associated with the request |
> [!NOTE]
>
> Setting up Audit Logs is straightforward:
>
> 1. Access is available to org owners and admins
> 2. Audit logs are automatically collected across all workspaces
> 3. No additional configuration needed - just enable and go
> 4. Access audit logs through the `Admin Settings` > `Audit Logs` page
## Filtering Capabilities
Portkey provides powerful filtering options to help you find specific audit events quickly:

### Available Filters
* **Method**: Filter by HTTP method (PUT, POST, DELETE)
* **Request ID**: Search for a specific request by its unique identifier
* **Resource Type**: Filter by type of resource affected:
* Workspaces
* API Keys
* Integrations
* Model Catalog
* Configs
* Prompts
* Guardrails
* Integrations
* Collections
* Organization
* Labels
* Custom Resource Types
* **Action**: Filter by the type of action performed:
* Create
* Update
* Delete
* Publish
* Export
* Rotate
* Manage
* Duplicate
* **Response Status**: Filter by HTTP response status codes
* **Workspace**: Filter by specific workspace
* **User**: Filter by the user who performed the action
* **Client IP**: Filter by originating IP address
* **Country**: Filter by geographic location of requests
* **Time Range**: Filter logs within a specific time period
## Enterprise Features
Portkey's Audit Logs include enterprise-grade capabilities:
### 1. Complete Visibility
* Full user attribution for every action
* Detailed timestamps and change history
* Cross-workspace tracking
* Searchable audit trail
### 2. Compliance & Security
* SOC 2, ISO 27001, GDPR, and HIPAA compliant
* PII data protection
* Indefinite log retention
### 3. Enterprise-Grade Features
* Role-based access control
* Cross-organization visibility
* Custom retention policies
> As a Director of AI Infrastructure at a Fortune 100 Healthcare company explained: *"Having a detailed audit trail isn't just about compliance. It's about being able to debug production issues quickly, understand usage patterns, and make data-driven decisions about our AI infrastructure."*
## Related Features
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
>
> Manage user roles and permissions across your organization
> [card] [Organizations](/docs/product/enterprise-offering/org-management/organizations)
>
> Learn about organization structure and management
> [card] [Workspaces](/docs/product/enterprise-offering/org-management/workspaces)
>
> Understand workspace management within your organization
> [card] [API Keys](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
>
> Authentication and authorization with API keys
## Support
For questions about Audit Logs or assistance with interpreting specific entries, contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
> [card] [Schedule a Demo](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
>
> Ready to bring enterprise-grade governance to your AI infrastructure? Learn more about Portkey's Audit Logs and other enterprise features in a personalized demo.
***
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Budget Limits
Source: https://docs.portkey.ai/docs/product/enterprise-offering/budget-limits
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Usage & Rate Limit Policies
Source: https://docs.portkey.ai/docs/product/enterprise-offering/budget-policies
Create fine-grained controls over API usage and rate limits at the workspace level
> [!NOTE]
>
> Available on **Enterprise** Self Hosting plan only.
>
> Requires **1.17.0** or higher version of the Gateway.
Policies allow you to create fine-grained controls over API usage and rate limits at the workspace level. You can define conditions to target specific requests and group usage/rate limits by various dimensions.
## Policy Types
### 1. Usage Limit Policies
Control spend (cost) or token consumption with configurable limits and periodic resets.
### 2. Rate Limit Policies
Control request throughput with requests-per-minute (rpm), requests-per-hour (rph), or requests-per-day (rpd) limits.
***
## Policy Structure
### Conditions
Conditions determine **which requests** a policy applies to. All conditions must match (AND logic). Each condition supports:
| Field | Type | Description |
| - | - | - |
| `key` | string | The dimension to match against |
| `value` | string \| string\[] | Value(s) to match (OR logic for arrays). Use `"*"` for wildcard. |
| `excludes` | string \| string\[] | Value(s) to exclude from matching |
> [!NOTE]
>
> Backend `v1.16.0+` allows updating `conditions` on existing usage-limit and rate-limit policies via the corresponding `PUT` endpoint. Earlier versions only supported updating other fields.
### Supported Condition Keys
| Key | Description | Example Value | Version |
| - | - | - | - |
| `api_key` | Match by API key ID | `"uuid_of_api_key"` | 1.17.0+ |
| `metadata.*` | Match by request metadata | `"metadata._user"` with value `"user123"` | 1.17.0+ |
| `virtual_key` | Match by virtual key slug | `"virtual key slug"` | 2.0.0+ |
| `provider` | Match by provider | `"openai"`, `"anthropic"`, `"azure-openai"` | 2.0.0+ |
| `config` | Match by config slug | `"config slug"` | 2.0.0+ |
| `prompt` | Match by prompt slug | `"prompt slug"` | 2.0.0+ |
| `model` | Match by model (with wildcard support) | `"@openai/gpt-4o"`, `"@anthropic/*"` | 2.0.0+ |
| `endpoint_type` | Match by endpoint type (rate limit policies only) | `"chatComplete"`, `"embed"`, `"imageGenerate"` | 1.13.0+ |
### Group By
Group by determines **how usage/limits are bucketed**. Each unique combination of group\_by values gets its own counter.
> [!NOTE]
>
> When `model` is used as a condition or group\_by key, Portkey uses the **request model name** (the model you sent in the request body) for both matching and bucketing — not the model name returned by the provider in the response. This is important for providers like Azure OpenAI that return versioned model names in responses (e.g. `gpt-4.1-2025-06-01`), which differ from the request model name (e.g. `gpt-4.1`).
**Example:**
```json theme={"system"}
[
{
"key": "api_key"
},
{
"key": "metadata._user"
}
]
```
***
## Authentication
All policy endpoints require authentication using:
* **API Key**: Include in `x-portkey-api-key` header
### Permissions
Policies require the following RBAC permissions:
* `policies:create` - Create policies
* `policies:read` - Read policies
* `policies:update` - Update policies
* `policies:delete` - Delete policies
* `policies:list` - List policies
### Base URL
All policy endpoints are under:
```
/v1/policies
```
***
## Usage Limits Policies
Usage limits policies allow you to set maximum usage (cost or tokens) that can be consumed over a period. When the limit is reached, requests will be blocked until the limit resets.
> [!NOTE]
>
> When a usage limit is exceeded, Portkey returns a **412 Precondition Failed** HTTP status code.
### Alert thresholds: audit logs and notifications
If you set an **`alert_threshold`**, Portkey records when usage crosses that threshold in **[audit logs](/docs/product/enterprise-offering/audit-logs)**. Email and other proactive alerts for threshold crossings are **work in progress**; they are not sent today.
### Policy Types
* **`cost`**: Limit based on total cost (in dollars)
* **`tokens`**: Limit based on total tokens consumed
* **`requests`**: Limit based on total number of requests *(Backend `v1.16.0+`)*
### Parameters
#### `name` (required)
A human-readable name for the policy.
* **Type**: String
* **Max length**: 255 characters
#### `description` (optional)
A description of the policy's purpose.
* **Type**: String (nullable)
* **Max length**: 500 characters
#### `credit_limit` (required)
The maximum usage limit that can be consumed before requests are blocked.
* **Type**: Number (integer or float)
* **Minimum value**:
* For `cost` type: `1` (represents \$1.00)
* For `tokens` type: `100` tokens
* For `requests` type: `1` request
* **Units**:
* For `cost` type: Value is in USD (dollars)
* For `tokens` type: Value is in tokens
* For `requests` type: Value is the number of requests
* **Behaviour**: When the credit limit is reached, all matching requests will be blocked until the limit resets (if `periodic_reset` is configured)
#### `alert_threshold` (optional)
An optional usage level (same units as `credit_limit`) before the limit is fully consumed.
* **Type**: Number (integer or float)
* **Minimum value**: `1`
* **Units**:
* For `cost` type: Value is in USD (dollars)
* For `tokens` type: Value is in tokens
* **Validation**: Must be less than `credit_limit` if provided
* **Behaviour**:
* When usage reaches this threshold, an event is written to [audit logs](/docs/product/enterprise-offering/audit-logs)
* Email and other proactive alerts for threshold crossings are **work in progress** and are not sent today
* Matching requests continue to be allowed until the full `credit_limit` is reached
#### `periodic_reset` (optional)
Configures automatic reset of the usage limit at regular intervals.
* **Type**: String (enum)
* **Valid values**:
* `"weekly"` - Budget limits automatically reset every week
* `"monthly"` - Budget limits automatically reset every month
* Omitted/not provided - No periodic reset (limit applies until exhausted)
* **Reset timing**:
* **Weekly**: Resets occur every Monday at 12:00 AM UTC
* **Monthly**: Resets occur on the 1st calendar day of each month at 12:00 AM UTC
* **Behaviour**: When a reset occurs, the usage counter resets to zero and the limit becomes available again
#### `periodic_reset_days` (optional)
Configures a custom reset cadence in days as an alternative to the calendar-based `periodic_reset`.
* **Type**: Integer (1–365)
* **Behaviour**: The usage counter resets every N days at 00:00 UTC, with the next reset computed from the policy's start date (or `next_usage_reset_at` if provided)
* **Mutually exclusive** with `periodic_reset` — setting both is rejected
#### `next_usage_reset_at` (optional)
Override the timestamp of the next scheduled reset.
* **Type**: ISO 8601 datetime (normalized to UTC midnight)
* **Behaviour**: Sets/overrides the next reset timestamp. Subsequent resets follow the configured `periodic_reset` or `periodic_reset_days` cadence.
### Validation Rules
1. **Conditions**: Each condition must have `key` and `value` fields.
2. **Group By**: Each group must have a `key` field.
3. **Valid Keys**: For both `conditions` and `group_by`, valid keys include `api_key`, `virtual_key`, `provider`, `config`, `prompt`, `model`, or any key starting with `metadata.`. `workspace_id` is supported only in `group_by`.
4. **Alert threshold**: Must be less than `credit_limit` if provided.
5. **Workspace**: Workspace ID is required (can be provided via API key or request body).
6. **Reset cadence**: `periodic_reset` and `periodic_reset_days` are mutually exclusive.
***
## Rate Limits Policies
Rate limits policies allow you to control the rate of requests or tokens consumed per minute, hour, day, or week. When the rate limit is exceeded, requests will be throttled.
> [!NOTE]
>
> When a rate limit is exceeded, Portkey returns a **429 Too Many Requests** HTTP status code.
### Target
Rate limit policies support a `target` field that determines whether the policy applies to LLM requests or MCP tool calls:
* **`llm`** (default) — Applies to LLM API requests
* **`mcp_tools`** — Applies to MCP tool calls through the MCP Gateway
All existing policies default to `target: llm`. The target is **immutable** — it cannot be changed after creation. Archive and recreate the policy if you need a different target.
> [!NOTE]
>
> MCP tool call rate limits require **Gateway v2.18.0+** and **Backend v1.24.0+**.
### Policy Types
* **`requests`**: Limit based on number of requests
* **`tokens`**: Limit based on number of tokens
### Rate Units
* **`rpm`**: Requests/Tokens per minute
* **`rph`**: Requests/Tokens per hour
* **`rpd`**: Requests/Tokens per day
* **`rpw`**: Requests/Tokens per week
### Parameters
#### `name` (required)
A human-readable name for the policy.
* **Type**: String
* **Max length**: 255 characters
#### `description` (optional)
A description of the policy's purpose.
* **Type**: String (nullable)
* **Max length**: 500 characters
#### `target` (optional)
The workload type this policy applies to.
* **Type**: String (enum)
* **Valid values**:
* `"llm"` (default) - Applies to LLM API requests
* `"mcp_tools"` - Applies to MCP tool calls
* **Behaviour**: Determines which condition and group-by keys are valid. Cannot be changed after creation.
#### `type` (required)
The type of rate limit to enforce.
* **Type**: String (enum)
* **Valid values**:
* `"requests"` - Limit based on number of API requests
* `"tokens"` - Limit based on number of tokens consumed
* **Behaviour**: Determines what metric is being rate-limited
#### `unit` (required)
The time interval unit for the rate limit.
* **Type**: String (enum)
* **Valid values**:
* `"rpm"` - Requests/Tokens per minute
* `"rph"` - Requests/Tokens per hour
* `"rpd"` - Requests/Tokens per day
* `"rpw"` - Requests/Tokens per week
* **Behaviour**:
* Defines the time window over which the rate limit is calculated
* Limits reset automatically at the start of each time period
#### `value` (required)
The maximum number of requests or tokens allowed within the specified time unit.
* **Type**: Number (integer)
* **Minimum value**: `1`
* **Units**:
* For `requests` type: Value represents the number of API requests
* For `tokens` type: Value represents the number of tokens
* **Behaviour**: When the rate limit is exceeded, subsequent requests are throttled/rejected until the time period resets
### Supported Condition and Group-By Keys by Target
#### LLM Target (`target: llm`)
| Key | Description | Example Value |
| - | - | - |
| `api_key` | Match by API key ID | `"uuid_of_api_key"` |
| `workspace_id` | Match by workspace ID | `"workspace_uuid"` |
| `metadata.*` | Match by request metadata | `"metadata._user"` with value `"user123"` |
| `virtual_key` | Match by virtual key slug | `"virtual key slug"` |
| `provider` | Match by provider | `"openai"`, `"anthropic"` |
| `config` | Match by config slug | `"config slug"` |
| `prompt` | Match by prompt slug | `"prompt slug"` |
| `model` | Match by model (with wildcard support) | `"@openai/gpt-4o"`, `"@anthropic/*"` |
| `endpoint_type` | Match by endpoint type | `"chatComplete"`, `"embed"`, `"imageGenerate"` |
#### MCP Tools Target (`target: mcp_tools`)
| Key | Description | Example Value |
| - | - | - |
| `api_key` | Match by API key ID | `"uuid_of_api_key"` |
| `workspace_id` | Match by workspace ID | `"workspace_uuid"` |
| `mcp_server` | Match by MCP server slug | `"slack"`, `"github"` |
| `mcp_tool` | Match by tool name | `"send_message"`, `"create_issue"` |
| `metadata.*` | Match by request metadata | `"metadata._user"` with value `"user123"` |
> [!WARNING]
>
> `api_key` is not available in OAuth-based MCP flows, since those requests are authenticated via identity provider tokens and do not carry an API key.
### Validation Rules
1. **Conditions**: Each condition must have `key` and `value` fields.
2. **Group By**: Each group must have a `key` field.
3. **Valid Keys (LLM)**: `api_key`, `virtual_key`, `provider`, `config`, `prompt`, `model`, `endpoint_type`, or any key starting with `metadata.`
4. **Valid Keys (MCP)**: `api_key`, `workspace_id`, `mcp_server`, `mcp_tool`, or any key starting with `metadata.`
5. **Value**: Must be a numeric value.
6. **Workspace**: Workspace ID is required (can be provided via API key or request body).
***
## Use Cases
### Use Case 1: Global Workspace Rate Limit
Limit all requests in a workspace to 1000 requests per minute.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [{"key": "api_key", "value": "*"}],
"group_by": [{"key": "workspace_id"}],
"value": 1000,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 2: Per User Rate Limit
Limit each user (identified by `_user` metadata) to 100 requests per minute.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "metadata._user", "value": "*" }
],
"group_by": [
{ "key": "metadata._user" }
],
"value": 100,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 3: Per User Monthly Spend Budget
Limit each user to \$50/month in API costs.
```json theme={"system"}
{
"type": "usage_limits",
"policy": {
"conditions": [
{ "key": "metadata._user", "value": "*" }
],
"group_by": [
{ "key": "metadata._user" }
],
"credit_limit": 50,
"type": "cost",
"periodic_reset": "monthly",
"status": "active"
}
}
```
***
### Use Case 4: Provider Specific Rate Limit
Limit OpenAI requests to 500 RPM, separate from other providers.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "provider", "value": "openai" }
],
"group_by": [{"key": "workspace_id"}],
"value": 500,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 5: Model Specific Token Rate Limit
Limit GPT-4o to 100,000 tokens per minute.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "model", "value": "@openai/gpt-4o" }
],
"group_by": [{"key": "workspace_id"}],
"value": 100000,
"type": "tokens",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 6: Limit All Models from a Provider (Wildcard)
Limit all Anthropic models to 50,000 tokens per minute.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "model", "value": "@anthropic/*" }
],
"group_by": [{ "key": "provider" }],
"value": 50000,
"type": "tokens",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 7: Per AI Provider Weekly Budget
Track and limit spend per AI Provider to \$100/week.
```json theme={"system"}
{
"type": "usage_limits",
"policy": {
"conditions": [
{ "key": "virtual_key", "value": "*" }
],
"group_by": [
{ "key": "virtual_key" }
],
"credit_limit": 100,
"type": "cost",
"periodic_reset": "weekly",
"status": "active"
}
}
```
***
### Use Case 8: Config Specific Rate Limit
Limit requests using a specific gateway config to 200 RPM.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "config", "value": "production-config" }
],
"group_by": [{"key": "config"}],
"value": 200,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 9: Prompt Specific Usage Budget
Limit a specific prompt template to 1 million tokens per month.
```json theme={"system"}
{
"type": "usage_limits",
"policy": {
"conditions": [
{ "key": "prompt", "value": "customer-support-v2" }
],
"group_by": [ { "key": "prompt"}],
"credit_limit": 1000000,
"type": "tokens",
"periodic_reset": "monthly",
"status": "active"
}
}
```
***
### Use Case 10: Multiple Allowed Values (OR Logic)
Allow only specific API keys to use expensive models, with a combined rate limit.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "api_key", "value": ["pk_premium_1", "pk_premium_2", "pk_premium_3"] },
{ "key": "model", "value": ["@openai/gpt-4o", "@anthropic/claude-3-5-sonnet-20241022"] }
],
"group_by": [{ "key": "api_key"}],
"value": 100,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 11: Exclude Specific Models
Apply rate limit to all OpenAI models EXCEPT GPT-4o.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "model", "value": "@openai/*", "excludes": "@openai/gpt-4o" }
],
"group_by": [ { "key": "model"} ],
"value": 1000,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 12: Per User, Per Model Budget
Track spend separately for each user AND model combination.
```json theme={"system"}
{
"type": "usage_limits",
"policy": {
"conditions": [
{ "key": "metadata._user", "value": "*" }
],
"group_by": [
{ "key": "metadata._user" },
{ "key": "model" }
],
"credit_limit": 10,
"type": "cost",
"periodic_reset": "monthly",
"status": "active"
}
}
```
***
### Use Case 13: Team Based Provider Quota
Limit each team (from metadata) to specific token quotas per provider.
```json theme={"system"}
{
"type": "usage_limits",
"policy": {
"conditions": [
{ "key": "metadata._team", "value": "*" }
],
"group_by": [
{ "key": "metadata._team" },
{ "key": "provider" }
],
"credit_limit": 500000,
"type": "tokens",
"periodic_reset": "weekly",
"status": "active"
}
}
```
***
### Use Case 14: Exclude Internal API Keys from Limits
Apply rate limits to all API keys except internal ones.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "api_key", "value": "*", "excludes": ["pk_internal_1", "pk_internal_2"] }
],
"group_by": [
{ "key": "api_key" }
],
"value": 50,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 15: Combined Conditions - Premium Users on Specific Models
Rate limit premium tier users only when using expensive models.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"conditions": [
{ "key": "metadata._tier", "value": "premium" },
{ "key": "model", "value": ["@openai/gpt-4o", "@openai/o1-preview", "@anthropic/claude-3-5-sonnet-20241022"] }
],
"group_by": [
{ "key": "metadata._user" }
],
"value": 500,
"type": "requests",
"unit": "rph",
"status": "active"
}
}
```
***
### Use Case 16: Global MCP Rate Limit
Limit all MCP tool calls in a workspace to 500 requests per minute.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"target": "mcp_tools",
"conditions": [{"key": "api_key", "value": "*"}],
"group_by": [{"key": "workspace_id"}],
"value": 500,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 17: Per-User MCP Rate Limit
Limit each user to 50 MCP tool calls per minute using metadata.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"target": "mcp_tools",
"conditions": [
{ "key": "metadata._user", "value": "*" }
],
"group_by": [
{ "key": "metadata._user" }
],
"value": 50,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 18: Per-Server Token Limit
Limit token consumption on the GitHub MCP server to 500,000 tokens per day.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"target": "mcp_tools",
"conditions": [
{ "key": "mcp_server", "value": "github" }
],
"value": 500000,
"type": "tokens",
"unit": "tpd",
"status": "active"
}
}
```
***
### Use Case 19: Per-API-Key Limits Grouped by MCP Server
Give each API key its own rate limit, tracked independently per MCP server.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"target": "mcp_tools",
"conditions": [
{ "key": "api_key", "value": "*" }
],
"group_by": [
{ "key": "api_key" },
{ "key": "mcp_server" }
],
"value": 100,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
### Use Case 20: Exclude Specific Tools from a Server Limit
Apply rate limit to all Slack MCP tools except `list_channels`.
```json theme={"system"}
{
"type": "rate_limits",
"policy": {
"target": "mcp_tools",
"conditions": [
{ "key": "mcp_server", "value": "slack" },
{ "key": "mcp_tool", "value": "*", "excludes": "list_channels" }
],
"value": 200,
"type": "requests",
"unit": "rpm",
"status": "active"
}
}
```
***
## Per-Entity Usage Reset
You can reset the usage counter for a specific entity within a usage limit policy. This is useful when you need to manually reset a user's or team's consumed budget before the automatic periodic reset.
### Step 1: List Entities
First, find the entity ID by listing all entities for a policy:
```
GET https://api.portkey.ai/v1/policies/usage-limits/{policyId}/entities?page_size=50
```
**Headers:**
```
x-portkey-api-key: YOUR_ADMIN_API_KEY
```
This returns entities with their `id`, `value_key` (e.g. `metadata._user:username`), and `current_usage`. Use the `search` query param to filter results.
### Step 2: Reset Entity Usage
Once you have the entity ID, reset its usage:
```
PUT https://api.portkey.ai/v1/policies/usage-limits/{policyId}/entities/{entityId}/reset
```
**Headers:**
```
x-portkey-api-key: YOUR_ADMIN_API_KEY
```
This resets the entity's usage counter to zero, allowing it to consume the full credit limit again.
***
## Important Notes
1. **Condition Matching**: All conditions must match (AND). Within a condition, multiple values use OR logic.
2. **Model Format**: Models are specified as `@provider/model-name`. Use `@provider/*` for wildcard matching. Both condition matching and group\_by bucketing use the **request model name** passed, not the provider's response model name.
3. **Metadata Keys**: Use `metadata.` prefix followed by your metadata key name (e.g., `metadata._user`, `metadata._team`).
4. **Periodic Reset Options**: `"weekly"`, `"monthly"`, or `null` for no reset.
5. **Rate Limit Units**: `"rpm"` (per minute), `"rph"` (per hour), `"rpd"` (per day), `"rpw"` (per week).
6. **Usage Limit Types**: `"cost"` (in dollars), `"tokens"`, or `"requests"` (Backend `v1.16.0+`).
***
## API Reference
For detailed API documentation, see the following endpoints:
### Usage Limits Policies
> [card] [Create Usage Limits Policy](/docs/api-reference/admin-api/control-plane/policies/usage-limits/create-usage-limits-policy)
> [card] [List Usage Limits Policies](/docs/api-reference/admin-api/control-plane/policies/usage-limits/list-usage-limits-policy)
> [card] [Retrieve Usage Limits Policy](/docs/api-reference/admin-api/control-plane/policies/usage-limits/retrieve-usage-limits-policy)
> [card] [Update Usage Limits Policy](/docs/api-reference/admin-api/control-plane/policies/usage-limits/update-usage-limits-policy)
> [card] [Delete Usage Limits Policy](/docs/api-reference/admin-api/control-plane/policies/usage-limits/delete-usage-limits-policy)
> [card] [List Usage Limits Policy Entities](/docs/api-reference/admin-api/control-plane/policies/usage-limits/list-usage-limits-policy-entities)
> [card] [Reset Usage Limits Policy Entity](/docs/api-reference/admin-api/control-plane/policies/usage-limits/reset-usage-limits-policy-entity)
### Rate Limits Policies
> [card] [Create Rate Limits Policy](/docs/api-reference/admin-api/control-plane/policies/rate-limits/create-rate-limits-policy)
> [card] [List Rate Limits Policies](/docs/api-reference/admin-api/control-plane/policies/rate-limits/list-rate-limits-policy)
> [card] [Retrieve Rate Limits Policy](/docs/api-reference/admin-api/control-plane/policies/rate-limits/retrieve-rate-limits-policy)
> [card] [Update Rate Limits Policy](/docs/api-reference/admin-api/control-plane/policies/rate-limits/update-rate-limits-policy)
> [card] [Delete Rate Limits Policy](/docs/api-reference/admin-api/control-plane/policies/rate-limits/delete-rate-limits-policy)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enterprise Components
Source: https://docs.portkey.ai/docs/product/enterprise-offering/components
Portkey's Enterprise Components provide the core infrastructure needed for production deployments. Each component handles a specific function - analytics, logging, or caching - with multiple implementation options to match your requirements.
***
## Analytics Store
Portkey leverages Clickhouse as the primary Analytics Store for the Control Panel, offering powerful capabilities for handling large-scale analytical workloads.
> [card] [Clickhouse](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#analytics-store)
> [!NOTE]
>
> Portkey supports exporting your Clickhouse analytics data to OpenTelemetry (OTel) compatible collectors, allowing you to integrate Portkey's analytics with your existing observability infrastructure.
***
## Log Store
Portkey provides flexible options for storing and managing logs in your enterprise deployment. Choose from various storage solutions including MongoDB for document-based storage, AWS S3 for cloud-native object storage, or Wasabi for cost-effective cloud storage. Each option offers different benefits in terms of scalability, cost, and integration capabilities.
> [card] [MongoDB](/docs/integrations/libraries/mongodb)
> [card] [AWS S3](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#log-storage)
> [card] [Wasabi](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#log-storage)
### Log Object Path Format
Configure how log files are organized in your blob storage using the `LOG_STORE_FILE_PATH_FORMAT` environment variable.
| Value | Format | Example Path |
| - | - | - |
| `v1` (default) | Flat structure | `30//.json` |
| `v2` | Time-hierarchical | `30///////.json` |
The `v2` format organizes logs by time hierarchy, making it easier to manage retention policies and query logs for specific time periods.
> [!NOTE]
>
> Changing `LOG_STORE_FILE_PATH_FORMAT` only affects newly written logs. Previously written logs retain their original path format and are not migrated.
> [!NOTE]
>
> The `v2` format is not supported for air-gapped deployments where `LOG_STORE` is set to `control_plane`.
***
## Cache Store
Portkey supports robust caching solutions to optimize performance and reduce latency in your enterprise deployment. Choose between Redis for in-memory caching or AWS ElastiCache for a fully managed caching service.
> [card] [Redis](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#cache-store)
> [card] [AWS ElastiCache](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#cache-store)
> [card] [Azure Cache for Redis](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#cache-store)
> [card] [GCP Memorystore](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#cache-store)
## Semantic Cache Store
Semantic caching stores embeddings in a vector database (**Milvus** or **Pinecone**) so similar prompts can reuse LLM responses. Embedding provider settings, vector store environment variables, and provider-specific setup (collection schema for Milvus, index naming and metric for Pinecone) are documented in **[Cache (Simple & Semantic)](/docs/product/ai-gateway/cache-simple-and-semantic#set-up-semantic-caching-self-hosted)** under *Set up semantic caching (self-hosted)*.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# KMS Integration
Source: https://docs.portkey.ai/docs/product/enterprise-offering/kms
Customers can bring their own encryption keys to Portkey AI to encrypt data at storage.
This document outlines how customers can bring their own encryption keys to Portkey AI to encrypt data at storage.
## Overview
Portkey AI supports integration with Key Management Services (KMS) to encrypt data at storage. This integration allows customers to manage their encryption keys and data protection policies through their existing KMS infrastructure.
## Supported KMS Providers
Portkey AI supports integration with the following KMS providers:
* AWS KMS
### Encryption Methodology
Envelope encryption is used to encrypt data at storage. The data is encrypted with a key that is stored in the KMS provider.
```mermaid theme={"system"}
sequenceDiagram
participant Application
participant AWS_KMS as AWS KMS (CMK)
participant Encrypted_Storage
Application->>AWS_KMS: Request DEK (GenerateDataKey)
AWS_KMS-->>Application: Returns Plaintext DEK + Encrypted DEK
Application->>Encrypted_Storage: Encrypt Data with DEK
Application->>Encrypted_Storage: Store Encrypted Data + Encrypted DEK
Application->>AWS_KMS: Decrypt Encrypted DEK
AWS_KMS-->>Application: Returns Plaintext DEK
Application->>Application: Decrypt Data using DEK
```
### Encrypted Fields
* Configs
* Full template
* LLM Integrations
* Auth Key
* Auth Configuration
* Prompts
* Full Template
* Prompt Partials
* Full Template
* Guardrails
* Checks
* Actions
* Integrations/Plugins
* Auth Credentials/Keys
* SSO/OAuth
* Client Secret
* Auth Settings
### Integration Steps:
Integrating with a KMS provider requires the following steps:
1. Create a KMS key in your KMS provider.
2. Update the key policy to allow Portkey AI to access the key.
3. Share the ARN of the key with the Portkey AI team.
For AWS KMS, the Portkey Account ARN is:
```sh Portkey Account ARN theme={"system"}
arn:aws:iam::299329113195:role/EnterpriseKMSPolicy
```
> [!NOTE]
>
> The above ARN only works when control plane is hosted on [hosted app](https://app.portkey.ai/).\\
>
> To enable KMS for AWS in your Portkey Enterprise self hosted control plane deployment. Please reach out to your Portkey representative or contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
## AWS KMS Key Creation Guide
1. Go to **Key Management Service (KMS)** in the AWS console and navigate to **Customer Managed Keys**.
2. Click on **Create Key**.
3. Select:
* **Key Type**: Symmetric
* **Key Usage**: Encrypt and Decrypt
4. Name the key according to your criteria.
5. Define key administrative permissions according to your criteria.
6. Define key usage permissions according to your criteria.
7. Once created, update the **Key Policy** with the following policy:
```json theme={"system"}
{
"Version": "2012-10-17",
"Id": "key-consolepolicy-3",
"Statement": [
{
"Sid": "Allow use of the key",
"Effect": "Allow",
"Principal": {
"AWS": "arn:aws:iam::299329113195:role/EnterpriseKMSPolicy"
},
"Action": [
"kms:Encrypt",
"kms:Decrypt",
"kms:ReEncrypt*",
"kms:GenerateDataKey*",
"kms:DescribeKey"
],
"Resource": "*"
}
]
}
```
8. Update the Key Arn in Portkey AI Admin Settings.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Logs Export
Source: https://docs.portkey.ai/docs/product/enterprise-offering/logs-export
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Org Management
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management
A high-level introduction to Portkey's organization management structure and key concepts.
Portkey's organization management structure provides a hierarchical system for managing teams, resources, and access within your AI development environment. This structure is designed to offer flexibility and security for enterprises of various sizes.
The account hierarchy in Portkey is organized as follows:

This hierarchy allows for efficient management of resources and access control across your organization. At the top level, you have your Account, which can contain one or more Organizations. Each Organization can have multiple Workspaces, providing a way to separate teams, projects, or departments within your company.
> [!NOTE]
>
> **Workspaces** is currently a feature only enabled on the **Enterprise Plans**. If you're looking to add this feature to your organisation, please reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form)
Organizations contain User Invites & Users, Admin API Keys, and Workspaces. Workspaces, in turn, have their own Team structure (with Managers and Members), Workspace API Keys, and various features like Integrations, Model Catalog, Configs, Prompts, and more.
This structure enables you to:
* Maintain overall control at the Organization level
* Delegate responsibilities and access at the Workspace level
* Ensure data separation and project scoping
* Manage teams efficiently across different projects or departments
> [card] [Organizations](/docs/product/enterprise-offering/org-management/organizations)
> [card] [Workspaces](/docs/portkey-endpoints/admin/workspaces)
> [card] [User Roles & Permissions](/docs/product/enterprise-offering/org-management/user-roles-and-permissions)
> [card] [API Keys (AuthN and AuthZ)](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# API Key Rotation
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/api-key-rotation
Periodically replace API key secrets without downtime using manual or automatic rotation with configurable transition periods.
> [!NOTE]
>
> **Availability:** API key rotation is available on **all plans** (Free, Growth, and Enterprise) on Portkey Cloud.
>
> For self-hosted deployments:
>
> * **Airgapped:** Backend `v1.14.0+`
> * **Hybrid:** Gateway Enterprise `v2.5.0+`
> [!WARNING]
>
> Most older versions are compatible, but there are known edge cases around cache invalidation during the transition window. We recommend upgrading to the versions above for full support.
## Overview
API Key Rotation enables you to replace API key secrets without causing service disruption.
When a key is rotated:
* A new secret is generated immediately.
* The previous secret remains valid for a configurable **transition period**, allowing time to update existing integrations.
* After the transition period ends, the old secret is automatically revoked.
You can initiate rotation:
* **Manually**, on demand
* **Automatically**, using a defined schedule
**Key Characteristics**
* The **API key ID remains unchanged** during rotation.
* Only the **secret value is updated**.
* Existing usage data, such as budget tracking, cost attribution, and analytics - continues to be associated with the same key.
## Key Concepts
| Concept | Description |
| - | - |
| **Rotation** | Replaces the current API key secret with a newly generated secret |
| **Transition Period** | A configurable window during which both the previous and new secrets remain valid (minimum and default: 30 minutes) |
| **Rotation Policy** | A per-key configuration that defines when automatic rotation occurs |
| **Key Version** | A previous secret retained temporarily during the transition period |
## How Rotation Works
1. A new API key secret is generated.
2. The current secret is retained as a **previous version**, with a `key_transition_expires_at` timestamp.
3. The API key is updated with the new secret, and `last_rotated_at` is recorded.
4. The new secret becomes immediately valid for authentication.
5. If a `rotation_period` is configured, `next_rotation_at` is recalculated for the next cycle.
**During the transition window**
* Both the **previous** and **current** secrets are accepted.
* Requests authenticated with either secret resolve to the same API key.
## Transition Window Lifecycle
```mermaid theme={"system"}
flowchart TD
A[Rotation triggered] --> B[New secret issued]
A --> C[Transition window starts]
C --> D[Old secret valid]
C --> E[New secret active]
D --> G[24h before expiry: warning sent]
G --> H[Transition ends]
H --> I[Old secret expires]
H --> J[Only new secret valid]
```
## Rotation Modes
### Manual Rotation
Triggered via API call. The caller receives the new key in the response.
**Endpoint:** [`POST /v2/api-keys/:apiKeyId/rotate`](/docs/api-reference/admin-api/control-plane/api-keys/rotate-api-key)
**Request body (optional):**
```json theme={"system"}
{
"key_transition_period_ms": 3600000
}
```
* `key_transition_period_ms` — overrides the policy/default transition period for this rotation. Minimum: `1800000` (30 min).
**Response:**
```json theme={"system"}
{
"id": "",
"key": "",
"key_transition_expires_at": "2026-04-08T12:30:00.000Z"
}
```
**Constraints:**
* Cannot rotate if a previous version is still in transition. Wait for the transition to expire first.
* If a rotation policy with `rotation_period` exists, the transition period must be shorter than the rotation period.
**Required scope:** `*.rotate` (e.g., `organisation-service-api-keys.rotate`, `workspace-user-api-keys.rotate`)
### Automatic Rotation
Automatic rotation is handled by a background worker that runs on a recurring schedule. On each run, the worker executes the following phases in order:
| Phase | Description |
| - | - |
| **Expire old versions** | Marks key versions whose transition window has ended as `EXPIRED`, making them unusable |
| **Rotate due keys** | Rotates keys that have reached their scheduled rotation time, issuing a new secret and updating the next rotation timestamp |
| **Transition expiry warnings** | Sends notifications for key versions that will expire within the next 24 hours |
| **Upcoming rotation warnings** | Sends notifications for keys scheduled to rotate within the next 24 hours |
## Rotation Policy Configuration
A rotation policy can be attached to any API key at [**creation**](/docs/api-reference/admin-api/control-plane/api-keys/create-api-key) or via [**update**](/docs/api-reference/admin-api/control-plane/api-keys/update-api-key).
| Field | Type | Required | Description |
| - | - | - | - |
| `rotation_period` | `"weekly"` \| `"monthly"` | One of `rotation_period`, `rotation_period_days`, or `next_rotation_at` | Recurring schedule. Weekly rotates every Monday 00:00 UTC; monthly rotates on the 1st of each month 00:00 UTC |
| `rotation_period_days` | integer (1–365) | One of `rotation_period`, `rotation_period_days`, or `next_rotation_at` | Custom rotation cadence in days. Mutually exclusive with `rotation_period`. *(Backend `v1.16.0+`)* |
| `next_rotation_at` | ISO 8601 datetime | One of `rotation_period`, `rotation_period_days`, or `next_rotation_at` | Explicit one-time or override date for the next rotation (normalized to UTC midnight) |
| `key_transition_period_ms` | integer (ms) | No | How long the old key stays valid after rotation. Min: `1800000` (30 min). Default: `1800000` |
> [!NOTE]
>
> * `key_transition_period_ms` must be strictly less than the rotation period duration.
> * If both `rotation_period` and `next_rotation_at` are provided,
> `next_rotation_at` takes precedence for the upcoming rotation.
> * Subsequent rotations follow the `rotation_period`.
**Setting a policy on create:**
```json theme={"system"}
{
"name": "Production Key",
"scopes": ["completions.write"],
"rotation_policy": {
"rotation_period": "monthly",
"key_transition_period_ms": 86400000
}
}
```
**Updating a policy:**
```json theme={"system"}
{
"rotation_policy": {
"rotation_period": "weekly"
}
}
```
**Removing a policy:** Set `rotation_policy` to `null` in the update request.
## Organisation-Enforced Rotation Period
Organisation owners/admins can enforce a rotation cadence on workspace-user API keys via the `user_api_key_rotation_period` setting (with optional per-workspace override). The setting accepts an integer between `1` and `365` (days). *(Backend `v1.17.0+` stores and returns days only; `weekly`/`monthly` input is normalized to `7`/`30`.)*
When set, newly-created workspace-user keys without a rotation policy automatically get the enforced cadence, and any explicit `rotation_period` / `rotation_period_days` that differs from the enforced value is rejected at create/update time. **`next_rotation_at`** cannot be manually changed on API key update while enforcement is active.
## Email Notifications
These notifications are triggered during automatic rotation runs.:
| Email | Trigger | Subject |
| - | - | - |
| **Rotation Alert** | Immediately after auto-rotation | "Action Required: API Key Rotated" |
| **Transition Expiry Warning** | Old key version expires within 24 hours | "Reminder: Old API Key Expiring Soon" |
| **Upcoming Rotation Warning** | Key scheduled to auto-rotate within 24 hours | "Reminder: API Key Scheduled for Rotation" |
**Recipients:** Organisation admins and owners, the key's owning user (for workspace-user keys), and any custom addresses in `alert_emails`.
## Reading Rotation State
[`GET /v2/api-keys/:apiKeyId`](/docs/api-reference/admin-api/control-plane/api-keys/retrieve-an-api-key) returns the rotation policy alongside the key details:
```json theme={"system"}
{
"id": "...",
"name": "Production Key",
"key": "...",
"rotation_policy": {
"rotation_period": "monthly",
"next_rotation_at": "2026-05-01T00:00:00.000Z",
"key_transition_period_ms": 1800000,
"status": "ACTIVE"
}
}
```
## Permissions & Authorization
| Action | Required Scope Pattern |
| - | - |
| Configure rotation policy | `*.update` (same as editing the API key) |
| Trigger manual rotation | `*.rotate` |
| View rotation policy | `*.read` (same as reading the API key) |
Admins (org admin/owner, workspace admin/manager) can rotate any key within their scope. Non-admins can only rotate their own keys.
## Constraints & Limits
* A maximum of **two active secrets** can exist per API key at any time:
* The current secret
* One previous secret within its transition window
* Rotation is **blocked while a transition is active** (i.e., until the previous secret expires)
* `key_transition_period_ms`:
* Minimum: **30 minutes** (`1800000` ms)
* Must be **strictly less than** the configured rotation period
* Supported `rotation_period` values:
* `weekly`
* `monthly`
* `rotation_period_days` (Backend `v1.16.0+`) accepts an integer between `1` and `365`. Mutually exclusive with `rotation_period`.
* `next_rotation_at` is always normalized to **UTC midnight** for consistency across schedules
## Audit Logging
Every rotation (manual and automatic) produces an audit log entry containing:
| Field | Value |
| - | - |
| `api_key_id` | The rotated key's ID |
| `rotation_mode` | `"manual"` or `"auto"` |
| `old_key_masked` | Masked version of the old key for traceability |
| `transition_expires_at` | When the old key stops working |
## Notes
* Automatic rotation phases are executed sequentially within a single run.
* A single run may process multiple keys across different phases.
* Notifications are advisory and do not affect key validity.
## Related
> [card] [Rotate API Key](/docs/api-reference/admin-api/control-plane/api-keys/rotate-api-key)
> [card] [Create API Key](/docs/api-reference/admin-api/control-plane/api-keys/create-api-key)
> [card] [Update API Key](/docs/api-reference/admin-api/control-plane/api-keys/update-api-key)
> [card] [Retrieve API Key](/docs/api-reference/admin-api/control-plane/api-keys/retrieve-an-api-key)
> [card] [API Keys (AuthN & AuthZ)](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
> [card] [User Roles & Permissions](/docs/product/enterprise-offering/org-management/user-roles-and-permissions)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# API Keys (AuthN and AuthZ)
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz
Discover how Admin and Workspace API Keys are used to manage access and operations in Portkey.
## API Keys
Portkey uses two types of API keys to manage access to resources and operations: **Admin API Keys** and **Workspace API Keys**. These keys play crucial roles in authenticating and authorizing various operations within your [organization](/docs/product/enterprise-offering/org-management/organizations) and [workspaces](/docs/api-reference/admin-api/control-plane/workspaces/create-workspace).
### Admin API Keys
Admin API Keys operate at the organization level and provide broad access across all workspaces within an organization.
Key features of Admin API Keys:
* Created and managed by organization owners and admins
* Provide access to organization-wide operations
* Can perform actions across all workspaces in the organization
* Used for administrative tasks and integrations that require broad access
* When making updates to entities, can specify a workspace\_id to target specific workspaces
Admin API Keys should be carefully managed and their use should be limited to necessary administrative operations due to their broad scope of access.
#### Admin API Key Permission Scopes
> [accordion] Organization Management
>
> | Scope | Description |
> | - | - |
> | `organisation_users.create` | Create new users in the organization |
> | `organisation_users.read` | View organization user details |
> | `organisation_users.update` | Modify organization user settings |
> | `organisation_users.delete` | Remove users from the organization |
> | `organisation_users.list` | List all organization users |
> | `organisation_service_api_keys.create` | Create new organization service API keys |
> | `organisation_service_api_keys.update` | Modify organization service API keys |
> | `organisation_service_api_keys.read` | View organization service API key details |
> | `organisation_service_api_keys.delete` | Delete organization service API keys |
> | `organisation_service_api_keys.list` | List all organization service API keys |
> | `organisation_service_api_keys.rotate` | Regenerate organization service API keys |
> | `organisation_settings.read` | View organisation settings, defaults, workspace overrides, and properties |
> | `organisation_settings.update` | Modify organisation settings, defaults, workspace overrides, and properties |
> | `organisation_guardrails.create` | Create organisation-level guardrails |
> | `organisation_guardrails.read` | View organisation guardrail details |
> | `organisation_guardrails.update` | Modify organisation guardrails |
> | `organisation_guardrails.delete` | Remove organisation guardrails |
> | `organisation_guardrails.list` | List organisation guardrails |
> | `organisation_exclusions.update` | Exempt workspaces from [organisation-level guardrails](/docs/product/administration/enforce-orgnization-level-guardrails#excluding-workspaces) |
> | `organisation_exclusions.list` | List workspaces exempted from organisation-level guardrails |
> | `audit_logs.list` | Access system-wide audit logs |
> | `plugins.create` | Create plugins |
> | `plugins.update` | Update plugins |
> | `plugins.list` | List plugins |
> | `deployments.create` | Create new deployments |
> | `deployments.read` | View deployment details |
> | `deployments.update` | Modify deployment settings |
> | `deployments.delete` | Remove deployments |
> | `deployments.list` | List deployments |
> | `secret_references.create` | Create new secret references |
> | `secret_references.read` | View secret reference details |
> | `secret_references.update` | Modify secret references |
> | `secret_references.delete` | Delete secret references |
> | `secret_references.list` | List secret references |
> [accordion] Workspace Management
>
> | Scope | Description |
> | - | - |
> | `workspaces.create` | Create new workspaces |
> | `workspaces.read` | View workspace details |
> | `workspaces.update` | Modify workspace settings |
> | `workspaces.delete` | Delete workspaces |
> | `workspaces.list` | List all workspaces |
> | `workspace_service_api_keys.create` | Create new workspace service API keys |
> | `workspace_service_api_keys.update` | Modify workspace service API keys |
> | `workspace_service_api_keys.read` | View workspace service API key details |
> | `workspace_service_api_keys.delete` | Delete workspace service API keys |
> | `workspace_service_api_keys.list` | List all workspace service API keys |
> | `workspace_service_api_keys.rotate` | Regenerate workspace service API keys |
> | `workspace_user_api_keys.create` | Create new workspace user API keys |
> | `workspace_user_api_keys.update` | Modify workspace user API keys |
> | `workspace_user_api_keys.read` | View workspace user API key details |
> | `workspace_user_api_keys.delete` | Delete workspace user API keys |
> | `workspace_user_api_keys.list` | List all workspace user API keys |
> | `workspace_user_api_keys.rotate` | Regenerate workspace user API keys |
> | `workspace_users.create` | Create new workspace users |
> | `workspace_users.read` | View workspace user details |
> | `workspace_users.update` | Update workspace user settings |
> | `workspace_users.delete` | Remove users from workspace |
> | `workspace_users.list` | List workspace users |
> [accordion] Resource Management
>
> | Scope | Description |
> | - | - |
> | `prompts.create` | Create new prompt templates |
> | `prompts.read` | View prompt template details |
> | `prompts.update` | Modify existing prompt templates |
> | `prompts.delete` | Delete prompt templates |
> | `prompts.list` | List available prompt templates |
> | `prompts.publish` | Publish prompt templates |
> | `configs.create` | Create new configurations |
> | `configs.update` | Update existing configurations |
> | `configs.delete` | Delete configurations |
> | `configs.read` | View configuration details |
> | `configs.list` | List available configurations |
> | `guardrails.create` | Create new guardrails |
> | `guardrails.read` | View guardrail details |
> | `guardrails.update` | Modify existing guardrails |
> | `guardrails.delete` | Delete guardrails |
> | `guardrails.list` | List available guardrails |
> | `virtual_keys.create` | Create new virtual keys |
> | `virtual_keys.read` | View virtual key details |
> | `virtual_keys.update` | Modify existing virtual keys |
> | `virtual_keys.delete` | Delete virtual keys |
> | `virtual_keys.list` | List available virtual keys |
> | `virtual_keys.duplicate` | Duplicate virtual keys |
> | `virtual_keys.copy` | Copy virtual keys |
> | `providers.create` | Create new providers |
> | `providers.read` | View provider details |
> | `providers.update` | Update existing providers |
> | `providers.delete` | Delete providers |
> | `providers.list` | List available providers |
> | `policies.create` | Create policies |
> | `policies.read` | View policy details |
> | `policies.update` | Update policies |
> | `policies.delete` | Delete policies |
> | `policies.list` | List policies |
> [accordion] Integrations
>
> | Scope | Description |
> | - | - |
> | `organisation_integrations.create` | Create organisation-level integrations |
> | `organisation_integrations.read` | View organisation integration details |
> | `organisation_integrations.update` | Update organisation integrations |
> | `organisation_integrations.delete` | Delete organisation integrations |
> | `organisation_integrations.list` | List organisation integrations |
> | `organisation_mcp_integrations.create` | Create organisation MCP integrations |
> | `organisation_mcp_integrations.read` | View organisation MCP integration details |
> | `organisation_mcp_integrations.update` | Update organisation MCP integrations |
> | `organisation_mcp_integrations.delete` | Delete organisation MCP integrations |
> | `organisation_mcp_integrations.list` | List organisation MCP integrations |
> | `organisation_agent_integrations.create` | Create organisation agent integrations |
> | `organisation_agent_integrations.read` | View organisation agent integration details |
> | `organisation_agent_integrations.update` | Update organisation agent integrations |
> | `organisation_agent_integrations.delete` | Delete organisation agent integrations |
> | `organisation_agent_integrations.list` | List organisation agent integrations |
> | `workspace_integrations.create` | Create workspace integrations |
> | `workspace_integrations.read` | View workspace integration details |
> | `workspace_integrations.update` | Update workspace integrations |
> | `workspace_integrations.delete` | Delete workspace integrations |
> | `workspace_integrations.list` | List workspace integrations |
> | `workspace_mcp_integrations.create` | Create workspace MCP integrations |
> | `workspace_mcp_integrations.read` | View workspace MCP integration details |
> | `workspace_mcp_integrations.update` | Update workspace MCP integrations |
> | `workspace_mcp_integrations.delete` | Delete workspace MCP integrations |
> | `workspace_mcp_integrations.list` | List workspace MCP integrations |
> | `workspace_agent_integrations.create` | Create workspace agent integrations |
> | `workspace_agent_integrations.read` | View workspace agent integration details |
> | `workspace_agent_integrations.update` | Update workspace agent integrations |
> | `workspace_agent_integrations.delete` | Delete workspace agent integrations |
> | `workspace_agent_integrations.list` | List workspace agent integrations |
> [accordion] AI & Agent Gateway
>
> | Scope | Description |
> | - | - |
> | `agent_servers.create` | Create agent servers |
> | `agent_servers.read` | View agent server details |
> | `agent_servers.update` | Update agent servers |
> | `agent_servers.delete` | Delete agent servers |
> | `agent_servers.list` | List agent servers |
> | `mcp_servers.create` | Create MCP servers |
> | `mcp_servers.read` | View MCP server details |
> | `mcp_servers.update` | Update MCP servers |
> | `mcp_servers.delete` | Delete MCP servers |
> | `mcp_servers.list` | List MCP servers |
> [accordion] Analytics and Logs
>
> | Scope | Description |
> | - | - |
> | `analytics.view` | Access analytics data |
> | `logs.export` | Export logs to external systems |
> | `logs.list` | List available logs |
> | `logs.view` | View log details |
### Workspace API Keys
Workspace API Keys are scoped to a specific workspace and are used for operations within that workspace only. There are two types — Service API Keys and User API Keys — which share most scopes. The only difference is that Service API Keys can also manage other API keys within the workspace; User API Keys cannot.
#### Workspace Service API Keys
Used for automated processes, backend integrations, and CI pipelines. In addition to all operational scopes, service keys can create, update, rotate, and delete other workspace API keys.
> [accordion] Key Management
>
> | Scope | Description |
> | - | - |
> | `workspace_service_api_keys.create` | Create new workspace service API keys |
> | `workspace_service_api_keys.read` | View workspace service API key details |
> | `workspace_service_api_keys.update` | Modify workspace service API keys |
> | `workspace_service_api_keys.delete` | Delete workspace service API keys |
> | `workspace_service_api_keys.list` | List all workspace service API keys |
> | `workspace_service_api_keys.rotate` | Regenerate workspace service API keys |
> | `workspace_user_api_keys.create` | Create new workspace user API keys |
> | `workspace_user_api_keys.read` | View workspace user API key details |
> | `workspace_user_api_keys.update` | Modify workspace user API keys |
> | `workspace_user_api_keys.delete` | Delete workspace user API keys |
> | `workspace_user_api_keys.list` | List all workspace user API keys |
> | `workspace_user_api_keys.rotate` | Regenerate workspace user API keys |
> [accordion] Workspace Management
>
> | Scope | Description |
> | - | - |
> | `workspaces.read` | View workspace details |
> | `workspaces.update` | Modify workspace settings |
> | `workspaces.list` | List available workspaces |
> | `workspace_users.create` | Create new workspace users |
> | `workspace_users.read` | View workspace user details |
> | `workspace_users.update` | Update workspace user settings |
> | `workspace_users.delete` | Remove users from workspace |
> | `workspace_users.list` | List workspace users |
> [accordion] LLM Operations
>
> | Scope | Description |
> | - | - |
> | `completions.write` | Create and manage completions (includes /chat/completions, /completions, /images, /audio) |
> | `prompts.create` | Create new prompt templates |
> | `prompts.read` | View prompt template details |
> | `prompts.update` | Modify existing prompt templates |
> | `prompts.delete` | Delete prompt templates |
> | `prompts.list` | List available prompt templates |
> | `prompts.publish` | Publish prompt templates |
> | `prompts.render` | Render prompt templates |
> [accordion] MCP Gateway
>
> | Scope | Description |
> | - | - |
> | `mcp.invoke` | Call MCP gateway methods |
> | `mcp_servers.create` | Create MCP servers |
> | `mcp_servers.read` | View MCP server details |
> | `mcp_servers.update` | Update MCP servers |
> | `mcp_servers.delete` | Delete MCP servers |
> | `mcp_servers.list` | List MCP servers |
> | `workspace_mcp_integrations.create` | Create workspace MCP integrations |
> | `workspace_mcp_integrations.read` | View workspace MCP integration details |
> | `workspace_mcp_integrations.update` | Update workspace MCP integrations |
> | `workspace_mcp_integrations.delete` | Delete workspace MCP integrations |
> | `workspace_mcp_integrations.list` | List workspace MCP integrations |
> | `organisation_mcp_integrations.list` | List organisation MCP integrations |
> [accordion] Agent Gateway
>
> | Scope | Description |
> | - | - |
> | `agents.invoke` | Invoke agents |
> | `agent_servers.create` | Create agent servers |
> | `agent_servers.read` | View agent server details |
> | `agent_servers.update` | Update agent servers |
> | `agent_servers.delete` | Delete agent servers |
> | `agent_servers.list` | List agent servers |
> | `workspace_agent_integrations.create` | Create workspace agent integrations |
> | `workspace_agent_integrations.read` | View workspace agent integration details |
> | `workspace_agent_integrations.update` | Update workspace agent integrations |
> | `workspace_agent_integrations.delete` | Delete workspace agent integrations |
> | `workspace_agent_integrations.list` | List workspace agent integrations |
> | `organisation_agent_integrations.list` | List organisation agent integrations |
> [accordion] Resources
>
> | Scope | Description |
> | - | - |
> | `configs.create` | Create new configurations |
> | `configs.update` | Update existing configurations |
> | `configs.delete` | Delete configurations |
> | `configs.read` | View configuration details |
> | `configs.list` | List available configurations |
> | `guardrails.create` | Create new guardrails |
> | `guardrails.read` | View guardrail details |
> | `guardrails.update` | Modify existing guardrails |
> | `guardrails.delete` | Delete guardrails |
> | `guardrails.list` | List available guardrails |
> | `guardrails.invoke` | Invoke guardrails directly |
> | `virtual_keys.create` | Create new virtual keys |
> | `virtual_keys.read` | View virtual key details |
> | `virtual_keys.update` | Modify existing virtual keys |
> | `virtual_keys.delete` | Delete virtual keys |
> | `virtual_keys.list` | List available virtual keys |
> | `virtual_keys.duplicate` | Duplicate virtual keys |
> | `virtual_keys.copy` | Copy virtual keys |
> | `providers.create` | Create new providers |
> | `providers.read` | View provider details |
> | `providers.update` | Update existing providers |
> | `providers.delete` | Delete providers |
> | `providers.list` | List available providers |
> | `policies.create` | Create policies |
> | `policies.read` | View policy details |
> | `policies.update` | Update policies |
> | `policies.delete` | Delete policies |
> | `policies.list` | List policies |
> [accordion] Integrations
>
> | Scope | Description |
> | - | - |
> | `workspace_integrations.create` | Create workspace integrations |
> | `workspace_integrations.read` | View workspace integration details |
> | `workspace_integrations.update` | Update workspace integrations |
> | `workspace_integrations.delete` | Delete workspace integrations |
> | `workspace_integrations.list` | List workspace integrations |
> | `organisation_integrations.list` | List organisation integrations |
> [accordion] Analytics and Logs
>
> | Scope | Description |
> | - | - |
> | `analytics.view` | Access analytics data |
> | `logs.export` | Export logs to external systems |
> | `logs.list` | List available logs |
> | `logs.view` | View log details |
> | `logs.write` | Create and modify logs |
#### Workspace User API Keys
Associated with individual users within a workspace. Identical in scope to service keys except they cannot manage other API keys — use these for personal access and user-level integrations.
> [accordion] Workspace Management
>
> | Scope | Description |
> | - | - |
> | `workspaces.read` | View workspace details |
> | `workspaces.update` | Modify workspace settings |
> | `workspaces.list` | List available workspaces |
> | `workspace_users.create` | Create new workspace users |
> | `workspace_users.read` | View workspace user details |
> | `workspace_users.update` | Update workspace user settings |
> | `workspace_users.delete` | Remove users from workspace |
> | `workspace_users.list` | List workspace users |
> [accordion] LLM Operations
>
> | Scope | Description |
> | - | - |
> | `completions.write` | Create and manage completions (includes /chat/completions, /completions, /images, /audio) |
> | `prompts.create` | Create new prompt templates |
> | `prompts.read` | View prompt template details |
> | `prompts.update` | Modify existing prompt templates |
> | `prompts.delete` | Delete prompt templates |
> | `prompts.list` | List available prompt templates |
> | `prompts.publish` | Publish prompt templates |
> | `prompts.render` | Render prompt templates |
> [accordion] MCP Gateway
>
> | Scope | Description |
> | - | - |
> | `mcp.invoke` | Call MCP gateway methods |
> | `mcp_servers.create` | Create MCP servers |
> | `mcp_servers.read` | View MCP server details |
> | `mcp_servers.update` | Update MCP servers |
> | `mcp_servers.delete` | Delete MCP servers |
> | `mcp_servers.list` | List MCP servers |
> | `workspace_mcp_integrations.create` | Create workspace MCP integrations |
> | `workspace_mcp_integrations.read` | View workspace MCP integration details |
> | `workspace_mcp_integrations.update` | Update workspace MCP integrations |
> | `workspace_mcp_integrations.delete` | Delete workspace MCP integrations |
> | `workspace_mcp_integrations.list` | List workspace MCP integrations |
> | `organisation_mcp_integrations.list` | List organisation MCP integrations |
> [accordion] Agent Gateway
>
> | Scope | Description |
> | - | - |
> | `agents.invoke` | Invoke agents |
> | `agent_servers.create` | Create agent servers |
> | `agent_servers.read` | View agent server details |
> | `agent_servers.update` | Update agent servers |
> | `agent_servers.delete` | Delete agent servers |
> | `agent_servers.list` | List agent servers |
> | `workspace_agent_integrations.create` | Create workspace agent integrations |
> | `workspace_agent_integrations.read` | View workspace agent integration details |
> | `workspace_agent_integrations.update` | Update workspace agent integrations |
> | `workspace_agent_integrations.delete` | Delete workspace agent integrations |
> | `workspace_agent_integrations.list` | List workspace agent integrations |
> | `organisation_agent_integrations.list` | List organisation agent integrations |
> [accordion] Resources
>
> | Scope | Description |
> | - | - |
> | `configs.create` | Create new configurations |
> | `configs.update` | Update existing configurations |
> | `configs.delete` | Delete configurations |
> | `configs.read` | View configuration details |
> | `configs.list` | List available configurations |
> | `guardrails.create` | Create new guardrails |
> | `guardrails.read` | View guardrail details |
> | `guardrails.update` | Modify existing guardrails |
> | `guardrails.delete` | Delete guardrails |
> | `guardrails.list` | List available guardrails |
> | `guardrails.invoke` | Invoke guardrails directly |
> | `virtual_keys.create` | Create new virtual keys |
> | `virtual_keys.read` | View virtual key details |
> | `virtual_keys.update` | Modify existing virtual keys |
> | `virtual_keys.delete` | Delete virtual keys |
> | `virtual_keys.list` | List available virtual keys |
> | `virtual_keys.duplicate` | Duplicate virtual keys |
> | `virtual_keys.copy` | Copy virtual keys |
> | `providers.create` | Create new providers |
> | `providers.read` | View provider details |
> | `providers.update` | Update existing providers |
> | `providers.delete` | Delete providers |
> | `providers.list` | List available providers |
> | `policies.create` | Create policies |
> | `policies.read` | View policy details |
> | `policies.update` | Update policies |
> | `policies.delete` | Delete policies |
> | `policies.list` | List policies |
> [accordion] Integrations
>
> | Scope | Description |
> | - | - |
> | `workspace_integrations.create` | Create workspace integrations |
> | `workspace_integrations.read` | View workspace integration details |
> | `workspace_integrations.update` | Update workspace integrations |
> | `workspace_integrations.delete` | Delete workspace integrations |
> | `workspace_integrations.list` | List workspace integrations |
> | `organisation_integrations.list` | List organisation integrations |
> [accordion] Analytics and Logs
>
> | Scope | Description |
> | - | - |
> | `analytics.view` | Access analytics data |
> | `logs.export` | Export logs to external systems |
> | `logs.list` | List available logs |
> | `logs.view` | View log details |
> | `logs.write` | Create and modify logs |
## Using API Key Scopes
When creating or updating API keys, you can define specific permission scopes based on your security requirements:
Both types of API keys play important roles in Portkey's security model, enabling secure and efficient access to resources while maintaining proper separation of concerns between organization-wide administration and workspace-specific operations.
### Related Topics
> [card] [Organizations](/docs/product/enterprise-offering/org-management/organizations)
> [card] [Workspaces](/docs/api-reference/admin-api/control-plane/workspaces/create-workspace)
> [card] [User Roles & Permissions](/docs/product/enterprise-offering/org-management/user-roles-and-permissions)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# CIE Directory Sync
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/directory-sync/cie-directory-sync
Sync users and groups from Palo Alto Networks Cloud Identity Engine (CIE) into SCM's AI Gateway for automated workspace provisioning.
# CIE Directory Sync
CIE (Cloud Identity Engine) Directory Sync allows you to pull users and groups from your organization's identity provider directories — such as **Entra ID (Azure AD)**, **Okta**, or **On-Premises Active Directory** — into SCM via Palo Alto's Cloud Identity Engine. Once synced, you can map CIE groups to SCM's AI Gateway workspaces so that users are **automatically provisioned** into the correct workspaces.
***
## Overview
CIE Directory Sync is available for organizations running in **SCM (Strata Cloud Manager)**. It replaces the need for manual user provisioning or standalone SCIM integration by leveraging CIE as the centralized identity source.
### How It Works
1. **CIE aggregates directories** — Your organization's identity providers (Entra ID, Okta, on-prem AD) are connected to CIE via the Strata Cloud Manager. CIE syncs and caches user/group data from these directories.
2. **Admin maps groups to workspaces** — An admin selects which CIE directory to connect, then maps CIE groups to AI Gateway workspaces.
3. **Users are auto-provisioned** — Background sync periodically pulls group membership changes from CIE and provisions/deprovisions users in the mapped workspaces automatically.
### Key Concepts
| Concept | Description |
| - | - |
| **Domain (Connected Directory)** | An identity provider directory synced into CIE. Each domain represents a separate directory source. |
| **Tenant ID** | The CIE tenant identifier for your organization, auto-provisioned during Onboarding. You never need to enter this manually. |
| **Group** | A directory group from CIE (e.g., a security group). Groups contain users that can be mapped to workspaces. |
| **Group-Workspace Mapping** | A 1:1 link between a CIE group and an AI Gateway workspace. All members of the mapped group are automatically provisioned into that workspace. |
| **User Identity Attribute** | The CIE user attribute used as the email address — either **UPN (User Principal Name)** or **Mail (Primary Email)**. |
| **Auth Profile** | The authentication profile used to validate user identity during MCP inbound authentication. These profiles are synced from [Authentication Profiles](https://docs.paloaltonetworks.com/identity/cloud-identity-engine/authenticate-users-with-the-cloud-identity-engine) configured under CIE. |
***
## Prerequisites
Before configuring CIE Directory Sync in SCM's AI Gateway, ensure the following:
1. **CIE is provisioned for your organization** — Your Strata Cloud Manager tenant must have CIE activated with a Directory Sync instance. This is set up during Onboarding.
2. **At least one directory is connected in CIE** — Navigate to CIE and verify that at least one directory (Entra ID, Okta, or On-Premises) has been added and has a successful sync status.
3. **You have SCM admin access** — Only organization admins can configure Directory Sync in SCM's AI Gateway.
> [!NOTE]
>
> CIE Directory Sync is only available for SCM Tenants. It is not available in standalone deployments. For non-SCM deployments, use [SCIM Provisioning](/docs/product/enterprise-offering/org-management/scim/scim) instead.
***
## Setting Up Directories in CIE
Before SCM's AI Gateway can sync from CIE, you need to connect your identity provider directories in CIE. This is done in the **Strata Cloud Manager → Cloud Identity Engine** console.
For more information about CIE, see the [Cloud Identity Engine documentation](https://docs.paloaltonetworks.com/identity/cloud-identity-engine/cloud-identity-engine-overview).

### Adding a New Directory
1. In the CIE console, navigate to **Directory Sync → Directories**.
2. Click **Add New Directory**.
3. You will see the directory type options:

For SCM's AI Gateway integration, the relevant directory types are:
| Directory Type | Provider | Description |
| - | - | - |
| **Cloud Directory** | Entra ID (Azure AD), Okta, Google | Connect a cloud identity provider. This is the most common setup. |
| **On-Premises Directory** | Active Directory | Install a Cloud Identity agent to sync from on-prem AD. |
| **CIE Directory** | CIE-native | Create a local directory managed entirely within CIE. |
> [!NOTE]
>
> SCM's AI Gateway can connect to **any** directory type that CIE supports. The "Connected Directory" dropdown will show all directories that have been successfully synced in CIE.
***
## Configuring Directory Sync in SCM's AI Gateway
Navigate to **AI Gateway → Admin Settings → Authentication → Directory Sync** in the SCM console.

The **Configure in CIE** button redirects to your CIE Directory Sync console, where you can manage directories.
### Step 1: Select a Connected Directory
The **Connected Directory** dropdown shows all available directories from CIE, along with their provider type and entity counts (groups and users).

Each entry displays:
* **Domain name** — the directory domain (e.g., `corp.example.com`)
* **Provider type** — `aad` (Entra ID), `okta`, `cie_directory` (CIE-native), `ad` (on-prem)
* **Group and user counts** — number of groups and users in that directory
Select the directory you want to sync from. You can also select **None (Disconnected)** to disconnect.
> [!WARNING]
>
> Currently, only **one directory** can be connected at a time.
### Step 2: Choose the User Identity Attribute
The **User Identity Attribute** determines which CIE attribute is used as the user's email address.

| Attribute | Description | When to Use |
| - | - | - |
| **UPN (User Principal Name)** | The `userPrincipalName` attribute from the directory (e.g., `john@contoso.com`) | Default choice. Use when UPN matches the user's email. |
| **Mail (Primary Email)** | The `mail` attribute from the directory | Use when UPN differs from email (e.g., UPN is `john@contoso.onmicrosoft.com` but email is `john@contoso.com`) |
> [!WARNING]
>
> If the selected attribute is **missing** for a user in CIE, that user will be **skipped** during sync. Verify that your chosen attribute is populated for all users in your directory.
> [!NOTE]
>
> Changing the User Identity Attribute after initial setup triggers an automatic **full re-sync** to update all user email addresses. This is safe — no users are removed during this re-sync.
### Step 3: Save Configuration
Click **Save** to persist your Connected Directory and User Identity Attribute selections.
Once saved, the sync configuration becomes **active** and the background sync scheduler begins monitoring for changes.
### Step 4: Select an Auth Profile
The **Auth Profile** dropdown shows authentication profiles available for your tenant. These profiles are synced from [Authentication Profiles](https://docs.paloaltonetworks.com/identity/cloud-identity-engine/authenticate-users-with-the-cloud-identity-engine) configured under CIE. The selected profile is used to validate user identity during MCP inbound authentication flows.
***
## Directory Sync State
The **Directory Sync State** section shows the current health of the sync process.

| Field | Description |
| - | - |
| **Status** | Current sync status — `Success`, `In Progress`, or `Failed` |
| **Last Updated** | Timestamp of the last sync run (success or failed) |
| **Objects Synced** | Count of users and groups currently mapped to workspaces |
### Full Sync Button
Delta sync with CIE for group-membership updates happens every 15 minutes. So any update can take up to 15 minutes to reflect in AI Gateway. If CIE rebuilds its cache (approximately every week), AI Gateway does a full sync automatically.
But in case there is some issue or mismatch noted and you don't want to wait for the full sync period, you can click **Full Sync** which will do a forceful full sync of data from CIE.
> [!NOTE]
>
> If a sync is already in progress, the full sync will run once the current sync completes.
***
## Group Mappings
The **Group Mappings** section is where you map CIE groups to workspaces. Users in a mapped group are automatically provisioned into the corresponding workspace.

### Adding a Mapping
1. Click **Add Mapping**. The **Add Group Mapping** dialog opens:

2. Select a **CIE Group** from the dropdown. The dropdown lists all groups from your connected directory.
3. Select a **Workspace** to map the group to.
4. Click **Add**.
### Mapping Rules
* **1:1 mapping** — Each group can only be mapped to one workspace, and each workspace can only have one group mapped to it
* **Workspace must exist** — The target workspace must already exist. Directory Sync does not create workspaces.
### Removing a Mapping
Click the **delete** (trash) icon next to a mapping to remove it. Users provisioned by this mapping will be **immediately removed** from that workspace.
> [!WARNING]
>
> Deleting a mapping immediately removes users from the workspace. This action cannot be undone — you would need to re-create the mapping and wait for a sync to re-provision users.
***
## Viewing Directory-Provisioned Members
Once Directory Sync is configured and group mappings are in place, users from CIE are automatically provisioned into the mapped workspaces. You can view these members through the Workspace Control page.
### Viewing Workspaces
Navigate to **AI Gateway → Workspace Control** to see all workspaces in your organization.

This page shows all workspaces along with their slug, creation date, and last update time. Workspaces that have CIE groups mapped to them will have directory-provisioned members automatically added.
### Viewing Workspace Members
Click on a workspace to open its settings, then navigate to the **Members** tab to see all members provisioned into that workspace.

Each member entry shows:
* **Name** — the user's display name, derived from CIE's `Common-Name` attribute
* **Email** — the user's email, based on the User Identity Attribute you selected (UPN or Mail)
* **Created At** — when the user was provisioned into the workspace
* **Last Update** — when the user's membership was last updated by a sync
> [!NOTE]
>
> Members listed here are automatically managed by Directory Sync. When a user is added to or removed from the mapped CIE group, the workspace membership is updated accordingly during the next sync cycle (within 15 minutes).
***
## Creating User API Keys for Directory-Provisioned Members
Once users are provisioned into workspaces via Directory Sync, you can create **User API Keys** scoped to individual directory-provisioned members. This allows each user to have their own key for accessing AI Gateway services within their workspace.
### Navigating to Security Keys
1. Select a workspace from the **Workspace** dropdown at the top of the page.
2. Navigate to **AI Gateway → Security Keys**.
You will see the **Gateway API Keys** page with two tabs — **Service** and **User**.

* **Service** keys are shared keys not tied to a specific user.
* **User** keys are tied to a specific directory-provisioned member.
Switch to the **User** tab to view existing user API keys.

### Creating a User API Key
1. Click **+ Create New**. The **Create New Gateway API Key** form opens.
2. Under **API Key Type**, select **User**.

3. Under **Select User**, choose a directory-provisioned member from the dropdown. Only users who have been synced into this workspace via Directory Sync will appear here.

4. Enter an **API Key Name** — this is required and helps identify the key later.
5. Optionally fill in a **Short Description**, **Configuration**, and **Metadata**.

6. Click **Next: Set Permissions**.
7. On the **Permissions** step, configure which permissions this key should have. Permissions are organized by resource (Agents, Completions, Logs, Mcp, Prompts) and action (Invoke, Write, Render).

8. Click **Create Gateway API Key**.
9. The generated API key is displayed. **Copy it now** — you will not be able to view it again.

10. Click **Copy and Close**. The new key will appear in the **User** tab of Security Keys.

> [!WARNING]
>
> You cannot create a User API key without selecting a user and providing a key name. Both fields are required.
> [!NOTE]
>
> User API keys are scoped to the selected workspace. Each key is attributed to a specific directory-provisioned member and tracks who created it and who owns it.
***
## Disabling Directory Sync
To disable Directory Sync entirely:
1. Navigate to **Admin Settings → Authentication → Directory Sync**
2. Select **None (Disconnected)** from the Connected Directory dropdown
**What happens when you disable sync:**
1. All CIE-synced users are **removed from their mapped workspaces**
2. All group-workspace mappings are removed
3. All group and sync status records are removed
4. The sync configuration is deactivated
> [!WARNING]
>
> Disabling Directory Sync immediately removes all CIE-provisioned users from their workspaces. This is a destructive action. Users can be re-provisioned by re-enabling sync and re-creating group mappings.
To **re-enable** sync after disabling:
1. Select a Connected Directory again and save
2. Group mappings do **not** carry over — you must re-create them explicitly
3. A full sync will run to provision users into the newly mapped workspaces
***
## Troubleshooting
### Common Issues
| Issue | Cause | Resolution |
| - | - | - |
| **No domains shown** in Connected Directory dropdown | CIE not provisioned for this org, or no directories added in CIE | Ensure CIE is activated for your SCM tenant. Add directories in CIE. |
| **Users not provisioned** after mapping | Selected User Identity Attribute is missing for those users | Check CIE to confirm users have the UPN or Mail attribute populated. Switch attribute if needed. |
| **Users not removed** after deleting mapping | User belongs to another group also mapped to the same workspace | This is by design — users who have access through another mapping are not removed. |
| **Delta sync falling back to full** | CIE cache was rebuilt, or cursor expired | This is expected behavior. CIE periodically rebuilds its cache, which triggers a full resync. This acts as a self-healing mechanism. |
***
## Support
If you encounter issues with CIE Directory Sync, contact your support team.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Gateway URLs
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/gateway-urls
Configure custom gateway endpoints for your organisation's AI gateway and MCP gateway deployments.
> [!NOTE]
>
> Gateway URLs are available on the **Enterprise** plan only.
The Gateway URLs settings let you point the Portkey dashboard at your own self-hosted gateway deployments instead of Portkey's cloud endpoints. Once configured, the dashboard uses your custom URLs when generating code snippets, running playground completions, and constructing MCP server endpoints.
Both fields are set at the **organisation level** and apply across all workspaces within that organisation.
***
## Gateway URL
The Gateway URL is the base URL of your self-hosted AI gateway. Setting it changes two things in the dashboard:
* **Code snippets** — the `baseURL` shown in the Model Catalog and Getting Started pages will use your gateway URL instead of `https://api.portkey.ai/v1`.
* **Playground completions** — prompt completions triggered from the dashboard are proxied through this URL.
If this field is left blank, the dashboard falls back to Portkey's cloud gateway at `https://api.portkey.ai/v1`.
> [!NOTE]
>
> The trailing `/v1` is automatically normalised. Whether you enter `https://gateway.yourcompany.com` or `https://gateway.yourcompany.com/v1`, the dashboard will always use the `/v1`-suffixed form.
***
## MCP Gateway URL
The MCP Gateway URL is the base URL of your self-hosted MCP gateway. It is used to construct the endpoint URL for each MCP server registered in your organisation.
For an MCP server with slug `my-server`, the resulting endpoint URL will be:
```
/my-server/mcp
```
If this field is left blank, the dashboard falls back to Portkey's default MCP gateway at `https://mcp.portkey.ai`.
***
## How to Configure
1. Navigate to **Settings** in the Portkey dashboard.
2. Under the **Organisation** section, click **General**.
3. Scroll to the **Gateway URLs** section.
4. Enter your gateway's base URL in the **Gateway URL** field (e.g. `https://gateway.yourcompany.com`).
5. Enter your MCP gateway's base URL in the **MCP Gateway URL** field if applicable (e.g. `https://mcp.yourcompany.com`).
6. Click outside the input field. The value saves automatically — there is no separate save button.
To clear either value and revert to the Portkey default, delete the URL from the field and click outside it.
> [!WARNING]
>
> Only organisation members with the **Admin** or **Owner** role can update these settings.
***
## Private and Self-Hosted Deployments
> [!NOTE]
>
> If you are running a **private or self-hosted deployment** of Portkey, the Gateway URL shown in the dashboard is controlled at the infrastructure level by your deployment team via the `INTERNAL_GATEWAY_URL` or `GATEWAY_BASE_URL` environment variable. In this case, the value entered in the UI has no effect — contact your deployment administrator to change the gateway endpoint.
***
## Related Topics
> [card] [Organizations](/docs/product/enterprise-offering/org-management/organizations)
> [card] [Workspaces](/docs/product/enterprise-offering/org-management/workspaces)
> [card] [MCP Gateway](/docs/product/mcp-gateway)
> [card] [Self-Hosting](/docs/self-hosting)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# JWT Authentication
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/jwt
Configure JWT-based authentication for your organization in Portkey
> [!NOTE]
>
> This feature is available only on the [Enterprise Plan](/docs/product/enterprise-offering) of Portkey.
Portkey supports JWT-based authentication in addition to API key authentication. Clients send a JWT in `x-portkey-api-key` or `Authorization: Bearer`; the token is validated against JWKS configured on the organisation.
**Portkey Cloud** validates JWTs on the control plane. **[Hybrid](/docs/self-hosting/hybrid-deployments/architecture) and [air-gapped](/docs/self-hosting/airgapped/model-pricing) deployments** can optionally enable **gateway-local JWT authentication** so the AI Gateway validates tokens locally instead of delegating every request to the control plane.
> [card] [Validate JWT Token (Guardrail)](/docs/product/guardrails/list-of-guardrail-checks#basic-%E2%80%94-deterministic-guardrails)
>
> Optionally validate JWTs inside a config's hook pipeline using the JWT guardrail plugin. This is separate from gateway-local JWT auth, which replaces API key validation at the gateway.
## Configuring JWT Authentication
JWT authentication can be configured under **Admin Settings** → **Organisation** → **Authentication**.

### JWKS Configuration
To validate JWTs, you must configure one of the following:
* **JWKS URL**: A URL from which the public keys will be dynamically fetched. You can provide multiple JWKS URLs as a comma-separated list (e.g. when rotating between IdPs); the gateway fetches and merges keys from all of them.
* **JWKS JSON**: A static JSON containing public keys.
## Hard Requirements (Read First)
### JWT Header (JOSE Header)
* `alg`: Must be `RS256`. Symmetric algorithms like `HS256` are not accepted.
* `typ`: Must be `JWT`.
* `kid`: Required. The value in the JWT header must match a `kid` in your JWKS.
### Key Requirements
* Key type: RSA
* Key size: 2048 bits or higher
* Your JWKS must expose only the public key parameters (e.g., `kty`, `n`, `e`, `use`, `alg`, `kid`). Do not include private key material.
## JWT Requirements
### Supported Algorithm
* JWTs must be signed using **RS256** (RSA Signature with SHA-256).
### Required Claims
Your JWT payload must contain the following claims:
| **Claim Key** | **Description** |
| - | - |
| `portkey_oid` / `organisation_id` | Unique identifier for the organization. |
| `portkey_workspace` / `workspace_slug` | Identifier for the workspace. |
| `scope` / `scopes` | Permissions granted by the token. |
| `exp` | Expiration time (as a UNIX timestamp, in seconds). |
* `exp` is mandatory. Tokens without `exp` or with expired `exp` are rejected. A small amount of clock skew is tolerated.
* `iat` and/or `nbf` are recommended but optional.
> [!NOTE]
>
> On Portkey Cloud, `portkey_oid` and `portkey_workspace` are required. In [gateway-local JWT auth](#gateway-local-jwt-authentication), org and workspace can be resolved from deployment configuration when you use a standard IdP token - see [Integration modes](#integration-modes).
### Optional Claims
| **Claim Key** | **Description** |
| - | - |
| `defaults` | Object containing default settings applied to all requests made with this token. See [Embedding Default Configs](#embedding-default-configs-in-jwt) below. |
| `usage_limits` | Usage limits to enforce on requests made with this token. |
| `rate_limits` | Rate limits to enforce on requests made with this token. |
### User Identification
Portkey identifies users in the following order of precedence for logging and metrics:
1. `email_id`
2. `sub`
3. `uid`
## End-to-End Working Example (Generate → Configure JWKS → Sign → Call)
The following example uses Node.js and the `jose` library to:
1. generate an RSA key pair,
2. create a JWKS containing the public key,
3. sign a JWT with the private key,
4. call Portkey with the JWT.
### 1) Prerequisites
```sh theme={"system"}
# Node 18+ recommended
npm init -y
npm install jose
```
### 2) Generate RSA Keys, Create JWKS, and Sign a JWT (NodeJS)
Create `generate-and-sign-jwt.mjs`:
```js theme={"system"}
import { generateKeyPair, exportJWK, SignJWT } from 'jose';
import { randomUUID } from 'node:crypto';
import fs from 'node:fs';
const { publicKey, privateKey } = await generateKeyPair('RS256');
// Create a public JWK for JWKS
const publicJwk = await exportJWK(publicKey);
publicJwk.kty = 'RSA';
publicJwk.use = 'sig';
publicJwk.alg = 'RS256';
publicJwk.kid = randomUUID();
const jwks = { keys: [publicJwk] };
fs.writeFileSync('jwks.json', JSON.stringify(jwks, null, 2));
const now = Math.floor(Date.now() / 1000);
// Sign a JWT with the private key
const jwt = await new SignJWT({
portkey_oid: '',
portkey_workspace: '',
scope: ['completions.write', 'logs.view'],
email_id: 'user@example.com',
sub: '',
// Optional: embed default config and metadata
// defaults: { config_id: 'pc-your-config-id', metadata: { environment: 'production' } }
})
.setProtectedHeader({ alg: 'RS256', kid: publicJwk.kid, typ: 'JWT' })
.setIssuedAt(now)
.setExpirationTime(now + 60 * 60) // 1 hour
.sign(privateKey);
fs.writeFileSync('token.jwt', jwt);
console.log('JWKS written to jwks.json');
console.log('JWT written to token.jwt');
console.log('kid:', publicJwk.kid);
```
Run it:
```sh theme={"system"}
node generate-and-sign-jwt.mjs
```
This produces:
* `jwks.json`: A JWKS containing your public key (with a `kid`).
* `token.jwt`: A signed JWT ready to use with Portkey.
### 3) Add Your Public Key to Portkey (JWKS)
In the Portkey Admin UI:
* Navigate to **Admin Settings** → **Organisation** → **Authentication**.
* Choose either:
* JWKS URL: Host `jwks.json` at a reachable HTTPS URL and paste that URL.
* JWKS JSON: Paste the entire contents of your generated `jwks.json`.
* Save changes.
Ensure the `kid` in your JWT header matches a key in the configured JWKS.
### 4) Call Portkey Using the Signed JWT
Send the JWT in the `x-portkey-api-key` header.
```sh theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $(cat token.jwt)" \
-H "x-portkey-provider: @" \
-d '{
"model": "your-model-id",
"messages": [
{ "role": "user", "content": "Hello!" }
]
}'
```
If your JWT, JWKS, and claims are correct, the request will authenticate and succeed.
> [!NOTE]
>
> If you prefer Python for signing, you can generate the RSA key pair using your preferred method, ensure the public key is present in your JWKS with a matching `kid`, and use a library like `PyJWT` to sign with `RS256` while setting the header `{ "alg": "RS256", "typ": "JWT", "kid": "" }`.
## Authentication Process
1. The client sends the JWT in `x-portkey-api-key` or `Authorization: Bearer`:
```http theme={"system"}
x-portkey-api-key:
```
If `x-portkey-api-key` is absent, `Authorization` is used.
2. The gateway or control plane validates the JWT:
* Verifies the signature using the organisation JWKS.
* Checks token expiry.
* Ensures required claims are present.
3. If valid, the request is authenticated and user details are extracted for authorization and logging.
4. If invalid, the request is rejected. Common responses include **401 Unauthorized** (invalid or expired token), **403 Forbidden** (scope or workspace not allowed), **412** (usage limit exceeded), and **429** (rate limit exceeded).
On hybrid and air-gapped gateways with `JWT_ENABLED=ON`, validation runs locally on the gateway. Otherwise, JWT-shaped tokens are validated by the control plane.
## Authorization & Scopes
Once the JWT is validated, the server checks for the required **scope**. Scopes can be provided in the JWT as either a single string or an array of strings using the `scope` or `scopes` claim.
**Available Permission Scopes**
**Workspace Management**
**workspaces.read** `string`
View workspace details
**workspaces.update** `string`
Modify workspace settings
**workspaces.list** `string`
List available workspaces
**Logs & Analytics**
**logs.export** `string`
Export logs to external systems
**logs.list** `string`
List available logs
**logs.view** `string`
View log details
**logs.write** `string`
Create and modify logs
**analytics.view** `string`
Access analytics data
**Configurations**
**configs.create** `string`
Create new configurations
**configs.update** `string`
Update existing configurations
**configs.delete** `string`
Delete configurations
**configs.read** `string`
View configuration details
**configs.list** `string`
List available configurations
**Providers**
**providers.create** `string`
Create new providers
**provider.update** `string`
Update existing providers
**virtual\_keys.delete** `string`
Delete providers
**providers.duplicate** `string`
Duplicate existing providers
**providers.read** `string`
View provider details
**providers.list** `string`
List available providers
**Workspace Users**
**workspace\_users.create** `string`
Create new workspace users
**workspace\_users.read** `string`
View workspace user details
**workspace\_users.update** `string`
Update workspace user settings
**workspace\_users.delete** `string`
Remove users from workspace
**workspace\_users.list** `string`
List workspace users
**Other**
**prompts.render** `string`
Render prompt templates
**completions.write** `string`
Create and manage completions
Scopes can also be prefixed with `portkey.` (e.g., `portkey.completions.write`).
> [!NOTE]
>
> JWT tokens with appropriate scopes function identically to workspace API keys, providing access to workspace-specific operations. They cannot be used as organization API keys, which have broader administrative permissions across all workspaces.
#### Example JWT Header
```json theme={"system"}
{
"alg": "RS256",
"typ": "JWT",
"kid": ""
}
```
* This matches the signing example (`.setProtectedHeader({ alg: 'RS256', kid: publicJwk.kid, typ: 'JWT' })`).
* Ensure `kid` exactly matches one key in your configured JWKS.
## Embedding Default Configs in JWT
You can embed a default [config](/docs/product/ai-gateway/configs) directly in the JWT payload using the `defaults` claim. This works the same way as [attaching default configs to API keys](/docs/product/administration/enforce-default-config), but lets you control it per-token - useful when different users or services need different routing rules.
The `defaults` object supports the following fields:
| **Field** | **Description** |
| - | - |
| `config_id` | The ID of the config to apply as the default for all requests made with this token. |
| `metadata` | A JSON object with custom metadata to attach to all requests. |
When a JWT with a `defaults.config_id` is used, Portkey validates that the config belongs to the same organization before applying it. If the config is not found or doesn't belong to the org, the default is ignored.
> [!NOTE]
>
> This follows the same precedence rules as API key default configs - if a user explicitly passes a config ID in their request headers, it will override the JWT default unless config override is disabled at the workspace level.
### Example JWT Payload with Defaults
```json theme={"system"}
{
"portkey_oid": "3ed1b666-7e3d-416a-9260-da10e1610d1a",
"portkey_workspace": "ws-shared-8622d1",
"scope": ["completions.write", "logs.view"],
"email_id": "user@example.com",
"sub": "user-123",
"exp": 1735689600,
"defaults": {
"config_id": "pc-your-config-id",
"metadata": {
"environment": "production",
"team": "backend"
}
}
}
```
## Example JWT Payload
```json theme={"system"}
{
"portkey_oid": "3ed1b666-7e3d-416a-9260-da10e1610d1a",
"portkey_workspace": "ws-shared-8622d1",
"scope": ["completions.write", "logs.view"],
"email_id": "user@example.com",
"sub": "user-123",
"exp": 1735689600
}
```
## Making API Calls with JWT Authentication
Once you have a valid JWT token, you can use it to authenticate your API calls to Portkey. Below are examples showing how to use JWT authentication with different SDKs.
> [tab] NodeJS
>
> Install the Portkey SDK with npm
>
> ```sh theme={"system"}
> npm install portkey-ai
> ```
>
> ```ts Chat Completions theme={"system"}
> import Portkey from 'portkey-ai';
>
> const client = new Portkey({
> apiKey: '', // Use JWT token instead of API key
> provider: '@'
>
> });
>
> async function main() {
> const response = await client.chat.completions.create({
> messages: [{ role: "user", content: "Hello, how are you today?" }],
> model: "your-model-id",
> });
>
> console.log(response.choices[0].message.content);
> }
>
> main();
> ```
> [tab] Python
>
> Install the Portkey SDK with pip
>
> ```sh theme={"system"}
> pip install portkey-ai
> ```
>
> ```py Chat Completions theme={"system"}
> from portkey_ai import Portkey
>
> client = Portkey(
> api_key = "", # Use JWT token instead of API key,
> provider = "@"
> )
>
> response = client.chat.completions.create(
> model="your-model-id",
> messages=[
> {"role": "system", "content": "You are a helpful assistant."},
> {"role": "user", "content": "Hello!"}
> ]
> )
>
> print(response.choices[0].message)
> ```
> [tab] cURL
>
> ```sh Chat Completions theme={"system"}
> curl https://api.portkey.ai/v1/chat/completions \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: " \
> -H "x-portkey-provider: @" \
> -d '{
> "model": "your-model-id",
> "messages": [
> { "role": "user", "content": "Hello!" }
> ]
> }'
> ```
> [tab] OpenAI Python SDK
>
> Install the OpenAI & Portkey SDKs with pip
>
> ```sh theme={"system"}
> pip install openai portkey-ai
> ```
>
> ```py Chat Completions theme={"system"}
> from openai import OpenAI
> from portkey_ai import createHeaders, PORTKEY_GATEWAY_URL
>
> client = OpenAI(
> api_key="xx",
> base_url=PORTKEY_GATEWAY_URL,
> default_headers=createHeaders(
> api_key="" # Use JWT token instead of API key
> )
> )
>
> completion = client.chat.completions.create(
> model="@/your-model-id",
> messages=[
> {"role": "system", "content": "You are a helpful assistant."},
> {"role": "user", "content": "Hello!"}
> ]
> )
>
> print(completion.choices[0].message)
> ```
> [tab] OpenAI NodeJS SDK
>
> Install the OpenAI & Portkey SDKs with npm
>
> ```sh theme={"system"}
> npm install openai portkey-ai
> ```
>
> ```ts Chat Completions theme={"system"}
> import OpenAI from 'openai';
> import { PORTKEY_GATEWAY_URL, createHeaders } from 'portkey-ai'
>
> const openai = new OpenAI({
> apiKey: 'xx',
> baseURL: PORTKEY_GATEWAY_URL,
> defaultHeaders: createHeaders({
> apiKey: "" // Use JWT token instead of API key
> })
> });
>
> async function main() {
> const completion = await openai.chat.completions.create({
> messages: [{ role: 'user', content: 'Say this is a test' }],
> model: '@/your-model-id'
> });
>
> console.log(completion.choices[0].message);
> }
>
> main();
> ```
## Troubleshooting “Invalid API Key” Errors
* **Wrong algorithm**: Only `RS256` is accepted; `HS256` or others will fail.
* **Missing or mismatched `kid`**: Your JWT header must include a `kid` that matches a key in the JWKS.
* **Incorrect header usage**: Send the raw JWT in `x-portkey-api-key`, or use `Authorization: Bearer `. Do not prefix the token with `Bearer` in `x-portkey-api-key`.
* **Expired or missing `exp`**: The `exp` claim is required and must be in the future. Allow for small clock skew.
* **Private vs Public key mix-up**: Your JWKS must contain only the public key parameters. The private key is used only for signing; never paste it into the JWKS JSON.
* **Wrong org/workspace identifiers**: `portkey_oid` (or `organisation_id`) and `portkey_workspace` (or `workspace_slug`) must correspond to valid identifiers in your Portkey tenant.
* **Scopes missing for the API you call**: E.g., chat completions needs `completions.write`.
* **Unreachable JWKS URL**: If using a URL, it must be publicly reachable by Portkey. For static JSON, ensure the pasted JSON is valid and includes `keys: [...]`.
> [!NOTE]
>
> All Invalid JWT errors are logged in the Audit Logs.
> Sample error message:
>
> ```
> "jwtToken": "ey****bt",
> "error": "Error Verifying JWT token: Signing Key Not Found",
> ```
## Gateway-Local JWT Authentication
> [!NOTE]
>
> Gateway-local JWT authentication is available only on **[hybrid](/docs/self-hosting/hybrid-deployments/architecture)** and **air-gapped** deployments.
>
> It requires gateway **2.5.0** or higher (Backend **v1.13.0** or higher for air-gapped) with `JWT_ENABLED=ON`.
When enabled, your AI Gateway validates JWTs locally instead of sending every request to the control plane for authentication. This reduces latency and keeps authentication working even when the control plane is temporarily unreachable.
If `JWT_ENABLED` is not `ON`, JWT-shaped tokens are validated by the control plane instead.
### How it works
1. The client sends a JWT in `x-portkey-api-key` or `Authorization: Bearer`.
2. The gateway determines the organisation and workspace for the request.
3. The gateway verifies the token signature against your configured JWKS.
4. The gateway applies the same authorization, usage limits, rate limits, and policies as it would for a regular API key.
### Integration modes
Choose the mode that matches how much control you have over your JWT issuer.
#### Mode A - You control the JWT issuer
You can add Portkey-specific claims to your tokens (`portkey_oid`, `portkey_workspace`, `usage_limits`, `rate_limits`, `defaults`, and others) and use the full JWT feature set described in this guide.
#### Mode B - Standard IdP token
Use this when tokens come from Okta, Auth0, Entra, Cognito, or another IdP whose token schema you cannot change. Portkey handles org, workspace, and budget configuration on the server side. If your IdP cannot include Portkey scopes in tokens, set `JWT_LOCAL_AUTH_DEFAULT_SCOPES` on the gateway instead.
| What you need | How to configure it |
| - | - |
| Organisation | Set `ORGANISATIONS_TO_SYNC` to a **single org UUID** when the token does not include `portkey_oid` or `organisation_id`. |
| Workspace | Restrict the deployment to specific workspaces, or set an org-level default workspace. See [Workspace resolution](#workspace-resolution). |
| Scopes | Register gateway scopes (e.g. `completions.write`) in your IdP, or set `JWT_LOCAL_AUTH_DEFAULT_SCOPES` on the gateway when IdP scope changes are not possible. Both `completions.write` and `portkey.completions.write` are accepted. |
| Usage and rate limits | Configure limits on the workspace, or use workspace policies keyed off request metadata. |
| User attribution in logs | The gateway uses `email_id`, `sub`, or `uid` from the token for per-user logging and metrics. When the token's email matches a Portkey user in the target workspace, the request is attributed to that user (and inherits their workspace role) instead of a generic workspace service key. |
| JWKS | Point your org's JWKS URL to your IdP's discovery endpoint (e.g. `https:///.well-known/jwks.json`) in **Admin Settings** → **Organisation** → **Authentication**. Supports a comma-separated list of URLs. |
### Enable gateway-local JWT
#### Gateway environment variables
| Variable | Required | Description |
| - | - | - |
| `JWT_ENABLED` | **Yes** | Set to `ON` to enable gateway-local JWT auth. Any other value uses control plane validation. |
| `ORGANISATIONS_TO_SYNC` | **Yes** | Comma-separated org UUIDs to sync from the control plane. Also restricts which orgs this gateway accepts. |
| `PORTKEY_CLIENT_AUTH` | **Yes** | Service auth token for the gateway to sync org, workspace, and deployment settings from the control plane. |
| `JWT_LOCAL_AUTH_DEFAULT_SCOPES` | No | Comma-separated gateway scopes to apply when the IdP token does not include `scope` or `scopes`. Use this when you cannot add Portkey scopes to tokens in your IdP. |
| `JWT_PREFER_USER_WORKSPACE_RESOLUTION` | No | Set to `ON` to resolve a user token's own workspace membership before the deployment and organisation defaults. See [Workspace resolution](#workspace-resolution). Service tokens are unaffected. |
| `JWT_JIT_USER_ACCESS` | No | Set to `ON` to admit a user token that fails the workspace membership check as a `WORKSPACE_SERVICE` key instead of rejecting with `403`. See [Workspace resolution](#workspace-resolution). |
Example:
```sh theme={"system"}
JWT_LOCAL_AUTH_DEFAULT_SCOPES=completions.write,mcp.invoke
```
These variables are also documented in the [hybrid deployment guides](/docs/self-hosting/hybrid-deployments/architecture).
#### Organisation JWKS
Configure JWKS under **Admin Settings** → **Organisation** → **Authentication**:
* **JWKS URL** (recommended) - your IdP's public key endpoint, or
* **JWKS JSON** - a static public key set
Authentication fails if JWKS is not configured for the organisation.
#### JWT Settings: claim policies and verification options
The same authentication settings object that holds JWKS also accepts a `jwt_settings` object, which lets you enforce policy on JWT claims and tune signature verification for gateway-local JWT auth.
**Claim policies**
| Field | Type | Description |
| - | - | - |
| `required_claims` | `string[]` | Claims that must be present and non-null in the verified token. A missing or null claim denies the request with a `403`. |
| `claim_values` | `Record` | Per-claim value checks. `match_type` is one of `exact` (default), `contains`, `containsAll`, or `regex`. A claim that fails its check, is missing, or has an invalid config denies the request with a `403`. Regex patterns are validated and rejected if unsafe or malformed. |
| `extract_claims` | `string[]` | Claims to copy into request metadata. Array values are joined with commas; object values are JSON-stringified. |
| `metadata_prefix` | `string` | Prefix added to each key written by `extract_claims` (for example, `jwt_` turns the `team` claim into `jwt_team`). |
Extracted claims, and Portkey's own metadata keys (`organisation_id`, `workspace_slug`, `_user`, `auth_type`), always take precedence over a client-supplied metadata value with the same key. This also applies when a configured claim is absent from the token, so a client cannot spoof it by sending the metadata header directly.
Example:
```json theme={"system"}
{
"jwt_settings": {
"required_claims": ["sub", "team"],
"claim_values": {
"team": { "values": ["ml", "platform"], "match_type": "contains" }
},
"extract_claims": ["team", "region"],
"metadata_prefix": "jwt_"
}
}
```
**Verification options**
| Field | Default | Description |
| - | - | - |
| `algos` | `RS256` | Allowed signing algorithm(s) for the token. Accepts a single string or an array. |
| `aud` | Not enforced | Expected audience. Enforced during verification when set. |
| `iss` | Not enforced | Expected issuer. Enforced during verification when set. |
| `clock_tolerance` | `5` | Seconds of tolerance allowed for `exp` / `nbf` checks. |
An unset or malformed value keeps the default above.
#### Required JWT claims (gateway-local)
| Claim | Required | Notes |
| - | - | - |
| `scope` or `scopes` | Conditional | At least one valid scope, unless `JWT_LOCAL_AUTH_DEFAULT_SCOPES` is set on the gateway. |
| `portkey_oid` or `organisation_id` | Conditional | Required when `ORGANISATIONS_TO_SYNC` lists more than one org. With a single-org gateway (Mode B), the env var supplies the org. |
| `sub` | Conditional | Required when your deployment restricts which user IDs may authenticate. |
#### Recommended optional claims
| Claim | Purpose | Mode B (locked IdP) |
| - | - | - |
| `exp` | Token expiry | Usually already present on IdP tokens |
| `email_id`, `sub`, or `uid` | User identity for logging | `sub` is used automatically |
| `portkey_workspace` or `workspace_slug` | Target workspace | Resolve via deployment settings or org default workspace |
| `usage_limits`, `rate_limits` | Per-token limits | Configure on the workspace or via policies instead |
| `defaults` | Default config and metadata | Set default config on the workspace instead |
#### Example token payloads
**Mode A - full Portkey-aware token:**
```json theme={"system"}
{
"portkey_oid": "4f8d2c3b-1a9e-4b7c-8d2f-6a1b3c4d5e6f",
"portkey_workspace": "engineering-workspace-slug",
"sub": "user-42",
"email_id": "alice@company.com",
"scope": "completions.write mcp.invoke",
"exp": 1735689600,
"usage_limits": [
{
"id": "ul-1",
"type": "cost",
"credit_limit": 50,
"status": "active"
}
]
}
```
**Mode B - minimal IdP token:**
```json theme={"system"}
{
"iss": "https://idp.example.com",
"aud": "portkey-gateway",
"sub": "user-42",
"exp": 1735689600
}
```
If the token omits `scope` / `scopes`, set `JWT_LOCAL_AUTH_DEFAULT_SCOPES` on the gateway (e.g. `completions.write,mcp.invoke`).
In Mode B, the gateway resolves the org from `ORGANISATIONS_TO_SYNC` and the workspace from your deployment configuration.
#### Gateway scopes
Scopes can be provided as a space-separated string (`scope`) or an array (`scopes`) in the token, or via `JWT_LOCAL_AUTH_DEFAULT_SCOPES` on the gateway. A `portkey.` prefix is optional.
| Scope | Used for |
| - | - |
| `completions.read` | Read completions |
| `completions.write` | Chat completions, embeddings, and most AI routes |
| `logs.read` | Read logs |
| `logs.write` | Write logs |
| `logs.export` | Export logs |
| `prompts.render` | Render prompts |
| `virtual_keys.list` | List virtual keys |
| `mcp.invoke` | MCP invocation |
| `agents.invoke` | Agent invocation |
| `guardrails.invoke` | Guardrail invocation |
| `feedbacks.read` | Read feedbacks |
| `feedbacks.write` | Write feedbacks |
Each API route requires a matching scope. For example, chat completions requires `completions.write`.
### Organisation resolution
The gateway determines which organisation a token belongs to using this priority order:
1. `portkey_oid` claim in the token
2. `organisation_id` claim in the token
3. `ORGANISATIONS_TO_SYNC` - only when exactly **one** org UUID is configured
If `ORGANISATIONS_TO_SYNC` is set, the resolved org must be in that list.
| Scenario | Result |
| - | - |
| Both `portkey_oid` and `organisation_id` are present | `portkey_oid` is used |
| No org in token, and exactly one org in `ORGANISATIONS_TO_SYNC` | That org is used |
| No org in token, and multiple orgs in `ORGANISATIONS_TO_SYNC` | Request rejected (**401**) |
| Token org is not in `ORGANISATIONS_TO_SYNC` | Request rejected (**403**) |
| Organisation not found | Request rejected (**401**) |
| JWKS not configured for the org | Request rejected (**403**) |
After the org is determined, the gateway verifies the token signature against that org's JWKS.
### Workspace resolution
Workspace is determined after the token is verified, using token claims first, then a request header, then deployment settings.
**From the token:**
1. `portkey_workspace`
2. `workspace_slug`
**From the request** (attributed, user-identified tokens only — ignored for service-key requests, and never overrides a workspace already present in the token):
* `x-portkey-workspace` header, set to a workspace slug or id
**From deployment settings** (when the token has no workspace claim or header hint):
| Setting | Effect |
| - | - |
| User allowlist | Restrict authentication to specific user IDs (`sub` values) |
| Workspace allowlist | When enabled, only listed workspaces are allowed; the first listed workspace is used as the default |
| Org default workspace | Used when no workspace is resolved from the token or deployment settings |
Whenever a request resolves to a specific workspace this way, the gateway verifies that the token's user is an active member of it, and rejects the request with **403** otherwise.
#### Preferring the user's own workspace
By default, when a user token does not name a workspace, the gateway tries the deployment default and the organisation default workspace before falling back to the user's own membership. Set `JWT_PREFER_USER_WORKSPACE_RESOLUTION=ON` on the gateway to try the user's own membership first.
| Step | Default (flag off or unset) | `JWT_PREFER_USER_WORKSPACE_RESOLUTION=ON` |
| - | - | - |
| 1 | `portkey_workspace` claim | `portkey_workspace` claim |
| 2 | `workspace_slug` claim | `workspace_slug` claim |
| 3 | `x-portkey-workspace` header hint (user tokens only) | `x-portkey-workspace` header hint (user tokens only) |
| 4 | Deployment `sub` → workspace mapping | Deployment `sub` → workspace mapping |
| 5 | Deployment default (first allowed workspace) | **The user's own membership** |
| 6 | Organisation default workspace | Deployment default (first allowed workspace) |
| 7 | The user's own membership | Organisation default workspace |
Steps 1–4 are identical in both modes. The flag changes behaviour only for user tokens — those carrying a valid email claim. Service tokens always follow the default order.
If the user-first lookup does not yield a workspace, the gateway falls back through the deployment default and then the organisation default. Membership is re-validated against whichever workspace is finally selected, so a user who is not an active member of the fallback workspace is still rejected with **403**.
#### Just-in-time service access for non-members
By default, a user token that resolves to a workspace it is not a member of is rejected with **403**. Set `JWT_JIT_USER_ACCESS=ON` to instead admit the request as a `WORKSPACE_SERVICE` key: the membership check is skipped, any `x-portkey-workspace` header hint is discarded, and the workspace is resolved the same way it would be for a service token (signed claim → deployment `sub` mapping → deployment default → organisation default).
This trades per-user attribution for availability — use it when non-member requests should still be served under the workspace's service-level limits and policies rather than failing outright.
### Usage limits, rate limits, and policies
JWT-authenticated requests are subject to the same limit and policy checks as API key requests. Limits can come from three places:
| Source | Description |
| - | - |
| **Token claims** | `usage_limits` and `rate_limits` embedded in the JWT (Mode A) |
| **Workspace settings** | Limits configured on the resolved workspace |
| **Workspace policies** | Conditional budget policies based on request context |
Each unique JWT is tracked separately for token-level limits. Workspace limits and policies apply on top of any token-level limits - all must pass before the request proceeds.
**Guidance by mode:**
* **Mode A:** Put per-user or per-session budgets in the JWT `usage_limits` claim. Use workspace limits and policies for shared team budgets.
* **Mode B:** Configure all budgets and rate limits on the workspace or as workspace policies. For per-user splits within a shared workspace, use policies keyed off user metadata.
### Authentication flow
```mermaid theme={"system"}
sequenceDiagram
participant Client
participant Gateway
participant ControlPlane as Control Plane
participant IdP as Your IdP (JWKS)
Client->>Gateway: API request with JWT
alt JWT_ENABLED = ON
Gateway->>Gateway: Resolve org and verify token
Gateway->>IdP: Fetch public keys (if using JWKS URL)
Gateway->>ControlPlane: Load org, deployment, and workspace settings
Gateway->>Gateway: Check scopes, limits, and policies
else JWT_ENABLED ≠ ON
Gateway->>ControlPlane: Validate JWT via control plane
end
Gateway->>Client: Process request or return error
```
### Troubleshooting gateway-local JWT
| Symptom | Likely cause | What to check |
| - | - | - |
| Organisation not found | Token missing org claim on a multi-org gateway | Add `portkey_oid` to the token, or set a single org in `ORGANISATIONS_TO_SYNC` |
| Org not allowed | Org ID not in sync list | Add the org to `ORGANISATIONS_TO_SYNC` or fix the token claim |
| JWKS not configured | No public keys set for the org | Configure JWKS URL or JSON under **Admin Settings** → **Organisation** → **Authentication** |
| JWT verification failed | Bad signature, expired token, or wrong keys | Verify IdP signing config, `exp`, and JWKS |
| No valid scopes | Missing scopes in token and no gateway defaults | Add scopes to the token, or set `JWT_LOCAL_AUTH_DEFAULT_SCOPES` on the gateway |
| User not allowed | User ID restricted by deployment settings | Update deployment allowlist or token `sub` |
| Workspace forbidden | Workspace not allowed for this deployment | Use an allowed workspace or update deployment settings |
### Quick setup checklist
**Both modes:**
* Set `JWT_ENABLED=ON`, `PORTKEY_CLIENT_AUTH`, and `ORGANISATIONS_TO_SYNC` on the gateway
* Configure JWKS for your org in the Portkey admin UI
* Ensure the gateway cache is enabled (required for hybrid and air-gapped deployments)
**Mode A:**
* Issue JWTs with required scopes and optionally `portkey_oid`, `portkey_workspace`, `usage_limits`, `rate_limits`, and `defaults`
**Mode B:**
* Set `ORGANISATIONS_TO_SYNC` to a **single** org UUID
* Configure scopes in your IdP, or set `JWT_LOCAL_AUTH_DEFAULT_SCOPES` on the gateway if IdP scope changes are not possible
* Set up workspace resolution (workspace allowlist or org default workspace)
* Configure workspace-level usage limits, rate limits, and policies in Portkey
## Caching & Token Revocation
Validated JWTs are cached until they expire to reduce validation overhead. On gateway-local auth, org and workspace settings are also cached locally and refreshed during control plane sync.
If you rotate signing keys:
* Publish the new public key in JWKS with a new `kid`.
* Start issuing tokens signed by the new private key (with the new `kid`).
* Old tokens remain valid until their `exp` is reached.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Organizations
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/organizations
Understand the role and features of Organizations, the highest level of abstraction in Portkey's structure.
Organizations in Portkey represent the highest level of abstraction within an account. They serve as containers for all users, entities, and workspaces (if the feature is enabled) associated with your company or project.
Key aspects of Organizations:
* **Comprehensive Scope:** An organization encompasses all the users and entities within it, providing a broad view of your entire operation.
* **Workspace Support:** Organizations can contain workspaces, which act as sub-organizations for more granular team management and project scoping.
* **Hierarchical Roles:** Organizations have owners and org admins who have access to all workspaces and can create and use admin keys.
* **Multi-Org Flexibility:** Portkey offers an org switcher, allowing users to switch between different organizations they have access to.
* **Security Features:** SSO (Single Sign-On) settings are applied at the organization level, enhancing security and user management.
* **Private Cloud Integration:** When deploying a gateway in a private cloud, the connection to the control panel is established at the organization level.
Organizations provide a robust framework for managing large-scale AI development projects, enabling efficient resource allocation, access control, and team management across your entire operation.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Azure Entra
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/scim/azure-ad
Setup Azure Entra for SCIM provisioning with Portkey.
#### Azure Active Directory (Azure AD)
[Reference](https://learn.microsoft.com/en-us/azure/active-directory/app-provisioning/use-scim-to-provision-users-and-groups)
Setting up Azure Entra for SCIM provisioning consists of the following steps:
* **New Entra Application & SCIM Provisioning**
* **Application Roles**
* **SCIM Attribute Mapping Update**
***
##### New Entra Application
First, create a new Azure Entra application to set up SCIM provisioning with Portkey.
1. Navigate to the [Entra Applications Page](https://entra.microsoft.com/?culture=en-in\&country=in#view/Microsoft_AAD_IAM/AppGalleryBladeV2) and click **`Create your own application`**.

2. Complete the required fields to create a new application.
3. Once the application is created, navigate to the application's **Provisioning** page under the **Manage** section.
4. Click **`New Configuration`** to go to the provisioning settings page.

5. Obtain the **Tenant URL** and **Secret Token** from the Portkey Admin Settings page (if SCIM is enabled for your organization).
* [Portkey Settings Page](https://app.portkey.ai/settings/organisation/sso)

6. Fill in the values from the Portkey dashboard in Entra's provisioning settings and click **`Test Connection`**. If successful, click **`Create`**.
> If the test connection returns any errors, please contact [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
##### Application Roles
Portkey supported roles should match Entra's application roles.
1. Navigate to **App Registrations** under **Enterprise Applications**, click **All Applications**, and select the application created earlier.
2. Go to the **App Roles** page and click **`Create app role`**.
> Portkey supports two application-level roles:
>
> * **`member`** (Organization Member)
> * **`admin`** (Organization Admin)
> * **`owner`** (Organization Owner)

> Users assigned any other role will default to the **member** role.
3. To support group roles, create a role with the value **`group`** and a name in title-case (e.g., `Group` for the value `group`).

4. Assign users to the application with the desired role (e.g., **`owner`**, **`member`**, or **`admin`**) for the organization.

***
#### Attribute Mapping
###### Adding a New Attribute
1. Go to the **Provisioning** page and click **Attribute Mapping (Preview)** to access the attributes page.
2. Enable advanced options and click **`Edit attribute list for customappsso`**.

3. Add a new attribute called **`roles`** with the following properties:
* **Multi-valued:** Enabled
* **Type:** String

###### Adding a new mapping
1. Click on the **`Add new mapping`** link to add a new mapping. (refer to the above images).
2. Follow the values from the below image to add a new mapping.

3. Once done, save the changes.
###### Removing Unnecessary Attributes
Delete the following unsupported attributes:
* **preferredLanguage**
* **addresses (all fields)**
* **phoneNumbers**
***
#### Updating Attributes
**Update `displayName`**
1. Edit the **`displayName`** field to concatenate `firstName + lastName` instead of using the default `displayName` value from Entra records.

2. Save the changes and enable provisioning on the **Overview** page of the provisioning settings.
***
> [!TIP]
>
> Looking for Workspace Management? Check out our [Workspace Management](/docs/product/enterprise-offering/org-management/scim/group-management) page.
##### Group (Workspace) Provisioning
Portkey supports RBAC (Role-Based Access Control) for workspaces mapped to groups in Entra. You have two options for mapping groups to workspaces:
**Option 1: Flexible Group Mapping (Recommended)**
Provision groups with any naming convention from Azure Entra, then map them to workspaces and assign roles directly from Portkey Control Plane. This eliminates the need for specific naming formats.
1. Provision your groups from Azure Entra (assign groups to the application)
2. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey
3. Use the **SCIM Mappings List** section to map groups to workspaces and assign roles
For detailed instructions, see the [SCIM Group Management](/docs/product/enterprise-offering/org-management/scim/group-management) guide.
> [!NOTE]
>
> This is the recommended approach as it provides flexibility in group naming and easier management of group-to-workspace mappings.
**Option 2: Naming Convention (Legacy)**
Alternatively, you can use the following naming convention for automatic mapping:
* **Format:** `ws-{group}-role-{role}`
* **Role:** One of `admin`, `member`, or `manager`
* A user should belong to only one group per `{group}`.
**Example:**
For a `Sales` workspace:
* `ws-Sales-role-admin`
* `ws-Sales-role-manager`
* `ws-Sales-role-member`
Users assigned to these groups will inherit the corresponding role in Portkey.
**Custom Prefix and Separator Configuration:**
You can configure your own prefix and separator to match your organization's group naming conventions. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey Control Plane and configure the **Pattern Based SCIM Grouping** section with your preferred prefix and separator.
For example, if you configure:
* **Prefix:** `ws-`
* **Role Separator:** `-role-`
Then your groups should follow: `ws-{group}{role_separator}{admin,manager,member}`
For detailed instructions, see the [SCIM Group Management](/docs/product/enterprise-offering/org-management/scim/group-management#configuring-group-naming-format-optional) guide.

***
### Support
If you face any issues with the group provisioning, please reach out to us at [here](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# SCIM Group Management
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/scim/group-management
Map SCIM groups to Portkey workspaces and roles without naming restrictions.
# SCIM Group Management
Portkey now supports flexible group-to-workspace mapping, allowing you to provision groups from your identity provider (Okta or Azure Entra) with any naming convention and then map them to one or more Portkey workspaces and roles directly from the Portkey Control Plane.
***
## Overview
Previously, SCIM group provisioning required groups to follow a specific naming format (`ws-{group}-role-{role}`) to automatically map to Portkey workspaces. This restriction has been removed.
With the new group management feature, you can:
* **Provision groups with any name** from your identity provider
* **Map a single group to one or more workspaces** after provisioning
* **Assign roles** to all members of a group
* **Manage mappings** directly from Portkey Control Plane
* **Configure custom prefix and separator** for automatic group-to-workspace mapping (optional)
***
## Workflow
The group mapping process follows these steps:
1. **Provision the group** from your identity provider (Okta or Azure Entra)
2. **Map the group** to a Portkey workspace and assign a role from Portkey Control Plane
3. **Users are automatically assigned** to the workspace with the specified role when added to the group
> [!WARNING]
>
> Groups must be provisioned from your identity provider **first** before they can be mapped in Portkey. You cannot map a group that hasn't been provisioned yet.
***
## Provisioning Groups from Identity Provider
Before mapping groups in Portkey, ensure the groups are provisioned from your identity provider.
### For Okta Users
1. Navigate to your Okta application settings
2. Go to the **Push Groups** tab
3. Push the groups you want to map to Portkey
4. Verify the groups appear in Portkey after provisioning
For detailed instructions, refer to the [Okta Group Provisioning](/docs/product/enterprise-offering/org-management/scim/okta#group-provisioning-with-okta) section.
### For Azure Entra Users
1. Navigate to your Azure Entra application
2. Go to the **Provisioning** page
3. Ensure groups are assigned to the application
4. Verify the groups are provisioned to Portkey
For detailed instructions, refer to the [Azure Entra Group Provisioning](/docs/product/enterprise-offering/org-management/scim/azure-ad#group-workspace-provisioning) section.
***
## Configuring Group Naming Format (Optional)
If you prefer automatic group-to-workspace mapping based on naming conventions, you can configure a custom prefix and separator to match your organization's group naming format.
### Default Format
By default, Portkey expects groups to follow this format:
* **Format:** `ws-{Workspace}-role-{admin,manager,member}`
* **Prefix:** `ws`
* **Role Separator:** `-role-`
**Example:**
* `ws-Sales-role-admin`
* `ws-Engineering-role-manager`
* `ws-Marketing-role-member`
* `ws-Complex Workspace-role-admin`
### Custom Configuration
You can configure your own prefix and separator to match your group naming conventions:
1. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey Control Plane
2. Find the **Pattern Based SCIM Grouping** section
3. Configure the following fields:
* **Workspace Prefix**: The prefix used in your group names (e.g., `ws-`, `portkey-`, `org-`)
* **Role Separator**: The character used to separate the role from the workspace (e.g., `-role-`, `_role_`, `.role.`)
4. Click **Save** to apply the configuration
> [!NOTE]
>
> The format will be: `{prefix}{Workspace}{role_separator}{admin,manager,member}`
> Once configured, groups matching this format will automatically map to workspaces with the specified role, without requiring manual mapping in the SCIM Mappings List.
***
## Mapping Groups to Workspaces
Once groups are provisioned from your identity provider, you can map them to Portkey workspaces. A single SCIM group can be mapped to **multiple workspaces**; every member of the group is automatically provisioned into each mapped workspace with the configured role.
1. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey Control Plane
2. Find the **SCIM Mappings List** section
3. Click on the **Add New Mapping** button
4. Select the appropriate fields from the dropdowns:
* **SCIM Group Name**: The name of the group from your identity provider. The dropdown supports search and paginates results, so groups remain easy to locate even with hundreds provisioned.
* **Portkey Workspace**: The workspace to map the group to
* **Role**: The role to assign to the group members
5. Click **Save** to complete the mapping
6. To map the same group to another workspace, repeat the steps above and pick a different workspace. The same group can appear in the mappings list once per workspace.
> [!NOTE]
>
> The role you select will be applied to **all members** added to the group, across **every** workspace the group is mapped to. All users in the group will have the same role in each mapped workspace.
> [!WARNING]
>
> A SCIM group can only be mapped with a **single role** across all of its workspaces. If a group is already mapped to one workspace as `manager`, attempting to map it to another workspace as `admin` will be rejected. Delete the existing mapping(s) first if you need to change the role.
***
### Supported Roles
| Role | Description |
| - | - |
| **Admin** | Full workspace access with management capabilities, including workspace settings and member management |
| **Manager** | Can manage workspace resources, view analytics, and manage members |
| **Member** | Standard workspace access with read and write permissions to workspace resources |
> [!NOTE]
>
> Role names are **case-insensitive**. For example, `Admin`, `admin`, and `ADMIN` are all treated as the same role. This applies to both organization roles and workspace roles in SCIM provisioning.
> [!WARNING]
>
> A role must be selected when mapping a group. The mapping cannot be saved without selecting a role.
***
## Group-Based User Provisioning
By default, when a SCIM group update includes an archived (deprovisioned) user, Portkey will **not** reactivate that user. This is because some identity providers (like Okta) send the full member list on every group update, which could unintentionally reactivate users that were removed.
If your identity provider (such as **JumpCloud**) expects group membership updates to reactivate archived users, you can enable the `group_based_user_provisioning` setting.
### Enabling Group-Based User Provisioning
1. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey Control Plane
2. Enable the **Group-Based User Provisioning** toggle
3. Click **Save**
When enabled:
* Archived users will be **automatically reactivated** when they are included in a SCIM group membership update
* The user will be added back to the workspace mapped to that group with the configured role
> [!WARNING]
>
> Only enable this setting if your identity provider requires it. Enabling this with providers like Okta that send full member lists on every update may cause unintended user reactivations.
***
## Managing Group Mappings
### Viewing Existing Mappings
You can view all group-to-workspace mappings in the **SCIM Mappings List** section of SCIM Provisioning settings. The list is paginated and each mapping displays:
* Group name (from identity provider)
* Mapped workspace
* Assigned role
A group that is mapped to multiple workspaces appears as one row per workspace, all sharing the same role.
### Removing Mappings
To remove a group mapping:
1. Navigate to the **SCIM Mappings List** section
2. Find the group mapping you want to remove
3. Click on the **Delete** icon next to the mapping
Deleting a mapping from Portkey only unlinks the SCIM group from that workspace. **Users already provisioned into the workspace remain as workspace members**, and the workspace itself is **not** archived. Future updates to the SCIM group will simply stop affecting that workspace. Other workspaces the group is still mapped to continue to operate normally.
> [!NOTE]
>
> Workspace and user cleanup only happen when the SCIM group is **deleted at the identity provider** (which sends `DELETE /v1/scim/Groups/{id}` to Portkey). In that path:
>
> * All of the group's workspace mappings are archived
> * For each affected workspace, if no other active mapping remains, users provisioned by the deleted mapping's role are archived
> * The workspace itself is archived only if it is **not** the organization's default/shared workspace
>
> If you need to remove users from a workspace through the UI, remove them via workspace member management — deleting the mapping alone will not do it.
***
## User-Based Group Management Mode (AirGapped only)
By default, group memberships are managed through the SCIM `/Groups` endpoint. For identity providers that manage group assignments through user attributes (e.g., Azure Entra), you can enable **User-Based Group Management Mode**.
When this mode is enabled:
* Group memberships can be managed via the SCIM `/Users` endpoint (create, update, and patch operations)
* The `groups` attribute on SCIM user responses includes the user's current group memberships
* Group member operations on the `/Groups` PATCH endpoint are skipped to avoid conflicts
### Enabling User-Based Group Management
Set the following environment variable on your backend deployment:
```
SCIM_MEMBERSHIP_USER_MODE=ON
```
This mode is useful when your identity provider pushes group membership updates as part of user provisioning rather than group provisioning operations.
***
## Benefits
The flexible group management feature provides several advantages:
* **No naming restrictions** - Use any group naming convention that fits your organization
* **Flexible mapping** - Map groups to workspaces after provisioning
* **One group, many workspaces** - Map a single SCIM group to multiple Portkey workspaces in one go, with one role applied uniformly across all of them
* **Simplified management** - Manage all mappings from Portkey Control Plane
* **Role consistency** - All group members automatically receive the same role across every mapped workspace
* **Custom naming format** - Configure prefix and separator to match your existing group naming conventions for automatic mapping
* **User-based management** - Optionally manage group memberships via the `/Users` endpoint for providers that require it
***
## Support
If you encounter any issues with group management or need assistance with mapping groups to workspaces, please contact our support team via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Okta
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/scim/okta
Set up Okta for SCIM provisioning with Portkey.
Portkey supports provisioning Users & Groups with Okta SAML Apps.
> [!WARNING]
>
> Okta does not support SCIM Provisioning with OIDC apps; only SAML apps are supported.
To set up SCIM provisioning between Portkey and Okta, you must first create a SAML App on Okta.
***
### Setting up SCIM Provisioning
1. Navigate to the app settings. Under general settings, enable the SCIM provisioning checkbox.

> [!NOTE]
>
> The `Provisioning` tab should be visible after enabling SCIM provisioning. Navigate to that page.
2. Obtain the Tenant URL and Secret Token from the Portkey Admin Settings page (if SCIM is enabled for your organization).
* [Portkey Settings Page](https://app.portkey.ai/settings/organisation/sso)

3. Fill in the values from the Portkey dashboard into Okta's provisioning settings and click **`Test Connection`**. If successful, click **`Save`**.
> [!NOTE]
>
> Ensure you choose the Authentication Mode as `HTTP Header`.
4. Check all the boxes as specified in the image below for full support of SCIM provisioning operations.

5. Once the details are saved, you will see two more options along with integration, namely `To App` and `To Okta`.
Select `To App` to configure provisioning from Okta to Portkey.
Enable the following checkboxes:
* Create Users
* Update User Attributes
* Deactivate Users

After saving the settings, the application header should resemble the following image.

This completes the SCIM provisioning settings between Okta and Portkey.
Whenever you assign a `User` or `Group` to the application, Okta automatically pushes the updates to Portkey.
***
### Organisation role support
Portkey supports the following organisation roles:
* **`owner`** (Organization Owner)
* **`admin`** (Organization Admin)
* **`member`** (Organization Member)
Users assigned any other role will default to the **member** role.
#### Editing Attributes
Okta by default doesn't support role attributes. To support role attributes, you need to edit the attributes in Okta.
1. Navigate to the app settings. Under general settings, click on the `Provisioning` tab.
2. Click on the `Go to Profile Editor` button, found under **Attribute Mappings** section.
3. Click on the `Add Attribute` button.
4. Fill the form with the following details:

5. Click on the `Save` button.
#### Verifying the changes
To verify the changes, you can assign a user to the application with the desired role (e.g., **`owner`**, **`member`**, or **`admin`**) for the organization.

> [!WARNING]
>
> Make sure to select only **one** role for a user, if multiple selected user will be assigned to highest qualified role.
***
### Group Provisioning with Okta
Portkey supports RBAC (Role-Based Access Control) for workspaces mapped to groups in Okta. You have two options for mapping groups to workspaces:
**Option 1: Flexible Group Mapping (Recommended)**
Provision groups with any naming convention from Okta, then map them to workspaces and assign roles directly from Portkey Control Plane. This eliminates the need for specific naming formats.
1. Push your groups to Portkey from Okta (see steps below)
2. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey
3. Use the **SCIM Mappings List** section to map groups to workspaces and assign roles
For detailed instructions, see the [SCIM Group Management](/docs/product/enterprise-offering/org-management/scim/group-management) guide.
> [!NOTE]
>
> This is the recommended approach as it provides flexibility in group naming and easier management of group-to-workspace mappings.
**Option 2: Naming Convention (Legacy)**
Alternatively, you can use the following naming convention for automatic mapping:
* **Format:** `ws-{group}-role-{role}`
* **Role:** One of `admin`, `member`, or `manager`
* A user should belong to only one group per `{group}`.
**Example:**
For a `Sales` workspace:
* `ws-Sales-role-admin`
* `ws-Sales-role-manager`
* `ws-Sales-role-member`
Users assigned to these groups will inherit the corresponding role in Portkey.
**Custom Prefix and Separator Configuration:**
You can configure your own prefix and separator to match your organization's group naming conventions. Navigate to **Admin Settings > Authentication Settings > SCIM Provisioning** in Portkey Control Plane and configure the **Pattern Based SCIM Grouping** section with your preferred prefix and separator.
For example, if you configure:
* **Prefix:** `ws-`
* **Role Separator:** `-role-`
Then your groups should follow: `ws-{group}{role_separator}{admin,manager,member}`
For detailed instructions, see the [SCIM Group Management](/docs/product/enterprise-offering/org-management/scim/group-management#configuring-group-naming-format-optional) guide.

> [!WARNING]
>
> Automatic provisioning with Okta works for `Users`, but it does not automatically work for `Groups`.
To support automatic provisioning for groups, you must first push the groups to the App (Portkey). Then, Okta will automatically provision updates.
To push the groups to Portkey, navigate to the `Push Groups` tab. If it is not found, ensure you have followed all the steps correctly and enabled all the fields mentioned in the Provisioning steps.
1. Click on **Push Groups**.

2. Select **Find group by name**.
3. Enter the name of the group, select the group from the list, and click **Save** or **Save & Add Another** to assign a new group.
> [!TIP]
>
> You can also use `Find groups by rule` to push multiple groups using a filter.
> [!NOTE]
>
> If there is any discrepancy or issue with group provisioning, you can retry provisioning by clicking the `Push Now` option. This can be found under the `Push Status` column in the groups list.
***
### Support
If you encounter any issues with group provisioning, please reach out to us [here](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Overview
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/scim/scim
SCIM integration with Portkey.
# SCIM Integration Guide
Portkey supports **SCIM (System for Cross-domain Identity Management)** to automate user provisioning and deprovisioning.
This guide will walk you through integrating SCIM with your identity provider to manage users and workspaces seamlessly.
***
## Table of Contents
* [What is SCIM?](#what-is-scim)
* [SCIM Base URL](#scim-base-url)
* [Authentication](#authentication)
* [Supported Operations](#supported-operations)
* [Required Configuration](#required-configuration)
* [Identity Provider Setup](#identity-provider-setup)
* [Troubleshooting](#troubleshooting)
***
## What is SCIM?
SCIM is an open standard that allows organizations to automate the management of user identities and groups across applications. By integrating with SCIM, you can:
* Automatically provision and update user accounts.
* Deprovision users when they leave your organization.
* Sync user attributes and workspace memberships.
> [!NOTE]
>
> SCIM will only provision users whose email belongs to a **valid and verified domain** configured for your organization in the Portkey dashboard (`Admin Settings > Authentication Settings > Allowed Domains`). Users with unverified or unconfigured domains will not be provisioned.
## SCIM Base URL
To integrate SCIM with our platform, get the SCIM Base URL from Portkey Control Plane.
`Admin Settings > Authentication Settings > SCIM Provisioning > SCIM URL`
## Authentication
We use **Bearer Token Authentication** for SCIM requests.
You need to generate an **API token** from Portkey Control Plane (\`\`Admin Settings > Authentication Settings > SCIM Provisioning\`) and use it as a bearer token in the SCIM requests.
You need to include the following header in the SCIM requests:
```
Authorization: Bearer
```
## Supported Operations
Our SCIM implementation supports the following operations:
| Operation | Supported |
| - | - |
| User Provisioning | ✅ |
| User Deprovisioning | ✅ |
| User Updates | ✅ |
| Group (Workspace) Provisioning | ✅ |
| Group (Workspace) Updates | ✅ |
| Group (Workspace) Deprovisioning | ✅ |
## Required Configuration
Before integrating SCIM, ensure you have the following details:
* **SCIM Base URL**: Provided above.
* **Bearer Token**: Generate this token from our platform’s **API Settings** section.
You will need to provide these details in your identity provider's SCIM configuration section.
## Identity Provider Setup
Follow your identity provider's documentation to set up SCIM integration. Below are the key fields you’ll need to configure:
| Field | Value |
| - | - |
| SCIM Base URL | `` |
| Bearer Token | `` |
Currently, we support SCIM provisioning for the following identity providers:
* [Azure AD](./azure-ad)
* [Okta](./okta)
## Troubleshooting
### Common Issues
* **Invalid Token**: Ensure the bearer token is correctly generated and included in the request header.
* **403 Forbidden**: Check if the provided SCIM Base URL and token are correct.
* **User Not Provisioned**: Ensure the user attributes meet our platform's requirements.
***
For further assistance, please contact our support team via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# SSO
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/sso
SSO support for enterprises
Portkey Control plane supports following authentication protocols for enterprise customers.
1. **OIDC** (OpenID Connect)
2. **SAML 2.0** (Security Assertion Markup Language)
Below are the steps to integrate your identity provider with our system.
> [!NOTE]
>
> **Auto-Provisioning**: First-time SSO users are automatically provisioned to your organization when they log in. If a user has a pending invite, it will be automatically accepted during their first SSO login.
>
> To restrict access to invited users only, enable **`disable_auto_provision_user`** in your authentication settings. Users without a pending invite are then denied at login, and invited users must still belong to a verified allowed domain.
> [!NOTE]
>
> SSO will only provision users whose email belongs to a **valid and verified domain** configured for your organization in the Portkey dashboard (`Admin Settings > Authentication Settings > Allowed Domains`). Users with unverified or unconfigured domains will not be provisioned.
## Table of Contents
* [OIDC Integration](#oidc-integration)
* [SAML Integration](#saml-integration)
## OIDC Integration
For OIDC integration, we require the following information from your identity provider:
### Required Information
* **Issuer URL**: The URL of your identity provider's OIDC authorization endpoint. Wellknown OIDC configuration should be available at this URL.
* **Client ID**: The client ID provided by your identity provider.
* **Client Secret Key**: The client secret provided by your identity provider.
### Client Authentication Method
By default Portkey authenticates to your identity provider's token endpoint with `client_secret_basic`. If your provider requires a different method, set **`token_endpoint_auth_method`** in your OIDC settings (for example `client_secret_post` or `private_key_jwt`).
For `private_key_jwt`, also supply a **`jwks`** object containing your client's private key set; register the matching public JWKS with your identity provider. When a JWKS is supplied without an explicit method, Portkey uses `private_key_jwt` automatically.
> [!NOTE]
>
> Self-hosted deployments running in single-organisation SSO mode configure the same behaviour through the `OIDC_TOKEN_ENDPOINT_AUTH_METHOD` and `OIDC_CLIENT_JWKS` environment variables on the backend service.
### Setup Steps
> [!NOTE]
>
> Following scopes are required for Portkey to work with OIDC:
>
> * openid
> * profile
> * email
> * offline\_access
>
> For airgapped deployments, you can configure additional custom OIDC scopes by setting the `OIDC_CUSTOM_SCOPES` environment variable (comma-separated list) on the backend service.
#### General
* Create an OIDC application in your identity provider.
* Once the application is created, please note the following details:
* `Issuer URL`
* `Client Id`
* `Client Secret`
* Update the above details in Portkey Control Plane in `Admin Settings > Authentication Settings > OIDC`.
#### Okta
* Go to `Applications` tab on Okta dashboard and `create a new app integration`.
* Select `OIDC - OpenID Connect` as the signin method.
* Select Application Type as `Web` Application
* On the next step, fill in the required fields. The `signin redirect URI` should be [https://app.portkey.ai/v2/auth/callback](https://app.portkey.ai/v2/auth/callback) and the `Grant Type` should have `Authorization code` and `Refresh Token` as checked
* Create Application
* After the application is created, go to the `General` section of the application.
* Click on the `edit` button for the General Settings section.
* Select `Either Okta or app` for the `Login initiated by` field.
* Add [https://app.portkey.ai/v2/auth/callback](https://app.portkey.ai/v2/auth/callback) as the `initiate login URI`
* Go to the `Sign On` section and click on `Edit`. Select `Okta Url` as the `issuer` and save the updated details
* Once everything is setup please note the following details
* `Issuer URL` will be the `Issuer` from above step
* `Client Id` would be same as `Audience`/ `Client ID`
* `Client Secret` is needed for Web App based flow. It can be found under `General > Client Credentials > Client Secrets` in your Okta App.
* Update the above details in Portkey Control Plane in `Admin Settings > Authentication Settings > OIDC`
#### Azure AD
* Sign in to the Azure portal.
* Search for and select Azure Active Directory.
* Under Manage, select App registrations.
* Select New registration.
* Enter a name.
* Select one of the Supported account types that best reflects your organization requirements.
* Under `Redirect URI`,
* Select `Web` as the platform
* Enter [https://app.portkey.ai/v2/auth/callback](https://app.portkey.ai/v2/auth/callback) as redirect url
* Click on Register
* Once saved, go to `Certificates & secrets`
* Click on `Client Secrets`
* Click on `New client secret`
* Use appropriate settings according to your organization
* Click on `Add`
* Once everything is set up. Please go to `Overview`
* Click on `Endpoints` and note the `OpenID Connect metadata document` url
* Please note the `Application (client) ID` from `Essentials`
* Please note the `Client Secret` from `Certificates & secrets`
* Update the above details in Portkey Control Plane in `Admin Settings > Authentication Settings > OIDC`
## SAML Integration
For SAML integration, we require the following information from your identity provider:
### Required Information
Either of the following information is required:
* **Provider Metadata URL**: The URL from your identity provider containing the metadata, including SAML configuration details.
* **Provider Metadata XML**: The XML metadata of your identity provider.
### Setup Steps
#### General
* Create an SAML application in your identity provider.
* Once the application is created, please note the following details:
* `Provider Metadata URL`
* `Provider Metadata XML`
* Update the above details in Portkey Control Plane in `Admin Settings > Authentication Settings > SAML`.
#### Okta
* Go to `Applications` tab on okta dashboard and `create a new app integration`.
* Select `SAML 2.0` as the signin method.
* In `Configure SAML`, update
* `Single sign-on URL` with Saml redirect url. You can find the Saml redirect url from the `Admin Settings > Authentication Settings > SAML Redirect/Consumer Service URL` from Portkey Control Plane.
* `Audience URI (SP Entity ID)` with SAML Entity ID from Portkey Control Plane.
* Create Application
* Once everything is set up, please note the following details
* `Sign On tab > SAML 2.0 tab > Metadata details > Metadata URL`
* Update the above details in Portkey Control Plane in `Admin Settings > Authentication Settings > SAML`
#### Azure AD
* Sign in to the Azure portal.
* Search for and select Azure Active Directory.
* Under Manage, select App registrations.
* Select New registration.
* Enter a name.
* Select one of the Supported account types that best reflects your organization requirements.
* Under `Redirect URI`,
* Select `Web` as the platform
* Enter the `SAML Redirect/Consumer Service URL` from Portkey Control Plane as redirect url
* Select `Register`.
* Select `Endpoints` at the top of the page.
* Find the `Federation metadata document URL` and select the copy icon.
* In the left side panel, select `Expose an API`.
* To the right of `Application ID URI`, select `Add`.
* Enter `SAML Entity ID` from Portkey Control Plane as the `App ID URI`.
* Select `Save`.
* Once everything is set up, please note the following details
* Copy the `Federation metadata document URL` and paste it in Portkey Control Plane in `Admin Settings > Authentication Settings > SAML > Provider Metadata URL`
***
## Allowed Domains
In `Admin Settings > Authentication Settings`, you can configure **Allowed Domains** to restrict which email domains are permitted to authenticate with your organization. You can add one or more domains (e.g., `example.com`) to control access.
### Subdomain Support
You can enable the **`allow_subdomains`** flag on a root domain to automatically allow authentication from **all subdomains** under that root domain.
For example, if you add `example.com` as an allowed domain and enable `allow_subdomains`, users with emails from any subdomain like `dev.example.com`, `team.example.com`, or `us.example.com` will also be allowed to authenticate.
> [!WARNING]
>
> The `allow_subdomains` flag can only be enabled on **root domains**. If you attempt to enable it on a subdomain (e.g., `dev.example.com`), the operation will fail and return an error. Always set this flag on the root domain instead.
| Configuration | `allow_subdomains` | Allowed Emails |
| - | - | - |
| `example.com` | Disabled | Only `*@example.com` |
| `example.com` | Enabled | `*@example.com`, `*@dev.example.com`, `*@team.example.com`, etc. |
| `dev.example.com` | Enabled | **Error** — flag only works on root domains |
| `dev.example.com` | Disabled | Only `*@dev.example.com` |
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# User Roles & Permissions
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/user-roles-and-permissions
Learn about Portkey's comprehensive role-based access control system across Organizations and Workspaces.
Portkey implements a comprehensive role-based access control (RBAC) system that operates across two main hierarchical levels: **Organizations** and **Workspaces**. This dual-layer approach ensures precise control over who can access what resources, enhancing security while enabling effective team collaboration.
## Organization Level
Organizations represent the highest level of structure within Portkey. At this level, there are three distinct roles with varying levels of administrative control:
> [card] Owner
>
> The highest authority with complete control of the organization
> [card] Admin
>
> Extensive administrative privileges across the organization
> [card] Member
>
> Base-level organization access, typically assigned to workspace roles
### Organization Role Permissions
| Capability | Owner | Admin | Member (without workspace) |
| - | :-: | :-: | :-: |
| Billing Management | | | |
| Manage Organization Settings | | | |
| Create/Delete Workspaces | | | |
| Manage Admin API Keys | | | |
| Edit User Roles | | | |
| Invite Organization Users | | | |
| Configure Access Permissions | | | |
| Access to All Workspaces | | | |
> [!NOTE]
>
> **Important**: Organization Owners and Admins automatically receive Admin-level access to all workspaces within the organization. All users must first be added as Organization Members before they can be invited to any workspace.
## Workspace Level
Workspaces are sub-organizational units that enable better team and project management. Each workspace maintains its own access control structure with three distinct roles:
> [card] Admin
>
> Complete control over workspace configuration and team management
> [card] Manager
>
> Administrative capabilities for team and resource management
> [card] Member
>
> Limited write access (own API keys, configs, prompts) with read-only access to other resources
### Workspace Role Permissions
| Capability | Admin | Manager | Member |
| - | :-: | :-: | :-: |
| Invite Organization Members to Workspace | | | |
| Assign Workspace Roles (including Admin) | | | |
| Update Workspace Settings | | | |
| Create/Update/Delete Service API Keys | | | |
| Create/Update/Delete User API Keys (own keys only for Members) | | | |
| Create/Update Prompts | | | |
| Publish/Delete Prompts | | | |
| Create/Update/Delete Configs | | | |
| Create/Update/Delete Guardrails | | | |
| Create/Update/Delete Policies | | | |
| Create/Update/Delete Providers | | | |
| Create/Update/Delete Virtual Keys | | | |
| View/List/Copy Virtual Keys | | | |
| Create/Update/Delete MCP Servers | | | |
| View/List MCP Servers | | | |
| Create/Update/Delete Agent Servers | | | |
| View/List Agent Servers | | | |
| Create/Update Workspace Integrations | | | |
| View Logs & Analytics | | | |
| Export Logs & Analytics | | | |
| View All Other Workspace Resources | | | |
> [!NOTE]
>
> **Member Access**: Workspace Members can create, update, and delete their own **User API Keys**, **Configs**, and **Prompts** (except publish/delete). For all other resources, Members have read-only access.
> [!WARNING]
>
> **API Key Privilege Escalation Prevention**: A user cannot modify an API key that carries permissions exceeding their own role. This is a security measure to prevent privilege escalation. If a legacy API key needs updating, an admin should retire it and create a new one with appropriately scoped permissions.
## Access Permission Configuration
Organization Owners and Admins can configure access permissions for various resources across workspaces. These settings determine what each role can access:
> [!NOTE]
>
> By default Workspace Admins and Managers have the same permissions unless changed by Organization Owner or Admin.
> [card] [Logs Access Permissions](/docs/product/administration/configure-logs-access-permissions-in-workspace)
>
> Control which roles can view, filter, and export logs
> [card] [Analytics Access Permissions](/docs/product/administration/configure-analytics-access-permissions)
>
> Control which roles can view analytics dashboards
> [card] [Providers Access Permissions](/docs/product/model-catalog)
>
> Manage access to LLM providers for different roles
> [card] [API Key Permissions](/docs/product/administration/configure-api-key-access-permissions)
>
> Configure API key creation and management rights
> [!NOTE]
>
> **Key Workflow**: Users must first be added as organization members before they can be invited to any workspace. Workspace admins and managers can then invite organization members to their workspace and assign appropriate roles.
## Related Topics
> [card] [Organizations](/docs/product/enterprise-offering/org-management/organizations)
> [card] [Workspaces](/docs/api-reference/admin-api/control-plane/workspaces/create-workspace)
> [card] [API Keys (AuthN and AuthZ)](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
> [card] [Access Control Management](/docs/product/enterprise-offering/access-control-management)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Workspaces
Source: https://docs.portkey.ai/docs/product/enterprise-offering/org-management/workspaces
Explore Workspaces, the sub-organizational units that enable granular project and team management.
## Workspaces
Workspaces in Portkey are sub-organizations that enable better separation of data, teams, scope, and visibility within your larger organization.
They provide a more granular level of control and organization, allowing you to structure your projects and teams efficiently.
Key features of Workspaces:
* **Team Management:** You can add team members to workspaces with specific roles (manager or member), allowing for precise access control.
* **Dedicated API Keys:** Workspaces contain their own API keys, which can be of two types:
* Service Account type: For automated processes and integrations
* User type: For individual user access
* Both these types of keys are scoped to the workspace by default and can only execute actions within that workspace.
* **Completion API Scoping:** Completion APIs are always scoped by workspace and can only be accessed using workspace API keys.
* **Admin Control:** While only org admins can create workspaces, managers can add API keys and team members with roles to existing workspaces.
* **Flexible Updates:** When making updates to entities via admin keys (at the org level), you can specify the `workspace_id` to target specific workspaces.
Workspaces provide a powerful way to organize your projects, teams, and resources within your larger organization, ensuring proper access control and data separation.
```mermaid theme={"system"}
graph TD
A[Workspace] --> B[Team]
B --> C[Managers]
B --> D[Members]
A --> E[Workspace API Keys]
E --> F[Service Account Type]
E --> G[User Type]
A --> H[Scoped Features]
H --> I[Logs]
H --> J[Prompts]
H --> K[Providers]
H --> L[Configs]
H --> M[Guardrails]
H --> N[Other Features]
```
This structure allows for efficient management of resources and access within each workspace, providing a clear separation between different projects or teams within your organization.
### Deleting a Workspace
> [!NOTE]
>
> * Before deleting a workspace, all resources within it must be removed.
> * You can't delete the default Shared Team Workspace.
To delete a workspace in Portkey, follow these steps:
1. Navigate to the sidebar in the Portkey app
2. Open the workspace menu dropdown
3. Select the workspace you wish to delete
4. Click on the delete option (trash icon) next to the workspace name
When attempting to delete a workspace, you'll receive a confirmation dialog. If the workspace still contains resources, you'll see a warning message prompting you to delete these resources first.

Workspace deletion confirmation
Resources that must be deleted before removing a workspace like - Prompts, Prompt partials, Providers, Configs, Guardrails and more.
Once all resources have been removed, enter the workspace name in the confirmation field to proceed with deletion.
> [!WARNING]
>
> Workspace deletion is permanent and cannot be undone
Alternatively you can also delete workspaces using the Admin API:
> [card] [Delete a Workspace API](/docs/api-reference/admin-api/control-plane/workspaces/delete-a-workspace)
### Related Topics
> [card] [Organizations](/docs/product/enterprise-offering/org-management/organizations)
> [card] [User Roles & Permissions](/docs/product/enterprise-offering/org-management/user-roles-and-permissions)
> [card] [API Keys (AuthN and AuthZ)](/docs/product/enterprise-offering/org-management/api-keys-authn-and-authz)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Analytics Export
Source: https://docs.portkey.ai/docs/product/enterprise-offering/otel/analytics
Export Portkey analytics data to OpenTelemetry-compatible collectors for centralized observability
Portkey supports sending your Analytics data to OpenTelemetry (OTel) compatible collectors, allowing you to integrate Portkey's analytics with your existing observability infrastructure.
## Overview
While Portkey leverages Clickhouse as the primary Analytics Store for the Control Panel by default, enterprise customers can integrate Portkey's analytics data with their existing data infrastructure through OpenTelemetry.
This export focuses on **aggregated metrics and analytics data** such as:
* Request counts and latency metrics
* Token usage statistics
* Cost tracking data
* Error rates and status codes
> [!NOTE]
>
> For exporting complete request/response logs with full prompt and completion content, see [Complete Logs Export](/docs/product/enterprise-offering/otel/complete-logs).
## Configuration
Portkey supports pushing your analytics data to an OTel compatible endpoint. The following environment variables are needed for pushing to OTel:
```yaml theme={"system"}
OTEL_PUSH_ENABLED: true
OTEL_ENDPOINT: http://localhost:4318
OTEL_EXPORTER_OTLP_HEADERS: x-api-key=my-api-key,x-another-header=value
```
### Environment Variables
| Variable | Required | Description |
| - | - | - |
| `OTEL_PUSH_ENABLED` | Yes | Set to `true` to enable analytics export |
| `OTEL_ENDPOINT` | Yes | The OTLP endpoint URL |
| `OTEL_EXPORTER_OTLP_HEADERS` | No | Comma-separated headers in `key=value` format |
### Resource Attributes
You can configure arbitrary resource attributes of the OTel logs by setting a comma-separated value for `OTEL_RESOURCE_ATTRIBUTES`:
```yaml theme={"system"}
OTEL_SERVICE_NAME: portkey-gateway
OTEL_RESOURCE_ATTRIBUTES: ApplicationShortName=gateway,AssetId=12323,deployment.service=production
```
| Variable | Description |
| - | - |
| `OTEL_SERVICE_NAME` | Service name for the telemetry data |
| `OTEL_RESOURCE_ATTRIBUTES` | Comma-separated key=value pairs for additional resource attributes |
### Experimental Gen AI OTEL Traces
You can push experimental traces directly to your specific OTEL target using the following configuration variables:
```yaml theme={"system"}
EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED: true
EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT: http://localhost:4318
EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS: x-api-key=my-api-key,x-another-header=value
EXPERIMENTAL_GEN_AI_OTEL_RESOURCE_ATTRIBUTES: ApplicationShortName=agent-test,AssetId=12323,deployment.service=production
```
| Variable | Description |
| - | - |
| `EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED` | Set to `true` to enable experimental gen AI traces |
| `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT` | The OTLP endpoint URL for Gen AI Traces |
| `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS` | Comma-separated headers in `key=value` format |
| `EXPERIMENTAL_GEN_AI_OTEL_RESOURCE_ATTRIBUTES` | Comma-separated key=value pairs for additional resource attributes |
## Integration Options
Enterprise customers commonly use these analytics exports with:
* **Datadog**: Monitor and analyze your AI operations alongside other application metrics
* **AWS S3**: Store analytics data for long-term retention and analysis
* **Prometheus/Grafana**: Build custom dashboards and alerting
* **Splunk**: Integrate with existing SIEM infrastructure
* **Other OTel-compatible systems**: Any system that can ingest OpenTelemetry data
## Use Cases
This feature enables:
* Centralized observability across your entire tech stack
* Long-term storage of analytics data
* Custom analytics dashboards in your preferred tools
* Integration with existing alerting systems
* Compliance and audit trail requirements
## Getting Support
For additional assistance with setting up analytics data export:
* Reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form)
Our team can help you with best practices for configuring your OTel collectors and integrating with your existing systems.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Complete Logs Export
Source: https://docs.portkey.ai/docs/product/enterprise-offering/otel/complete-logs
Export complete LLM request/response logs to OpenTelemetry endpoints following GenAI semantic conventions
> [!NOTE]
>
> This is an experimental feature available for **Enterprise** and **Self-Hosted** deployments only.
## Overview
Portkey Gateway can push complete LLM request/response logs to any OpenTelemetry-compatible endpoint, following the [experimental semantic conventions for Generative AI](https://opentelemetry.io/docs/specs/semconv/gen-ai/gen-ai-spans/). This enables integration with external observability platforms like LangSmith, Datadog, Honeycomb, or any OTLP-compatible collector.
Unlike the [Analytics Export](/docs/product/enterprise-offering/otel/analytics), this feature exports **complete logs** including:
* Full prompt and completion content
* Tool definitions and function calls
* All request parameters (temperature, max\_tokens, etc.)
* Complete response metadata
### Why Use This Feature?
* **Unified Observability**: Consolidate LLM telemetry with your existing monitoring infrastructure
* **External Analysis**: Send Portkey logs to specialized GenAI observability tools like LangSmith
* **Standards-Based**: Follows OpenTelemetry GenAI semantic conventions for consistent attribute naming
* **Zero Code Changes**: Enable via environment variables without modifying application code
## Scope
### Included
* Automatic log export to OTLP-compatible HTTP endpoints
* Full GenAI semantic convention attribute mapping
* Request parameters, response metadata, and token usage
* Tool definitions and prompt/completion content
* LangSmith-compatible attribute overrides
### Out of Scope
* gRPC OTLP transport (HTTP/JSON only)
* Metrics export (use [Analytics Export](/docs/product/enterprise-offering/otel/analytics) for that)
* Custom attribute mapping configuration
## Architecture
```mermaid theme={"system"}
graph LR
subgraph Portkey Gateway
REQ[Incoming Request]
PROC[Request Processing]
LOG[Log Generation]
PUSH[OTel Exporter]
end
LLM[LLM Provider]
OTel[External OTel Endpoint]
REQ --> PROC
PROC --> LLM
LLM --> PROC
PROC --> LOG
LOG --> PUSH
PUSH --> OTel
```
**Data Flow:**
1. LLM request is processed through Portkey Gateway
2. After receiving the LLM response, a log object is generated
3. The log is transformed into OTLP span format with GenAI semantic attributes
4. The span is pushed to the configured external OTLP endpoint
## Configuration
### Environment Variables
| Variable | Required | Description |
| - | - | - |
| `EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED` | Yes | Set to `true` to enable log pushing |
| `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT` | Yes | The OTLP endpoint URL (without `/v1/traces` suffix) |
| `EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS` | No | Comma-separated headers in `key=value` format |
| `EXPERIMENTAL_GEN_AI_OTEL_RESOURCE_ATTRIBUTES` | No | Comma-separated `key=value` pairs added as OTLP resource attributes |
### Example Configuration
> [tab] LangSmith
>
> ```yaml theme={"system"}
> EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED: "true"
> EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT: https://api.smith.langchain.com/otel
> EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS: x-api-key=
> ```
> [tab] Datadog
>
> ```yaml theme={"system"}
> EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED: "true"
> EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT: https://http-intake.logs.datadoghq.com/api/v2/otlp
> EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS: DD-API-KEY=
> ```
> [tab] Custom Collector
>
> ```yaml theme={"system"}
> EXPERIMENTAL_GEN_AI_OTEL_TRACES_ENABLED: "true"
> EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318
> EXPERIMENTAL_GEN_AI_OTEL_EXPORTER_OTLP_HEADERS: Authorization=Bearer
> ```
> [!NOTE]
>
> The endpoint should be the base OTLP URL. Portkey automatically appends `/v1/traces` when sending data.
## Span Attributes
Logs are exported as OpenTelemetry spans with attributes following the [GenAI semantic conventions](https://github.com/open-telemetry/semantic-conventions/blob/main/model/gen-ai/spans.yaml).
### Resource Attributes
| Attribute | Value | Description |
| - | - | - |
| `service.name` | `portkey` | Service identifier |
| `otel.semconv.version` | `1.40.0` | Semantic convention version |
| Custom attributes | Configurable | Additional attributes from `EXPERIMENTAL_GEN_AI_OTEL_RESOURCE_ATTRIBUTES` |
### Portkey Tenant Attributes
These attributes are set on all spans and identify the Portkey organisation, workspace, and user associated with the request:
| Attribute | Source | Description |
| - | - | - |
| `portkey.organisation.id` | Metrics | Organisation ID in Portkey |
| `portkey.workspace.slug` | Metrics | Slug of the workspace that made the request |
| `portkey.user.id` | Metrics | User ID or API key ID that initiated the request |
### Portkey Metadata and Cost Attributes
These attributes are set on generation spans when the data is available:
| Attribute | Source | Description |
| - | - | - |
| `portkey.metadata.` | Request metadata | One attribute per [metadata](/docs/product/observability/metadata) key sent with the request, for example `portkey.metadata.team` |
| `portkey.usage.cost` | Metrics | Cost of the request, exported as a double. Set only when the cost is known. |
| `portkey.usage.cost_currency` | Metrics | Currency of `portkey.usage.cost` |
### Common Attributes
These attributes are set on all spans (inference and embeddings):
| Attribute | Source | Description |
| - | - | - |
| `gen_ai.operation.name` | Derived | Operation type: `chat`, `embeddings`, or derived from request URL |
| `gen_ai.provider.name` | Metrics | Semconv-normalized provider name (e.g., `openai`, `anthropic`, `aws.bedrock`, `azure.ai.openai`) |
| `gen_ai.system` | Metrics | Backward-compatible alias for `gen_ai.provider.name` |
| `gen_ai.request.model` | Request body | Model identifier |
| `gen_ai.response.model` | Response body | Model used for generation |
| `server.address` | Request URL | Provider endpoint hostname |
| `server.port` | Request URL | Server port (derived from URL, 443 for HTTPS) |
| `error.type` | Response | HTTP status code (for errors ≥300) |
### Inference Attributes
These attributes are set on inference (chat completion) spans:
| Attribute | Source | Description |
| - | - | - |
| `gen_ai.request.max_tokens` | Request body | Maximum tokens to generate (from `max_tokens` or `max_completion_tokens`) |
| `gen_ai.request.temperature` | Request body | Sampling temperature |
| `gen_ai.request.top_p` | Request body | Top-p sampling parameter |
| `gen_ai.request.top_k` | Request body | Top-k sampling parameter |
| `gen_ai.request.stop_sequences` | Request body | Stop sequences |
| `gen_ai.request.frequency_penalty` | Request body | Frequency penalty |
| `gen_ai.request.presence_penalty` | Request body | Presence penalty |
| `gen_ai.request.seed` | Request body | Random seed |
| `gen_ai.request.choice.count` | Request body | Number of choices requested (only set when > 1) |
| `gen_ai.response.id` | Response body | Response identifier |
| `gen_ai.response.finish_reasons` | Response body | Normalized finish reasons (e.g., `tool_use`/`tool_calls`/`function_call` → `tool_call`) |
| `gen_ai.usage.input_tokens` | Response usage | Input token count |
| `gen_ai.usage.output_tokens` | Response usage | Output token count |
| `gen_ai.usage.cache_creation.input_tokens` | Response usage | Tokens written to prompt cache |
| `gen_ai.usage.cache_read.input_tokens` | Response usage | Tokens read from prompt cache |
| `gen_ai.conversation.id` | Request/Response | Conversation or thread identifier |
| `gen_ai.output.type` | Request body | Output format type: `json`, `image`, `speech`, or `text` |
### Embeddings Attributes
These attributes are set on embeddings spans:
| Attribute | Source | Description |
| - | - | - |
| `gen_ai.request.encoding_formats` | Request body | Requested encoding formats |
| `gen_ai.embeddings.dimension.count` | Request body | Embedding dimensions |
| `gen_ai.usage.input_tokens` | Response usage | Input token count |
### Message Attributes
Messages are exported using structured semconv 1.40.0 format with role-based grouping and multimodal part normalization:
| Attribute | Description |
| - | - |
| `gen_ai.input.messages` | Array of input messages (excluding system), each with `role` and `parts` (text, tool\_call, tool\_call\_response, image, audio, file, reasoning) |
| `gen_ai.system_instructions` | System message content extracted as instruction parts |
| `gen_ai.output.messages` | Array of output messages, each with `role`, `parts`, and `finish_reason` |
| `gen_ai.tool.definitions` | Array of tool definitions from request |
> [!NOTE]
>
> Tool call semantics are normalized across providers: `tool_use` (Anthropic), `tool_calls` (OpenAI), and `function_call` are all mapped to the standard `tool_call` type.
## Span Structure
Each log is exported as a span with the following structure:
```json theme={"system"}
{
"resourceSpans": [{
"resource": {
"attributes": [
{ "key": "service.name", "value": { "stringValue": "portkey" } },
{ "key": "otel.semconv.version", "value": { "stringValue": "1.40.0" } }
]
},
"scopeSpans": [{
"scope": { "name": "custom.genai.instrumentation" },
"spans": [{
"traceId": "<32-char-hex>",
"spanId": "<16-char-hex>",
"parentSpanId": "",
"name": "chat gpt-4o",
"kind": 3,
"startTimeUnixNano": "",
"endTimeUnixNano": "",
"status": { "code": 1, "message": "200" },
"attributes": [/* GenAI attributes */]
}]
}]
}]
}
```
* **Span name** follows the format `{operation_name} {model}` (e.g., `chat gpt-4o`, `embeddings text-embedding-3-small`)
* **Span kind** is `CLIENT` (3), reflecting that the gateway acts as a client to the LLM provider
## Trace Context
The feature preserves trace context from incoming requests:
* **Trace ID**: Uses Portkey's trace ID if valid (32 hex chars), otherwise generates a new one
* **Span ID**: Uses Portkey's span ID if valid (16 hex chars), otherwise generates a new one
* **Parent Span ID**: Preserved from parent request if available
This allows correlation with upstream traces in distributed tracing scenarios.
## Error Handling
* **Export Failures**: Logged internally; does not affect request processing
* **Invalid Endpoints**: Connection errors are caught and logged
* **Malformed Responses**: Error responses from the OTLP endpoint are logged with status text
> [!WARNING]
>
> Export failures do not block or retry the LLM request. Logs may be lost if the external endpoint is unavailable.
## Performance Considerations
* **Async Processing**: Log export runs in parallel with other post-request handlers
* **No Request Latency Impact**: Export happens after the response is returned
* **HTTP/JSON Protocol**: Uses standard HTTP POST with JSON payload
## Security Considerations
> [!WARNING]
>
> When enabled, request/response content including prompts and completions are sent to the external endpoint. Ensure your endpoint is trusted and properly secured.
* **Authentication**: Use the headers configuration to pass API keys or bearer tokens
* **Data Sensitivity**: Prompt and completion content is included in exports
* **Network Security**: Use HTTPS endpoints for production deployments
## Integration with LangSmith
Portkey exports spans using the semconv 1.40.0 structured message format (`gen_ai.input.messages`, `gen_ai.output.messages`, `gen_ai.system_instructions`), which is compatible with LangSmith and other modern GenAI observability tools.
For LangSmith setup, refer to [LangSmith OpenTelemetry documentation](https://docs.smith.langchain.com/observability/how_to_guides/trace_with_opentelemetry).
## Verification
To verify the feature is working:
1. Enable the feature with your endpoint configuration
2. Make an LLM request through Portkey Gateway
3. Check your external observability platform for incoming spans
4. Verify spans contain expected GenAI attributes
## Known Limitations
> [!WARNING]
>
> The [OpenTelemetry GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/gen-ai-spans/) are experimental and subject to change. Attribute names may evolve as the specification stabilizes.
* **HTTP Only**: gRPC OTLP protocol is not supported
* **No Batching**: Each log is pushed individually (no span batching)
* **No Retry Logic**: Failed exports are not retried
* **Experimental Conventions**: GenAI semantic conventions may change
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# OpenTelemetry(OTel) Export
Source: https://docs.portkey.ai/docs/product/enterprise-offering/otel/otel
Export Portkey data to OpenTelemetry compatible endpoints for external observability
Portkey supports exporting data to OpenTelemetry (OTel) compatible collectors, enabling integration with your existing observability infrastructure. Choose the export type based on your needs:
> [card] [Analytics](/docs/product/enterprise-offering/otel/analytics)
>
> Export aggregated analytics data including request counts, latency metrics, token usage, and cost tracking to OTel-compatible collectors.
> [card] [Complete Logs](/docs/product/enterprise-offering/otel/complete-logs)
>
> Export complete LLM request/response logs with full prompt and completion content following GenAI semantic conventions.
## Comparison
| Feature | Analytics | Complete Logs |
| - | - | - |
| **Data Type** | Aggregated metrics | Full request/response logs |
| **Includes Prompts** | No | Yes |
| **Includes Completions** | No | Yes |
| **Token Usage** | Yes | Yes |
| **Latency Metrics** | Yes | Yes |
| **GenAI Semantic Conventions** | No | Yes |
| **LangSmith Compatible** | No | Yes |
| **Status** | Stable | Experimental |
## Use Cases
### Analytics
Best for:
* Building dashboards in Datadog, Grafana, or similar tools
* Setting up alerts on error rates or latency
* Long-term storage of usage metrics
* Cost tracking and attribution
### Complete Logs
Best for:
* Debugging specific LLM interactions
* Quality analysis of prompt/completion pairs
* Integration with LangSmith or similar GenAI observability tools
* Compliance requirements needing full audit trails
## Getting Started
**1. Choose your export type**
Determine whether you need aggregated metrics or complete logs based on your use case
**2. Configure environment variables**
Set the appropriate environment variables for your chosen export type
**3. Deploy and verify**
Redeploy your Portkey Gateway and verify data appears in your OTel collector
> [!NOTE]
>
> Both export types can be enabled simultaneously if you need both aggregated metrics and complete logs.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Secret References
Source: https://docs.portkey.ai/docs/product/enterprise-offering/secret-references
Reference secrets stored in external secret managers like AWS Secrets Manager, Azure Key Vault, and HashiCorp Vault instead of storing them directly in Portkey.
Secret References let you point Portkey to credentials stored in your external vault. Instead of entering keys directly in Portkey, you create a **reference**, that tells Portkey where to fetch the value at runtime.
This keeps sensitive material in infrastructure you already control and audit.
> [!NOTE]
>
> Available on **Enterprise** plans only. Requires:
>
> * Gateway version **2.2.4** or higher
> * Backend version **1.12.0** or higher (for air-gapped deployments).
## Supported Secret Managers
| Manager | `manager_type` value |
| - | - |
| AWS Secrets Manager | `aws_sm` |
| Azure Key Vault | `azure_kv` |
| HashiCorp Vault | `hashicorp_vault` |
## How It Works
Secret references use a split architecture between Portkey's **control plane** and **data plane**:
1. You create a **secret reference** in Portkey via the API. The control plane stores only the reference configuration (manager type, secret path, auth config) — never the actual secret value.
2. At runtime, the **data plane** (AI Gateway) reads the reference configuration and fetches the secret directly from your external manager.
3. The control plane never fetches or sees the final secret. The data plane caches the fetched secret value for **5 minutes** to avoid hitting your secret manager on every request. After the TTL expires, the next request triggers a fresh fetch.
```mermaid theme={"system"}
sequenceDiagram
participant User
participant ControlPlane as Control Plane
participant DataPlane as Data Plane (AI Gateway)
participant SecretManager as Your Secret Manager
participant LLM as LLM Provider
User->>ControlPlane: Create secret reference (path + auth config)
ControlPlane->>ControlPlane: Store reference config (no secret value)
User->>DataPlane: API request using secret reference
DataPlane->>ControlPlane: Fetch reference config
ControlPlane-->>DataPlane: Returns reference config (path + auth)
DataPlane->>SecretManager: Fetch actual secret using config
SecretManager-->>DataPlane: Returns secret value
DataPlane->>DataPlane: Cache secret (5 min TTL)
DataPlane->>LLM: Forward request with secret
```
## Creating a Secret Reference
### From the Control Panel
1. From your admin panel, go to [**Secret References**](https://app.portkey.ai/secret-references) and click **Create**.
2. Configure the reference identity:

* **Name**: A name for this reference
* **Slug**: Unique identifier, auto-generated from name if not added. Pattern: `^[a-zA-Z0-9_-]+$`
* **Description**: Optional context about this reference's purpose
3. Choose your external vault from the supported options:
* AWS Secrets Manager
* Azure Key Vault
* HashiCorp Vault
4. Select the authentication type for your chosen manager and add the required details.
5. Secret Location:
* **Secret Path**: Add the Secret name from the external manager
* **Secret Key** (optional): Add the specific key within the secret

### Via Admin APIs
Send a `POST` request to `/v1/secret-references` with the following body:
```json theme={"system"}
{
"name": "prod-openai-key",
"manager_type": "aws_sm",
"auth_config": {
"aws_auth_type": "accessKey",
"aws_access_key_id": "AKIA...",
"aws_secret_access_key": "wJalr...",
"aws_region": "us-east-1"
},
"secret_path": "prod/openai/api-key",
"secret_key": "OPENAI_API_KEY"
}
```
| Field | Type | Required | Description |
| - | - | - | - |
| `name` | string | Yes | Display name (1–255 chars). |
| `slug` | string | No | Unique identifier. Auto-generated from name if omitted. Pattern: `^[a-zA-Z0-9_-]+$`. |
| `description` | string \| null | No | Max 1024 chars. |
| `manager_type` | string | Yes | `aws_sm`, `azure_kv`, or `hashicorp_vault`. |
| `auth_config` | object | Yes | Auth credentials for connecting to the manager. See [Auth Config](#auth-config) below. |
| `secret_path` | string | Yes | Path to the secret in the external manager. |
| `secret_key` | string \| null | No | Specific key within the secret (when the secret holds multiple key-value pairs). |
| `allow_all_workspaces` | boolean | No | Default `true`. Grant access to all workspaces. |
| `allowed_workspaces` | string\[] | No | Restrict access to specific workspace UUIDs or slugs. Mutually exclusive with `allow_all_workspaces: true`. |
| `tags` | object \| null | No | Key-value metadata tags. |
## Updating a Secret Reference
Send a `PUT` request to `/v1/secret-references/:id` with only the fields you want to change. At least one field must be provided.
`auth_config` updates are **merged** with the existing config - you don't need to resend the full object.
Setting `allow_all_workspaces: true` purges any workspace-specific mappings. Providing `allowed_workspaces` automatically sets `allow_all_workspaces` to `false`.
## Deleting a Secret Reference
Send a `DELETE` request to `/v1/secret-references/:id`.
It will fail if the secret reference is currently in use by any integrations - remove those associations first.
## Workspace Scoping
By default, a secret reference is accessible from **all workspaces** in your organisation. To restrict access:
* Pass `allowed_workspaces` with an array of workspace UUIDs or slugs when creating or updating the reference.
* This automatically disables `allow_all_workspaces`.
To revert to org-wide access, set `allow_all_workspaces: true` - this purges all workspace-specific mappings.
## Auth Config
The `auth_config` schema depends on the `manager_type` you choose.
> [tab] AWS Secrets Manager
>
> ### Access Key
>
> | Field | Type | Required |
> | - | - | - |
> | `aws_auth_type` | `"accessKey"` | Yes |
> | `aws_access_key_id` | string | Yes |
> | `aws_secret_access_key` | string | Yes |
> | `aws_region` | string | Yes |
>
> ### Assumed Role
>
> Use this when Portkey should assume an IAM role in your account.
>
> | Field | Type | Required |
> | - | - | - |
> | `aws_auth_type` | `"assumedRole"` | Yes |
> | `aws_role_arn` | string | Yes |
> | `aws_external_id` | string \| null | No |
> | `aws_region` | string | Yes |
>
> ### Service Role
>
> Uses Portkey's own service role. Requires your secret's resource policy to grant Portkey access.
>
> | Field | Type | Required |
> | - | - | - |
> | `aws_auth_type` | `"serviceRole"` | Yes |
> | `aws_region` | string | No |
> [tab] Azure Key Vault
>
> ### Entra (Service Principal)
>
> | Field | Type | Required |
> | - | - | - |
> | `azure_auth_mode` | `"entra"` | Yes |
> | `azure_entra_tenant_id` | string | Yes |
> | `azure_entra_client_id` | string | Yes |
> | `azure_entra_client_secret` | string | Yes |
> | `azure_vault_url` | url | Yes |
>
> ### Managed Identity
>
> | Field | Type | Required |
> | - | - | - |
> | `azure_auth_mode` | `"managed"` | Yes |
> | `azure_managed_client_id` | string | No |
> | `azure_vault_url` | url | Yes |
>
> ### Default Credentials
>
> | Field | Type | Required |
> | - | - | - |
> | `azure_auth_mode` | `"default"` | Yes |
> | `azure_vault_url` | url | Yes |
> [tab] HashiCorp Vault
>
> ### Token
>
> | Field | Type | Required |
> | - | - | - |
> | `vault_auth_type` | `"token"` | Yes |
> | `vault_addr` | url | Yes |
> | `vault_token` | string | Yes |
> | `vault_namespace` | string | No |
>
> ### AppRole
>
> | Field | Type | Required |
> | - | - | - |
> | `vault_auth_type` | `"approle"` | Yes |
> | `vault_addr` | url | Yes |
> | `vault_role_id` | string | Yes |
> | `vault_secret_id` | string | Yes |
> | `vault_namespace` | string | No |
>
> ### Kubernetes
>
> | Field | Type | Required |
> | - | - | - |
> | `vault_auth_type` | `"kubernetes"` | Yes |
> | `vault_addr` | url | Yes |
> | `vault_role` | string | Yes |
> | `vault_namespace` | string | No |
## Secret Mappings
Secret mappings allow integrations to dynamically resolve secrets from secret references at runtime, instead of storing credentials directly. The `secret_mappings` field is an optional JSON array accepted on create and update in **Integrations**.
### Schema
Each entry in the `secret_mappings` array:
| Field | Type | Required | Description |
| - | - | - | - |
| `target_field` | string | Yes | The field on the entity that should be populated from the secret reference. Must be unique within the array. |
| `secret_reference_id` | string | Yes | UUID or slug of the secret reference to resolve. Must belong to the same organisation and be accessible by the workspace. |
| `secret_key` | string \| null | No | Override the `secret_key` defined on the secret reference. Use to pick a specific key from a multi-value secret. |
| `value_format` | string \| null | No | Format of the secret value. Either `json` or `string`. Use `json` when the secret value is a JSON object that should be parsed. |
### From the Control Panel
If you're storing provider API keys in your vault, map your secrets in LLM Integrations:
1. While creating a new LLM integration (or editing an existing one), you'll see a toggle. Switch to **Secret Ref** to use the key via your vault.

2. Select the secret reference. Optionally, provide a **Secret Key** if the reference contains multiple values.

### Via Admin APIs
### Valid `target_field` Values
> [tab] LLM Integrations
>
> **Integrations** (`POST /v1/integrations`, `PUT /v1/integrations/:integrationId`)
>
> | target\_field | Description |
> | - | - |
> | `key` | The provider API key. When mapped, the `key` body field can be omitted. |
> | `configurations.` | Any provider-specific configuration field (e.g. `configurations.aws_secret_access_key`, `configurations.azure_entra_client_secret`). |
> [tab] MCP Integrations
>
> **MCP Integrations** (`POST /v1/mcp-integrations`, `PUT /v1/mcp-integrations/:mcpIntegrationId`)
>
> > [!NOTE]
> >
> > MCP integration secret mappings require:
> >
> > * Enterprise Gateway version **2.7.0** or higher
> > * Frontend version **1.8.1** or higher
> > * Backend version **1.15.0** or higher
>
> | target\_field | Description |
> | - | - |
> | `configurations.` | Any MCP server configuration field (e.g. `configurations.oauth_metadata`, `configurations.headers`, `configurations.passthrough_headers`, `configurations.forward_headers`, `configurations.external_auth_config`, `configurations.jwt_validation`). |
>
> MCP integrations support the same secret mapping functionality as LLM integrations. This is particularly useful for:
>
> * **OAuth credentials**: Store OAuth client secrets, tokens, and metadata in your vault
> * **API keys**: Reference API keys for MCP servers that use header-based authentication
> * **Complex configurations**: Use `value_format: "json"` for nested configuration objects like OAuth metadata
>
> **Example: MCP Integration with OAuth metadata from vault**
>
> ```json theme={"system"}
> {
> "name": "GitHub MCP",
> "slug": "github-mcp",
> "server_url": "https://api.githubcopilot.com/mcp",
> "auth_type": "oauth",
> "secret_mappings": [
> {
> "target_field": "configurations.oauth_metadata",
> "secret_reference_id": "my-github-oauth",
> "value_format": "json"
> }
> ]
> }
> ```
### Example
```json theme={"system"}
{
"secret_mappings": [
{
"target_field": "key",
"secret_reference_id": "my-aws-api-key"
},
{
"target_field": "configurations.aws_secret_access_key",
"secret_reference_id": "aws-credentials-ref",
"secret_key": "secret_access_key"
},
{
"target_field": "configurations.oauth_metadata",
"secret_reference_id": "my-github-oauth",
"value_format": "json"
}
]
}
```
#### Using `value_format: json`
When your secret value is a JSON object (not a plain string), use `value_format: "json"` to have Portkey parse the value as JSON before injecting it into the configuration.
```json theme={"system"}
{
"secret_mappings": [
{
"secret_key": "oauth_metadata",
"target_field": "configurations.oauth_metadata",
"value_format": "json",
"secret_reference_id": "my-github-oauth"
}
]
}
```
This is useful for complex configuration objects like OAuth metadata that contain multiple nested fields.
### Example: Storing OAuth Metadata for GitHub MCP
This walkthrough shows how to store GitHub OAuth credentials in AWS Secrets Manager and reference them in Portkey for an MCP integration.
#### 1. Store the secret in AWS Secrets Manager
In your AWS Secrets Manager console (or via CLI), create a secret with:
* **Secret name** (path): `portkey/mcp/github-oauth`
* **Secret key**: `oauth_metadata`
* **Secret value**: Store the OAuth metadata as a **native JSON object** — no need to stringify it.
```json theme={"system"}
{
"client_id": "Ov**********6lf4J",
"client_secret": "99*************0",
"redirect_uri": "https://mcp.portkey.ai/oauth/upstream-callback",
"scope": "repo read:org read:user read:project"
}
```
> [!TIP]
>
> AWS Secrets Manager natively supports JSON values. Store your OAuth metadata as a JSON object directly — you do **not** need to `JSON.stringify()` it first. Portkey (with `value_format: "json"`) will parse the value correctly either way, but storing as native JSON makes it easier to read and edit in the AWS console.
#### 2. Create a secret reference in Portkey
In the Portkey dashboard, go to [**Secret References**](https://app.portkey.ai/secret-references) and click **Create**:
1. **Name**: `my-github-oauth`
2. **Secret Manager**: Select **AWS Secrets Manager** (or Azure Key Vault / HashiCorp Vault, depending on where you stored the secret)
3. **Authentication**: Provide the credentials for your chosen manager
4. **Secret Location**:
* **Secret Path**: `portkey/mcp/github-oauth`
* **Secret Key**: `oauth_metadata`
Or via the API:
```json theme={"system"}
{
"name": "my-github-oauth",
"manager_type": "aws_sm",
"auth_config": {
"aws_auth_type": "serviceRole",
"aws_region": "us-east-1"
},
"secret_path": "portkey/mcp/github-oauth",
"secret_key": "oauth_metadata"
}
```
This example uses the `serviceRole` auth type, where Portkey authenticates using its own service role — your secret's resource policy must grant Portkey access. When you retrieve a secret reference via the API, any sensitive `auth_config` fields are automatically [masked](#sensitive-field-masking).
#### 3. Use the secret reference in your MCP integration
When creating or updating the GitHub MCP integration, map `oauth_metadata` to your secret reference:
```json theme={"system"}
{
"name": "GitHub MCP",
"server_url": "https://api.githubcopilot.com/mcp",
"auth_type": "oauth",
"secret_mappings": [
{
"target_field": "configurations.oauth_metadata",
"secret_reference_id": "my-github-oauth",
"secret_key": "oauth_metadata",
"value_format": "json"
}
]
}
```
At runtime, Portkey's data plane fetches the OAuth metadata from AWS Secrets Manager and injects it into the MCP integration configuration — no credentials are stored in Portkey's control plane.
### Example: Storing External Auth Config for MCP
This example shows how to store OAuth/OIDC provider configuration (e.g., Okta) for external authentication in your MCP integrations.
#### 1. Store the external auth config in your vault
In AWS Secrets Manager (or your preferred vault), create a secret with:
* **Secret name**: `portkey/mcp/okta-auth`
* **Secret key**: `external_auth_config`
* **Secret value**: Store the OAuth configuration as a JSON object:
```json theme={"system"}
{
"issuer": "https://your-org.okta.com",
"authorization_endpoint": "https://your-org.okta.com/oauth2/v1/authorize",
"token_endpoint": "https://your-org.okta.com/oauth2/v1/token",
"revocation_endpoint": "https://your-org.okta.com/oauth2/v1/revoke",
"registration_endpoint": "https://your-org.okta.com/oauth2/v1/clients",
"client_id": "0oaxxxxxxxxxxxxxxxxx",
"client_secret": "your-client-secret-here",
"scope": "openid email profile offline_access",
"response_types_supported": ["code"],
"code_challenge_methods_supported": ["S256"],
"grant_types_supported": ["authorization_code", "refresh_token"],
"token_endpoint_auth_methods_supported": ["client_secret_basic", "client_secret_post"],
"scopes_supported": ["openid", "email", "profile", "offline_access"]
}
```
#### 2. Create a secret reference in Portkey
```json theme={"system"}
{
"name": "okta-external-auth",
"manager_type": "aws_sm",
"auth_config": {
"aws_auth_type": "serviceRole",
"aws_region": "us-east-1"
},
"secret_path": "portkey/mcp/okta-auth",
"secret_key": "external_auth_config"
}
```
#### 3. Use the secret reference in your MCP integration
```json theme={"system"}
{
"name": "Internal MCP Server",
"server_url": "https://mcp.internal.yourcompany.com",
"auth_type": "oauth",
"secret_mappings": [
{
"target_field": "configurations.external_auth_config",
"secret_reference_id": "okta-external-auth",
"secret_key": "external_auth_config",
"value_format": "json"
}
]
}
```
### Example: Storing JWT Validation Config for MCP
For MCP servers that use JWT validation with an external IdP, you can store the validation configuration in your vault.
#### 1. Store the JWT validation config in your vault
* **Secret name**: `portkey/mcp/jwt-validation`
* **Secret key**: `jwt_validation`
* **Secret value**:
```json theme={"system"}
{
"jwksUri": "https://your-org.okta.com/oauth2/v1/keys",
"algorithms": ["RS256"],
"requiredClaims": ["sub", "email"],
"claimValues": {
"iss": {
"values": "https://your-org.okta.com",
"matchType": "exact"
}
}
}
```
#### 2. Create a secret reference in Portkey
```json theme={"system"}
{
"name": "okta-jwt-validation",
"manager_type": "aws_sm",
"auth_config": {
"aws_auth_type": "assumedRole",
"aws_role_arn": "arn:aws:iam::123456789012:role/PortkeySecretAccess",
"aws_region": "us-east-1"
},
"secret_path": "portkey/mcp/jwt-validation",
"secret_key": "jwt_validation"
}
```
#### 3. Use the secret reference in your MCP integration
```json theme={"system"}
{
"name": "Internal MCP Server",
"server_url": "https://mcp.internal.yourcompany.com",
"auth_type": "external",
"secret_mappings": [
{
"target_field": "configurations.jwt_validation",
"secret_reference_id": "okta-jwt-validation",
"secret_key": "jwt_validation",
"value_format": "json"
}
]
}
```
### Example: Combining External Auth and JWT Validation
For complete external OAuth setups, you may need both `external_auth_config` (for OAuth flow) and `jwt_validation` (for token verification):
```json theme={"system"}
{
"name": "Secure Internal MCP",
"server_url": "https://mcp.internal.yourcompany.com",
"auth_type": "external",
"secret_mappings": [
{
"target_field": "configurations.external_auth_config",
"secret_reference_id": "okta-external-auth",
"value_format": "json"
},
{
"target_field": "configurations.jwt_validation",
"secret_reference_id": "okta-jwt-validation",
"value_format": "json"
}
]
}
```
This setup:
* Uses `external_auth_config` to configure the OAuth endpoints and credentials for user authentication
* Uses `jwt_validation` to validate incoming tokens against your IdP's JWKS
### Validation Rules
* `secret_mappings` must be an array (if provided).
* Each `target_field` must be one of the allowed fields/prefixes for the entity type.
* No duplicate `target_field` values within the array.
* Each `secret_reference_id` must reference an existing, active secret reference in the same organisation.
* If the entity is workspace-scoped, the secret reference must be accessible to that workspace (either `allow_all_workspaces: true` or explicitly mapped).
* On create, `target_field` values with the `configurations.` prefix are auto-normalized — you can pass just the field name without the prefix and it will be prepended.
### Behavior
* At gateway runtime, mapped fields are resolved from the external secret manager using the referenced secret reference's `auth_config`, `secret_path`, and the mapping's `secret_key` (or the secret reference's default `secret_key`).
* When a `target_field` of `key` is mapped, the `key` field on the entity becomes optional during creation.
* Secret mappings are returned in GET responses for integrations.
***
## Sensitive Field Masking
When you retrieve a secret reference via the API, sensitive `auth_config` fields are automatically masked. The original field is replaced with a `masked_` prefixed version containing a truncated value.
| Original Field | Masked Field |
| - | - |
| `aws_secret_access_key` | `masked_aws_secret_access_key` |
| `aws_access_key_id` | `masked_aws_access_key_id` |
| `aws_role_arn` | `masked_aws_role_arn` |
| `aws_external_id` | `masked_aws_external_id` |
| `azure_entra_client_secret` | `masked_azure_entra_client_secret` |
| `vault_token` | `masked_vault_token` |
| `vault_secret_id` | `masked_vault_secret_id` |
## Access Requirements
* **Authentication**: `x-portkey-api-key` header.
* **RBAC Role**: `OWNER` or `ADMIN`.
***
## API Reference
> [card] [Create Secret Reference](/docs/api-reference/admin-api/control-plane/secret-references/create-secret-reference)
> [card] [List Secret References](/docs/api-reference/admin-api/control-plane/secret-references/list-secret-references)
> [card] [Retrieve Secret Reference](/docs/api-reference/admin-api/control-plane/secret-references/retrieve-secret-reference)
> [card] [Update Secret Reference](/docs/api-reference/admin-api/control-plane/secret-references/update-secret-reference)
> [card] [Delete Secret Reference](/docs/api-reference/admin-api/control-plane/secret-references/delete-secret-reference)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Security @ Portkey
Source: https://docs.portkey.ai/docs/product/enterprise-offering/security-portkey
Portkey AI provides a secure, reliable AI gateway for the seamless integration and management of large language models (LLMs).
This document outlines our robust security protocols, designed to meet the needs of businesses requiring high standards of data protection and operational reliability.
At Portkey AI, we understand the critical importance of security in today's digital landscape and are committed to delivering state-of-the-art solutions that protect our clients' data and ensure their AI applications run smoothly.
## Security Framework
### Authentication
Portkey AI ensures secure API access through token-based authentication mechanisms, supporting Single Sign-On (SSO) via OIDC on enterprise plans.
We also implement key encryption, which provide an added layer of security by securely storing provider API keys within a controlled and monitored environment.
This multi-tier authentication strategy is crucial for protecting against unauthorized access and ensuring the integrity of user interactions.
### Encryption
To protect data integrity and privacy, all data in transit to and from Portkey AI is encrypted using TLS 1.2 or higher. We employ AES-256 encryption for data at rest, safeguarding it against unauthorized access and breaches.
These encryption standards are part of our commitment to maintaining secure data channels and storage.
### Access Control
Our access control measures are designed with granularity to offer precise control over who can see and manage data.
For enterprise clients, we provide enhanced [Role-Based Access Control (RBAC)](/docs/product/enterprise-offering/access-control-management#id-2.-fine-grained-user-roles-and-permissions), allowing for stringent governance suited to complex organizational needs.
This system is pivotal for enforcing security policies and ensuring that only authorized personnel have access to sensitive operations and data.
## Compliance and Data Privacy
### Compliance with Standards
Our platform is compliant with leading security standards, including [SOC2, ISO27001, GDPR, and HIPAA](https://trust.portkey.ai).
Portkey AI undergoes regular audits, compliance checks, and penetration testing conducted by third-party security experts to ensure continuous adherence to these standards.
These certifications demonstrate our commitment to global security practices and our ability to meet diverse regulatory requirements.

### Privacy Protections
At Portkey AI, we prioritize user privacy. Our privacy protocols are designed to comply with international data protection regulations, ensuring that all data is handled responsibly.
We engage in minimal data retention and deploy advanced anonymization technologies to protect personal information and sensitive data from being exposed or improperly used.
Read our privacy policy here - [https://portkey.ai/privacy](https://portkey.ai/privacy)[-policy](https://portkey.ai/privacy-policy)
## System Integrity and Reliability
### **Network and System Security**:
We protect our systems with advanced firewall technologies and DDoS prevention mechanisms to thwart a wide range of online threats. Our security measures are designed to shield our infrastructure from malicious attacks and ensure continuous service availability.
### **Reliability and Availability**:
Portkey AI offers an industry-leading [99.995% uptime](https://status.portkey.ai), supported by a global network of 310 data centers.
This extensive distribution allows for effective load balancing and edge deployments, minimizing latency and ensuring fast, reliable service delivery across geographical locations.
Our failover mechanisms are sophisticated, designed to handle unexpected scenarios seamlessly and without service interruption.
## Incident Management and Continuous Improvement
### Incident Response
Our proactive incident response team is equipped with the tools and procedures necessary to quickly address and resolve security incidents.
This includes comprehensive risk assessments, immediate containment actions, and detailed investigations to prevent future occurrences.
We maintain transparent communication with our clients throughout the incident management process. Please review our [status page](https://status.portkey.ai) for incident reports.
### Updates and Continuous Improvement
Security at Portkey AI is dynamic; we continually refine our security measures and systems to address emerging threats and incorporate best practices. Our ongoing commitment to improvement helps us stay ahead of the curve in cybersecurity and operational performance.
## Contact Information
For more detailed information or specific inquiries regarding our security measures, please reach out to our support team:
* **Support**: [Submit a ticket](https://support.portkey.ai/forms/customer-portal-ticket-form)
* **Data protection**: [dpo@portkey.ai](mailto:dpo@portkey.ai)
## Useful Links
[Privacy Policy](https://portkey.ai/privacy-policy)
[Terms of Service](https://portkey.ai/terms)
[Data Processing Agreement](https://portkey.ai/dpa)
[Trust Portal](https://trust.portkey.ai)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Guardrails
Source: https://docs.portkey.ai/docs/product/guardrails
Ship to production confidently with Portkey Guardrails on your requests & responses
> [!NOTE]
>
> This feature is available on all plans.
>
> * **Developer**: Access to `BASIC` Guardrails
> * **Production**: Access to `BASIC`, `PARTNER`, `PRO` Guardrails.
> * **Enterprise**: Access to **all** Guardrails plus `custom` Guardrails.
LLMs are brittle - not just in API uptimes or their inexplicable `400`/`500` errors, but also in their core behavior. You can get a response with a `200` status code that completely errors out for your app's pipeline due to mismatched output. With Portkey's Guardrails, we now help you enforce LLM behavior in real-time with our *Guardrails on the Gateway* pattern.
Use Portkey's Guardrails to verify your LLM inputs AND outputs, adhering to your specifed checks. Since Guardrails are built on top of our [Gateway](https://github.com/portkey-ai/gateway), you can orchestrate your request - with actions ranging from *denying the request*, *logging the guardrail result*, *creating an evals dataset*, *falling back to another LLM or prompt*, *retrying the request*, and more.
#### Examples of Guardrails Portkey offers:
* **Regex match** - Check if the request or response text matches a regex pattern
* **JSON Schema** - Check if the response JSON matches a JSON schema
* **Contains Code** - Checks if the content contains code of format SQL, Python, TypeScript, etc.
* **Custom guardrail** - If you are running a custom guardrail currently, you can also integrate it with Portkey
* ...and many more.
Portkey currently offers 20+ deterministic guardrails like the ones described above as well as LLM-based guardrails like `Detect Gibberish`, `Scan for prompt injection`, and more. These guardrails serve as protective barriers that help mitigate risks associated with Gen AI, ensuring its responsible and ethical deployment within organizations.
> [card] [List of supported Guardrail checks here](/docs/product/guardrails/list-of-guardrail-checks)
> [!NOTE]
>
> Portkey also integrates with your favourite Guardrail platforms like [Aporia](https://www.aporia.com/), [SydeLabs](https://sydelabs.ai/), [Pillar Security](https://www.pillar.security/) and more. Just add their API keys to Portkey and you can enable their guardrails policies on your Portkey calls! [More details on Guardrail Partners here.](/docs/product/guardrails/list-of-guardrail-checks)
***
## Using Guardrails
Putting Portkey Guardrails in production is just a 4-step process:
1. Create Guardrail Checks
2. Create Guardrail Actions
3. Enable Guardrail through Configs
4. Attach the Config to a Request
This flowchart shows how Portkey processes a Guardrails request:

> [!NOTE]
>
> Portkey only evaluates the last message in the request body when running guardrails checks.
***
## 1. Create a New Guardrail & Add Checks
On the `Guardrails` page, click on `Create` and add your preferred Guardrail checks from the right sidebar.
> [!NOTE]
>
> On Portkey, you can configure Guardrails to be run on either the `INPUT` (i.e. `PROMPT`) or the `OUTPUT`. Hence, for the Guardrail you create, make sure your Guardrail is only validating **ONLY ONE OF** the **Input** or the **Output**.

Each Guardrail Check has a custom input field based on its usecase — just add the relevant details to the form and save your check.
> [!NOTE]
>
> * You can add as many checks as you want to a single Guardrail.
> * A check ONLY returns a boolean (`Yes`/`No`) verdict.
> [card] [List of Guardrail checks](/docs/product/guardrails/list-of-guardrail-checks)
***
## 2. Add Guardrail Actions
Define a basic orchestration logic for your Guardrail here.
> [!NOTE]
>
> Guardrail is created to validate **ONLY ONE OF** the `Input` or the `Output`. The Actions set here will also apply only to either the `request` or the `response`.

### There are 7 Types of Guardrail Actions
| Action | State | Description | Impact |
| :- | :- | :- | - |
| **Async** | **TRUE** This is the **default** state | Run the Guardrail checks **asynchronously** along with the LLM request. | Will add no latency to your requestUseful when you only want to log guardrail checks without affecting the request |
| **Async** | **FALSE** | **On Request** Run the Guardrail check **BEFORE** sending the request to the **LLM** **On Response** Run the Guardrail check **BEFORE** sending the response to the **user** | Will add latency to the requestUseful when your Guardrail critical and you want more orchestration over your request based on the Guardrail result |
| **Deny** | **TRUE** | **On Request & Response** If any of the Guardrail checks **FAIL**, the request will be killed with a **446** status code. If all of the Guardrail checks **SUCCEED**, the request/response will be sent further with a **200** status code. | This is useful when your Guardrails are critical and upon them failing, you can not run the requestWe would advice running this action on a subset of your requests to first see the impact |
| **Deny** | **FALSE** This is the **default** state | **On Request & Response** If any of the Guardrail checks **FAIL**, the request will STILL be sent, but with a **246** status code. If all of the Guardrail checks **SUCCEED**, the request/response will be sent further with a **200** status code. | This is useful when you want to log the Guardrail result but do not want it to affect your result |
| **Sequential** | **TRUE** | Run the Guardrail checks **sequentially** one after another. The next check only runs after the previous one completes. | Useful when checks have dependencies or when you want predictable ordering. Adds latency as checks run one at a time. |
| **Sequential** | **FALSE** This is the **default** state | Run the Guardrail checks **in parallel**. All checks execute simultaneously. | Faster execution when checks are independent of each other. |
| **On Success** | **Send Feedback** | If **all of the** Guardrail checks **PASS**, append your custom defined feedback to the request | We recommend setting up this actionThis will help you build an "Evals dataset" of Guardrail results on your requests over time |
| **On Failure** | **Send Feedback** | If **any of the** Guardrail checks **FAIL**, append your custom feedback to the request | We recommend setting up this actionThis will help you build an "Evals dataset" of Guardrail results on your requests over time |
Set the relevant actions you want with your checks, name your Guardrail and save it! When you save the Guardrail, you will get an associated `$Guardrail_ID` that you can then add to your request.
***
## 3. "Enable" the Guardrails through Configs
This is where Portkey's magic comes into play. The Guardrail you created above is yet not an `Active` guardrail because it is not attached to any request.
Configs is one of Portkey's most powerful features and is used to define all kinds of request orchestration - everything from caching, retries, fallbacks, timeouts, to load balancing.
> [!NOTE]
>
> Now, you can use Configs to add **Guardrail checks** & **actions** to your request.
### Option 1: Direct Guardrail Configuration (Recommended)
Portkey now offers a more intuitive way to add guardrails to your configurations:
| Config Key | Value | Description |
| :- | :- | :- |
| **input\_guardrails** | `["guardrails-id-xxx", "guardrails-id-yyy"]` | Apply these guardrails to the **INPUT** before sending to LLM |
| **output\_guardrails** | `["guardrails-id-xxx", "guardrails-id-yyy"]` | Apply these guardrails to the **OUTPUT** from the LLM |
```json theme={"system"}
{
"retry": {
"attempts": 3
},
"cache": {
"mode": "simple"
},
"provider":"@openai-xxx",
"input_guardrails": ["guardrails-id-xxx", "guardrails-id-yyy"],
"output_guardrails": ["guardrails-id-xxx", "guardrails-id-yyy"]
}
```
### Option 2: Hook-Based Configuration (For Creating [Raw Guardrails](/docs/product/guardrails/creating-raw-guardrails-in-json))
You can also continue to use the original hook-based approach:
| Type | Config Key | Value | Description |
| :- | :- | :- | :- |
| Before Request Hook | **before\_request\_hooks** | `[{"id":"$guardrail_id"}]` | These hooks run on the **INPUT** before sending to the LLM |
| After Request Hook | **after\_request\_hooks** | `[{"id":"$guardrail_id"}]` | These hooks run on the **OUTPUT** after receiving from the LLM |
```json theme={"system"}
{
"retry": {
"attempts": 3
},
"cache": {
"mode": "simple"
},
"provider":"@openai-xxx",
"before_request_hooks": [{
"id": "input-guardrail-id-xx"
}],
"after_request_hooks": [{
"id": "output-guardrail-id-xx"
}]
}
```
> [!NOTE]
>
> Both configuration approaches work identically - choose whichever is more intuitive for your team. The simplified `input_guardrails` and `output_guardrails` fields are recommended for better readability.
### Guardrail Behaviour on the Gateway
For **asynchronous** guardrails (`async= TRUE`), Portkey returns the standard, default status codes from the LLM providers — this is because the Guardrails verdict is not affecting how you orchestrate your requests. Portkey will only log the Guardrail result for you.
But for **synchronous** requests (`async= FALSE`), Portkey can orchestrate your requests based on the Guardrail verdict. The behaviour is dependent on the following:
* Guardrail Check Verdict (`PASS` or `FAIL`) AND
* Guardrail Action — DENY Setting (`TRUE` or `FALSE`)
Portkey sends different `request status codes` corresponding to your set Guardrail behaviour.
For requests where `async= FALSE`:
| Guardrail Verdict | DENY Setting | Returned Status Code | Description |
| :- | :- | :- | :- |
| **PASS** | **FALSE** | **200** | Guardrails have **passed**, request will be processed regardless |
| **PASS** | **TRUE** | **200** | Guardrails have **passed**, request will be processed regardless |
| **FAIL** | **FALSE** | **246** | Guardrails have **failed**, but the request should still \*\*be processed.\*\*Portkey introduces a new Status code to indicate this state. |
| **FAIL** | **TRUE** | **446** | Guardrails have **failed**, and the request should **not** \*\*be processed.\*\*Portkey introduces a new Status code to indicate this state. |
### Example Config Using the New `246` & `446` Status Codes
> [tab] Fallback to Another Model on Guardrail Fail
>
> ```json theme={"system"}
> {
> "strategy": {
> "mode": "fallback",
> "on_status_codes": [246, 446]
> },
> "targets": [
> {"provider":"@openai-key-xxx"},
> {"provider":"@anthropic-key-xxx"}
> ],
> "input_guardrails": ["guardrails-id-xxx"]
> }
> ```
> [tab] Retry on Guardrail Fail (Simplified)
>
> ```json theme={"system"}
> {
> "retry": {
> "on_status_codes": [246],
> "attempts": 5
> },
> "output_guardrails": ["guardrails-id-xxx"]
> }
> ```
Create these Configs in Portkey UI, save them, and get an associated Config ID to attach to your requests. [More here](/docs/product/ai-gateway/configs).
## 4. Final Step - Attach Config to Request
Now, while instantiating your Portkey client or while sending headers, just pass the Config ID.
```js Node theme={"system"}
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
config: "pc-***" // Supports a string config id or a config object
});
```
```py Python theme={"system"}
portkey = Portkey(
api_key="PORTKEY_API_KEY",
config="pc-***" # Supports a string config id or a config object
)
```
```js OpenAI Node theme={"system"}
const openai = new OpenAI({
apiKey: 'OPENAI_API_KEY',
baseURL: PORTKEY_GATEWAY_URL,
defaultHeaders: createHeaders({
apiKey: "PORTKEY_API_KEY",
config: "CONFIG_ID"
})
});
```
```py OpenAI Python theme={"system"}
client = OpenAI(
api_key="OPENAI_API_KEY", # defaults to os.environ.get("OPENAI_API_KEY")
base_url=PORTKEY_GATEWAY_URL,
default_headers=createHeaders(
provider="openai",
api_key="PORTKEY_API_KEY", # defaults to os.environ.get("PORTKEY_API_KEY")
config="CONFIG_ID"
)
)
```
```sh cURL theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: $CONFIG_ID" \
-d '{
"model": "gpt-3.5-turbo",
"messages": [{
"role": "user",
"content": "Hello!"
}]
}'
```
For more, refer to the [Config documentation](/docs/product/ai-gateway/configs).
***
## Viewing Guardrail Results in Portkey Logs
Portkey Logs will show you detailed information about Guardrail results for each request.
### On the `Feedback & Guardrails` tab on the log drawer, you can see
#### Guardrail Details
* **Overview**: How many checks `passed` and how many `failed`
* **Verdict**: Guardrail verdict for each of the checks in your Guardrail
* **Latency**: Round trip time for each check in your Guardrail
#### Feedback Details
Portkey will also show the feedback object logged for each request
* `Value`:\*\* The numerical feedback value you passed
* `Weight`: The numerical feedback weight
* `Metadata Key & Value`:\*\* Any custom metadata sent with the feedback
* `successfulChecks`: Which checks associated with this request `passed`
* `failedChecks`: Which checks associated with this request `failed`
* `erroredChecks`: If there were any checks that errored out along the way
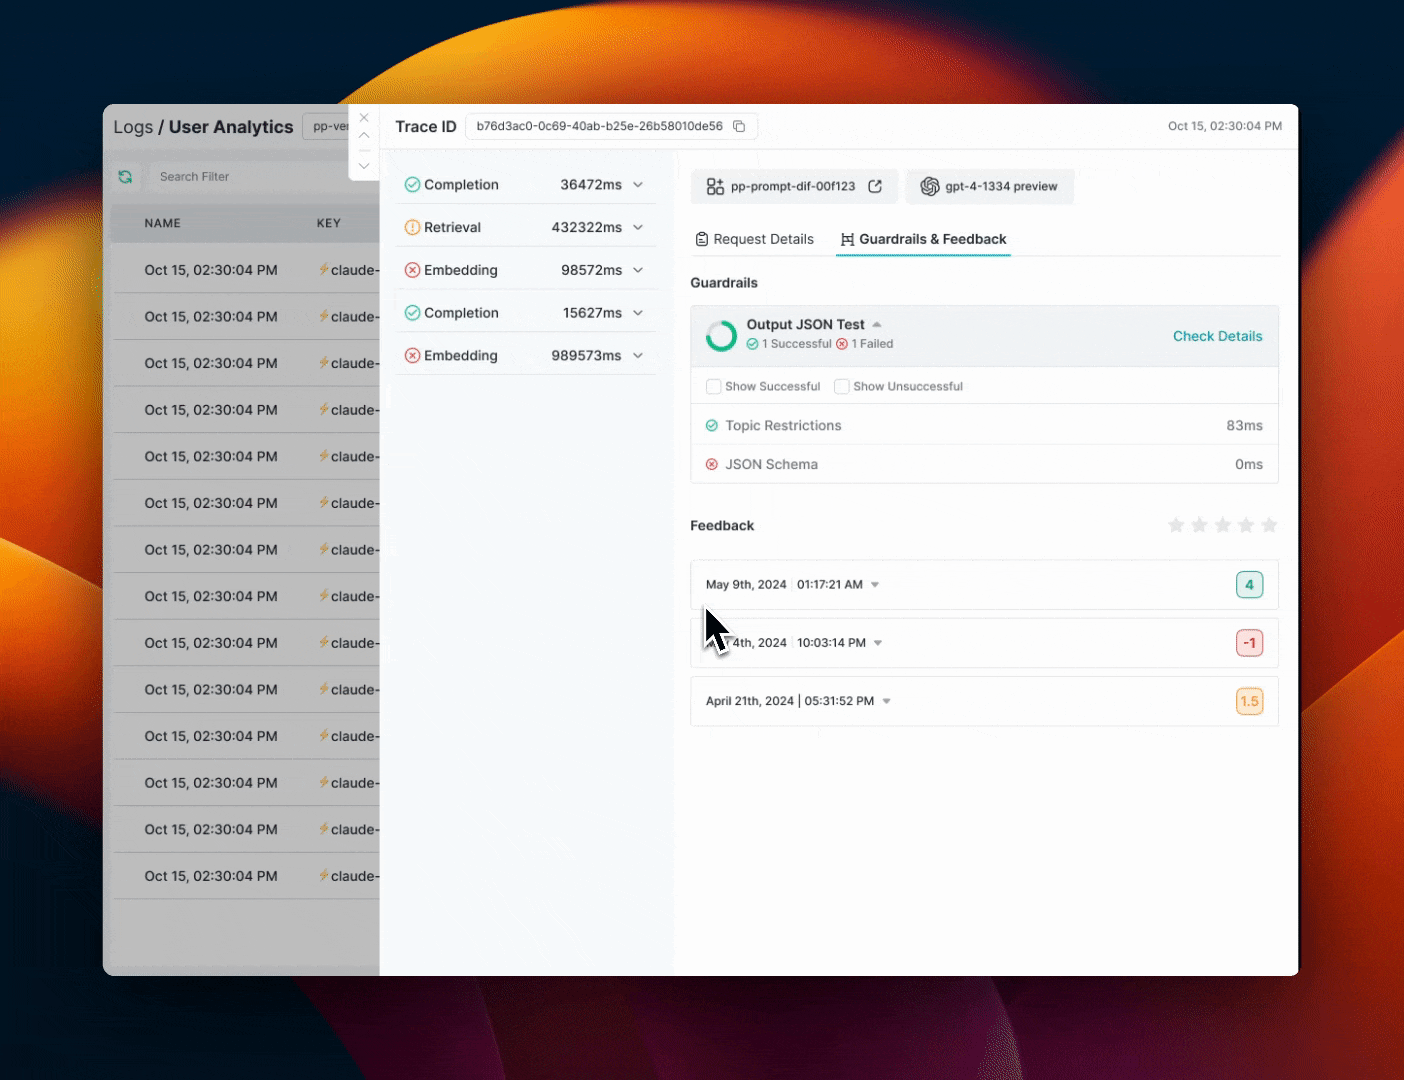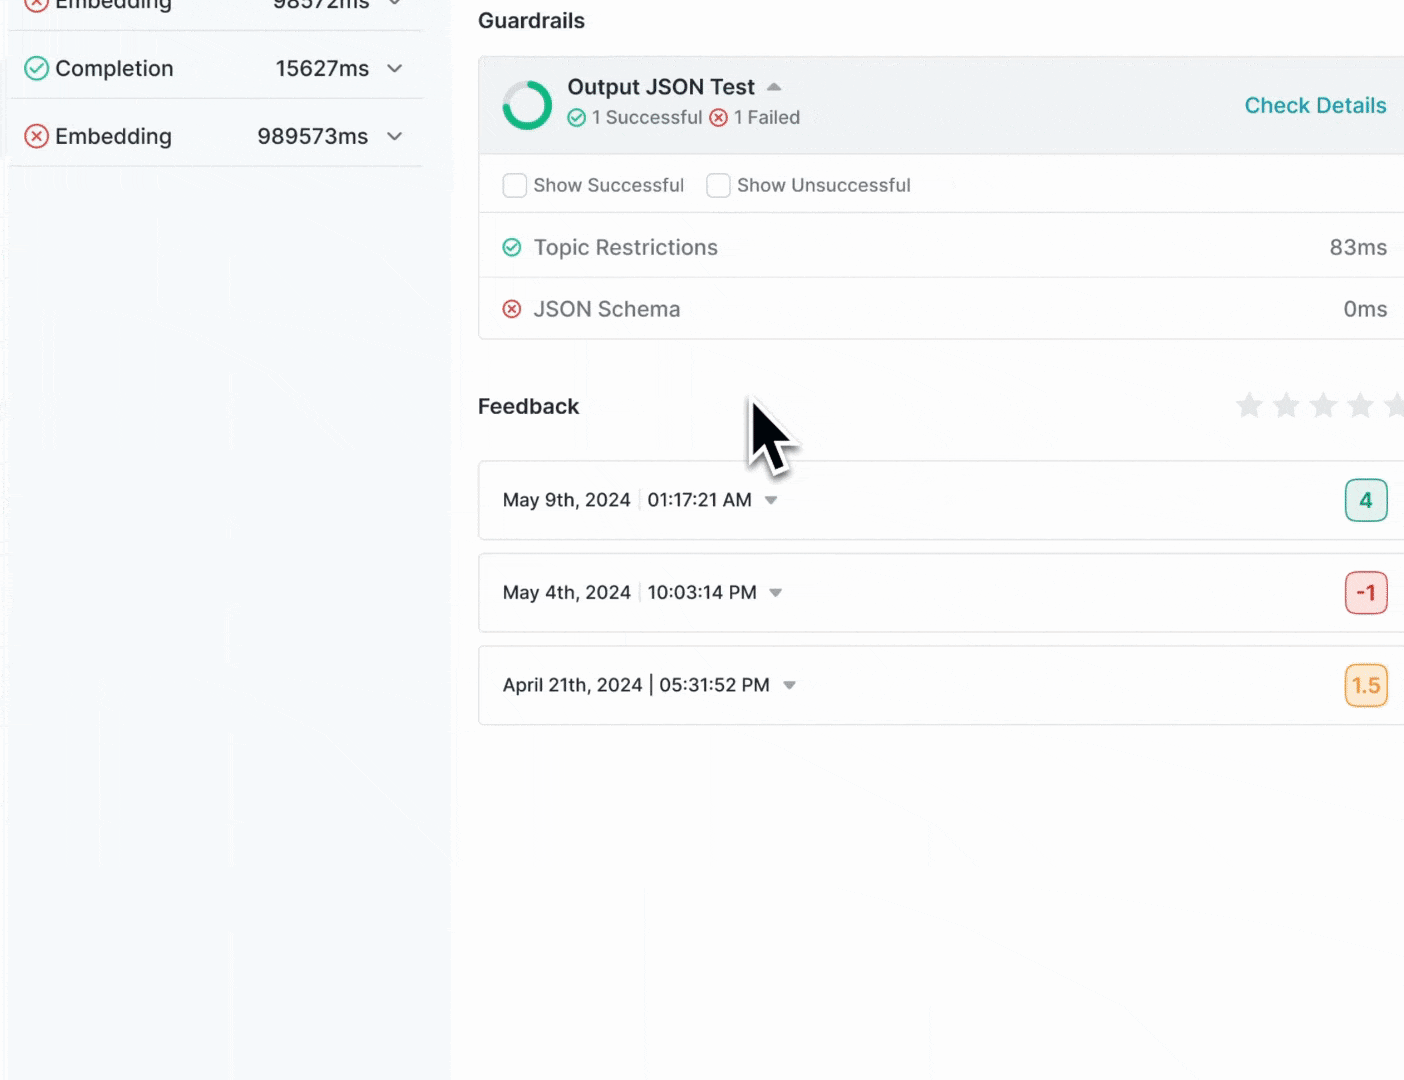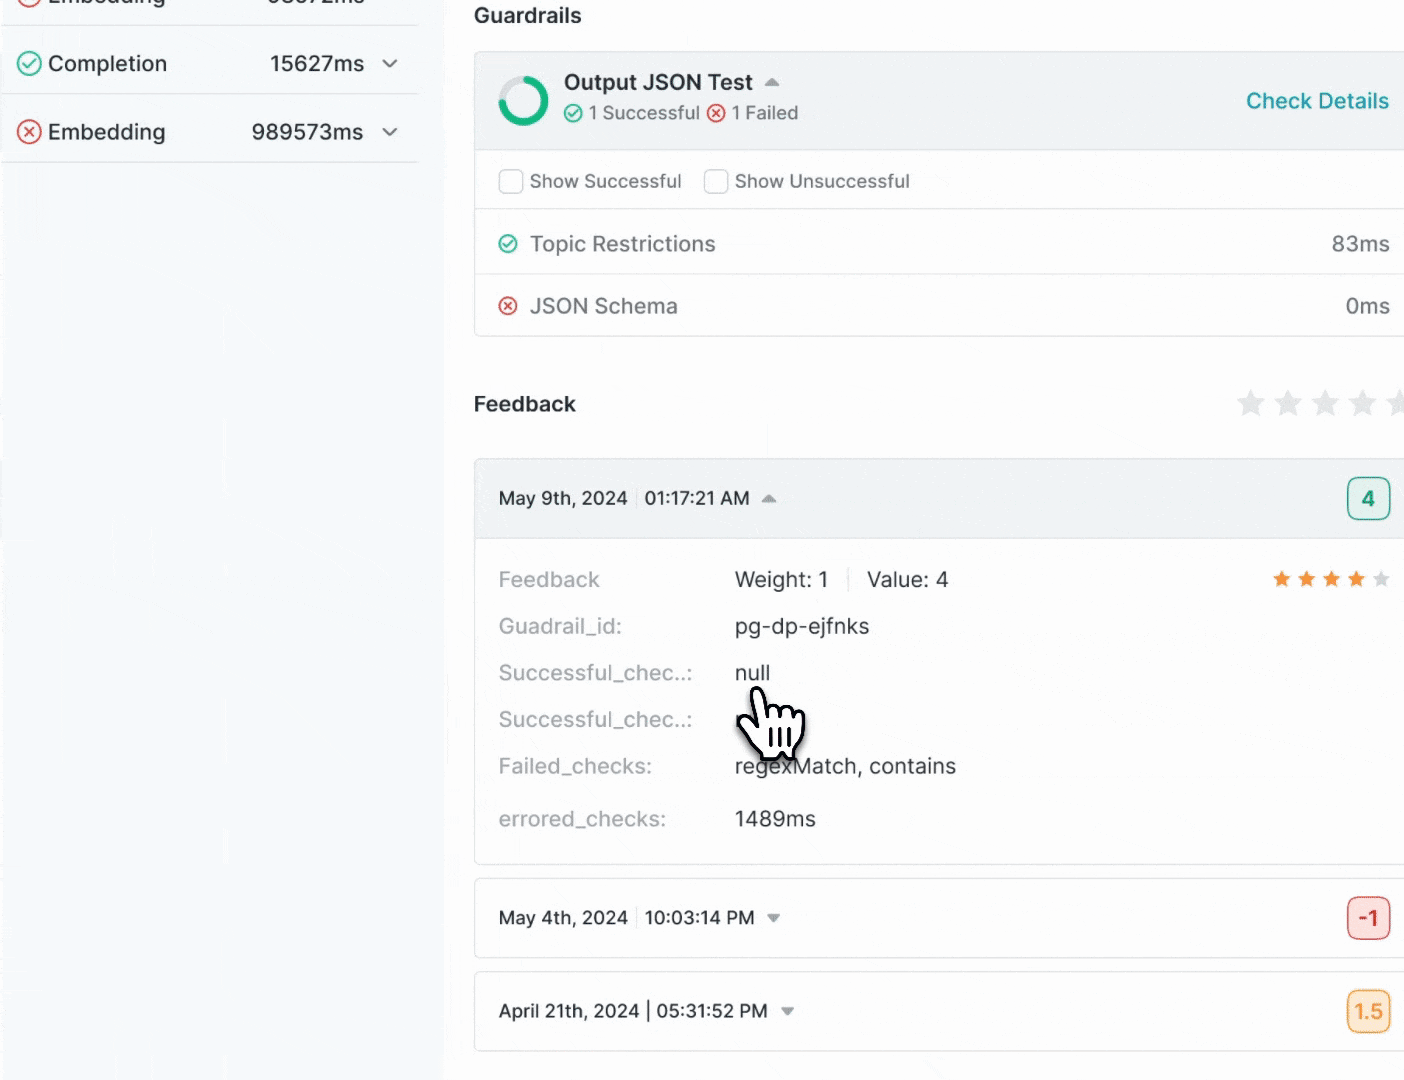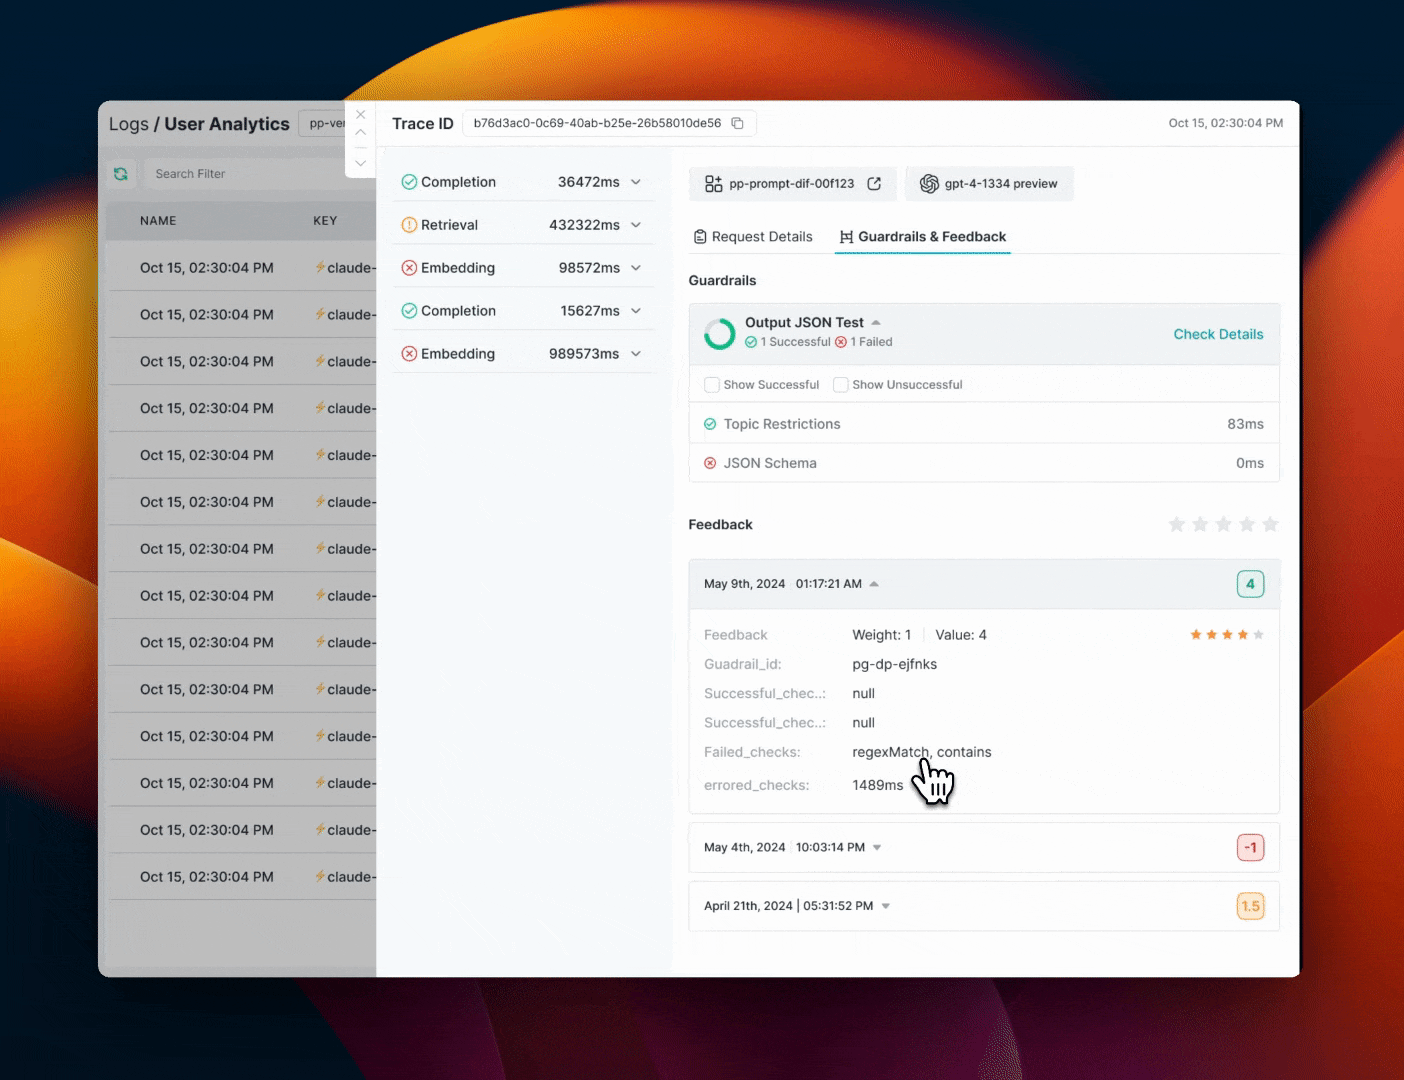
***
## Understanding Guardrail Response Structure
When Guardrails are enabled and configured to run synchronously (`async=false`), Portkey adds a `hook_results` object to your API responses. This object provides detailed information about the guardrail checks that were performed and their outcomes.
### Hook Results Structure
The `hook_results` object contains two main sections:
```json theme={"system"}
"hook_results": {
"before_request_hooks": [...], // Guardrails applied to the input
"after_request_hooks": [...] // Guardrails applied to the output
}
```
Each section contains an array of guardrail execution results, structured as follows:
**Hook Result Object Structure**
**verdict** `boolean`
Overall verdict of this guardrail (true = passed, false = failed). Only true if all checks within this guardrail passed.
**id** `string`
The ID of the guardrail that was executed (e.g., "pg-check-cfa540")
**transformed** `boolean`
Indicates if the guardrail modified the request or response (e.g., PII redaction)
**checks** `array`
An array of individual check results within this guardrail
**Check Object Structure**
**data** `object`
Check-specific data that varies based on the guardrail type (e.g., for wordCount it includes counts and thresholds)
**verdict** `boolean`
Result of this specific check (true = passed, false = failed)
**id** `string`
Identifier of the specific check (e.g., "default.sentenceCount", "default.wordCount")
**execution\_time** `number`
Time taken to execute this check in milliseconds
**transformed** `boolean`
Whether this check modified the content
**created\_at** `string`
Timestamp when the check was executed
**log** `string|null`
Additional logging information (if available)
**error** `string|object`
Error message or object if the guardrail encountered an error
**feedback** `object`
Feedback information configured in the guardrail
**Feedback Object Structure**
**value** `number`
The numerical feedback value
**weight** `number`
The weight assigned to this feedback
**metadata** `object`
Additional metadata including which checks succeeded or failed
**successfulChecks** `string`
Comma-separated list of checks that passed
**failedChecks** `string`
Comma-separated list of checks that failed
**erroredChecks** `string`
Comma-separated list of checks that encountered errors
**execution\_time** `number`
Total execution time for the guardrail in milliseconds
**async** `boolean`
Whether the guardrail was run asynchronously
**type** `string`
Always "guardrail" for guardrail hooks
**created\_at** `string`
Timestamp when the guardrail was executed
**deny** `boolean`
Whether failed checks should deny the request/response
### Example Hook Results
#### Non-Streaming Responses
Here's a simplified example of what the `hook_results` might look like in a non-streaming response:
```json [expandable] theme={"system"}
"hook_results": {
"before_request_hooks": [
{
"verdict": true,
"id": "sentence_and_word_check_guardrail",
"transformed": false,
"checks": [
{
"data": {
"sentenceCount": 1,
"minCount": 1,
"maxCount": 99999,
"not": false,
"verdict": true,
"explanation": "The sentence count (1) is within the specified range of 1 to 99999.",
"textExcerpt": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number,..."
},
"verdict": true,
"id": "default.sentenceCount",
"execution_time": 0,
"transformed": false,
"created_at": "2025-05-20T08:00:59.492Z",
"log": null
},
{
"data": {
"wordCount": 24,
"minWords": 1,
"maxWords": 99999,
"not": false,
"verdict": true,
"explanation": "The text contains 24 words, which is within the specified range of 1-99999 words.",
"textExcerpt": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number,..."
},
"verdict": true,
"id": "default.wordCount",
"execution_time": 0,
"transformed": false,
"created_at": "2025-05-20T08:00:59.492Z",
"log": null
}
],
"feedback": {
"value": 5,
"weight": 1,
"metadata": {
"successfulChecks": "default.sentenceCount, default.wordCount",
"failedChecks": "",
"erroredChecks": ""
}
},
"execution_time": 0,
"async": false,
"type": "guardrail",
"created_at": "2025-05-20T08:00:59.492Z",
"deny": false
},
{
"verdict": true,
"id": "character_check_guardrai",
"transformed": false,
"checks": [
{
"data": {
"characterCount": 130,
"minCharacters": 1,
"maxCharacters": 9999999,
"not": false,
"verdict": true,
"explanation": "The text contains 130 characters, which is within the specified range of 1-9999999 characters.",
"textExcerpt": "when does the flight from new york to bengaluru land tomorrow, what time, what is its flight number,..."
},
"verdict": true,
"id": "default.characterCount",
"execution_time": 0,
"transformed": false,
"created_at": "2025-05-20T08:00:59.492Z",
"log": null
}
],
"feedback": {
"value": 5,
"weight": 1,
"metadata": {
"successfulChecks": "default.characterCount",
"failedChecks": "",
"erroredChecks": ""
}
},
"execution_time": 0,
"async": false,
"type": "guardrail",
"created_at": "2025-05-20T08:00:59.492Z",
"deny": false
}
],
"after_request_hooks": [
{
"verdict": true,
"id": "sentence_and_word_check_guardrail",
"transformed": false,
"checks": [
{
"data": {
"sentenceCount": 2,
"minCount": 1,
"maxCount": 99999,
"not": false,
"verdict": true,
"explanation": "The sentence count (2) is within the specified range of 1 to 99999.",
"textExcerpt": "I'm unable to provide real-time flight information, such as specific flight times, numbers, or bagga..."
},
"verdict": true,
"id": "default.sentenceCount",
"execution_time": 0,
"transformed": false,
"created_at": "2025-05-20T08:01:02.229Z",
"log": null
},
{
"data": {
"wordCount": 46,
"minWords": 1,
"maxWords": 99999,
"not": false,
"verdict": true,
"explanation": "The text contains 46 words, which is within the specified range of 1-99999 words.",
"textExcerpt": "I'm unable to provide real-time flight information, such as specific flight times, numbers, or bagga..."
},
"verdict": true,
"id": "default.wordCount",
"execution_time": 0,
"transformed": false,
"created_at": "2025-05-20T08:01:02.229Z",
"log": null
}
],
"feedback": {
"value": 5,
"weight": 1,
"metadata": {
"successfulChecks": "default.sentenceCount, default.wordCount",
"failedChecks": "",
"erroredChecks": ""
}
},
"execution_time": 0,
"async": false,
"type": "guardrail",
"created_at": "2025-05-20T08:01:02.229Z",
"deny": false
}
]
}
}
```
This example corresponds to a `config` like:
```json theme={"system"}
{
"input_guardrails": [
"sentence_and_word_check_guardrail", // Contains sentenceCount and wordCount checks
"characer_check_guardrail" // Contains characterCount check
],
"output_guardrails": [
"sentence_and_word_check_guardrail" // The same guardrail can be used for both input and output
]
}
```
#### Streaming Responses
> [!NOTE]
>
> Portkey supports hook results in streaming responses for `/chat/completions`, `/completions`, `/embeddings`, and `/messages` endpoints. Both **input guardrails** (before request hooks) and **output guardrails** (after request hooks) are supported for streaming responses.
* **Input guardrails** (`input_guardrails` / before request hooks) are evaluated before the stream starts.
* **Output guardrails** (`output_guardrails` / after request hooks) are evaluated on the full assembled response after the stream completes. After the final `[DONE]` chunk, the `hook_results` for output guardrails are sent as an additional chunk. Note that **no action is taken** for output guardrails on streaming — fallback and retry are not triggered; results are informational only.
To receive `hook_results` inside streaming chunks, set the `x-portkey-strict-open-ai-compliance` header to `false`. By default this header is `true`, and `hook_results` chunks will not be visible.
**How output guardrails work with streaming:** Portkey accumulates all stream chunks, then parses the complete response and runs the output guardrails after the stream ends. The guardrail results are sent as an additional SSE chunk at the end of the stream.
```bash cURL - /chat/completions theme={"system"}
curl --location 'https://api.portkey.ai/v1/chat/completions' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: PORTKEY_API_KEY' \
--header 'x-portkey-config: {"beforeRequestHooks":[{"type":"guardrail","id":"my_solid_guardrail","checks":[{"id":"default.regexMatch","parameters":{"rule": "*asd"}}]}],"retry": {"attempts": 1}}' \
--header 'x-portkey-strict-open-ai-compliance: false' \
--data '{
"model": "@my-openai/gpt-3.5-turbo",
"max_tokens": 100,
"stream": true,
"messages": [
{
"role": "system",
"content": "You are a helpful assistant"
},
{
"role": "user",
"content": "hello sir how are you?"
}
]
}'
```
```python Python theme={"system"}
from portkey_ai import AsyncPortkey
import asyncio
portkey = AsyncPortkey(
api_key="PORTKEY_API_KEY",
provider="openai",
config={
"beforeRequestHooks": [
{
"type": "guardrail",
"id": "my_solid_guardrail",
"checks": [{"id": "default.regexMatch", "parameters": {"rule": "*"}}],
}
],
"cache": {"mode": "simple"},
},
)
async def main():
hook_results = None
try:
response = await portkey.chat.completions.create(
model="@my-openai/gpt-3.5-turbo",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "Hello!"},
],
stream=True,
)
async for chunk in response:
if chunk.model_extra and chunk.model_extra.get("hook_results"):
hook_results = chunk.model_extra.get("hook_results")
if len(hook_results.get("before_request_hooks", [])) > 0:
# Input guardrails — sent before the stream starts
pass
if len(hook_results.get("after_request_hooks", [])) > 0:
# Output guardrail - sent after the stream ends (informational only, no fallback/retry)
pass
print(chunk.choices, end="", flush=True)
print("\n")
except Exception as e:
print(e)
if __name__ == "__main__":
asyncio.run(main())
```
```javascript Node theme={"system"}
import Portkey from 'portkey-ai';
const portkey = new Portkey({
apiKey: "PORTKEY_API_KEY",
provider: "openai",
config: {
beforeRequestHooks: [
{
type: "guardrail",
id: "my_solid_guardrail",
checks: [{ id: "default.regexMatch", parameters: { rule: "*" } }],
}
],
cache: { mode: "simple" },
},
});
async function main() {
let hookResults = null;
try {
const response = await portkey.chat.completions.create({
model: "@my-openai/gpt-3.5-turbo",
messages: [
{ role: "system", content: "You are a helpful assistant." },
{ role: "user", content: "Hello!" },
],
stream: true,
});
for await (const chunk of response) {
if (chunk.model_extra && chunk.model_extra.hook_results) {
hookResults = chunk.model_extra.hook_results;
if (hookResults.before_request_hooks?.length > 0) {
// Input guardrails — sent before the stream starts
}
if (hookResults.after_request_hooks?.length > 0) {
// Output guardrails — sent after the stream ends (informational only, no fallback/retry)
}
}
process.stdout.write(JSON.stringify(chunk.choices));
process.stdout.write("\n");
}
} catch (error) {
console.error(error);
}
}
main();
```
```python OpenAI Python theme={"system"}
from openai import AsyncOpenAI
import asyncio
client = AsyncOpenAI(
api_key="OPENAI_API_KEY",
base_url="https://api.portkey.ai/v1",
default_headers={
"x-portkey-api-key": "PORTKEY_API_KEY",
"x-portkey-config": '{"beforeRequestHooks":[{"type":"guardrail","id":"my_solid_guardrail","checks":[{"id":"default.regexMatch","parameters":{"rule":"*"}}]}]}',
"x-portkey-strict-open-ai-compliance": "false"
}
)
async def main():
hook_results = None
try:
response = await client.chat.completions.create(
model="gpt-3.5-turbo",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "Hello!"},
],
stream=True,
)
async for chunk in response:
if chunk.model_extra and chunk.model_extra.get("hook_results"):
hook_results = chunk.model_extra.get("hook_results")
if len(hook_results.get("before_request_hooks", [])) > 0:
# Input guardrails — sent before the stream starts
pass
if len(hook_results.get("after_request_hooks", [])) > 0:
# Output guardrails — sent after the stream ends (informational only, no fallback/retry)
pass
print(chunk.choices, end="", flush=True)
print("\n")
except Exception as e:
print(e)
if __name__ == "__main__":
asyncio.run(main())
```
```javascript OpenAI Node theme={"system"}
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: process.env.OPENAI_API_KEY,
baseURL: "https://api.portkey.ai/v1",
defaultHeaders: {
"x-portkey-api-key": process.env.PORTKEY_API_KEY,
"x-portkey-config": JSON.stringify({
beforeRequestHooks: [
{
type: "guardrail",
id: "my_solid_guardrail",
checks: [{ id: "default.regexMatch", parameters: { rule: "*" } }],
}
]
}),
"x-portkey-strict-open-ai-compliance": "false"
}
});
async function main() {
let hookResults = null;
try {
const response = await client.chat.completions.create({
model: "gpt-3.5-turbo",
messages: [
{ role: "system", content: "You are a helpful assistant." },
{ role: "user", content: "Hello!" },
],
stream: true,
});
for await (const chunk of response) {
if (chunk.model_extra && chunk.model_extra.hook_results) {
hookResults = chunk.model_extra.hook_results;
if (hookResults.before_request_hooks?.length > 0) {
// Input guardrails — sent before the stream starts
}
if (hookResults.after_request_hooks?.length > 0) {
// Output guardrails — sent after the stream ends (informational only, no fallback/retry)
}
}
process.stdout.write(JSON.stringify(chunk.choices));
process.stdout.write("\n");
}
} catch (error) {
console.error(error);
}
}
main();
```
```bash cURL - /messages (Anthropic) theme={"system"}
curl --location 'https://api.portkey.ai/v1/messages' \
--header 'Content-Type: application/json' \
--header 'x-portkey-api-key: YOUR_PORTKEY_API_KEY' \
--header 'x-portkey-config: {"beforeRequestHooks":[{"type":"guardrail","id":"my_solid_guardrail","checks":[{"id":"default.regexMatch","parameters":{"rule": "*asd"}}]}],"retry": {"attempts": 1}}' \
--header 'x-portkey-strict-open-ai-compliance: false' \
--data '{
"model": "@dev-anthropic/claude-haiku-4-5",
"max_tokens": 100,
"stream": true,
"messages": [
{
"role": "user",
"content": "tell me a story?"
}
]
}'
```
**Input guardrail response chunk for /chat/completions** (sent before the stream):
```json theme={"system"}
data: {"hook_results":{"before_request_hooks":[{"verdict":true,"id":"my_solid_guardrail","transformed":false,"checks":[{"data":{"explanation":"An error occurred while processing the regex: Invalid regular expression: /*/: Nothing to repeat","regexPattern":"*","not":false,"textExcerpt":"hello sir how are you?"},"verdict":false,"id":"default.regexMatch","error":{"name":"SyntaxError","message":"Invalid regular expression: /*/: Nothing to repeat"},"execution_time":0,"created_at":"2025-11-14T08:14:04.772Z","transformed":false,"fail_on_error":false}],"feedback":null,"execution_time":0,"async":false,"type":"guardrail","created_at":"2025-11-14T08:14:04.772Z","deny":false}]}}
```
**Output guardrail response chunk for /chat/completions** (sent after the stream ends):
```json theme={"system"}
data: {"hook_results":{"after_request_hooks":[{"verdict":true,"id":"my_output_guardrail","transformed":false,"checks":[...],"feedback":null,"execution_time":12,"async":false,"type":"guardrail","created_at":"2025-11-14T08:14:06.772Z","deny":false}]}}
```
**Input guardrail response chunk for /messages** (sent before the stream):
```
event: hook_results
data: {"hook_results":{"before_request_hooks":[{"verdict":true,"id":"my_solid_guardrail","transformed":false,"checks":[{"data":{"explanation":"An error occurred while processing the regex: Invalid regular expression: /*asd/: Nothing to repeat","regexPattern":"*asd","not":false,"textExcerpt":"tell me a story?"},"verdict":false,"id":"default.regexMatch","error":{"name":"SyntaxError","message":"Invalid regular expression: /*asd/: Nothing to repeat"},"execution_time":0,"transformed":false,"created_at":"2025-11-14T09:23:12.457Z","log":null,"fail_on_error":false}],"feedback":null,"execution_time":0,"async":false,"type":"guardrail","created_at":"2025-11-14T09:23:12.457Z","deny":false}]}}
```
**Output guardrail response chunk for /messages** (sent after the stream ends):
```
event: hook_results
data: {"hook_results":{"after_request_hooks":[{"verdict":true,"id":"my_output_guardrail","transformed":false,"checks":[...],"feedback":null,"execution_time":12,"async":false,"type":"guardrail","created_at":"2025-11-14T09:23:15.457Z","deny":false}]}}
```
> [!NOTE]
>
> For the `/messages` endpoint (Anthropic), it is not possible to access hook results through the Anthropic SDK because the SDK only parses Anthropic-specific events. Use cURL or raw HTTP requests to access hook results for this endpoint.
**Accessing Hook Results in SDKs**
When using Portkey or OpenAI SDKs with streaming enabled (`stream=True`), the hook results are available in the `.model_extra.hook_results` parameter of the response chunks. Input guardrail results (`before_request_hooks`) appear in the first chunk before the stream, while output guardrail results (`after_request_hooks`) appear in the final chunk after the stream ends. This applies to:
* `.chat.completions.create()` with `stream=True`
* `.completions.create()` with `stream=True`
* `.embeddings.create()` with `stream=True`
For input guardrails, `hook_results` appear in the first chunk (before any content). For output guardrails, `hook_results` are sent as an additional chunk after the `[DONE]` chunk — these contain the `after_request_hooks` array with the guardrail verdicts.
### Important Notes
* If a guardrail is configured to run asynchronously (`async=true`), the `hook_results` will not appear in the API response. The results will only be available in the Portkey logs.
* Output guardrails on streaming requests are **informational only** — no fallback or retry actions are triggered based on the results.
* The `data` field varies based on the type of guardrail check being performed. Each guardrail type returns different information relevant to its function.
* The overall `verdict` for a guardrail is `true` only if all individual checks pass. If any check fails, the verdict will be `false`.
* When `transformed` is `true`, it indicates that the guardrail has modified the content (such as redacting PII).
* If `deny` is `true` and the verdict is `false`, the request will be denied with a 446 status code.
### Special Fields
* **Check-specific data**: Each guardrail type provides different data in the `data` field. For example, a sentence count check provides information about the number of sentences, while a PII check might provide information about detected PII entities.
* **Feedback metadata**: The `metadata` object within `feedback` keeps track of which checks were successful, failed, or encountered errors.
## Defining Guardrails Directly in JSON
On Portkey, you can also create the Guardrails in code and add them to your Configs. Read more about this here:
> [card] [Creating Raw Guardrails (in JSON](/docs/product/guardrails/creating-raw-guardrails-in-json)
***
## Bring Your Own Guardrails
If you already have a custom guardrail pipeline where you send your inputs/outputs for evaluation, you can integrate it with Portkey using a modular, custom webhook! Read more here:
> [card] [Bring Your Own Guardrails](/docs/integrations/guardrails/bring-your-own-guardrails)
***
## Examples of When to Deny Requests with Guardrails
1. **Prompt Injection Checks**: Preventing inputs that could alter the behavior of the AI model or manipulate its responses.
2. **Moderation Checks**: Ensuring responses do not contain offensive, harmful, or inappropriate content.
3. **Compliance Checks**: Verifying that inputs and outputs comply with regulatory requirements or organizational policies.
4. **Security Checks**: Blocking requests that contain potentially harmful content, such as SQL injection attempts or cross-site scripting (XSS) payloads.
By appropriately configuring Guardrail Actions, you can maintain the integrity and reliability of your AI app, ensuring that only safe and compliant requests are processed.
To enable Guardrails for your org, reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Supported Endpoints & Capabilities
Source: https://docs.portkey.ai/docs/product/guardrails/capabilities
Which endpoints, providers, input types, and execution modes Portkey Guardrails support.
Guardrails run at the Gateway layer — provider-agnostic, between your app and any upstream LLM.
***
## Supported Endpoints
| Endpoint | Input | Output |
| :- | :-: | :-: |
| `/v1/chat/completions` | ✓ | ✓ |
| `/v1/completions` | ✓ | ✓ |
| `/v1/embeddings` | ✓ | — |
| `/v1/messages` (Anthropic) | ✓ | ✓ |
| `/v1/responses` | ✓ | ✓ |
| `/v1/prompts/{promptId}/completions` | ✓ | ✓ |
| `/v1/decisions` | ✓ (content to judge only) | — |
> [!NOTE]
>
> Embeddings have no model-generated output to evaluate, so only `input_guardrails` apply. See [Guardrails for Embeddings](/docs/product/guardrails/embedding-guardrails).
> [!NOTE]
>
> Decisions requests only expose the content to judge to guardrails: `state` in the Jev shape, or the text in `input` in the OpenAI shape. `model`, `questions`, and `criteria` are your own instructions and are never scanned. Typed answers have no free text to evaluate, so only `input_guardrails` apply. See [Guardrails for Decisions](/docs/product/guardrails/decisions-guardrails).
***
## Endpoints That Don’t Support Guardrails
Guardrails are only evaluated on **LLM inference** endpoints where Portkey can extract a text input and/or text output.
The following Inference API endpoints **do not run guardrails**:
* **Assistants API (all endpoints)**: `/v1/assistants/*`, `/v1/threads/*`
* **Audio (all endpoints)**: `/v1/audio/*`
* **Images (all endpoints)**: `/v1/images/*`
* **Files (all endpoints)**: `/v1/files/*`
* **Batch (all endpoints)**: `/v1/batches/*`
* **Fine-tuning (all endpoints)**: `/v1/fine_tuning/*`
* **Moderations**: `/v1/moderations`
* **Models**: `/v1/models`
* **Prompt rendering (no model call)**: `/v1/prompts/{promptId}/render`
* **Response retrieval (no model call)**: `GET /v1/responses/*` (guardrails apply only to `POST /v1/responses`)
***
## Sync vs. Async
| Mode | `async` | Behavior | Latency |
| :- | :- | :- | :- |
| **Async** (default) | `true` | Runs in parallel with the LLM call. Results are logged only — no effect on the response. | None |
| **Sync** | `false` | Runs before forwarding the request (input) or before returning the response (output). Can deny or modify. | Adds guardrail check latency |
Use async to observe and log without blocking. Use sync when the guardrail result must gate the request.
> [!NOTE]
>
> With `async=false`, Portkey returns `246` (failed, but allowed) or `446` (failed, denied) instead of the standard provider status codes. See [Guardrail behavior on the gateway](/docs/product/guardrails#guardrail-behavior-on-the-gateway).
***
## Streaming
| Guardrail Type | Streaming |
| :- | :- |
| `input_guardrails` | **Supported** — evaluated before the stream starts |
| `output_guardrails` | **Supported** — evaluated on the full response after stream completes (informational only) |
With input guardrails on a streaming request: if the check passes, the stream proceeds normally. If it fails with `deny=true`, the stream is blocked with `446` before any tokens are sent.
With output guardrails on a streaming request: After the stream completes and the `[DONE]` chunk is sent, Portkey evaluates the full assembled response against your output guardrails. The results are delivered as an additional `hook_results` chunk. Output guardrail results on streaming are **informational only** — no fallback or retry actions are triggered.
To receive `hook_results` inside streaming chunks, set:
```
x-portkey-strict-open-ai-compliance: false
```
By default this header is `true`, and `hook_results` chunks will not be visible.
`hook_results` for input guardrails appear in the first chunk for `/chat/completions`, or as a separate `hook_results` event for `/messages`. Output guardrail results are sent as a chunk after `[DONE]`.
> [!NOTE]
>
> For Anthropic `/messages` streaming, `hook_results` aren't accessible via the Anthropic SDK. Use cURL or raw HTTP requests.
See [Streaming Hook Results](/docs/product/guardrails#streaming-responses) for SDK examples.
***
## What Gets Evaluated
### Text
Input guardrails evaluate the **last message** in the request. Output guardrails evaluate the **generated text** in the response.
### Images
Guardrails are text-only. Image inputs (base64 or URLs in multimodal messages) are **not evaluated**. Only the text portions of a message are passed to checks.
### Tool Calls
| Scenario | Evaluated by |
| :- | :- |
| Model deciding to call a tool | Output guardrails |
| Tool result sent back to the model | Input guardrails (on the follow-up request) |
| Function definitions in the system prompt | Input guardrails |
Tool call arguments (JSON) are treated as text — checks like Regex Match, Contains, and LLM-based detectors (e.g., Prompt Injection) all process this content.
***
## Quick Reference
| Capability | Supported |
| :- | :- |
| `/chat/completions` | ✓ |
| `/completions` | ✓ |
| `/embeddings` | ✓ (input only) |
| `/messages` (Anthropic) | ✓ |
| `/responses` | ✓ |
| `/prompts/{promptId}/completions` | ✓ |
| `/decisions` | ✓ (input only, `state` or `input` text) |
| All providers & models | ✓ |
| Input guardrails | ✓ |
| Output guardrails | ✓ |
| Async execution | ✓ (default) |
| Sync execution | ✓ |
| Streaming — input | ✓ |
| Streaming — output | ✓ (informational only, no fallback/retry) |
| Image inputs | ✗ |
| Text in multimodal messages | ✓ |
| Tool call text | ✓ |
***
> [card] [Guardrails Overview](/docs/product/guardrails)
>
> Create guardrails, configure actions, attach to requests
> [card] [Guardrails for Embeddings](/docs/product/guardrails/embedding-guardrails)
>
> Guardrails on embedding workflows
> [card] [Guardrails for Decisions](/docs/product/guardrails/decisions-guardrails)
>
> Guardrails on typed-judgment (Decisions) requests
> [card] [List of Guardrail Checks](/docs/product/guardrails/list-of-guardrail-checks)
>
> All built-in and partner checks
> [card] [Raw Guardrails in JSON](/docs/product/guardrails/creating-raw-guardrails-in-json)
>
> Define guardrails directly in code
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Creating Raw Guardrails (in JSON)
Source: https://docs.portkey.ai/docs/product/guardrails/creating-raw-guardrails-in-json
With the raw Guardrails mode, we let you define your Guardrail checks & actions however you want, directly in code.
At Portkey, we believe in helping you make your workflows [as modular as possible](https://portkey.ai/blog/what-it-means-to-go-to-prod/).
This is useful when:
* You want the same Guardrail checks but want to take different basic actions on them
* Your Guardrail checks definitions are dependent on an upstream task and are updated in code
* You want greater control over how you want to handle Guardrails
With the Raw Guardrails mode, you can achieve all this.
### Example of a Raw Guardrail
```JSON theme={"system"}
"before_request_hooks": [{
"type": "guardrail",
"id": "my_solid_guardrail",
"checks": [{
"id": "default.regexMatch",
"parameters": {
"rule": "test"
}
}]
}]
```
In this example:
* `type`: Specifies the type of hook, which is `guardrail`.
* `name`: Gives a name to the guardrail for identification.
* `checks`: Lists the checks that make up the guardrail. Each check includes an `id` and `parameters` for the specific conditions to validate.
### Configuring Guardrail Actions
```JSON theme={"system"}
"before_request_hooks": [{
"type": "guardrail",
"id": "my_solid_guardrail",
"checks": [{
"id": "default.regexMatch",
"parameters": {
"rule": "test"
}
}],
"deny": false,
"async": false,
"sequential": false,
"on_success": {
"feedback": {"value": 1,"weight": 1}
},
"on_fail": {
"feedback": {"value": -1,"weight": 1}
}
}]
```
In this example,
* `deny`: Is set to `TRUE` or `FALSE`
* `async`: Is set to `TRUE` or `FALSE`
* `sequential`: Is set to `TRUE` or `FALSE` - when `TRUE`, guardrail checks run one after another instead of in parallel
* `on_success`: Used to pass custom `feedback`
* `on_failure`: Used to pass custom `feedback`
### Forwarding Client Headers
You can forward specific client request headers to a guardrail provider by adding `forwardHeaders` inside the check's `parameters`:
```JSON theme={"system"}
"before_request_hooks": [{
"type": "guardrail",
"id": "my_solid_guardrail",
"checks": [{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://my-guardrail.example.com/check",
"forwardHeaders": ["x-session-id", "traceparent"]
}
}],
"deny": true,
"async": false
}]
```
* `forwardHeaders`: Optional `string[]` of client headers to forward to this check's provider. If omitted, no client headers are forwarded. See [Forwarding Headers](/docs/product/guardrails/forwarding-headers) for restricted headers and configuration details.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Guardrails for Decisions Requests
Source: https://docs.portkey.ai/docs/product/guardrails/decisions-guardrails
Apply guardrails to the caller-supplied state field on /v1/decisions requests, without scanning your own prompt instructions.
Portkey's guardrails also cover `/v1/decisions`, the typed-judgment endpoint. This lets you screen the content a decision is made about before it reaches the model, the same way you would for a chat or embedding request. Guardrails work with both [request shapes](/docs/product/ai-gateway/decisions-api#request-shapes) and every [supported provider](/docs/product/ai-gateway/decisions-api#supported-providers).
## Why Use Guardrails for Decisions?
A decisions request has three parts: `model`, `questions`, and the content to judge. The content is `state` in the Jev shape and `input` in the OpenAI shape. Only that content is caller-supplied — `model` and `questions` (including any `criteria`, `choices`, or `levels`) are your own application's instructions. Guardrails scan the content alone, so they check what a user or upstream system fed into the judgment, never your prompt design.
This matters because the content often carries the same kind of untrusted text you'd otherwise send to a chat model — support tickets, form submissions, extracted document text — before it's judged, scored, or classified. Guardrails let you catch PII, prompt injection, or policy violations in that content before the judgment call is made.
## How It Works
Guardrails for decisions run only at the **before-request** stage, on the content to judge only:
```mermaid theme={"system"}
flowchart LR
App[Your Application] --> Portkey[Portkey Gateway]
Portkey --> Guardrails[Guardrail Checks on state / input]
Guardrails -->|Pass| LLM[Decisions Provider]
Guardrails -->|Fail + deny=false| LLM
Guardrails -->|Fail + deny=true, softDeny200=true| SoftDeny[/Soft Deny\nStatus: 200/]
Guardrails -->|Fail + deny=true| Blocked[/Blocked\nStatus: 446/]
LLM --> Success[Typed answers]
class Success success
class SoftDeny warning
class Blocked danger
```
1. Your application sends the content to judge, `model`, and `questions` to `/v1/decisions`.
2. Portkey's before-request guardrails scan the content — `state` in the Jev shape, or the text in `input` in the OpenAI shape. They never scan `model`, `questions`, or nested `criteria`, `choices`, or `levels`.
3. If all checks pass, the request (with the content possibly redacted by a mutator) is forwarded to the provider.
4. If a check fails, the configured [guardrail action](/docs/product/guardrails) applies: log only, soft-deny with a `200`, or hard-deny with a `446`.
> [!NOTE]
>
> There are no after-request (output) guardrails on `/v1/decisions`. A successful answer is a typed judgment — a choice, a score, or a probability — with no free text to scan, so only `input_guardrails` apply. This mirrors [Guardrails for Embeddings](/docs/product/guardrails/embedding-guardrails).
## Redacting the Content
Mutator guardrails (for example, PII redaction) can rewrite the content before it's forwarded. Redaction is written back into the shape the request used.
**Jev shape (`state`)**
* If `state` was a plain string, the redacted text replaces it directly.
* If `state` was a JSON object or array, the redacted text is parsed back into JSON before being written back.
* If a mutator's output is no longer valid JSON for an object/array `state`, Portkey keeps the original `state` unchanged rather than forwarding corrupted content.
**OpenAI shape (`input`)**
* If `input` was a string, the redacted text replaces it.
* If `input` was a list of messages, each message's text is redacted in place. Message `role` and non-text parts such as `input_image` are left unchanged. Only message text and `input_text` parts are scanned.
## Response When a Guardrail Fails
A hard deny (`deny: true`, no soft-deny) returns `446` with the standard guardrail error shape:
```json theme={"system"}
{
"error": {
"message": "The guardrail checks defined in the config failed. You can find more information in the `hook_results` object.",
"type": "hooks_failed",
"param": null,
"code": null
},
"hook_results": {
"before_request_hooks": [ /* per-check verdicts */ ],
"after_request_hooks": []
}
}
```
A soft deny (`deny: true`, `softDeny200: true`) returns `200` with empty `answers` instead of an OpenAI-style error envelope, keeping the response shape consistent with a normal decisions response. `answers` is `{}` for a Jev-shaped request and `[]` for an OpenAI-shaped request:
```json theme={"system"}
{
"answers": {},
"message": "The guardrail checks defined in the config failed. You can find more information in the `hook_results` object.",
"hook_results": {
"before_request_hooks": [ /* per-check verdicts */ ],
"after_request_hooks": []
}
}
```
## Setting Up Guardrails for Decisions
### 1. Create a Guardrail
* Navigate to the `Guardrails` page and click `Create`.
* Select a check that supports `beforeRequestHook` (for example, PII Detection, Regex Match, Moderate Content).
* Configure the check parameters and set the action for failed checks (log, soft-deny, or hard-deny).
* Save the guardrail to get its ID.
> [!NOTE]
>
> Only guardrails that support `beforeRequestHook` run on `/v1/decisions`. Guardrails scoped to `afterRequestHook` only are skipped for this endpoint.
### 2. Add the Guardrail to Your Config
```json theme={"system"}
{
"input_guardrails": ["gr-xxx", "gr-yyy"]
}
```
### 3. Use the Config with a Decisions Request
```bash cURL theme={"system"}
curl https://api.portkey.ai/v1/decisions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H "x-portkey-config: pc-xxx" \
-d '{
"model": "@your-typesafe-slug/jev-latest",
"state": "Help! My payouts have been failing for 3 days.",
"questions": {
"department": {
"type": "choice",
"instructions": "Which team should handle this?",
"criteria": { "billing": "Payments", "technical": "Bugs" }
}
}
}'
```
## Learn More
> [card] [Guardrails Overview](/docs/product/guardrails)
>
> Create guardrails, configure actions, attach to requests
> [card] [Supported Endpoints & Capabilities](/docs/product/guardrails/capabilities)
>
> Where guardrails run across the gateway
> [card] [Decisions API](/docs/product/ai-gateway/decisions-api)
>
> Request shapes, supported providers, and question types
> [card] [TypeSafe (Jev)](/docs/integrations/llms/typesafe)
>
> Provider setup and quick start for /v1/decisions
> [card] [List of Guardrail Checks](/docs/product/guardrails/list-of-guardrail-checks)
>
> All built-in and partner checks
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Guardrails for Embedding Requests
Source: https://docs.portkey.ai/docs/product/guardrails/embedding-guardrails
Apply security and data validation measures to vector embedding requests to protect sensitive information and ensure data quality.
Portkey's guardrails aren't limited to chat completions - they can also be applied to embedding requests. This means you can protect your embedding workflows with the same robust security measures you use for your other LLM interactions.
## Why Use Guardrails for Embeddings?
Vector embeddings form the backbone of modern AI applications, transforming text into numerical representations that power semantic search, recommendation systems, and RAG pipelines. However, unprotected embedding workflows create significant business risks that technical leaders cannot ignore.
Without proper guardrails, sensitive customer data can leak into vector databases, toxic content can contaminate downstream systems, and resources are wasted embedding low-quality inputs. Protecting these workflows is essential because:
1. **Data leakage prevention**: Stop PII, PHI, or sensitive information from being sent to embedding models
2. **Data quality control**: Ensure only clean, formatted data gets embedded
3. **Cost optimization**: Avoid unnecessary API calls for data that doesn't meet your criteria
4. **Compliance**: Maintain regulatory compliance by filtering problematic content
By implementing guardrails at the embedding stage, you create a critical safety layer that protects your entire AI pipeline. For technical teams already building with embeddings, Portkey's guardrails integrate seamlessly with existing workflows while providing the security measures that enterprise applications demand.
## How It Works
Guardrails for embeddings are applied at the "before request" stage, examining your text before it's sent to the embedding model:
```mermaid theme={"system"}
flowchart LR
App[Your Application] --> Portkey[Portkey Gateway]
Portkey --> Guardrails[Guardrail Checks]
Guardrails -->|Pass| Success[/Success\nStatus: 240/]
Guardrails -->|Fail + Deny=false| Warning[/Warning\nStatus: 446/]
Guardrails -->|Fail + Deny=true| Blocked[/Blocked\nStatus: 446/]
Success --> LLM[LLM Provider]
Warning --> LLM
class Success success
class Warning warning
class Blocked danger
```
1. Your application sends text to Portkey for embedding
2. Portkey's guardrails analyze the text before sending to the LLM provider
3. If the text passes all checks, it's sent to the embedding model
4. If it fails, the configured [guardrail action](/docs/product/guardrails) is taken (deny, feedback, etc.)
## Supported Guardrails for Embeddings
You can use any of Portkey's "before request" guardrails with embedding requests:
> [card] [PII Detection](/docs/product/guardrails/pii-redaction)
>
> Protect user privacy by preventing PII from being embedded
> [card] [Regex Match](/docs/product/guardrails/list-of-guardrail-checks#basic--deterministic-guardrails)
>
> Filter content based on custom pattern matching
> [card] [Contains Check](/docs/product/guardrails/list-of-guardrail-checks#basic--deterministic-guardrails)
>
> Block embedding requests with specific words/phrases
> [card] [Word/Character Count](/docs/product/guardrails/list-of-guardrail-checks#basic--deterministic-guardrails)
>
> Ensure embeddings meet appropriate length requirements
> [card] [Contains Code](/docs/product/guardrails/list-of-guardrail-checks#basic--deterministic-guardrails)
>
> Detect and block code snippets from being embedded
> [card] [Custom Webhook](/docs/product/guardrails/bring-your-own-guardrails)
>
> Implement your own custom guardrail logic
> [card] [Partner Guardrails](/docs/product/guardrails/list-of-guardrail-checks#partner-guardrails)
>
> Utilize guardrails from Pangea, Pillar, and other partners
> [card] [PHI Detection](/docs/product/guardrails/list-of-guardrail-checks#pro--llm-guardrails)
>
> Prevent healthcare data from entering embedding systems
> [card] [Moderate Content](/docs/product/guardrails/list-of-guardrail-checks#pro--llm-guardrails)
>
> Filter out harmful content before embedding
[Learn More...](/docs/product/guardrails)
## Setting Up Embedding Guardrails
### 1. Create a Guardrail
Follow the standard process to create a guardrail in Portkey:
* Navigate to the `Guardrails` page and click `Create`
* Select the appropriate check from available guardrails (e.g., PII Detection, Regex Match)
* Configure the check parameters & set desired actions for failed checks
* Save the guardrail to get its ID
> [!NOTE]
>
> Make sure to select guardrails that support the `beforeRequestHook` since embeddings only use pre-request validation.
### 2. Add the Guardrail to Your Config
Add your guardrail ID to the `before_request_hooks` in your Portkey [config](/docs/product/ai-gateway/configs):
```json theme={"system"}
{
"input_guardrails": ["gr-xxx", "gr-yyy", ...]
}
```
### 3. Use the Config with Embedding Requests
> [tab] Python
>
> ```python theme={"system"}
> # Initialize Portkey with your config
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> config="pc-xxx" # Config with embedding guardrails
> )
>
> # Make your embedding request
> response = portkey.embeddings.create(
> input="Your text string goes here",
> model="text-embedding-3-small"
> )
>
> ```
> [tab] Node.js
>
> ```javascript theme={"system"}
> // Initialize Portkey with your config
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> config: "pc-xxx" // Config with embedding guardrails
> });
>
> // Make your embedding request
> const response = await portkey.embeddings.create({
> input: "Your text string goes here",
> model: "text-embedding-3-small"
> });
>
>
> ```
> [tab] OpenAI Python
>
> ```python theme={"system"}
> from openai import OpenAI
> from portkey.api_client.openai import createHeaders
>
> client = OpenAI(
> api_key="OPENAI_API_KEY",
> base_url="PORTKEY_GATEWAY_URL",
> default_headers=createHeaders(
> provider="openai",
> api_key="PORTKEY_API_KEY",
> config="pc-xxx" # Config with embedding guardrails
> )
> )
>
> # Make your embedding request
> response = client.embeddings.create(
> input="Your text string goes here",
> model="text-embedding-3-small"
> )
>
>
> ```
> [tab] cURL
>
> ```bash theme={"system"}
> curl https://api.portkey.ai/v1/embeddings \
> -H "Content-Type: application/json" \
> -H "Authorization: Bearer $OPENAI_API_KEY" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -H "x-portkey-config: pc-xxx" \
> -d '{
> "model": "text-embedding-3-small",
> "input": "Your text string goes here"
> }'
> ```
## Common Use Cases
* **Protecting Against PII in Embeddings**: When building search systems or RAG applications, you need to ensure no personally identifiable information is inadvertently embedded:
* **Filtering Code from Document Embeddings**: If you're building a knowledge base that shouldn't include code snippets:
* **Size-Based Filtering**: Ensure only appropriately sized documents get embedded:
* **Custom Regex Filtering**: Create domain-specific filters using regex patterns:
## Monitoring and Logs
All guardrail actions on embedding requests are logged in the Portkey dashboard, just like other guardrail activities. You can:
* See which embedding requests were blocked
* View detected issues (PII, regex matches, etc.)
* Track guardrail performance over time
* Export logs for compliance reporting

## Get Support
If you're implementing guardrails for embeddings and need assistance, reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
## Learn More
* [Portkey Guardrails Overview](/docs/product/guardrails)
* [List of Guardrail Checks](/docs/product/guardrails/list-of-guardrail-checks)
* [Creating Raw Guardrails in JSON](/docs/product/guardrails/creating-raw-guardrails-in-json)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Forwarding Headers
Source: https://docs.portkey.ai/docs/product/guardrails/forwarding-headers
Pass client request headers through to guardrail providers for trace correlation and session context.
Header forwarding passes specific client headers through to your guardrail providers. Use it for trace correlation, session-aware policy enforcement, or custom context your provider expects.
Without forwarding configured, only `Content-Type` and the provider's authentication reach the guardrail endpoint. All other client headers stop at Portkey.
***
## Configuration
Add `forwardHeaders` to any external check's `parameters`. List the exact header names you want forwarded:
```json theme={"system"}
{
"checks": [
{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://guardrails.example.com/check",
"forwardHeaders": ["x-portkey-trace-id", "traceparent", "x-session-id"]
}
}
]
}
```
If `forwardHeaders` is absent or omitted, nothing is forwarded. Each check configures forwarding independently.
Provider authentication headers always take precedence — forwarded headers cannot overwrite them.
> [!NOTE]
>
> If you include `traceparent` in your list and the client sends `x-portkey-trace-id` but no `traceparent`, Portkey synthesizes a valid W3C traceparent automatically. If the client sends a valid `traceparent` directly, it passes through unchanged.
***
## Restricted Headers
Portkey prevents forwarding headers that carry credentials or sensitive context. The following categories are blocked and rejected at save time:
* **Credentials** — `authorization`, `x-api-key`, `ocp-apim-subscription-key`, `proxy-authorization`
* **Session** — `cookie`
* **Cloud metadata** — headers used by cloud IMDS endpoints (AWS, GCP)
* **Internal routing** — all `x-portkey-*` headers except `x-portkey-trace-id` and `x-portkey-span-id`
* **Hop-by-hop** — protocol headers like `connection`, `host`, `transfer-encoding`
Header names must be valid per RFC 7230 — lowercase alphanumeric characters and hyphens only. Wildcards are not supported.
***
## Related
> [card] [Guardrails](/docs/product/guardrails)
> [card] [Bring Your Own Guardrails](/docs/integrations/guardrails/bring-your-own-guardrails)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Guardrails for Batches
Source: https://docs.portkey.ai/docs/product/guardrails/guardrails-for-batches
Secure batch inference with Portkey Guardrails
> [!NOTE]
>
> Gateway >= `2.9.0`
> Data Service >= `1.8.0`
Imagine usecases where you want to redact PII, remove some requests and redact responses when making a bulk batch inference call to providers like OpenAI, Azure OpenAI, Bedrock, Vertex AI, etc.
Portkey supports running [guardrails](/docs/product/guardrails) on [provider batch requests](/docs/api-reference/inference-api/batch/create-batch). You pass guardrails through a [config](/docs/product/ai-gateway/configs),
and Portkey applies them asynchronously — pre-processing inputs before sending to the provider, and post-processing outputs after the provider completes.
```mermaid theme={"system"}
flowchart LR
A(["📄 Upload JSONL\n(input file)"])
B(["⚙️ Create Config\nwith guardrails"])
C(["🚀 Create Batch\n(file ID + config)"])
subgraph portkey["Portkey"]
direction TB
D["🛡️ Input Guardrails\n(filter / transform requests)"]
E[("pk_file_* v2\n(processed input)")]
D --> E
end
subgraph provider["Upstream Provider"]
F["🤖 LLM Inference\n(batch processing)"]
end
subgraph postprocess["Portkey"]
direction TB
G["🛡️ Output Guardrails\n(filter / transform responses)"]
H[("pk_file_* final\n(output file)")]
G --> H
end
I(["⬇️ Download\noutput file"])
A --> C
B --> C
C --> D
E --> F
F --> G
H --> I
style portkey fill:#f0f4ff,stroke:#346df1,color:#1a1a1a
style provider fill:#f5f5f5,stroke:#888,color:#1a1a1a
style postprocess fill:#f0f4ff,stroke:#346df1,color:#1a1a1a
```
## How It Works
**1. Upload a batch input file**
Upload a JSONL file in OpenAI chat completions format to Portkey.
```sh theme={"system"}
curl --location 'https://api.portkey.ai/v1/files' \
--header 'x-portkey-api-key: {{PORTKEY_API_KEY}}' \
--header 'x-portkey-provider: portkey' \
--form 'file=@"/path/to/batch_requests.jsonl"' \
--form 'purpose="batch"'
```
Each line in the file should be a valid chat completions request. [Download an example JSONL file](https://github.com/Portkey-AI/docs-core/blob/main/files/chat_completions_101_requests.jsonl).
The response returns a Portkey file ID (`pk_file_*`):
```json theme={"system"}
{
"object": "file",
"id": "pk_file_1db86eb1-22b5-4440-8810-e45ddd1e5aca",
"purpose": "batch",
"filename": "d2d44065-0f52-4780-a216-eb0122a25d78/pk_file_1db86eb1-22b5-4440-8810-e45ddd1e5aca.jsonl",
"bytes": 26204,
"created_at": 1777975975402,
"status": "processed",
"status_details": null
}
```
**2. Create a config with guardrails**
Guardrails are the **only** supported way to pass guardrail checks to a provider batch request. Define them in a [Portkey config](/docs/product/ai-gateway/configs) [here](https://app.portkey.ai/configs):
```json theme={"system"}
{
"retry": {
"attempts": 3
},
"input_guardrails": ["pg-sync-g-0663db"],
"output_guardrails": ["pg-mutato-9760bc"]
}
```
Save this config in the Portkey dashboard and note the config ID (e.g., `pc-sync-g-1009a3`).
**3. Create a provider batch**
Reference your uploaded file ID and config when creating the batch:
```sh theme={"system"}
curl --location 'https://api.portkey.ai/v1/batches' \
--header 'x-portkey-api-key: {{PORTKEY_API_KEY}}' \
--header 'x-portkey-provider: portkey' \
--header 'Content-Type: application/json' \
--data '{
"input_file_id": "pk_file_1db86eb1-22b5-4440-8810-e45ddd1e5aca",
"endpoint": "/v1/chat/completions",
"completion_window": "24h",
"model": "gpt-3.5-turbo",
"portkey_options": {
"x-portkey-config": "pc-sync-g-1009a3",
"x-portkey-virtual-key": "openai-virtual-key"
}
}'
```
The response contains a Portkey batch ID (`pk_batch_*`) and the initial guardrail results in `hook_results`:
```json theme={"system"}
{
"id": "pk_batch_cd7f0e97-37b6-48cb-abd7-1bb699300585",
"object": "batch",
"status": "validating",
"input_file_id": "pk_file_1db86eb1-22b5-4440-8810-e45ddd1e5aca",
"hook_results": {
"before_request_hooks": [],
"after_request_hooks": [
{
"verdict": true,
"id": "portkey-dataservice",
"type": "guardrail",
"deny": false
}
]
}
}
```
**4. Poll for batch status**
Poll the batch to track progress. Once input guardrails are applied, the `input_file_id` is replaced with a new processed file. Use `include_provider_details=true` to see full upstream details:
```sh theme={"system"}
curl --location 'https://api.portkey.ai/v1/batches/pk_batch_cd7f0e97-37b6-48cb-abd7-1bb699300585?include_provider_details=true' \
--header 'x-portkey-api-key: {{PORTKEY_API_KEY}}'
```
If your config includes `output_guardrails`, the batch enters an intermediate `processing_post_request_guardrails` state after the upstream provider finishes. Once complete, `output_file_id` reflects the final guardrail-processed output file.
**5. Download the output file**
Once the batch status is `completed`, retrieve the output using the Portkey-exclusive file content endpoint:
```sh theme={"system"}
curl --location 'https://api.portkey.ai/v1/files/{{OUTPUT_FILE_ID}}/content' \
--header 'x-portkey-api-key: {{PORTKEY_API_KEY}}' \
--header 'x-portkey-provider: portkey'
```
## Batch Lifecycle with Guardrails
| State | Description |
| :- | :- |
| `validating` | Batch created; input guardrails being evaluated |
| `in_progress` | Input guardrails passed; provider is processing requests |
| `processing_post_request_guardrails` | Provider finished; output guardrails being evaluated |
| `completed` | All guardrails applied; output file ready |
> [!NOTE]
>
> The `input_file_id` in the batch response is updated after input guardrails
> process the file — the new ID points to the transformed input sent to the
> upstream provider.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# List of Guardrail Checks
Source: https://docs.portkey.ai/docs/product/guardrails/list-of-guardrail-checks
A **Guardrail Check** is a specific rule or validation applied to your AI traffic. You can apply checks to the **Input** (to sanitize user prompts before they reach the LLM) or the **Output** (to validate the LLM's response before sending it back to your user). You can combine multiple checks to build a robust Guardrail.
> [!NOTE]
>
> You can now have configurable timeouts for Partner & Pro Guardrails!
## Partner Guardrails
Each Guardrail Check has a specific purpose, it's own parameters, supported hooks, and sources.
> [card] [Acuvity](/docs/integrations/guardrails/acuvity)
>
> * Scan prompts and responses for security threats \* Detect PII, toxicity,
> and prompt injections \* Real-time content analysis and filtering
> [card] [Aporia](/docs/integrations/guardrails/aporia)
>
> * Validate custom Aporia policies via project ID \* Define policies on your
> Aporia dashboard \* Seamless integration with Portkey checks
> [card] [AWS Bedrock](/docs/integrations/guardrails/bedrock-guardrails)
>
> * Analyze and redact PII to prevent manipulation \* Integrate AWS Guardrails
> directly in Portkey \* Advanced security policy enforcement
> [card] [Azure](/docs/integrations/guardrails/azure-guardrails)
>
> * Detect and redact sensitive PII data \* Apply Azure's comprehensive content
> safety checks \* Detect jailbreaks and prompt injections with Shield Prompt
> * Identify copyrighted content with Protected Material detection
> [card] [Javelin (Highflame)](/docs/integrations/guardrails/javelin)
>
> * Platform to secure your entire AI journey, with visibility at every step,
> protection against emerging AI threats across GenAI, Agents & MCPs, and the
> confidence to innovate at scale
> [card] [Lasso Security](/docs/integrations/guardrails/lasso)
>
> * Analyze content for security risks and jailbreaks \* Enforce custom policy
> violations detection \* AI-powered threat detection and prevention
> [card] [Mistral](/docs/integrations/guardrails/mistral)
>
> * Detect and filter harmful content automatically \* Multi-dimensional
> content safety analysis \* Real-time moderation capabilities
> [card] [Pangea](/docs/integrations/guardrails/pangea)
>
> * Guard LLM inputs and outputs with Text Guard \* Detect malicious content
> and data transfers \* Prevent model manipulation attempts
> [card] [Palo Alto Networks Prisma AIRS](/docs/integrations/guardrails/palo-alto-panw-prisma)
>
> * Real-time threat detection across all OSI layers (1-7) \* Block prompt
> injections, data leakage, and model DoS attacks
> [card] [Patronus](/docs/integrations/guardrails/patronus-ai)
>
> * Detect hallucinations and factual errors \* Assess quality: conciseness,
> helpfulness, tone \* Identify gender and racial bias in outputs
> [card] [Pillar](/docs/integrations/guardrails/pillar)
>
> * Scan prompts and responses comprehensively \* Detect PII, toxicity, and
> injection attacks \* Enterprise security and compliance features
> [card] [Prompt Security](/docs/integrations/guardrails/prompt-security)
>
> * Scan prompts for security vulnerabilities \* Analyze responses for policy
> violations \* Advanced threat detection and mitigation
> [card] [Qualifire](/docs/integrations/guardrails/qualifire)
>
> * Best in class evaluation and guardrails for agents, RAG and chat bots.
> Detect and mitigate hallucinations, grounding issues, and any custom
> policies.
> [card] [CrowdStrike AIDR](/docs/integrations/guardrails/crowdstrike-aidr)
>
> * Pass LLM Input and Output to guard chat completions \* Block or sanitize text depending on configured rules
> [card] [Exa](/docs/integrations/plugins/exa)
>
> * Provider business-grade search and crawling for any web data
> [card] [Tavily](/docs/integrations/plugins/tavily)
>
> * Real-time web search grounding for any LLM \* Fine-tune freshness, domains,
> answers, raw content, images, and search depth from Portkey guardrails
> [card] [F5 Guardrails](/docs/integrations/guardrails/f5-guardrails)
>
> * Advanced content moderation and PII detection capabilities for LLM inputs and outputs
> [card] [Walled AI](/docs/integrations/guardrails/walledai)
>
> * Ensure the safety and compliance of your LLM inputs \* Generic safety checks, greetings, PII, and compliance checks
> [card] [Zscaler](/docs/integrations/guardrails/zscaler)
>
> * Integrates Zscaler AI Guard to perform security checks on both inbound prompts and outbound LLM responses
> [card] [Akto](/docs/integrations/guardrails/akto)
>
> * Advanced threat detection and security scanning for LLM inputs and outputs \* Protect against prompt injection and sensitive data leakage
## Portkey's Guardrails
Along with the partner Guardrails, there are also deterministic as well as LLM-based Guardrails supported natively by Portkey.
* `BASIC` Guardrails are available on all Portkey plans.
* `PRO` Guardrails are available on Portkey Pro & Enterprise plans.
### Understanding Supported Hooks
* `input_guardrails`: Runs on the user's prompt *before* calling the model.
* `output_guardrails`: Runs on the model's generated text *after* the call.
### `BASIC` — Deterministic Guardrails
Basic deterministic guardrails are ideal for quick, hard-coded validations that require zero LLM overhead. Implement these when you need to enforce strict data structures (like JSON schema), exact regex matches, or basic text limits (like word counts) with absolute certainty and minimal latency.
#### Text & Format Validation
| Guardrail Check | Description | Parameters | Supported On |
| :- | :- | :- | :- |
| **Regex Match** | Checks if the request or response text matches a regex pattern. | `rule`: string | Input, Output |
| **Sentence Count** | Checks if the content contains a certain number of sentences. Ranges allowed. | `minSentences`: number, `maxSentences`: number | Input, Output |
| **Word Count** | Checks if the content contains a certain number of words. Ranges allowed. | `minWords`: number, `maxWords`: number | Input, Output |
| **Character Count** | Checks if the content contains a certain number of characters. Ranges allowed. | `minCharacters`: number, `maxCharacters`: number | Input, Output |
| **Uppercase check** | Checks if content has all uppercase letters. | `not`: boolean | Input, Output |
| **Lowercase Detection** | Check if the given string is lowercase or not. | `format`: string | Input, Output |
| **Ends With** | Check if the content ends with a specified string. | `Suffix`: string | Input, Output |
#### Data & Structure
| Guardrail Check | Description | Parameters | Supported On |
| :- | :- | :- | :- |
| **JSON Schema** | Check if the response JSON matches a JSON schema. | `schema`: json | Output only |
| **JSON Keys** | Check if the response JSON contains any, all or none of the mentioned keys. | `keys`: array, `operator`: string | Output only |
| **Valid URLs** | Checks if all the URLs mentioned in the content are valid. | `onlyDNS`: boolean | Output only |
| **Contains Code** | Checks if the content contains code of format SQL, Python, TypeScript, etc. | `format`: string | Output only |
| **Not Null** | Checks if the response content is not null, undefined, or empty. | `not`: boolean | Output only |
| **Contains** | Checks if the content contains any, all or none of the words or phrases. | `words`: array, `operator`: string | Output only |
#### Security & Auth
| Guardrail Check | Description | Parameters | Supported On |
| :- | :- | :- | :- |
| **JWT Token Validator** | [Validate JWT tokens](/docs/integrations/guardrails/jwt) with signature verification (JWKS), token introspection, claim validation, and extract claims. | *Multiple* | Input only |
| **[Request Parameters Check](/docs/integrations/guardrails/request-parameters-check)** | Allow/block tools, top-level request keys, and specific parameter values. | `tools`: object, `params`: object | Input only |
#### Routing & Control
| Guardrail Check | Description | Parameters | Supported On |
| :- | :- | :- | :- |
| **Model Whitelist** | Check if the inference model to be used is in the whitelist. | `Models`: array, `Inverse`: boolean | Input only |
| **[Model Rules](/docs/integrations/guardrails/model-rules)** | Allow requests based on metadata-driven rules mapping to allowed models. | `rules`: object, `not`: boolean | Input only |
| **Allowed Request Types** | Control which request types (endpoints) can be processed using an allowlist or blocklist. | `allowedTypes`: array, `blockedTypes`: array | Input only |
| **Required Metadata Keys** | Checks if the metadata contains all the required keys. | `metadataKeys`: array, `operator`: string | Input only |
| **Required Metadata Key-Value Pairs** | Checks if the metadata contains specified key-value pairs. | `metadataPairs`: object, `operator`: string (all/any/none), `matchType`: string (exact/contains/containsAll/regex, default: exact) | Input only |
#### Media Processing
| Guardrail Check | Description | Parameters | Supported On | |
| :- | :- | :- | :- | - |
| | **Inline Image URLs** | Fetches external image URLs and converts them to Base64 inline data. Useful for VPC-SC environments where LLM providers cannot access external URLs. | `providers`: array, `maxSizeBytes`: number (default: 20971520), `timeoutMs`: number (default: 30000), `failOnError`: boolean (default: false) | Input only |
#### Extensibility
| Guardrail Check | Description | Parameters | Supported On |
| :- | :- | :- | :- |
| **Webhook** | Makes a webhook request for custom guardrails. | `webhookURL`: string, `headers`: json | Input, Output |
| **Log** | Makes a request to a log URL and always gives true as the verdict. | `logURL`: string, `headers`: json | Output only |
### `PRO` — LLM Guardrails
Pro guardrails leverage LLMs to perform nuanced, semantic validations. Implement these when you need to detect complex concepts like PII, toxicity, or gibberish that cannot be reliably caught with simple regex or deterministic rules.
| Guardrail Check | Description | Parameters | Supported On |
| :- | :- | :- | :- |
| **Moderate Content** | Checks if the content passes the mentioned content moderation checks. | `categories`: array | Input only |
| **Check Language** | Checks if the response content is in the mentioned language. | `language`: string | Input only |
| **Detect PII** | Detects Personally Identifiable Information (PII) in the content. | `categories`: array | Input, Output |
| **Detect Gibberish** | Detects if the content is gibberish. | `boolean` | Input, Output |
## Bring Your Own Guardrail
We have built Guardrails in a very modular way, and support bringing your own Guardrail using a custom webhook! [Learn more here](/docs/integrations/guardrails/bring-your-own-guardrails).
## Contribute Your Guardrail
Integrate your Guardrail platform with Portkey Gateway and reach our growing user base.
Check out some [existing integrations](https://github.com/portkey-ai/gateway) to get started.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# PII Redaction
Source: https://docs.portkey.ai/docs/product/guardrails/pii-redaction
Replace any sensitive data in requests with standard identifiers
Advanced PII Redaction feature automatically detects and redacts sensitive information from requests before they reach the LLM. This feature works seamlessly with our entire guardrails ecosystem, providing an additional layer of security for your AI interactions.
## Enabling PII Redaction
On the Guardrail creation page, for select PII guardrails, you will see a **Redact PII** toggle. Just enable it to start redacting PII in your requests.

## Guardrails Support
PII redaction is supported across 5 guardrail providers:
> [card] Portkey Pro PII
>
> Redact `Phone number`, `Email addresses`, `Location information`, `IP addresses`, `Social Security Numbers (SSN)`, `Names`, `Credit card information` from requests
> [card] [Patronus AI](/docs/product/guardrails/patronus-ai)
>
> Based on Patronus's EnterprisePII dataset, this guardrail can detect and redact confidential information typically found in business documents like meeting notes, commercial contracts, marketing emails, performance reviews, and more
> [card] [Pangea](/docs/integrations/guardrails/pangea)
>
> Pangea's redact feature can redact PII like geographic locations, payment card industry (PCI) data, and many other types of sensitive information, with support for rule customization
> [card] AWS Bedrock Guardrails
>
> You can select from a list of predefined PII or define a custom sensitive-information type using regular expressions (RegEx) and redact PII.
> [card] Promptfoo
>
> Promptfoo helps detect multiple PII exposures - in session data, via social engineering, or a direct exposure.
## Custom PII Redaction with Regex
For more granular control over PII redaction, you can create custom patterns using Portkey's **Regex Match** guardrail with redaction capabilities. This allows you to define specific patterns for sensitive information unique to your use case.
### Setting Up Custom PII Patterns

1. **Navigate to Guardrails**: Go to the `Guardrails` page and click `Create`
2. **Select Regex Match**: Choose the "Regex Match" guardrail from the BASIC category
3. **Configure the Pattern**:
* **Regex Rule**: Enter your regex pattern to match specific PII (e.g., `\b\d{3}-\d{2}-\d{4}\b` for SSN patterns)
* **Replacement Text**: Define what to replace matches with (e.g., `[REDACTED]`, `*****`, `[SSN_HIDDEN]`)
* **Enable Redact**: Toggle the "Redact" option to `ON`
* **Inverse**: Keep this `OFF` unless you want to redact everything except the pattern
4. **Save the Guardrail**: Name your guardrail and save it to get the associated Guardrail ID
### Common Regex Patterns for PII
```
| PII Type | Regex Pattern | Replacement Example |
|----------|---------------|-------------------|
| Credit Card | `\b\d{4}[- ]?\d{4}[- ]?\d{4}[- ]?\d{4}\b` | `[CREDIT_CARD]` |
| Social Security Number | `\b\d{3}-\d{2}-\d{4}\b` | `[SSN_REDACTED]` |
| Phone Numbers | `\b\d{3}[-.]\d{3}[-.]\d{4}\b` | `[PHONE_HIDDEN]` |
| Email Addresses | `\b[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Z|a-z]{2,}\b` | `[EMAIL_REDACTED]` |
| Custom Employee IDs | `EMP-\d{6}` | `[EMPLOYEE_ID]` |
```
### Adding to Your Config
Once you've created your custom PII regex guardrail, add it to your Portkey config:
```json theme={"system"}
{
"before_request_hooks": [
{"id": "your-custom-pii-guardrail-id"}
],
"after_request_hooks": [
{"id": "your-custom-pii-guardrail-id"}
]
}
```
> [!NOTE]
>
> You can add the same guardrail to both `before_request_hooks` (input guardrails) and `after_request_hooks` (output guardrails) to scan and redact PII in both user inputs and LLM responses.
### Example Implementation
> [tab] NodeJS
>
> ```js theme={"system"}
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY",
> config: "pc-***" // Config with custom PII redaction
> });
>
> const response = await portkey.chat.completions.create({
> model: "@your-model-slug",
> messages: [
> {
> role: "user",
> content: "My SSN is 123-45-6789 and credit card is 4532-1234-5678-9012"
> }
> ]
> });
> ```
> [tab] Python
>
> ```py theme={"system"}
> portkey = Portkey(
> api_key="PORTKEY_API_KEY",
> config="pc-***" # Config with custom PII redaction
> )
>
> response = portkey.chat.completions.create(
> model="@your-model-slug",
> messages=[
> {
> "role": "user",
> "content": "My SSN is 123-45-6789 and credit card is 4532-1234-5678-9012"
> }
> ]
> )
> ```
With the custom regex guardrail configured, the input would be automatically transformed to:
```
"My SSN is [SSN_REDACTED] and credit card is [CREDIT_CARD]"
```
## How It Works
1. **Detection**: When enabled, the system scans incoming or outgoing requests for PII using the configured guardrail provider.
2. **Redaction**: Detected PII is automatically replaced with standardized identifiers:
* Email addresses → `{{EMAIL_ADDRESS_1}}`, `{{EMAIL_ADDRESS_2}}`, etc.
* Phone numbers → `{{PHONE_NUMBER_1}}`, `{{PHONE_NUMBER_2}}`, etc.
* And similar patterns for other PII types
3. **Processing**: The redacted request is then forwarded to the LLM, ensuring sensitive data never reaches the model.
Example:
```
Original Request:
"Hi, you can reach me at john@example.com or 555-0123"
Redacted Request:
"Hi, you can reach me at {{EMAIL_ADDRESS_1}} or {{PHONE_NUMBER_1}}"
```
## Monitoring PII Redaction
You can track request transformations through two key indicators in the request/response body:
1. `transformed` boolean flag: Indicates whether any redaction occurred
2. `check_results` object: Contains detailed information about specific transformations
## Best Practices
1. **Gradual Implementation**:
* Start by enabling the feature for a subset of requests
* Monitor the logs and transformation results
* Gradually expand coverage after validation
2. **Regular Monitoring**:
* Review transformation logs periodically
* Validate that sensitive information is being caught appropriately
3. **Documentation**:
* Maintain records of what types of PII you're scanning for
* Document any specific compliance requirements being addressed
## Security Considerations
* Redaction is irreversible by design
* Original PII storage and handling varies by guardrail provider
* The feature can be applied to both input and output content
* Custom regex patterns should be carefully designed to avoid false positives
**Compliance Implications**
This feature can help organizations meet various compliance requirements by:
* Preventing accidental exposure of sensitive data to LLMs
* Providing audit trails of PII handling
* Supporting data minimization principles
* Enabling systematic PII management across AI operations
## Limitations
* Redaction patterns are not customizable for pre-built guardrails (but can be customized using regex)
* Transformation is one-way (non-reversible)
* Performance may vary based on chosen guardrail provider
* Complex regex patterns may impact processing latency
## Troubleshooting
If you experience issues:
1. Verify the feature is enabled in your guardrails configuration
2. Check the `transformed` flag and `check_results` for specific transformation details
3. Review logs for any error messages or unexpected behavior
4. For custom regex patterns, validate the regex syntax and test with sample data
5. [Contact us](https://support.portkey.ai/forms/customer-portal-ticket-form) for additional assistance
## FAQs
> [accordion] Can I customize the redaction patterns?
>
> Currently, redaction patterns are standardized and not customizable.
> [accordion] How does the system handle multiple instances of the same type of PII?
>
> Each instance receives a numbered identifier (e.g., `{{EMAIL_ADDRESS_1}}`, `{{EMAIL_ADDRESS_2}}`, etc.).
> [accordion] Does this feature impact request latency?
>
> Impact varies by guardrail provider and request complexity. Custom regex patterns with complex expressions may add minimal latency.
> [accordion] Can I use this feature with any LLM?
>
> Yes, the feature works with any LLM supported by Portkey.
> [accordion] Does this feature work on both input and output?
>
> Yes, you can configure the guardrail to scan both requests and responses.
> [accordion] Can I combine multiple PII redaction methods?
>
> Yes, you can use multiple guardrails in the same config to combine pre-built PII detection with custom regex patterns.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Start Hooks
Source: https://docs.portkey.ai/docs/product/guardrails/start-hooks
Validate, block, or normalize a request's headers, metadata, and endpoint at the very start of the request lifecycle, before input guardrails and before the provider is called.
Start hooks are a guardrail lifecycle stage that runs **before** [input guardrails](/docs/product/guardrails). Where input and output guardrails inspect the content of a prompt or a response, start hooks look at the **envelope** of a request: its headers, metadata, endpoint, and caller identity.
Use them to enforce rules that don't depend on the prompt:
* Reject requests that are missing required metadata or headers
* Validate a JWT and pass its claims downstream as headers and metadata
* Restrict which endpoints a key, workspace, or organization can call
* Strip or rewrite headers before the request is routed
Because start hooks work on the envelope, they apply to **every request** that reaches the LLM Gateway, not only chat completions.
## Where Start Hooks Run
```mermaid theme={"system"}
flowchart LR
Client[Your Application] --> Auth[API key auth and config resolution]
Auth --> Start[Start Hooks]
Start -->|Pass| Input[Input Guardrails]
Start -->|Fail + deny=true| Blocked[/Blocked\nStatus: 446/]
Start -->|Fail + deny=true, soft_deny_200=true| SoftDeny[/Soft Deny\nStatus: 200/]
Input --> LLM[Provider]
LLM --> Output[Output Guardrails]
Output --> Response[Response]
class Blocked danger
class SoftDeny warning
```
1. The gateway authenticates the API key and resolves the request's config, along with the start hooks inherited from the organization and workspace.
2. Start hooks run. If any hook with `deny: true` fails, the request stops here. No input guardrail runs and no provider is called.
3. If the start hooks pass, the request continues to input guardrails, the provider, and output guardrails as usual. Any header or metadata changes made by the start hooks are applied to the request first.
> [!NOTE]
>
> Start hooks run after authentication, so the gateway already knows which organization and workspace the request belongs to. They are not a replacement for API key authentication.
## What a Start Hook Can See
Start hooks run before the request body is processed, so a check sees:
| Available to start hooks | Not available |
| :- | :- |
| Request headers (internal gateway headers are removed) | The request body: prompt, messages, parameters |
| Request metadata | The provider response |
| Request path and endpoint type | |
| Provider, if set | |
Use [input guardrails](/docs/product/guardrails) for anything that needs to read the prompt.
## Supported Checks
Not every guardrail check can run as a start hook, and the Guardrails page does not filter the check list for you. When you create a guardrail you intend to use as a start hook, pick only the checks in this table.
| Check | What it does at the start stage | Can also run as an input guardrail |
| :- | :- | :- |
| **Header Check** (`headerCheck`) | Allows or blocks a request based on whether its headers match key-value pairs | No, start hooks only |
| **Header Transform** (`headerTransform`) | Removes, sets, or conditionally rewrites request headers | No, start hooks only |
| **Required Metadata Keys** (`requiredMetadataKeys`) | Requires, or prohibits, specific metadata keys | Yes |
| **Allowed Request Types** (`allowedRequestTypes`) | Allows or blocks endpoints with an allowlist or blocklist | Yes, with differences. See [Allowed Request Types](#allowed-request-types) |
| **[JWT](/docs/integrations/guardrails/jwt)** (`jwt`) | Validates a bearer token. As a start hook it can also extract claims into headers and metadata | Yes, but claim extraction applies only to start hooks |
| **Webhook** (`webhook`) | Sends the request context to your service, which returns the verdict. Request headers are not sent to the webhook | Yes |
### Header Check
Compares request headers with the key-value pairs you list. Header names are matched case-insensitively. Use `*` as a value to match any value, so the check tests only whether the header is present.
| Parameter | Description |
| :- | :- |
| `headerPairs` | Object of header names and expected values |
| `operator` | `all`: every pair must match. `any`: at least one pair must match. `none`: no pair may match |
```json theme={"system"}
{
"headerPairs": { "x-portkey-debug": "false" },
"operator": "none"
}
```
This example fails any request that sends `x-portkey-debug: false`. Use it to stop clients from turning off request logging.
The check result lists the names of the headers that matched and didn't match, never their values, so secrets in headers don't end up in logs.
### Header Transform
Rewrites headers before the request is routed. It never denies a request.
| Parameter | Description |
| :- | :- |
| `remove` | Header names to drop |
| `removeIf` | Drops headers when a condition on another header is met. Use `equals` or `exists` as the condition, with `drop` (header names) or `dropValues` (comma-separated values to strip from the condition header) |
| `set` | Header names and values to add or overwrite |
| `setIf` | Sets headers when a condition (`equals` or `exists`) on another header is met |
```json theme={"system"}
{
"remove": ["x-debug"],
"set": { "x-env": "production" },
"removeIf": {
"x-env": { "equals": "staging", "drop": ["x-experimental"] }
}
}
```
> [!WARNING]
>
> Header Transform cannot touch authentication headers (`cookie`, `set-cookie`, `x-api-key`, `x-portkey-api-key`, `api-key`, `apikey`, `x-auth-token`, `x-access-token`, `x-user-claims`, `x-user-jwt`) or any `x-portkey-*` header. If a transform references one of these, the whole check is rejected and **none** of its changes are applied.
> [!WARNING]
>
> Header Transform can't change headers that the gateway itself interprets when it builds the upstream call, such as `anthropic-beta` and `anthropic-version`. For these, the gateway reads the value from the request as the client sent it, so a transform that removes or overwrites them is accepted and reported as applied, but has no effect on what the provider receives. To control these values, have the client send them, or set `anthropic_beta` in the request body.
> [!WARNING]
>
> If a guardrail uses Header Transform, turn on **Execute guardrails sequentially** (`"sequential": true`) for that guardrail. Checks then run one after another, and each check sees the headers as changed by the checks before it. Without it, checks run in parallel and a check placed after Header Transform, such as a Header Check that verifies the new header, can still see the original headers.
> [!NOTE]
>
> Header Transform changes the headers the gateway sends upstream. It can't make the provider act on them. A provider is free to ignore any header it doesn't recognize, and the headers a transform sets or removes usually don't appear in the response JSON. To confirm a transform ran, look at the `headerTransform` check in `hook_results.start_hooks` or in the request log, which list the names of the headers removed and set.
### Required Metadata Keys
Checks the request's metadata keys.
| Parameter | Description |
| :- | :- |
| `metadataKeys` | Array of metadata key names |
| `operator` | `all`: every key must be present. `any`: at least one must be present. `none`: none of the keys may be present |
### Allowed Request Types
Controls which endpoints can be called. Provide `allowedTypes`, `blockedTypes`, or both. If a type appears in both lists the check returns an error. With neither, all request types are allowed.
```json theme={"system"}
{
"allowedTypes": ["chatComplete", "messages", "embed"]
}
```
If you leave both parameters empty, the check reads `supported_endpoints` and `blocked_endpoints` (comma-separated) from the request metadata instead.
#### Request types a start hook recognizes
A start hook matches the endpoint the client called, based on the request path:
| Request path | Request type |
| :- | :- |
| `/v1/chat/completions` | `chatComplete` |
| `/v1/completions` | `complete` |
| `/v1/embeddings` | `embed` |
| `/v1/rerank` | `rerank` |
| `/v1/messages` | `messages` |
| `/v1/messages/count_tokens` | `messagesCountTokens` |
| `/v1/responses` | `modelResponse`. Also accepted as `createModelResponse` |
| `/v1/images/generations` | `imageGenerate` |
| `/v1/images/edits` | `imageEdit` |
| `/v1/audio/speech` | `createSpeech` |
| `/v1/audio/transcriptions` | `createTranscription` |
| `/v1/audio/translations` | `createTranslation` |
| `/v1/files` | `files`. Also accepted as `uploadFile`, `listFiles`, `retrieveFile`, `deleteFile`, `retrieveFileContent` |
| `/v1/batches` | `batches`. Also accepted as `createBatch` |
| `/v1/fine_tuning/jobs` | `finetune`. Also accepted as `createFinetune` |
| `/v1/realtime` | `realtime` |
A request to any other path is matched by its path, for example `/v1/models`. In a start hook, `files`, `batches`, `finetune`, and `modelResponse` each cover every operation on that endpoint family, so `blockedTypes: ["files"]` blocks uploads, listing, retrieval, and deletion alike.
#### Using it as an input guardrail
Allowed Request Types also runs as an input guardrail, with these differences:
* It sees the gateway's internal request type for the call, not the original path. When the gateway adapts a request for a provider, the type can change. For example, a `/v1/messages` request sent to a provider without a native Messages API is handled as `chatComplete`.
* The family names `files`, `batches`, `finetune`, and `modelResponse` are not recognized. List the specific operation, such as `uploadFile` or `createBatch`.
> [!NOTE]
>
> Other input guardrails run only on `chatComplete`, `complete`, `embed`, `messages`, `createBatch`, `createFinetune`, `createModelResponse`, and `decisions` requests. Allowed Request Types is exempt from this restriction so that it can act on any endpoint. Start hooks have no such restriction.
### JWT
Start hooks are the only place JWT validation can do more than pass or fail. When `extractClaims` is set and the token is valid, the gateway writes those claims into the request:
* As headers, named `claimPrefix` plus the claim name (default `x-jwt-`, for example `x-jwt-sub`)
* As metadata, named `metadataPrefix` plus the claim name (default: no prefix, for example `sub`)
Claim values overwrite any client-supplied header or metadata key of the same name. If validation fails, or the token lacks a configured claim, the client-supplied value is removed, so a caller can't spoof a claim. See the [JWT guardrail](/docs/integrations/guardrails/jwt) for the full parameter list.
## Create a Start Hook
There is no separate "start hook" guardrail type on the **Guardrails** page. A start hook is a regular guardrail that you attach to the start stage. (Creating a guardrail from **Admin Settings** > **Organisation Guardrails** > **Start Hooks** does limit the check list to compatible checks.)
1. Go to **Guardrails** and click **Create**.
2. Enter a name and choose **LLM APIs** as the target. The target can't be changed after the guardrail is created.
3. Add one or more checks from the [supported checks](#supported-checks) list and configure their parameters.
4. On the **Actions** tab, choose the guardrail actions, described under [Deny, Soft Deny, and Log Only](#deny-soft-deny-and-log-only). If the guardrail uses Header Transform, turn on **Execute guardrails sequentially**.
5. Save the guardrail.
> [!WARNING]
>
> The workspace settings don't filter guardrails by the stage they are meant for. When you pick a guardrail under **Start Hook Guardrail** in a workspace, the list shows all guardrails in the workspace, including ones with checks that can't run at the start stage, such as a regex match or a PII check. Choose only guardrails made of the [supported checks](#supported-checks). A check that can't run at the start stage may return errors or not enforce what you intended, because start hooks don't see the request body. The same applies to guardrails you reference from a config, described under [Attach a Start Hook in a Config](#attach-a-start-hook-in-a-config).
### Example: Block Clients from Turning Off Request Logging
This example blocks every request in a workspace that sends `x-portkey-debug: false`, so clients can't opt out of request logging.
1. Open **Guardrails** and click **Create**.

2. In the **Add Guardrail** dialog, enter the name `block-debug-opt-out`, keep **LLM APIs** selected as the target, and click **Continue**.

3. Under **Available Checks**, search for `header` and click **Add** on **Header Check**.

4. Set **Operator** to `none` and **Header Key-Value Pairs** to `{"x-portkey-debug": "false"}`, then click **Save**. With `none`, the check fails when the request sends any of the listed pairs.

5. Switch to the **Actions** tab and select **Deny on Failure** under **Additional Settings**, then save the guardrail. The **On Success** and **On Failure** feedback settings on the left are optional and don't affect whether the request is blocked.

6. Open your workspace's settings and go to **Workspace Guardrails**. The page has three sections: **Input Guardrail**, **Output Guardrail**, and **Start Hook Guardrail**.

7. Under **Start Hook Guardrail**, open **Select Start Hook Guardrail** and choose `block-debug-opt-out`.

> [!WARNING]
>
> This list shows every guardrail in the workspace, such as `xsxs` and `Word_Count` above, not only the ones that can run as start hooks. Some of them may not be start hook compliant. Select only guardrails made of the [supported checks](#supported-checks).
8. Click **Update** to save.

9. Send a request with the `x-portkey-debug: false` header. It returns `446` and never reaches the provider. The response lists the check that failed and the header that matched. A request that doesn't send the header, or sends `x-portkey-debug: true`, goes through.

To enforce the same guardrail across the whole organization, add it under **Admin Settings** > **Organisation Guardrails** > **Start Hooks** instead. See [Enforcing Policies with Start Hooks](/docs/product/administration/enforce-policies-with-start-hooks).
A start hook guardrail takes effect once it is attached to requests. You can attach it in three places:
| Where | Applies to | Learn more |
| :- | :- | :- |
| Config `start_hooks` | Requests that use that config | [Attach a start hook in a config](#attach-a-start-hook-in-a-config) |
| Workspace settings | Every request in the workspace | [Enforcing policies with start hooks](/docs/product/administration/enforce-policies-with-start-hooks) |
| Organization settings | Every request in every workspace | [Enforcing policies with start hooks](/docs/product/administration/enforce-policies-with-start-hooks) |
### Attach a Start Hook in a Config
> [!WARNING]
>
> Use only [checks that support start hooks](#supported-checks) in `start_hooks`, whether you reference a saved guardrail by ID or define the hook inline. Neither the gateway nor the config editor checks whether a check supports the start stage, so a config with an unsupported check is saved and accepted without any error. At request time the check still runs, but it has no request body or response to work with. For example, a Regex Match check reports an error such as "Missing text to match", and unless the check has `failOnError` set, that error does not block the request. The policy you meant to enforce is then silently not applied.
Add the guardrail's ID to `start_hooks` in a [config](/docs/product/ai-gateway/configs):
```json theme={"system"}
{
"provider": "@openai-xxx",
"start_hooks": ["guardrails-id-xxx"]
}
```
To set the actions for a hook for this config only, use the object form:
```json theme={"system"}
{
"provider": "@openai-xxx",
"start_hooks": [
{
"id": "guardrails-id-xxx",
"deny": true,
"soft_deny_200": false
}
]
}
```
The object form accepts the same action keys as `before_request_hooks`: `deny`, `soft_deny_200`, `async`, `on_fail`, and `on_success`.
### Define a Start Hook Inline
You can also send the full hook definition in the `x-portkey-config` header, without creating a guardrail first. This is useful for testing:
```bash theme={"system"}
curl https://api.portkey.ai/v1/chat/completions \
-H "Content-Type: application/json" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-H 'x-portkey-config: {
"start_hooks": [{
"id": "require-team-header",
"type": "guardrail",
"deny": true,
"checks": [{
"id": "default.headerCheck",
"parameters": {
"headerPairs": { "x-team": "*" },
"operator": "all"
}
}]
}]
}' \
-d '{
"model": "@openai-xxx/gpt-4o-mini",
"messages": [{ "role": "user", "content": "Hello" }]
}'
```
A request without an `x-team` header is blocked before it reaches the provider.
## Deny, Soft Deny, and Log Only
What happens when a start hook fails depends on its actions.
| Verdict | `deny` | `soft_deny_200` | Result |
| :- | :- | :- | :- |
| Pass | any | any | The request continues |
| Fail | `false` | any | The request continues. The failure is logged and appears in `hook_results` |
| Fail | `true` | `false` | The request is blocked with status `446` |
| Fail | `true` | `true` | The request is blocked, but the response has status `200` and the normal shape for the endpoint |
> [!NOTE]
>
> Unlike a failed input guardrail with `deny: false`, a failed start hook does not change the response status to `246`. The request continues with its usual status and you can read the failure from `hook_results.start_hooks`.
### Hard Deny (`446`)
```json theme={"system"}
{
"status": "failure",
"message": "Request denied by start hook guardrail",
"details": {
"hookId": "require-team-header",
"checks": [
{
"id": "default.headerCheck",
"verdict": false,
"data": {
"explanation": "Check failed for 'all' header key-value pairs. Some header key-value pairs did not match.",
"matched_keys": [],
"unmatched_keys": ["x-team"],
"operator": "all"
}
}
]
}
}
```
The `message` is the guardrail's custom error message if you set one (up to 512 characters). Otherwise it is `Request denied by start hook guardrail`.
> [!NOTE]
>
> This error body is different from the one returned for a failed input guardrail, which uses an `error` object and `hook_results`. If your client already parses `446` responses from input guardrails, handle the start hook shape too.
### Soft Deny (`200`)
With `soft_deny_200: true`, the client gets a `200` response shaped like a normal response for the endpoint. For chat completions, the assistant message contains the guardrail's custom error message, or the default guardrail failure message if none is set, and the guardrail results are included in `hook_results`. For streaming requests the gateway sends a well-formed event stream, so client SDKs don't fail while parsing it.
Use soft deny when a client can't handle a non-`2xx` status.
### Log Only
With `deny: false`, the hook never blocks. Use it to watch for violations before you start enforcing them.
### Async Start Hooks
With `async: true`, the hook runs after the response has been sent and cannot affect the request. Use it for logging and auditing. Header and metadata changes from async hooks are not applied.
## Reading Results
Start hook results are reported separately from the other hook types:
* In responses, under `hook_results.start_hooks`, next to `before_request_hooks` and `after_request_hooks`
* In [logs](/docs/product/observability/logs), on the **Feedback & Guardrails** tab of the log drawer, recorded with the `startHook` event type
```json theme={"system"}
{
"hook_results": {
"start_hooks": [
{
"id": "require-team-header",
"verdict": true,
"deny": false,
"checks": [
{
"id": "default.headerCheck",
"verdict": true,
"data": {
"explanation": "Check passed for 'all' header key-value pairs. All header key-value pairs matched.",
"matched_keys": ["x-team"],
"unmatched_keys": [],
"operator": "all"
}
}
]
}
],
"before_request_hooks": [],
"after_request_hooks": []
}
}
```
> [!NOTE]
>
> On streaming requests, set the `x-portkey-strict-open-ai-compliance` header to `false` to receive `hook_results` in the stream. See [Guardrails](/docs/product/guardrails) for details.
## How Hooks Combine
* **Multiple hooks:** Every start hook runs, and the request is blocked if any hook with `deny: true` fails.
* **Multiple checks in one hook:** The checks run in parallel by default, and the hook passes only if all of them pass. To make later checks see the changes of earlier ones, such as a Header Check that verifies a Header Transform, define the hook with `"sequential": true`.
* **Header and metadata changes:** Changes from Header Transform and JWT claim extraction are applied only if the request is allowed to continue.
## Handling Check Errors
If a check can't complete, for example a webhook times out or a JWT can't be verified, the error is recorded in the check result. By default a check that errors does **not** block the request. For checks that enforce a policy, set `failOnError` to `true` in the check's parameters so an error counts as a failure:
```json theme={"system"}
{
"id": "default.webhook",
"parameters": {
"webhookURL": "https://guardrails.example.com/start-check",
"timeout": 3000,
"failOnError": true
}
}
```
A hook that is defined in a config but has no usable checks, for example because every check ID is unknown, is treated as failed. A hook with `deny: true` blocks the request instead of silently letting it through.
## Related
> [card] [Enforcing Policies with Start Hooks](/docs/product/administration/enforce-policies-with-start-hooks)
>
> Apply start hooks to every request in a workspace or organization
> [card] [Guardrails](/docs/product/guardrails)
>
> Input and output guardrails, actions, and response structure
# Open Source
Source: https://docs.portkey.ai/docs/product/open-source
## [Portkey AI Gateway](https://github.com/portkey-ai/rubeus)
We have open sourced our battle-tested AI Gateway to the community - it connects to 250+ LLMs with a unified interface and a single endpoint, and lets you effortlessly setup fallbacks, load balancing, retries, and more.
This gateway is in production at Portkey processing billions of tokens every day.
#### [Contribute here](https://github.com/portkey-ai/rubeus).
***
## [Portkey Models](https://github.com/Portkey-AI/models)
Open-source pricing database for **2,300+ LLMs** across **35+ providers**. Powers cost tracking across the Portkey ecosystem.
* **[UI Explorer](https://portkey.ai/models)** — Browse and search all models
* **[Model Rankings](https://portkey.ai/rankings)** — Top models by usage on Portkey
> [card] [API Documentation](/docs/product/model-catalog/portkey-models)
***
## [AI Grants Finder](https://grantsfinder.portkey.ai/)
Community resource for AI builders to find `GPU credits`, `grants`, `AI accelerators`, or `investments` - all in a single place. Continuously updated, and sometimes also featuring [exclusive deals](https://twitter.com/PortkeyAI/status/1692463628514156859).
Access the data [here](https://airtable.com/appUjtBcdLQIgusqW/shrAU1e4M5twTmRal).
***
## [Gateway Reports](https://portkey.ai/blog/tag/benchmarks/)
We collaborate with the community to dive deep into how the LLMs & their inference providers are performing at scale, and publish gateway reports. We track latencies, uptime, cost changes, fluctuations across various modalitites like time-of-day, regions, token-lengths, and more.
#### [2025 AI Infrastructure Benchmark Report](https://portkey.ai/llms-in-prod-25)

Insights from analyzing 2 trillion+ tokens, across 90+ regions and 650+ teams in production. The report contains:
* Trends shaping AI adoption and LLM provider growth.
* Benchmarks to optimize speed, cost and reliability.
* Strategies to scale production-grade AI systems.
> [card] [The report is available here](https://portkey.ai/llms-in-prod-25)
***
#### [GPT-4 is getting faster](https://portkey.ai/blog/gpt-4-is-getting-faster/)

***
## Collaborations
Portkey supports various open source projects with additional production capabilities through its custom integrations.
> [card] [Check out our expanding ecosystem of integrations](/docs/integrations/ecosystem)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Feature Comparison
Source: https://docs.portkey.ai/docs/product/product-feature-comparison
Comparing Portkey's Open-source version and Dev, Pro, Enterprise plans.
Portkey has a generous free tier (10k requests/month) on our **Dev** plan — but, as you move to production-scale, you may benefit from Portkey's **Pro** or **Enterprise** plans.
> [card] 650+ Global Orgs
>
> Trust Portkey for democratizing and productionizing Gen AI
> [card] 2.5 Trillion+ LLM Tokens
>
> Processed on Portkey so far
> [card] 99.9% Uptime SLA
>
> Ensuring your AI services are always available
> [card] 7,400 Stars
>
> The most popular and performant AI Gateway in the market
## Why Enterprises Choose Portkey
Enterprise customers leverage Portkey to **observe**, **govern**, and **optimize** their Gen AI services at scale across the entire org. Our Enterprise plan offers advanced security configurations, dedicated support, and customized infrastructure designed for high-volume production deployments.
> [card] [For Scale & Performance](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
>
> ▪️ Processing millions of requests
>
> ▪️ Need Five 9s reliability
>
> ▪️ Routing to private LLMs
>
> ▪️ Building for multiple partner teams and departments
> [card] [For Security & Compliance](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
>
> ▪️ SOC2, ISO27001, GDPR, HIPAA
>
> ▪️ VPC / Hybrid deployment
>
> ▪️ PII anonymization
>
> ▪️ Advanced access controls
Here's a detailed comparison of our plans to help you choose the right solution for your needs:
> [accordion] tl;dr Summary for each plan
>
> > [card] [Open Source](https://github.com/portkey-ai/gateway)
> >
> > For developers needing complete control over AI infrastructure on their own servers.
> >
> > **Ideal for:**
> >
> > * Technical teams with privacy requirements
> > * Self-hosted AI applications
> > * Local development & experimentation
>
> > [card] [Dev Plan](https://app.portkey.ai/signup)
> >
> > Free starter plan with basic observability and key management features.
> >
> > **Ideal for:**
> >
> > * Solo developers building POCs
> > * Startups in early development
> > * Testing Portkey capabilities
>
> > [card] [Pro Plan](https://app.portkey.ai/signup)
> >
> > For growing teams with advanced caching, alerts, and access control needs.
> >
> > **Ideal for:**
> >
> > * Startups scaling AI applications
> > * SaaS products integrating AI
> > * Teams needing collaboration features
>
> > [card] [Enterprise Plan](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
> >
> > Enterprise-grade security, compliance, and scalability with flexible deployment.
> >
> > **Ideal for:**
> >
> > * Organizations with compliance needs
> > * Handling sensitive data
> > * Custom infrastructure requirements
> > * Multiple deployment options (SaaS, Hybrid)
| Product / Plan | \[card] Open Source | \[card] Dev (Free Forever) | \[card] Pro (\$49/Month) | \[card] Enterprise (Custom) |
| :- | :- | :- | :- | :- |
| Get Started | \[card] [Run Local](https://github.com/portkey-ai/gateway) | \[card] [Sign Up](https://app.portkey.ai/signup) | \[card] [Upgrade](https://app.portkey.ai/signup) | \[card] [Book Call](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action) |
| Requests per Month | No Limit | 10K | 100K | Custom |
| Overage | - | No Overage Allowed | \$9/Month for Every 100K Up to 3M Requests | Custom Pricing |
| Observability | | | | |
| Logs | | | | |
| Traces | | | | |
| Feedback | | | | |
| Custom Metadata | | | | |
| Filters | | | | |
| Alerts | | | | |
| FinOps + Executive Dashboard | | | | |
| Retention Period | | 3 Days | 30 Days | Custom |
| AI Gateway | | | | |
| Universal API | | | | |
| Automatic Fallbacks | | | | |
| Loadbalancing | | | | |
| Conditional Routing | | | | |
| Automatic Retries | | | | |
| Request Timeouts | | | | |
| Config Management | | | | |
| LLM Key Management | | | | (with Budgeting, Rate Limiting support) |
| Simple Caching | | 1 Day TTL SUport | Unlimited TTL Stream from Cache | Unlimited TTL Stream from Cache |
| Semantic Caching | | | Unlimited TTL Stream from Cache | Unlimited TTL Stream from Cache |
| Unified Construct for Fine-Tuning, Files, Batche APIs | | | | |
| Support for AWS, GCP, Azure Private LLM Deployments | | | | |
| Prompt Management | | | | |
| Prompt Templates | | Upto 3 Templates | Unlimited | Unlimited |
| Playground | | | | |
| API Deployment | | | | |
| Versioning | | | | |
| Variable Management | | | | |
| Prompt Partials | | | | |
| Side-by-Side Comparison | | | | |
| User Access Control | | | | |
| Guardrails | | | | |
| Deterministic Guardrails | | | | |
| Partner Guardrails (LLM or Non LLM based) | | | | |
| Portkey LLM Guardrails with PII / PHI Redaction | | | | |
| Autonomous Fine-Tuning | | | | |
| Continuous Improvement | | | | |
| Security & Compliance | | | | |
| Role Based Access Control | | | | (Advanced) |
| Team Management | | | | (Advanced) |
| Audit Logs | | | | |
| Admin APIs (Control Plane & Data Plane) | | | | |
| SCIM Provisioning | | | | |
| JWT-based Authentication | | | | |
| Bring Your Own Key for Encryption | | | | |
| Enforce Org-level Metadata Reporting | | | | |
| Enforce Org-level LLM Guardrails | | | | |
| SSO with Okta Auth | | | | |
| SOC2, ISO27001, GDPR, HIPAA Compliance Certificates | | | | |
| BAA Signing for Compliances | | | | |
| VPC Managed Hosting | | | | |
| Private Tenancy | | | | |
| Configurable Retention Periods | | | | |
| Configurable exports to datalakes | | | | |
| Org Management | | | | |
## Enterprise Deployment Options
Portkey offers a range of deployment options designed to meet the diverse security, compliance, and operational requirements of enterprise organizations.
> [tab] Portkey-Managed SaaS
>
> ### Portkey-Managed Enterprise SaaS
>
> A fully-managed solution on Portkey's secure cloud infrastructure with enterprise-grade features and dedicated resources.
>
> **Ideal for:** Organizations seeking enterprise capabilities without the operational overhead of self-hosting.
>
> **Key Features:**
>
> * Isolated cluster exclusively for your organization's data
>
> * Dedicated infrastructure for optimal performance
>
> * Complete suite of enterprise features (RBAC, SSO, audit logs)
>
> * Guaranteed SLAs with priority support
>
> * SOC2, ISO27001, GDPR, and HIPAA compliant
>
> > [card]
> >
> > **Benefits:**
> >
> > * Faster implementation timeline (1-2 weeks)
> > * No infrastructure management required
> > * Automatic updates and scaling
> > * Reduced operational costs
> > * Predictable pricing model
> [tab] Hybrid Deployment
>
> ### Hybrid Deployment
>
> A balanced approach where the AI Gateway and data plane run in your environment while Portkey manages the control plane.
>
> **Ideal for:** Organizations with strict data residency requirements who want operational simplicity.
>
> **Key Features:**
>
> * AI Gateway deployed in your VPC/environment
> * All sensitive LLM data stays within your infrastructure
> * Control plane hosted by Portkey for management
> * Significantly reduced latency for API calls
> * End-to-end encryption between components
>
> 
>
> Hybrid deployment architecture
> [tab] Airgapped Deployment (Legacy)
>
> > [!WARNING]
> >
> > **Air-gapped deployment is no longer offered.** Portkey no longer provisions new fully air-gapped deployments. This content is retained for reference and for customers with an existing air-gapped deployment, which remains supported.
> >
> > [Contact us](https://www.paloaltonetworks.in/ai-security/ai-gateway#contact?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_footer) to discuss deployment options.
>
> ### Fully Airgapped Deployment (No Longer Offered)
>
> Complete control with all components (Data plane, Control plane, and AI Gateway) deployed within your infrastructure.
>
> **Ideal for:** Organizations in highly regulated industries with stringent security requirements.
>
> **Key Features:**
>
> * 100% of components run in your environment
>
> * Zero data leaves your network, including metrics
>
> * Complete network isolation possible
>
> * Compatible with air-gapped environments
>
> * Custom support structure tailored to your security protocols
>
> > [card]
> >
> > **Use Cases:**
> >
> > * Financial institutions handling sensitive financial data
> > * Healthcare organizations with strict PHI requirements
> > * Government agencies with classified information
> > * Defense contractors working with sensitive IP
> > * Organizations in regions with strict data sovereignty laws
***
All enterprise deployment options include comprehensive security features such as SOC2, ISO27001, GDPR, and HIPAA compliance certifications, PII anonymization, custom data retention policies, and encryption at rest and in transit.
> [card] Ready to explore Enterprise options?
>
> **Schedule a 30-minute consultation** with our solutions team to discuss your specific requirements and see a live demo.
>
> \[Book Your Consultation]\([https://www.paloaltonetworks.com/ai-security/ai-gateway#:\~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
## Enterprise Implementation Journey
**1. Discovery Call**
30-minute discussion to understand your use case and requirements
**2. Technical Deep Dive**
Call with the Portkey engineering team to demo exact requirements & understand deployment options
**3. Solution Design | Parallel Purchasing/Legal Discussions**
Our team configures the optimal deployment model for your needs
**4. Onboarding | Parallel Contract Close**
Most enterprise customers are fully operational within 3-4 weeks
> [card] [Not sure which deployment model is right for you?](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
>
> Our enterprise team can help assess your requirements and recommend the optimal deployment strategy for your organization's specific needs.
>
> Book a Consultation here.
## Interested? Schedule a Call Below
[https://www.paloaltonetworks.com/ai-security/ai-gateway#:\~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action](https://www.paloaltonetworks.com/ai-security/ai-gateway#:~:text=See%20Prisma%20AIRS%20AI%20Gateway%20in%20Action)
## Frequently Asked Questions
> [accordion] What are the different deployment options available for Portkey Enterprise?
>
> Portkey Enterprise offers two deployment options:
>
> 1. **Portkey-Managed SaaS**: A fully-managed solution where your data is hosted on Portkey's secure infrastructure with an isolated cluster exclusively for your organization.
>
> 2. **Hybrid Deployment**: The AI Gateway and data plane run in your own environment while Portkey manages the control plane, ensuring all sensitive LLM data stays within your infrastructure.
>
> A third option, **Fully Airgapped Deployment** (all components in your infrastructure with zero data leaving your network), is no longer offered for new deployments. Existing air-gapped deployments remain supported.
>
> Each option is designed to meet different security, compliance, and operational requirements. Our enterprise team can help you determine which option is best for your specific needs.
> [accordion] What is the typical implementation timeline for Enterprise customers?
>
> Most Enterprise customers can be fully onboarded within 1-2 weeks, depending on specific requirements. Our dedicated implementation team will work with you to ensure a smooth transition. For complex deployments or those requiring special compliance measures, the timeline may extend to 3-4 weeks.
> [accordion] How does Portkey handle migration from other AI infrastructure solutions?
>
> Portkey offers a comprehensive migration service for Enterprise customers, including API mapping, configuration setup, and verification testing. Our team will work with you to ensure minimal disruption during the transition. We provide detailed documentation and support throughout the migration process.
> [accordion] What integration capabilities are available for Enterprise customers?
>
> Enterprise customers have access to all Portkey integration capabilities, including custom API integrations, webhooks, SDKs for major programming languages, and specialized connectors for enterprise systems. We also offer custom integration development for specific needs.
> [accordion] What level of support do Enterprise customers receive?
>
> Enterprise customers receive priority 24/7 support with guaranteed response times (typically under 1 hour), a dedicated customer success manager, regular performance reviews, and direct access to our engineering team when needed. We also provide customized SLAs based on your specific requirements.
> [accordion] How does Portkey ensure data security and compliance?
>
> Portkey's Enterprise plan includes comprehensive security features such as SOC2, ISO27001, GDPR, and HIPAA compliance certifications. We offer PII anonymization, custom data retention policies, VPC deployment options, and BAA signing for healthcare organizations. All data is encrypted in transit and at rest.
> [accordion] Can we run Portkey in our own cloud environment?
>
> Yes, Enterprise customers can deploy Portkey in their own AWS, GCP, or Azure environments, with options for VPC peering, private network connectivity, and dedicated infrastructure. Our team will work with your cloud operations staff to ensure optimal deployment.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt API
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-api
Learn how to integrate Portkey's prompt templates directly into your applications using the Prompt API
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
The Portkey Prompts API allows you to seamlessly integrate your saved prompts directly into your applications. This powerful feature lets you separate prompt engineering from application code, making both easier to maintain while providing consistent, optimized prompts across your AI applications.
With the Prompt API, you can:
* Use versioned prompts in production applications
* Dynamically populate prompts with variables at runtime
* Override prompt parameters as needed without modifying the original templates
* Retrieve prompt details for use with provider-specific SDKs
## API Endpoints
Portkey offers two primary endpoints for working with saved prompts:
1. **Prompt Completions** (`/prompts/{promptId}/completions`) - Execute your saved prompt templates directly, receiving model completions
2. **Prompt Render** (`/prompts/{promptId}/render`) - Retrieve your prompt template with variables populated, without executing it
## Prompt Completions
The Completions endpoint is the simplest way to use your saved prompts in production. It handles the entire process - retrieving the prompt, applying variables, sending it to the appropriate model, and returning the completion.
### Making a Completion Request
> [tab] Python SDK
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY"
> )
>
> # Execute the prompt with provided variables
> completion = portkey.prompts.completions.create(
> prompt_id="YOUR_PROMPT_ID",
> variables={
> "user_input": "Hello world"
> },
> max_tokens=250,
> presence_penalty=0.2
> )
>
> print(completion)
> ```
> [tab] NodeJS SDK
>
> ```javascript theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY"
> });
>
> // Execute the prompt with provided variables
> const completion = await portkey.prompts.completions.create({
> promptID: "YOUR_PROMPT_ID",
> variables: {
> "user_input": "Hello world"
> },
> max_tokens: 250,
> presence_penalty: 0.2
> });
>
> console.log(completion);
> ```
> [tab] cURL
>
> ```bash theme={"system"}
> curl -X POST "https://api.portkey.ai/v1/prompts/YOUR_PROMPT_ID/completions" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "variables": {
> "user_input": "Hello world"
> },
> "max_tokens": 250,
> "presence_penalty": 0.2
> }'
> ```
### Streaming Support
The completions endpoint also supports streaming responses for real-time interactions:
> [tab] NodeJS SDK
>
> ```javascript theme={"system"}
> import Portkey from 'portkey-ai';
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY"
> });
>
> // Create a streaming completion
> const streamCompletion = await portkey.prompts.completions.create({
> promptID: "YOUR_PROMPT_ID",
> variables: {
> "user_input": "Hello world"
> },
> stream: true
> });
>
> // Process the stream
> for await (const chunk of streamCompletion) {
> console.log(chunk);
> }
> ```
> [tab] Python SDK
>
> ```python theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY"
> )
>
> # Create a streaming completion
> completion = portkey.prompts.completions.create(
> prompt_id="YOUR_PROMPT_ID",
> variables={
> "user_input": "Hello world"
> },
> stream=True
> )
>
> # Process the stream
> for chunk in completion:
> print(chunk)
> ```
## Prompt Render
You can retrieve your saved prompts on Portkey using the `/prompts/$PROMPT_ID/render` endpoint. Portkey returns a JSON containing your prompt or messages body along with all the saved parameters that you can directly use in any request.
This is helpful if you are required to use provider SDKs and can not use the Portkey SDK in production. ([Example of how to use Portkey prompt templates with OpenAI SDK](/docs/product/prompt-library/retrieve-prompts#using-the-render-output-in-a-new-request))
## Using the `Render` Endpoint/Method
1. Make a request to `https://api.portkey.ai/v1/prompts/$PROMPT_ID/render` with your prompt ID
2. Pass your Portkey API key with `x-portkey-api-key` in the header
3. Send up the variables in your payload with `{ "variables": { "VARIABLE_NAME": "VARIABLE_VALUE" } }`
That's it! See it in action:
> [tab] cURL
>
> ```sh theme={"system"}
> curl -X POST "https://api.portkey.ai/v1/prompts/$PROMPT_ID/render" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "variables": {"movie":"Dune 2"}
> }'
> ```
>
> The Output:
>
> ```JSON theme={"system"}
> {
> "success": true,
> "data": {
> "model": "gpt-4",
> "n": 1,
> "top_p": 1,
> "max_tokens": 256,
> "temperature": 0,
> "presence_penalty": 0,
> "frequency_penalty": 0,
> "messages": [
> {
> "role": "system",
> "content": "You're a helpful assistant."
> },
> {
> "role": "user",
> "content": "Who directed Dune 2?"
> }
> ]
> }
> }
> ```
> [tab] Portkey Python SDK
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY"
> )
>
> render = portkey.prompts.render(
> prompt_id="PROMPT_ID",
> variables={ "movie":"Dune 2" }
> )
>
> print(render.data)
> ```
>
> The Output:
>
> ```JSON theme={"system"}
> {
> "model": "gpt-4",
> "n": 1,
> "top_p": 1,
> "max_tokens": 256,
> "temperature": 0,
> "presence_penalty": 0,
> "frequency_penalty": 0,
> "messages": [
> {
> "role": "system",
> "content": "You're a helpful assistant."
> },
> {
> "role": "user",
> "content": "Who directed Dune 2?"
> }
> ]
> }
> ```
> [tab] Portkey Node SDK
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY"
> })
>
> async function getRender(){
> const render = await portkey.prompts.render({
> promptID: "PROMPT_ID",
> variables: { "movie":"Dune 2" }
> })
>
> console.log(render.data)
> }
>
> getRender()
> ```
>
> The Output:
>
> ```JSON theme={"system"}
> {
> "model": "gpt-4",
> "n": 1,
> "top_p": 1,
> "max_tokens": 256,
> "temperature": 0,
> "presence_penalty": 0,
> "frequency_penalty": 0,
> "messages": [
> {
> "role": "system",
> "content": "You're a helpful assistant."
> },
> {
> "role": "user",
> "content": "Who directed Dune 2?"
> }
> ]
> }
> ```
## Updating Prompt Params While Retrieving the Prompt
If you want to change any model params (like `temperature`, `messages body` etc) while retrieving your prompt from Portkey, you can send the override params in your `render` payload.
Portkey will send back your prompt with overridden params, **without** making any changes to the saved prompt on Portkey.
> [tab] cURL
>
> ```sh theme={"system"}
> curl -X POST "https://api.portkey.ai/v1/prompts/$PROMPT_ID/render" \
> -H "Content-Type: application/json" \
> -H "x-portkey-api-key: $PORTKEY_API_KEY" \
> -d '{
> "variables": {"movie":"Dune 2"},
> "model": "gpt-3.5-turbo",
> "temperature": 2
> }'
> ```
>
> Based on the above snippet, `model` and `temperature` params in the retrieved prompt will be **overridden** with the newly passed values
>
> The New Output:
>
> ```JSON theme={"system"}
> {
> "success": true,
> "data": {
> "model": "gpt-3.5-turbo",
> "n": 1,
> "top_p": 1,
> "max_tokens": 256,
> "temperature": 2,
> "presence_penalty": 0,
> "frequency_penalty": 0,
> "messages": [
> {
> "role": "system",
> "content": "You're a helpful assistant."
> },
> {
> "role": "user",
> "content": "Who directed Dune 2?"
> }
> ]
> }
> }
> ```
> [tab] Python SDK
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY"
> )
>
> render = portkey.prompts.render(
> prompt_id="PROMPT_ID",
> variables={ "movie":"Dune 2" },
> model="gpt-3.5-turbo",
> temperature=2
> )
>
> print(render.data)
> ```
>
> Based on the above snippet, `model` and `temperature` params in the retrieved prompt will be **overridden** with the newly passed values.
>
> **The New Output:**
>
> ```JSOn theme={"system"}
> {
> "model": "gpt-3.5-turbo",
> "n": 1,
> "top_p": 1,
> "max_tokens": 256,
> "temperature": 2,
> "presence_penalty": 0,
> "frequency_penalty": 0,
> "messages": [
> {
> "role": "system",
> "content": "You're a helpful assistant."
> },
> {
> "role": "user",
> "content": "Who directed Dune 2?"
> }
> ]
> }
> ```
> [tab] NodeJS SDK
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY"
> })
>
> async function getRender(){
> const render = await portkey.prompts.render({
> promptID: "PROMPT_ID",
> variables: { "movie":"Dune 2" },
> model: "gpt-3.5-turbo",
> temperature: 2
> })
>
> console.log(render.data)
> }
>
> getRender()
> ```
>
> Based on the above snippet, `model` and `temperature` params in the retrieved prompt will be **overridden** with the newly passed values.
>
> **The New Output:**
>
> ```JSON theme={"system"}
> {
> "model": "gpt-3.5-turbo",
> "n": 1,
> "top_p": 1,
> "max_tokens": 256,
> "temperature": 2,
> "presence_penalty": 0,
> "frequency_penalty": 0,
> "messages": [
> {
> "role": "system",
> "content": "You're a helpful assistant."
> },
> {
> "role": "user",
> "content": "Who directed Dune 2?"
> }
> ]
> }
> ```
## Using the `render` Output in a New Request
Here's how you can take the output from the `render` API and use it for making a call. We'll take example of OpenAI SDKs, but you can use it simlarly for any other provider SDK as well.
> [tab] OpenAI NodeJS
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai';
> import OpenAI from 'openai';
>
> // Retrieving the Prompt from Portkey
>
> const portkey = new Portkey({
> apiKey: "PORTKEY_API_KEY"
> })
>
> async function getPromptTemplate() {
> const render_response = await portkey.prompts.render({
> promptID: "PROMPT_ID",
> variables: { "movie":"Dune 2" }
> })
> return render_response.data;
> }
>
> // Making a Call to OpenAI with the Retrieved Prompt
>
> const openai = new OpenAI({
> apiKey: 'OPENAI_API_KEY',
> baseURL: 'https://api.portkey.ai/v1',
> defaultHeaders: {
> 'x-portkey-provider': 'openai',
> 'x-portkey-api-key': 'PORTKEY_API_KEY',
> 'Content-Type': 'application/json',
> }
> });
>
> async function main() {
> const PROMPT_TEMPLATE = await getPromptTemplate();
> const chatCompletion = await openai.chat.completions.create(PROMPT_TEMPLATE);
> console.log(chatCompletion.choices[0]);
> }
>
> main();
> ```
> [tab] OpenAI Python
>
> ```py theme={"system"}
> from portkey_ai import Portkey
> from openai import OpenAI
>
> # Retrieving the Prompt from Portkey
>
> portkey = Portkey(
> api_key="PORTKEY_API_KEY"
> )
>
> render_response = portkey.prompts.render(
> prompt_id="PROMPT_ID",
> variables={ "movie":"Dune 2" }
> )
>
> PROMPT_TEMPLATE = render_response.data
>
> # Making a Call to OpenAI with the Retrieved Prompt
>
> openai = OpenAI(
> api_key = "OPENAI_API_KEY",
> base_url = "https://api.portkey.ai/v1",
> default_headers = {
> 'x-portkey-provider': 'openai',
> 'x-portkey-api-key': 'PORTKEY_API_KEY',
> 'Content-Type': 'application/json',
> }
> )
>
> chat_complete = openai.chat.completions.create(**PROMPT_TEMPLATE)
>
> print(chat_complete.choices[0].message.content)
> ```
# Create Prompt via API
You can create and manage prompt templates programmatically using the Portkey Admin API. This is the recommended approach when you need structural Mustache templates (section blocks like `{{#var}}...{{/var}}` that conditionally include entire JSON objects), which cannot be created through the UI's Pretty Mode editor.
## The `is_raw_template` field
| Value | Behaviour |
| - | - |
| `0` (default) | Portkey treats the `string` field as structured messages. Variables (`{{var}}`) inside string values work normally. |
| `1` | Portkey runs Mustache rendering on the raw `string` first, then parses the result as JSON. Required when section blocks span JSON structure (e.g. a conditional `image_url` content block). |
## Creating a Prompt
> [tab] cURL
>
> ```bash theme={"system"}
> curl --request POST \
> --url https://api.portkey.ai/v1/prompts \
> --header 'Content-Type: application/json' \
> --header 'x-portkey-api-key: $PORTKEY_API_KEY' \
> --data '{
> "collection_id": "YOUR_COLLECTION_ID",
> "name": "vision-conditional-prompt",
> "model": "YOUR_MODEL",
> "parameters": {
> "max_tokens": 512,
> "temperature": 0.5,
> "top_p": 0.9,
> "n": 1,
> "stream": true
> },
> "string": "[{\"role\":\"user\",\"content\":[{\"type\":\"text\",\"text\":\"{{user_prompt}}\"}{{#has_image}},{\"type\":\"image_url\",\"image_url\":{\"url\":\"{{image_url}}\"}}{{/has_image}},{\"type\":\"text\",\"text\":\"Please analyze accordingly.\"}]}]",
> "is_raw_template": 1,
> "virtual_key": "YOUR_VIRTUAL_KEY",
> "version_description": "Conditional vision prompt with Mustache section",
> "template_metadata": {
> "template_type": "chat"
> }
> }'
> ```
> [tab] Python SDK
>
> ```python theme={"system"}
> import requests
>
> response = requests.post(
> "https://api.portkey.ai/v1/prompts",
> headers={
> "Content-Type": "application/json",
> "x-portkey-api-key": "PORTKEY_API_KEY"
> },
> json={
> "collection_id": "YOUR_COLLECTION_ID",
> "name": "vision-conditional-prompt",
> "model": "YOUR_MODEL",
> "parameters": {
> "max_tokens": 512,
> "temperature": 0.5,
> "top_p": 0.9,
> "n": 1,
> "stream": True
> },
> "string": '[{"role":"user","content":[{"type":"text","text":"{{user_prompt}}"}{{#has_image}},{"type":"image_url","image_url":{"url":"{{image_url}}"}}{{/has_image}},{"type":"text","text":"Please analyze accordingly."}]}]',
> "is_raw_template": 1,
> "virtual_key": "YOUR_VIRTUAL_KEY",
> "version_description": "Conditional vision prompt with Mustache section",
> "template_metadata": {"template_type": "chat"}
> }
> )
>
> prompt_id = response.json()["id"]
> print(prompt_id)
> ```
A successful response returns the prompt `id` and `slug`:
```json theme={"system"}
{
"id": "PROMPT_UUID",
"slug": "pp-vision-conditional-XXXXXX",
"version_id": "VERSION_UUID",
"object": "prompt"
}
```
Use the returned `id` or `slug` to call the prompt via the [Completions](/docs/product/prompt-engineering-studio/prompt-api#prompt-completions) or [Render](/docs/product/prompt-engineering-studio/prompt-api#prompt-render) endpoints.
## API Reference
For complete API details, including all available parameters and response formats, refer to the API reference documentation:
* [Prompt Completions API Reference](https://portkey.ai/docs/api-reference/inference-api/prompts/prompt-completion)
* [Prompt Render API Reference](https://portkey.ai/docs/api-reference/inference-api/prompts/render)
## Next Steps
Now that you understand how to integrate prompts into your applications, explore these related features:
* [Prompt Playground](/docs/product/prompt-engineering-studio/prompt-playground) - Create and test prompts in an interactive environment
* [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) - Track changes to your prompts over time
* [Prompt Observability](/docs/product/prompt-engineering-studio/prompt-observability) - Monitor prompt performance in production
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Guides
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-guides
Learn how to get the most out of Portkey Prompts with these practical guides
## Getting Started with Portkey Prompts
Our guides help you master Portkey Prompts - from basic concepts to advanced techniques. Whether you're new to prompt engineering or looking to optimize your existing workflows, these resources will help you build better AI applications.
> [!NOTE]
>
> You can easily access Prompt Engineering Studio using [https://prompt.new](https://prompt.new)
> [card] [Create a chatbot using Portkey Prompt Templates](/docs/guides/prompts/build-a-chatbot-using-portkeys-prompt-templates)
Still have questions? Reach out to [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) to get help from our team.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Integrations
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-integration
Portkey prompts can be seamlessly integrated with your development workflow and existing tools. These integrations help you leverage your optimized prompts across your entire AI infrastructure.
> [!NOTE]
>
> You can easily access Prompt Engineering Studio using [https://prompt.new](https://prompt.new)
> [card] [Promptfoo](/docs/integrations/libraries/promptfoo)
> [card] [Llamaindex](/docs/integrations/libraries/llama-index-python)
> [card] [Langchain](/docs/integrations/libraries/langchain-python)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Prompt Partials
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-partial
With Prompt Partials, you can save your commonly used templates (which could be your instruction set, data structure explanation, examples etc.) separately from your prompts and flexibly incorporate them wherever required.
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
Partials can also serve as a global variable store. You can define common variables that are used across multiple of your prompt templates and can reference or update them easily.
## Creating Partials
Partials are directly accessible from the Prompts Page in the [Prompt Engineering Studio](/docs/product/prompt-engineering-studio):

You can create a new Partial and use it for any purpose in any of your prompt templates. For example, here's a prompt partial where we are separately storing the instructions:

Upon saving, each Partial generates a unique ID that you can use inside [prompt templates](/docs/product/prompt-engineering-studio/prompt-playground#prompt-templates).
### Template Engine
Partials also follow the [Mustache template engine](https://mustache.github.io/) and let you easily handle data input at runtime by using tags.
Portkey supports `{{variable}}`, `{{#block}} {{/block}}`, `{{^block}}` and other tags.
For more details on template syntax, check out the [Prompt Playground documentation](/docs/product/prompt-engineering-studio/prompt-playground#supported-tags) which includes a comprehensive guide on how to use tags.
### Versioning
Portkey follows the same `Update` **&** `Publish` flow as prompt templates. You can keep updating the partial and save new versions, and choose to send any version to production using the `Publish` feature.
All the version history for any partial is available on the right column and any previous version can be restored to be `latest` or `published` to production easily. For more details on how versioning works, see the [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) documentation.
## Using Partials
You can call Partials by their ID inside any prompt template by just starting to type `{{>`.
Portkey lists all of the available prompt partials with their names to help you easily pick:

When a partial is incorporated in a template, all the variables/blocks defined are also rendered on the Prompt variables section:

When a new Partial version is **Published**, your partial that is in use in any of the prompt templates also gets automatically updated.
### Using Different Versions of Partials
Similar to prompt templates, you can reference specific versions of your prompt partials in the playground. By default, when you use a partial, Portkey uses the published version, but you can specify any version you want.
To reference a specific version of a partial, use the following syntax:
```
{{>prompt-partial-id@version-number}}
```
For example:
```
{{>pp-instructions-123@5}}
```
This will use version 5 of the prompt partial with ID "pp-instructions-123".
**Note:** Unlike prompt templates, prompt partials do not support `labels`, `@latest`, `@published` for versioning. You can only reference partials by their version number, `@latest`, or the published version.
### Making a Prompt Completion Request
All the variables/tags defined inside the partial can now be directly called at the time of making a `prompts.completions` request:
> [tab] NodeJS SDK
>
> ```js theme={"system"}
> import Portkey from 'portkey-ai'
>
> const portkey = new Portkey({
> apiKey: "YOUR_PORTKEY_API_KEY"
> })
>
> const response = portkey.prompts.completions.create({
> promptID: "pp-system-pro-34a60b",
> variables: {
> "user_query":"",
> "company":"",
> "product":"",
> "benefits":"",
> "phone number":"",
> "name":"",
> "device":"",
> "query":""
> }
> })
> ```
> [tab] Python SDK
>
> ```py theme={"system"}
> from portkey_ai import Portkey
>
> portkey = Portkey(
> api_key="YOUR_PORTKEY_API_KEY"
> )
>
> response = portkey.prompts.completions.create(
> prompt_id="PROMPT_ID",
> variables={
> "user_query":"",
> "company":"",
> "product":"",
> "benefits":"",
> "phone number":"",
> "name":"",
> "device":"",
> "query":""
> }
> )
> ```
For more details on integrating prompts in your application, see the [Prompt API documentation](/docs/product/prompt-engineering-studio/prompt-api).
## Sharing Partials Across Workspaces
Share partials with other workspaces in your organization with read-only access. Recipients can reference the partial in their prompts or fork it into their own workspace to customize.
When forking a shared partial, the destination workspace must have access to any LLM integrations the partial depends on through [Workspace Provisioning](/docs/product/model-catalog/integrations#1-workspace-provisioning). Forking fails with an error if the required integration isn't provisioned.
If a prompt being shared uses partials that aren't shared yet, Portkey prompts you to share those partials in the same flow. See [Sharing prompts and partials](/docs/product/prompt-engineering-studio/prompt-sharing) for the full flow.
## Benefits of Using Partials
Using Prompt Partials offers several advantages for your AI applications:
1. **Reusability**: Create instructions once and use them across multiple prompts
2. **Consistency**: Ensure all prompts follow the same guidelines and structure
3. **Maintainability**: Update instructions in one place and have changes propagate everywhere
4. **Organization**: Keep your prompt library clean by separating reusable components
5. **Collaboration**: Enable team members to use standardized components in their prompts
## Best Practices for Prompt Partials
For optimal use of Prompt Partials:
* Use descriptive names for your partials to make them easy to identify
* Create partials for frequently used instructions, examples, or context
* Keep partials focused on a single purpose for better reusability
* Document your partials to help team members understand their purpose
* Use [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) to track changes to your partials
* Consider creating specialized partials for different use cases (e.g., one for detailed instructions, another for examples)
## Common Use Cases for Partials
Prompt Partials are particularly useful for:
* **System Instructions**: Create standardized directives for your AI models
* **Example Sets**: Maintain collections of examples to guide model outputs
* **Context Blocks**: Store context information that can be reused across prompts
* **Output Formats**: Define structured output templates for consistent responses
* **Tool Definitions**: Maintain standard tool definitions for function calling
## Next Steps
Now that you understand how to use Prompt Partials, explore these related features:
* [Prompt Playground](/docs/product/prompt-engineering-studio/prompt-playground) - Create and test prompts using your partials
* [Prompt Library](/docs/product/prompt-engineering-studio/prompt-library) - Organize your prompts and partials
* [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) - Track changes to your partials over time
* [Prompt API](/docs/product/prompt-engineering-studio/prompt-api) - Use partials in your applications
* [Prompt Observability](/docs/product/prompt-engineering-studio/prompt-observability) - Monitor how prompts using your partials perform
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Sharing Prompts and Partials
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/prompt-sharing
Share prompts and partials across workspaces in your organization with read-only access.
> [!NOTE]
>
> This feature is available on all Portkey [plans](https://portkey.ai/pricing).
> [!NOTE]
>
> Requires Backend: `v1.17.0` or later
>
> Requires Frontend: `v1.9.0` or later
Share prompts and partials from one workspace to others in your organization so teams can reuse vetted templates without duplicating work. Recipient workspaces only get **read-only** access and can fork the prompt or partial into their own workspace to customize and own it.
## How sharing works
* **Read-only access** — Recipients can view and use shared prompts and partials, but cannot edit them. Only the owning workspace can publish new versions.
* **Organization or specific workspaces** — Share with everyone in the organization, or pick specific workspaces.
* **Fork to customize** — Recipients can fork a shared prompt or partial into their own workspace to make changes.
* **Dependencies are handled** — If a prompt uses partials that aren't shared yet, Portkey prompts you to share them alongside.
## Sharing a prompt
1. Open the prompt in the [Prompt Library](/docs/product/prompt-engineering-studio/prompt-library).
2. Click **Share**.
3. Under **Access**, choose:
* **Organization** — Visible to everyone in your organization.
* **Specific workspaces** — Visible only to the workspaces you select.
4. Click **Share**.

> [!NOTE]
>
> If the prompt references any [partials](/docs/product/prompt-engineering-studio/prompt-partial) that aren't already shared with the target workspaces, Portkey shows an option to share those partials in the same flow. Shared prompts won't render correctly without their partials.
## Sharing a partial
Partials follow the same flow as prompts:
1. Open the partial from the **Prompt Partials** page.
2. Click on the **Share** icon on the prompt card
3. Choose **Organization** or **Specific workspaces**.
4. Click **Share**.
## Viewing shared prompts and partials
Recipients access shared items from the **Shared with me** tab in the Prompts and Prompt Partials pages. Each entry is labeled **Read only** and shows the original author and last update time.

Use the prompt ID shown in this tab to reference the prompt directly via the [Prompt API](/docs/product/prompt-engineering-studio/prompt-api).
## Forking a shared prompt
Forking creates an editable copy of a shared prompt or partial in your workspace. The fork is a new prompt with its own ID and version history — changes to the original do not propagate to forks.
To fork:
1. Open the shared prompt from the **Shared with me** tab.
2. Click **Fork**.
3. Select the destination workspace.
### Requirements for forking
The destination workspace must have access to the same LLM integration the prompt uses. Integration access is managed through [Workspace Provisioning](/docs/product/model-catalog/integrations#1-workspace-provisioning) in the Model Catalog.
> [!WARNING]
>
> If the LLM integration referenced by the prompt isn't provisioned to the destination workspace, the fork will fail with an error. Provision the integration to the workspace before forking, or fork into a workspace that already has access.
If the prompt depends on partials, those partials must also be shared with the destination workspace before forking succeeds.
## Permissions
* Any workspace member with edit access to a prompt or partial can share it.
* Only the owning workspace can publish new versions of a shared item.
* Recipients with read-only access can view, use via the Prompt API, and fork — but cannot edit the original.
## Next steps
* [Prompt Library](/docs/product/prompt-engineering-studio/prompt-library) — Organize prompts and folders
* [Prompt Partials](/docs/product/prompt-engineering-studio/prompt-partial) — Build reusable prompt components
* [Workspace Provisioning](/docs/product/model-catalog/integrations#1-workspace-provisioning) — Manage LLM integration access per workspace
* [Prompt Versioning](/docs/product/prompt-engineering-studio/prompt-versioning) — Track changes over time
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Tool Library
Source: https://docs.portkey.ai/docs/product/prompt-engineering-studio/tool-library
## Coming Soon!!!
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Model Pricing for Air-Gapped Deployments
Source: https://docs.portkey.ai/docs/self-hosting/airgapped/model-pricing
Configure model pricing and capabilities data for fully air-gapped Portkey deployments. Legacy — air-gapped is no longer offered for new deployments.
> [!WARNING]
>
> **Air-gapped deployment is no longer offered.** Portkey no longer provisions new fully air-gapped deployments. This content is retained for reference and for customers with an existing air-gapped deployment, which remains supported.
>
> [Contact us](https://www.paloaltonetworks.in/ai-security/ai-gateway#contact?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_footer) to discuss deployment options.
## Requirements
* [Helm chart](https://github.com/Portkey-AI/helm) `app-1.5.0+`
* [Backend](/docs/changelog/backend#private-deployment-pricing) `v1.7.0+`
* [Enterprise Gateway](/docs/changelog/enterprise#dynamic-model-pricing-for-air-gapped-deployments) `v2.0.0+`
## Overview
In air-gapped setups, the Gateway and Backend cannot access Portkey's hosted control plane for automatic pricing updates. Pricing and model capability data must be sourced locally or from an allowed endpoint.
**Flow:**
* The **Gateway** fetches pricing from the **Backend** when:
```
MODEL_CONFIGS_PROXY_FETCH_ENABLED=ON
```
* The **Backend** resolves pricing using a fallback chain.
### Built-In Fallback Behavior
* If the Gateway cannot reach the Backend → it uses bundled pricing configs.
* If the Backend cannot reach any configured source → it uses bundled pricing configs.
* A baseline dataset is always available.
```mermaid theme={"system"}
flowchart TD
GW["Gateway"] -->|MODEL_CONFIGS_PROXY_FETCH_ENABLED=ON| BE["Backend"]
GW -.->|Backend unreachable| GW_LOCAL["Gateway Bundled Configs"]
BE --> CACHE{"Memory Cache (1h TTL)"}
CACHE -->|hit| DONE["Return Pricing"]
CACHE -->|miss| PROXY{"Proxy Service Configured?"}
PROXY -->|success| DONE
PROXY -->|fail / not configured| LOG{"Log Store Configured?"}
LOG -->|success| DONE
LOG -->|fail / not configured| LOCAL{"Local Path Configured?"}
LOCAL -->|success| DONE
LOCAL -->|fail / not configured| IMG["Backend Bundled Configs"]
IMG --> DONE
```
## Option 1: Use Portkey Hosted Config Service
Use when outbound HTTPS is allowed from Backend.
Backend fetches pricing and capabilities JSON from:
```
https://configs.portkey.ai/pricing/{provider}.json
https://configs.portkey.ai/general/{provider}.json
```
> [!NOTE]
>
> No request data is sent to Portkey. Only static JSON files are retrieved. See the [Portkey Models API docs](/docs/product/model-catalog/portkey-models) for the full schema.
### Gateway
| Variable | Value |
| - | - |
| `MODEL_CONFIGS_PROXY_FETCH_ENABLED` | `ON` |
| `CONFIG_READER_PATH` | `/albus/v2/utils/model-configs` |
### Backend
| Variable | Value |
| - | - |
| `MODEL_CONFIGS_PROXY_FETCH_ENABLED` | `ON` |
| `MODEL_CONFIGS_PROXY_URL` | `https://configs.portkey.ai` |
Data is cached in memory for 1 hour.
## Option 2: Fully Air-Gapped (Self-Hosted Data)
Use when no outbound internet is allowed.
### Gateway
| Variable | Value |
| - | - |
| `MODEL_CONFIGS_PROXY_FETCH_ENABLED` | `ON` |
| `CONFIG_READER_PATH` | `/albus/v2/utils/model-configs` |
### Backend
Maintain a local copy of the open-source [Portkey Models repository](https://github.com/Portkey-AI/models).
Repository structure:
```
pricing/{provider}.json
general/{provider}.json
```
Example:
```
pricing/openai.json
general/openai.json
```
You can expose these files to Backend in two ways.
### 2A. Log Store
Upload pricing and capability JSON files to your object storage.
#### Backend Environment
| Variable | Description |
| - | - |
| `MODEL_CONFIGS_PRICING_LOG_STORE_PATH` | Path to pricing JSON files |
| `MODEL_CONFIGS_CAPABILITIES_LOG_STORE_PATH` | Path to capabilities JSON files |
Expected structure:
```
{PRICING_PATH}/openai.json
{CAPABILITIES_PATH}/openai.json
```
**Updates**
* Replace JSON files in the same path.
* Backend refreshes within 1 hour (cache TTL).
### 2B. Local Volume Mount
Mount `pricing/` and `general/` directories to Backend.
#### Backend Environment
| Variable | Description |
| - | - |
| `MODEL_CONFIGS_PRICING_LOCAL_PATH` | Mounted pricing directory |
| `MODEL_CONFIGS_CAPABILITIES_LOCAL_PATH` | Mounted capabilities directory |
Example Helm values:
```yaml theme={"system"}
backend:
extraVolumes:
- name: model-configs
configMap:
name: portkey-model-configs
extraVolumeMounts:
- name: model-configs
mountPath: /app/model-configs
env:
MODEL_CONFIGS_PRICING_LOCAL_PATH: /app/model-configs/pricing
MODEL_CONFIGS_CAPABILITIES_LOCAL_PATH: /app/model-configs/general
```
**Updates**
* Update ConfigMap/PVC/mounted path.
* Restart Backend pods if required by your mount strategy.
* Data refreshes into memory cache.
***
## Keeping Pricing Updated
1. Pull latest files from the [models repository](https://github.com/Portkey-AI/models).
2. Update your log store or volume mount.
3. Backend refreshes within 1 hour.
For ConfigMap mounts, pod restart may be required.
## Related
* [Model Pricing and Cost Management](/docs/product/observability/cost-management)
* [Portkey Models API](/docs/product/model-catalog/portkey-models)
* [Backend Changelog](/docs/changelog/backend)
* [Enterprise Gateway Changelog](/docs/changelog/enterprise)
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Cache Behavior
Source: https://docs.portkey.ai/docs/self-hosting/cache-behavior
How the Gateway cache works: population, TTL, sync, resync, and cache invalidation and refresh.
The Gateway uses a local cache store (Redis or compatible) for two distinct purposes:
1. **Control Plane entity cache:** stores configuration objects (API keys, virtual keys, configs, prompts, guardrails, integrations) fetched from the Control Plane
2. **LLM response cache:** stores LLM request/response pairs for reuse across identical requests
> [!NOTE]
>
> **Hybrid vs air-gapped:** In a hybrid deployment, the Control Plane is hosted by Portkey. In an air-gapped deployment, the Control Plane runs entirely within your own infrastructure. Air-gapped is no longer offered for new deployments; references to it apply to existing air-gapped customers.
***
## TTL: Control Plane Entities
All configuration objects are cached with a **7-day TTL (604,800 seconds)**. The TTL resets each time an item is re-fetched and re-written to cache.
| Object type | TTL |
| :- | :- |
| API keys | 7 days, or until the key's `expires_at` date (whichever comes first) |
| Virtual keys | 7 days |
| Configs | 7 days |
| Prompt templates | 7 days |
| Prompt partials | 7 days |
| Guardrails | 7 days |
| Integrations | 7 days |
Cache entries are **lazy-loaded**: an object is only written to cache the first time it is requested. Objects that have never been requested are not present in cache.
***
## TTL: LLM Response Cache
LLM response caching is opt-in and must be explicitly enabled per request or via a Portkey Config. TTL only applies when caching is active. The [Cache (Simple & Semantic)](/docs/product/ai-gateway/cache-simple-and-semantic) doc covers how to enable caching, set TTL via `max_age`, configure org-level default TTL, and use force refresh.
***
## Sync: Control Plane → Gateway
Every **minute**, the Gateway sends a sync request to the Control Plane carrying a stable `syncIdentifier` (a UUID generated once per Gateway instance and persisted in cache). The Control Plane uses this identifier to return only the objects that have changed since the last successful sync for that Gateway instance.
The response contains the identifiers of changed objects grouped by type: virtual keys, API keys, configs, prompts, prompt partials, guardrails, and integrations.
For each object in the delta, the Gateway **deletes** its cache entry. The updated data is not pushed into the cache at this point. On the next incoming request that needs that object, the Gateway fetches the latest version from the Control Plane and re-populates the cache with a fresh 7-day TTL.
***
## Resync: Gateway → Control Plane
Separately, a **resync** process also runs every **minute**. Its direction is the opposite of sync: it pushes data from the Gateway back to the Control Plane.
The only data pushed back is **usage counters** (token usage and cost usage). Rather than writing to the Control Plane on every request, the Gateway accumulates these counters locally in cache as requests are processed. The resync worker reads the accumulated values and flushes them to the Control Plane in batches. After a successful flush, the local counter keys are deleted from cache.
Usage counters are tracked for:
* API keys
* Virtual keys
* Integration workspaces
* Usage limit policies
No other cached data (configs, prompts, guardrails, or LLM responses) is ever pushed back to the Control Plane.
***
## Cache Invalidation and Refresh
Invalidation and refresh are two sides of the same lifecycle: an entry is first invalidated (removed from cache), and on the next request for that object, it is refreshed (re-fetched and re-cached).
### Control Plane Entities
| Trigger | What happens |
| :- | :- |
| Delta sync (every minute) | The Gateway deletes cache entries for any object the Control Plane reports as changed. The next request for that object fetches the latest version and re-caches it with a fresh 7-day TTL. |
| TTL expiry (7 days) | The entry is removed automatically. The next request triggers a fresh fetch from the Control Plane. |
| Memory eviction | The entry is evicted by the cache store. The next request triggers a fresh fetch, same as TTL expiry. |
### LLM Response Cache
| Trigger | What happens |
| :- | :- |
| `x-portkey-cache-force-refresh: true` header | The cached response for that request is deleted and replaced with a fresh LLM response. |
| TTL expiry | The entry is removed. The next matching request results in a cache miss and a live LLM call. |
| Memory eviction | Same behaviour as TTL expiry. |
See [Cache (Simple & Semantic)](/docs/product/ai-gateway/cache-simple-and-semantic) for full details on force refresh and TTL configuration.
***
## Data-Bound: Memory Capacity Scenarios
The cache store is an in-memory system. When it reaches its configured memory limit, it evicts entries based on the eviction policy set on the cache instance.
Depending on the eviction policy in use:
* **LRU-based policies** evict the least recently used entries first. Recently accessed config objects and LLM responses are retained; idle ones are removed.
* **Random eviction policies** remove entries without regard to recency, which may evict active objects.
* **`noeviction`** causes all new write operations to fail once the limit is reached, which prevents new entries from being cached at all.
In each case, an evicted entry behaves the same as an expired one: the next request for that object triggers a fresh fetch from the Control Plane (for config objects) or a live LLM call (for response cache entries).
***
## Related
> [card] [Enterprise Architecture](/docs/self-hosting/hybrid-deployments/architecture)
>
> Overview of the Data Plane / Control Plane split and data flow between them
> [card] [Enterprise Components](/docs/product/enterprise-offering/components)
>
> Supported cache backends: Redis, AWS ElastiCache, and more
> [card] [Helm Chart: Cache Store](https://github.com/Portkey-AI/helm-chart/tree/main/helm/enterprise#cache-store)
>
> Full configuration reference for the cache store
> [card] [Data Plane Resiliency](https://github.com/Portkey-AI/helm/blob/main/charts/portkey-gateway/docs/Dataplane%20Resiliency.md)
>
> Detailed resiliency guide including network flow diagrams, outage scenarios, and Helm configuration
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# FIPS-Compliant Images
Source: https://docs.portkey.ai/docs/self-hosting/fips-compliant-images
FIPS 140-3 compliant container images for the Portkey Enterprise Gateway and Data Service
> [!NOTE]
>
> FIPS-compliant images are available on the **Enterprise** plan. Contact your
> Portkey representative or [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form) to
> receive access to the FIPS image registry.
Portkey publishes FIPS-compliant container image variants for the **Enterprise Gateway** and the **Data Service** for customers operating under FIPS 140-3 / FedRAMP requirements. The FIPS images are functionally identical to the standard images, with the following differences:
* The container runs Node.js with the OpenSSL FIPS provider enabled.
* Cryptographic primitives used internally (e.g. SHA-256 for AWS request signing) are routed through FIPS-validated providers — the Data Service uses [`@smithy/hash-node`](https://www.npmjs.com/package/@smithy/hash-node) instead of the default JS hashing path.
* The base image and dependencies are pinned to FIPS-validated versions.
## Components with FIPS images
| Component | First available in | Notes |
| - | - | - |
| Data Service | [v1.7.1](/docs/changelog/data-service#v1-7-1) | Separate FIPS Dockerfile; FIPS-validated SHA-256 used for AWS signing |
| Enterprise Gateway | Available on request | FIPS image variant published alongside the standard release |
## Deploying via Helm
The standard Portkey Helm chart accepts the FIPS image references through the existing `*Image.repository` / `*Image.tag` values — point them at the FIPS image registry provided by Portkey:
```yaml theme={"system"}
images:
gatewayImage:
repository: "/gateway-enterprise"
tag: ""
dataserviceImage:
repository: "/data-service"
tag: ""
```
No other chart values need to change. Existing `LOG_STORE`, virtual-key, config, and observability settings continue to apply.
## Verifying FIPS mode
After deploying, you can confirm FIPS mode is active by checking the OpenSSL providers loaded inside the container:
```sh theme={"system"}
kubectl exec -n portkey deploy/portkey-gateway -- node -e "console.log(crypto.getFips())"
```
A return value of `1` indicates FIPS is enabled.
## Support
For access to the FIPS image registry, validation reports, or compliance documentation, reach out to the Portkey team via [Portkey support](https://support.portkey.ai/forms/customer-portal-ticket-form).
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# Enterprise Architecture
Source: https://docs.portkey.ai/docs/self-hosting/hybrid-deployments/architecture
Comprehensive guide to Portkey's hybrid deployment architecture for enterprises
Portkey Enterprise offers a **secure hybrid deployment model** that balances security, flexibility, and fast deployment timelines:
* **Data Plane** runs within your VPC, keeping sensitive LLM data and AI traffic in your environment
* **Control Plane** hosted by Portkey handles administration, configs, and analytics

Portkey Enterprise Hybrid Deployment Architecture
> [card] [Schedule an Enterprise Architecture Demo](https://portkey.wiki/demo-27)
>
> Want to learn more about our hybrid deployment model? Schedule a personalized demo with our solutions team to see how Portkey Enterprise can fit your security and compliance requirements.
## Core Architecture Components
### Data Plane (Your VPC)
The Data Plane is deployed in your cloud environment and processes all your AI traffic:
| Component | Description | Security Benefit |
| :- | :- | :- |
| **AI Gateway** | Core engine that routes traffic across LLM providers and implements metering, access control, and guardrails | All LLM requests remain in your network perimeter |
| **Cache Store** | Local cache storage for gateway consumption | Eliminates runtime dependency on Control Plane |
| **Data Store** | Storage for LLM request/response logs | Keep sensitive LLM data completely in your environment |
The AI Gateway runs as containerized workloads in your infrastructure, deployable via your preferred orchestration method (Kubernetes, ECS, etc.).
### Control Plane (Portkey VPC)
The Control Plane is fully managed by Portkey and provides the administrative layer for your deployment:
* Hosts the web dashboard for managing configurations, tracking analytics, and viewing logs
* Maintains routing configs, provider integrations
* Stores non-sensitive metadata and aggregated metrics
* Automatically updates with new features and provider integrations without requiring changes to your infrastructure
## Data Flow Between Planes
> [accordion] AI Traffic Flow (Fully Contained in Your VPC)
>
> All LLM traffic stays within your network boundary:
>
> 1. Your application sends requests to the AI Gateway
> 2. The Gateway processes the request (applying routing, caching, guardrails)
> 3. The Gateway forwards the request to the appropriate LLM provider
> 4. Responses from LLMs return through the same path
>
> **Security Benefit**: Complete isolation of sensitive prompt data and responses
> [accordion] Data Sync (Gateway ↔ Control Plane)
>
> The AI Gateway periodically synchronizes with the Control Plane:
>
> * **Frequency**: 1-minute heartbeat intervals
> * **Data Retrieved**: Prompt templates, routing configs, integrations, providers, API keys
> * **Process**: Deltas (changed items) are fetched, decrypted locally, and the corresponding cache entries are invalidated — they are re-fetched from the Control Plane on next use
> * **Resilience**: Gateway operates independently between syncs using cached configs
>
> **Security Benefit**: Continuous operation even during Control Plane disconnection
> [accordion] Cache Behavior
>
> The Gateway holds all configuration objects — API keys, virtual keys, configs, prompts, guardrails — in a local cache so every request is served without a real-time round-trip to the Control Plane. Key points:
>
> * **Lazy-loaded**: items enter the cache on first use; their TTL resets to 7 days on every re-population, so actively used objects stay fresh automatically.
>
> * **Delta invalidation**: every minute the Gateway fetches a list of changed items from the Control Plane and deletes the corresponding cache entries — they are re-fetched on the next request.
>
> * **Eviction policy**: use `volatile-lru` so that idle entries are evicted first under memory pressure, preserving the objects your live traffic depends on.
>
> > [card] [Cache Behavior](/docs/self-hosting/cache-behavior)
> >
> > TTL details, delta sync mechanics, eviction policy, and configuration reference.
> [accordion] Analytics Flow (Gateway → Control Plane)
>
> The Gateway sends anonymized metrics to the Analytics Store:
>
> * **Data Sent**: Non-sensitive operational metrics (model used, token counts, response times)
> * **Purpose**: Powers analytics dashboards for monitoring performance and costs
> * **Example**: [View sample analytics data](#sample-files)
>
> **Security Benefit**: Provides insights without exposing sensitive information
> [accordion] Log Management Options
>
> **Option A: Logs in Your VPC** (Recommended for high-security environments)
>
> * Logs stored in your environment's Blob Store
> * When viewing logs in Dashboard UI, Control Plane requests them from Gateway
>
> **Option B: Logs in Portkey Cloud**
>
> * Gateway encrypts and sends logs to Portkey Log Store
> * No connections required from Portkey to your environment for viewing logs
>
> **Security Benefit**: Flexibility to match your compliance requirements
## Deployment Architecture
Portkey AI Gateway is deployed as containerized workloads using Helm charts for Kubernetes environments, with flexible deployment options for various cloud providers.
### Infrastructure Components
| Component | Description | Configuration Options |
| :- | :- | :- |
| **AI Gateway** | Core container running the routing logic | Deployed as stateless containers that can scale horizontally |
| **Cache System** | Stores routing configs, integrations, providers, and more | Redis (in-cluster, AWS ElastiCache, or custom endpoint) |
| **Log Storage** | Persistence for request/response data | Multiple options (see below) |
### Storage Options
> [tab] Object Storage
>
> S3-compatible storage options including:
>
> * AWS S3 (standard credentials or assumed roles)
> * Google Cloud Storage (S3 compatible interoperability mode)
> * Azure Blob Storage (key, managed identity, or Entra ID)
> * Any S3-compatible Blob Storage
> [tab] Document DB
>
> MongoDB/DocumentDB for structured log storage with options for:
>
> * Direct connection string with username/password
> * Certificate-based authentication (PEM)
> * Connection pooling configurations
### Authentication Methods
> [tab] Cloud Provider IAM
>
> * IAM roles for service accounts (IRSA) in Kubernetes
> * Instance Metadata Service (IMDS) for EC2/ECS
> * Managed identities in Azure environments
> [tab] Direct Authentication
>
> * Standard access/secret keys
> * Certificate-based authentication
> * JWT-based authentication
```mermaid theme={"system"}
flowchart LR
subgraph "Customer VPC"
app["Customer Application"] --> gw["AI Gateway"]
gw <--> cache["Cache Store"]
gw --> logs["Log Storage"]
gw --> llm["LLM Providers"]
end
subgraph "Portkey VPC"
cp["Control Plane"]
end
gw -- "Config Sync\n(Outbound HTTPS)" --> cp
gw -- "Anonymous Metrics\n(Outbound HTTPS)" --> cp
cp -- "Fetch individual logs\n(Inbound HTTPS)" --> gw
```
### Infrastructure Requirements
* **Kubernetes Cluster**: K8s 1.20+ with Helm 3.x
* **Outbound Network**: HTTPS access to Control Plane endpoints
* **Container Registry Access**: For pulling gateway container images
* **Recommended Resource Requirements**:
* CPU: 1-2 cores per gateway instance
* Memory: 2-4GB per gateway instance
* Storage: Dependent on logging configuration
## Data Security & Encryption
> [tab] Data Residency
>
> **Your Sensitive Data Stays in Your VPC**
>
> * All prompt content and LLM responses remain within your network
> * Only anonymized metrics data cross network boundaries
> * Log storage location is configurable based on your requirements
> [tab] Encryption Methods
>
> **Multi-layered Encryption Approach**
>
> * All data in the Control Plane is encrypted at rest
> * Communication between planes uses TLS 1.3 encryption in transit
> * Sensitive data uses envelope encryption
> * Optional BYOK (Bring Your Own Key) support with AWS KMS integration
> [tab] Access Controls
>
> **Defense-in-Depth Security Model**
>
> * Network-level controls limit Control Plane access to authorized IPs
> * Role-based access control for administrative functions
> * Audit logging of all administrative actions
> * Access tokens are short-lived with automatic rotation
## Advantages of Hybrid Architecture
| Benefit | Technical Implementation | Business Value |
| :- | :- | :- |
| **Security & Compliance** | - Sensitive data never leaves VPC - Configurable encryption methods - Flexible authentication options | - Meets data residency requirements - Supports regulated industries - Simplifies security reviews |
| **Operational Efficiency** | - No database management overhead - Automatic model config updates - Horizontally scalable architecture | - Low operational burden - Always up-to-date with LLM ecosystem - Scales with your traffic patterns |
| **Deployment Flexibility** | - Kubernetes-native deployment - Support for major cloud providers - Multiple storage backend options | - Fits into existing infrastructure - Avoids vendor lock-in - Customizable to specific needs |
| **Developer Experience** | - OpenAI-compatible API - Simple integration patterns - Comprehensive observability | - Minimal code changes needed - Smooth developer onboarding - Full visibility into system behavior |
## Technical Rationale
> [accordion] Why Maintain Transaction DB in Control Plane?
>
> 1. **Real-time Model Updates**: LLM providers frequently change model parameters, pricing, and availability. Centralizing this data ensures all gateways operate with current information.
>
> 2. **Feature Velocity**: AI landscape evolves rapidly. Control Plane architecture allows Portkey to deliver new features multiple times per week without requiring customer-side deployments.
>
> 3. **Operational Efficiency**: Eliminates need for customers to maintain complex database infrastructure solely for non-sensitive object management.
> [accordion] Why Cache Objects Locally?
>
> 1. **Performance**: Eliminates network latency during LLM requests by having all routing and configs data available locally.
>
> 2. **Resilience**: Gateway continues operating even if temporarily disconnected from Control Plane.
>
> 3. **Security**: Reduces attack surface by minimizing runtime external dependencies.
## Sample Files
These samples demonstrate the typical data patterns flowing between systems:
> [card] [Sample Log File (4KB)](https://github.com/Portkey-AI/docs-core/tree/main/images/enterprise/private-cloud-deployments/architecture/sample_log_file.json)
> [card] [Sample Metric File (3KB)](https://github.com/Portkey-AI/docs-core/tree/main/images/enterprise/private-cloud-deployments/architecture/sample_metric_file.json)
## Resources & Next Steps
> [card] [Helm Repository](https://github.com/Portkey-AI/helm)
> [card] [Enterprise Changelog](/docs/changelog/enterprise)
> [card] [AWS Deployment Guide](/docs/product/enterprise-offering/private-cloud-deployments/aws)
> [card] [Azure Deployment Guide](/docs/product/enterprise-offering/private-cloud-deployments/azure)
## Have Questions?
Our solution architects are available to discuss your specific deployment requirements and security needs.
> [card] [Schedule Architecture Discussion](https://portkey.wiki/demo-27)
>
> Book a personalized consultation with our enterprise team to explore how Portkey's architecture can be tailored to your organization's specific requirements.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# ECS
Source: https://docs.portkey.ai/docs/self-hosting/hybrid-deployments/aws/ecs
This enterprise-focused document provides comprehensive instructions for deploying the Portkey software on Amazon Elastic Container Service (ECS), tailored to meet the needs of large-scale, mission-critical applications. It includes specific recommendations for component sizing, high availability, and integration with monitoring systems.
## Components and Sizing Recommendations
| Component | Options | Sizing Recommendations |
| - | - | - |
| AI Gateway | Deploy in your ECS cluster using Terraform. | Use Amazon ECS tasks with at least 1 vCPU (1024 CPU units) and 2 GiB of memory per task. For high availability, run tasks across multiple Availability Zones with auto-scaling enabled. |
| Logs Store (optional) | Amazon S3 or S3-compatible Storage | Each log document is \~10kb in size (uncompressed) |
| Cache (Prompts, Configs & Providers) | Built-in Redis or Amazon ElastiCache for Redis OSS or Valkey | Deployed within the same VPC as the Portkey Gateway. |
## Prerequisites
Ensure the following tools and resources are installed and available:
* [AWS Account](https://aws.amazon.com/) with permissions to create ECS, EC2, VPC, ELB, IAM, S3, Secrets Manager, and CloudWatch resources.
* [AWS CLI](https://docs.aws.amazon.com/cli/latest/userguide/getting-started-install.html) configured with credentials.
* [Terraform](https://developer.hashicorp.com/terraform/install) v1.13 or later.
## Create a Portkey Account
* Go to the [Portkey](https://app.portkey.ai) website.
* Sign up for a Portkey account.
* Once logged in, locate and save your `Organisation ID` for future reference. It can be found in the browser URL:
`https://app.portkey.ai/organisation//`
* Contact the Portkey AI team and provide your Organisation ID and the email address used during signup.
* The Portkey team will share the following information with you:
* Docker credentials for the Gateway images (username and password).
* License: Client Auth Key.
## Setup Project Environment
### 1. Prepare AWS Secrets
Create the required secrets in AWS Secrets Manager. You can either use the [CloudFormation template](https://github.com/Portkey-AI/portkey-gateway-infrastructure/blob/main/cloudformation/secrets.yaml) provided in the [portkey-gateway-infrastructure](https://github.com/Portkey-AI/portkey-gateway-infrastructure) repository, or create them manually using the AWS CLI.
**Option A: Using CloudFormation**
1. Go to the [AWS CloudFormation Console](https://console.aws.amazon.com/cloudformation) and create a stack.
2. Upload `cloudformation/secrets.yaml` from the [portkey-gateway-infrastructure](https://github.com/Portkey-AI/portkey-gateway-infrastructure) repository.
3. Provide the following parameters:
* **Project Name** — e.g., `portkey-gateway`
* **Environment** — e.g., `dev`
* **Docker Username / Password** — provided by Portkey
* **Portkey Client Auth** — provided by Portkey
* **Organisations** — your Portkey Organisation ID(s), comma-separated if multiple
4. After the stack completes, note the following outputs for use in the Terraform configuration:
* `DockerCredentialsSecretArn`
* `ClientOrgSecretNameArn`
**Option B: Using AWS CLI**
```sh theme={"system"}
project_name=portkey-gateway # Provide a name for the project
environment=dev # Provide the environment name
aws_region=us-east-1 # Provide the AWS region
# Store Docker credentials shared by Portkey
aws secretsmanager create-secret \
--name ${project_name}/${environment}/docker-credentials \
--region ${aws_region} \
--secret-string '{"username":"","password":""}'
# Store Portkey client auth and organisation ID
aws secretsmanager create-secret \
--name ${project_name}/${environment}/client-org \
--region ${aws_region} \
--secret-string '{"PORTKEY_CLIENT_AUTH":"","ORGANISATIONS_TO_SYNC":""}'
```
Note the ARNs returned for both secrets — they will be used in the Terraform configuration.
### 2. Create Terraform Configuration Files
Create a new directory for your deployment:
```sh theme={"system"}
mkdir portkey-gateway-deployment
cd portkey-gateway-deployment
```
(Optional) Create an S3 bucket to store the Terraform state remotely:
```sh theme={"system"}
aws s3api create-bucket \
--bucket portkey-tfstate- \
--region us-east-1
aws s3api put-bucket-versioning \
--bucket portkey-tfstate- \
--versioning-configuration Status=Enabled
```
Create a `backend.config` file:
```hcl theme={"system"}
bucket = "portkey-tfstate-"
key = "portkey-gateway/dev.tfstate"
region = "us-east-1"
```
### 3. Create Module Configuration
Create a `main.tf` file:
```hcl theme={"system"}
terraform {
required_version = ">= 1.13"
required_providers {
aws = {
source = "hashicorp/aws"
version = "~> 6.0"
}
}
backend "s3" {
use_lockfile = true
}
}
provider "aws" {
region = "us-east-1"
default_tags {
tags = {
Environment = "dev"
ManagedBy = "Terraform"
Project = "portkey-gateway"
}
}
}
module "portkey_gateway" {
source = "github.com/Portkey-AI/portkey-gateway-infrastructure//terraform/ecs?ref=v2.0.0" # Change module version as per requirement
# Project Configuration
project_name = "portkey-gateway"
environment = "dev"
aws_region = "us-east-1"
# Docker Credentials (Secrets Manager ARN)
docker_cred_secret_arn = ""
# Network Configuration
create_new_vpc = true
vpc_cidr = "10.0.0.0/16"
num_az = 2
single_nat_gateway = true
# ECS Cluster Configuration
create_cluster = true
instance_type = "t4g.medium"
min_asg_size = 1
max_asg_size = 2
desired_asg_size = 1
# Server Mode Configuration
server_mode = "gateway" # Set to "all" to deploy both AI Gateway and MCP Gateway
# Gateway Configuration
gateway_config = {
desired_task_count = 1
cpu = 1024
memory = 2048
gateway_port = 8787
mcp_port = 8788
}
# Redis Configuration (built-in)
redis_configuration = {
redis_type = "redis"
cpu = 256
memory = 512
endpoint = ""
tls = false
mode = "standalone"
}
# Object Storage (S3 Log Store)
object_storage = {
log_store_bucket = ""
bucket_region = "us-east-1"
}
# Load Balancer Configuration
create_lb = true
internal_lb = true # Set to false to create an internet-facing Load Balancer
lb_type = "network" # "network" for NLB, "application" for ALB
allowed_lb_cidrs = [""] # CIDR ranges allowed to reach the LB (e.g., the VPC CIDR for an internal LB)
# Environment Variables
environment_variables = {
gateway = {
SERVICE_NAME = "gateway"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
}
}
# Secrets (Secrets Manager ARNs)
secrets = {
gateway = {
PORTKEY_CLIENT_AUTH = ""
ORGANISATIONS_TO_SYNC = ""
}
}
}
output "load_balancer_dns_name" {
value = module.portkey_gateway.load_balancer_dns_name
}
output "vpc_id" {
value = module.portkey_gateway.vpc_id
}
```
### 4. Deploy the Gateway
```sh theme={"system"}
terraform init -backend-config=backend.config
terraform plan
terraform apply
```
**Note:** Values in the `secrets` block must be **AWS Secrets Manager ARNs**, not raw secret values. The ECS task definition references the secret ARN directly and AWS injects the secret value at runtime.
## Advanced Configuration
### MCP Gateway (Optional)
By default, only the AI Gateway is enabled. To enable the MCP Gateway, update your module configuration:
**MCP Only:**
```hcl theme={"system"}
server_mode = "mcp"
mcp_gateway_base_url = "https://mcp.example.com" # MCP external domain clients use to reach MCP
gateway_config = {
desired_task_count = 1
cpu = 256
memory = 1024
gateway_port = 8787
mcp_port = 8788
}
```
**Gateway + MCP (single service, ALB required):**
```hcl theme={"system"}
server_mode = "all"
mcp_gateway_base_url = "https://mcp.example.com"
create_lb = true
lb_type = "application"
allowed_lb_cidrs = [""] # CIDR ranges allowed to reach the ALB
alb_routing_configuration = {
enable_host_based_routing = true
gateway_host = "gateway.example.com"
mcp_host = "mcp.example.com"
}
gateway_config = {
desired_task_count = 2
cpu = 1024
memory = 2048
gateway_port = 8787
mcp_port = 8788
}
```
**Notes:**
* `mcp_gateway_base_url` is **required** when `server_mode` is `"mcp"` or `"all"`. It must be the MCP external domain (with `https://` or `http://` prefix) that clients use to reach the MCP service.
* When `server_mode = "all"`, an Application Load Balancer is required (`lb_type = "application"`) and you must configure host-based routing via `alb_routing_configuration` (`gateway_host` and `mcp_host`).
* For the initial deployment, you can set `mcp_gateway_base_url` to a placeholder, then update it after the Load Balancer is provisioned and DNS is mapped.
**Server Modes**
1. `"gateway"`: Deploys only the AI Gateway. This is the default configuration.
2. `"mcp"`: Deploys only the MCP Gateway. Requires `mcp_gateway_base_url`.
3. `"all"`: Deploys both the AI Gateway and MCP Gateway. Requires `mcp_gateway_base_url` and an ALB with host-based routing.
### Auto-Scaling Configuration
Control how ECS tasks scale based on CPU and memory utilisation:
```hcl theme={"system"}
gateway_autoscaling = {
enable_autoscaling = true
autoscaling_min_capacity = 3
autoscaling_max_capacity = 20
target_cpu_utilization = 70
target_memory_utilization = 80
scale_in_cooldown = 120
scale_out_cooldown = 60
}
```
### Deployment Strategies
ECS supports multiple deployment strategies via `gateway_deployment_configuration`:
**Blue/Green Deployment:**
```hcl theme={"system"}
gateway_deployment_configuration = {
enable_blue_green = true
}
```
**Canary Deployment:**
```hcl theme={"system"}
gateway_deployment_configuration = {
enable_blue_green = false
canary_configuration = {
canary_bake_time_in_minutes = 5
canary_percent = 10
}
}
```
### Network Configuration with VPC
Deploy the Gateway within a VPC.
**Create a new VPC:**
```hcl theme={"system"}
create_new_vpc = true
vpc_cidr = "10.0.0.0/16"
num_az = 2
single_nat_gateway = true
```
**Use an existing VPC and subnets:**
```hcl theme={"system"}
create_new_vpc = false
vpc_id = "vpc-xxxxxxxxxxxxxxxxx"
public_subnet_ids = ["subnet-xxxxxxxx", "subnet-yyyyyyyy"]
private_subnet_ids = ["subnet-aaaaaaaa", "subnet-bbbbbbbb"]
```
### Load Balancer Ingress
The module can provision either an Application Load Balancer (ALB) or a Network Load Balancer (NLB) in front of the Gateway tasks. Pick based on what you need:
| Requirement | Use |
| - | - |
| Host-based routing (required when `server_mode = "all"`) | ALB |
| HTTP/HTTPS-aware routing, WAF, ALB access logs | ALB |
| Layer-4 pass-through, AWS PrivateLink (Inbound Control Plane) | NLB |
| Lowest-latency, simple TCP forwarding | NLB |
#### Application Load Balancer (ALB)
Deploy a public ALB with TLS termination:
```hcl theme={"system"}
create_lb = true
internal_lb = false # true for an internal ALB
lb_type = "application"
tls_certificate_arn = "arn:aws:acm:us-east-1:123456789012:certificate/xxxxxxxx"
allowed_lb_cidrs = [""]
```
**Host-based Routing (required when `server_mode = "all"`):**
```hcl theme={"system"}
alb_routing_configuration = {
enable_host_based_routing = true
gateway_host = "gateway.example.com"
mcp_host = "mcp.example.com"
}
```
Configure DNS:
```
gateway.example.com A/CNAME
mcp.example.com A/CNAME
```
**Enable ALB Access Logs:**
```hcl theme={"system"}
enable_lb_access_logs = true
lb_access_logs_bucket = "portkey-alb-access-logs"
```
#### Network Load Balancer (NLB)
```hcl theme={"system"}
create_lb = true
internal_lb = true # false for an internet-facing NLB
lb_type = "network"
allowed_lb_cidrs = [""] # CIDR ranges allowed to reach the NLB (e.g., the VPC CIDR for an internal NLB)
```
**Note:** NLB does not support host-based routing, so it cannot be used when `server_mode = "all"`.
### Amazon ElastiCache for Redis
Use an existing Amazon ElastiCache cluster instead of the built-in Redis container:
```hcl theme={"system"}
redis_configuration = {
redis_type = "aws-elastic-cache"
cpu = 256 # Ignored for ElastiCache
memory = 512 # Ignored for ElastiCache
endpoint = "master.portkey-redis.xxxxx.use1.cache.amazonaws.com:6379" # Primary or Configuration endpoint
tls = true # Match the cluster's transit encryption setting
mode = "standalone" # or "cluster" for cluster-mode-enabled
}
```
If ElastiCache AUTH is enabled, store the AUTH token in AWS Secrets Manager (as JSON with a `REDIS_PASSWORD` key) and reference the secret ARN. Both the Gateway and Data Service connect to Redis, so the secret must be passed to **both** blocks if the Data Service is enabled:
```hcl theme={"system"}
secrets = {
gateway = {
PORTKEY_CLIENT_AUTH = ""
ORGANISATIONS_TO_SYNC = ""
REDIS_PASSWORD = ""
}
data-service = {
PORTKEY_CLIENT_AUTH = ""
ORGANISATIONS_TO_SYNC = ""
REDIS_PASSWORD = ""
}
}
```
**Note:** ElastiCache's security groups must allow **inbound TCP 6379** (or your configured port) from the Gateway and Data Service task security groups.
### Object Storage (S3 Log Store)
Specify the S3 bucket for storing LLM access logs:
```hcl theme={"system"}
object_storage = {
log_store_bucket = "portkey-prod-logs"
log_exports_bucket = "portkey-prod-exports" # Optional, used by Data Service for log exports
bucket_region = "us-east-1"
}
```
The module attaches an IAM policy to the Gateway task role granting `s3:PutObject` and `s3:GetObject` permissions on the configured buckets.
### Data Service (Optional)
The Data Service is responsible for batch processing, fine-tuning, and log exports. Enable it via:
```hcl theme={"system"}
dataservice_config = {
enable_dataservice = true
desired_task_count = 2
cpu = 512
memory = 1024
}
environment_variables = {
data-service = {
SERVICE_NAME = "data-service"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
HYBRID_DEPLOYMENT = "ON"
}
}
secrets = {
data-service = {
PORTKEY_CLIENT_AUTH = ""
ORGANISATIONS_TO_SYNC = ""
}
}
```
### Amazon Bedrock (Optional)
To allow the Gateway to invoke Amazon Bedrock models, attach an IAM policy with the required `bedrock:InvokeModel` (and related) permissions to the Gateway ECS task role via `gateway_task_role_policy_arns`:
```hcl theme={"system"}
gateway_task_role_policy_arns = {
bedrock = ""
}
```
The module supports both **same-account** and **cross-account** Bedrock access (via `sts:AssumeRole`). For the full IAM policy documents, trust policy templates, and step-by-step setup for both modes, refer to following guide: [Bedrock Access Configuration](https://github.com/Portkey-AI/portkey-gateway-infrastructure/blob/main/terraform/ecs/docs/Bedrock.md).
## Integrating Gateway with Control Plane
**Outbound Connectivity (Data Plane to Control Plane)**
Portkey supports the following methods for integrating the Data Plane with the Control Plane for outbound connectivity:
* AWS PrivateLink
* Over the Internet
### AWS PrivateLink (Outbound)
Establishes a secure, private connection between the Data Plane and the Portkey Control Plane within the AWS network.
**Steps to establish AWS PrivateLink connectivity:**
1. Contact Portkey and provide your AWS account ARN so it can be whitelisted in Portkey's Control Plane.
2. Once you receive confirmation from Portkey that your AWS account is whitelisted, go to the [VPC Console](https://console.aws.amazon.com/vpc/).
3. Select the AWS Region where the Portkey Gateway is deployed.
4. Navigate to the **Endpoints** section in the VPC console.
5. Click on **Create endpoint** and enter the required details.
6. Select the `PrivateLink Ready partner services` category and, under **Service settings**, provide the following details.
* For **Service name**, enter `com.amazonaws.vpce.us-east-1.vpce-svc-0c2c1c323d9f56d95`
* (Optional) If the Gateway is deployed in a region other than `us-east-1`, select `Enable Cross Region endpoint`, choose the `us-east-1` region, and click the **Verify service** button.
7. Under **Network settings**:
* Select the VPC and subnets (at least two in different AZs for high availability) where the endpoint should be created. Ideally, this should be the same VPC where the Gateway is deployed.
* Select the security group to associate with the endpoint. The security group must allow inbound connections on port 443 from the Gateway tasks.
8. After all details are filled in, click on **Create endpoint**.
9. Wait for the Status to change to `Available`.
10. Once the status changes to `Available`, click on **Actions** > **Modify private DNS name** > select **Enable for this endpoint**.
11. Update the `main.tf` to point the Gateway to the private Control Plane endpoint:
```hcl theme={"system"}
environment_variables = {
gateway = {
SERVICE_NAME = "gateway"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
ALBUS_BASEPATH = "https://aws-cp.portkey.ai/albus"
CONTROL_PLANE_BASEPATH = "https://aws-cp.portkey.ai/api/v1"
SOURCE_SYNC_API_BASEPATH = "https://aws-cp.portkey.ai/api/v1/sync"
CONFIG_READER_PATH = "https://aws-cp.portkey.ai/api/model-configs"
}
}
```
12. Re-deploy the Gateway:
```sh theme={"system"}
terraform apply
```
### Over the Internet
Ensure the Gateway has access to the following endpoints over the internet:
* `https://api.portkey.ai`
* `https://albus.portkey.ai`
No additional configuration is needed if your VPC allows outbound internet access via a NAT Gateway.
### Inbound Connectivity (Control Plane to Data Plane)
* AWS PrivateLink
* IP Whitelisting
#### AWS PrivateLink (Inbound)
Establishes a secure, private connection between the Control Plane and the Data Plane within the AWS network.
**Steps to establish AWS PrivateLink connectivity:**
AWS VPC Endpoint Services only support **Network Load Balancers (NLB)** or Gateway Load Balancers — they cannot be created directly against an ALB. Pick one of the two paths below depending on what the module provisions for you.
> [tab] Terraform-provisioned NLB
>
> If your deployment uses `lb_type = "network"`, the module already provisions an NLB that can be associated with the Endpoint Service directly. Ensure the Gateway is exposed via that NLB:
>
> ```hcl theme={"system"}
> create_lb = true
> internal_lb = true # false for internet-facing NLB
> lb_type = "network"
> allowed_lb_cidrs = [""] # CIDR ranges allowed to reach the NLB
> ```
> [tab] Existing ALB (NLB-in-front)
>
> If your deployment already uses an Application Load Balancer (e.g., because `server_mode = "all"` requires host-based routing), the module's ALB cannot be the target of a VPC Endpoint Service. You'll need to provision an NLB **outside this terraform** that uses the existing ALB as a target, and then create the Endpoint Service against that NLB.
>
> High-level steps:
>
> 1. Keep the module-provisioned ALB in place (`lb_type = "application"`).
> 2. Outside this Terraform module, create a Network Load Balancer in the same VPC.
> 3. Create a target group of type `alb` and register the existing ALB as the target.
> 4. Add a listener on the NLB that forwards to that target group on the port the ALB listens on (e.g., 443).
> 5. Use this NLB as the load balancer for the Endpoint Service in the next step.
>
> See the AWS guide on [using an ALB as a target for an NLB](https://docs.aws.amazon.com/elasticloadbalancing/latest/network/application-load-balancer-target.html) for the full procedure.
**Create the Endpoint Service**
* Navigate to the [AWS VPC Console](https://console.aws.amazon.com/vpcconsole/home#CreateVpcEndpointServiceConfiguration).
* In the top-right corner of the AWS Console, select the region where the Portkey Gateway is deployed.
* Provide the following details:
* Name of the endpoint service
* Select the Network Load Balancer to associate with the endpoint (the module-provisioned NLB, or the NLB you created in front of the ALB)
* Choose the regions in which the endpoint service will be available
* Select whether acceptance is required for incoming connections
* Choose whether to enable a Private DNS name — if enabled, provide the Private DNS Name
* Select **IPv4** under Supported IP address types
* Click **Create**.
**(Optional) Verify ownership of the Private DNS name**
This step is required only if you are using a Private DNS Name.
Open the created Endpoint Service > click on **Actions** > select **Verify domain ownership for private DNS name** > create the recommended record in your DNS server > click **Verify**.
**Authorize Portkey's Control Plane to initiate connection requests**
* Open the Endpoint Service > click on **Actions** > select **Allow principals**, and enter the Control Plane's ARN (`arn:aws:iam::299329113195:root`).
* Reach out to the Portkey team and share the following details:
* **Service name**
* **DNS names**
* **Private DNS name**
* **Region** selected while creating the Endpoint Service
* Port number on which the Load Balancer is listening for connections
* Wait for the Portkey team to initiate a connection request from the Control Plane's AWS account to your Gateway's AWS account. Navigate to the **Endpoint connections** section, and once the request appears, approve it.
#### IP Whitelisting
Allows the Control Plane to access the Data Plane over the internet by restricting inbound traffic to specific IP addresses of the Control Plane. This method requires the Data Plane to have a publicly accessible endpoint.
To whitelist, add an inbound rule to the Load Balancer's security group allowing connections from the Portkey Control Plane's IPs (`54.81.226.149`, `34.200.113.35`, `44.221.117.129`) on the listener port. Alternatively, set `allowed_lb_cidrs` in the module configuration:
```hcl theme={"system"}
allowed_lb_cidrs = ["54.81.226.149/32", "34.200.113.35/32", "44.221.117.129/32"]
```
To integrate the Control Plane with the Data Plane, contact the Portkey team and provide the **Public Endpoint** of the Data Plane.
## Verifying Gateway Integration with the Control Plane
* Send a test request to the Gateway using `curl`:
```sh theme={"system"}
# Replace with the Load Balancer DNS or your custom hostname
OPENAI_API_KEY=
PORTKEY_API_KEY=
curl 'http:///v1/chat/completions' \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-H "x-portkey-provider: openai" \
-H "x-portkey-api-key: $PORTKEY_API_KEY" \
-d '{
"model": "gpt-4o-mini",
"messages": [{"role": "user", "content": "What is a fractal?"}]
}'
```
* Go to the [Portkey website](https://app.portkey.ai/) -> **Logs**.
* Verify that the test request appears in the logs and that you can view its full details by selecting the log entry.
## Uninstalling Portkey Gateway
```sh theme={"system"}
terraform destroy
```
## Example Configurations
### Minimal Development Deployment
This example shows a basic deployment with built-in Redis, a new VPC, and no load balancer:
```hcl theme={"system"}
module "portkey_gateway" {
source = "github.com/Portkey-AI/portkey-gateway-infrastructure//terraform/ecs?ref=v2.0.0"
project_name = "portkey-gateway"
environment = "dev"
aws_region = "us-east-1"
docker_cred_secret_arn = ""
environment_variables = {
gateway = {
SERVICE_NAME = "gateway"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
}
}
secrets = {
gateway = {
PORTKEY_CLIENT_AUTH = ""
ORGANISATIONS_TO_SYNC = ""
}
}
create_new_vpc = true
vpc_cidr = "10.0.0.0/16"
num_az = 2
single_nat_gateway = true
create_cluster = true
instance_type = "t4g.medium"
desired_asg_size = 1
min_asg_size = 1
max_asg_size = 2
server_mode = "gateway"
gateway_config = {
desired_task_count = 1
cpu = 256
memory = 1024
gateway_port = 8787
mcp_port = 8788
}
redis_configuration = {
redis_type = "redis"
cpu = 256
memory = 512
endpoint = ""
tls = false
mode = "standalone"
}
object_storage = {
log_store_bucket = ""
bucket_region = "us-east-1"
}
create_lb = true
internal_lb = true
lb_type = "network"
allowed_lb_cidrs = [""]
}
```
### Production Deployment with ALB, ElastiCache, and Data Service
This example shows a production-grade deployment with a public ALB, Amazon ElastiCache, the Data Service enabled, and auto-scaling:
```hcl theme={"system"}
module "portkey_gateway" {
source = "github.com/Portkey-AI/portkey-gateway-infrastructure//terraform/ecs?ref=v2.0.0"
project_name = "portkey-gateway"
environment = "prod"
aws_region = "us-east-1"
docker_cred_secret_arn = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/docker-credentials"
environment_variables = {
gateway = {
SERVICE_NAME = "gateway"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
}
data-service = {
SERVICE_NAME = "data-service"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
HYBRID_DEPLOYMENT = "ON"
}
}
secrets = {
gateway = {
PORTKEY_CLIENT_AUTH = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/client-org"
ORGANISATIONS_TO_SYNC = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/client-org"
REDIS_PASSWORD = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/redis-auth"
}
data-service = {
PORTKEY_CLIENT_AUTH = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/client-org"
ORGANISATIONS_TO_SYNC = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/client-org"
REDIS_PASSWORD = "arn:aws:secretsmanager:us-east-1:123456789012:secret:portkey-gateway/prod/redis-auth"
}
}
# Network
create_new_vpc = true
vpc_cidr = "10.0.0.0/16"
num_az = 3
single_nat_gateway = false
# ECS Cluster
create_cluster = true
instance_type = "t4g.large"
min_asg_size = 2
max_asg_size = 10
desired_asg_size = 3
server_mode = "gateway"
gateway_config = {
desired_task_count = 3
cpu = 1024
memory = 2048
gateway_port = 8787
mcp_port = 8788
}
gateway_autoscaling = {
enable_autoscaling = true
autoscaling_min_capacity = 3
autoscaling_max_capacity = 20
target_cpu_utilization = 70
target_memory_utilization = 80
scale_in_cooldown = 120
scale_out_cooldown = 60
}
gateway_deployment_configuration = {
enable_blue_green = true
}
# Data Service
dataservice_config = {
enable_dataservice = true
desired_task_count = 2
cpu = 512
memory = 1024
}
# Amazon ElastiCache
redis_configuration = {
redis_type = "aws-elastic-cache"
cpu = 256
memory = 512
endpoint = "prod-redis.xxxxx.cache.amazonaws.com:6379"
tls = true
mode = "cluster"
}
# S3 Log Store
object_storage = {
log_store_bucket = "portkey-prod-logs"
log_exports_bucket = "portkey-prod-exports"
bucket_region = "us-east-1"
}
# Public ALB with TLS
create_lb = true
internal_lb = false
lb_type = "application"
tls_certificate_arn = "arn:aws:acm:us-east-1:123456789012:certificate/xxxxxxxx"
allowed_lb_cidrs = [""]
enable_lb_access_logs = true
lb_access_logs_bucket = "portkey-alb-access-logs"
}
```
### Gateway + MCP Deployment
This example shows how to deploy both the AI Gateway and the MCP Gateway behind an Application Load Balancer with host-based routing:
```hcl theme={"system"}
module "portkey_gateway" {
source = "github.com/Portkey-AI/portkey-gateway-infrastructure//terraform/ecs?ref=v2.0.0"
project_name = "portkey-gateway"
environment = "prod"
aws_region = "us-east-1"
docker_cred_secret_arn = ""
environment_variables = {
gateway = {
SERVICE_NAME = "gateway"
ANALYTICS_STORE = "control_plane"
LOG_STORE = "s3_assume"
}
}
secrets = {
gateway = {
PORTKEY_CLIENT_AUTH = ""
ORGANISATIONS_TO_SYNC = ""
}
}
create_new_vpc = true
vpc_cidr = "10.0.0.0/16"
num_az = 2
single_nat_gateway = true
create_cluster = true
instance_type = "t4g.large"
min_asg_size = 2
max_asg_size = 6
desired_asg_size = 2
# Deploy both Gateway and MCP
server_mode = "all"
mcp_gateway_base_url = "https://mcp.example.com"
gateway_config = {
desired_task_count = 2
cpu = 1024
memory = 2048
gateway_port = 8787
mcp_port = 8788
}
redis_configuration = {
redis_type = "redis"
cpu = 256
memory = 512
endpoint = ""
tls = false
mode = "standalone"
}
object_storage = {
log_store_bucket = "portkey-logs"
bucket_region = "us-east-1"
}
# ALB with host-based routing
create_lb = true
internal_lb = false
lb_type = "application"
tls_certificate_arn = "arn:aws:acm:us-east-1:123456789012:certificate/xxxxxxxx"
allowed_lb_cidrs = [""]
alb_routing_configuration = {
enable_host_based_routing = true
gateway_host = "gateway.example.com"
mcp_host = "mcp.example.com"
}
}
```
## Multi-Environment Setup
To manage `dev`, `staging`, and `prod` from a single codebase, organise your project as follows:
```
my-infrastructure/
├── dev/
│ ├── main.tf
│ ├── backend.config
│ └── terraform.tfvars
├── staging/
│ ├── main.tf
│ ├── backend.config
│ └── terraform.tfvars
└── prod/
├── main.tf
├── backend.config
└── terraform.tfvars
```
Each environment has its own remote state and variable values:
```hcl theme={"system"}
# dev/backend.config
bucket = "portkey-tfstate-"
key = "portkey-gateway/dev.tfstate"
region = "us-east-1"
# prod/backend.config
bucket = "portkey-tfstate-"
key = "portkey-gateway/prod.tfstate"
region = "us-east-1"
```
Deploy each environment independently:
```sh theme={"system"}
# Dev
cd dev
terraform init -backend-config=backend.config
terraform apply -var-file=terraform.tfvars
# Prod
cd ../prod
terraform init -backend-config=backend.config
terraform apply -var-file=terraform.tfvars
```
## Version Pinning and Upgrades
Always pin the module to a specific version in production:
```hcl theme={"system"}
# Recommended - pinned to v2.0.0
source = "github.com/Portkey-AI/portkey-gateway-infrastructure//terraform/ecs?ref=v2.0.0"
```
To upgrade, review the [release notes](https://github.com/Portkey-AI/portkey-gateway-infrastructure/releases), test the new version in a non-production environment first, then promote to production:
```sh theme={"system"}
terraform init -upgrade
terraform plan # Review changes carefully
terraform apply
```
To roll back, revert the `ref` to the previous version and re-run `terraform init -upgrade && terraform apply`.
***
> [card] [Portkey is now PRISMA AIRS AI Gateway. See it in action.](https://www.paloaltonetworks.in/ai-security/ai-gateway?utm_source=portkey\&utm_medium=referral\&utm_campaign=prisma_airs\&utm_content=docs_nav#contact)
>
> Contact Us
# EKS
Source: https://docs.portkey.ai/docs/self-hosting/hybrid-deployments/aws/eks
This enterprise-focused document provides comprehensive instructions for deploying the Portkey software in a hybrid mode on Amazon EKS clusters, designed to meet the needs of large-scale, mission-critical applications. It includes specific recommendations for component sizing, high availability, and integration with monitoring systems.
## Components and Sizing Recommendations
| Component | Options | Sizing Recommendations |
| - | - | - |
| AI Gateway | Deploy in your EKS cluster using Helm charts. | Use Amazon EKS t4g.medium worker nodes, each providing at least 2 vCPUs and 4 GiB of memory. For high availability, deploy them across multiple Availability Zones. |
| Logs Store (optional) | Amazon S3 or S3-compatible Storage | Each log document is \~10kb in size (uncompressed) |
| Cache (Prompts, Configs & Providers) | Built-in Redis, Amazon ElastiCache for Redis OSS or Valkey | Deployed within the same VPC as the Portkey Gateway. |
## Prerequisites
Ensure that following tools and resources are installed and available:
* A running [Amazon EKS cluster](https://docs.aws.amazon.com/eks/latest/userguide/create-cluster-auto.html) with at least 2 worker nodes. ( **Best Practice:** Use 2 nodes, with 1 node in each Availability Zone, to ensure high availability.)
* [AWS CLI](https://docs.aws.amazon.com/cli/latest/userguide/getting-started-install.html)
* [Kubectl](https://docs.aws.amazon.com/eks/latest/userguide/install-kubectl.html)
* [Helm (v3 or above)](https://helm.sh/docs/intro/install/)
* [eksctl](https://docs.aws.amazon.com/eks/latest/userguide/install-kubectl.html)
## Create a Portkey Account
* Go to the [Portkey](https://app.portkey.ai) website.
* Sign up for a Portkey account.
* Once logged in, locate and save your `Organisation ID` for future reference. You can find it in the browser URL:
`https://app.portkey.ai/organisation//`
* Contact the Portkey AI team and provide your Organisation ID and the email address used during signup.
* The Portkey team will share the following information with you:
* Docker credentials for the Gateway images (username and password).
* License: Client Auth Key.
## Setup Project Environment
```sh theme={"system"}
cluster_name= # Specify the name of the EKS cluster where the gateway will be deployed.
namespace= # Specify the namespace where the gateway should be deployed (for example, portkeyai).
service_account_name= # Provide a name for the Service Account to be associated with Gateway Pod (for example, gateway-sa)
mkdir portkey-gateway
cd portkey-gateway
touch values.yaml
```
### Image Credentials Configuration
```yaml theme={"system"}
# Update the values.yaml file
imageCredentials:
- name: portkey-enterprise-registry-credentials
create: true
registry: https://index.docker.io/v1/
username:
password:
images:
gatewayImage:
repository: "docker.io/portkeyai/gateway_enterprise"
pullPolicy: Always
tag: "latest"
dataserviceImage:
repository: "docker.io/portkeyai/data-service"
pullPolicy: Always
tag: "latest"
redisImage:
repository: "docker.io/redis"
pullPolicy: IfNotPresent
tag: "7.2-alpine"
environment:
create: true
secret: true
data:
ANALYTICS_STORE: control_plane
SERVICE_NAME: # Specify a name for the service
PORTKEY_CLIENT_AUTH:
ORGANISATIONS_TO_SYNC: # This is obtained after signing up for a Portkey account.
```
## Configure Components
Based on the choice of components and their configuration update the `values.yaml`.
### MCP Gateway (Optional)
By default, only the AI Gateway is enabled in the deployment. To enable the MCP Gateway, add the following configuration to `values.yaml`:
```yaml theme={"system"}
environment:
data:
SERVER_MODE: "mcp/all"
MCP_PORT: "8788"
MCP_GATEWAY_BASE_URL: ""
```
**Note:**
* `MCP_GATEWAY_BASE_URL` must include the protocol prefix — either `http://` or `https://`.
* This value is not required for the initial deployment. After the first deployment, once the MCP Load Balancer is provisioned and a hostname is mapped to the MCP Service, set this value and redeploy.
**Server Modes**
1. `""` (empty or not provided): Deploys only the AI Gateway. This is the default configuration.
2. `"mcp"`: Deploys only the MCP Gateway.
3. `"all"`: Deploys both the AI Gateway and MCP Gateway.
### Cache Store
The Portkey Gateway deployment includes a Redis instance pre-installed by default. You can either use this built-in Redis or connect to an external cache like `Amazon ElastiCache for Redis OSS` or `Valkey`.
#### Built-in Redis
No additional permissions or network configurations are required.
```yaml theme={"system"}
## To use the built-in Redis, add the following configuration to the values.yaml file.
environment:
data:
CACHE_STORE: redis
REDIS_URL: "redis://redis:6379"
REDIS_TLS_ENABLED: "false"
```
#### Amazon ElastiCache
To enable the gateway to work with an ElastiCache cache, ensure that an inbound rule is configured in ElastiCache's Security Group allowing access from the EKS cluster on the required port.
> [tab] No Auth
>
> ```yaml theme={"system"}
> environment:
> data:
> CACHE_STORE: aws-elastic-cache
> REDIS_URL: "redis://:"
> REDIS_TLS_ENABLED: "false"
> REDIS_MODE: cluster ## Add this parameter only if cluster mode is enabled
> ```
> [tab] Auth Token
>
> ```yaml theme={"system"}
> environment:
> data:
> CACHE_STORE: aws-elastic-cache
> REDIS_URL: "redis://:"
> REDIS_TLS_ENABLED: "true"
> REDIS_MODE: cluster ## Add this parameter only if cluster mode is enabled
> REDIS_PASSWORD: ## Provide Auth Token configured on ElastiCache
> ```
> [tab] IRSA
>
> ```yaml theme={"system"}
> serviceAccount:
> create: true
> automount: true
> name:
> annotations:
> eks.amazonaws.com/role-arn:
>
> environment:
> data:
> CACHE_STORE: aws-elastic-cache
> REDIS_URL: "redis://:"
> REDIS_TLS_ENABLED: "true"
> REDIS_MODE: cluster ## Add this parameter only if cluster mode is enabled
> AWS_REDIS_AUTH_MODE: iam
> AWS_REDIS_CLUSTER_NAME: ## Name of the ElastiCache replication group or serverless cache
> REDIS_USERNAME: ## ElastiCache user ID configured for IAM authentication
> ```
>
> **Note:** The IAM role must have `elasticache:Connect` permission. See [ElastiCache IAM authentication](https://docs.aws.amazon.com/AmazonElastiCache/latest/dg/auth-iam.html) for details.
> [tab] EKS Pod Identity
>
> ```yaml theme={"system"}
> serviceAccount:
> create: true
> automount: true
> name: